
MARL-BattleGrounds
The JAX-native Benchmark for Heterogeneous and Competitive Multi-agent Reinforcement Learning: built from scratch by researchers, for researchers.




Installation | Quick Start | Baselines | Guides | See Also | Citation
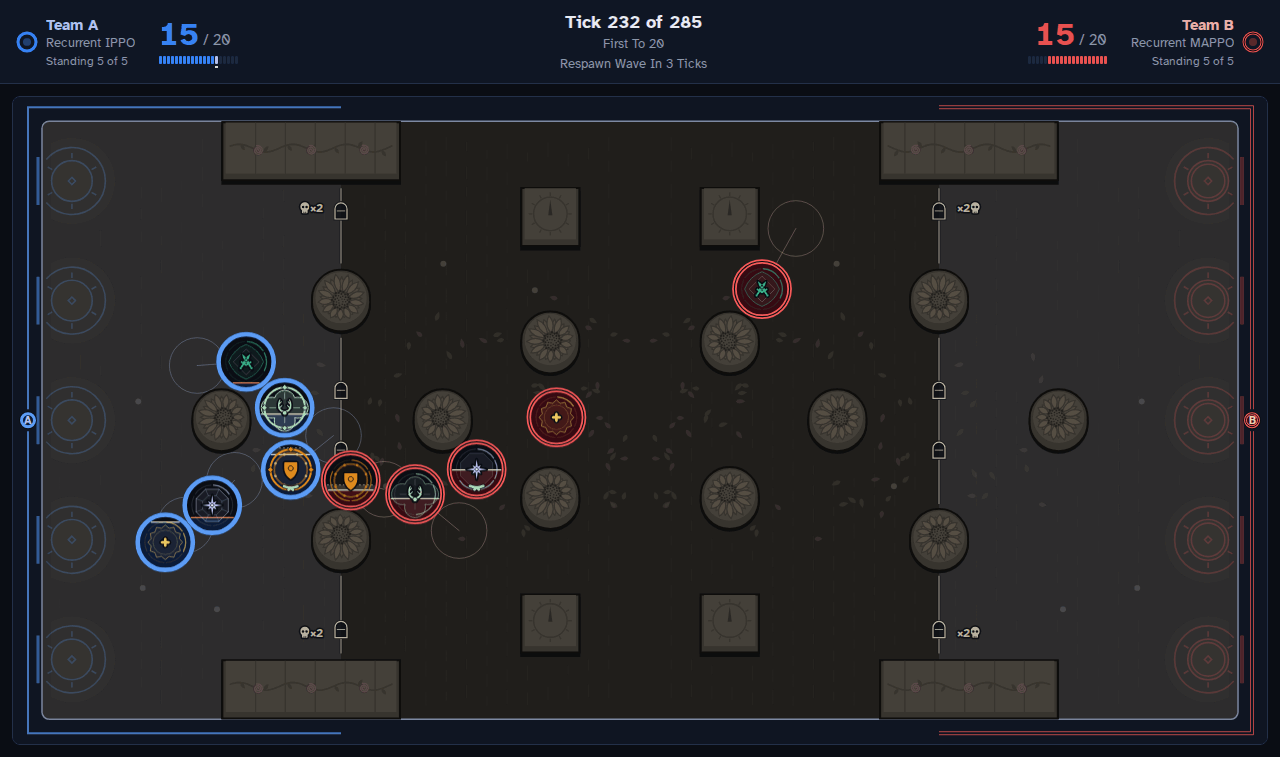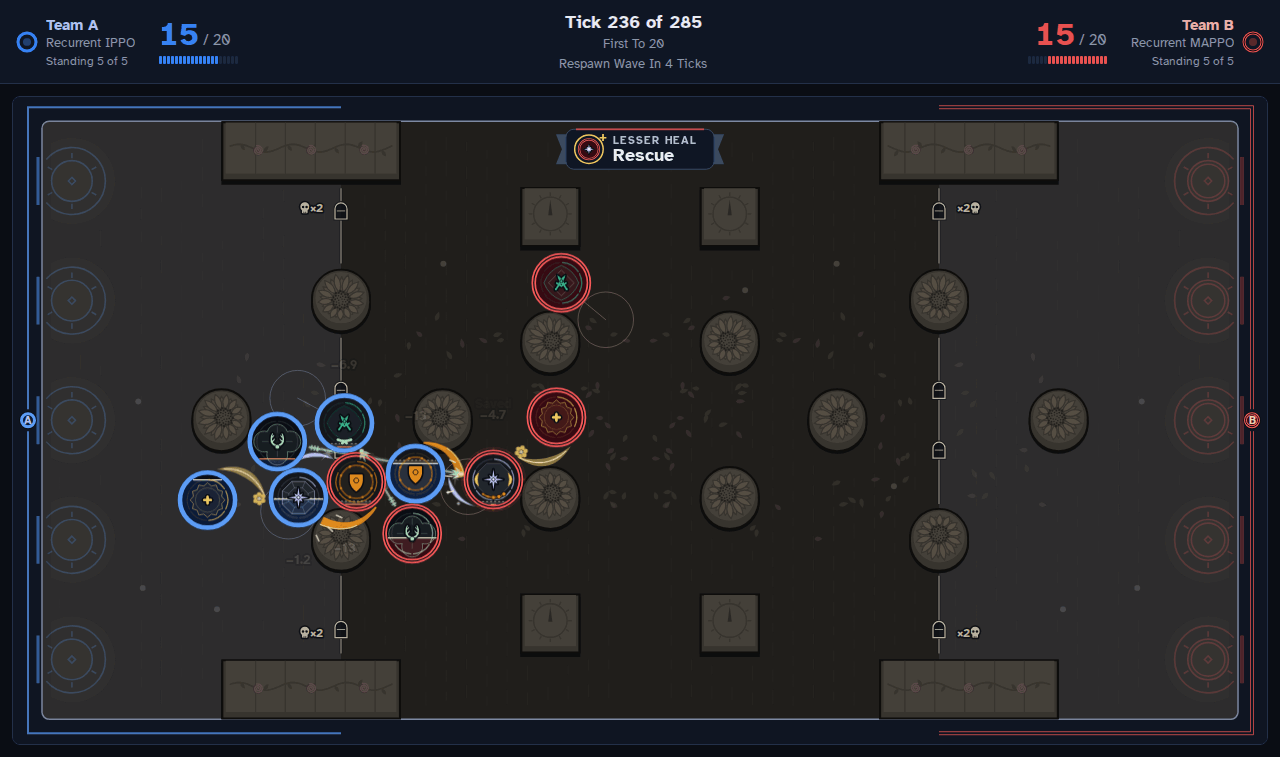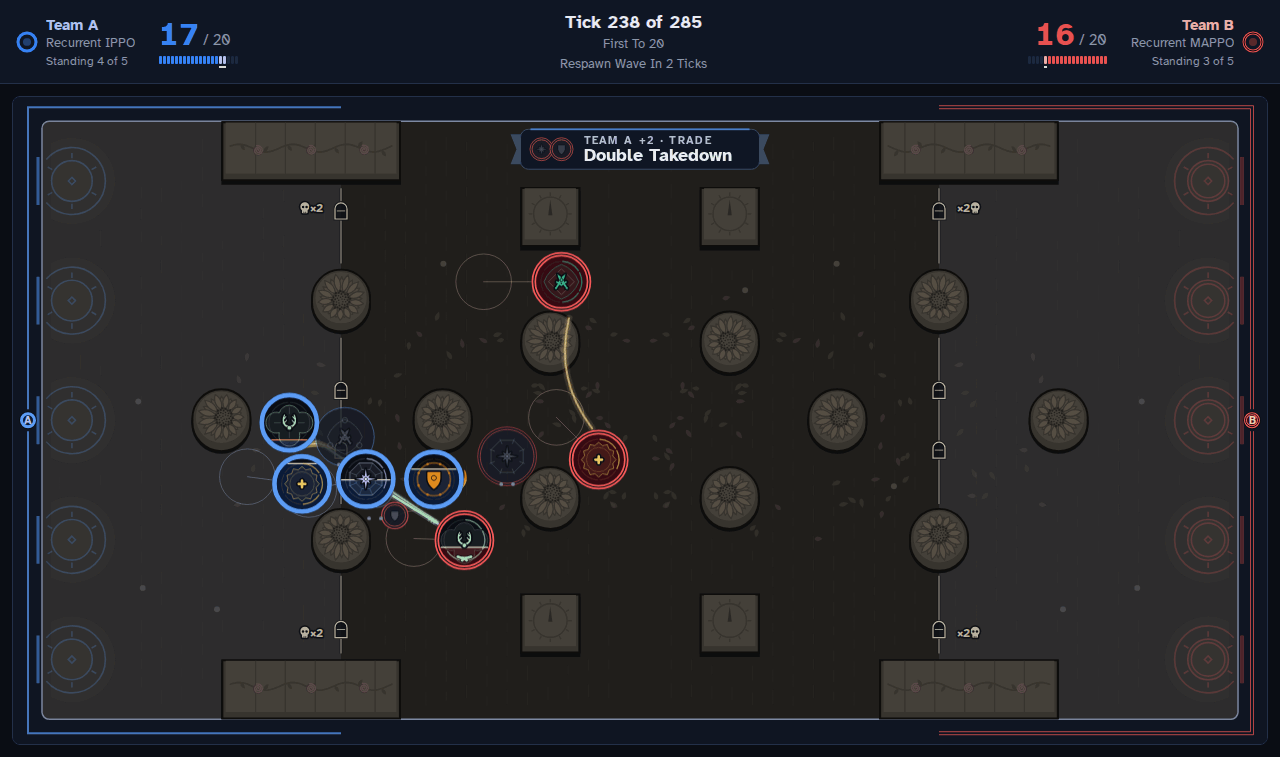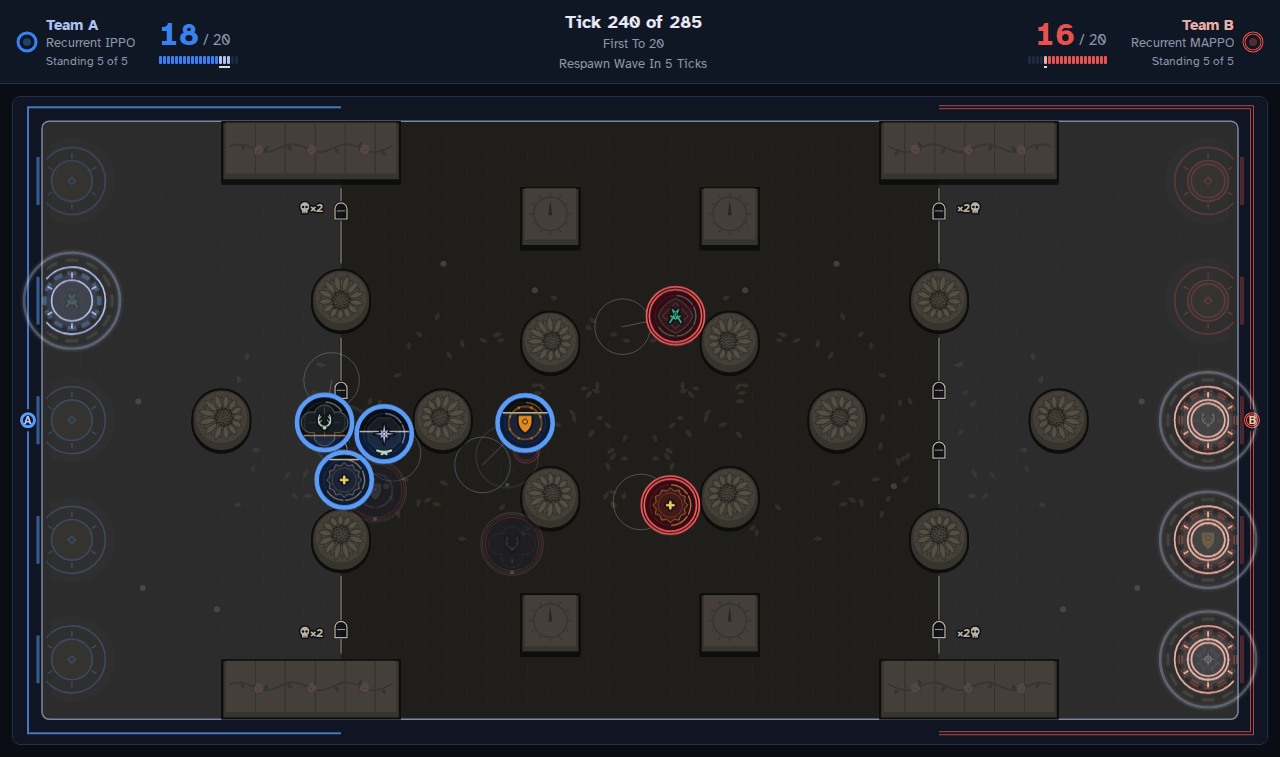
MARL-BattleGrounds (MARL-BGs) is an easy-to-use, JAX-native benchmark for heterogeneous and competitive team-vs-team multi-agent reinforcement learning (MARL). It is designed to be sample-efficient, computationally efficient and researcher-centric. Most MARL benchmarks are either fast but simple, like SMAX, where winning comes down to unit micromanagement, or rich but costly, like Dota 2, which took OpenAI Five ten months of training on large clusters. MARL-BGs fills the missing middle: rich team play, with fast and cheap experiments on one GPU.
- The Game. In Team Deathmatch, two teams of up to five agents fight on 52 hand-designed maps. Each agent is a Mage, Warrior, Hunter, Rogue or Priest. Each class has its own Basic ability, passive and Ultimate, built to help allies and counter enemies, so the team that wins is the one that coordinates its specialists best, not the one with the best individual agents. Obstacles block sight and attacks, so each agent sees only part of the map. Maps 0-11 form a curriculum, maps 0-41 are for training, maps 42-46 for validation and maps 47-51 for testing.
- The Evaluation. Eight hand-crafted endgame scenarios, each with a verified winning line, test skills such as agent modeling and multi-step planning. Each season's tournament retrains every entry on equal compute, plays it against the current "Big Nine" on the test maps, and rates it with draw-aware Elo and confidence intervals, so the benchmark's difficulty grows with the quality of its entries. Every entrant is released as a downloadable opponent. Up to 11,192 metrics per game, in 28 topics, show how a team won, such as how much the Priest healed each ally.
- The Tools. Bring your own learner through plain JAX
resetandstep, or start from six tuned baselines. Their trained Season 0 models, and every save from 0 to 250 million steps, load by name from Hugging Face. Training helpers cover self-play, opponent pools, curricula and reward shaping. One call evaluates any mix of policies, so cross-play and zero-shot coordination tests come out of the box. MARL-BGs also ships three strong scripted opponents, an LLM API that turns a language model into a team, the BattleClient for playing alongside or against your policies, and the analytical Replay Viewer for stepping through any game tick by tick.
Try it in your browser: the walkthrough covers the API, the speed, training a team and the trained Season 0 teams, and the analysis notebook rebuilds the paper's analysis of all 7,200 Season 0 games.
Installation
Start here:
| You Want To | Do This |
|---|---|
| Look around in your browser, with nothing to install | Open the walkthrough in Colab: the API, the speed, training a team and the trained Season 0 teams |
| Play the game | The one command below |
| Use MARL-BattleGrounds in your own project | pip, below |
You do not need to install JAX first: each route installs the right JAX for your machine. An NVIDIA GPU is optional but recommended: without one, everything runs on the CPU, only slower.
On Linux, an Apple Silicon Mac or Windows with WSL2, one command installs everything and opens the BattleClient. It picks the right JAX build for your GPU:
curl -L https://github.com/arm-2-lab/MARL-BattleGrounds/archive/refs/tags/v1.0.2.tar.gz | tar xz
cd MARL-BattleGrounds-1.0.2 && sh start.sh
In your own Python project (Python 3.12 to 3.14; 3.14 recommended):
pip install "marl-battlegrounds[all]"           # CPU
pip install "marl-battlegrounds[all,cuda13]"    # NVIDIA GPU, driver 580 or newer
With Docker or Podman, on any system (add --gpus all and the 1.0.2-cuda12 tag for an NVIDIA GPU):
docker run --rm -it -p 127.0.0.1:8765:8766 -p 127.0.0.1:8767:8768 -v "${PWD}:/work" ghcr.io/arm-2-lab/marl-battlegrounds:1.0.2
| Route | For | Tested |
|---|---|---|
One command, sh start.sh |
Linux (x86_64 and ARM), Apple Silicon Mac, Windows with WSL2 | Tested: Linux x86_64 with an NVIDIA RTX 5090; Linux x86_64 and ARM, and an Apple Silicon Mac, on the CPU; Windows 11 with WSL2 (Ubuntu 24.04) and an NVIDIA RTX 5090 |
| pip | Linux, Apple Silicon Mac, WSL2; Python 3.12 to 3.14 | Tested: Linux x86_64 and ARM, and an Apple Silicon Mac, each with Python 3.12, 3.13 and 3.14; Windows 11 with WSL2 (Ubuntu 24.04, Python 3.12) and an NVIDIA RTX 5090 |
| Docker | Any system with Docker or Podman; NVIDIA GPUs on Linux and Windows | Tested: Linux with Docker (CPU, and an NVIDIA GPU with the CUDA 12 image), Linux with Podman, the ARM image on ARM Linux, Docker Desktop on Windows 11 (CPU, and an NVIDIA RTX 5090 with the CUDA 12 image), Docker Desktop on an Apple Silicon Mac (macOS 26). Not tested yet; it should work: Docker Desktop on an Intel Mac |
| Colab, Open in Colab | A browser | Tested: Colab's free T4 GPU |
"Tested" means we ran exactly these instructions on that system for this release.
Docker runs everything: play, replays, training, evaluation, tournaments, analysis and notebooks. Its limits:
| Limit | What to Do |
|---|---|
| No GPU in Docker on a Mac | Use the CPU image; Docker cannot reach Apple GPUs |
study (big multi-run jobs) is not tested in containers and stops when the container stops |
Start the container with -d; not tested yet |
| You cannot add packages to a running container | Build a two-line Dockerfile: FROM ghcr.io/arm-2-lab/marl-battlegrounds:1.0.2, then RUN uv pip install <package> |
| Docker Desktop (Mac, Windows) limits the container's memory | Raise the memory limit in Docker Desktop's settings for large training runs |
Every route, the GPU builds, Windows, clusters and offline use: the install guide.
Quick Start
make, reset and step use JaxMARL's call order (reset(key), step(key, state, actions)), and compile under jit, vmap and lax.scan.
import jax
import marl_battlegrounds as marl_bgs

env = marl_bgs.make("tdm", map_id=0, num_envs=4)  # four games at once
key = jax.random.key(0)
observation, state = env.reset(key)
for _ in range(50):
    key, act_key, step_key, reset_key = jax.random.split(key, 4)
    actions = env.sample_actions(act_key, state)  # legal random actions
    observation, state, reward, done, info = env.step(step_key, state, actions)
    observation, state = env.reset_done(reset_key, state)  # restart finished games
On one RTX 5090 with 1,024 parallel 5v5 games, the simulator alone runs 50,416 game steps per second (random legal actions, compilation excluded), and recurrent MAPPO trains at 29,878 game steps per second in pure self-play.
Train
One command trains recurrent IPPO with the Season 0 learner settings (250 million game steps) against itself, its past copies and the three scripted opponents, and keeps its best checkpoint on the validation maps. What Training Costs gives the time and memory on one GPU.
python -m marl_battlegrounds.experiments.train method=ippo pool=scripted \
  'validation_opponents=[tdm-alpha,tdm-beta,tdm-gamma]' output_dir=runs/my-ippo
Evaluate
import marl_battlegrounds as marl_bgs

results = marl_bgs.evaluate("random", "tdm-alpha", num_episodes=32, num_envs=32)
print(results.head_to_head())  # games, wins, draws, losses, point margin
Your method is always Team A, and paired games swap the spawn ends, so a map's layout cannot favor either side.
The analysis notebook shows what full metrics
reveal: the Season 0 ladder, who beats whom on each map, the teamwork that follows
Elo and who helps whom. Point it at your own tournament with MARL_BGS_RESULTS.
Watch and Play
python -m marl_battlegrounds replay path/to/game.marlbg-replay.json
import marl_battlegrounds as marl_bgs

marl_bgs.battle_client(team_b="tdm-alpha")  # play in your browser against a scripted team
Baselines
| Method | Name | Memory | Critic | Reference | Source |
|---|---|---|---|---|---|
| Recurrent MAPPO | mappo |
Recurrent | Centralized | Yu et al., 2022 | ppo.py |
| Feedforward MAPPO | ff_mappo |
None | Centralized | Yu et al., 2022 | ppo.py |
| Recurrent IPPO | ippo |
Recurrent | One per agent | de Witt et al., 2020 | ppo.py |
| Feedforward IPPO | ff_ippo |
None | One per agent | de Witt et al., 2020 | ppo.py |
| QMIX | qmix |
Recurrent | QMIX mixer | Rashid et al., 2018 | qmix.py |
| PQN-VDN | pqn_vdn |
Recurrent | Sum of agent values | Gallici et al., 2024; Sunehag et al., 2017 | pqn.py |
Every save of the six Season 0 models, from 0 to 250 million steps, loads by name from
Hugging Face, for example
marl_bgs.load_method("MARL-BattleGrounds/tdm-season-0-recurrent-ippo@final")
(Released Models).
Your own method can be anything that turns permitted observations into legal actions: a network, a planner, a language model or a mix.
Leaderboard
Season 1: submissions are open until 00:00 UK time on December 29, 2026, and its table is published at 00:00 UK time on January 1, 2027, on the leaderboard. Season 2 is February 2027, and after that there is one season a month.
Any method that runs as pure JAX may enter, not only MARL: learned, scripted, search-based, hybrid or built on a language model. We run your training script once on our RTX 5090: at most 255 million game steps and 8 hours. Every entry gets the same budget on the same machine, so the leaderboard rewards MARL methods that are efficient in both samples and compute. Your entry then plays the current Big Nine (at the start of Season 1, Season 0's six baselines and three scripted bots) on the test maps and is rated with draw-aware Elo. The table also shows what each entry cost to train and to play. Every entrant is released as a downloadable opponent.
python -m marl_battlegrounds entry new my-entry   # a starter entry
python -m marl_battlegrounds entry check          # checks it the way we will
python -m marl_battlegrounds entry submit         # opens the GitHub issue form
The Tournament Rules say who may enter and set the limits. Enter the Leaderboard walks through the three commands.
Guides
| Guide | What It Covers | Website |
|---|---|---|
| Getting Started | Install, your first games, maps, rosters, what agents see | start |
| Game Rules | Classes, abilities, scoring, Red Zone, scenarios | game |
| Your Method | Plug in your own model or learner, with JAX's jit, vmap and scan | your-method |
| Training | The six learners, opponents, curriculum, rewards, checkpoints | training |
| Released Models | Load, play, train against or start from the six trained Season 0 models | models |
| Hydra Configs | Settings files, overrides, sweeps, studies and the experiment stages | configs |
| Evaluation | Fair games, validation and test maps, scenarios, saved results | evaluate |
| Metrics | What is measured and how to read it | metrics |
| Tournaments | Round robins, Elo ratings and tiers | round-robin |
| Tournament Rules | The leaderboard rulebook | leaderboard-rules |
| Replays | Save games and watch them in the analytical Replay Viewer | record |
| BattleClient | Play against or beside your own agents in the browser | battleclient |
| LLM Agents | Run a language model as a team | llm |
| Performance | Speed and memory, and how to measure them on your machine | performance |
| Method Sources | Where the built-in learners come from | method-sources |
| API Reference | Every public name on one page | api |
Reproduce the Paper
The paper's commands, frozen settings and result tables are in
scripts/paper_experiments/.
The Season 0 ladder and teamwork figures also rebuild in the
analysis notebook, with nothing to install.
See Also
JAX-native environments:
- JaxMARL: Multi-Agent RL Environments and Algorithms in JAX.
- JaxAHT: a benchmark for ad hoc teamwork (working with teammates never met in training) in JAX.
- Gymnax: classic RL environments in JAX.
- Jumanji: combinatorial and planning environments in JAX.
- Pgx: board games in JAX.
- Brax: physics simulation for robot learning in JAX.
- XLand-MiniGrid: open-ended grid worlds for meta-RL in JAX.
- Craftax: an open-ended survival game in JAX.
JAX-native algorithms:
- Mava: JAX implementations of popular MARL algorithms.
- PureJaxRL: JAX implementation of PPO, and demonstration of end-to-end JAX-based RL training.
Citation
If you use MARL-BattleGrounds in your work, please cite the paper:
@article{hawili2026marlbattlegrounds,
  title   = {{MARL-BattleGrounds}: A Novel {JAX}-native Benchmark for Heterogeneous and Competitive Multi-agent {RL}},
  author  = {Hawili, Ulixes Tariq and Ramamoorthy, Subramanian and Altmann, Yoann and Carlucho, Ignacio},
  journal = {arXiv preprint arXiv:2610.14883},
  month   = oct,
  year    = {2026}
}
Contribute
Pull requests are welcome. Start with CONTRIBUTING.md, and open an issue for bugs, ideas, questions and leaderboard submissions.
License
Licensed under the Apache License, Version 2.0.
1 maintainer

Metadata
1 maintainer
Release files for marl-battlegrounds 1.0.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| marl_battlegrounds-1.0.2.tar.gz | 4.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| marl_battlegrounds-1.0.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 9.3 MB
Release files / marl_battlegrounds-1.0.2.tar.gz
| Download URL | marl_battlegrounds-1.0.2.tar.gz |
|---|---|
| Size | 4.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0ea79d379f831e498b097aadfd54f5ff69879b10f24a71e149238cdbdbdd45e3
|
|
BLAKE2b-256 checksum How to use checksums |
b1f58d22c2392df3d38df2475ab1e9a9fe9384f0ac9ca19fed8a8baa688d714c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency logRelease files / marl_battlegrounds-1.0.2-py3-none-any.whl
| Download URL | marl_battlegrounds-1.0.2-py3-none-any.whl |
|---|---|
| Size | 4.8 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7a8a5e7ce7f4838d1037dfa02030ce4373d10c51a27a02ebd693537a4bc46a01
|
|
BLAKE2b-256 checksum How to use checksums |
d470f52a8e739718d78e9f7bf50efa469a4dff6013a0e2427c18616143e2c172
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency log













