
MASHBOX Labs makes open models run faster and cheaper on TPUs and accelerated hardware, as well as exploring the future of the intersection of AI and gaming.
Install • Models • Docs • Hugging Face • Coding agents

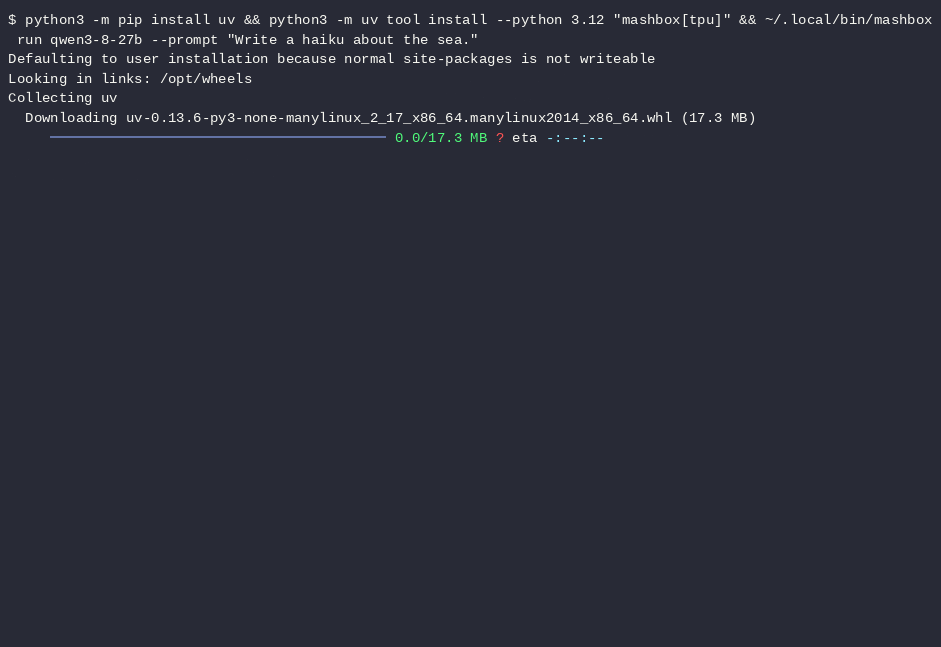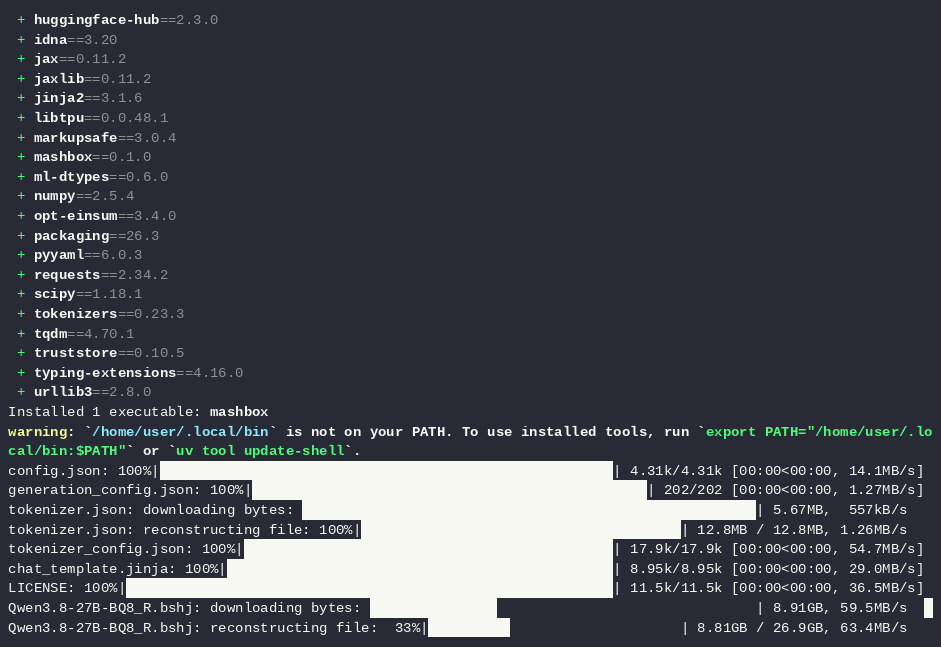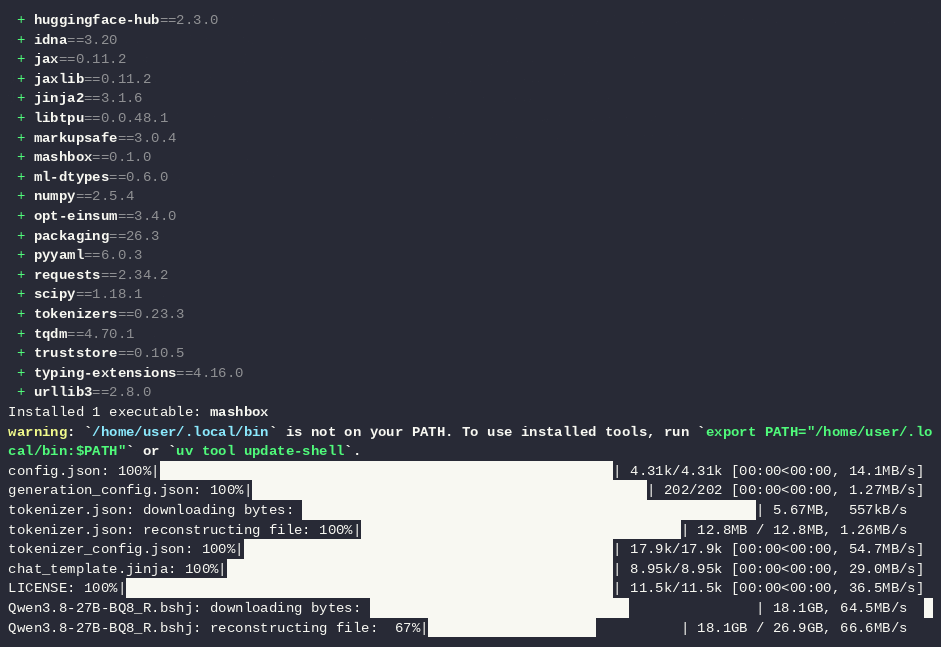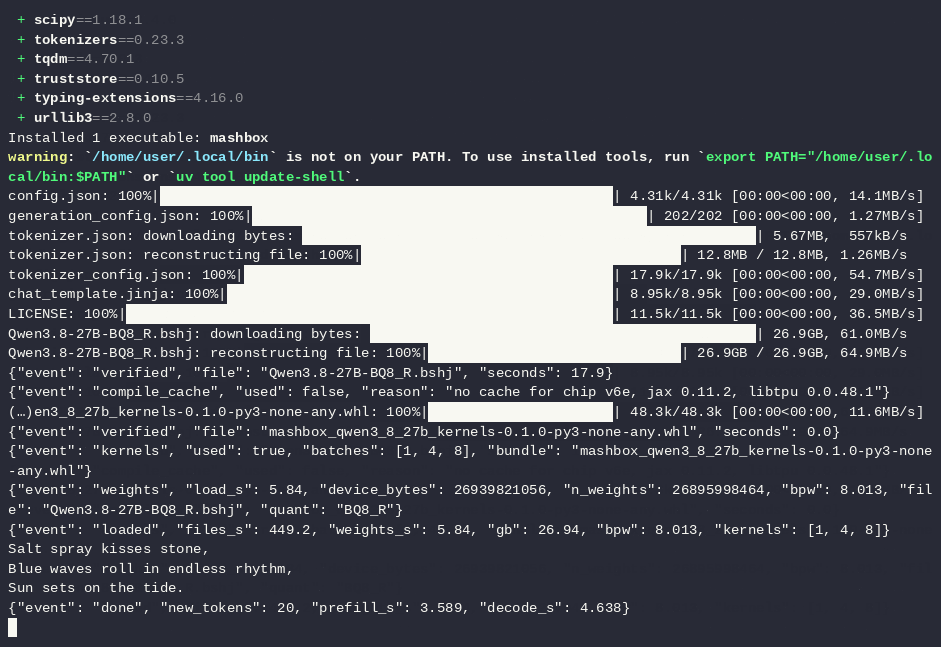
Qwen3.8-27B on one TPU v6e chip: first-time install to first answer (sped up 10x).
Install
Two lines on your own machine (Linux or macOS, x86_64 or arm64; on Windows, use WSL2). The first installs the mashbox command, the second gets a Google Cloud TPU chip and starts Qwen3.8-27B on it:
curl -fsSL https://mashbox.gg/install.sh | sh
mashbox tpu up qwen3-8-27b
Line 2 needs the Google Cloud CLI, signed in to a project with billing and the TPU API turned on; Run on Google Cloud TPU steps 1 to 5 do that from a new Google account. It prints the chip's price per hour and asks before it creates anything. Then it installs the same mashbox version on the chip and starts the server there, reached through an SSH tunnel from your machine. mashbox tpu down mashbox-qwen3-8-27b deletes the chip, and if you forget, the chip deletes itself at its max lifetime.
On a machine that has a TPU, such as a Cloud TPU VM you created yourself, the same line 1 installs the TPU version and mashbox run runs a model there:
curl -fsSL https://mashbox.gg/install.sh | sh
mashbox run qwen3-8-27b --prompt "Write a haiku about the sea."
If the shell does not find mashbox after line 1, ~/.local/bin is not on your PATH: line 1 printed the export PATH=... line for this terminal, or call it as ~/.local/bin/mashbox. To do the same by hand with gcloud, one chip and one answer: Quickstart.
What each install adds:
| Install | What it adds | Where it goes |
|---|---|---|
mashbox |
the mashbox command with mashbox models and mashbox tpu, which gets a chip and runs a model on it from your machine. It has no JAX, so models do not run on this machine. |
your laptop or desktop: line 1 installs this anywhere but a TPU VM |
mashbox[cpu] |
JAX for CPU | a machine that runs a CPU model: Track2Rig, which adds its own extra (mashbox[cpu,track2rig]) |
mashbox[tpu] |
JAX for TPU | a TPU VM: line 1 installs this there |
mashbox[tpu,hy-nomas] |
JAX for TPU, plus PyTorch and the other libraries the Hy-Nomas pipeline uses | a TPU VM that runs Hy-Nomas: mashbox tpu up hy-nomas installs it on its chip |
Each one needs Python 3.12 or newer. Line 1 installs with uv, which brings its own Python 3.12, since a Cloud TPU VM's system Python is 3.10. On a TPU VM without line 1: python3 -m pip install uv && python3 -m uv tool install --python 3.12 "mashbox[tpu]". For Hy-Nomas with line 1, name the extras:
curl -fsSL https://mashbox.gg/install.sh | MASHBOX_EXTRAS=tpu,hy-nomas sh
mashbox run fetches the compiled TPU kernels a model uses by itself, so there is nothing to install or pick. They come from two places. The engine kernel package, used for GGUF files and Hugging Face models, is one file attached to a mashbox release on GitHub; models.json lists it under engine_kernels, with the chips and the JAX version it is built for. Each MASHBOX build that ships kernels has its own kernel package in its Hugging Face repo, under kernels/. mashbox run checks every file against its sha256 in models.json before it uses it. When no package fits the chip and the JAX version, the model runs without one, on plain JAX, which is slower, and the log says so.
The chip bills from create to delete: one TPU v6e chip is $2.70 an hour at Google's on-demand list price. Qwen3.8-27B's options, chips and results: docs/models/qwen3-8-27b.md.
Models
37 models and files run in mashbox: 4 MASHBOX builds and 33 GGUF files of 20 models.
MASHBOX builds
Models we port or make ourselves. A BSHJ build is our weights file for the model, run on our TPU kernels. Measured is each one's number against its baseline, on the chip named.
| Model | What it does | Chips | Measured | Weights |
|---|---|---|---|---|
| Hy-Nomas by Tencent Hunyuan |
World model: text and movement keys in, video out | TPU v5e: Not tested yet TPU v6e (v6e-1): One chip: the full pipeline fits on a single TPU v6e chip (32 GB), 2.46 s of compute per second of video, main model quantized. This version of mashbox run starts on a v6e-4TPU v5p slice (v5p-8): Not tested yet TPU v6e slice (v6e-4): Supported |
Compute per second of video, quality preset, Tencent decoder, 1.00 = real time: 1.045 s (TPU v6e-4) Compute per second of video, quality preset, MASHBOX Fast decoder: 0.689 s (TPU v6e-4) |
Hy-Nomas-TPU |
| Qwen3.8-27B by Qwen |
LLM: text in, text out | TPU v5e (v5e-4): Supported TPU v6e (v6e-1): Supported TPU v5p slice (v5p-8): Not tested yet TPU v6e slice (v6e-4): Supported |
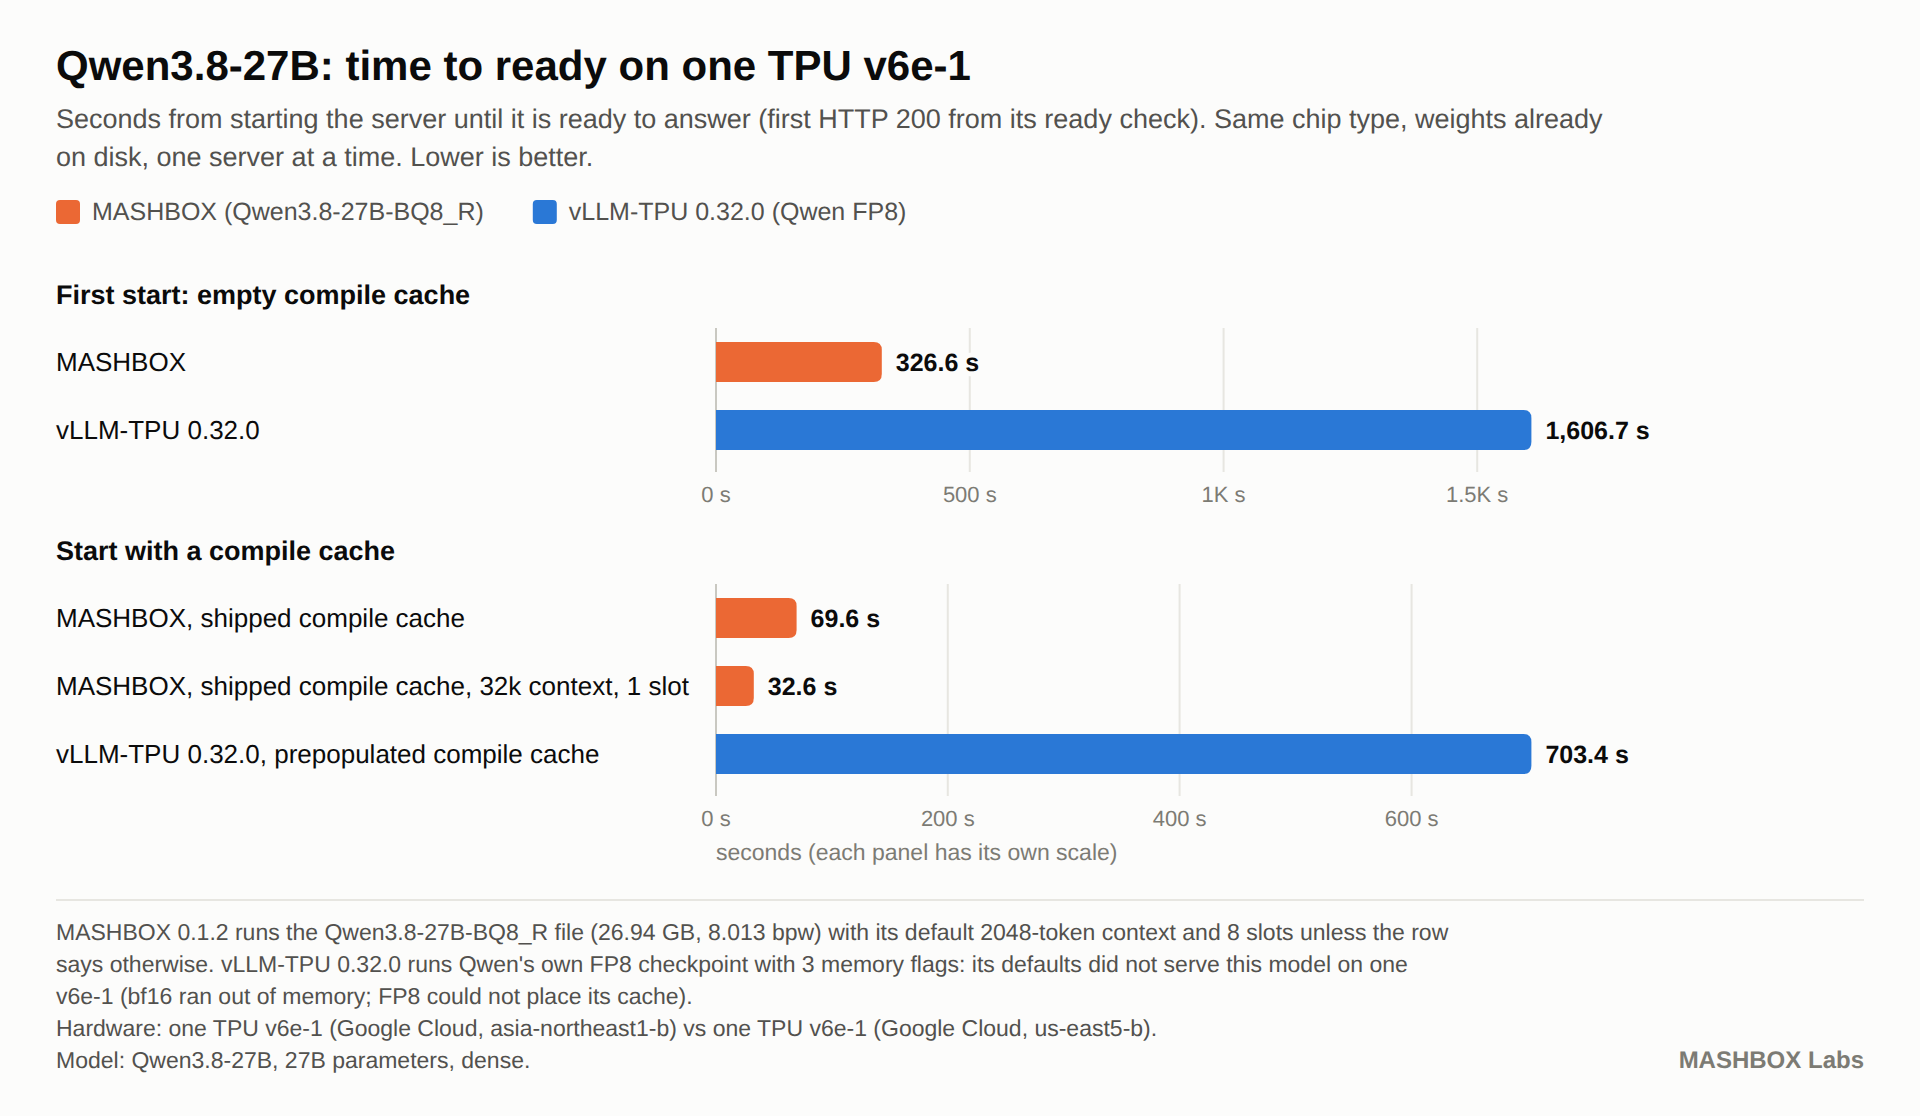
38.1 vs 31.4 tok/s vs vLLM on the same chip, 1 request at a time; 74.84 tok/s with speculative decoding (--mtp 2), 1 request at a time, greedy; 37.77 tok/s with it off; 326.6 vs 1,606.7 s first start to ready, weights on disk, empty compile caches, vs vLLM on the same chip type (TPU v6e-1). All results | Qwen3.8-27B-TPU |
| Track2Rig by MASHBOX Labs Experimental |
Rigging: 3D point tracks in, rig (JSON and glTF) out | CPU: Supported TPU v5e: Not tested yet TPU v6e: Supported TPU v5p slice (v5p-8): Not tested yet TPU v6e slice (v6e-4): Not tested yet |
0.784% vs 0.915% held-out error vs SSDR at the same bone count, synthetic test set with noisy, partly hidden tracks, % of body size, lower is better; 6.24% vs 7.73% joint error vs SSDR, % of body size, lower is better (CPU, AMD EPYC 7502P). All results | Track2Rig |
| TRELLIS.2 by Microsoft Experimental |
image-to-3d: an RGBA image (background cut out) in, a textured 3D mesh (GLB) out | TPU v5e: Not tested yet TPU v6e (v6e-1): Supported TPU v5p slice (v5p-8): Not tested yet TPU v6e slice (v6e-4): Not tested yet |
One picture in, a textured GLB out: the whole command: 15 min 32.4 s to 30 min 11.7 s (TPU v6e-1) Picture in to mesh out: the model's stages on the chip, with the host work between them: 46.7 s to 1 min 37.5 s (TPU v6e-1) |
TRELLIS.2-TPU |
GGUF files that run in our engine
GGUF files from other publishers, run as they are by mashbox. Level and Runs on say how far each file has been checked; a speed shows only where a chip run measured it on our kernels.
0bserverx (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-Heretic-Q4_K_M.gguf from 0bserverx, 16.55 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.2 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
bartowski (7 files): Falcon3-1B-Instruct, Llama-3.2-1B-Instruct, Llama-3.2-3B-Instruct, Qwen2.5-0.5B-Instruct, Qwen2.5-1.5B-Instruct, Qwen2.5-7B-Instruct
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Falcon3-1B-Instruct by Technology Innovation Institute |
Falcon3-1B-Instruct-Q8_0.gguf from bartowski, 1.78 GB |
llama |
Q8_0 | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 579.24 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Llama-3.2-1B-Instruct by Meta |
Llama-3.2-1B-Instruct-Q4_K_M.gguf from bartowski, 0.81 GB |
llama |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 403 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Llama-3.2-3B-Instruct by Meta |
Llama-3.2-3B-Instruct-IQ4_XS.gguf from bartowski, 1.83 GB |
llama |
IQ4_XS | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 250.5 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen2.5-0.5B-Instruct by Qwen |
Qwen2.5-0.5B-Instruct-Q4_K_M.gguf from bartowski, 0.4 GB |
qwen2 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 322.01 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen2.5-1.5B-Instruct by Qwen |
Qwen2.5-1.5B-Instruct-Q4_K_M.gguf from bartowski, 0.99 GB |
qwen2 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 205.07 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen2.5-1.5B-Instruct by Qwen |
Qwen2.5-1.5B-Instruct-Q5_K_M.gguf from bartowski, 1.13 GB |
qwen2 |
Q5_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 196.63 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen2.5-7B-Instruct by Qwen |
Qwen2.5-7B-Instruct-Q4_K_M.gguf from bartowski, 4.68 GB |
qwen2 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 101.55 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
byteshape (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-IQ2_XXS-2.56bpw.gguf from byteshape, 8.84 GB |
qwen35 |
IQ2_XXS | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 11.42 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
cdiamond (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-iMatrix-NVFP4-MTP.gguf from cdiamond, 17.13 GB |
qwen35 |
MTP | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 12.43 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
DavidAU (2 files): Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic-NEO-IMATRIX-MAX-MTP, Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic-NEO-IMATRIX-MAX-MTP by DavidAU |
Qwen3.5-9B-The-Defiant-Fable-Uncnr-Heretic-NEO-MAX-MTP-Q4_K_M.gguf from DavidAU, 6.98 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 87.37 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU by DavidAU |
Qwen3.8-27B-TurboFCFusion-735-882-Here-Uncen-NEO-CODER-MAX-MTP-Q4_K_M.gguf from DavidAU, 18.5 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.25 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
ggml-org (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-Q4_K_M.gguf from ggml-org, 18.97 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 30.65 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
HauhauCS (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-Uncensored-HauhauCS-Aggressive-Q4_K_P.gguf from HauhauCS, 17.92 GB |
qwen35 |
Q4_K_P | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 28.25 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
huihui-ai (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Huihui-Qwen3.8-27B-abliterated-UD-DW-Q4_K_M.gguf from huihui-ai, 16.55 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.33 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
ibm-granite (1 file): granite-3.3-2b-instruct
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| granite-3.3-2b-instruct by IBM |
granite-3.3-2b-instruct-Q4_K_M.gguf from ibm-granite, 1.55 GB |
granite |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 197.56 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
JonathanColetti (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-Uncensored-Q4_K_M.gguf from JonathanColetti, 16.81 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.2 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
LGAI-EXAONE (1 file): EXAONE-3.5-2.4B-Instruct
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| EXAONE-3.5-2.4B-Instruct by LG AI Research |
EXAONE-3.5-2.4B-Instruct-Q4_K_M.gguf from LGAI-EXAONE, 1.64 GB |
exaone |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 256.27 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
lmstudio-community (2 files): Qwen3.5-9B, Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.5-9B by Qwen |
Qwen3.5-9B-Q4_K_M.gguf from lmstudio-community, 5.63 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 87.31 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-Q4_K_M.gguf from lmstudio-community, 16.81 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.21 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
peculiar-ragdoll (1 file): Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen3.8-27B by Qwen |
Dirk-Qwen3.8-27B-UD-Q4_K_M.gguf from peculiar-ragdoll, 16.46 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.45 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
Qwen (5 files): Qwen2.5-0.5B-Instruct, Qwen2.5-1.5B-Instruct, Qwen2.5-Coder-1.5B-Instruct, Qwen3-14B, Qwen3-4B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| Qwen2.5-0.5B-Instruct by Qwen |
qwen2.5-0.5b-instruct-q4_k_m.gguf from Qwen, 0.49 GB |
qwen2 |
q4_k_m | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 323.92 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen2.5-1.5B-Instruct by Qwen |
qwen2.5-1.5b-instruct-q4_k_m.gguf from Qwen, 1.12 GB |
qwen2 |
q4_k_m | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 205.7 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen2.5-Coder-1.5B-Instruct by Qwen |
qwen2.5-coder-1.5b-instruct-q4_k_m.gguf from Qwen, 1.12 GB |
qwen2 |
q4_k_m | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 205.38 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3-14B by Qwen |
Qwen3-14B-Q4_K_M.gguf from Qwen, 9 GB |
qwen3 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 45.67 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3-4B by Qwen |
Qwen3-4B-Q4_K_M.gguf from Qwen, 2.5 GB |
qwen3 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 142.36 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
unsloth (7 files): gemma-3-1b-it, Qwen3-0.6B, Qwen3-1.7B, Qwen3-4B-Instruct-2507, Qwen3.5-4B, Qwen3.5-9B, Qwen3.8-27B
| Model | GGUF file | Architecture | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|---|
| gemma-3-1b-it by Google DeepMind |
gemma-3-1b-it-Q4_K_M.gguf from unsloth, 0.81 GB |
gemma3 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 389.7 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3-0.6B by Qwen |
Qwen3-0.6B-Q8_0.gguf from unsloth, 0.64 GB |
qwen3 |
Q8_0 | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 419.38 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3-1.7B by Qwen |
Qwen3-1.7B-Q4_0.gguf from unsloth, 1.06 GB |
qwen3 |
Q4_0 | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 216.5 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3-4B-Instruct-2507 by Qwen |
Qwen3-4B-Instruct-2507-Q4_K_M.gguf from unsloth, 2.5 GB |
qwen3 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 142.2 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3.5-4B by Qwen |
Qwen3.5-4B-Q4_K_M.gguf from unsloth, 2.74 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 147.9 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3.5-9B by Qwen |
Qwen3.5-9B-Q4_K_M.gguf from unsloth, 5.68 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 87.84 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
| Qwen3.8-27B by Qwen |
Qwen3.8-27B-UD-Q4_K_M.gguf from unsloth, 16.46 GB |
qwen35 |
Q4_K_M | Quick check Runs on one chip of a TPU v6e-4 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) |
one chip of a TPU v6e-4 | 27.51 tok/s, steady decode, 1 user, on one chip of a TPU v6e-4 |
Full catalog, with the run command for each file.
Listed, not in mashbox run
Models we publish that mashbox run does not start in this version. Each names the device its files are made for and links the page that shows how to use them.
| Model | What it does | Made for | Files | How to use |
|---|---|---|---|---|
| Audio2Face-3D v3.0 by NVIDIA |
Speech audio to face motion for skin, tongue, jaw and eyes. | TPU | Audio2Face-3D-v3.0-TPU | How to use |
| Granite Speech 4.1 2B by IBM |
Speech recognition and speech translation. | TPU | granite-speech-4.1-2b-TPU | How to use |
| LFM3-1.7B by Liquid AI |
Text generation, as a Core ML model. | Apple Neural Engine | LFM3-1.7B-CoreML | How to use |
| maya1 and the SNAC 24 kHz decoder by Maya Research |
Text to speech from a voice description and the text to say. | TPU | maya1-TPU | How to use |
| Real-ESRGAN x2plus and x4plus by Xintao Wang |
Image upscaling. | TPU | Real-ESRGAN-TPU | How to use |
| Z-Image-Turbo by Tongyi-MAI |
Text to image. | TPU | Z-Image-Turbo-TPU | How to use |
Every number names the chip it was measured on; each model's guide has all its results. Options for any model: ~/.local/bin/mashbox run <model> --help.
Results
Each chart names the hardware on both sides.
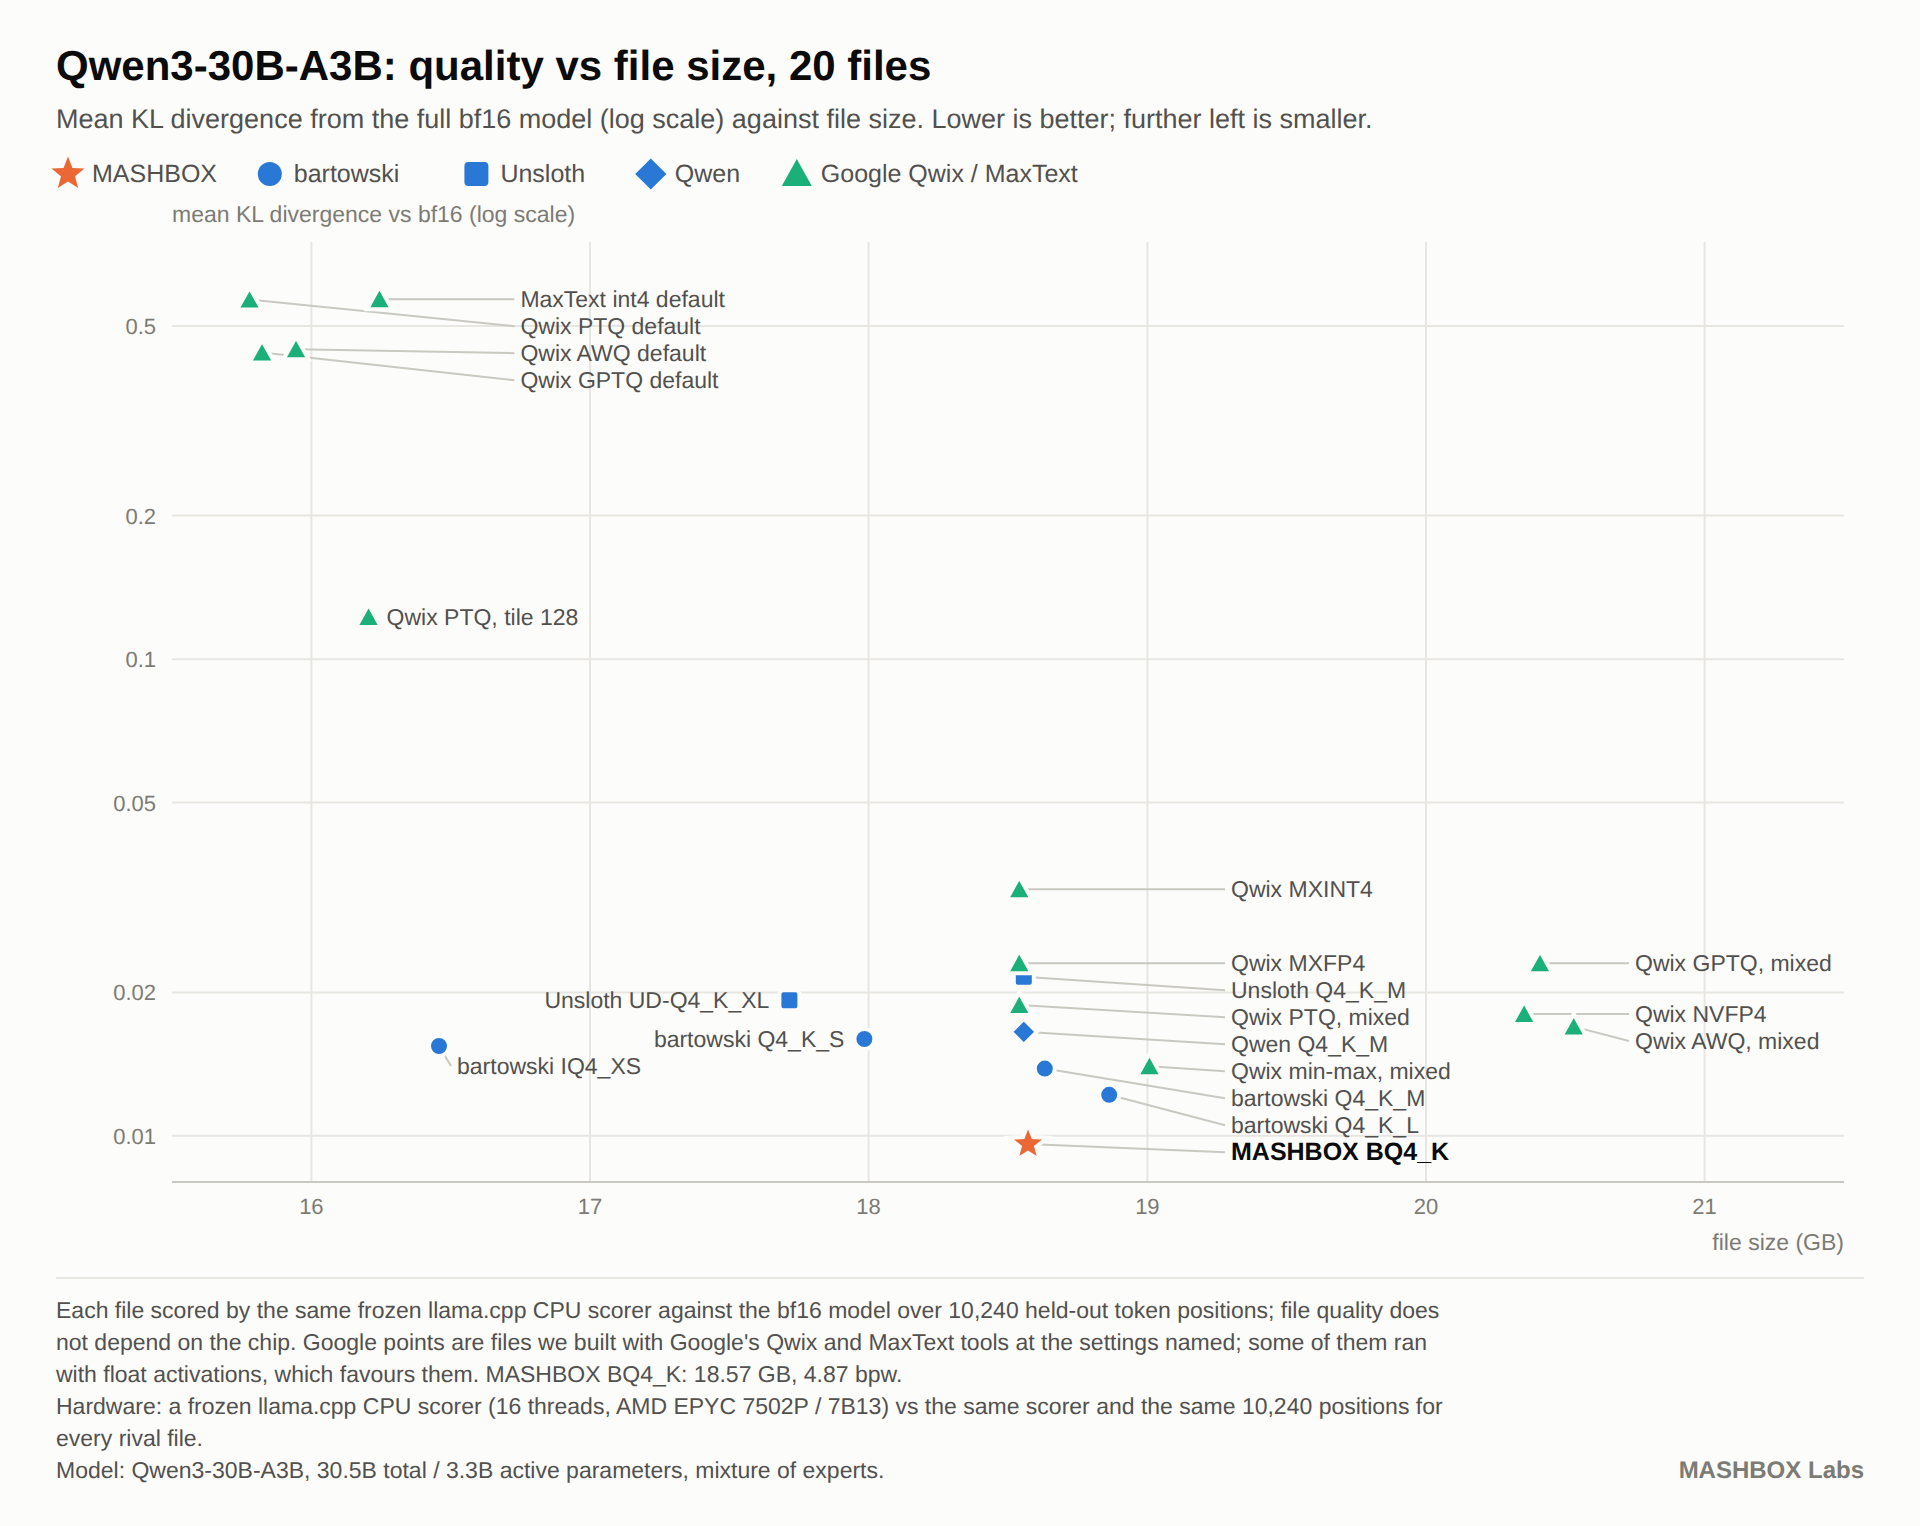
Qwen3-30B-A3B is not in this package: this chart compares quantized files of it, each scored the same way.
What you get
- One command per model.
mashbox run <model>downloads the weights, checks every file's sha256, loads the model and serves it. - Fits on fewer chips. Qwen3.8-27B runs on a single TPU v6e chip (32 GB) from a 26.94 GB weights file at 8.01 bits per weight, with 99.72% top-1 agreement against Qwen's own bf16 weights.
- Fast starts. Models ship their compiled TPU kernels, and Qwen3.8-27B also ships a precompiled compile cache for TPU v6e, so a start skips compiling: Qwen3.8-27B on TPU v6e-1 is ready in 69.6 s with it, 326.6 s without it.
- An OpenAI-compatible server for the language models, with batching: 8 requests at once share the chip.
- Works with Claude Code, Codex and Pi. The server also speaks the Anthropic Messages and OpenAI Responses APIs, so coding agents can use a model you serve as their LLM: Use with coding agents.
- Docs for coding agents. AGENTS.md gives an agent the rules and the steps to set up a chip, run a model and delete the chip; llms.txt lists the docs.
- Named files. Every weights file on Hugging Face is named by its type (for example
Qwen3.8-27B-BQ8_R.bshj), with size, bits per weight and measured quality next to it.
TPU v6e and v5e
| TPU v6e | TPU v5e | |
|---|---|---|
| Memory per chip | 32 GB | 16 GB |
| Memory bandwidth per chip | 1,638 GBps | 800 GiBps |
| Peak bf16 per chip | 918 TFLOPs | 197 TFLOPs |
| Peak int8 per chip | 1,836 TOPs | 393 TOPs |
| Create with | --accelerator-type=v6e-1 --version=v2-alpha-tpuv6e |
--accelerator-type=v5litepod-1 --version=v2-alpha-tpuv5-lite |
| Zones to try first | us-east5-b, europe-west4-a | us-central1-a |
v6e is the default. A model too big for one v5e chip (16 GB) splits across the 4 chips of a v5e-4 when its row says so; the models table says which chips each model runs on. Specs from Google's v6e and v5e pages. More in docs/chips.md.
TPU v6e (one chip and a v6e-4) against one NVIDIA H100 at Google Cloud list prices, with the memory bandwidth of each and the cost per 1M output tokens of Qwen3.8-27B (27B parameters, dense): TPU or GPU: price and bandwidth.
Open code, compiled kernels
The source of the model ports, CLI, runtime, demo apps and docs is in this repo, under Apache-2.0. The TPU kernels (our Culet kernels) ship compiled, as files that mashbox run fetches and checks by itself, with a precompiled compile cache where we built one; Install says where each kernel package comes from. Models that list plain JAX as tested also run without them, slower. The compiled files are under the MASHBOX Kernel Licence: free for personal use, research and evaluation, and for any use by companies under US$1M annual revenue. Larger companies in production: hello@mashbox.gg.
Coding agents
Use a model as your agent's LLM. Claude Code, Codex and Pi work with every LLM that mashbox run serves: start the server, open the tunnel, set the agent's base URL. Settings for each agent and measured results: Use with coding agents.
Let an agent set it up. AGENTS.md gives an agent the rules and the steps, from a Google account to a run and a deleted chip, and tells it to ask you before anything that costs money. llms.txt lists the docs.
Community and links
| Docs | mashbox.gg/docs |
| Models and weights | huggingface.co/mashbox-labs |
| News | x.com/mashboxgg |
| Bugs and model requests | GitHub issues, see CONTRIBUTING.md |
| Security reports | SECURITY.md |
| Companies | hello@mashbox.gg |
Licence
Our code is under the Apache License 2.0. The compiled kernels and compile cache are under the MASHBOX Kernel Licence. Model weights keep each model's own licence, shown on its Hugging Face card and kept unchanged in licenses/. Details: docs/licence.md.
Citation
@software{mashbox,
  author = {{MASHBOX Labs}},
  title = {mashbox: open models that run faster and cheaper},
  url = {https://github.com/mashbox-labs/mashbox},
  year = {2026}
}
Thank you
- Tencent Hunyuan for Hy-Nomas and Qwen for Qwen3.8-27B, and for releasing their weights.
- The JAX and Pallas teams, and Google Cloud TPU.
- llama.cpp and the ggml authors for GGUF; mashbox reads GGUF files with their
ggufpackage (GGUF files). - Hugging Face for hosting the weights and uv for a one-line Python 3.12.
1 maintainer

Metadata
1 maintainer
Release files for mashbox 0.1.12
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| mashbox-0.1.12.tar.gz | 770.3 kB | Without provenance | Details for mashbox-0.1.12.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| mashbox-0.1.12-py3-none-any.whl | Python 3 | none | any | Details for mashbox-0.1.12-py3-none-any.whl |
Total release size: 1.6 MB
Release files / mashbox-0.1.12.tar.gz
| Download URL | mashbox-0.1.12.tar.gz |
|---|---|
| Size | 770.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
65368143cc2010b158293d8a8c36dc53e0df1764aaedad441e9b539cdaf5479c
|
|
BLAKE2b-256 checksum How to use checksums |
ad40a48f034b5708dcb39e128cdc2f135e5c1f424f62059876c3f8870fc50634
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / mashbox-0.1.12-py3-none-any.whl
| Download URL | mashbox-0.1.12-py3-none-any.whl |
|---|---|
| Size | 834.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e3ae4c09d066ab3bb3d2634ec48f3bb9935630d53d7d3483251d860ca15eb8fe
|
|
BLAKE2b-256 checksum How to use checksums |
ab9b09cbe10ad3ba97ab15511f28ddfa551589fe387fc18fb16c49bd29321463
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Security for mashbox 0.1.12
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














