
MASHBOX Labs makes open models run faster and cheaper on TPUs and accelerated hardware, as well as exploring the future of the intersection of AI and gaming.
Quickstart • Models • Docs • Hugging Face • Coding agents

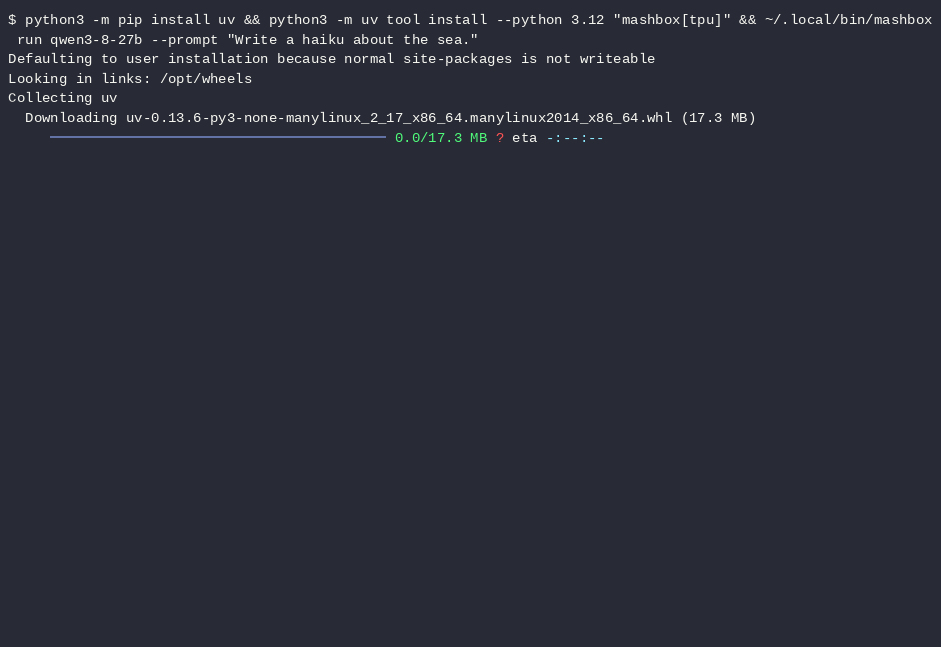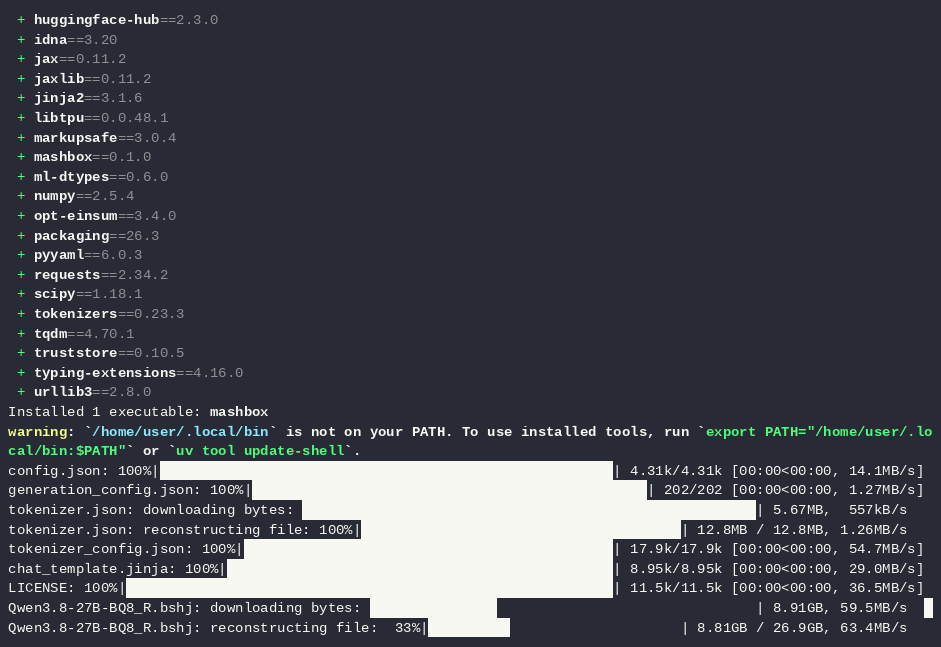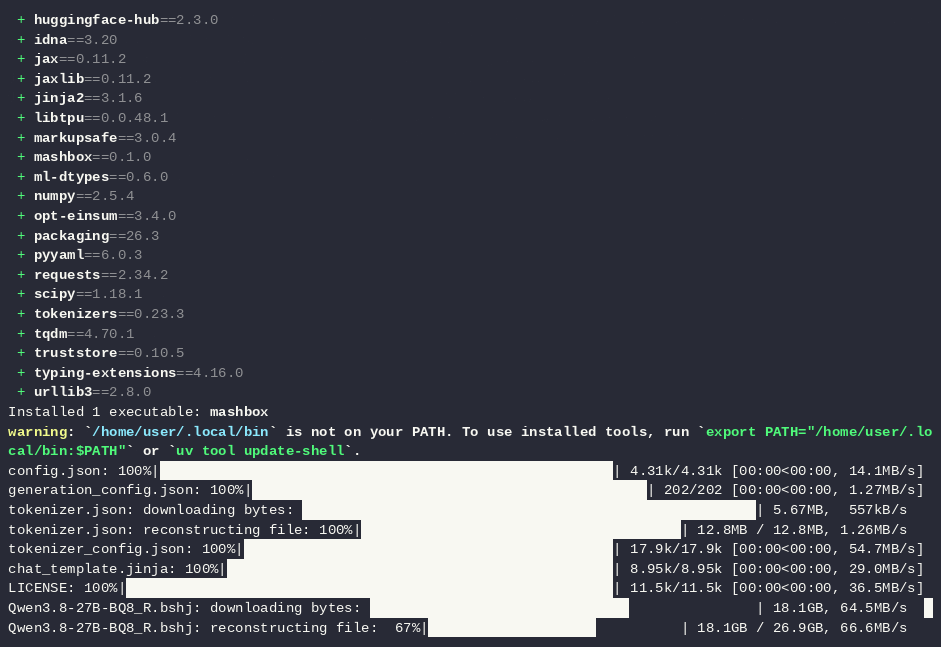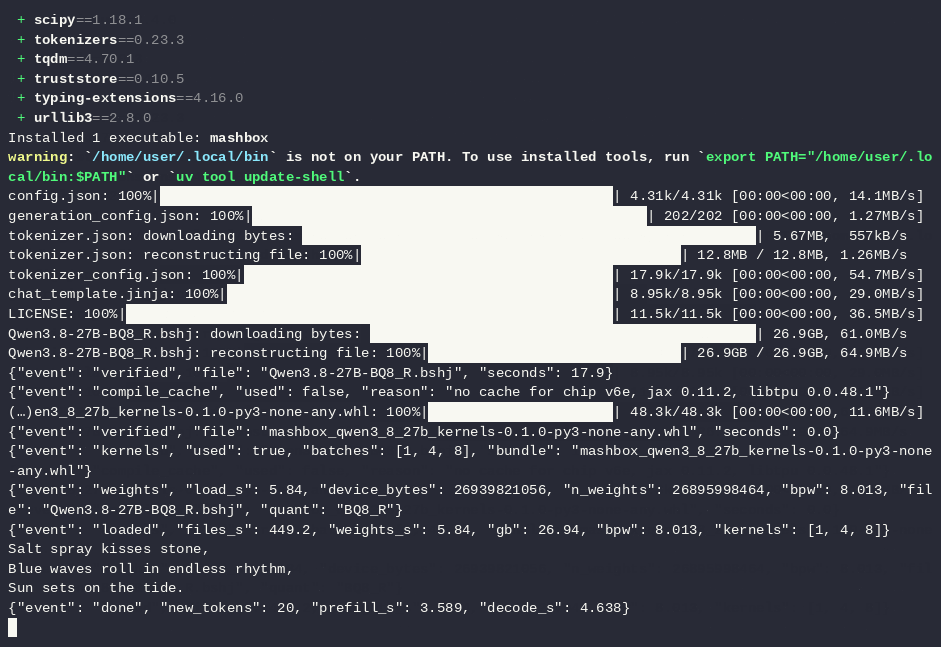
Qwen3.8-27B on one TPU v6e chip: first-time install to first answer (sped up 10x).
Quickstart
From your own machine, with the Google Cloud CLI set up (docs/google-cloud.md does that from a new Google account). This runs Qwen3.8-27B on one TPU v6e chip:
gcloud compute tpus tpu-vm create mashbox-1 --zone=us-east5-b --accelerator-type=v6e-1 --version=v2-alpha-tpuv6e
gcloud compute tpus tpu-vm ssh mashbox-1 --zone=us-east5-b --command='python3 -m pip install uv && python3 -m uv tool install --python 3.12 "mashbox[tpu]" && ~/.local/bin/mashbox run qwen3-8-27b --prompt "Write a haiku about the sea."'
gcloud compute tpus tpu-vm delete mashbox-1 --zone=us-east5-b --quiet
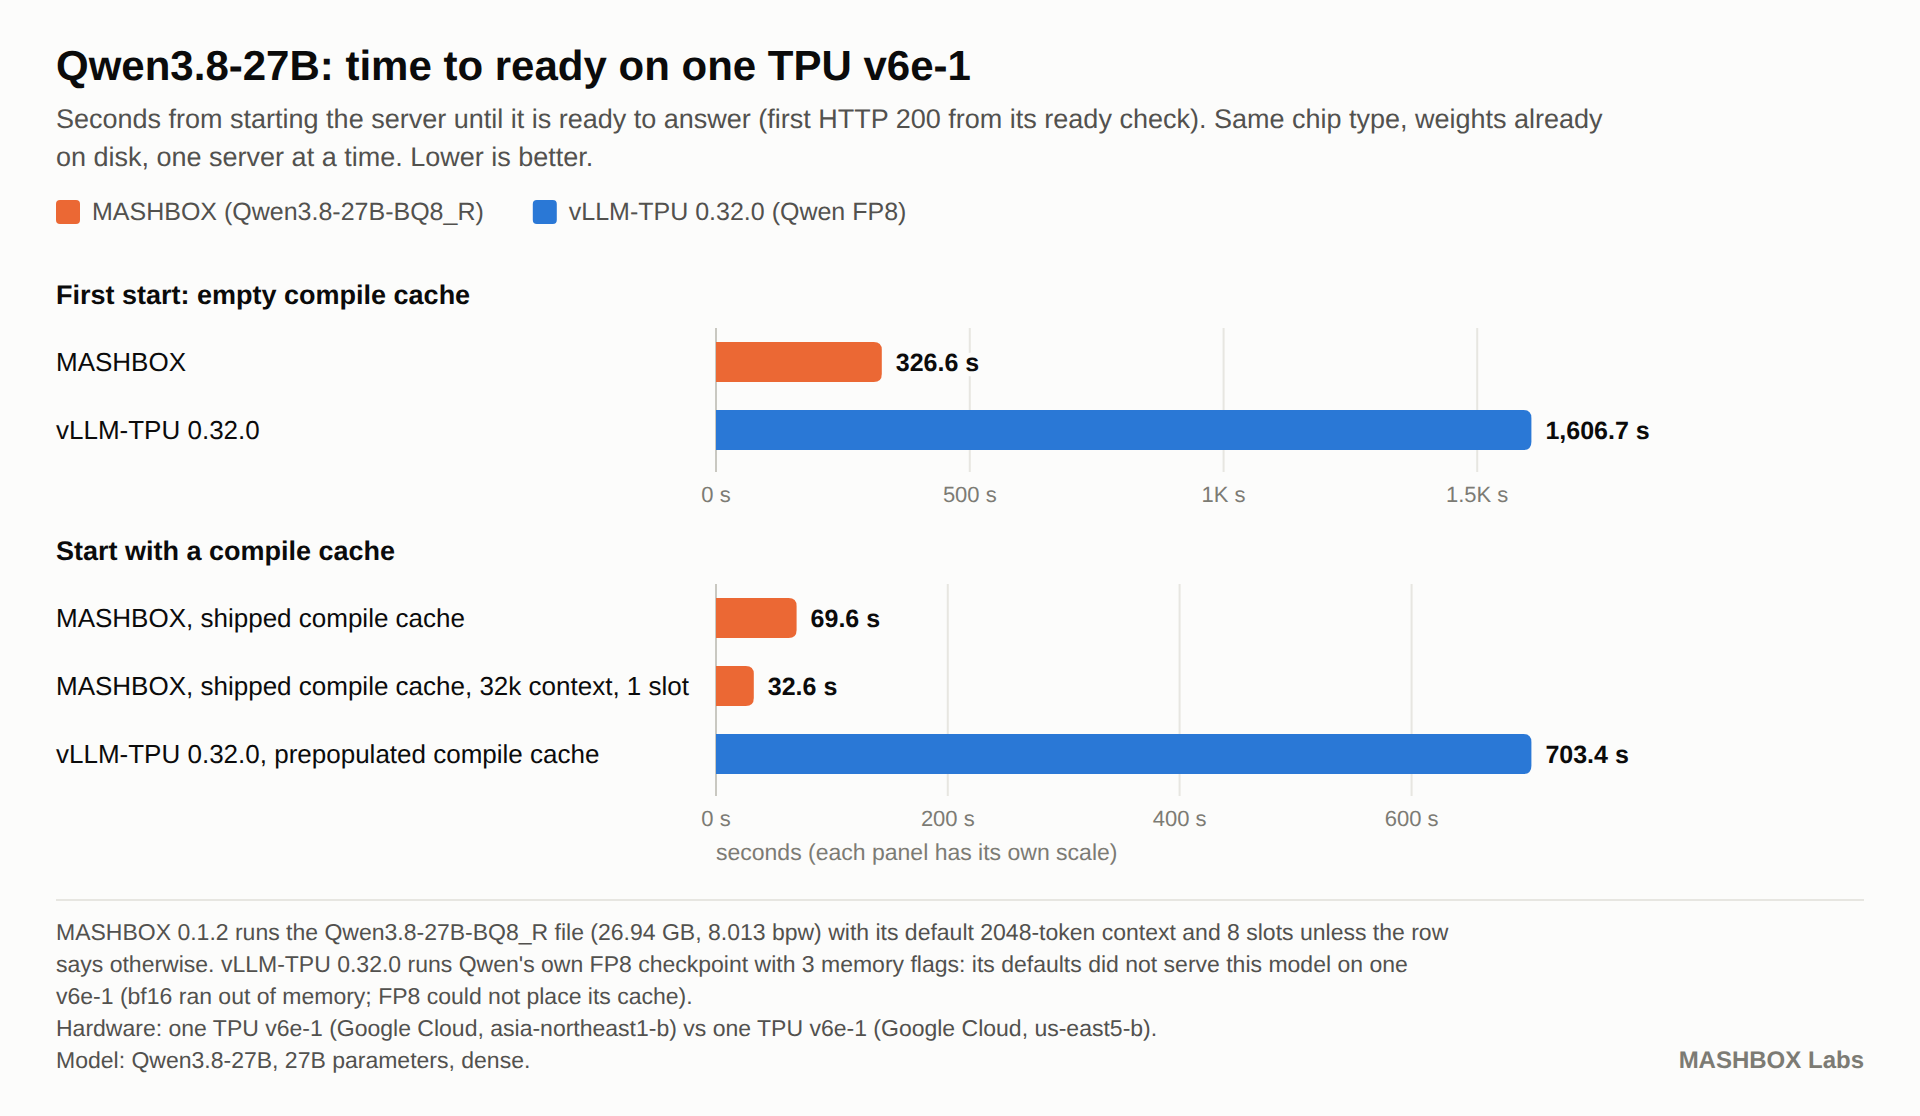
The chip's system Python is 3.10 and JAX for TPU needs 3.12, so the second line installs uv, which brings its own Python 3.12 and puts the mashbox command in ~/.local/bin. The first run downloads the 26.9 GB weights file and the compile cache; with them on disk, the server on a TPU v6e-1 is ready in 69.6 s. If the create command says the zone has no capacity, use another zone from step 6 of the setup guide in all three lines.
The chip bills from create to delete: one TPU v6e chip is $2.70 an hour at Google's on-demand list price. To serve Qwen3.8-27B with an OpenAI-compatible API instead, see docs/models/qwen3-8-27b.md.
Models
| Model | What it does | Chips | Measured | Weights |
|---|---|---|---|---|
| Hy-Nomas by Tencent Hunyuan |
World model: text and movement keys in, video out | TPU v5e: Not supported TPU v6e (v6e-1): One chip: the full pipeline fits on a single TPU v6e chip (32 GB), 2.46 s of compute per second of video. This version of mashbox run starts on a v6e-4TPU v5p slice (v5p-8): Not supported TPU v6e slice (v6e-4): Supported |
Compute per second of video, quality preset, Tencent decoder, 1.00 = real time: 1.045 s (TPU v6e-4) Compute per second of video, quality preset, MASHBOX Fast decoder: 0.689 s (TPU v6e-4) |
Hy-Nomas-TPU |
| Qwen3.8-27B by Qwen |
LLM: text in, text out | TPU v5e (v5e-4): Supported TPU v6e (v6e-1): Supported TPU v5p slice (v5p-8): Not supported TPU v6e slice (v6e-4): Supported |
38.1 vs 31.4 tok/s vs vLLM on the same chip, 1 request at a time; 326.6 vs 1,606.7 s first start to ready, weights on disk, empty compile caches, vs vLLM on the same chip type (TPU v6e-1). All results | Qwen3.8-27B-TPU |
Every number names the chip it was measured on; each model's guide has all its results. Options for any model: ~/.local/bin/mashbox run <model> --help.
Results
Each chart names the hardware on both sides.
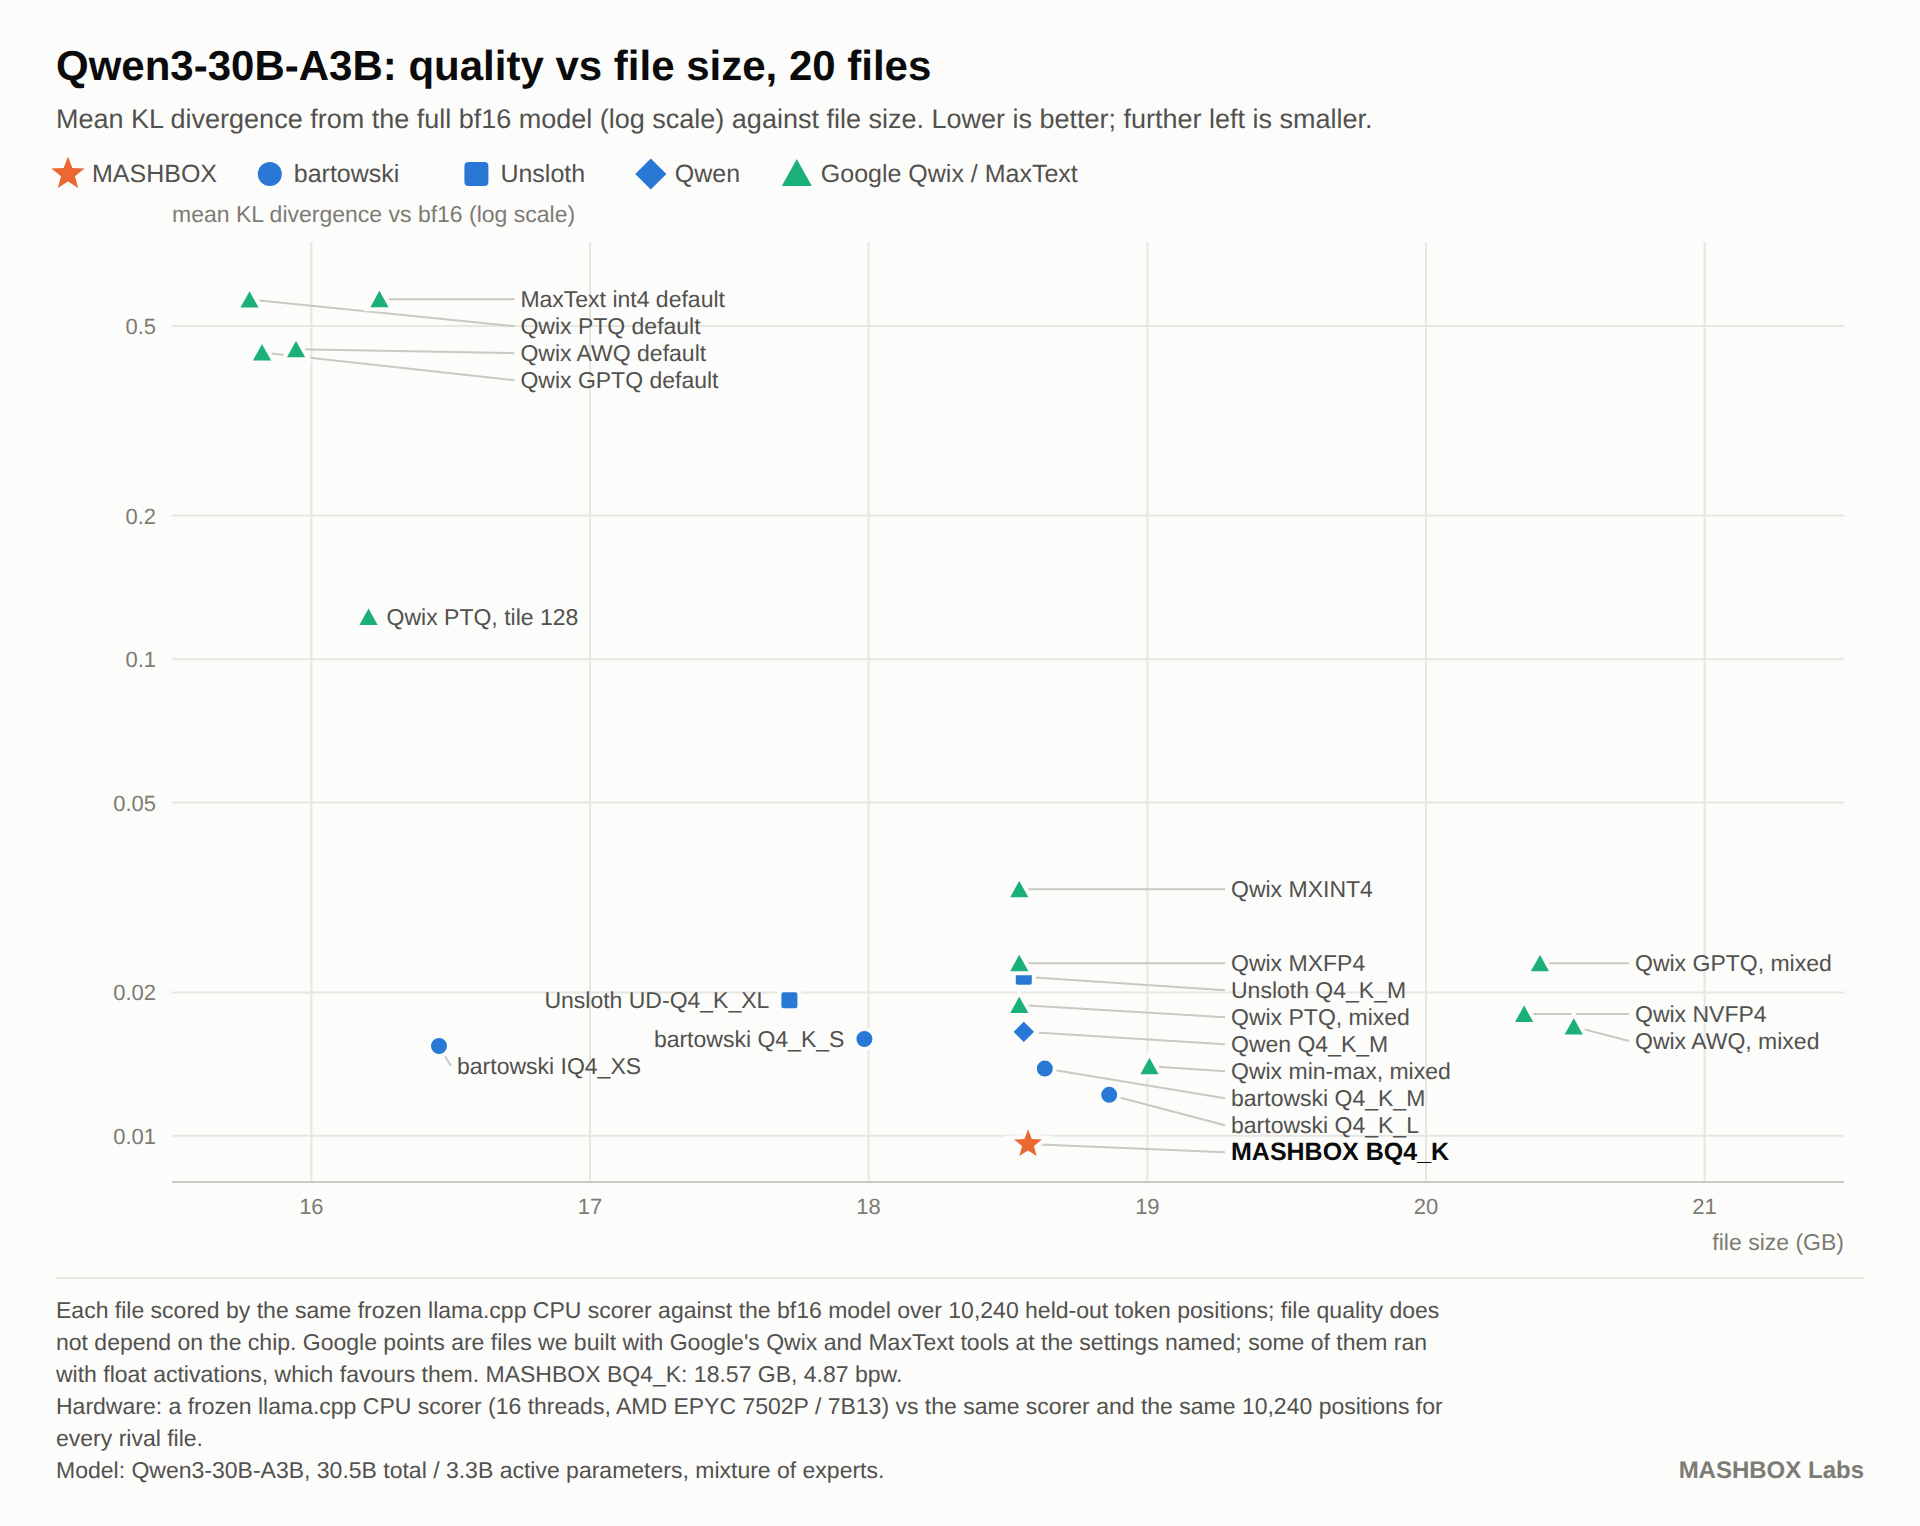
Qwen3-30B-A3B is not in this package: this chart compares quantized files of it, each scored the same way.
What you get
- One command per model.
mashbox run <model>downloads the weights, checks every file's sha256, loads the model and serves it. - Fits on fewer chips. Qwen3.8-27B runs on a single TPU v6e chip (32 GB) from a 26.94 GB weights file at 8.01 bits per weight, with 99.72% top-1 agreement against Qwen's own bf16 weights.
- Fast starts. Models ship their compiled TPU kernels, and Qwen3.8-27B also ships a precompiled compile cache for TPU v6e, so a start skips compiling: Qwen3.8-27B on TPU v6e-1 is ready in 69.6 s with it, 326.6 s without it.
- An OpenAI-compatible server for the language models, with batching: 8 requests at once share the chip.
- Works with Claude Code, Codex and Pi. The server also speaks the Anthropic Messages and OpenAI Responses APIs, so coding agents can use a model you serve as their LLM: Use with coding agents.
- Docs for coding agents. AGENTS.md gives an agent the rules and the steps to set up a chip, run a model and delete the chip; llms.txt lists the docs.
- Named files. Every weights file on Hugging Face is named by its type (for example
Qwen3.8-27B-BQ8_R.bshj), with size, bits per weight and measured quality next to it.
TPU v6e and v5e
| TPU v6e | TPU v5e | |
|---|---|---|
| Memory per chip | 32 GB | 16 GB |
| Memory bandwidth per chip | 1,638 GBps | 800 GiBps |
| Peak bf16 per chip | 918 TFLOPs | 197 TFLOPs |
| Peak int8 per chip | 1,836 TOPs | 393 TOPs |
| Create with | --accelerator-type=v6e-1 --version=v2-alpha-tpuv6e |
--accelerator-type=v5litepod-1 --version=v2-alpha-tpuv5-lite |
| Zones to try first | us-east5-b, europe-west4-a | us-central1-a |
v6e is the default. A model runs on v5e when its weights and working memory fit in 16 GB; the models table says which chips each model runs on. Specs from Google's v6e and v5e pages. More in docs/chips.md.
TPU v6e (one chip and a v6e-4) against one NVIDIA H100 at Google Cloud list prices, with the memory bandwidth of each and the cost per 1M output tokens of Qwen3.8-27B (27B parameters, dense): TPU or GPU: price and bandwidth.
Open code, compiled kernels
The source of the model ports, CLI, runtime, demo apps and docs is in this repo, under Apache-2.0. Each model ships with its own compiled TPU kernels (our Culet kernels) and, where we built one, a precompiled compile cache, only what that model needs: mashbox run downloads them from the model's Hugging Face repo and checks them against the sha256 in models.json. Models that list plain JAX as tested also run without them, slower. The compiled files are under the MASHBOX Kernel Licence: free for personal use, research and evaluation, and for any use by companies under US$1M annual revenue. Larger companies in production: hello@mashbox.gg.
Coding agents
Use a model as your agent's LLM. Claude Code, Codex and Pi work with every LLM that mashbox run serves: start the server, open the tunnel, set the agent's base URL. Settings for each agent and measured results: Use with coding agents.
Let an agent set it up. AGENTS.md gives an agent the rules and the steps, from a Google account to a run and a deleted chip, and tells it to ask you before anything that costs money. llms.txt lists the docs.
Community and links
| Docs | mashbox.gg/docs |
| Models and weights | huggingface.co/mashbox-labs |
| News | x.com/mashboxgg |
| Bugs and model requests | GitHub issues, see CONTRIBUTING.md |
| Security reports | SECURITY.md |
| Companies | hello@mashbox.gg |
Licence
Our code is under the Apache License 2.0. The compiled kernels and compile cache are under the MASHBOX Kernel Licence. Model weights keep each model's own licence, shown on its Hugging Face card and kept unchanged in licenses/. Details: docs/licence.md.
Citation
@software{mashbox,
  author = {{MASHBOX Labs}},
  title = {mashbox: open models that run faster and cheaper},
  url = {https://github.com/mashbox-labs/mashbox},
  year = {2026}
}
Thank you
- Tencent Hunyuan for Hy-Nomas and Qwen for Qwen3.8-27B, and for releasing their weights.
- The JAX and Pallas teams, and Google Cloud TPU.
- llama.cpp and the ggml authors for GGUF; mashbox reads GGUF files with their
ggufpackage (GGUF files). - Hugging Face for hosting the weights and uv for a one-line Python 3.12.
1 maintainer

Metadata
1 maintainer
Release files for mashbox 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| mashbox-0.1.3.tar.gz | 451.8 kB | Without provenance | Details for mashbox-0.1.3.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| mashbox-0.1.3-py3-none-any.whl | Python 3 | none | any | Details for mashbox-0.1.3-py3-none-any.whl |
Total release size: 945.2 kB
Release files / mashbox-0.1.3.tar.gz
| Download URL | mashbox-0.1.3.tar.gz |
|---|---|
| Size | 451.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c48890788ac9efea061ecde013a4fa0588ab5777ba920de9164c47e63c6abedb
|
|
BLAKE2b-256 checksum How to use checksums |
1e4e48566a98987dcc10dc4475030faec987330d1ec6493bf8e25df9ed52f5cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / mashbox-0.1.3-py3-none-any.whl
| Download URL | mashbox-0.1.3-py3-none-any.whl |
|---|---|
| Size | 493.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
30dad865208bd8c4ad8f8e60c4f027960e777ae68c24c8348052c69c23d39252
|
|
BLAKE2b-256 checksum How to use checksums |
629e3cb19a15356e658fb15687d7c14e9f004e238e92bfbd22dfe5b7d147d36b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Security for mashbox 0.1.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














