
mlx-quant-fidelity

You install a 4-bit model. It loads, it answers, the prose reads fine. Nothing in the logs suggests otherwise.
On Qwen2.5-7B with a 4-bit KV cache active from the first token, 99% of next-token choices come out different from the same model running a full-precision cache. Quantizing from token zero is the harshest way to measure, and it is not what you get by default: mlx-lm's own generate command leaves the cache unquantized until token 5000. Nothing about installing that model, or setting that flag, surfaces a number like 99%. A quantization failure does not announce itself, and file size tells you nothing about it.
mlx-quant-fidelity runs the same text through your model twice, once quantized and once not, and reports how far apart the two ended up: KL divergence, top-token flip rate, perplexity delta. It covers both KV-cache quantization and weight quantization.
The CUDA and GGUF world has had this for years — llama.cpp's --kl-divergence-base, EleutherAI's lm-evaluation-harness. MLX had nothing, and neither of those covers the KV-cache and attention angle.
Try it in one command
pip install mlx-quant-fidelity
mlx-quant-fidelity kv mlx-community/Llama-3.2-3B-Instruct-4bit --kv-bits 8 --max-chunks 100
# KV-fidelity: `mlx-community/Llama-3.2-3B-Instruct-4bit` @ 8-bit (group 64)

**Verdict:** good · **mode:** stress (quantize_start=0)

| metric | value |
|---|---|
| KL mean | 0.0002 nats |
| KL median | 0.0001 nats |
| KL p99 | 0.0015 nats |
| KL max | 0.1129 nats |
| flip rate | 0.0065 |
| perplexity Δ | +0.0054 (17.722 → 17.728) |

Measured on **wikitext-2-raw/test**, 51100 positions across 100 chunks of length 512 (tokenizer `mlx-community/Llama-3.2-3B-Instruct-4bit`).

...
That model at 8-bit KV clears the good tier on this corpus. Apple Silicon, Python 3.11+.
Common options
--kv-bits/--kv-group-size— the KV configuration to score, default4/64. The4:32,4:64shorthand incompare kv --configsisbits:group_size.--kv-method—stock(default) reads--kv-bits/--kv-group-sizedirectly.turboquant,turboquant-vonly, andaffinealso take a colon-delimited spec string in place of a bare name:turboquant:bits[:seed],turboquant-vonly:v_bits[:seed](K stays fp16; only V quantizes), andaffine:k_bits:v_bits[:group_size](an independent per-side K/V bit width no shipped cache runs — see docs/measurement-principles.md).compare kv --configsmixes any of these into one list, e.g.8:64,turboquant:4,affine:8:4.--kv-seedsets the TurboQuant rotation seed (default 42, must be ≥ 1) for the flag-based--kv-method turboquantand--kv-method turboquant-vonlyforms.--control— stock only. Runs a third, quantizer-only forward (dequantize on fetch, standard SDPA, the same bits and group size) alongside the deployed path, so a stock report carries both numbers.compare kvalways ranks every method on the quantizer-only number and runs this control lane for stock automatically — see docs/ranking-principles.md.--max-chunks N— score only the first N corpus chunks. Every number in this README uses--max-chunks 100; leave it off and the run covers the whole WikiText-2 test split.--chunk-length N— the scoring window, default 512, hard ceiling 4096.--quantize-start N—0for stress mode, the default; any N above 0 for deployment mode.--format json|md|badge—mdby default.jsonis the machine-readable form the reports under_artifacts/samples/are written in, andbadgeworks onweightsas well askv. The twocomparesubcommands takejsonandmdonly.repo@revisiononweightsandcompare weightspins a Hugging Face revision inline; an inline pin wins over--quant-revision/--reference-revision.kvandcompare kvkeep--model-revision.--allow-custom-code— let a repo whoseconfig.jsonnames amodel_filerun that file. mlx-lm executes it on load, so the tool refuses such a repo unless you pass this flag. Only use it for repos you trust.--worker-timeout SECONDS—compare weightsonly: the wall-clock limit for each target's worker, default 21600 (six hours;0turns it off). A worker that runs over it becomes a failed row; raise the limit for full-corpus runs on large models.
Both cost something to run. The quickstart pulls roughly 1.8 GB of weights plus the corpus on first use, and a wider window costs memory rather than time: the 4096-token run further down peaks at 13.53 GiB, so it will not fit a 16 GB machine. docs/measurement-principles.md lists the measured peak for every window length and explains the pre-flight that refuses one too large for your device.
Does this apply to you?
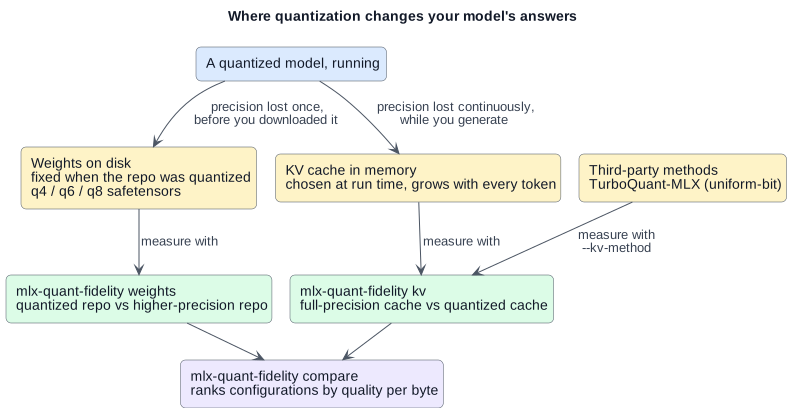
Precision gets lost in two places — on disk and in the running cache — and each needs its own command.
"I'm about to run a quantized model and I want to know what I gave up."
mlx-quant-fidelity kv mlx-community/Llama-3.2-3B-Instruct-4bit --kv-bits 4
mlx-quant-fidelity weights mlx-community/Llama-3.2-3B-Instruct-4bit --reference mlx-community/Llama-3.2-3B-Instruct-bf16
"I need this model to fit in my RAM and I don't know which setting to cut."
mlx-quant-fidelity compare kv <model> --sweep --max-kv-bytes-per-token 200
Builds the whole bits-by-group-size grid from the model's config.json, drops anything over your memory budget, and ranks what's left by quality per byte. Building the grid downloads that file and nothing else.
"I publish quantized models and I want to show they're good."
mlx-quant-fidelity kv <model> --kv-bits 8 --format badge
Prints one shields.io line for your model card. Green, yellow, or red, with the bit width, corpus, chunk length, and mode baked into the message, so two badges from the same model at different configurations are distinguishable at a glance.
Badge output
--format badge replaces the whole report with one line:

Green for good, yellow for marginal, red for bad. Threshold values and the color map are in docs/threshold-policy.md. A hybrid model measured on only some of its layers carries partial 4/26 layers in the badge message, so the badge can't be read as covering the whole cache.
What it found
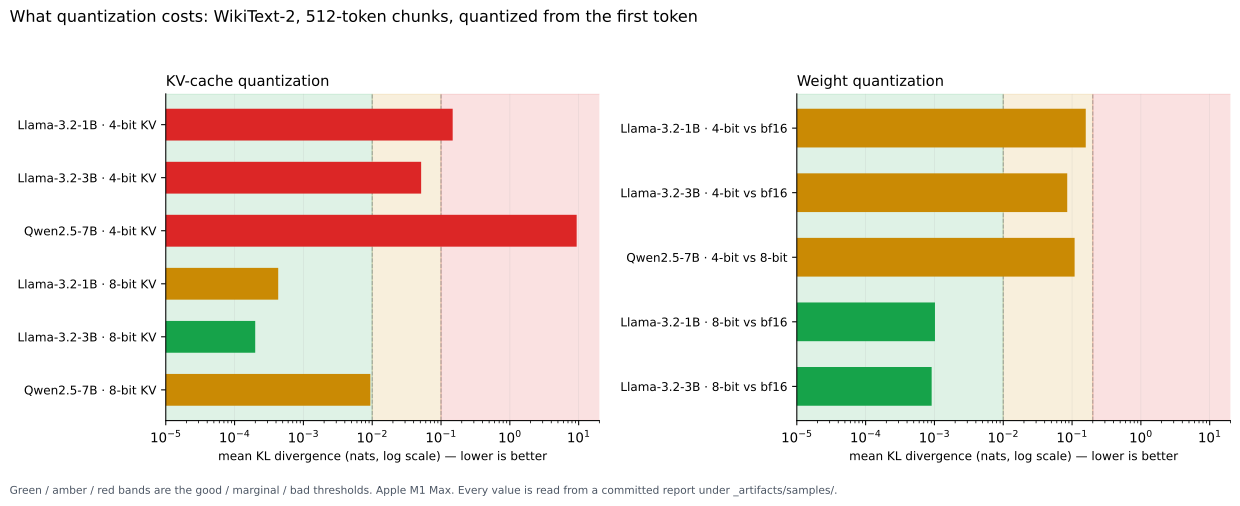
Eight-bit costs little everywhere we measured it. Four-bit is a real trade, and on one checkpoint it collapses.
Bar length is mean KL divergence and nothing else. Bar color is the overall verdict, which also weighs the p99 tail and the top-token flip rate, so two of the three 8-bit KV bars sit in the green band and are still amber, and the 4-bit Llama-3.2-3B bar is red inside the amber band. docs/threshold-policy.md lists the ceilings. The right panel gets its own section further down.
KV cache, M1 Max, WikiText-2 test (100 chunks of 512 tokens), stress mode (quantize from token 0). Reproduce any row with mlx-quant-fidelity kv <model> --kv-bits <bits> --max-chunks 100; the full committed reports are under _artifacts/samples/.
| Model | KV bits | KL mean (nats) | flip rate | verdict |
|---|---|---|---|---|
| Llama-3.2-1B | 4 | 0.148 | 0.20 | bad |
| Llama-3.2-1B | 8 | 0.0004 | 0.013 | marginal |
| Llama-3.2-3B | 4 | 0.051 | 0.11 | bad |
| Llama-3.2-3B | 8 | 0.0002 | 0.007 | good |
| Qwen2.5-7B | 4 | 9.36 | 0.99 | bad |
| Qwen2.5-7B | 8 | 0.009 | 0.032 | marginal |
8-bit KV costs little on all three models, though only Llama-3.2-3B clears the good tier outright. 4-bit is another matter, and Qwen2.5-7B at 4-bit in stress mode falls apart: nearly every token flips. This measurement establishes a checkpoint-specific failure, not its cause. mlx-lm's own generate command leaves the cache unquantized until token 5000, so those positions are computed while attention uses a full-precision cache. At the boundary, however, mlx-lm converts the entire stored prefix too. The Python API defaults differently: pass kv_bits to mlx_lm.generate and quantization starts at token 0 unless you also set quantized_kv_start. Run the tool first and you see the fidelity risk before deployment.
Does drift change with position depth?
Every stress-mode report already breaks mean and p99 KLD down by position depth within a chunk. --chunk-length 4096 widens the window so those buckets span more positions.
mlx-quant-fidelity kv mlx-community/Llama-3.2-1B-Instruct-4bit \
  --kv-bits 4 --chunk-length 4096 --max-chunks 12
Llama-3.2-1B at 4-bit KV, M1 Max, WikiText-2 test (12 chunks of 4096 tokens, the same ~50k-token corpus coverage as the 512-token samples above):
| positions | KL mean | KL p99 |
|---|---|---|
| 0-510 | 0.1485 | 0.9470 |
| 511-1022 | 0.1455 | 0.8659 |
| 1023-1534 | 0.1534 | 0.9329 |
| 1535-2046 | 0.1479 | 0.9568 |
| 2047-2558 | 0.1439 | 0.9048 |
| 2559-3070 | 0.1572 | 0.9835 |
| 3071-3582 | 0.1537 | 0.9757 |
| 3583-4094 | 0.1554 | 1.0237 |
On this model and corpus, drift at position 4000 looks about the same as drift at position 60 — quantization cost isn't building up across the window at these lengths. That's a narrower claim than it might sound: 4096 tokens is short next to the context lengths where other work has found KV-quantization drift growing with depth. docs/measurement-principles.md covers the measured memory cost of longer windows and why the comparison to longer-context findings elsewhere isn't apples to apples. The full report, including the 8-bit KV counterpart, is under _artifacts/samples/ (llama-3.2-1b-4bit-kv4-cl4096.md, llama-3.2-1b-4bit-kv8-cl4096.md).
How much does weight quantization cost?
Same corpus and recipe, but the comparison is now a quantized model repo against a higher-precision reference repo. Reproduce any row with mlx-quant-fidelity weights <quant> --reference <reference> --max-chunks 100; the committed reports are under _artifacts/samples/weights/.
These five rows were captured with the 0.5.0 report format and are kept as recorded, so they predate the measured-geometry column in the comparison below.
| Model | quant | reference | KL mean (nats) | flip rate | perplexity Δ | verdict |
|---|---|---|---|---|---|---|
| Llama-3.2-1B | 4-bit | bf16 | 0.158 | 0.21 | +3.5 | marginal |
| Llama-3.2-1B | 8-bit | bf16 | 0.001 | 0.023 | −0.01 | good |
| Llama-3.2-3B | 4-bit | bf16 | 0.085 | 0.15 | +1.4 | marginal |
| Llama-3.2-3B | 8-bit | bf16 | 0.0009 | 0.021 | 0.00 | good |
| Qwen2.5-7B | 4-bit | 8-bit | 0.109 | 0.16 | +0.9 | marginal |
8-bit weights are near-lossless: about 2% of top tokens flip and perplexity barely moves. Across these five rows, 4-bit flips 15 to 21% of top tokens and perplexity climbs by 0.9 to 3.5 points, worst on the smallest model here. The Qwen row compares 4-bit against 8-bit rather than bf16, so its drift is relative to an already-quantized reference, not full precision; the report records that the reference is 8-bit and says so in plain text. The verdict tiers are provisional, anchored to these q8 and q4 reference points on short prose rather than to downstream task accuracy.
Unlike the KV probe, both runs use standard attention, so the drift is the deployed quantized model's weight-quant cost with no quantized-attention kernel folded in. It does still include the quantized-matmul kernel's numerics, which is exactly what you run when you load the model.
One model, five quantizations
Qwen3-0.6B has a bf16 reference on the Hub and five quantized repos beside it, three of them at 4 bits. compare weights scores all five against that one reference:
| target | cost | KL mean | KL p99 | flip | bits/wt | verdict | frontier |
|---|---|---|---|---|---|---|---|
mlx-community/Qwen3-0.6B-4bit-DWQ |
335.5 MB | 0.3539 | 1.4570 | 0.2289 | 4.50 | bad | ✓ |
mlx-community/Qwen3-0.6B-4bit |
335.5 MB | 0.2538 | 1.5364 | 0.2586 | 4.50 | bad | ✓ |
mlx-community/Qwen3-0.6B-4bit-AWQ |
345.2 MB | 0.1608 | 1.1002 | 0.2117 | 4.63 | marginal | ✓ |
mlx-community/Qwen3-0.6B-6bit |
484.4 MB | 0.0213 | 0.1324 | 0.0781 | 6.50 | marginal | ✓ |
mlx-community/Qwen3-0.6B-8bit |
633.4 MB | 0.0040 | 0.0198 | 0.0331 | 8.50 | good | ✓ |
mlx-quant-fidelity compare weights \
  mlx-community/Qwen3-0.6B-4bit@73e3e38d981303bc594367cd910ea6eb48349da8 \
  mlx-community/Qwen3-0.6B-4bit-DWQ@e630d870397d5a2d95fe0c9075c6f499fc0fc5c8 \
  mlx-community/Qwen3-0.6B-4bit-AWQ@3c064b3401d4a7d355262a1d518faa823a4d8f11 \
  mlx-community/Qwen3-0.6B-6bit@45d962b21b1e813c3e9a7f3505391e72e8daba1e \
  mlx-community/Qwen3-0.6B-8bit@11de96878523501bcaa86104e3c186de07ff9068 \
  --reference mlx-community/Qwen3-0.6B-bf16@42096995f6402fde107068cf530136fe64b604f8 \
  --max-chunks 100
Apple M1 Max, WikiText-2 test, 100 chunks of 512 tokens, peaking at 3.60 GiB across the five runs. The committed report is _artifacts/samples/compare/weight-qwen3-0.6b-ladder.md.
The plain -4bit repo and the -4bit-DWQ repo are the same size to within 36 bytes, and the metrics disagree about which of them is better. The -4bit-DWQ repo has the higher mean KL on this model and this corpus, 0.3539 against 0.2538, and the lower flip rate and p99 tail, with a smaller perplexity delta: +3.59 against +4.51. Ranking scores quality on mean KL alone, so on that axis the -4bit-DWQ repo is the worse of the two, and neither row is dominated: the -4bit-DWQ row stays on the frontier only on its 36-byte cost edge.
Of the three 4-bit repos, -4bit-AWQ is the best on every quality column and on perplexity delta (+3.23), and it stores 4.63 bits per weight rather than 4.50; its geometry has one module at group 32 where the other 196 use 64. Above 4 bits the drift falls away quickly: 6-bit is marginal and 8-bit good on this model and this corpus. The report does not know which of these repos was produced with learned scales or activation-aware scaling — mlx-lm records only the geometry — so the rows are labeled by repo, not by method.
Comparing quantizations
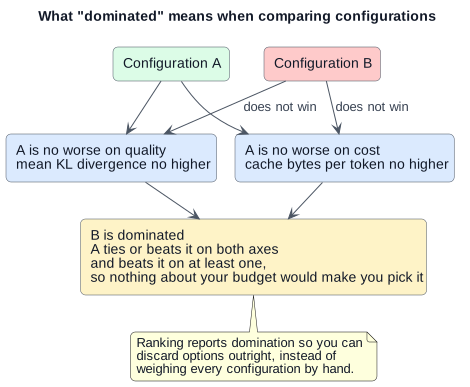
compare ranks a set of quantizations on a memory-normalized Pareto frontier: quality (mean KL divergence) on one axis, memory cost on the other. It identifies any configuration that another option on the list matches or beats on both axes and beats on at least one — those are dominated and you would never choose them.
# rank weight quantizations against a bf16 reference
mlx-quant-fidelity compare weights q4 q6 q8 --reference fp16

# rank KV configs on a single model
mlx-quant-fidelity compare kv <model> --configs 4:32,4:64,8:64

# or auto-generate the grid from the model's config.json instead of listing configs by hand
mlx-quant-fidelity compare kv <model> --sweep --max-kv-bytes-per-token 200
Add --max-kld 0.05 to get the cheapest configuration whose mean KLD stays under a threshold, or --min-tier good to get the cheapest one that passes the good-tier verdict. --sweep builds the (bits × group-size) grid from the model's config alone, no weight download needed, and drops any combination that would crash the upstream KV cache implementation; --max-kv-bytes-per-token narrows that grid to configurations under a memory budget. Either way, skipped configurations are listed in the report rather than silently dropped. docs/ranking-principles.md explains how each axis is computed, what Pareto domination means in practice, and where the ranking has limits.
Measuring a third-party cache
The KV probe is not tied to mlx-lm's cache. --kv-method turboquant measures the
TurboQuant-MLX uniform-bit cache on the same
paired, teacher-forced, full-vocabulary yardstick, and compare kv ranks it against the stock
configurations memory-normalized. Install the pinned port first — the PyPI package named
turboquant-mlx is unrelated. The tool checks the install record before importing the port and accepts
only an https git install of this repository (a different commit is measured with a note in the
report); a PyPI, editable, SSH or fork install is refused on purpose:
pip install "turboquant-mlx @ git+https://github.com/arozanov/turboquant-mlx@6e928d715595dee9f6b6cc3968baa44e1f408d28"
mlx-quant-fidelity compare kv mlx-community/Llama-3.2-1B-Instruct-4bit --configs 8:64,4:64,turboquant:4,turboquant:3,turboquant-vonly:4,turboquant-vonly:3,affine:8:4,affine:8:2
With uv, uv sync --group turboquant installs the same pin.
# Quant comparison (kv) vs `mlx-community/Llama-3.2-1B-Instruct-4bit`

| target | cost | KL mean | KL p99 | flip | bundled KL | resident +/token | verdict | frontier |
|---|---|---|---|---|---|---|---|---|
| `turboquant:3` | 8.2 KB | 0.4229 | 2.3559 | 0.3259 | — | 65.5 KB | bad | ✓ |
| `4:64` | 9.2 KB | 0.1485 | 0.9571 | 0.2056 | 0.1477 | 0 B | bad | ✗ dominated by `turboquant:4` |
| `turboquant:4` | 9.2 KB | 0.0825 | 0.5663 | 0.1582 | — | 65.5 KB | bad | ✓ |
| `affine:8:2` | 11.3 KB | 0.2180 | 1.3105 | 0.2391 | — | 32.8 KB | bad | ✗ dominated by `turboquant:4` |
| `affine:8:4` | 13.3 KB | 0.0120 | 0.0818 | 0.0628 | — | 32.8 KB | bad | ✓ |
| `8:64` | 17.4 KB | 0.0004 | 0.0028 | 0.0121 | 0.0004 | 0 B | marginal | ✓ |
| `turboquant-vonly:3` | 36.9 KB | 0.0297 | 0.2025 | 0.0974 | — | 32.8 KB | bad | ✗ dominated by `affine:8:4` |
| `turboquant-vonly:4` | 37.4 KB | 0.0078 | 0.0520 | 0.0508 | — | 32.8 KB | bad | ✗ dominated by `8:64` |
Read this table with two things in mind. The KL mean column is quantizer-only for every row:
turboquant, turboquant-vonly, and affine dequantize on fetch and ride standard SDPA by
construction, and 4:64/8:64 ran a --control forward alongside their deployed path so stock
ranks on the same footing. Stock's own deployed-path number — mlx-lm's two-quantized-matmul
attention — is the bundled KL column instead; on this sample it barely differs from the
quantizer-only column (0.1477 vs 0.1485 for 4:64) — the two numbers land within about half a
percent of each other at this configuration and scale, not evidence that the kernel's own
contribution is small or zero in general (see
docs/measurement-principles.md).
And the cost column is stored bytes, not the memory a method's fetch path needs while it runs:
turboquant and its V-only variant keep full-precision dequantization buffers beyond what they
store, shown in resident +/token — turboquant-vonly's pinned port even stores an unused fp16
copy of V, so its stored bytes exceed a plain fp16 cache's even though V itself compresses (see
docs/ranking-principles.md). The
uniform-bit cache and its V-only variant are measured at the port's default seed; its asymmetric
and layer-adaptive configurations are not, and its make_adaptive_cache silently ignores the
documented k_bits/v_bits parameters at the pinned commit. affine:k:v measures an independent
per-side bit width that no shipped cache runs. Sample captured on Apple M1 Max, 32 GB, revision
08231374…, 100 chunks of 512 tokens, stress mode.
How it works
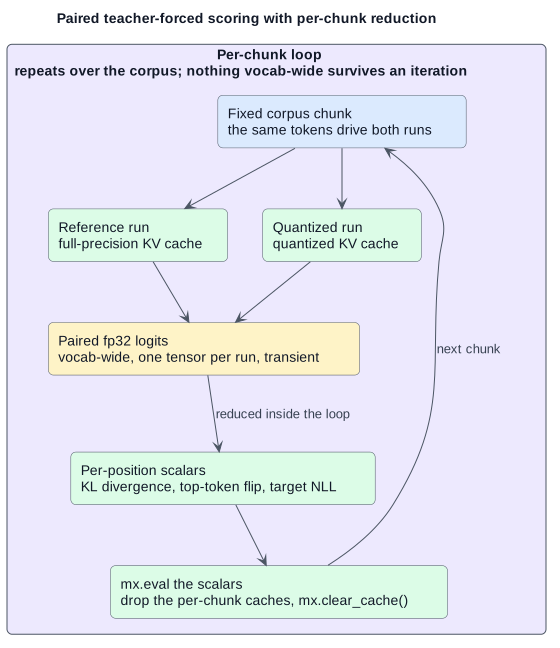
Teacher-forced scoring, not generation. For each fixed-length corpus chunk the model runs twice on the same tokens — once with a full-precision KV cache, once with a quantized one — and the two next-token distributions are compared position by position. Generation would let the runs diverge in their own inputs the moment quantization changed a sampled token, turning the measurement into trajectory drift instead of cache cost. Logits collapse to per-position scalars inside the chunk loop and are released before the next chunk, so a long corpus never holds full distributions in memory.
Every report records which of two modes produced it.
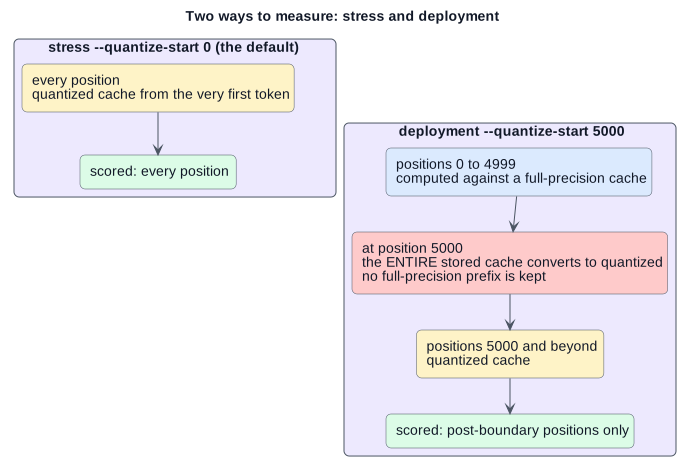
Stress mode (--quantize-start 0, the default) quantizes from token 0 — the harsh, apples-to-apples quantizer test. Deployment mode (--quantize-start N) computes the first N positions with a full-precision cache, then converts the entire stored cache and scores only the post-boundary region. That matches mlx-lm's --quantized-kv-start conversion behavior, which does not preserve a full-precision prefix in storage. docs/measurement-principles.md explains why deployment and stress drift need a matched comparison and why neither is a long-context deployment average.
A run that returns exactly zero drift raises instead of reporting a silent "perfect fidelity." That almost always means quantization never engaged, not that it was free.
The weight probe works the same way with two models instead of two caches: a quantized repo and a reference repo, scored on the same corpus tokens. Both config.json files are read before either model loads: a mismatched pair (a different architecture or vocabulary, or a "quantized" repo whose config declares no quantization) is refused there. A memory pre-flight then sizes the two models, from the local cache or from Hub metadata for a repo you haven't downloaded yet, adds the per-chunk logits, and refuses a pair too large for the device rather than risking a kernel panic. When neither source gives a size, the run goes ahead and the report says the pre-flight was skipped.
See docs/measurement-principles.md for the zero-probability policy, the exact-zero guard, and how perplexity delta relates to mean KLD.
What a fidelity number can't tell you
- A fidelity number is corpus- and context-length-specific. WikiText-2 at temperature 0 measures short-prose distributional drift; the paper this builds on, Accuracy Is Not All You Need, shows that under-predicts task-specific and long-context degradation. Every report records the corpus and the token count so the number is never read as a bare score.
- Perplexity delta is reported for continuity with llama.cpp. It is related to but distinct from mean KLD — it scores the realized next token and can diverge from full-vocabulary drift — so it is not independent corroboration.
- The KV probe's deployed-path drift bundles the quantizer's error with the quantized-attention kernel's numerics. That is the real end-to-end cost.
kv --control(stock only) measures the quantizer alone alongside it, andcompare kvalways ranks on that quantizer-only number — see docs/measurement-principles.md.
Python API
Each command has a function behind it that returns the same report object the CLI renders.
from mlx_quant_fidelity import measure_kv_fidelity

report = measure_kv_fidelity("mlx-community/Llama-3.2-3B-Instruct-4bit", kv_bits=8)
print(report.kl.mean, report.flip_rate, report.verdict)
from mlx_quant_fidelity import measure_weight_fidelity

# measure_weight_fidelity(quantized_repo, reference_repo)
report = measure_weight_fidelity(
    "mlx-community/Llama-3.2-3B-Instruct-4bit",  # quantized
    "mlx-community/Llama-3.2-3B-Instruct-bf16",  # reference
)
print(report.kl.mean, report.flip_rate, report.verdict)
Pass a method object to measure a cache other than mlx-lm's stock one. TurboQuant needs the pinned install described under Measuring a third-party cache; AffineKVMethod needs nothing extra.
from mlx_quant_fidelity import AffineKVMethod, TurboQuantKVMethod, measure_kv_fidelity

report = measure_kv_fidelity(
    "mlx-community/Llama-3.2-1B-Instruct-4bit",
    method=TurboQuantKVMethod(bits=4, seed=42),  # or AffineKVMethod(k_bits=8, v_bits=4)
)
print(report.kv_method, report.kl.mean, report.drift_footing)
compare_kv_fidelity and compare_weight_fidelity back the two compare subcommands and return a ComparisonReport. None of the Python functions print progress unless you pass a progress callback, and none of them start the memory watchdog described below.
Exit codes and safety
| code | meaning |
|---|---|
| 0 | the report was printed |
| 1 | compare measured no row at all (the report is still printed), or an unexpected internal error |
| 2 | a user error: a bad option, a missing or gated repo, no network, a refused configuration, or a refused measurement (a NaN metric, an exact-zero result) |
| 3 | the memory watchdog stopped the run |
Every command reads the model's config.json before loading any weights. mlx-lm runs the Python file a repo names under model_file when it loads the model, so a repo whose config names one is refused unless you pass --allow-custom-code, and the model is then loaded at exactly the commit whose config.json was checked. (Custom tokenizer code is a separate case that transformers handles itself: it refuses to run it without your confirmation.) Invalid method parameters and a missing TurboQuant install are also caught at this point, before a download starts.
compare records a target it cannot read as a failed row and carries on with the rest. A shared reference it cannot read (compare weights), or an unreadable model (compare kv), is exit 2, since no row could be measured.
Every entry point, the Python API included, caps MLX's wired memory and its buffer cache (4 GiB) before loading. The CLI also runs a watchdog that exits with code 3 once MLX's active plus cached memory passes the device's memory size less 4 GiB. That ceiling is only a backstop. The pre-flight gates described in docs/measurement-principles.md are what should refuse an oversized run before it starts. Long runs print progress to stderr; standard output carries only the report.
Further reading
- Low-bit KV caches on MLX: what exists and what is missing — surveys mlx-lm's shipped cache, the measured 8-bit and 4-bit fidelity cost, KIVI and KVQuant-style alternatives, and the remaining MLX layout and kernel gaps.
- How to measure what quantization actually costs — the methods companion: teacher-forced paired scoring, streaming full-vocabulary KL on a 32 GB machine, the guards that keep a harness from passing by doing nothing, and where the verdict thresholds honestly come from.
- More writing at ineshin.space.
Status
0.10.0, released on PyPI as mlx-quant-fidelity. A hardening release: the memory guards count model weights and run before the weights probe loads anything, repos that would execute their own code are refused unless you opt in, and bad parameters fail before a download starts. Measured numbers are unchanged from 0.9.0. Threshold validation and MLA coverage are on the roadmap.
License
Sister projects
Other MLX libraries for Apple Silicon:
- mlx-taef — tiny autoencoders for fast diffusion-latent previews and low-memory decode (FLUX / SD).
- mlx-teacache — TeaCache residual caching to skip redundant FLUX denoising steps.
- mlx-model-doctor — validate an MLX / Hugging Face model repo before you load it (config, tokenizer, safetensors, memory).
1 maintainer

Metadata
1 maintainer
Release files for mlx-quant-fidelity 0.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| mlx_quant_fidelity-0.10.0.tar.gz | 1.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mlx_quant_fidelity-0.10.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.3 MB
Release files / mlx_quant_fidelity-0.10.0.tar.gz
| Download URL | mlx_quant_fidelity-0.10.0.tar.gz |
|---|---|
| Size | 1.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a0f14c723d3f4b91a596c71f1af83b492c817a2cf9bd64de42cb4587d9079945
|
|
BLAKE2b-256 checksum How to use checksums |
b7ba802958cf1207962cb54d9df09d4919bd1538d46642e45f8c64eabd8c495f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 29, 2026.
Transparency logRelease files / mlx_quant_fidelity-0.10.0-py3-none-any.whl
| Download URL | mlx_quant_fidelity-0.10.0-py3-none-any.whl |
|---|---|
| Size | 107.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c3b174f946c68e190e445a16d78cb5aebff384c52d6a8a32dabfe3e403880093
|
|
BLAKE2b-256 checksum How to use checksums |
ab767caf1b4cfbc510c2ae63c8861bb068ba391ffb8938a32033ff90a002aa8f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 29, 2026.
Transparency log













