


Validate your product idea before you build. mockcrowd builds a crowd of hundreds of AI personas from real posts on Reddit, Hacker News and Bluesky, lets them argue about your idea in a simulated Reddit thread, and tells you how many would really pay, why the rest would not, and how far to trust the answer.
It runs on your machine, on the AI you already have: Claude Code, Codex, Code Puppy, Ollama, or any OpenAI compatible API.
mockcrowd validate "An app that scans your vinyl records with the phone camera to catalog your collection and track prices" --price "\$3.99/month"
Real output from a small test run (20 personas, 1 discussion round, Claude, Hacker News and Bluesky voices):
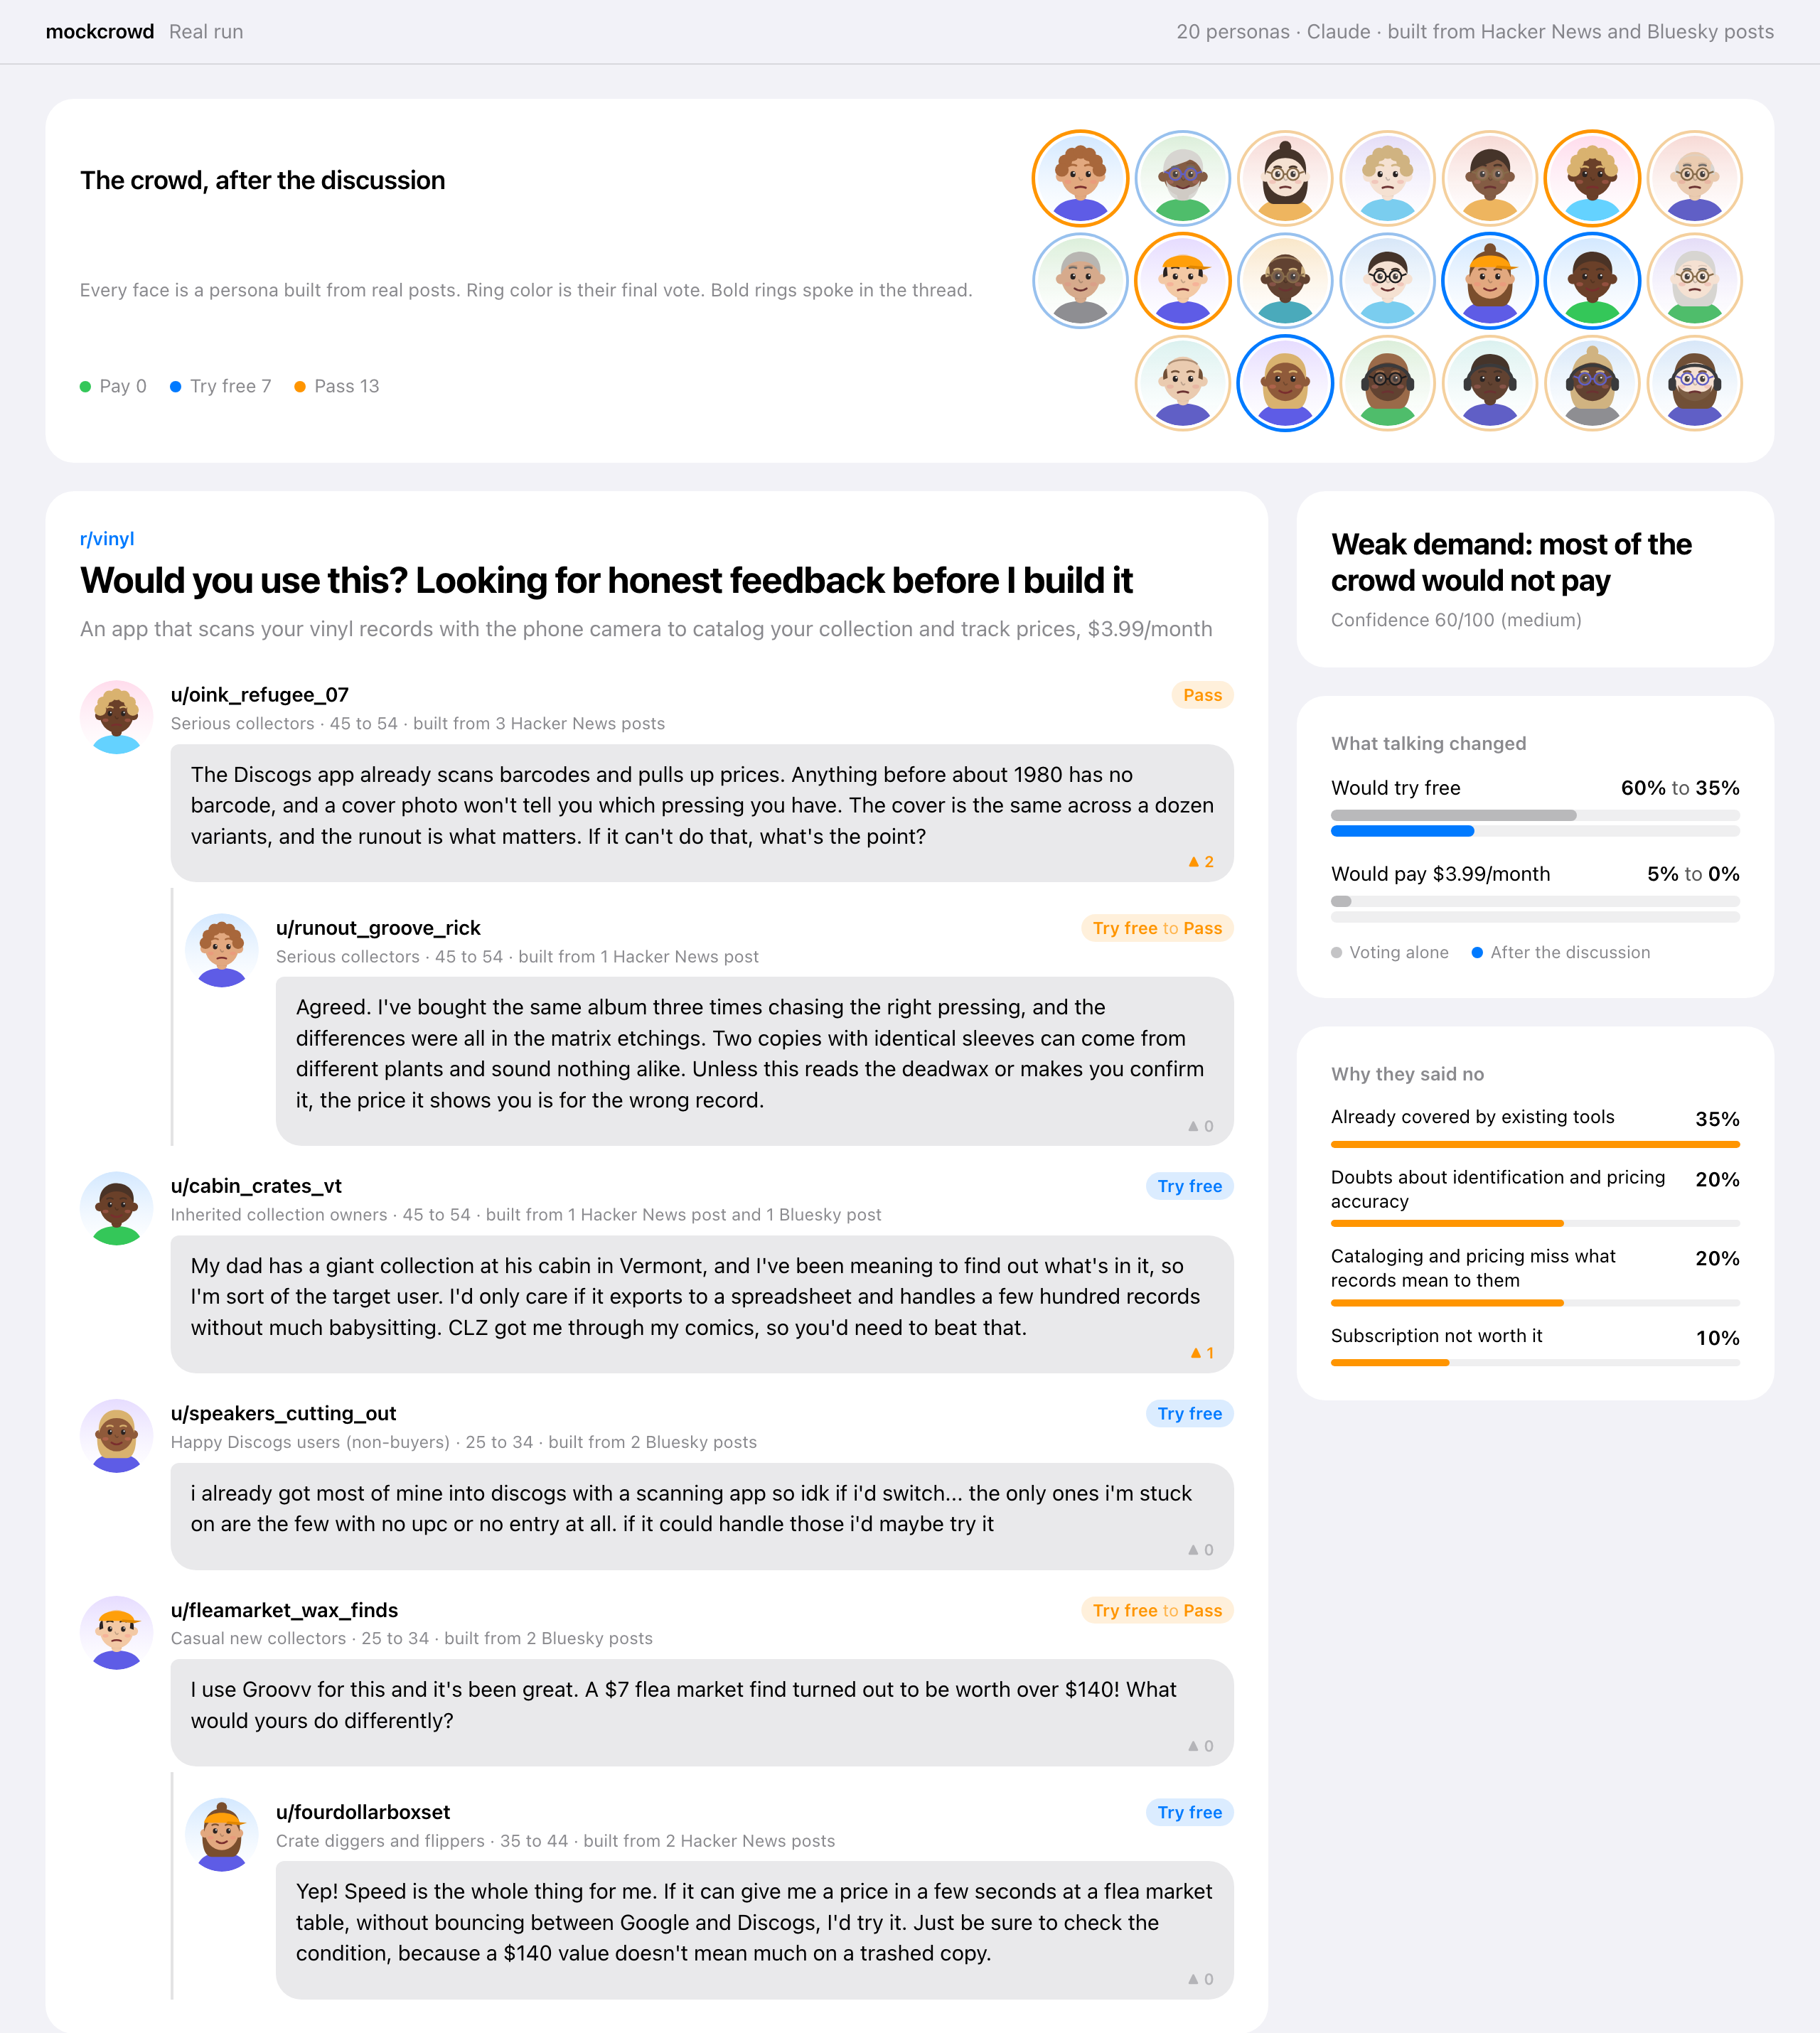
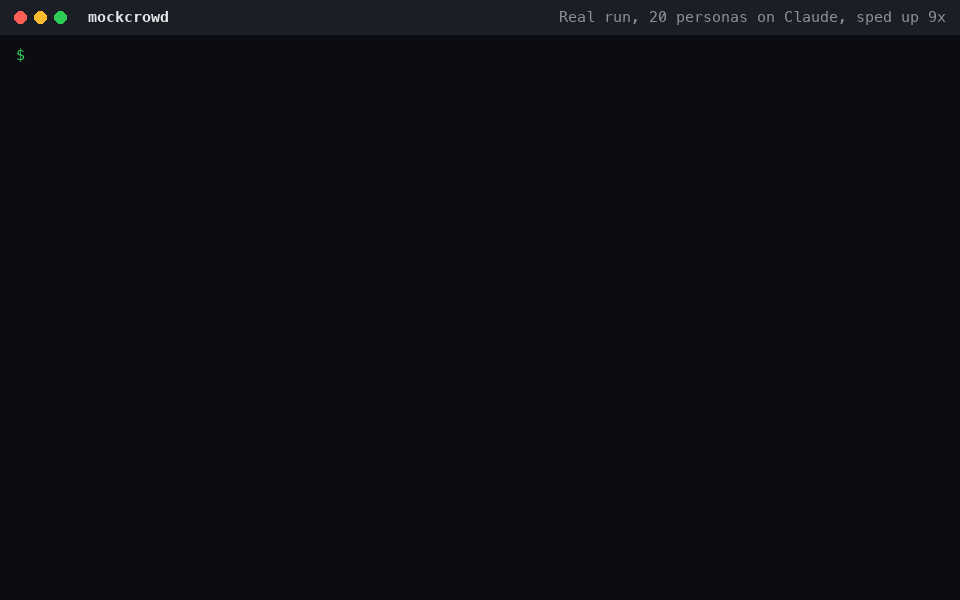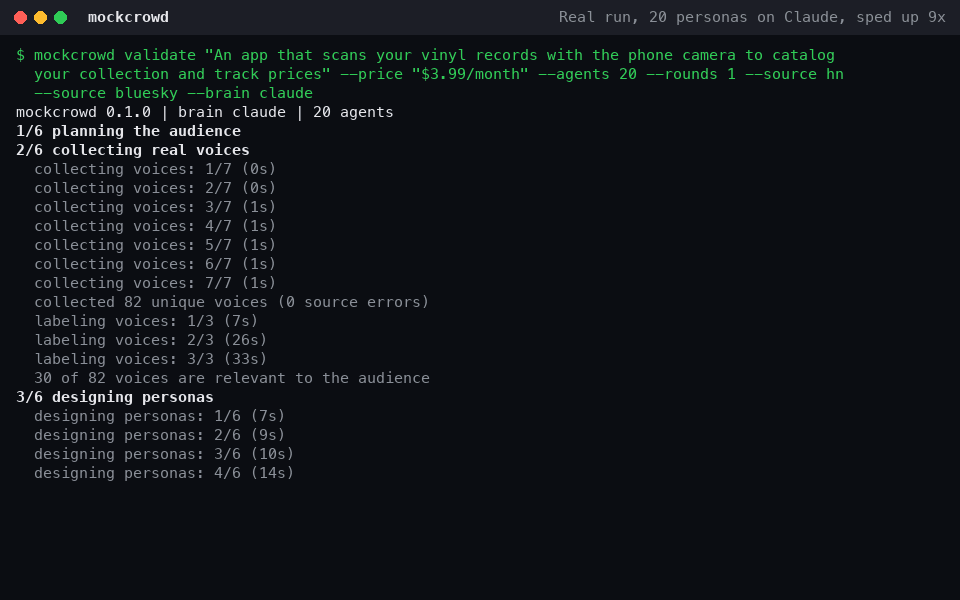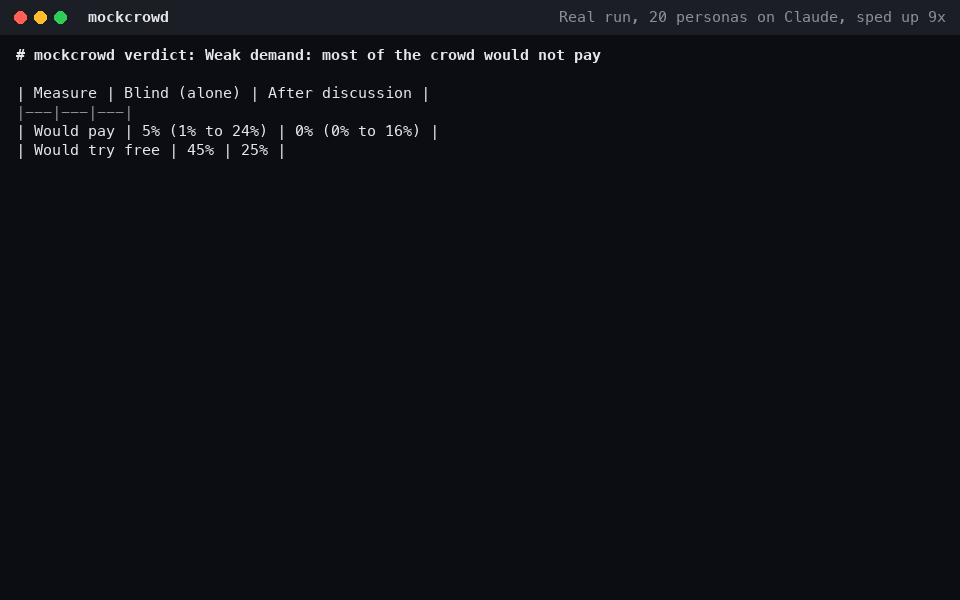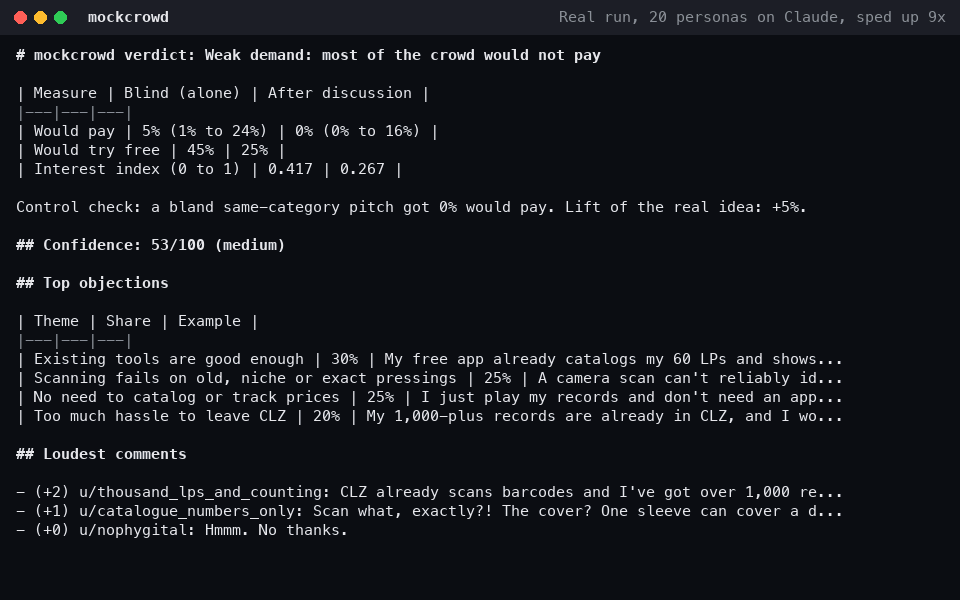
Alone, 60% said they would try it free and 5% would pay. After the discussion, 35% would try it and nobody would pay. That is the kind of answer you want before you spend a month building.
Why it is different
| Problem with asking an LLM "would people buy this?" | What mockcrowd does |
|---|---|
| Models are agreeable and say yes to everything | Every persona also rates a bland control pitch in the same blind vote. The verdict is the lift over the control, not the raw yes rate. |
| Invented personas sound like marketing copy | Every persona is built from real posts and cites them. The stance mix of the crowd (positive, neutral, skeptical, negative) is matched to the mix measured in those posts. |
| One voice, no social dynamics | A Reddit style discussion: threads of about 20 personas, a ranked feed, and a fixed action space (comment, reply, upvote, downvote, do nothing), following the design of OASIS. You see the vote before and after people talk. |
| No way to know if the tool is right | Evals and a backtest on products with known outcomes (crowdfunding records and well known flops), plus your own recorded outcomes. |
Install
uv tool install git+https://github.com/phanisaimunipalli/mockcrowd
# or: pipx install git+https://github.com/phanisaimunipalli/mockcrowd
mockcrowd brains        # shows which AI it can use
Python 3.10 or newer. One small dependency (certifi).
Pick the brain
mockcrowd uses the first one it finds, or the one you pass with --brain.
| Brain | How it runs | Setup |
|---|---|---|
claude |
claude -p on your Claude Code plan |
Claude Code installed |
codex |
codex exec on your ChatGPT or API plan |
Codex CLI installed |
code-puppy |
code-puppy -p with your configured model |
Code Puppy installed |
ollama |
Local models, free and private, slower | ollama serve, then --model <name> |
openai |
Any OpenAI compatible endpoint (OpenAI, OpenRouter, LM Studio, vLLM) | MOCKCROWD_API_BASE, MOCKCROWD_API_KEY, --model |
Claude has been run live end to end. The Codex, Code Puppy, Ollama and OpenAI adapters are tested against the flags and API each tool documents, but not yet in a live run; reports are welcome. Claude and Code Puppy run with tools off. Codex runs in its read only sandbox, which blocks writes but not reads, so prefer the others if your machine holds sensitive files.
--model is passed through exactly as you write it. A 500 persona run makes roughly 100 to 150 LLM calls, because one call steps a whole batch or thread of personas. A faster, cheaper model makes runs quicker. OPENAI_API_KEY is only used with api.openai.com; other endpoints need MOCKCROWD_API_KEY.
Real voices
| Source | Key needed | Notes |
|---|---|---|
| Yes, free | Create a "script" app at reddit.com/prefs/apps and set REDDIT_CLIENT_ID and REDDIT_CLIENT_SECRET. Reddit blocks keyless requests. Free access is for non-commercial use. |
|
| Hacker News | No | Comments through the Algolia search API |
| Bluesky | No | Public post search |
| App Store | No | Opt in with --source appstore. Apple's public review feed returned no reviews when last tested. |
| Anything else | X, Threads, Instagram, Discord, surveys, support tickets, interview notes: put the posts in a file and pass --voices posts.jsonl (JSONL, CSV or text). |
Each source that fails is listed in the report, and the confidence score drops when evidence is thin.
Use it from your coding agent
mockcrowd install-skill                    # Claude Code: ~/.claude/skills/mockcrowd
mockcrowd install-skill --dir <skills dir> # any agent that reads SKILL.md files
Then ask: "validate my idea for a vinyl collection app at $3.99 a month". The agent runs mockcrowd, and when a source is blocked it can gather posts with its own web tools and pass them in.
Commands
mockcrowd validate "idea" [--price P] [--audience A] [--agents 500] [--rounds 2]
                          [--voices file.jsonl] [--no-live] [--source reddit|hn|bluesky|appstore]
                          [--question "choice:first:Which feature first?:scan|alerts|wishlist"]
                          [--brain auto|claude|codex|code-puppy|ollama|openai] [--model M]
mockcrowd collect "idea" -o voices.jsonl   # only gather real posts
mockcrowd runs                             # list past runs
mockcrowd report <run-id> [--json]
mockcrowd outcome <run-id> --demand high|medium|low --note "what really happened"
mockcrowd eval --suite quick|full|backtest [--gate]
Runs are saved in ~/.mockcrowd/runs/<run-id>/ as report.md and run.json (every voice, persona, vote and comment).
How a run works
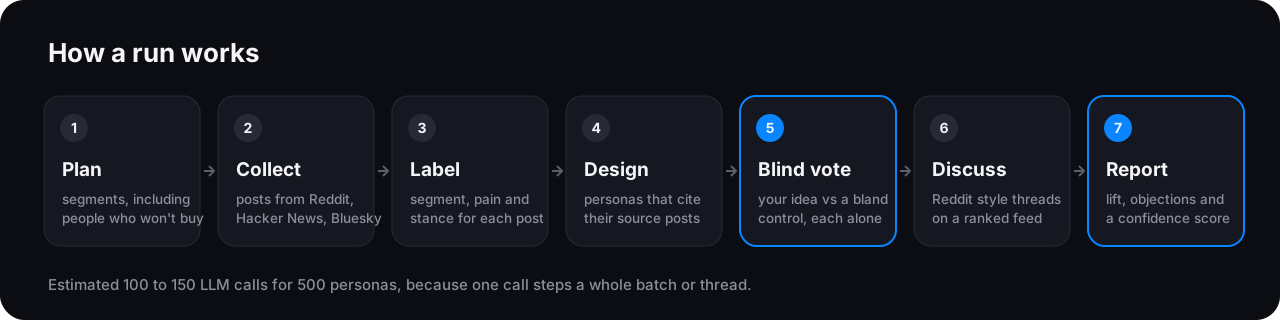
- Plan. The brain reads your idea and lists the segments (including people who would not buy), subreddits and search queries.
- Collect. Real posts from the sources above.
- Label. Each post gets a segment, relevance, pain level and stance. Irrelevant posts are dropped.
- Design. Personas are written in batches from samples of real posts, in the segment shares and stance mix those posts show. Each persona cites its posts.
- Blind vote. Every persona answers alone: interest, would try free, would pay, biggest objection, plus your own typed questions. The real idea and a bland control appear side by side in random order.
- Discuss. Threads of about 20 mixed personas, one action each per round on a ranked feed.
- Final vote and report. Shares with 95% intervals, lift over control, shift after discussion, by segment results, objection themes and a confidence score.
Evals and continuous improvement
mockcrowd eval scores the simulator itself and appends to ~/.mockcrowd/evals/history.jsonl. With --gate it exits 1 when any metric falls more than 5 points below its best.
| Metric | What it checks |
|---|---|
| grounding, citation_valid | Personas are built from real posts, and their citations exist |
| mix_fidelity | The crowd's stance mix matches the real posts |
| diversity | Personas are not copies of each other |
| control_lift, agreeableness | The crowd does not reward a bland idea |
| persuasion_drift | How much the discussion moved the vote |
| stability | Rerunning the vote gives the same answer |
| realism | A judge cannot tell real posts from persona comments |
| backtest_accuracy, backtest_auc | Known hits score above known flops |
| leakage | How many backtest products the brain recognizes from memory |
The backtest ships with 13 cases: six with record crowdfunding or user growth (for example Pebble Time, Exploding Kittens, Flow Hive) and seven well known flops (for example Juicero, Quibi, Fire Phone). Each case cites its source. Pitches are anonymized, and the leakage metric reports how often the model recognizes them anyway.
Your outcomes are the strongest signal. After you test or launch, run mockcrowd outcome <run-id> --demand .... The run becomes a backtest case, and future confidence scores include how well mockcrowd did on cases like yours.
Honest limits
- It is a simulation. Use it to rank ideas, find objections and choose what to test for real, not to forecast revenue.
- Personas reflect the people who post online, who are louder and more opinionated than most buyers.
- Backtest products are famous, so models may know how they ended. Watch the leakage metric.
- The verdict thresholds are starting points. The backtest reports how well they separate hits from flops on your brain.
Credits
Simulation design follows OASIS by CAMEL-AI (Apache 2.0). The idea of building a world from seed material and simulating it was inspired by MiroFish. No code from either project is included. See NOTICE.
License
Apache 2.0
1 maintainer

Metadata
1 maintainer
Release files for mockcrowd 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| mockcrowd-0.1.0.tar.gz | 744.8 kB | With provenance | Details for mockcrowd-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| mockcrowd-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for mockcrowd-0.1.0-py3-none-any.whl |
Total release size: 799.7 kB
Release files / mockcrowd-0.1.0.tar.gz
| Download URL | mockcrowd-0.1.0.tar.gz |
|---|---|
| Size | 744.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
093619868ea0db2dac79550a6e668549bb99e14ca4592456bd751ea4c46d64e3
|
|
BLAKE2b-256 checksum How to use checksums |
1f9b013439bf211de27960ed0a459aac6e6762603c000c3c743d5a43c0fc85bd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logRelease files / mockcrowd-0.1.0-py3-none-any.whl
| Download URL | mockcrowd-0.1.0-py3-none-any.whl |
|---|---|
| Size | 54.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
60701fd817ea6a125c00e1a8c00aeb2a076bb95e414d5a15498b1c1298ca37a0
|
|
BLAKE2b-256 checksum How to use checksums |
4e88bf225711a24ac63116bdc6158b84bbb0e215c1b9a07a5fa2d6dd841ac0bf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logSecurity for mockcrowd 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for mockcrowd-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














