
model2data


Turn a data model into a running analytics stack in one command.
Give model2data a data model — a .model2data.yml file, or a DBML
schema hand-written or exported from an existing database — and it generates realistic,
relationship-preserving synthetic data
and a complete, runnable dbt project around it: seeds, staging models, tests, and a
DuckDB or Postgres profile. No sample data to hunt down, no dbt boilerplate to hand-write, no
production data to risk exposing.
pip install model2data
model2data --file examples/ecommerce.model2data.yml --rows 200 --seed 42
cd dbt_ecommerce && dbt build
Prefer a browser? model2data studio is the same engine as a web app: write DBML, watch the entity diagram redraw as you type, see what every column will generate before you generate it, then export CSVs or a runnable dbt project. Nothing to install, free to start.
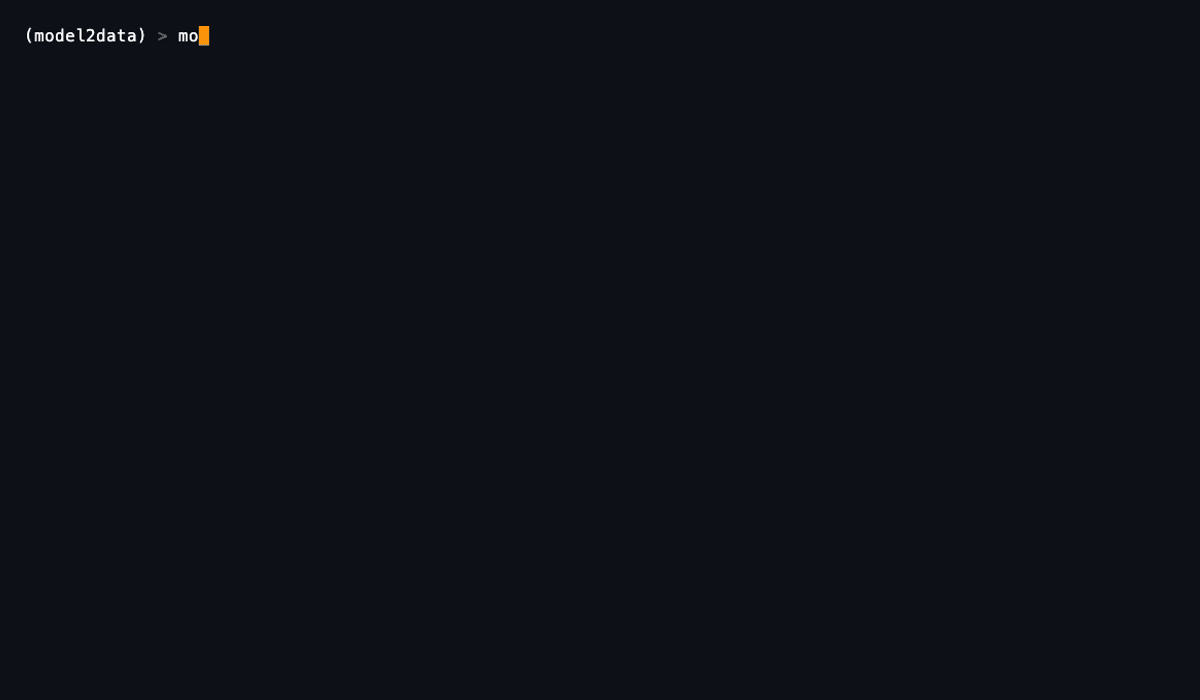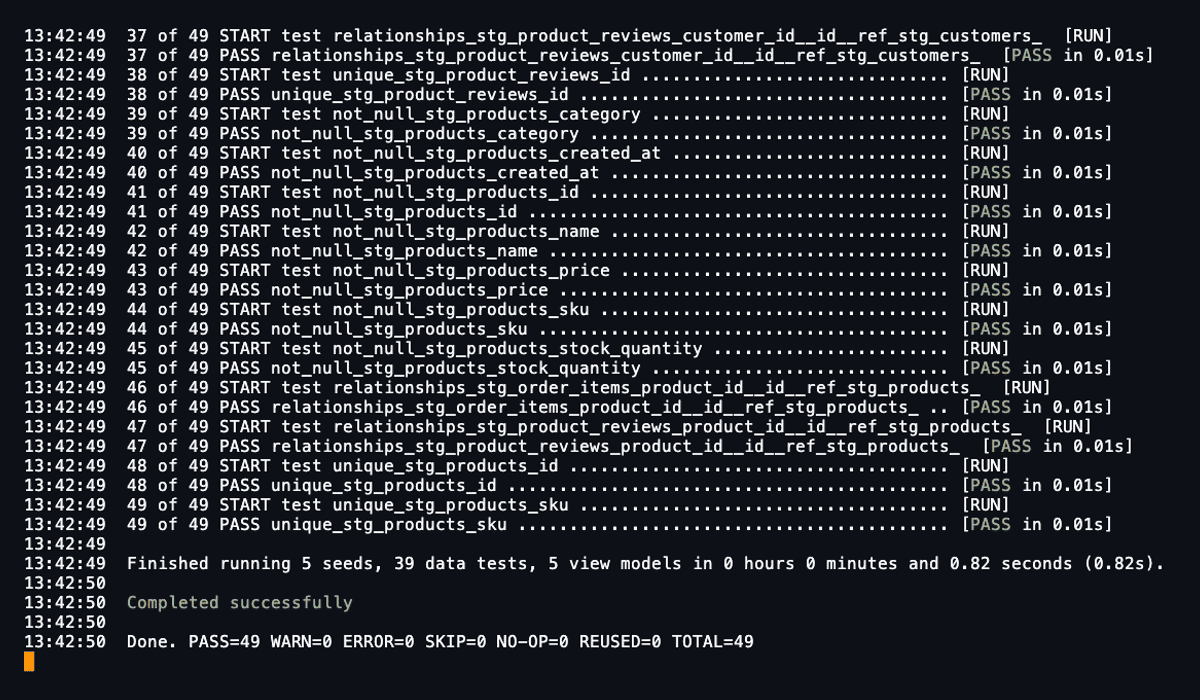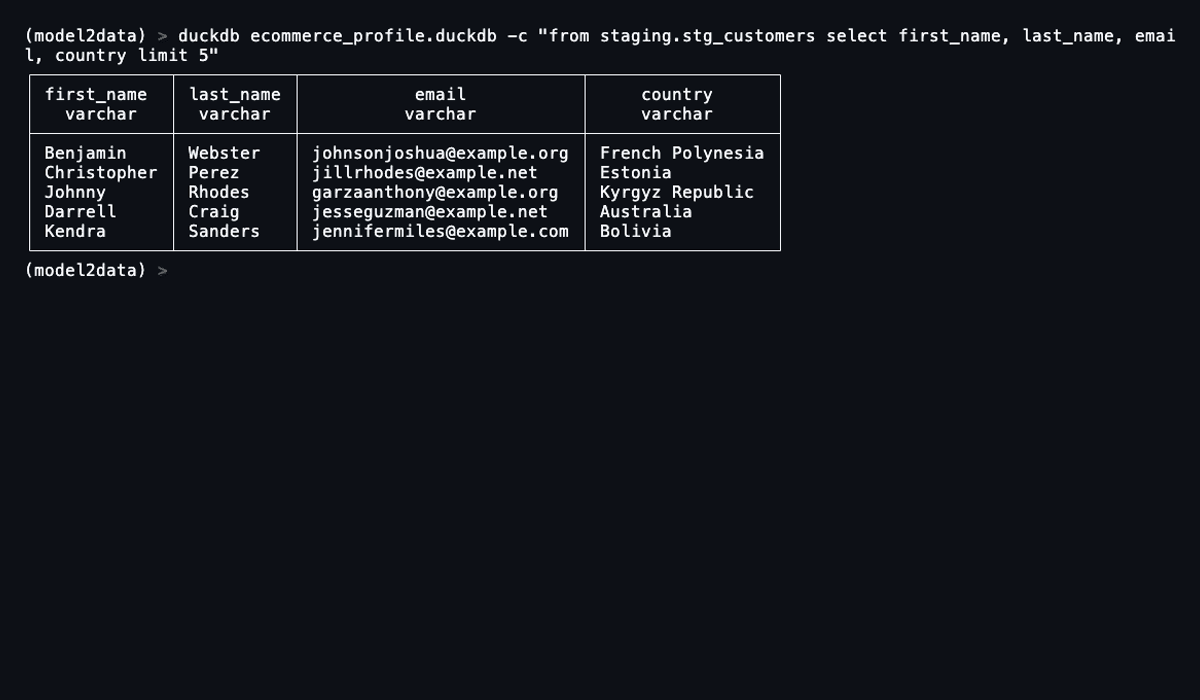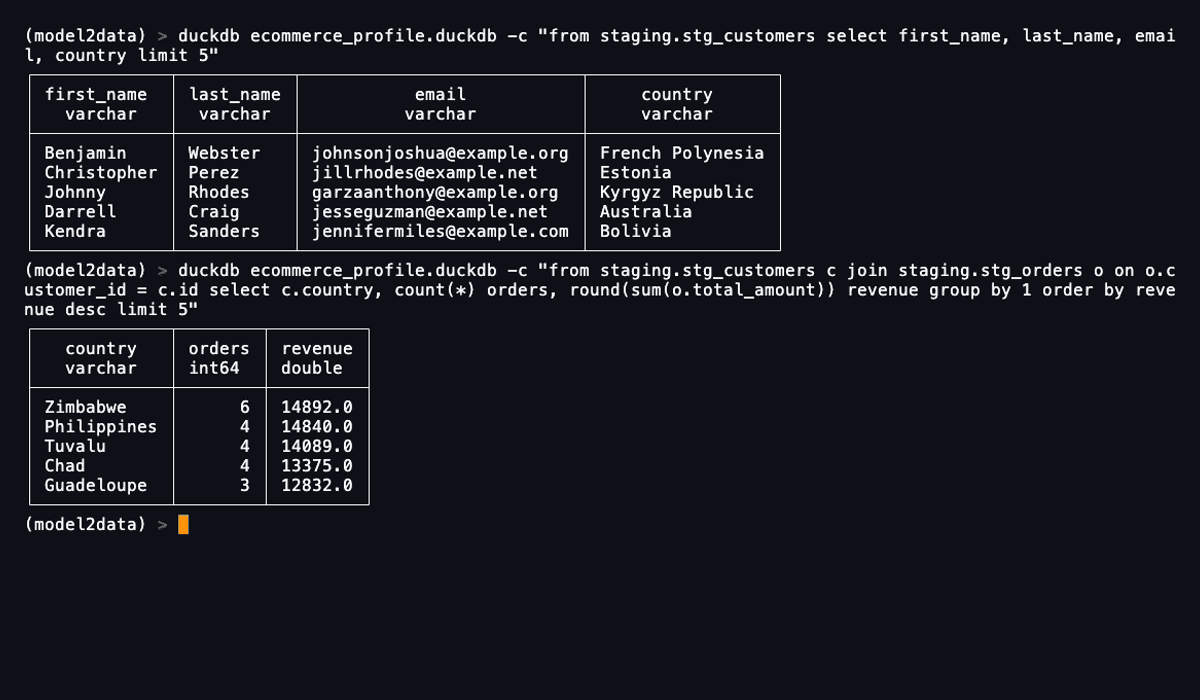
That's a working analytics stack — real (synthetic) data, tested dbt models, queryable in DuckDB — from a schema file, in seconds:
Why this exists
Analytics engineers hit the same wall constantly: you need realistic data to build or test a
pipeline, but production data is off-limits (privacy, access, scale), and hand-rolling mock CSVs
is tedious and doesn't scale past two tables. model2data closes that gap — from a schema
definition to a seeded, tested dbt project you can actually run, with no database or production
access required.
- Privacy-safe. Nothing but a schema definition goes in; nothing but synthetic data comes out.
- Realistic, not random. Column names are matched against ~35 common patterns —
email,first_name,city,phone,company, ... — so a column calledemailgets real-looking emails, notLorem ipsumtext. - Relationship-preserving. Foreign keys resolve to real parent rows; tables are generated in dependency order.
- Deterministic. Pass
--seedand the same schema always produces the same data — safe to commit fixtures, safe to diff across CI runs. Add--as-ofto pin the date the data is anchored on, and the run reproduces on any later day rather than only on the day it first ran. - Re-rollable one table at a time.
--table-seed orders=7regenerates a single table and leaves every other table byte-identical, so you can keep the four tables that look right. - A real dbt project, not just CSVs. Seeds, staging models that
ref()them, schema tests, and a ready-to-use profile — the thing you'd otherwise spend an afternoon scaffolding by hand. A singledbt buildloads, transforms, and tests the whole thing.
Who is model2data for?
- Analytics engineers — generate realistic datasets and a working dbt project without waiting on production access.
- Data engineers — produce deterministic test data from an existing schema for pipeline and migration testing.
- Software & data teams — prototype integrations and analytics workflows without exposing production data.
- Consultants & architects — spin up realistic environments for demos, workshops, and architecture validation in minutes, not hours.
How it works
- Read. Reads the model — its tables, columns, keys, references and generation hints — from
a
.model2data.ymldocument, checking it against the spec, or from DBML, which it converts to the same model first. - Generate. Produces synthetic values per column — typed generation for known SQL types
(int, date, timestamp, ...), name-aware inference for everything else (
email,phone,city, ...), foreign keys resolved against already-generated parent rows. - Scaffold. Writes a complete dbt project around that data: CSV seeds, staging models that
ref()those seeds,not_null/unique/relationshipstests,accepted_valuestests for enum-typed columns, singular SQL tests for composite primary/unique keys, table and columndescription:fields from the model, and a profile for DuckDB (zero-config, file-based) or Postgres.
The model file
A model is one YAML document, <name>.model2data.yml — or the same document as JSON. Its format
is spec 0.3.0, with a JSON Schema your editor can autocomplete and
check against:
# yaml-language-server: $schema=https://www.jbanalytica.com/model2data/spec/0.2.0/model.schema.json
model2data: 0.2.0
name: coffee_webshop

enums:
  order_status: [pending, paid, shipped, delivered, cancelled]

tables:
  customers:
    columns:
      id: {type: bigint, pk: true}
      email: {type: email, unique: true, not_null: true}

  orders:
    columns:
      id: {type: bigint, pk: true}
      customer_id:
        type: bigint
        not_null: true
        references: customers.id
        generate: {skew: 0.8}
      total_amount:
        type: numeric
        generate:
          min: 10
          max: 5000
          distribution: {kind: lognormal, median: 120, spread: 0.7}
      status:
        type: order_status
        generate:
          weights: {delivered: 20, cancelled: 1}

run:
  seed: 1
  as_of: 2026-01-01
generate holds a column's hints; run saves the generation settings with the model, and every
CLI option overrides the one it names. model2data validate FILE checks a model and prints every
issue with its path in the document.
Validate models in CI. model2data validate a.model2data.yml b.model2data.yml (or
--glob "**/*.model2data.yml", --format github for inline pull request annotations) exits 1
when any model has an error. A GitHub Action (uses: JB-Analytica/model2data@v1), a pre-commit
hook (model2data-validate) and a GitLab CI snippet are in the
README.
DBML is supported input. --file also takes a .dbml file, converted to the same model
before generating; a JSON note on a column ([note: '{"min": 1}']) becomes its generate, any
other note its description. model2data convert schema.dbml -o schema.model2data.yml writes the
model a DBML file converts to.
model2data studio — the same engine, in the browser
model2data studio puts everything on this page behind a web UI. It is built by JB Analytica on top of this library, it's the fastest way to try model2data, and it's the better fit while a schema is still being designed:
- Type DBML, see the diagram. Syntax highlighting, autocomplete and live error checking; the entity diagram redraws as you type. Click a column to trace what actually joins to it.
- See what you'll get before you generate. Every column shows an example of the value it will produce, and columns nothing recognises are marked — so placeholder data is visible rather than silent.
- Generate and export. Per-table row counts, then CSVs or a complete dbt project: the same seeds, staging models, tests and DuckDB profile this CLI produces, reproducing the exact rows you previewed.
- Share the model. A share link that also embeds as a chrome-free diagram in a Notion, Confluence or wiki page.
Free to start, nothing to install: studio.jbanalytica.com. The CLI stays the right tool for scripting, CI and fixtures you commit; the studio is where a model gets designed and shown.
Installation
pip install model2data
Quick start
We bundle several example schemas in examples/ — this walkthrough uses the e-commerce one
(examples/ecommerce.model2data.yml: customers, products, orders, order items, and reviews).
Generate a project with synthetic data:
model2data --file examples/ecommerce.model2data.yml --rows 200 --seed 42
This creates a dbt_ecommerce/ folder with your data and dbt setup.
--seed reproduces a run's numbers, but dates and timestamps are generated relative to the
current date, so the same seed drifts once the day turns over. --as-of pins the date they're
anchored on, and the whole dataset reproduces on any later day — which is what makes a generated
fixture safe to commit. If one table comes out wrong and the rest looks right, --table-seed
re-rolls just that table, leaving every other table's seed CSV byte-identical. --locale picks
the country every generated person and address comes from:
model2data --file examples/ecommerce.model2data.yml --rows 200 --seed 42 \
  --as-of 2026-01-31 --table-seed orders=7 --locale nl_BE
Run dbt to load, transform, and test the data:
cd dbt_ecommerce
dbt build
Staging models ref() their seeds, so a single dbt build loads the seeds, builds the models,
and runs every generated test in one dependency-ordered pass — no separate dbt seed/dbt run
needed, even on a brand-new database. (The individual dbt deps, dbt seed, and dbt run
commands still work if you'd rather drive the steps yourself; the generated project declares no
packages, so dbt deps is a no-op.)
Your analytics-ready dataset is now in DuckDB!
To target Postgres instead, install the extra and pass --adapter postgres:
pip install "model2data[postgres]"
model2data --file examples/ecommerce.model2data.yml --rows 200 --seed 42 --adapter postgres
Connection details are read from environment variables (MODEL2DATA_PG_HOST, MODEL2DATA_PG_PORT, MODEL2DATA_PG_USER, MODEL2DATA_PG_PASSWORD, MODEL2DATA_PG_DATABASE), defaulting to localhost:5432 with a postgres/postgres user for local development.
After generation, the CLI prints a short summary — tables and rows generated, relationships found in the model, and any columns that fell back to generic placeholder text because neither their type nor name could be matched.
Pass --unit-tests to also generate deterministic dbt unit test fixtures (models/staging/ut_stg_<table>.yml) from the actually-generated seed rows:
model2data --file examples/ecommerce.model2data.yml --rows 200 --seed 42 --unit-tests
This targets dbt-core's native unit testing feature, which works out of the box with the base install — see dbt-core versions below.
Your model's hints also write data tests for the dbt project, so the model that generates the
fixtures guards the real pipeline too. Every hint that states a constraint becomes a generic test
on the staging model, shipped as a self-contained macro in macros/model2data_hint_tests.sql (no
dbt package, so dbt build still works offline):
| In the model | dbt test | Tolerance |
|---|---|---|
generate: {min, max} on a numeric column |
model2data_between |
none |
generate: {after: other} |
model2data_not_before (where both are not null) |
none |
generate: {null_rate} |
model2data_max_null_share: nulls at most null_rate + tolerance |
--test-tolerance, default 0.1 |
generate: {distinct: n} |
model2data_max_distinct: at most n distinct values |
none |
grain on a table |
model2data_unique_combination |
none |
| an enum-typed column | accepted_values (always written) |
none |
true_rate, weights, skew, distribution and the temporal shape hints (business_hours,
growth, seasonality) describe a statistical shape rather than a constraint a row can break, so
they write no test. --hint-tests {error,warn,off} sets these tests' severity (default warn:
they describe intent and should not break a first dbt build on real data); the structural tests
(not_null, unique, relationships) are unaffected. A model with no such hints generates the
same YAML as before. To call the mapping from Python, model2data.dbt.hint_tests.hint_tests_for(model)
returns the tests as data.
Generate the next days
A table with incremental in the model moves on day by day: each day adds new_per_day rows
(their dates and timestamps falling on that day) and updates update_rate of the rows it already
holds, and an enum column with transitions moves from a state to one of the states allowed to
follow it. See examples/ecommerce_daily.model2data.yml and "Days after the first" in the
spec.
model2data --file examples/ecommerce_daily.model2data.yml --seed 42 --as-of 2026-01-31 --days 7
model2data --file examples/ecommerce_daily.model2data.yml --seed 42 --as-of 2026-01-31 --next
--days N generates day 0, the run you would get without it, and N days after it (--next is
--days 1). The dbt seeds hold the state after the last day. --days-format picks what else is
written beside the project, outside seeds/ so dbt does not load it: batches (the default),
days/<table>/day_000.csv whole and then one file per day with the rows inserted and updated that
day; changelog, changelog/<table>.csv with a _day and an _op (insert or update) column
on every row; or final, nothing more. A day depends only on the seed, --as-of, the day and the
model, so day n never changes when you generate more days or add an unrelated table. From Python:
from model2data.generate.days import generate_days
from model2data.model import load

days = generate_days(load("examples/ecommerce_daily.model2data.yml"), 7, seed=42)
days[3].tables["orders"].inserted   # rows day 3 added
days[3].tables["orders"].updated    # rows day 3 changed, with their new values
days[3].tables["orders"].state      # the table after day 3
Break the data on purpose
A dbt test you have never seen fail is a test you hope works. --defects puts deliberate,
counted defects in the generated data, so dbt build fails exactly the tests it should — for
teaching dbt, or for proving a project's tests fire:
model2data --file examples/ecommerce.model2data.yml --seed 42 --defects training
cd dbt_ecommerce && dbt build    # fails unique, not_null, relationships, accepted_values once each
training breaks each kind of standard dbt test once; messy puts a small share of every defect
on every table; clean (the default) is the data as it always was, byte for byte; none also
ignores the defects a model's tables list, for the clean data of a training model. A table can
also list its own defects in the model (spec 0.3.0):
orders:
  defects:
    - {type: duplicate_keys, count: 3}                               # fails unique
    - {type: orphan_foreign_keys, column: customer_id, share: 0.02}  # fails relationships
    - {type: nulls, column: order_date, count: 5}                    # fails not_null
The types are duplicate_keys, orphan_foreign_keys, nulls, invalid_values (fails
accepted_values), messy_text (whitespace and casing to clean in staging), and, with --days,
late_arriving (rows an incremental model filtering on updated_at > max(updated_at) skips) and
late_updates (versions a strategy: timestamp snapshot misses) and overlapping_history (see
below). Every run with defects writes
defects_report.json (each defect, the rows it broke, the tests it breaks) and
EXPECTED_FAILURES.md into the project, so a test that does not fire is visible. Defects are applied
after the clean data, from their own random stream: the same seed gives the same bytes, and a
defect on one table moves nothing in another. From Python, model2data.defects.planned_defects
says what a run will break, model2data.output.finish_run applies it (and builds the histories)
after generate_days, and write_defects_report / write_expected_failures write the two files.
A source that keeps its history
history: true in a table's incremental (spec 0.3.0) also writes <table>_history: every
version of every row over the generated days, with valid_from, valid_to (null for the current
version) and is_current — an SCD type 2 source to build snapshots and point-in-time joins
against. The project tests it with two package-free tests, one current row per key and no
overlapping versions; the overlapping_history defect breaks the second.
orders:
  incremental: {new_per_day: 20, update_rate: 0.1, updated_at: updated_at, history: true}
Generated dbt project structure
The generated dbt project includes:
dbt_{project_name}/
├── seeds/
│   └── raw/
│       ├── __seed_config.yml  # seed descriptions + column-type overrides
│       ├── table1.csv
│       └── table2.csv
├── models/
│   └── staging/
│       ├── stg_table1.sql
│       ├── stg_table1.yml
│       ├── ut_stg_table1.yml  # only with --unit-tests
│       └── ...
├── data-tests/
│   └── unique_combination_stg_table1_col_a_col_b.sql  # only for composite pk/unique keys
├── macros/
│   ├── generate_schema_name.sql
│   └── model2data_hint_tests.sql  # only when the model's hints write tests
├── dbt_project.yml
├── profiles.yml  # DuckDB or Postgres config, depending on --adapter
└── {project_name}_profile.duckdb  # DuckDB adapter only
- Seeds: CSV files with generated synthetic data, plus
__seed_config.yml— each seed'sdescription:(the table'sdescriptionin the model) and the column-type overrides that keep all-digit text columns (barcodes, zero-padded postcodes, ...) from being loaded as integers. - Staging Models: Basic dbt models that
ref()their seed. Usingref()rather than declaring the seeds as dbtsourcesis what gives each model a real DAG edge to the seed behind it, so onedbt buildorders seeds before models on a fresh database. - Tests: A YAML per staging model with column tests (
not_null,unique,relationships, andaccepted_valuesfor enum-typed columns), plus the hint tests above. A column'sdescriptionin the model becomes itsdescription:field. - Composite key tests: Composite primary/unique keys (
keys, or severalpk: truecolumns) get a singular SQL test underdata-tests/, dbt's configuredtest-paths. - Profiles: Pre-configured for DuckDB (file-based) or Postgres (via env vars), with schema handling.
- Unit tests (opt-in via
--unit-tests):models/staging/ut_stg_<table>.ymlfixtures built from real generated rows, co-located with each staging model so dbt (which only parses unit tests frommodel-paths) picks them up.
Using model2data with an LLM
If you want to go from a plain-English description of a data model straight to a running, demo-ready dbt project, LLMS.md is written for an LLM/agent to read: it covers the DBML feature set model2data understands (enums, notes, defaults, composite keys, both relationship syntaxes, self-references), which it converts to a spec 0.2.0 model and the exact command sequence to run. Point an LLM-backed coding assistant at it and describe your data model — it can author the DBML and run model2data for you.
dbt-core versions
model2data requires dbt-core >= 1.11, tracking dbt's own version support
policy: dbt Labs supports each minor release for one
year, and 1.11 is the oldest that still is. Generated projects build cleanly — no deprecation
warnings — on every supported dbt-core version, and CI proves it on each push by running a real
dbt build against both the stated floor and the newest release.
If you're pinned to an older dbt-core, use model2data 0.5.x, which supported down to 1.8.5.
Design decisions / non-goals
- DuckDB Default: Chosen for its zero-config, file-based nature, making it easy to get started without database setup. Postgres is supported via
--adapter postgres; other adapters can be configured manually. - dbt Integration: Leverages dbt's transformation capabilities for a familiar workflow in analytics engineering.
- Synthetic Data: Uses deterministic generation for reproducibility; not intended for production use or as a replacement for real data.
- Non-goals: This is not a data migration tool, ETL pipeline, or real-time data generator. It focuses on static, synthetic datasets for testing and prototyping.
Limitations
- Synthetic data generation is heuristic-based (typed generation, name-aware inference, enum/default awareness) and may not perfectly mimic real-world distributions or edge cases.
- DuckDB and Postgres are supported today; other databases require manual profile adjustments.
- No support for incremental models or advanced dbt features in generated projects.
- Composite foreign keys (across a bridge/join table) are generated as independent single-column FKs — each column's values are individually valid, but the combination isn't guaranteed to match a real parent composite key unless that key is separately enforced as a key of the child (
keys). - A model that doesn't conform to the spec — or DBML that can't be read, or converts to such a model — is refused with every issue and where it is, rather than generated from in part. A reference onto a column that is not a key is allowed with a warning: its values are drawn from the ones the parent column holds.
Project status
As of 1.0.0, model2data is considered feature-complete for its intended use case: turning a
data model into realistic synthetic data and a runnable dbt project, reliably. There's no active
roadmap of new capabilities planned — the focus from here is maintenance: bug fixes, keeping pace
with new dbt-core releases, and reviewing community contributions.
Ideas that came up during development but were deliberately left out of scope, in case anyone wants to pick them up as a contribution:
- Additional database adapters (e.g. Snowflake, BigQuery).
- A rule-based semantic layer scaffold (
semantic_models.yml/basic metrics) derived from the parsed schema shape. - Example mart-layer models on top of staging (the generated
dbt_project.ymlcarries a ready-to-uncommentmartsschema/materialization config for this).
See CONTRIBUTING.md if you'd like to work on any of these.
Contributing
We welcome contributions!
- Open issues for bugs or feature requests.
- Submit PRs to add new example models, custom data generators, or improvements.
- Ensure all new features include tests if possible.
See CONTRIBUTING.md for detailed guidelines, and DEVELOPMENT.md for the local dev setup and release process.
Code of Conduct
Please read our Code of Conduct to understand our community standards.
License
MIT License. See LICENSE for details.
Built and maintained by JB Analytica —
Data & Analytics Engineering · Data Platform Architecture · Modern BI.
Try model2data studio — model2data in the browser, nothing to install.
1 maintainer

Metadata
1 maintainer
Release files for model2data 1.10.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| model2data-1.10.1.tar.gz | 324.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| model2data-1.10.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 551.6 kB
Release files / model2data-1.10.1.tar.gz
| Download URL | model2data-1.10.1.tar.gz |
|---|---|
| Size | 324.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
74222a9076120af0e8667e16bf9e6866f838778504a830739103b43e692cc750
|
|
BLAKE2b-256 checksum How to use checksums |
20c2a3224f1bbbd933935026dbb52b2d698a62a5367bb94a5a2bad421bc9f137
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / model2data-1.10.1-py3-none-any.whl
| Download URL | model2data-1.10.1-py3-none-any.whl |
|---|---|
| Size | 227.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
37f71883fc602a4bf32f192f77e8e373a1f6ecf5c614b2112ccfe2a3f9800ddf
|
|
BLAKE2b-256 checksum How to use checksums |
6a6ae50f281ecae31482be6769a2cf71d2d171d930c67149b36dc29af2d7a3cc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














