
model2data




Built and maintained by JB Analytica — data platform architecture and analytics engineering.
Turn a data model into a running analytics stack in one command.
Give model2data a data model — a .model2data.yml file, or a DBML
schema hand-written or exported from an existing database — and it generates realistic,
relationship-preserving synthetic data and a complete, runnable dbt project around it: seeds,
staging models, tests, and a DuckDB or Postgres profile. Add a metrics file and it also knows
what your revenue comes to, and writes a dbt test that proves it. No sample data to hunt down,
no dbt boilerplate to hand-write, no production data to risk exposing.
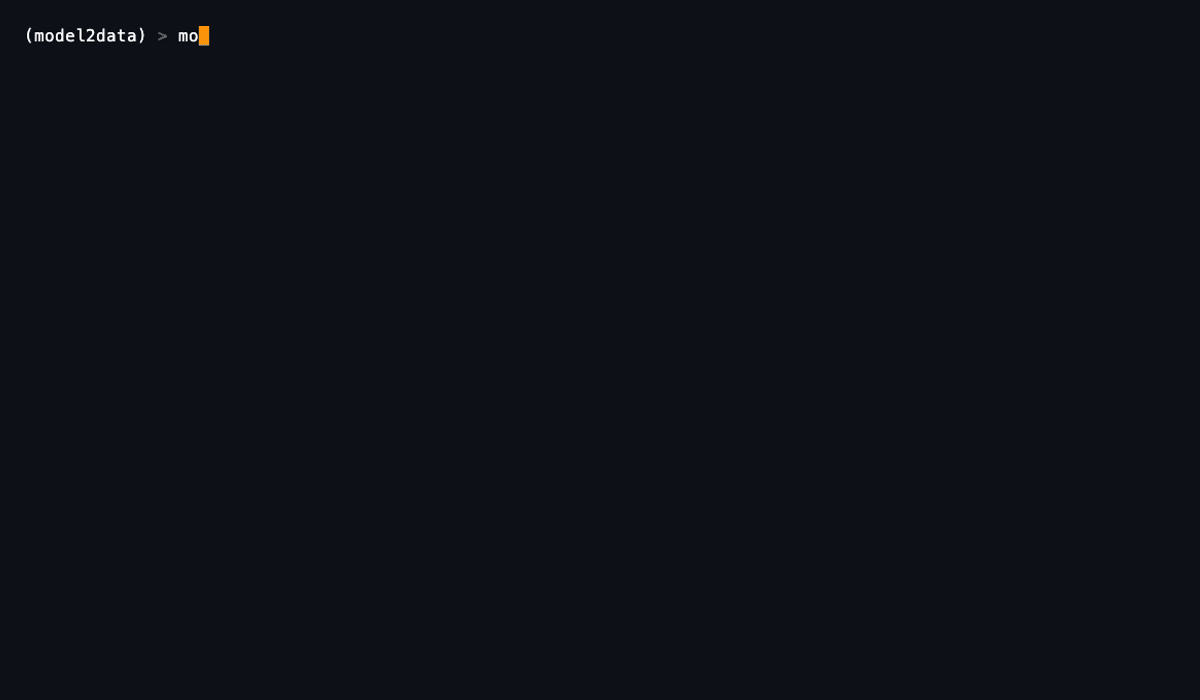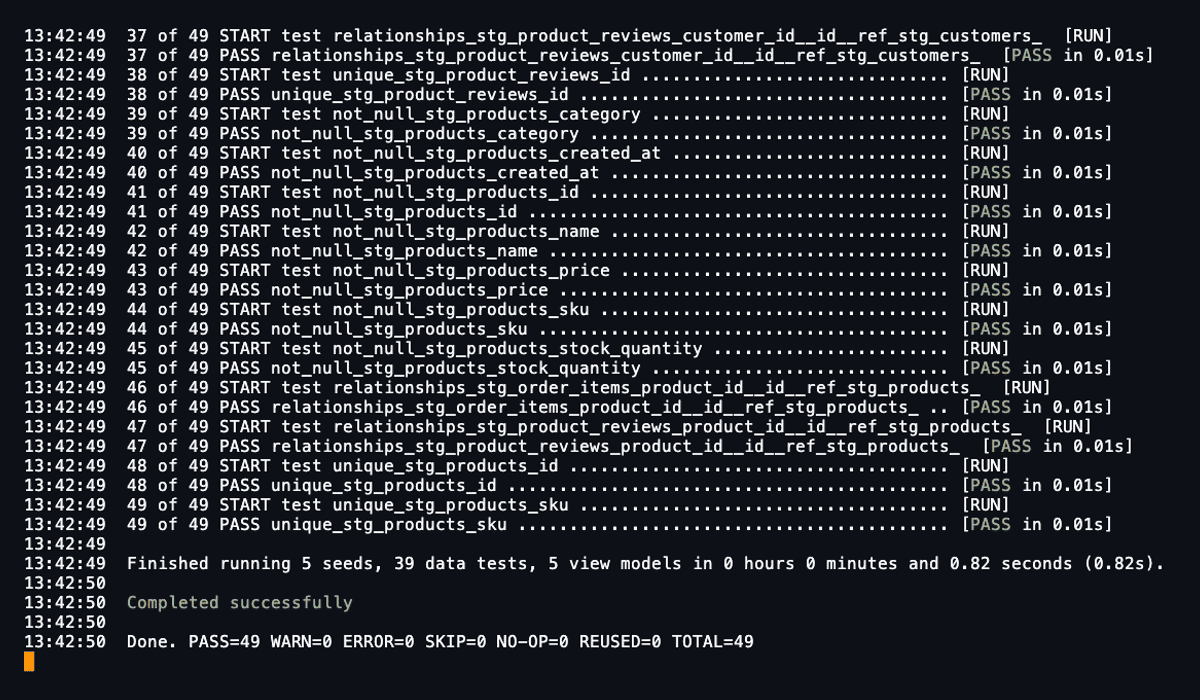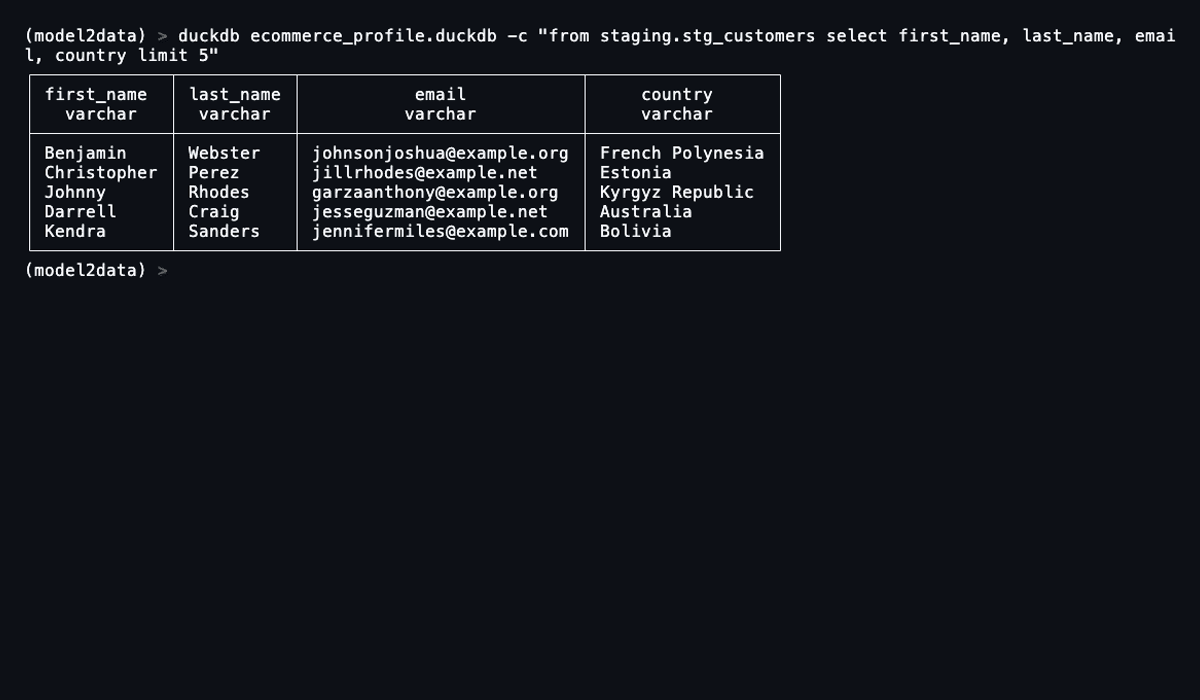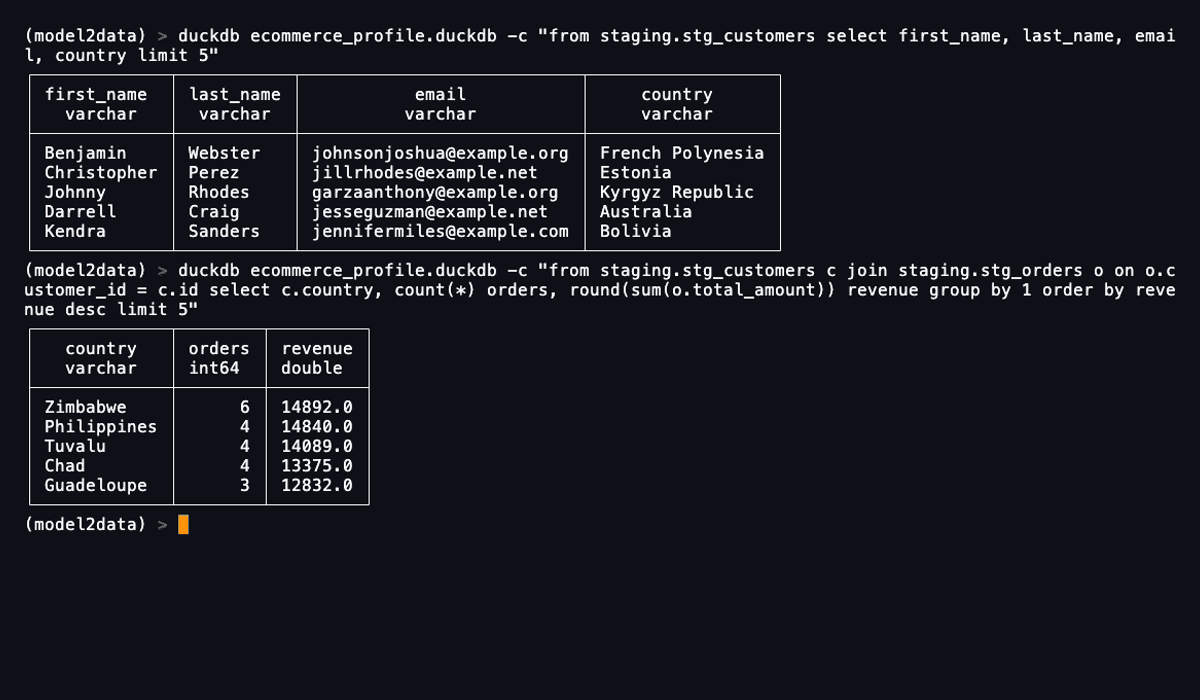
pip install model2data
model2data --file examples/ecommerce.model2data.yml --rows 200 --seed 42   # examples/ is in the GitHub repository
cd dbt_ecommerce && dbt build
Prefer a browser? model2data studio is the same engine as a web app: write DBML, watch the entity diagram redraw as you type, see what every column will generate before you generate it, then export CSVs or a runnable dbt project. Nothing to install, free to start.
What you get
Values that look real. Column names are matched against about 40 common patterns — email,
first_name, city, phone, company, ... — so a column called email gets real-looking
emails, not Lorem ipsum. Type a column with any Faker provider (billing_country state,
sku ean13) to pick its generator outright, and --locale nl_BE makes every person and address
come from one country. → The model file
Foreign keys that resolve. Tables are generated in dependency order and every foreign key
points at a parent row that exists — onto a primary key or a unique one — and
after: customers.created_at keeps an order on or after the sign-up of the customer it points
at (validate suggests it where a date could fall before its parent's). Integer primary keys
number the rows 1..N, in order. Composite primary and unique keys hold, and a column that repeats a
parent's value through a foreign key (orders.customer_email) holds the email of the order's
own customer.
→ The model file
A dbt project that runs. Seeds, staging models that ref() them, not_null, unique,
relationships and accepted_values tests, data tests written from the model's own hints, and
a DuckDB (zero-config) or Postgres profile. One dbt build loads, builds and tests it, and
--unit-tests adds dbt unit test fixtures. → The generated dbt project
The same files, byte for byte. The same model, --seed, --as-of and options give the same
files on any machine, any day, with the same model2data version — safe to commit as fixtures,
safe to diff in CI. --table-seed orders=7 re-rolls one table and leaves every other one
byte-identical. → The determinism promise
Days after the first. A table marked incremental moves on day by day: --days 7 or
--next adds new rows and updates existing ones, an enum with transitions moves an order from
pending to shipped, and each day is written as a batch or a changelog to load incrementally.
→ Days after the first
History tables. history: true writes <table>_history, every version of every row with
valid_from, valid_to and is_current: an SCD type 2 source to build snapshots against.
→ A source that keeps its history
When things happen. --business-hours, --growth and --seasonality shape every timestamp
(weekdays and working hours, a trend, a Q4 peak), or one column at a time. updated_at never
lands before created_at, after orders any two columns, or a column after a parent's, and when gives shipped_at a value on shipped and delivered orders only. → When things happen
How the data is spread. --skew lets a few customers place most of the orders; weights,
true_rate, null_rate and distinct shape a column; distribution draws a number from a
normal, lognormal or exponential curve. → How the data is spread
Defects on purpose. --defects training breaks each standard dbt test once, messy puts a
small share of every defect on every table, and a table can list its own: duplicate keys,
orphans, nulls, invalid values, messy text, late-arriving rows. Every run with defects writes
EXPECTED_FAILURES.md, so a test that does not fire shows. → Defects on purpose
Metrics with known values (new in 1.13.0). A metrics file beside the model defines revenue,
orders, average order value. The run writes each metric's value over the generated data to
metric_values.json, overall and per month, a dbt test per metric that must reproduce it on the
warehouse, and an Apache Ossie semantic model under osi/.
New in 1.14.0: --lightdash writes the same metrics into the staging models' YAML as
Lightdash reads them, filters, joins and ratios included, so the
dashboard's revenue can be checked against the number the run already knows.
→ Metrics with known values
Validate in CI. model2data validate checks models and metrics files and prints GitHub
annotations; uses: JB-Analytica/model2data@v1 fails a pull request that breaks one. A
pre-commit hook and a GitLab CI snippet do the same. → Validate models in CI
Use it from an agent. uvx model2data@latest guide prints instructions written for a coding
agent, shipped with the installed version; LLMS.md takes an LLM from a plain-English
description to a running project. → Agents and LLMs
Or in the browser. model2data studio is the same engine with a DBML editor and a live diagram.
Before and after
In: a model (here the orders table of
examples/ecommerce.model2data.yml) and, optionally, the
metrics that matter (examples/ecommerce.metrics.yml):
  orders:
    columns:
      id: {type: bigint, pk: true, not_null: true}
      customer_id: {type: bigint, not_null: true, references: customers.id}
      order_date: {type: timestamp, not_null: true}
      total_amount:
        type: numeric
        not_null: true
        generate: {min: 10, max: 5000}
      status: order_status
metrics:
  revenue:
    label: Revenue
    measure: orders.total_amount
    agg: sum
    where:
      orders.status: [processing, shipped, delivered]
    time: orders.order_date
    format: currency
  orders:
    count: orders
    where:
      orders.status: [processing, shipped, delivered]
    time: orders.order_date
  average_order_value:
    ratio: {numerator: revenue, denominator: orders}
model2data --file examples/ecommerce.model2data.yml --metrics examples/ecommerce.metrics.yml \
  --rows 200 --seed 42 --as-of 2026-01-31
Out: a dbt project.
dbt_ecommerce/
├── seeds/raw/                  customers.csv, orders.csv, order_items.csv, products.csv,
│                               product_reviews.csv, __seed_config.yml
├── models/staging/             stg_<table>.sql + stg_<table>.yml (with tests), for each table
├── data-tests/metrics/         metric_revenue.sql, metric_orders.sql,
│                               metric_average_order_value.sql, metric_units_sold.sql
├── macros/                     generate_schema_name.sql, model2data_hint_tests.sql
├── osi/ecommerce.yml           the model and its metrics as Apache Ossie 0.1.1
├── metric_values.json          each metric's known value
├── ecommerce.model2data.yml    the model, and
├── ecommerce.metrics.yml       its metrics, copied as given
├── dbt_project.yml
└── profiles.yml                DuckDB
dbt build loads the seeds, builds the staging models and runs every test, the four metric
tests included:
Finished running 5 seeds, 49 data tests, 5 view models in 0 hours 0 minutes and 0.71 seconds (0.71s).

Completed successfully

Done. PASS=59 WARN=0 ERROR=0 SKIP=0 NO-OP=0 REUSED=0 TOTAL=59
And metric_values.json says what a dashboard on this data must show:
{
  "model2data-metrics": "0.1.0",
  "model": "ecommerce",
  "run": {
    "seed": 42,
    "as_of": "2026-01-31"
  },
  "rounding": "counts, and sums, minimums and maximums of integer columns, are exact; every other value is rounded to 6 decimal places, half to even",
  "metrics": {
    "revenue": {
      "kind": "simple",
      "label": "Revenue",
      "value": 220291.8,
      "time": "orders.order_date",
      "by_month": {
        "2025-01": 3967.88,
        "2025-02": 10676.66,
        ...
        "2026-01": 31879.13
      }
    },
    "orders": { "kind": "count", "label": "Orders", "value": 92, ... },
    "average_order_value": { "kind": "ratio", "label": "Average order value", "value": 2394.476087, ... },
    "units_sold": { "kind": "simple", "label": "Units sold", "value": 734, ... }
  }
}
Run it again tomorrow, or on another machine, with the same model2data version, and every one of those files is the same.
Who it's for
Analytics engineers hit the same wall constantly: you need realistic data to build or test a pipeline, but production data is off-limits (privacy, access, scale), and hand-rolling mock CSVs is tedious and doesn't scale past two tables. model2data closes that gap. Nothing but a schema definition goes in; nothing but synthetic data comes out.
- A consultant who needs a client demo before source access. Write the client's model from a kick-off call, generate a year of their data, and show a working dbt project and dashboard in the first week, without touching production.
- An analytics engineer who wants fixtures in CI. Commit the model, generate with
--seedand--as-of, and every CI run builds against the same bytes.--daysgives an incremental model the next day's batch to process. - A trainer who needs data that fails on purpose.
--defects trainingbreaks each standard dbt test once and says which, so a class seesunique,not_null,relationshipsandaccepted_valuesfail for the right reason. - A team defining metrics once. Write revenue in one metrics file, check every number the
semantic layer or dashboard shows against
metric_values.json, letdbt buildprove the SQL, and hand the definitions on as Apache Ossie or straight to Lightdash.
How it works
model (.model2data.yml or DBML) + metrics file (optional)
  -> read and validate -> generate -> scaffold the dbt project + compute each metric's known value
  -> seeds, staging models and tests, metric tests, metric_values.json, osi/, profiles.yml
  -> dbt build
- Read. Reads the model — its tables, columns, keys, references and generation hints — from
a
.model2data.ymldocument, checking it against the spec, or from DBML, which it converts to the same model first. A metrics file is checked against its spec and against the model. - Generate. Produces synthetic values per column — typed generation for known SQL types
(int, date, timestamp, ...), then a Faker provider named as the type (
sku ean13), then name-aware inference for everything else (email,phone,city, ...), foreign keys resolved against already-generated parent rows. The metrics file is never read here: the data is the same with or without it. - Scaffold. Writes a complete dbt project around that data: CSV seeds, staging models that
ref()those seeds,not_null/unique/relationshipstests,accepted_valuestests for enum-typed columns, singular SQL tests for composite primary/unique keys, tests from the model's hints, table and columndescription:fields from the model, and a profile for DuckDB (zero-config, file-based) or Postgres. - Compute metrics. With
--metrics, computes each metric over the generated data and writes its known value, a dbt test that checks it, and the Apache Ossie file; with--lightdash, Lightdash metrics and dimensions in the staging models' YAML.
Installation
pip install model2data                 # DuckDB included
pip install "model2data[postgres]"     # to target Postgres with --adapter postgres
uvx model2data --help                  # or run it without installing
Python 3.10 to 3.14. The examples used on this page are in examples/.
dbt-core versions
model2data requires dbt-core >= 1.11, tracking dbt's own version support
policy: dbt Labs supports each minor release for one
year, and 1.11 is the oldest that still is. Generated projects build cleanly — no deprecation
warnings — on every supported dbt-core version, and CI proves it on each push by running a real
dbt build against both the stated floor and the newest release.
If you're pinned to an older dbt-core, use model2data 0.5.x, which supported down to 1.8.5.
License
MIT License. See LICENSE. Built and maintained by JB Analytica. Try model2data studio — model2data in the browser, nothing to install.
Documentation
- The model file —
.model2data.yml, DBML as input,validate,convert - Generating a project — row counts,
--as-of, the determinism promise,--table-seed,--locale - The generated dbt project —
dbt build, Postgres, unit tests, hint tests, structure - Days after the first and history tables
- When things happen and how the data is spread
- Defects on purpose
- Metrics with known values
- Validate models in CI
- Agents and LLMs, and LLMS.md
- The model spec and the metrics spec
- Examples and the changelog
1 maintainer

Metadata
1 maintainer
Release files for model2data 1.16.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| model2data-1.16.2.tar.gz | 464.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| model2data-1.16.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 794.9 kB
Release files / model2data-1.16.2.tar.gz
| Download URL | model2data-1.16.2.tar.gz |
|---|---|
| Size | 464.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9463358f2bffe3f219920cb99043559ee4623ef9524803f6b76bacf6869e5a34
|
|
BLAKE2b-256 checksum How to use checksums |
3f2eb96b0adfe9d9735c0cd1fdac10435917e9d345b1bc1db71024179f9a3e10
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / model2data-1.16.2-py3-none-any.whl
| Download URL | model2data-1.16.2-py3-none-any.whl |
|---|---|
| Size | 330.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ed31865978fd9fe5e73facd5dc590502da738a3e8e3da5085b31dabc83923eee
|
|
BLAKE2b-256 checksum How to use checksums |
6f0bde1d98ffc8a905217e25dcde3f9819af910d6a2d07f64bcc8850247ad703
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














