
ModelRoom
Does this model have room on your machine?
ModelRoom (package and command: modelroom) answers two questions for a list of model
families you care about:
- Which local packages exist? It reads the Hugging Face API and the Ollama registry for the base models and packagers you allow, and records every package with its size, format, quantization and the exact revision it was seen at.
- Which of them fit a given machine? It measures a machine itself, cross-checks the reading with llmfit when that is installed, and computes, per package, whether weights plus KV cache plus a configured reserve fit into the memory that machine has.
The result is a JSON snapshot, one hardware profile per machine and a rendered Markdown document with a ranking per configured machine. Nothing in the tool is tied to a specific operator: you bring a configuration file with your families, packagers and machines, run it on the machine you want to size, and keep the files wherever you keep your notes.
Status
Alpha, version 0.1.0, the first release (see CHANGELOG.md). The guided mode and the six
subcommands work end to end; the data shapes are versioned contracts (see CONTRACTS.md). Expect changes to the rendered layout and to the fit rules before a stable
release. CHANGELOG.md lists what has landed.
Requirements
- Python 3.11 or newer and uv.
llmfit1.1.16 or newer onPATHis optional:hardwaremeasures the machine itself and usesllmfitonly to cross-check the physical RAM and the VRAM. Without it the profile records both checks asabsentand the command still succeeds. The minimum version is set in the configuration ([llmfit] min_version).nvidia-smionPATHfor a machine with an NVIDIA card; without it the profile records that an adapter is present but unmeasured, and no fit is computed for it.- An Ollama daemon on
http://127.0.0.1:11434for the load test only. Without one the guided mode says so in one line and goes on; nothing else in the tool needs it. - Internet access for the search and the fetch.
Installation
As a command-line tool from the Python Package Index, with either installer:
uv tool install modelroom
pipx install modelroom
Both need Python 3.11 or newer and the installer itself (uv or
pipx), and both put modelroom into an environment of its own. If the
command is not found afterwards, the installer's folder is not on PATH yet: run
uv tool update-shell or pipx ensurepath once and open a new terminal. The guided mode needs
no configuration file: it writes one into the folder you choose. modelroom.example.toml in this
repository is the starting point for the subcommands further down.
Quick start
Open a terminal in the folder where the results should live and type the command:
modelroom
It opens with what it already knows and then walks five numbered steps. Every step is a block of
its own; a question disappears once it is answered and one line takes its place, with the answer
in the words you gave it, and each step writes its files as it goes. Esc leaves a list, Ctrl-C
leaves at any point. The next run is the same command: it remembers the folder, the machine it
measured and the context you chose.
A guided run, step by step
The pictures are one run on a laptop with one 12 GB graphics card and 127 GB of memory, in a
folder named C:\models, chosen for the pictures; any folder does (Windows Terminal; the run
looks the same on Linux and macOS). Your numbers, and so the fit of every package, will differ.
Start
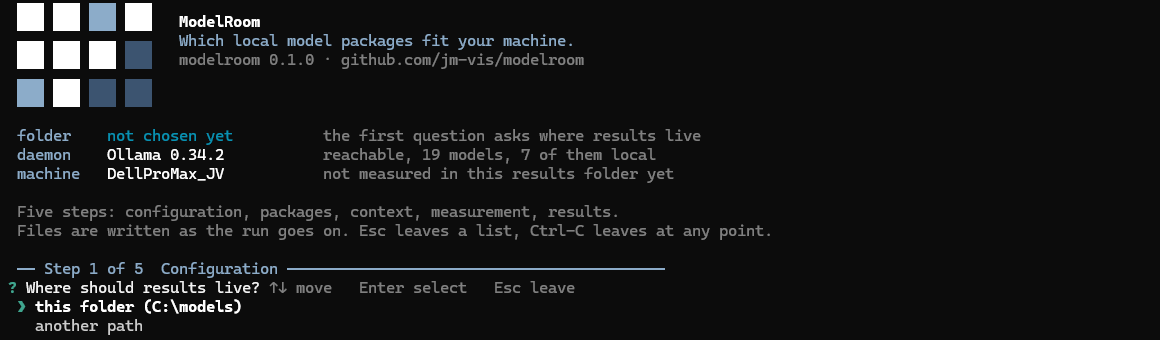
Three facts before the first question: the folder (none chosen yet), the local daemon (Ollama is reachable, with 19 models, 7 of them local and the rest cloud entries) and this machine (its name, and that no measurement is stored in this folder yet). The first question of step 1 is where the results should live: the folder you are in, or another path.
Step 1, Configuration
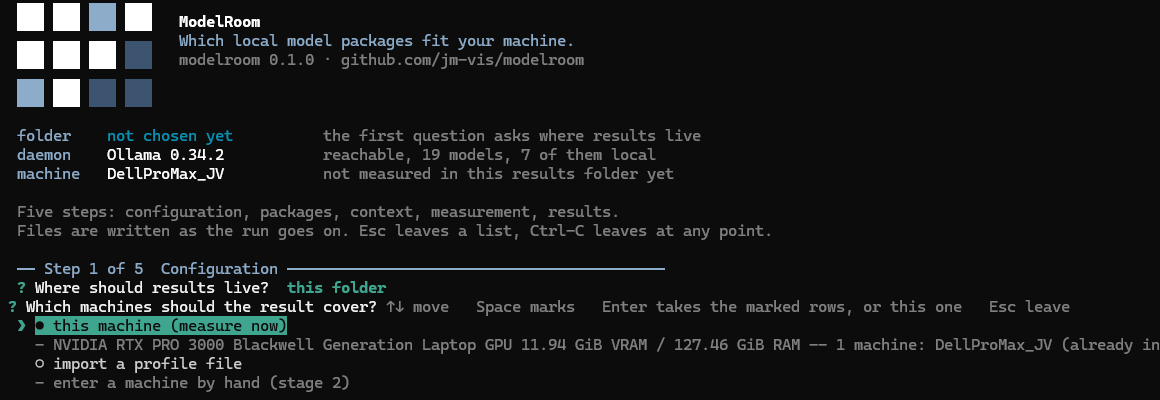
Which machines the result covers. this machine is measured right here, once the question is answered; the gray line under it lists the machine profiles this folder already holds, here the one an earlier run left, with the graphics card, its memory and the system memory. A profile file measured on another machine can be imported instead, so one folder can rank the same packages for a laptop and a server. Entering a machine by hand is not in yet. The measurement is cross-checked with llmfit when it is installed.
Step 2, Packages
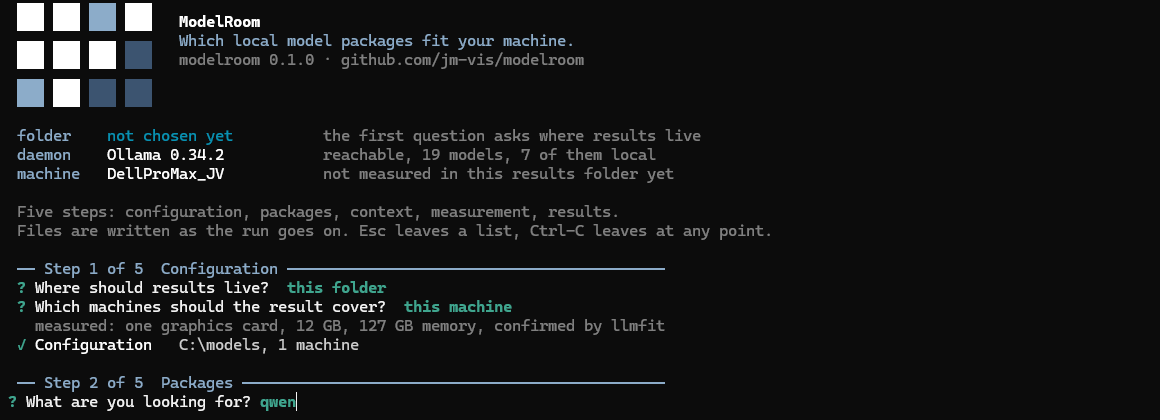
What you are looking for. You can answer in four ways, and none of them has to be the exact spelling of anything:
| What you type | What happens |
|---|---|
qwen |
the word goes to the Hub, and every account is asked for it |
qwen 3.5 9b |
blanks, hyphens, underscores and colons all separate words; one of them is asked for and the rest narrow the answer, so a missing hyphen, a blank in the wrong place or a gguf you wrote out of habit still find the model. The words themselves have to be right: 9x finds no 9B |
unsloth/Qwen3.5-9B-GGUF |
a repository you already know: one request for exactly that one, and the owner filter never hides it. If it cannot be read or holds no GGUF file, the words of its name are searched instead |
| nothing at all | press Enter and the current models of the shipped catalog are looked up one by one -- the answer to "I have no model in mind, what fits this machine?" (see the last picture) |
A word close to something the catalog knows that finds nothing to pick (qwn) ends in a short
list of what you may have meant; picking one searches again.
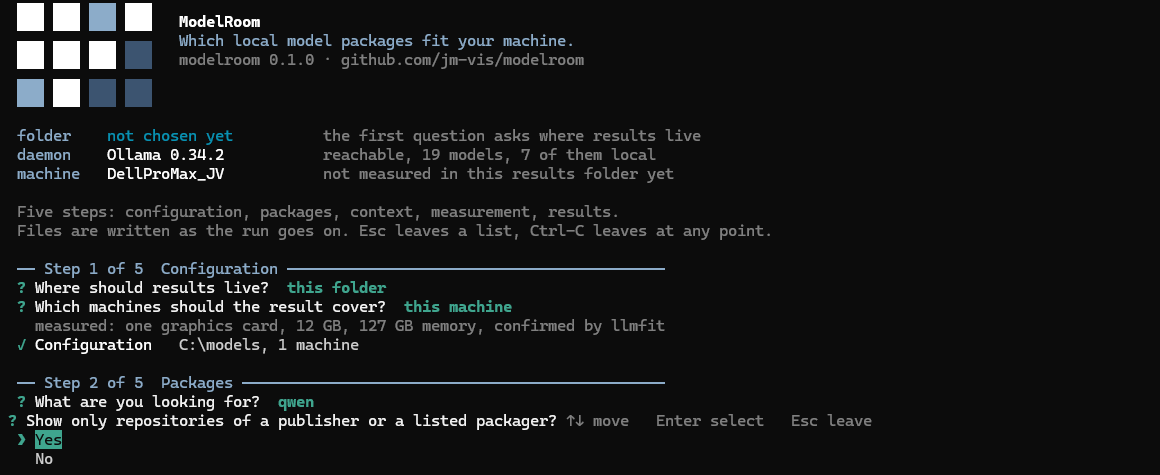
The owner filter. Yes (the default) keeps the list to the publisher of what you searched for
and the packagers configured for the folder, by default these five (unsloth, bartowski,
mradermacher, lmstudio-community, ggml-org), each asked for its newest and its most
downloaded repositories. No adds the twenty
most downloaded and the ten newest repositories for that word, whoever owns them, and lets a model
of a publisher the catalog does not know be picked as well.
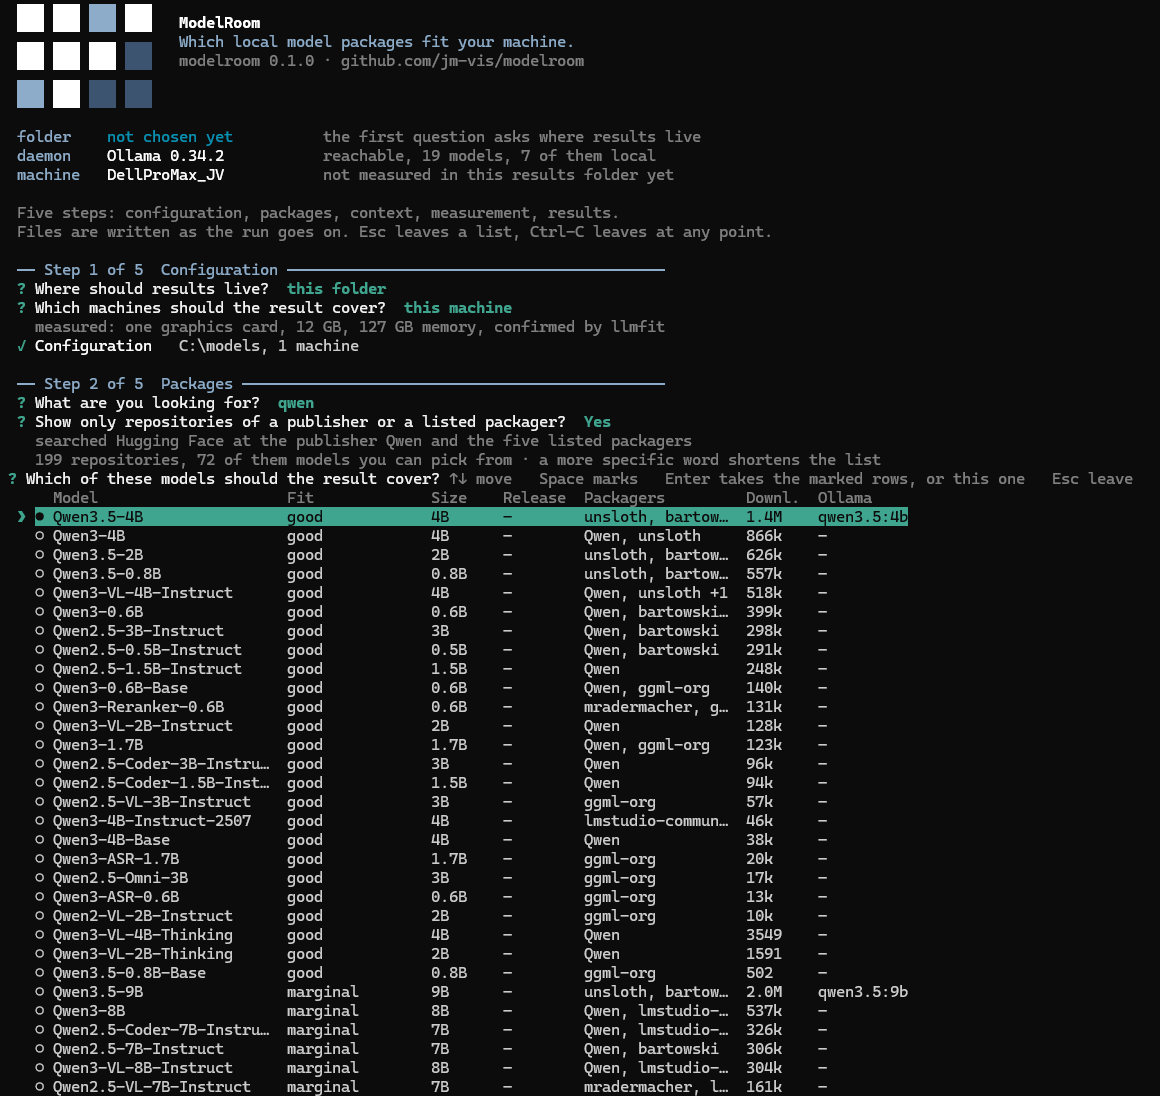
The list of models, one row per model that can really be picked, best fit first. The columns:
Fit is what the model's size allows on this machine at the folder's context (32k for a new
folder): good, marginal, too tight; good (RAM) means it needs system memory rather than
the graphics card's. After the fetch the fit is computed per package from what the fetch found. Size is the parameter count. Release says latest when the publisher's own page
names this model as the current one of its family, legacy when the publisher named a successor,
and – when the catalog holds no evidence either way. Packagers are the accounts that offer a
GGUF build of it, Downl. the downloads of all of them together, Ollama the name of the same
model in the Ollama registry when the catalog knows one. Space marks a row, Enter takes the
marked rows or, with nothing marked, the row under the pointer. Here Qwen3.5-4B is marked. The
repositories that are no model of the list, and why, are counted in state/search.json rather
than shown as rows nobody can choose. After the choice the run fetches, per model, the packages of
the publisher's own repository and of the first listed packager that has it: their sizes,
formats, quantizations and the exact revision they were seen at.
Step 3, Context
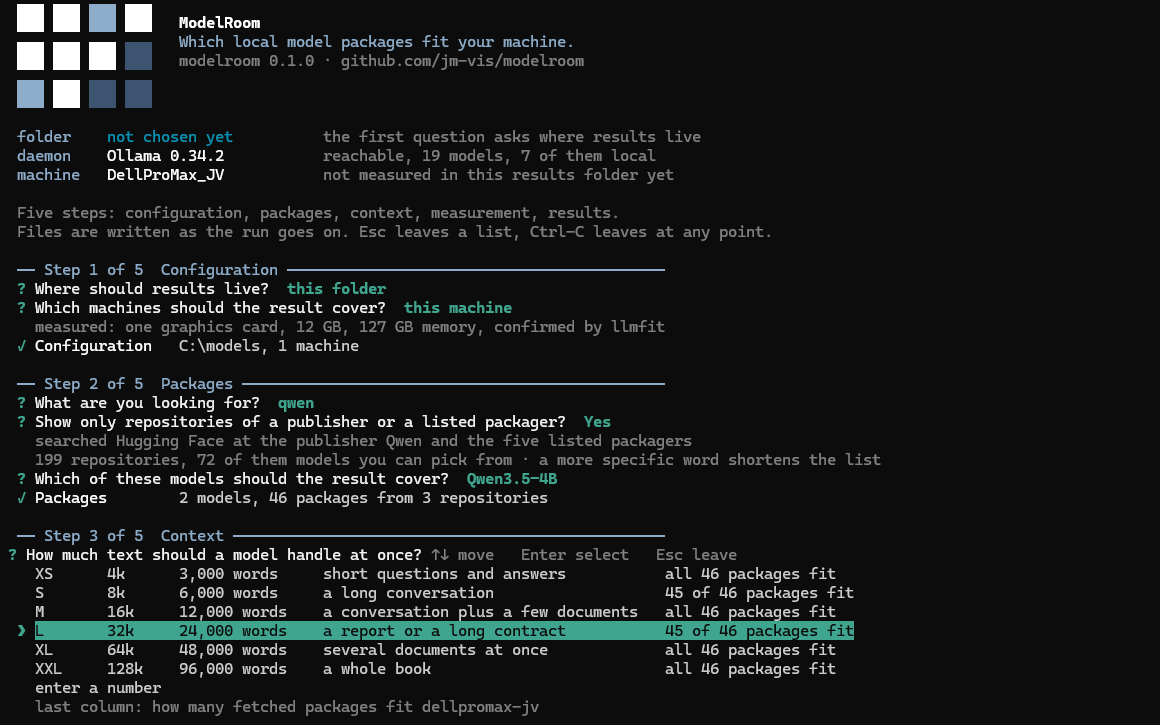
How much text a model should handle at once, as a scale from XS to XXL with the tokens, the words that are and an example. The last column is the point of the question: how many of the packages just fetched still fit this machine at that context, because the memory a model needs grows with the text it holds. L (32k, a report or a long contract) is the default for a new folder; a folder keeps the level it chose last time, and a number of tokens can be typed instead.
Step 4, Measurement
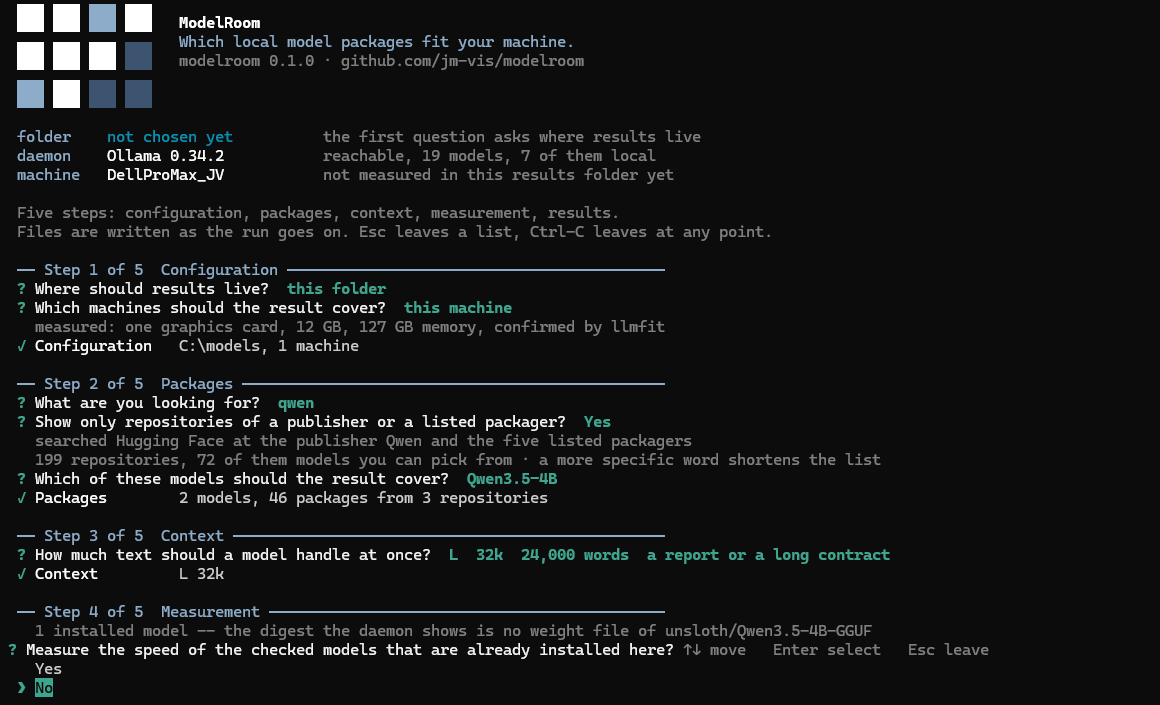
Whether to measure the speed of the packages your local Ollama daemon already has. Yes lists
the installed packages that match this folder's snapshot and lets you pick which to measure; a
measurement runs a short prompt through the package and records tokens per second. It never
downloads anything. The gray line says what was found: here the daemon has a Qwen3.5-4B, but
its weights are Ollama's own build and not one of the fetched packages, so there is nothing to
measure as such. No skips new measurements; a measurement stored earlier for the same package
content at the same context stays in the ranking, and a row without one shows – for speed.
Step 5, Results
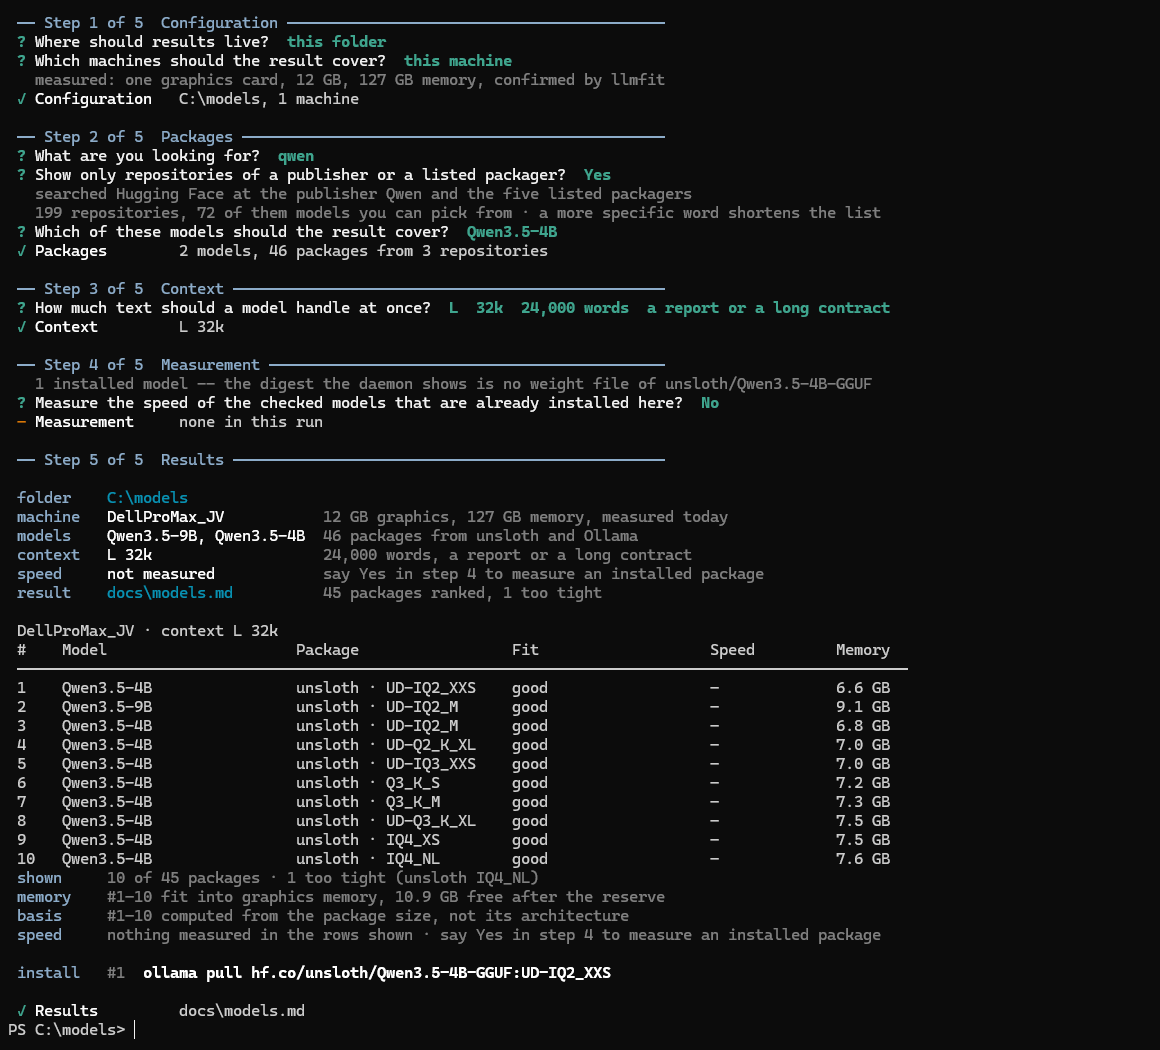
The card of the whole run: folder, machine, models, context, speed, and where the result went. The
folder here already held a configuration from an earlier run naming Qwen3.5-9B; the run added
Qwen3.5-4B to it. Under the card, the ranking for this machine at the chosen context: rank,
model, package (packager and quantization), fit, measured speed, memory need. The notes under the
table say what is shown (ten of 45, one too tight), which rows fit into graphics memory and
which need system memory, which rows have their fit computed from the package size as its
basis rather than from the architecture (the line appears only when there are such rows) and
what was measured for speed. The install line is the command for the first row, ready to
paste. The ranking, the top ten per machine with the totals and what was set aside, is written to
docs/models.md and docs/models.json; what the search asked, page by page, is in
state/search.json next to them.
Nothing in mind
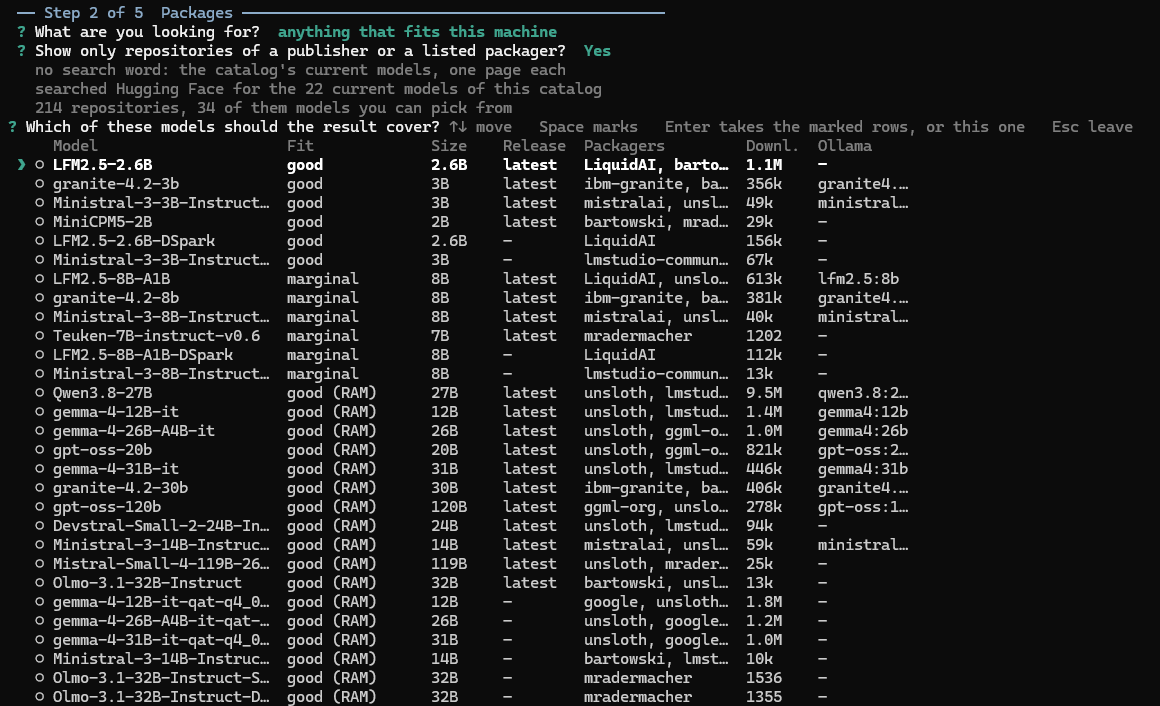
Press Enter on an empty search word and the run looks up the current models of the shipped catalog, one page each, and lists them best fit first: what fits into the graphics card, then what is marginal there, then what needs system memory. This is the answer to "I have no model in mind, show me what fits this machine".
Without a terminal
Every choice is a list with the arrow keys, including yes and no; the search word and a path are
typed. Without an interactive terminal the command prints the help and stops; modelroom --answers <file> takes the answers
from a TOML file instead (for a self-test or CI) -- context there is a level ("L") or a number
of tokens -- and modelroom --config <file> works on that configuration rather than the
remembered folder. See CONTRACTS.md, "Guided mode", for every question and its key.
The six subcommands never ask anything; the guided mode is built on the same measurement, fetch
and render. From a clone of this repository, after uv sync --frozen:
cp modelroom.example.toml modelroom.toml
uv run --frozen modelroom hardware --config modelroom.toml
uv run --frozen modelroom fetch --config modelroom.toml --machine workstation
uv run --frozen modelroom render --config modelroom.toml
cat docs/models.md
- The example configuration names three families, the packagers and publishers it allows,
two machines (
workstation, a writer, andinference-server) and two paths. Relative paths resolve against the configuration file's own directory, never the current working directory. Edit the copy for your own models and machines. hardwaremeasures the machine it runs on and writesstate/hardware/<profile_id>.json. Run it once on every machine you want to size; the machine is remembered in a small pointer file in your home folder, so a second run updates the same profile.--machine <name>is optional and adopts that configuration entry's profile;--cpu-onlyjudges the machine as a CPU machine,--new-identitymeasures a clone as a machine of its own, and--same-machinemeasures this machine again under the profile id it is already bound to -- the answer for a results folder whose profile file is gone. The two exclude each other.fetchqueries the registries and writes the snapshotstate/modelroom.json. The named machine has to be markedwriter = true.renderreads the snapshot and every machine's hardware profile and writes two views: the Markdown one topaths.markdown(docs/models.mdin the example) and the JSON one next to it under the same stem. It takes no--machine. A machine is ranked from the profile its[machines.<name>].profilenames -- the guided mode writes that entry after it has measured the machine. It assumes the context the last guided run of that folder chose ([guided].context), so the ranking it writes is the one that run showed; a configuration no guided run has chosen a context in assumes 8192.- Read the table. Only active, complete packages with
metadata_okorapprovedprovenance are shown, and every one of them is ranked per machine: best fit first, a measured package ahead of an unmeasured one of the same fit class, with the rule and the scenario printed in the header. Packages fit v1 cannot judge stand under "not covered" with the reason, ones that do not fit under "too tight". Every computed number says(computed), the measured speed says(measured).
--config is required by every subcommand; there is no default path.
Files
Under paths.state:
| File | Written by | Kind |
|---|---|---|
modelroom.json |
fetch |
snapshot, versioned contract |
hardware/<profile_id>.json |
hardware, on that machine |
hardware profile, versioned contract |
measurements/<profile_id>/<id>.json |
the load test | speed measurement, versioned contract |
modelroom.lock |
fetch, render |
runtime only, not a contract |
run-status.json |
fetch |
runtime only, not a contract |
The snapshot and the hardware profiles carry a schema_version and can be kept under version
control. The lock file and run-status.json are operating data of one deployment. The lock
file is never deleted: the lock is a kernel lock on it, which the operating system releases
when its holder exits, and a second fetch or render against the same state directory
stops at it instead of waiting.
Publishers the search resolves
The shipped catalog modelroom/catalog.toml names the publisher accounts whose models a search
resolves: with the owner filter on, a hit is selectable when the Hugging Face account of its base
model is one of them, whoever packaged the GGUF build, or when you typed that repository yourself. Those accounts are mistralai, utter-project, openGPT-X,
Qwen, deepseek-ai, meta-llama, google, microsoft, openai, zai-org, moonshotai,
ibm-granite, nvidia, allenai, tiiuae, CohereLabs, LiquidAI, HuggingFaceTB, openbmb,
tencent, baidu and MiniMaxAI. Every row of the catalog carries the page it was read from, and
a model is called latest only with the publisher page or collection that says so and the date it
was checked; without one the age stays unknown.
The list is a preference, not a gate (since 2026-09-25). With the owner filter on -- the default
-- a hit whose base model belongs to an account that is not in that list is no row of the list of
models; it is counted in state/search.json among the owners the catalog does not list. Say no to the
filter and it can be picked like any
other, with its age left at unknown for want of evidence and its owner shown as other; and a
repository you name yourself (unsloth/Qwen3.5-9B-GGUF) is never filtered out at all, whatever the
catalog says about it. If a publisher you use is missing, open an issue in
this repository naming the account and one of its models; the catalog is data in this repository
and takes a new family with its evidence.
What the fit class means
For a judged fit, the cell reads <class> (<mode>, need <n> / pool <n> GiB). The class is
computed from a memory formula: weights plus 10 %, plus a 16-bit KV cache for the context of the
run (the level the guided mode chose for the folder; 8192 for a configuration no guided run has
chosen one in), plus 0.5 GiB. The result is compared with the machine's
VRAM minus its reserve, or with its RAM minus its reserve when it does not fit the GPU.
perfect needs at most 60 % of that pool, good 85 %, marginal 98 %; anything above is
too_tight. Off the GPU the class is capped at good. The full rule is in CONTRACTS.md,
"Fit contract v1".
What it does not say: the class is arithmetic, not a measurement. It makes no statement about tokens per second, output quality or whether a runtime actually loads the package. It is labeled "fit (computed, v1)" in the output for that reason.
Limits of fit v1
- Only a dense transformer architecture is judged from its own layers and heads. A hybrid or
mixture-of-experts architecture is judged from the size of the package instead: the same
formula with the KV cache taken from a constant, shown as
good (from size)and never asperfect. The KV cache in that formula is one fixed assumption, not a bound: a mixture architecture usually needs less, a dense model with many layers more, so agood (from size)is coarser than agoodwith the architecture behind it (CONTRACTS.md, "Fit from size"). - Only complete GGUF packages are judged; other formats are
unknown. - A machine without a hardware profile shows
no profile(orno recommendation: no profile). - Unified memory is not modeled: a machine whose profile records
unified_memorygets no fit from v1, and the automatic graphics measurement covers NVIDIA cards only; on other platforms the graphics side of the profile is recorded asunsupported_platform(CONTRACTS.md, "Hardware profile").
Exit codes
| Code | Meaning |
|---|---|
0 |
success: every fetch area complete; hardware measured and wrote the profile (also when llmfit was not there to cross-check it); render wrote the document (also when its rating source failed) |
1 |
at least one fetch area incomplete (complete areas are still written); or another process holds the lock; or this fetch is not newer than the stored snapshot; or render has no snapshot; or the existing document was rendered from a newer snapshot; or hardware wrote the profile but could not record the binding in the pointer file. Every case but the first and the last leaves the snapshot, hardware profiles, run-status.json and the rendered document unchanged; the lock file may be created or updated |
2 |
the configuration is missing or invalid; the machine is not a writer (fetch) or not configured (hardware); hardware's bound profile is missing or belongs to another machine (run it with --same-machine or --new-identity, never both); or a tool a command requires is missing, older than the minimum, fails, or returns invalid output |
3 |
an unsupported schema_version in the configuration, the snapshot, a hardware profile, the answer file or the pointer file; or one of them is not valid JSON or does not match its model |
130 |
the guided mode was stopped with Ctrl-C; nothing is left half written |
The guided mode ends with 1 when it wrote its document but a step did not finish -- a
measurement that failed, a fetch that did not complete, an import that did not go through.
Those lines are printed as they happen; the run goes on with the machines that are there.
Source: CONTRACTS.md, "Exit codes", and AGENTS.md.
Network access
Requests go only to huggingface.co, ollama.com and registry.ollama.ai over HTTPS and to
the local Ollama daemon at 127.0.0.1:11434 over HTTP; every redirect and pagination link is
checked against the same list before it is followed. HTTP_PROXY, HTTPS_PROXY and
NO_PROXY from the environment are honored for the registries, but a proxy only changes how an
allowed request travels, never which targets are allowed; the local daemon is reached directly. Details: CONTRACTS.md, "Transport security and
proxying".
Language choice
Python, because the catalog logic and Pydantic contracts it integrates with are Python, and the run has to be platform neutral (Windows, Linux, macOS). Everything in this repository, from identifiers to documentation, is English.
Release
For maintainers, from a clean clone at the commit to be released:
uv run --frozen python scripts/release-check.py
uv run --frozen python scripts/release-smoke.py
The first is the release gate (clean tree, version and changelog, public hygiene over the files,
the history and the commit metadata, content of wheel and sdist); with --tag vX.Y.Z it also
checks the release tag. The second installs the built wheel into a fresh environment and runs
hardware, an offline fetch and render against it. Both must end with exit 0; the full
procedure is in AGENTS.md, "Versioning and releases".
Contributing and conventions
AGENTS.md is the tool-neutral rule set for anyone (human or agent) working on this
repository. CONTRACTS.md describes the data shapes and their versioning. Issues and pull
requests are welcome.
About
ModelRoom is built and maintained by VISCONSULT, a consultancy in Germany that runs AI agents for its own work and for clients under EU data-protection rules. We use it to decide which models run on our own laptops and servers, and with clients to size on-premise deployments before anyone buys hardware.
License
MIT, see LICENSE. The machine measurement is cross-checked with llmfit (MIT), which runs as a separate program and is not part of this package.
1 maintainer

Release files for modelroom 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| modelroom-0.1.0.tar.gz | 769.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| modelroom-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.0 MB
Release files / modelroom-0.1.0.tar.gz
| Download URL | modelroom-0.1.0.tar.gz |
|---|---|
| Size | 769.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e47ce738b4ce3012b062a7e3c43f3f5bee256cd8702dcfb0d710d9df75176ab4
|
|
BLAKE2b-256 checksum How to use checksums |
8f962490da7ea36b65989e94f950fa2f17eb183454771fa4fe8e85af0f483447
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.11.7 {"installer":{"name":"uv","version":"0.11.7","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / modelroom-0.1.0-py3-none-any.whl
| Download URL | modelroom-0.1.0-py3-none-any.whl |
|---|---|
| Size | 264.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
00cb4c6544109ac97c5abedc285bed55f247db3e6687d07e088c1f4cf2d1e4f6
|
|
BLAKE2b-256 checksum How to use checksums |
e01450d0926ec507bf8226ba4ebf3f7a5dcf4cc8abb53db080438fc4240902f3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.11.7 {"installer":{"name":"uv","version":"0.11.7","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|













