
vLLM Router
Intelligent load balancer for distributed vLLM server clusters
What problem does it solve?
When you have multiple GPU servers running vLLM, you face:
- Fragmented Resources: Multiple independent GPUs cannot be managed unifiedly
- Unbalanced Load: Some servers are overloaded while others are idle
- Poor Availability: Single server failure affects overall service
vLLM Router provides a unified entry point that intelligently distributes requests to the best servers.
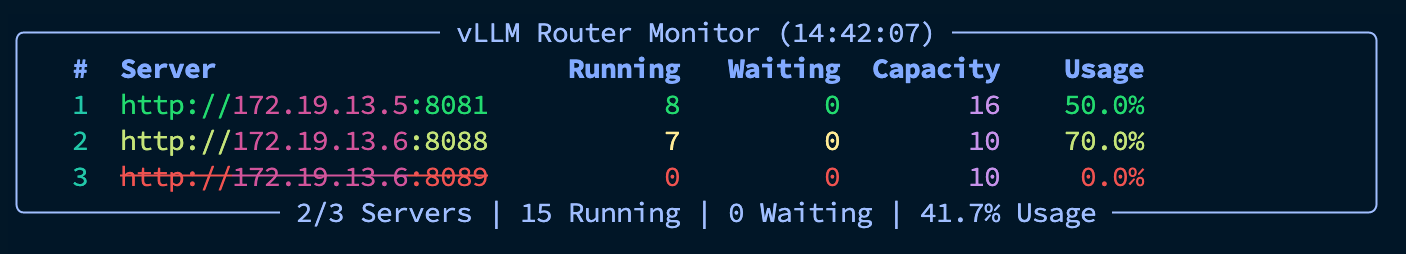
Key Advantages
🎯 Intelligent Load Balancing
- Real-time Monitoring: Direct metrics from vLLM
/metricsendpoints - Smart Algorithm:
(running + waiting * 0.5) / capacity - Priority Selection: Prefers servers with load < 50%
- Zero Queue: Direct forwarding without intermediate queues
🔄 High Availability
- Automatic Failover: Detects and removes unhealthy servers
- Smart Retry: Automatically retries failed requests on other servers
- Hot Reload: Configuration changes without service restart
Quick Start
Installation
git clone https://github.com/xerrors/mvllm.git
pip install -e .

mvllm run
Configuration
Create server configuration file:
cp servers.example.toml servers.toml
Edit servers.toml:
[servers]
servers = [
    { url = "http://gpu-server-1:8081", max_concurrent_requests = 3 },
    { url = "http://gpu-server-2:8088", max_concurrent_requests = 5 },
    { url = "http://gpu-server-3:8089", max_concurrent_requests = 4 },
]

[config]
health_check_interval = 10
request_timeout = 120
max_retries = 3
Running
# Production mode (fullscreen monitoring)
mvllm run

# Development mode (console logging)
mvllm run --console

# Custom port
mvllm run --port 8888
Usage Examples
Chat Completions
curl -X POST http://localhost:8888/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "llama3.1:8b",
    "messages": [
      {"role": "user", "content": "Hello, please introduce yourself"}
    ]
  }'
Check Load Status
curl http://localhost:8888/health
curl http://localhost:8888/load-stats
API Endpoints
POST /v1/chat/completions- Chat completionsPOST /v1/completions- Text completionsGET /v1/models- Model listingGET /health- Health statusGET /load-stats- Load statistics
Deployment
Docker
docker build -t mvllm .
docker run -d -p 8888:8888 -v $(pwd)/servers.toml:/app/servers.toml mvllm
Docker Compose
version: '3.8'
services:
  mvllm:
    build: .
    ports:
      - "8888:8888"
    volumes:
      - ./servers.toml:/app/servers.toml
Configuration
Server Configuration
url: vLLM server addressmax_concurrent_requests: Maximum concurrent requests
Global Configuration
health_check_interval: Health check interval (seconds)request_timeout: Request timeout (seconds)max_retries: Maximum retry attempts
Monitoring
- Real-time Load Monitoring: Shows running and waiting requests per server
- Health Status: Real-time server availability monitoring
- Resource Utilization: GPU cache usage and other metrics
Chinese Version
For Chinese documentation, see README.zh.md
License
MIT License
1 maintainer

Metadata
1 maintainer
Release files for mvllm 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| mvllm-0.1.0.tar.gz | 108.4 kB | Without provenance | Details for mvllm-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| mvllm-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for mvllm-0.1.0-py3-none-any.whl |
Total release size: 131.8 kB
Release files / mvllm-0.1.0.tar.gz
| Download URL | mvllm-0.1.0.tar.gz |
|---|---|
| Size | 108.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
deaa66dc44b8db39e7b33d79cd106cd00af7792cc2f0491fa5acb98be7f1b96e
|
|
BLAKE2b-256 checksum How to use checksums |
be91e8554498c021b84d453e1322b75013d6b8a616da637ae66b1cb97d589792
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.6.17
|
Release files / mvllm-0.1.0-py3-none-any.whl
| Download URL | mvllm-0.1.0-py3-none-any.whl |
|---|---|
| Size | 23.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a8fb247902541e2cddb191b568358996887c55a338b3d8aae6ce474ec67662fc
|
|
BLAKE2b-256 checksum How to use checksums |
c73da3d7ba919778089c3cca413a81041a95e09ec8cf374c10c7b9ba6fdf37a8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.6.17
|
Security for mvllm 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













