
Permission-aware retrieval for RAG.
Every user gets only the chunks they are allowed to read,
whatever vector store, permission system or framework you use.



Documentation · Quickstart · Integrations · Benchmarks · Security model · Changelog
from needtoknow import PermissionedRetriever, MetadataACLAuthorizer, Subject

retriever = PermissionedRetriever(backend, MetadataACLAuthorizer())
result = retriever.retrieve("What are this year's salary bands?", Subject("bob", groups=["engineering"]), k=5)
# result.hits holds only chunks Bob may read. HR documents never reach the prompt.
Why
A RAG assistant over company documents is only as safe as its retrieval step. If the vector search ignores who is asking, an engineer can ask the assistant about salaries and get HR documents summarised back. Every team building internal RAG has to solve this, and most solve it by hand, differently each time.
needtoknow is that layer as a small, tested library:
- Works with what you have. Wrap any search backend and any permission system. The core has no dependencies.
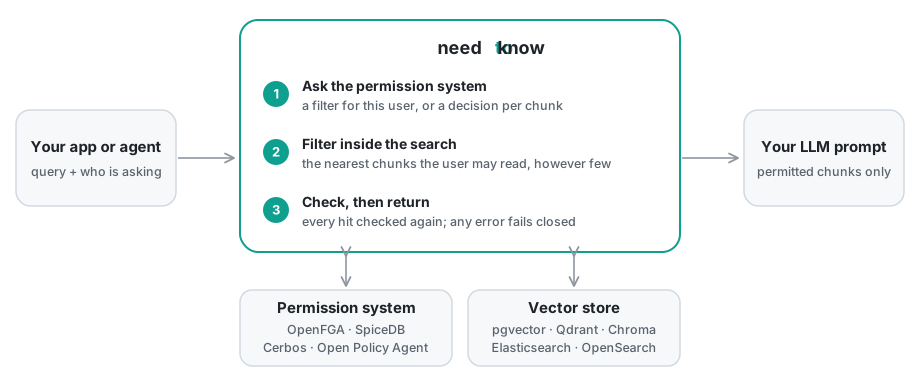
- Filters in the right place. When the permission system can describe "everything Bob may read" as a filter, the filter goes inside the vector search, so results are the true top-k of what Bob may read. When it cannot, candidates are checked after the search and the search widens until enough permitted results are found.
- Fails closed. If the permission service errors, times out or returns malformed answers, the user gets an error, never unfiltered results.
- Defence in depth. Pre-filtered results are checked again, so a backend bug that ignores the filter cannot leak. Each result reports how many such violations it caught.
Install
pip install needtoknow
Python 3.11 or newer: every Python version CPython still supports, each dropped in the first minor release after its end of life. Adapters for external systems install as optional extras.
Quickstart
from needtoknow import Document, InMemoryBackend, MetadataACLAuthorizer, PermissionedRetriever, Subject

backend = InMemoryBackend(
    [
        Document("handbook", "Annual leave is 25 days.", {"allowed_groups": ["*"]}),
        Document("salaries", "Salary bands for 2026 ...", {"allowed_groups": ["hr"]}),
        Document("runbook", "Roll back a failed deploy ...", {"allowed_groups": ["engineering"]}),
    ]
)
retriever = PermissionedRetriever(backend, MetadataACLAuthorizer())

result = retriever.retrieve("leave salary bands", Subject("bob", groups=["engineering"]), k=3)
print([hit.id for hit in result.hits])  # ['handbook']
print(result.strategy, result.complete)  # prefilter True
aretrieve is the async equivalent, with the same arguments and guarantees.
How it works
| Strategy | When | Cost | Result |
|---|---|---|---|
prefilter |
The authorizer can return a filter and the backend supports filters | One search | The exact top-k of what the subject may read |
postfilter |
Any authorizer | Searches k × overfetch candidates, widening up to max_candidates |
Exact when enough permitted candidates exist; complete=False otherwise |
auto (default) |
Picks prefilter when both sides support it |
Every call returns a RetrievalResult with the hits plus strategy, examined, denied,
violations (pre-filtered hits the re-check rejected, which should always be 0) and complete.
Integrations
Each integration is an optional extra, so the core stays dependency-free.
| Integration | Kind | Install | Where permissions apply |
|---|---|---|---|
| PostgreSQL + pgvector | Vector store | needtoknow[pgvector] |
Inside the SQL query |
| Qdrant | Vector store | needtoknow[qdrant] |
Qdrant's query_filter |
| Milvus | Vector store | needtoknow[milvus] |
Inside the vector search, with parameterized filters |
| MongoDB Atlas Vector Search | Vector store | needtoknow[mongodb] |
The $vectorSearch pre-filter |
| Weaviate | Vector store | needtoknow[weaviate] |
Inside the vector search |
| Redis | Vector store | needtoknow[redis] |
In the same KNN query, on hex-encoded terms |
| LanceDB | Vector store, embedded | needtoknow[lancedb] |
Before the vector search ranks, on hex-encoded terms |
| Elasticsearch, OpenSearch | Vector store | needtoknow[elasticsearch], [opensearch] |
Inside the kNN search |
| Chroma | Vector store | needtoknow[chroma] |
Chroma's where clause |
| OpenFGA | Permission system | none | ListObjects pre-filter, batched checks |
| SpiceDB | Permission system | none | LookupResources pre-filter, bulk checks |
| Cerbos | Permission system | none | Pre-filter from query plans |
| Cedar | Permission system, in process | needtoknow[cedar] |
Post-filter |
| Open Policy Agent | Permission system | none | Pre-filter when the policy returns one |
| Google Drive | Permission sync | none (bring Google's client) | Copies Drive sharing onto the chunks |
| LangChain | Framework | needtoknow[langchain] |
Retriever and agent tools; any store |
| LlamaIndex | Framework | needtoknow[llamaindex] |
Retriever and postprocessor; any index |
| Haystack | Framework | needtoknow[haystack] |
Retriever component; any needtoknow backend |
| MCP | Agent tool server | needtoknow[mcp] |
Search tool; the user comes from the verified token |
Setup for each, with code:
PostgreSQL + pgvector
PostgreSQL + pgvector (pip install "needtoknow[pgvector]", pgvector 0.8+). The permission
filter runs inside the SQL query as JSON containment tests, served by a GIN index, and iterative
index scans keep HNSW returning k rows under selective filters.
from psycopg_pool import ConnectionPool

from needtoknow.backends.pgvector import PgVectorBackend, create_schema

pool = ConnectionPool("postgresql://localhost/app")
create_schema(pool, dim=768)
backend = PgVectorBackend(pool, embed=my_embedding_model)  # embed: str -> list[float]
backend.add(documents)
Chroma
Chroma (pip install "needtoknow[chroma]"). The filter becomes Chroma's where clause. Each
value in a permission list is stored as its own field rather than as a Chroma array, and an exact
copy of the metadata is kept for the re-check: in chromadb 1.5.x, deleting a collection leaves its
array metadata behind for new records in other collections to pick up
(chroma-core/chroma#7594), which for
permissions would be a leak.
import chromadb

from needtoknow.backends.chroma import ChromaBackend

collection = chromadb.PersistentClient(path="./chroma").get_or_create_collection("docs")
backend = ChromaBackend(collection)  # uses the collection's embedding function
Qdrant
Qdrant (pip install "needtoknow[qdrant]"). The filter becomes Qdrant's query_filter, served
by payload indexes on the permission fields. Points use the layout of LangChain's Qdrant
integration, so a collection built with LangChain can be searched with permissions as it is.
from qdrant_client import QdrantClient

from needtoknow.backends.qdrant import QdrantBackend, create_collection

client = QdrantClient(url="http://localhost:6333")
create_collection(client, "docs", dim=768)
backend = QdrantBackend(client, "docs", embed=my_embedding_model)
create_collection(..., text_search=True) adds a BM25 sparse vector, and
QdrantBackend(client, "docs", mode="keyword") then ranks by BM25 under the same filter, for hybrid
search with RankFusion.
Milvus
Milvus (pip install "needtoknow[milvus]"). The filter runs inside Milvus's vector search.
Permissions are matched on a type-tagged array field, and the values are passed as filter
parameters, never written into the expression, so a group name cannot change what a filter
selects.
from pymilvus import MilvusClient

from needtoknow.backends.milvus import MilvusBackend, create_collection

client = MilvusClient(uri="http://localhost:19530")
create_collection(client, "docs", dim=768)
backend = MilvusBackend(client, "docs", embed=my_embedding_model)
create_collection(..., text_search=True) also derives a BM25 sparse vector from the text, and
MilvusBackend(client, "docs", mode="keyword") then searches it under the same filter, for hybrid
search with RankFusion.
MongoDB Atlas Vector Search
MongoDB Atlas Vector Search (pip install "needtoknow[mongodb]"). The filter is the
$vectorSearch pre-filter, on a type-tagged array field. Atlas indexes writes a moment after they
happen, so add and delete wait until the index shows them, including a chunk's new
permissions.
from pymongo import MongoClient

from needtoknow.backends.mongodb import MongoDBBackend, create_search_index

collection = MongoClient(MONGODB_URI)["rag"]["chunks"]
create_search_index(collection, dim=768)
backend = MongoDBBackend(collection, embed=my_embedding_model)
create_text_index(collection) adds an Atlas Search index on the text, and
MongoDBBackend(collection, mode="keyword") then runs BM25 under the same filter, for hybrid search
with RankFusion.
Weaviate
Weaviate (pip install "needtoknow[weaviate]"). The filter runs inside Weaviate's vector
search, on a type-tagged text[] property with field tokenization, so terms match exactly, case
and whitespace included. The metadata is stored as JSON and returned as written.
import weaviate

from needtoknow.backends.weaviate import WeaviateBackend, create_collection

client = weaviate.connect_to_local()
create_collection(client, "Chunks")
backend = WeaviateBackend(client, "Chunks", embed=my_embedding_model)
Redis
Redis (pip install "needtoknow[redis]"). A KNN query on the Redis Query Engine (Redis 8 or
later, or Redis Stack) with the permission filter in the same query. Permission terms are stored
hex-encoded, so no group name can add query syntax and case never merges two values.
import redis

from needtoknow.backends.redis import RedisBackend, create_index

client = redis.Redis.from_url(REDIS_URL)
create_index(client, "chunks", dim=768)
backend = RedisBackend(client, "chunks", embed=my_embedding_model)
create_index(..., content_field="content") also indexes the text, and
RedisBackend(client, "chunks", mode="keyword") then runs BM25 under the same filter, for hybrid
search with RankFusion.
LanceDB
LanceDB (pip install "needtoknow[lancedb]"). An embedded vector database, on a local directory
or object storage, with no server to run. The permission filter is applied before the vector
search ranks, on hex-encoded terms, so no group name or user id is ever part of the SQL.
import lancedb

from needtoknow.backends.lancedb import LanceDBBackend, create_table

table = create_table(lancedb.connect("data/chunks"), "chunks", dim=768)
backend = LanceDBBackend(table, embed=my_embedding_model)
create_indexes(table, content_field="content") builds a full-text index, and
LanceDBBackend(table, mode="keyword") then runs BM25 under the same filter, for hybrid search with
RankFusion.
Elasticsearch and OpenSearch
Elasticsearch and OpenSearch (pip install "needtoknow[elasticsearch]" or [opensearch]).
The filter runs inside the kNN search. Permissions are matched on a type-tagged keyword field, so
the integer 1 and the string "1" stay different values, as the reference semantics require.
from elasticsearch import Elasticsearch

from needtoknow.backends.elasticsearch import ElasticsearchBackend, create_index

client = Elasticsearch("http://localhost:9200")
create_index(client, "docs", dim=768)
backend = ElasticsearchBackend(client, "docs", embed=my_embedding_model)
mode="keyword" runs BM25 on the same index under the same filter. RankFusion(vector, keyword)
fuses the two into hybrid search, and fuses any other backends the same way
(hybrid search).
Open Policy Agent
Open Policy Agent (no extra dependency). Your Rego policy returns one decision per chunk, and
can optionally return a filter so the vector store does the filtering. A complete policy is in
examples/opa/needtoknow.rego.
from needtoknow.authorizers.opa import OPAAuthorizer

authorizer = OPAAuthorizer("http://localhost:8181", filter_path="needtoknow/filter")
OpenFGA
OpenFGA (no extra dependency). Relationship-based access control in the Google Zanzibar style. Checks run in batches; for pre-filtering, ListObjects returns every document the user may view, and if that list may have been truncated the retriever post-filters instead. The subject's groups can be sent as contextual tuples, so memberships from your identity provider need no syncing.
from needtoknow.authorizers.openfga import OpenFGAAuthorizer

authorizer = OpenFGAAuthorizer("http://localhost:8080", store_id, resource_field="doc_id")
SpiceDB
SpiceDB (no extra dependency). Zanzibar-style permissions through SpiceDB's HTTP API.
CheckBulkPermissions decides each chunk, LookupResources gives the pre-filter, and the subject's
groups are checked as subject sets (group:<name>#member), so memberships from your identity
provider need no syncing.
from needtoknow.authorizers.spicedb import SpiceDBAuthorizer

authorizer = SpiceDBAuthorizer("http://localhost:8443", token=spicedb_key, resource_field="doc_id")
Cerbos
Cerbos (no extra dependency). Each chunk is a Cerbos resource whose attributes are its
metadata. Pre-filters come from Cerbos query plans: the conditions a vector store can apply
exactly are translated into a filter, and anything else is post-filtered with Cerbos deciding each
chunk. An example policy is in
examples/cerbos.
from needtoknow.authorizers.cerbos import CerbosAuthorizer

authorizer = CerbosAuthorizer("http://localhost:3592")
Google Drive
Google Drive (bring google-api-python-client). GoogleDriveACL reads who may read a Drive
file, in My Drive or a shared drive, and with_access writes it onto the file's chunks for
MetadataACLAuthorizer. Grants that do not open the content fail closed: link-only sharing,
deleted accounts, expired grants, limited-access folders' metadata views and grants a shared drive
shuts out grant nothing.
from needtoknow.sync import with_access
from needtoknow.sync.google_drive import GoogleDriveACL

access = GoogleDriveACL(drive_service, domains=["example.com"]).access(file_id)
backend.set_metadata({cid: with_access(metadata, access) for cid, metadata in chunks.items()})
LangChain
LangChain (pip install "needtoknow[langchain]"). NeedToKnowRetriever is a LangChain
retriever, so it works in chains, agents and LangGraph tools; LangChainVectorStoreBackend turns
any LangChain vector store into a needtoknow backend (post-filtered).
from needtoknow.langchain import NeedToKnowRetriever

retriever = NeedToKnowRetriever(retriever=PermissionedRetriever(backend, authorizer))
docs = retriever.invoke("What are this year's salary bands?", subject=Subject("bob", ["sales"]))
LlamaIndex
LlamaIndex (pip install "needtoknow[llamaindex]"). NeedToKnowRetriever for query and chat
engines, PermissionNodePostprocessor for existing pipelines, and LlamaIndexBackend to wrap an
existing index. Runnable examples for both frameworks are in examples/.
Haystack
Haystack (pip install "needtoknow[haystack]"). NeedToKnowRetriever is a pipeline component
over any needtoknow backend and authorizer. The authenticated user is a run input, so one pipeline
serves every user; it outputs documents and complete, and has run_async.
from haystack import Pipeline

from needtoknow.haystack import NeedToKnowRetriever

pipeline = Pipeline()
pipeline.add_component("retriever", NeedToKnowRetriever(PermissionedRetriever(backend, authorizer)))
result = pipeline.run({"retriever": {"query": question, "subject": subject}})
MCP
MCP (pip install "needtoknow[mcp]"). add_search_tool gives an MCP server a search tool for
AI assistants and agents. Whose permissions apply comes from the access token the server verified,
never from the tool's arguments, and a call without a verified token is refused.
from needtoknow.mcp import add_search_tool


def subject_for(token):  # the verified token's user, with their groups
    return Subject(token.subject, groups_of(token.subject))


add_search_tool(server, PermissionedRetriever(backend, authorizer), subject_for)
server.run(transport="streamable-http")
Filter values are strings or integers, the types permission identifiers use. That keeps every backend's answer identical to the reference semantics, which the test suite checks for each one.
Caching, audit, tracing and metrics
from needtoknow import CachingAuthorizer, JsonLinesAudit
from needtoknow.otel import OpenTelemetryMetrics, OpenTelemetryObserver  # pip install "needtoknow[otel]"

retriever = PermissionedRetriever(
    backend,
    CachingAuthorizer(authorizer, ttl=30),  # a revoked permission stops granting access within 30 s
    observers=[JsonLinesAudit(audit_file), OpenTelemetryObserver(), OpenTelemetryMetrics()],
    audit_key=b"...",  # optional: an HMAC of each query, so repeats can be matched without storing them
)
CachingAuthorizer caches pre-filters and per-chunk decisions per subject for ttl seconds and
never caches an error; invalidate() drops decisions after a change you know about. Every
retrieval, including failed ones, produces one RetrievalEvent (who asked, strategy, returned ids,
denied and violation counts, time spent in the backend and the authorizer, error type).
JsonLinesAudit writes each one to audit_file, an open text file; OpenTelemetryObserver turns
it into a span and OpenTelemetryMetrics into counters and latency histograms. Events never
contain query or chunk text, and an observer that fails is logged without affecting retrieval.
Bring your own backend or permission system
A backend is any object with a search method:
class MyBackend:
    supports_filters = True  # set False if search() ignores `filter`

    def search(self, query: str, k: int, filter=None) -> list[Hit]:
        """Return hits best first. Translate `filter` (In / And / Or) into your store's filter."""
An authorizer answers two questions:
class MyAuthorizer:
    def check(self, subject, hits, action="read") -> list[bool]:
        """One decision per hit, in order. Raise on any doubt: the retriever fails closed."""

    def filter_for(self, subject, action="read"):
        """A Filter selecting everything the subject may read, or None if you cannot express one."""
Either can add async versions (asearch, acheck, afilter_for); otherwise the sync methods
run in a thread under aretrieve. FunctionAuthorizer wraps a plain function.
Testing approach
The guarantees are tested as properties with Hypothesis: for randomly generated corpora, permissions, users and queries, every strategy must
- never return a chunk the user may not read,
- return exactly the top-k of what the user may read (checked against an independent oracle),
- stay safe when the backend ignores the filter, and
- give identical results through
retrieveandaretrieve.
Benchmarks
On 57,600 real chunks (BEIR FiQA, Qwen3-Embedding-0.6B), across 33,000 retrievals, no needtoknow strategy returned a single forbidden chunk. Filtering inside the search kept recall@10 at 0.949 or better on pgvector for users who may read anywhere from 0.06% to 100% of the corpus, including when what they may read is far from what they ask about. Filtering after a top-10 search found almost nothing for selective permissions. Method, tables and caveats: Benchmarks.
| Readable (far from the query) | Naive top-k, then filter | needtoknow postfilter | needtoknow prefilter (pgvector) |
|---|---|---|---|
| 0.9% | 0.000 | 0.048 | 0.995 |
| 4.8% | 0.000 | 0.314 | 0.950 |
| 20% | 0.041 | 0.974 | 0.949 |
At a million chunks (MS MARCO in PostgreSQL + pgvector, on 4 CPUs), pre-filtering kept recall@10
between 0.88 and 0.97 for users who may read 0.1% to 100% of the corpus, at a median of 3 to 21 ms
one query at a time; the machine served up to 126 requests a second. Open Policy Agent as the
permission service cost 8 to 9% of throughput, and CachingAuthorizer recovered nearly all of it. No
retrieval leaked: none of the 185,040 chunks returned under concurrent load, each checked against its
user's permissions, and none one at a time, there or on Qdrant, Elasticsearch, OpenSearch and
Weaviate measured the same way on the same million chunks (benchmarks).
Stability and roadmap
1.0 is the stable base: the core, the pgvector and Chroma backends, the OPA and OpenFGA authorizers, the LangChain and LlamaIndex integrations, caching, audit events and tracing. The public API in the API reference follows semantic versioning: no breaking change without a major version and a deprecation period first.
Since 1.0, 1.1 added resilient connections to remote permission services and signed, verifiable releases. 1.2 added the Qdrant, Milvus, Elasticsearch and OpenSearch backends, the SpiceDB and Cerbos authorizers, combined and multi-tenant authorizers, a permission cache shared across replicas, OpenTelemetry metrics and a conformance kit. 1.3 added hybrid search, reranking after the permission check, searches with your own vectors, permission changes without re-embedding, an MCP search tool for AI agents, a Haystack component, and the MongoDB Atlas, Weaviate, Redis and LanceDB backends. 1.4 added keyword search on every store, the Cedar authorizer and permission sync from Google Drive. Next, in rough order: permission sync from SharePoint and Confluence, and more vector stores. Contributions are welcome; see CONTRIBUTING.md.
Example deployment
examples/gateway is a complete, self-hosted, OpenAI-compatible gateway built
on the same ideas: OPA policies, pgvector hybrid search with the ACL inside the query, PII
pseudonymisation, prompt-injection quarantine and a hash-chained audit log. It is being ported onto
this library.
Community and support
- Questions and bugs: GitHub issues.
- Security reports: privately, as SECURITY.md describes; it also shows how to verify a release's signatures.
- Contributing: CONTRIBUTING.md, GOVERNANCE.md and the code of conduct.
- Citing: CITATION.cff, or "Cite this repository" on GitHub.
License
1 maintainer

Metadata
1 maintainer
Release files for needtoknow 1.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| needtoknow-1.4.0.tar.gz | 190.0 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| needtoknow-1.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 316.2 kB
Release files / needtoknow-1.4.0.tar.gz
| Download URL | needtoknow-1.4.0.tar.gz |
|---|---|
| Size | 190.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cf0810c372191d721469e72ad7fd9515dcf5f1e75f6db8061ae5fbdd3d31f4a8
|
|
BLAKE2b-256 checksum How to use checksums |
7bf4844d06fb8524d955a286b05541f8c17b744649224e7c0a982eaa152b68ed
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 22, 2026.
Transparency logRelease files / needtoknow-1.4.0-py3-none-any.whl
| Download URL | needtoknow-1.4.0-py3-none-any.whl |
|---|---|
| Size | 126.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
12178011bb2aaa9fccf965aa16c96cac7fa7a64bab7eb39bebfe41a389b8cc6d
|
|
BLAKE2b-256 checksum How to use checksums |
db9f54a6af2310d3d7475594e56b84eb431e5943f14fce118838323a8e29e2f8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 22, 2026.
Transparency logSecurity for needtoknow 1.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for needtoknow-1.4.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 22, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














