



Nlptutti: 한국어 STT 평가 패키지
nlptutti는 한국어 STT(Speech-to-Text) 출력의 CER, WER, CRR, 키워드와
개체명 보존 성능을 계산하고 여러 시스템의 결과를 재현 가능한 JSON과
Markdown으로 비교하는 Python 패키지입니다.
Microsoft Azure Speech, Amazon Transcribe, Google Cloud Speech-to-Text 같은 클라우드 STT와 OpenAI Whisper, FunASR 같은 오픈소스 도구가 만든 출력을 평가합니다. 음성을 전사하거나 모델을 내려받는 패키지는 아닙니다.
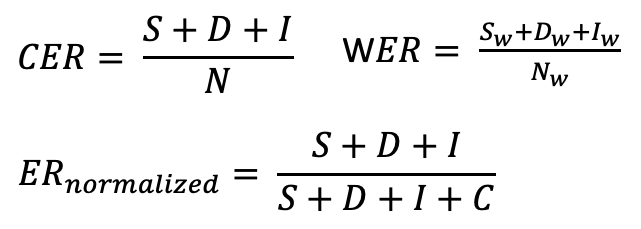
S 치환 · D 삭제 · I 삽입 · N 참조 단위 수 · C 정답 일치 수
1분 빠른 시작
1. 설치
python -m pip install -U nlptutti
python -c "import nlptutti; print('nlptutti ready')"
성공하면 nlptutti ready가 출력됩니다. Python 3.8부터 3.14까지의 환경을
CI에서 테스트합니다.
2. 한 문장 평가
import nlptutti as metrics

result = metrics.get_cer(
    "오늘 날씨가 맑습니다",
    "오늘 날씨는 맑습니다",
    rate_mode="standard",
)

print(round(result["cer"], 4))       # 0.1111
print(result["substitutions"])       # 1
CER와 WER는 낮을수록 좋고 완전 일치는 0.0입니다. CRR은 높을수록 좋고
완전 일치는 1.0입니다.
3. 두 STT 시스템 비교
import nlptutti as metrics

report = metrics.compare_systems(
    ["오늘 날씨가 맑습니다", "서울은 따뜻합니다"],
    {
        "baseline": ["오늘 날씨는 맑습니다", "서울은 춥습니다"],
        "candidate": ["오늘 날씨가 맑습니다", "서울은 따뜻합니다"],
    },
    rate_mode="standard",
)

for system in report["systems"]:
    print(
        system["id"],
        round(system["metrics"]["cer"]["micro"], 4),
        round(system["metrics"]["wer"]["micro"], 4),
    )

# baseline 0.2353 0.4
# candidate 0.0 0.0
micro는 코퍼스 전체의 편집 횟수를 합산한 점수이고, macro는 문장별 점수의
단순 평균입니다. 논문이나 모델 벤치마크에서는 보통 rate_mode="standard"와
micro를 먼저 봅니다.
4. JSON과 Markdown으로 저장
저장소의 examples/comparison_input.json은
바로 위 Python 예제와 같은 입력입니다.
python -c "from urllib.request import urlretrieve; urlretrieve('https://raw.githubusercontent.com/hyeonsangjeon/computing-Korean-STT-error-rates/main/examples/comparison_input.json', 'comparison_input.json')"
nlptutti compare comparison_input.json \
  --rate-mode standard \
  --output-dir comparison-report
성공하면 다음 두 파일이 생성됩니다.
comparison-report/report.json
comparison-report/report.md
report.json은 자동화에서 읽는 버전 스키마이고, report.md는 사람이 검토할
표입니다. 입력, 옵션, 패키지 버전이 같으면 실행할 때마다 같은 내용을 만듭니다.
문장 전체를 담는 raw_inputs는 include_transcripts=True 또는
--include-transcripts를 선택할 때만 추가됩니다. 다만 기존 상세 모드에는
키워드·개체명 이름, 개체명 오류 구간, 진단 토큰이 남을 수 있습니다.
0.0.0.23부터 외부 공유용 보고서는 privacy_mode="aggregate" 또는
--privacy-mode aggregate를 지정하세요. 사전·라벨·오류 텍스트를 제외하고
시스템 이름도 system-1, system-2로 바꿉니다. 점수는 그대로이며 원문 포함
옵션과 함께 쓸 수 없습니다. 기존 코드 호환을 위해 기본값은 "detailed"로
유지합니다. 해시와 집계값만 남겨도 익명성이 보장되는 것은 아닙니다.
입력 형식, 오류 처리, paired bootstrap과 결과 해석은 시스템 비교 매뉴얼에 정리했습니다.
기본값부터 확인하기
기존 사용자 결과를 바꾸지 않기 위해 정규화 관련 기본값은 그대로 유지합니다.
| 옵션 | 기본값 | 의미 |
|---|---|---|
rate_mode |
"normalized" |
삽입 오류를 분모에도 넣는 Nlptutti 기존 계산식입니다. 입력 문자열을 바꾸는 옵션이 아닙니다. |
rate_mode="standard" |
직접 지정 | 참조 길이를 분모로 쓰는 표준 CER/WER입니다. 삽입이 많으면 1보다 클 수 있습니다. |
rm_punctuation |
True |
평가 전에 문장부호를 제거합니다. CER/CRR은 이 값과 관계없이 공백을 제거합니다. |
unicode_normalization |
None |
Unicode 표현을 그대로 둡니다. 조합형 혼입을 정리할 때만 "NFC" 등을 지정합니다. |
비교 API에서 선택한 Unicode 정규화는 키워드·개체명 사전과 조사·어미에도
적용합니다. 단독 evaluate_keywords에서도 같은 옵션을 선택할 수 있습니다.
키워드 매칭은 구두점을 제거하지 않으므로 C++와 C를 다르게 봅니다.
기존 결과를 재현할 때는 기본 normalized를 유지하고, 새 공식 비교에서는
standard를 직접 지정합니다. 두 모드의 숫자는 같은 열에서 비교하면 안
됩니다.
어떤 함수를 선택할까
| 목적 | API | 성공 기준과 경계 |
|---|---|---|
| 문자 전사 품질 | get_cer |
낮을수록 좋습니다. 공백을 항상 제거하므로 띄어쓰기 자체는 평가하지 않습니다. |
| 단어·띄어쓰기 포함 품질 | get_wer |
낮을수록 좋습니다. 시스템 간 토큰화 정책을 같게 맞춰야 합니다. |
| 높을수록 좋은 문자 지표 | get_crr |
round(1 - CER, 2)인 보조 지표입니다. 독립 정렬 점수가 아닙니다. |
| 여러 문장 micro/macro | evaluate_corpus |
같은 길이의 reference와 hypothesis 목록이 필요합니다. |
| 둘 이상의 시스템 비교 | compare_systems |
정렬된 입력, 시스템별 점수, pairwise delta를 반환합니다. |
| 핵심어 누락·오탐 | evaluate_keywords |
제공한 키워드 사전의 precision, recall, F1을 계산합니다. |
| 개체명 구간 품질 | evaluate_entities |
제공한 개체명 사전의 Entity CER와 언급 F1을 계산합니다. NER 모델은 아닙니다. |
| 오류 원인 확인 | explain_errors |
문자 또는 단어 정렬과 상위 치환·삭제·삽입을 반환합니다. |
| JSON·SRT·TSV 평가 | parse_transcript + evaluate_transcript |
필드와 시간 단위를 검증하고 평가 provenance를 남깁니다. |
선택 기능
Paired bootstrap 신뢰구간
문장 쌍을 유지한 채 percentile bootstrap을 실행하면 pairwise CER/WER delta의
신뢰구간도 보고서에 남습니다. 기본값 bootstrap=0에서는 실행하지 않습니다.
report = metrics.compare_systems(
    references,
    systems,
    rate_mode="standard",
    bootstrap=1000,
    seed=42,
    confidence=0.95,
)
한국어 오류 진단
diagnostic_profile="korean-v1"을 지정하면 띄어쓰기 경계, 숫자·단위,
조사·어미 인접 치환, 상위 문자 편집을 따로 보여 줍니다. 전체 CER/WER에는
영향을 주지 않으며 기본값은 None입니다. 숫자·단위와 조사·어미 규칙은
형태소 분석이 아닌 experimental 단계의 휴리스틱입니다.
자세한 규칙과 오분류 가능성은 한국어 오류 진단 프로필에 정리했습니다.
STT 도구별 JSON 읽기
parse_provider_transcript()는 네트워크나 SDK를 사용하지 않고 저장된 JSON만
읽습니다. 현재 테스트로 확인한 형식은 다음 두 가지입니다.
- Microsoft Azure Speech short-audio REST
simple성공 응답 - 오픈소스
openai/whisper의transcribe()반환 구조
공급자와 schema version은 반드시 직접 지정해야 하며 자동으로 감지하지
않습니다. Azure의 다른 REST 형식, OpenAI API, AWS, Google, FunASR 전용 형식은
현재 지원 범위에 포함되지 않습니다. 일반 text/JSON/SRT/TSV는 특정 공급자에
종속되지 않는 parse_transcript()로 평가할 수 있습니다.
지원 필드와 공식 출처는 공급자 출력 어댑터에 정리했습니다.
문서
- 한국어 사용자 매뉴얼
- 시스템 비교와 결과 번들
- 비교 JSON schema
- 구조화 STT 결과
- 한국어 오류 진단
- Azure Speech·Whisper 출력 어댑터
- 정렬 커널과 성능 기준선
- 공개 채택 지표 기준선과 30·60·90일 검토
이 패키지를 만든 배경과 한국어 ASR/STT 평가 실험은 한국어 프롤로그와 영문 글에 정리되어 있습니다.
계산식
표준 CER/WER는 치환(S), 삭제(D), 삽입(I), 정답 토큰(C)을 사용합니다.
standard:   (S + D + I) / (S + D + C)
normalized: (S + D + I) / (S + D + I + C)
구현은 Levenshtein 최소 편집거리를 사용합니다. backtrace가 필요한 오류 설명과 개체명 평가는 동률일 때 선택 순서가 고정된 같은 정렬 커널을 사용합니다.
관련 논문과 공개 구현
- Galibert et al., Generating Task-Pertinent sorted Error Lists for Speech Recognition, LREC 2016.
- Le-Duc et al., Medical Spoken Named Entity Recognition, NAACL 2025.
- Szymański et al., Why Aren't We NER Yet?, ACL 2023.
- Gong et al., BR-ASR, Interspeech 2025.
- K et al., Advocating Character Error Rate for Multilingual ASR Evaluation, NAACL 2025 Findings.
- ContextASR-Bench 평가 코드
- Teklia
ie-eval - PIER
evaluate_entities()는 위 구현을 포팅한 코드가 아닙니다. 공통 평가 원칙을
한국어 문자 span과 aliases로 직접 지정하는 별칭 정책에 맞춰 독립 구현했으며
차이는
test_entity_reference_implementations.py에
고정했습니다.
라이선스
코드는 MIT License로 배포됩니다. 이 저장소는 STT 모델, 가중치, 음성 데이터셋을 포함하지 않으며 외부 모델·데이터의 라이선스는 각각 별도로 확인해야 합니다.
1 maintainer

Metadata
1 maintainer
Release files for nlptutti 0.0.0.23
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| nlptutti-0.0.0.23.tar.gz | 153.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| nlptutti-0.0.0.23-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 199.6 kB
Release files / nlptutti-0.0.0.23.tar.gz
| Download URL | nlptutti-0.0.0.23.tar.gz |
|---|---|
| Size | 153.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a4a89789862af3b83398a4ccd0b244d152d3e29f31a4b55402a47dbcc3944e53
|
|
BLAKE2b-256 checksum How to use checksums |
22967caf7c08439d41a1f3463766d97fe8b881057d807a181e28a5f2d90e8c1e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 2, 2026.
Transparency logRelease files / nlptutti-0.0.0.23-py3-none-any.whl
| Download URL | nlptutti-0.0.0.23-py3-none-any.whl |
|---|---|
| Size | 46.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
37bb24c8c6649d4be4c0e103ba0d30cdb988db33cc9f1dd10c8820fdb8ecfd3f
|
|
BLAKE2b-256 checksum How to use checksums |
ff6c088c1662c9cd777bf4bb6ee4ff43bd43d92c4dde7027bec2919dd7439800
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 2, 2026.
Transparency log













