
normalize-tabular-data
A terminal UI (Textual) for interactively normalizing tabular data, backed by polars for speed and gnosis-date-parser for fuzzy date parsing at Rust speed.
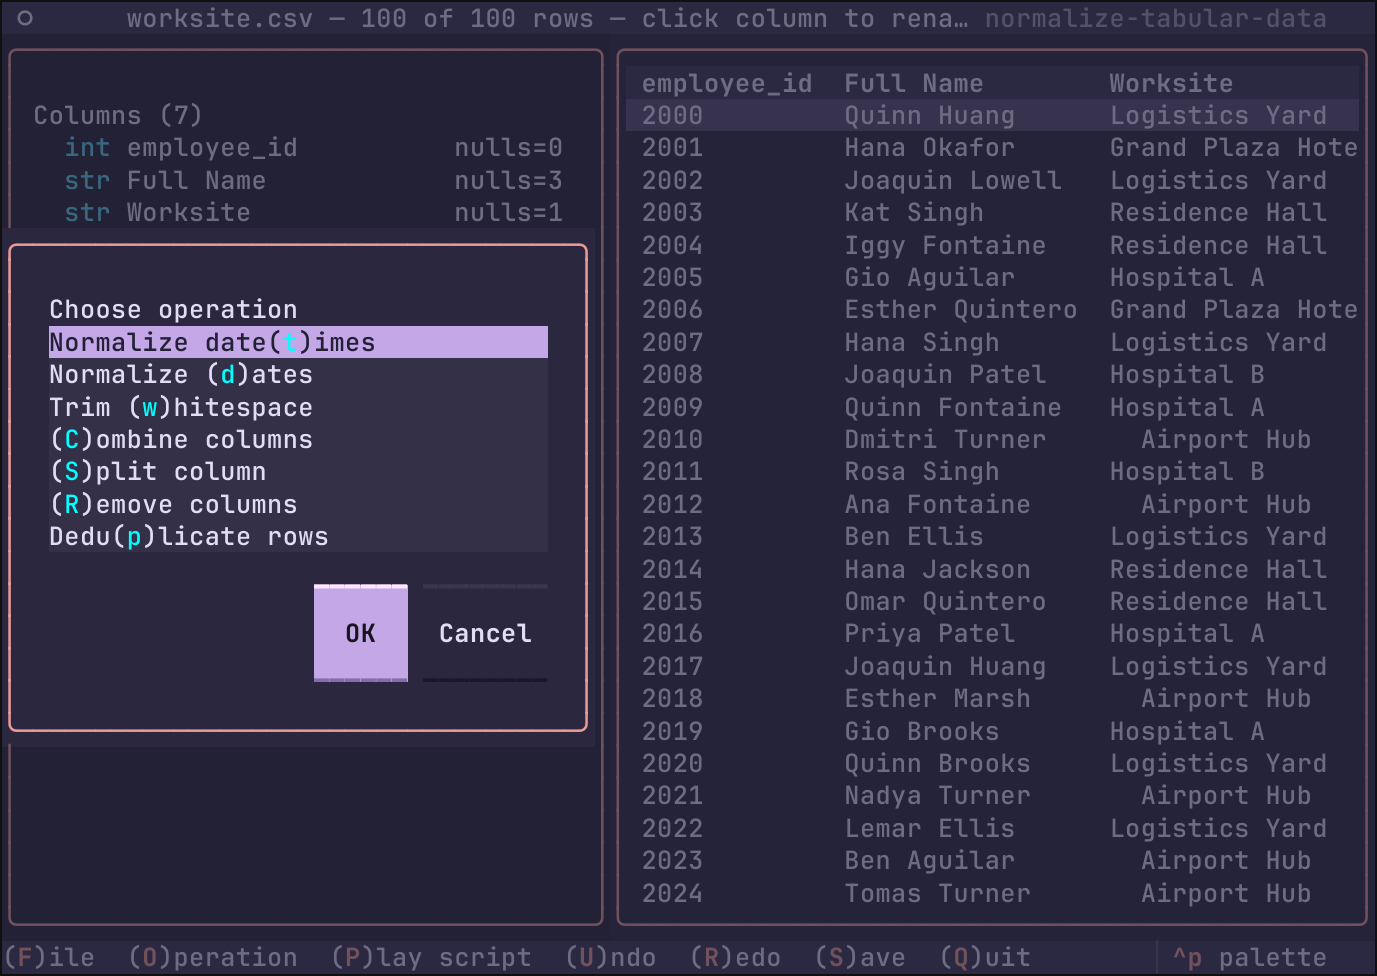
Load a file, see a preview, build up a pipeline of normalization operations (normalize messy dates, trim whitespace, rename a column, deduplicate, combine/split columns, drop columns), then save the cleaned result.
Running
Persistent install
uv tool install normalize-tabular-data
# upgrade later with:
uv tool upgrade normalize-tabular-data
Ephemeral run (no install)
uvx fetches into a throwaway environment each time:
uvx normalize-tabular-data
# pin a specific version:
uvx normalize-tabular-data==0.1.0
Straight from a checkout
uv run normalize-tabular-data
Usage
Launch with normalize-tabular-data. Keys:
| Key | Action |
|---|---|
f |
(F)ile — open a file |
o |
(O)peration — choose an op |
p |
(P)lay script — apply .ntd |
u |
(U)ndo last applied step |
r |
(R)edo |
s |
(S)ave the data in a format |
q |
(Q)uit |
Operations
- Normalize dates — parse a messy date column of any input format into canonical UTC datetimes; unparseable values become null.
- Trim whitespace — strip edges and collapse internal whitespace runs, per selected columns.
- Rename a column — click its header in the preview and type the new name.
- Deduplicate rows — on all or selected columns, keeping first or last.
- Combine columns — concatenate two or more columns with a separator.
- Split column — break one column into
{col}_1..{col}_k; a blank delimiter splits on runs of whitespace. - Remove columns — drop selected columns entirely.
Formats
Reads: CSV, TSV, JSON lines, Parquet, Excel (.xlsx/.xls — first sheet).
Writes: CSV, TSV, JSON lines, Parquet, Excel (.xlsx).
Large files are previewed with a random sample of 250 rows; every operation still runs on the full data.
Operation scripts (.ntd)
Every open file keeps an internal log of the operations performed on it. When
saving, the dialog offers a Save sequence of operations? checkbox
(unticked by default); with it ticked, a second dialog asks where to write
the script — suggested <table>.ntd, any other extension you type is kept.
The script is plain ASCII text, one operation per line, e.g.:
# normalize-tabular-data script
# source: employees.csv
# table: /data/employees-normalized.csv
# saved: 2026-10-05T12:30:11
trim_collapse(columns=["Dept", "Name"])
date_normalize(column="Hired Date")
Playing a script back
Press p (available while a file is loaded) to pick a script file: the
dialog previews the highlighted .ntd file (syntax-highlighted, first 40
lines) before you confirm. Its operations are applied, in order, to the table you have open. If any step
cannot be performed against the currently loaded file — a column it
renames, trims or splits is missing, the operation is unknown — playing
stops with an alert naming the failing step, and every step the script had
already applied is rolled back, so the table is left exactly as it was.
Publishing
PyPI credentials live in $HOME/.pypirc (sections [pypi] and
[testpypi]); uploads go through twine, which honors that file —
uv publish does not read .pypirc, so it is not used here.
make dist       # build sdist+wheel into dist/ and run `twine check`
make testpypi   # upload to the TestPyPI sandbox (login section [testpypi])
make pypi       # upload to PyPI (login section [pypi])
twine upload    # equivalent of `make pypi`, minus a fresh build
The targets fail fast if the package metadata does not pass twine check,
and twine runs with --non-interactive so a missing or wrong
credential aborts the upload instead of prompting mid-run.
License
BSD 2-Clause. Copyright (c) 2026, Service Employees International Union (SEIU).
See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for normalize-tabular-data 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| normalize_tabular_data-0.1.1.tar.gz | 22.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| normalize_tabular_data-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 48.7 kB
Release files / normalize_tabular_data-0.1.1.tar.gz
| Download URL | normalize_tabular_data-0.1.1.tar.gz |
|---|---|
| Size | 22.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
02c0d3d0c138211f079c5fd428fb14c0e2ead06af27b783d00b7f8eaf0c7a2f2
|
|
BLAKE2b-256 checksum How to use checksums |
1478c48ce7afa02411374f6fadd488333b7560b60452bd21d22d69edd4b66b42
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.0
|
Release files / normalize_tabular_data-0.1.1-py3-none-any.whl
| Download URL | normalize_tabular_data-0.1.1-py3-none-any.whl |
|---|---|
| Size | 26.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c296c48eecbb21f9ff1838f9f1509a81e55396b9916d4ad35c0b6719ef7dae7b
|
|
BLAKE2b-256 checksum How to use checksums |
62551afc7d1be8be5c785cb730ca3dc4698445f609673dba60c596279f59aa83
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.0
|














