
notebook-to-pipeline
Your agent turns a messy Jupyter notebook into a tested, reproducible pipeline, and proves the outputs didn't change.
Try it on a real notebook
curl -LO https://raw.githubusercontent.com/Abelo9996/notebook-to-pipeline/main/examples/sklearn-feature-scaling/plot_scaling_importance.ipynb
uvx --with scikit-learn,pandas,matplotlib notebook-to-pipeline capture plot_scaling_importance.ipynb
uvx notebook-to-pipeline scaffold plot_scaling_importance.ipynb --out demo
uvx --with scikit-learn,pandas,matplotlib notebook-to-pipeline verify --pipeline demo/src/plot_scaling_importance/pipeline.py:run --reference plot_scaling_importance.ipynb
That runs the notebook top to bottom in a fresh kernel, writes a first-draft package from it and
proves the draft reproduces all 26 variables and all 3 figures (Verdict: EQUIVALENT (all 29 compared outputs match)). It took 27 s with an empty uv cache on an Apple M4 MacBook.
The draft is a project of its own with an equivalence test, a Makefile and a GitHub Actions
workflow. cd demo && uv run pytest -q installs its pinned packages and runs the same comparison
(1 passed). Nothing else goes into the project: the test runs this tool through uv, pinned to
the version that wrote it.
On your own notebook, from a project whose .venv has the notebook's packages and ipykernel:
uvx notebook-to-pipeline analyze analysis.ipynb      # hidden-state problems, proposed modules
uvx notebook-to-pipeline capture analysis.ipynb      # fresh-kernel run, saves the reference
uvx notebook-to-pipeline verify --pipeline src/analysis/pipeline.py:run --reference analysis.ipynb
verify compares every output: exact for integers, strings and hashes, with a tolerance for floats,
column by column for DataFrames, fitted models by their learned attributes, and matplotlib figures
pixel by pixel. Every command ends with what to do next. The short command is nb2p.
Use it with your agent
uvx notebook-to-pipeline setup --yes
Restart Claude Code (or Codex, or Cursor), open the folder with your notebook and ask:
Can you turn snowiest_month.ipynb into a proper Python pipeline (a small package with a test) and prove the outputs didn't change? Keep it small.
From a real headless Claude Code session on the pandas-cookbook notebook in
examples/, with only this tool's MCP server (a local build of 0.1.1) and skill loaded. The agent called
analyze_notebook, capture_reference, wrote src/snowiest_month/pipeline.py, called
verify_pipeline and write_report, and finished with:
I turned the notebook into a small package with tests, and the outputs didn't change. The verification tool says equivalent: all 11 compared outputs match. That's 6 variables (dataframes and series), each identical byte for byte, and 5 figures, each identical pixel for pixel.
Things to know about the original notebook: It runs cleanly from top to bottom, but its saved outputs don't all come from such a run. Cells were run out of order, and 8 executions aren't visible in the file.
In an earlier session (0.1.0) on the scikit-learn notebook it kept a real bug on purpose and said so:
The notebook has a bug, and I kept it on purpose. One PCA object is shared by both
unscaled_clfandscaled_clf. [...] If you want that fix, I'll capture a new reference from the fixed notebook and report the new numbers.
A real run
The "Importance of Feature Scaling" notebook from the scikit-learn 1.9.1 example gallery, captured
with nb2p capture plot_scaling_importance.ipynb --out evidence/reference --repeat 2
(artifact list trimmed):
Python 3.12.13: ~/Downloads/notebook-to-pipeline/examples/.venv/bin/python (virtualenv found at ~/Downloads/notebook-to-pipeline/examples/.venv)
Top-to-bottom run: OK, 7/7 code cells in 36.439 s
Captured 26 artifacts:
  X                            dataframe  a676a863527a
  y                            series     55c53e167556
  ...
  y_proba                      ndarray    260abb10bbbb
  y_proba_scaled               ndarray    71b105b5e066
[warning] shared_object: After the run, `pca`, `unscaled_clf[0]`, `scaled_clf[1]` are one and the same sklearn.decomposition._pca.PCA object. Fitting or changing it through one name changed it for all of them.
[info] identical_artifacts: `pca`, `scaled_pca` have identical content after the run. If the notebook treats them as different results, check for shared objects or a step that was meant to differ.
Determinism check (2 runs): every artifact reproduced
Figures recorded: 3 (rendered as PNG for comparison): 1 (KNN without scaling; KNN with scaling), 2 (Weights of the first principal component), 3 (Unscaled training dataset after PCA; Standardized training dataset after PCA)
Printed output: 10 non-empty lines recorded
Reference: evidence/reference
The notebook builds its "unscaled" and "standardized" pipelines around the same PCA object, so
fitting the second one refits the PCA inside the first. A hand-written pipeline that keeps this
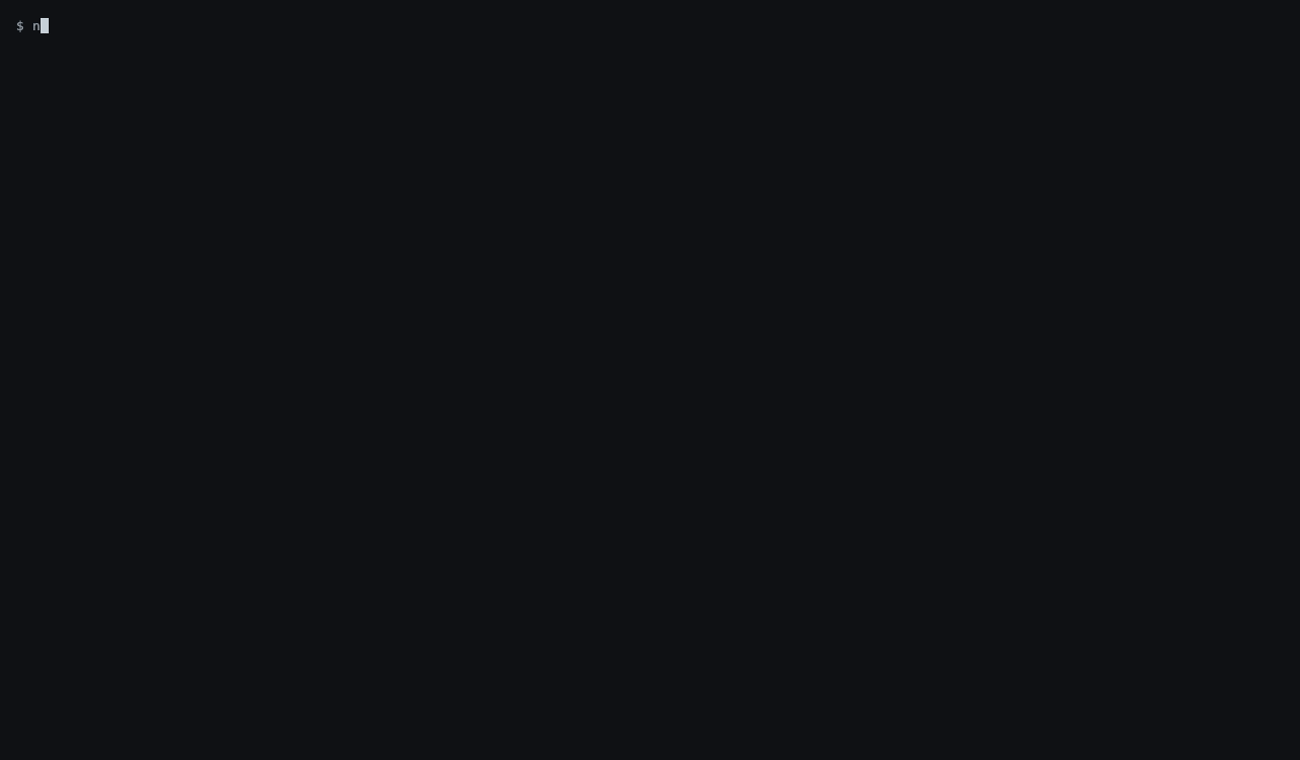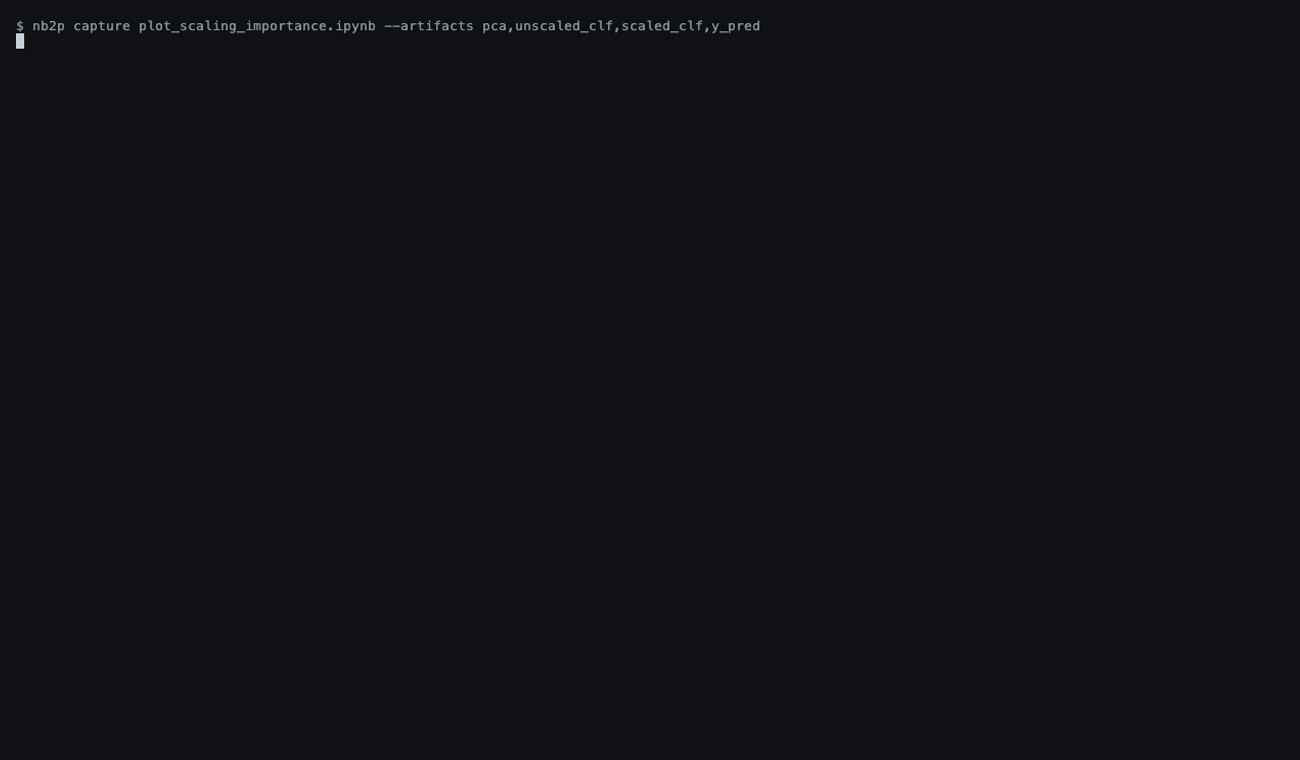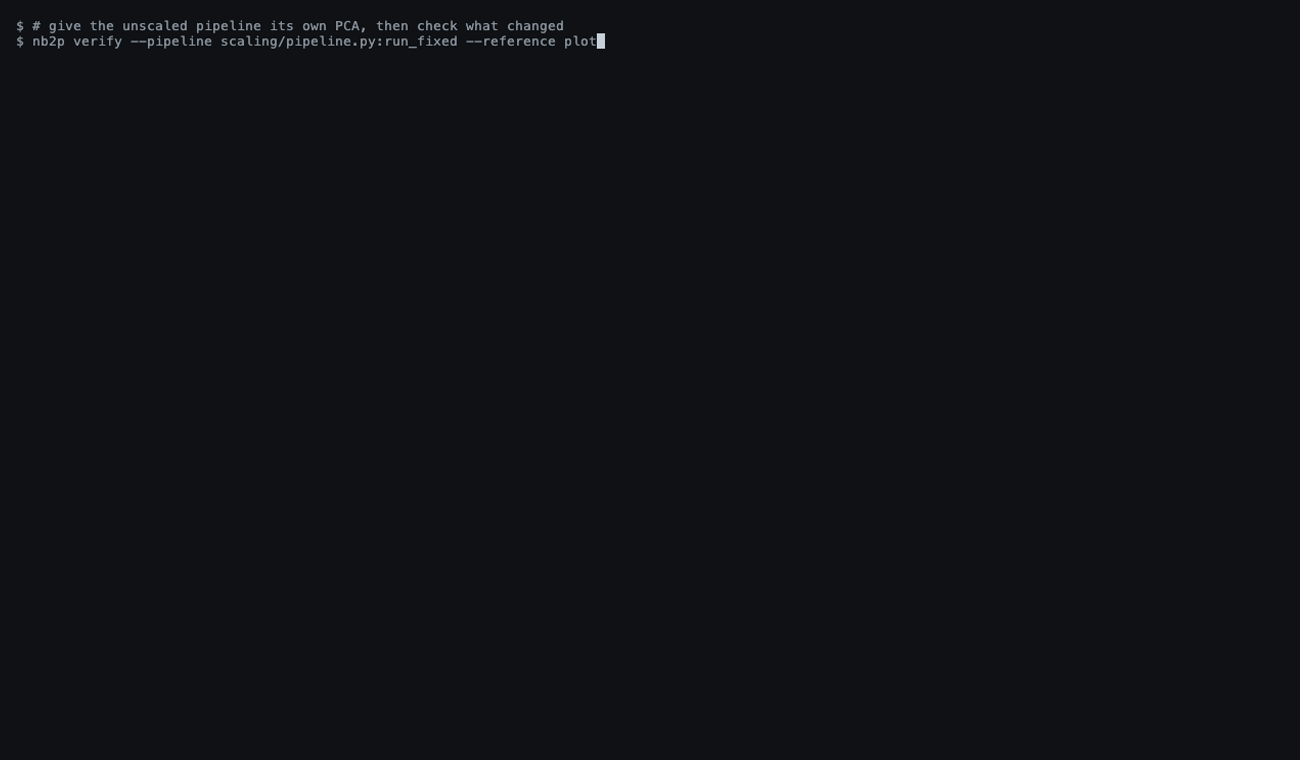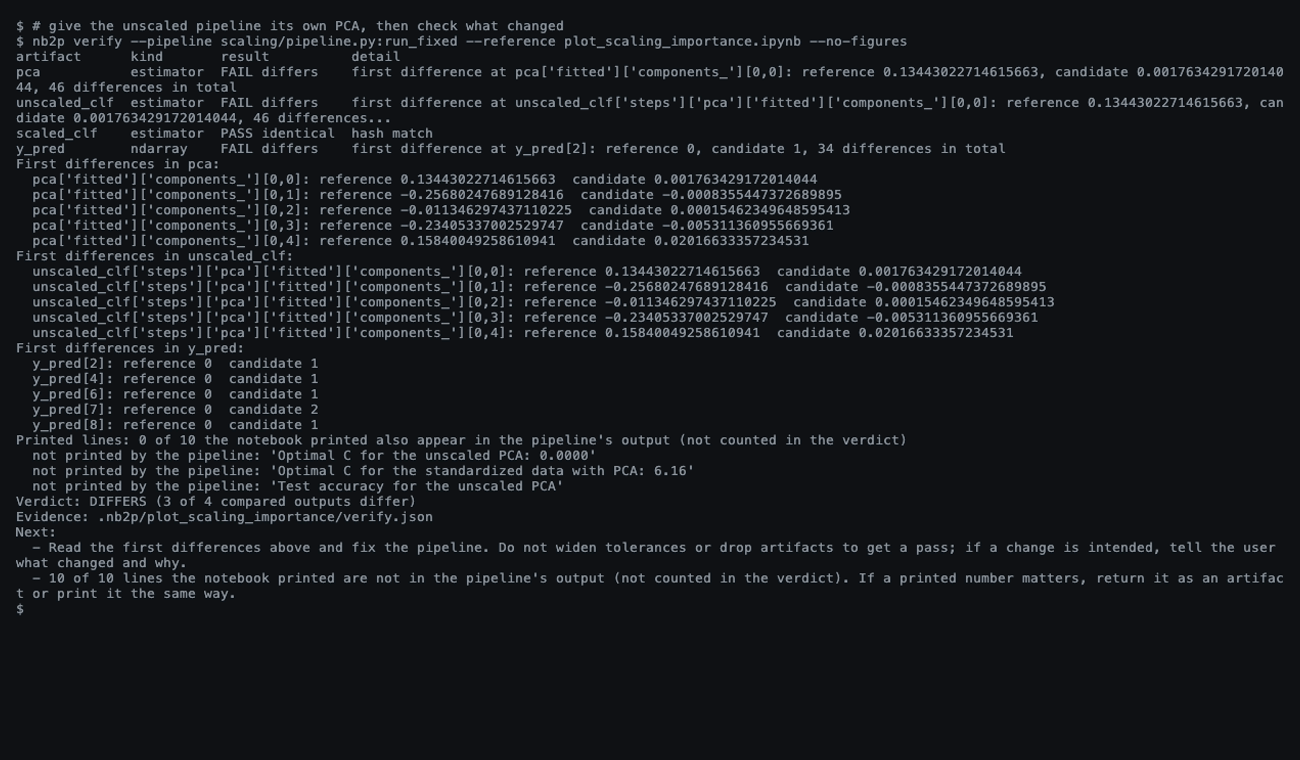
behavior verifies as EQUIVALENT on all 26 artifacts. Giving the unscaled pipeline its own PCA is a
deliberate change, and verify shows exactly what it touches (3 of the 26 rows shown):
pca                      estimator  FAIL differs    first difference at pca['fitted']['components_'][0,0]: reference 0.13443022714615663, candidate 0.001763429172014044, 46 differences in total
y_pred                   ndarray    FAIL differs    first difference at y_pred[2]: reference 0, candidate 1, 34 differences in total
y_pred_scaled            ndarray    PASS identical  hash match
Verdict: DIFFERS (4 of 26 compared outputs differ; not counted: 3 not compared)
The unscaled test accuracy the example prints, 35.19%, becomes 74.07% with its own PCA; the
standardized pipeline stays at 96.30%. (The 3 uncounted rows are the figures: that hand-written
pipeline does not plot.) The mechanical draft from nb2p scaffold verifies as EQUIVALENT on this
notebook (26 variables and 3 figures) and on the pandas-cookbook one (6 variables and 5 figures; since
0.1.2 also 4 values the notebook only displayed, 15 outputs in all, see
the end-to-end run).
All of this, plus a notebook broken by hidden state, is in examples/ with the
full reports.
How it works
- analyze parses each cell with Python's
astafter IPython's own input transformer (so%magicsand!shelllines are understood), and builds a def/use graph across cells, including in-place mutation (df.dropna(inplace=True),model.fit(...),x.append(...), item and attribute assignment) and mutation through functions defined in the notebook. Findings: use before definition, names that only a deleted cell defined, out-of-order and hidden executions from the saved execution counts, saved outputs computed from a different definition than a clean run would use, cross-cell mutation, estimators shared between scikit-learn pipelines, unseeded randomness, network and shell access. It proposes a split into load, clean, features, train, evaluate and report, and says which calls put each cell there. - capture starts a new Jupyter kernel (
nbclient+ipykernel, over a Unix socket on macOS and Linux) on your project's interpreter, runs every cell in order and stops at the first error. It saves the chosen variables with a content hash and a summary (shape, dtypes, column stats, fitted attributes), records files the notebook wrote, re-renders every matplotlib figure as a PNG at 72 dpi when Jupyter closes it, records what the notebook printed, compares the saved text outputs with the fresh run, reports objects reachable under several names, and with--repeat Nreruns to find outputs that change between runs. A value a cell displays as its last expression (df.describe(), a score) is saved too, asdisplayed_cell_<n>, when it is data. - verify runs the pipeline in the same interpreter (
file.py:funcormodule:funcreturning a dict, or a script whose globals hold the results), saves the same artifacts and compares them in that interpreter, so pandas, numpy and scikit-learn objects load with the versions that made them. Fitted estimators are compared by parameters and fitted attributes. Figures the pipeline draws are rendered the same way and matched to the notebook's by pixels, then in order. Every failure shows the first differences with their path, for exampletemperature.index[0]orpca['fitted']['components_'][0,0]. - scaffold writes
src/<package>/with one module per proposed stage (the notebook code pasted into functions as a first draft, displayed values kept asdisplayed_cell_<n>),pipeline.py:run(),tests/test_equivalence.py, a Makefile, apyproject.tomlpinned to the captured versions and a GitHub Actions workflow. The test callsuv tool run --from notebook-to-pipeline==<that version> nb2p verifywith the project's interpreter, so the project needs only pytest. For a uv project (uv.lock, a uv-made.venv, or a new folder when uv is installed) pytest goes in a dev dependency group and CI usesastral-sh/setup-uv; for a pip project it writesrequirements.txtandrequirements-dev.txt(pytest and uv) and CI usesactions/setup-python, both with the Python version of the reference run.examples/scaffold_e2e.shchecks both kinds end to end. - report writes
report.mdandreport.json: notebook hash, interpreter and package versions, the top-to-bottom result, hidden-state findings, the per-artifact and per-figure tables, the verdict and the limits.
The interpreter is chosen in this order: --python, $NB2P_PYTHON, a .venv next to the
notebook or in a parent directory, then the one running nb2p. If the notebook needs a package that
interpreter lacks, capture says so and how to fix it.
Exit codes: capture 0 when the notebook runs, 3 when it fails. verify 0 equivalent, 1 differs,
3 pipeline failed, 4 reference invalid.
Setup for agents
uvx notebook-to-pipeline setup          # shows what it would change
uvx notebook-to-pipeline setup --yes    # applies it
It detects Claude Code, Codex and Cursor and registers the MCP server (uvx notebook-to-pipeline mcp)
with each: claude mcp add --scope user, a [mcp_servers.notebook-to-pipeline] table in
~/.codex/config.toml, an entry in ~/.cursor/mcp.json. It copies the agent skill to
~/.claude/skills/ and ~/.codex/skills/. Files are backed up before they are edited and a second
run changes nothing. --project DIR writes a project .mcp.json instead.
MCP tools: analyze_notebook, capture_reference, verify_pipeline, scaffold_pipeline,
write_report. Each result carries next_steps. The skill (skills/notebook-to-pipeline/SKILL.md)
tells the agent to capture before changing anything, verify after every step, and never change
logic to make outputs match without saying so.
What it can't do
- Figures are compared only for matplotlib (pandas and seaborn plots included), and only when the pipeline draws figures too; otherwise they are listed as not compared. They are compared pixel by pixel, so a different matplotlib or font version will show up as a difference. Plotly, Bokeh and Altair charts are not compared.
- A value that was only printed is checked line by line against the pipeline's output, but that
check is not counted in the verdict. A value a cell displayed as its last expression is compared
when it is data and the pipeline returns it as
displayed_cell_<n>(the scaffold draft does); otherwise it is listed as not returned. Values shown withdisplay(), rich-only output such asdf.style, and plot handles are not compared. - The generated equivalence test needs uv (installed, or
pip install uv) and, the first time, network access to fetch the pinned notebook-to-pipeline. Without uv it skips with a message, and underCIit fails instead. scaffoldpins only the packages the notebook imports, to the versions of the reference run. Their own dependencies (scipy under scikit-learn, for example) are not pinned.- Static analysis does not follow
exec,eval,%run, imports of local modules or aliases (b = a; b.append(1)). Shared objects of that kind are caught at runtime only if both names are captured. - Equivalence is shown for this data in this environment. A different input file or library version can still change results.
- Outputs that change from run to run (unseeded randomness, timings) cannot be verified.
--repeatfinds them; it does not fix them. - The stage proposal is a heuristic starting point and
scaffoldproduces a mechanical draft. The refactor itself is the agent's job. - Plain Python kernels only. No R or Julia notebooks, no Spark or remote kernels.
Privacy and safety
Everything runs on your machine. The tool makes no network calls and calls no LLM; the agent you
already use does the refactoring. The equivalence test that scaffold writes asks uv for the pinned
notebook-to-pipeline from PyPI the first time it runs. capture and verify execute the notebook and the pipeline with
your user's permissions, exactly as running them yourself would. References are stored as pickles,
so only verify against capture directories you created (see SECURITY.md). Evidence files replace
your home directory with ~.
License
MIT. The example notebooks keep their own licenses (CC BY-SA 4.0 and BSD 3-Clause), noted in each
example's NOTICE.txt.
1 maintainer

Metadata
1 maintainer
Release files for notebook-to-pipeline 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| notebook_to_pipeline-0.1.2.tar.gz | 95.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| notebook_to_pipeline-0.1.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 186.9 kB
Release files / notebook_to_pipeline-0.1.2.tar.gz
| Download URL | notebook_to_pipeline-0.1.2.tar.gz |
|---|---|
| Size | 95.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5958cbf7d00a0eac4f4b005ce666fa6dcb56ed4d4d989b2db7f704e88becd0c0
|
|
BLAKE2b-256 checksum How to use checksums |
d94142e9b9030d011d4bc6ae12dc1c5ea2ccbf5d6cfe51c83fac9d83c2a4d5a3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / notebook_to_pipeline-0.1.2-py3-none-any.whl
| Download URL | notebook_to_pipeline-0.1.2-py3-none-any.whl |
|---|---|
| Size | 91.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b4e27eeac0b5097b64c3558ea13ab8d5e79e8f5c1c50ca48ce0e4c91441bd95a
|
|
BLAKE2b-256 checksum How to use checksums |
078098d1d379a8a3edbe13c7b9a0af21bef8438c83ac0a011fd05e4bef500262
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency log













