
numpy-groupies



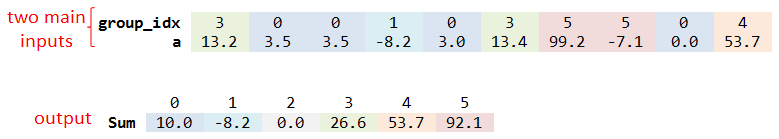
Fast group-by aggregation on plain NumPy arrays. Give it values and a group label for each value, get back one result per group — sum, mean, std, median, min/max, argmax, cumulative sums, custom functions and more. No DataFrame required, with an optional Numba backend for speed.
import numpy as np
import numpy_groupies as npg

group_idx = np.array([3, 0, 0, 1, 0, 3, 5, 5, 0, 4])
a = np.array([13.2, 3.5, 3.5, -8.2, 3.0, 13.4, 99.2, -7.1, 0.0, 53.7])

npg.aggregate(group_idx, a, func="sum", fill_value=0)
# array([10. , -8.2,  0. , 26.6, 53.7, 92.1])
#  group:  0     1    2     3     4     5
Group 2 never occurs in group_idx, so its slot is filled with fill_value.
Contents: Why numpy-groupies? · Installation · Quickstart · Input forms · Functions · Helper tools · Implementations · Performance · Development
Why numpy-groupies?
- Fast. With Numba installed,
aggregateis the fastest group-by aggregation for plain NumPy arrays. See Performance. - One call, many functions. The usual reductions plus
median,sort(ascending or descending),trapezoid, the cumulativecumsum/cumprod/cummin/cummax,argmin/argmax,array(collect the members of each group) and any custom callable. Every reduction has anan…variant. - Array in, array out. Plain NumPy arrays, no DataFrame and no index. The result is an array indexed by group label, with empty groups filled with the value you choose. Multi-dimensional output (N-D binning) and aggregation along an
axisare built in. - Usable inside your own jitted code. Every Numba kernel is
@njit-callable, so group statistics can sit inside your own compiled loops. - Numerically careful. Integer sums, means and variances accumulate in a dtype wide enough not to wrap around, NaN handling follows NumPy, and complex and
float16input are supported. - Light on dependencies. NumPy is the only requirement; Numba is optional and only makes things faster. A pure-Python implementation is included as a fallback.
Installation
pip install numpy_groupies            # NumPy implementation
pip install "numpy_groupies[fast]"    # + Numba for the fastest implementation
conda install -c conda-forge numpy_groupies
NumPy is the only declared dependency. Numba is optional and only the fastest implementation needs it; the pure-Python implementation runs without Numba but still imports NumPy (see Implementations).
If you only want one implementation, you can copy a single file (e.g. aggregate_numpy.py) into your project: paste the contents of utils.py at its top, replacing the from .utils import (...) line.
Quickstart
Counting, and other reductions. The default function is sum; pass a scalar to count items per group (this is what np.bincount does under the hood in the NumPy implementation). Labels must be non-negative integers. For strings or other objects, map them first with np.unique(labels, return_inverse=True) and pass the inverse as group_idx. a are the values that you want to run your reductions on.
npg.aggregate(group_idx, 1)  # items per group
npg.aggregate(group_idx, a, func="mean")  # nan for the empty group 2
npg.aggregate(group_idx, a, func="mean", fill_value=-1)
Ignoring NaNs. Every common reduction has a nan… variant, as in NumPy.
group_idx = np.array([0, 0, 0, 1, 1, 2])
a = np.array([1.0, 2.0, np.nan, 4.0, np.nan, np.nan])

npg.aggregate(group_idx, a, func="nanmean")  # array([1.5, 4. , nan])
npg.aggregate(group_idx, a, func="nanvar")  # array([0.25, 0.  , nan])
npg.aggregate(group_idx, a, func="var")  # array([nan, nan, nan])  (plain var propagates NaN)
Cumulative functions don't reduce; the output has the same length as the input.
npg.aggregate(np.array([0, 1, 0, 1, 0]), np.array([1, 2, 3, 4, 5]), func="cumsum")
# array([1, 2, 4, 6, 9])
Custom functions. Any callable works. Non-numeric output needs dtype=object, and since the default fill value of a custom function cannot be guessed, give one explicitly. Use the NumPy implementation for this: Numba can only compile numeric functions, so with Numba installed the plain aggregate fails on the string example below — and it compiles functions, so a callable object (a functools.partial, a dataclass with __call__) is for the NumPy implementation as well.
group_idx = np.array([1, 0, 1, 4, 1])
a = np.array([12.0, 3.2, -15, 88, 12.9])
npg.aggregate_np(group_idx, a, func=lambda x: " or ".join(map(str, x)), fill_value="", dtype=object)
# array(['3.2', '12.0 or -15.0 or 12.9', '', '', '88.0'], dtype=object)
Integration into own jitted functions. Every kernel is @njit-callable, so group statistics can sit inside a compiled loop of your own:
import numba as nb
import numpy as np
from numpy_groupies.aggregate_numba import kernels

@nb.njit
def zscore(group_idx, a):
    mean = kernels.aggregate_mean(group_idx, a)
    std = kernels.aggregate_std(group_idx, a)
    scale = np.where(std > 0, std, 1.0)
    return (a - mean[group_idx]) / scale[group_idx]
Multi-dimensional output. Give group_idx one row per output dimension — here, 1000 values binned into a 15×15×15 cube:
group_idx = np.random.randint(0, 15, size=(3, 1000))
a = np.random.random(1000)
cube = npg.aggregate(group_idx, a, func="sum", size=(15, 15, 15), order="F")
cube.shape  # (15, 15, 15)
np.isfortran(cube)  # True
Aggregating along an axis of an N-D array: the groups run along axis, everything else is carried along.
a = np.array([[99, 2, 11, 14, 20], [33, 76, 12, 100, 71], [67, 10, -8, 1, 9]])
group_idx = np.array([3, 3, 7, 0, 0])  # one label per column

npg.aggregate(group_idx, a, axis=1)
# array([[ 34,   0,   0, 101,   0,   0,   0,  11],
#        [171,   0,   0, 109,   0,   0,   0,  12],
#        [ 10,   0,   0,  77,   0,   0,   0,  -8]])
Coming from pandas? These are equivalent:
import pandas as pd

group_idx = np.array([3, 0, 0, 1, 0, 3, 5, 5, 0, 4])
a = np.array([13.2, 3.5, 3.5, -8.2, 3.0, 13.4, 99.2, -7.1, 0.0, 53.7])

npg.aggregate(group_idx, a, func="sum", fill_value=0)
# array([ 10. ,  -8.2,   0. ,  26.6,  53.7,  92.1])
pd.Series(a).groupby(group_idx).sum().reindex(range(group_idx.max() + 1), fill_value=0).to_numpy()
# array([ 10. ,  -8.2,   0. ,  26.6,  53.7,  92.1])
Input forms
aggregate(group_idx, a, func="sum", size=None, fill_value=DEFAULT, order="C", dtype=None, axis=None, ddof=0, ...) accepts five combinations of input shapes:
| Form | group_idx |
a |
axis |
Output |
|---|---|---|---|---|
| 1 | 1-D, length n | 1-D, len n | — | 1-D, one value per group |
| 2 | 1-D | scalar | — | like form 1, scalar broadcast (e.g. counting) |
| 3 | 1-D, length a.shape[axis] (or broadcastable to a.shape) |
N-D | required | a's shape with axis replaced by the groups |
| 4 | 2-D, shape (d, n) | 1-D, len n | — | d-dimensional; group_idx[:, i] is the position of a[i] |
| 5 | 2-D | scalar | — | like form 4, scalar broadcast |
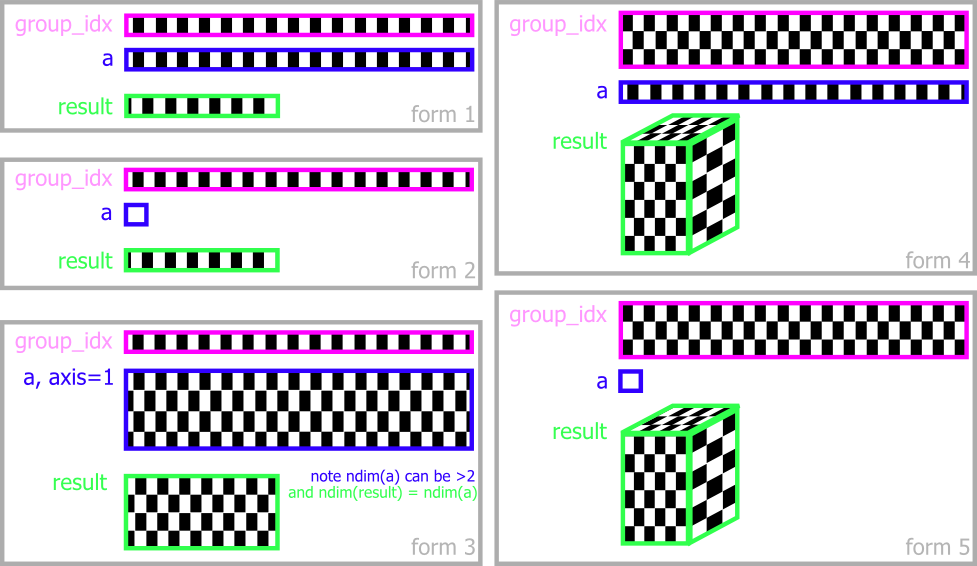
Output size defaults to max(group_idx) + 1 per dimension; pass size= to fix it. Full parameter descriptions, plus notes on memory layout and performance, are in the reference.
Functions
func can be a name, a NumPy function or builtin (np.max, max, len, …), or any callable. Optimised built-ins:
| Category | Functions |
|---|---|
| Reductions | sum prod mean median var std min max first last len sumofsquares trapezoid |
| Index of extremes | argmin argmax |
| Boolean | all any allnan anynan |
| NaN-skipping variants | nansum nanmean nanvar nanmax … — a nan prefix on every reduction above except allnan/anynan |
| Cumulative (size of input) | cumsum cumprod cummin cummax |
| Sorting (size of input) | sort (reverse=True for descending) |
| Collect group members | array |
Not every implementation supports every function — the function reference has the exact semantics, default fill values, complex-number behaviour and a function × implementation matrix.
Helper tools
uaggregate(group_idx, a, ...) takes the same arguments as aggregate but broadcasts the result back to the size of a, so every element carries the result of its own group — aggregate(...)[group_idx] in one call:
group_idx = np.array([3, 0, 0, 1, 0, 3, 5, 5, 0, 4])
a = np.array([13.2, 3.5, 3.5, -8.2, 3.0, 13.4, 99.2, -7.1, 0.0, 53.7])

npg.uaggregate(group_idx, a, func="mean")
# array([13.3 ,  2.5 ,  2.5 , -8.2 ,  2.5 , 13.3 , 46.05, 46.05,  2.5 , 53.7 ])

a - npg.uaggregate(group_idx, a, func="mean")  # demean within each group
The rest of the exports are small and situational: unpack and unpack_into (broadcast a per-group result back, optionally into a preallocated array), step_count and step_indices (runs of equal labels, Numba only), multi_arange, label_contiguous_1d, relabel_groups_unique and relabel_groups_masked (close gaps in sparse labels), and default_fill_value. All of them are described in the reference.
Implementations
from numpy_groupies import aggregate picks the best available implementation: numba if installed, otherwise numpy. To choose explicitly:
from numpy_groupies import aggregate_nb as aggregate  # numba
from numpy_groupies import aggregate_np as aggregate  # numpy
from numpy_groupies import aggregate_py as aggregate  # pure python
from numpy_groupies.aggregate_numpy import aggregate  # same, via the module
All implementations share the calling syntax and produce the same results up to floating-point error, but some support only a subset of functions and raise NotImplementedError otherwise.
| Implementation | Needs | Notes |
|---|---|---|
| numba | numpy, numba | Fastest. Default if numba is installed. |
| numpy | numpy | Based on np.bincount and indexing tricks. Default without numba. |
| pure python | numpy | Plain Python loops, no Numba. Very slow; useful as a fallback or for porting. |
| numpy ufunc | numpy | For benchmarking only: built on ufunc.at (np.add.at, …), in numpy_groupies.benchmarks. Incomplete. |
| pandas | numpy, pandas | For benchmarking only: wraps groupby (in numpy_groupies.benchmarks). Skips NaN even in the plain functions (except median, cumsum). |
| polars | numpy, polars | For benchmarking only: wraps group_by (in numpy_groupies.benchmarks). |
Gotchas: with Numba installed, custom callables must be Numba-compilable (numeric code). For the cases that are not, call the NumPy implementation:
npg.aggregate_np(group_idx, a, func=my_callable).
Performance
Best of three passes of five timed runs each, in milliseconds, for 500,000 values in 1,000 groups (lower is better):
| function | numpy | numba | numbagg | polars | pandas |
|---|---|---|---|---|---|
sum |
0.92 | 0.45 | 0.48 | 2.68 | 6.89 |
mean |
1.49 | 0.48 | 0.55 | 2.69 | 7.32 |
max |
1.64 | 0.60 | 0.86 | 2.81 | 6.61 |
std |
3.03 | 0.66 | 0.69 | 2.17 | 7.64 |
nansum |
4.05 | 0.44 | 1.75 | 5.88 | 8.25 |
median |
11.01 | 9.28 | --- | 3.72 | 15.60 |
sort |
70.29 | 25.72 | --- | --- | --- |
cumsum |
14.48 | 0.60 | --- | 7.94 | 7.23 |
array |
7.54 | 1.90 | --- | --- | --- |
| custom callable | 111.39 | 5.90 | --- | 80.97 | 96.79 |
Absolute numbers depend on your machine, so compare the columns against each other rather than reading a single one as the price of the operation.
The complete table and the benchmark setup are in docs/benchmarks.md. To run it yourself, from the repository root — --help explains which columns to ask for:
python -m numpy_groupies.benchmarks --numbagg --pandas --polars
The numpy and numba columns above are not the whole story: NumPy 1.25 brought major speed improvements to ufuncs, which narrowed the gap between the NumPy and Numba implementations considerably. The authors hope that ufunc.at or an equivalent in NumPy or SciPy will eventually become fast enough to make this package redundant.
Development
git clone https://github.com/ml31415/numpy-groupies
cd numpy-groupies
pip install -e ".[dev]"     # pytest, numba, pandas
pytest
The repository uses pre-commit (pre-commit install). Release notes are on the releases page.
Credits. Started by @ml31415, who wrote the Numba implementation; the pure-Python and NumPy implementations were written by @d1manson. Currently maintained by Deepak Cherian (@dcherian).
License
BSD 2-Clause — see LICENSE.txt.


Release files for numpy-groupies 0.14.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| numpy_groupies-0.14.2.tar.gz | 347.9 kB | Without provenance | Details for numpy_groupies-0.14.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| numpy_groupies-0.14.2-py3-none-any.whl | Python 3 | none | any | Details for numpy_groupies-0.14.2-py3-none-any.whl |
Total release size: 500.8 kB
Release files / numpy_groupies-0.14.2.tar.gz
| Download URL | numpy_groupies-0.14.2.tar.gz |
|---|---|
| Size | 347.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
63679d59550f1e2aad722e9ec69e8a1665754ff3fc30b67e0548bf39589530e0
|
|
BLAKE2b-256 checksum How to use checksums |
0f61fb6a137f24874d5da539e019668278ac5d70af38be736641367381605161
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / numpy_groupies-0.14.2-py3-none-any.whl
| Download URL | numpy_groupies-0.14.2-py3-none-any.whl |
|---|---|
| Size | 152.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f9e83fa049246fb8cc0e623f28072dd2f8d86c1d14bc7bcfd0f58bfba03d2b37
|
|
BLAKE2b-256 checksum How to use checksums |
3eefa2737974ff47ab46156c5e31d3fbb3233dc8f153ca8bd0051a0888e7029b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Security for numpy-groupies 0.14.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














