
OEV is a small (184M params) neural decision engine. Instead of generating text, it scores answer options directly. The state, the question, and every option are packed into one sequence. One forward pass returns a calibrated probability distribution.
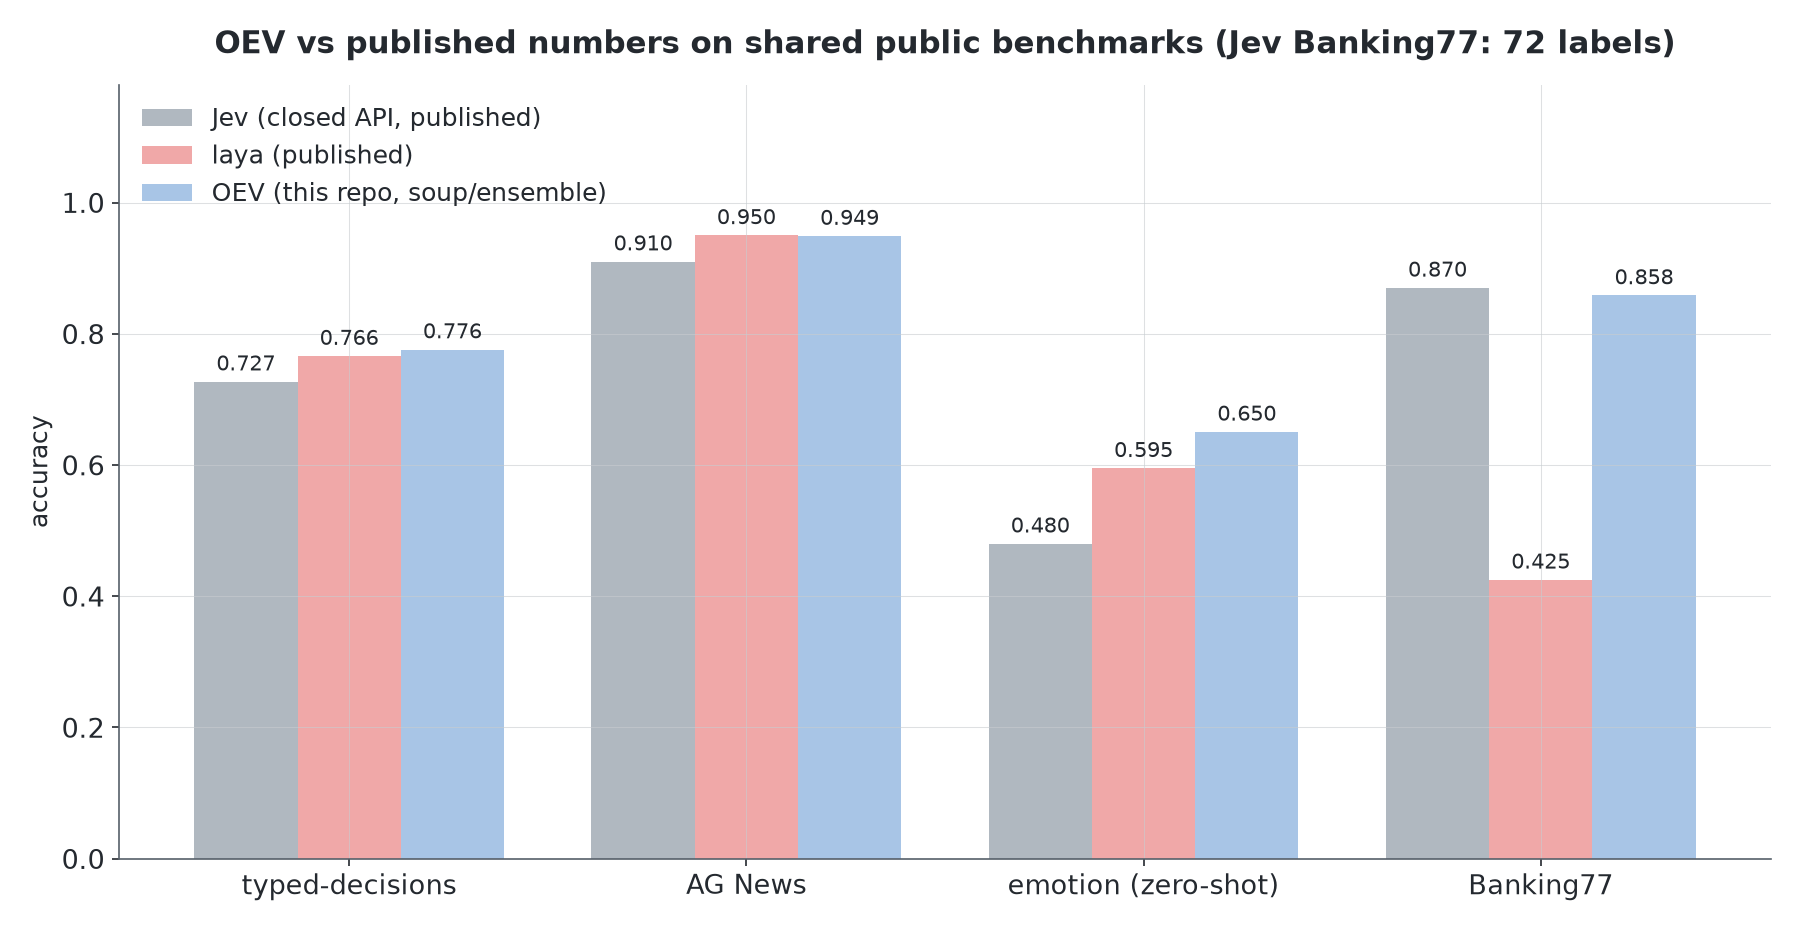
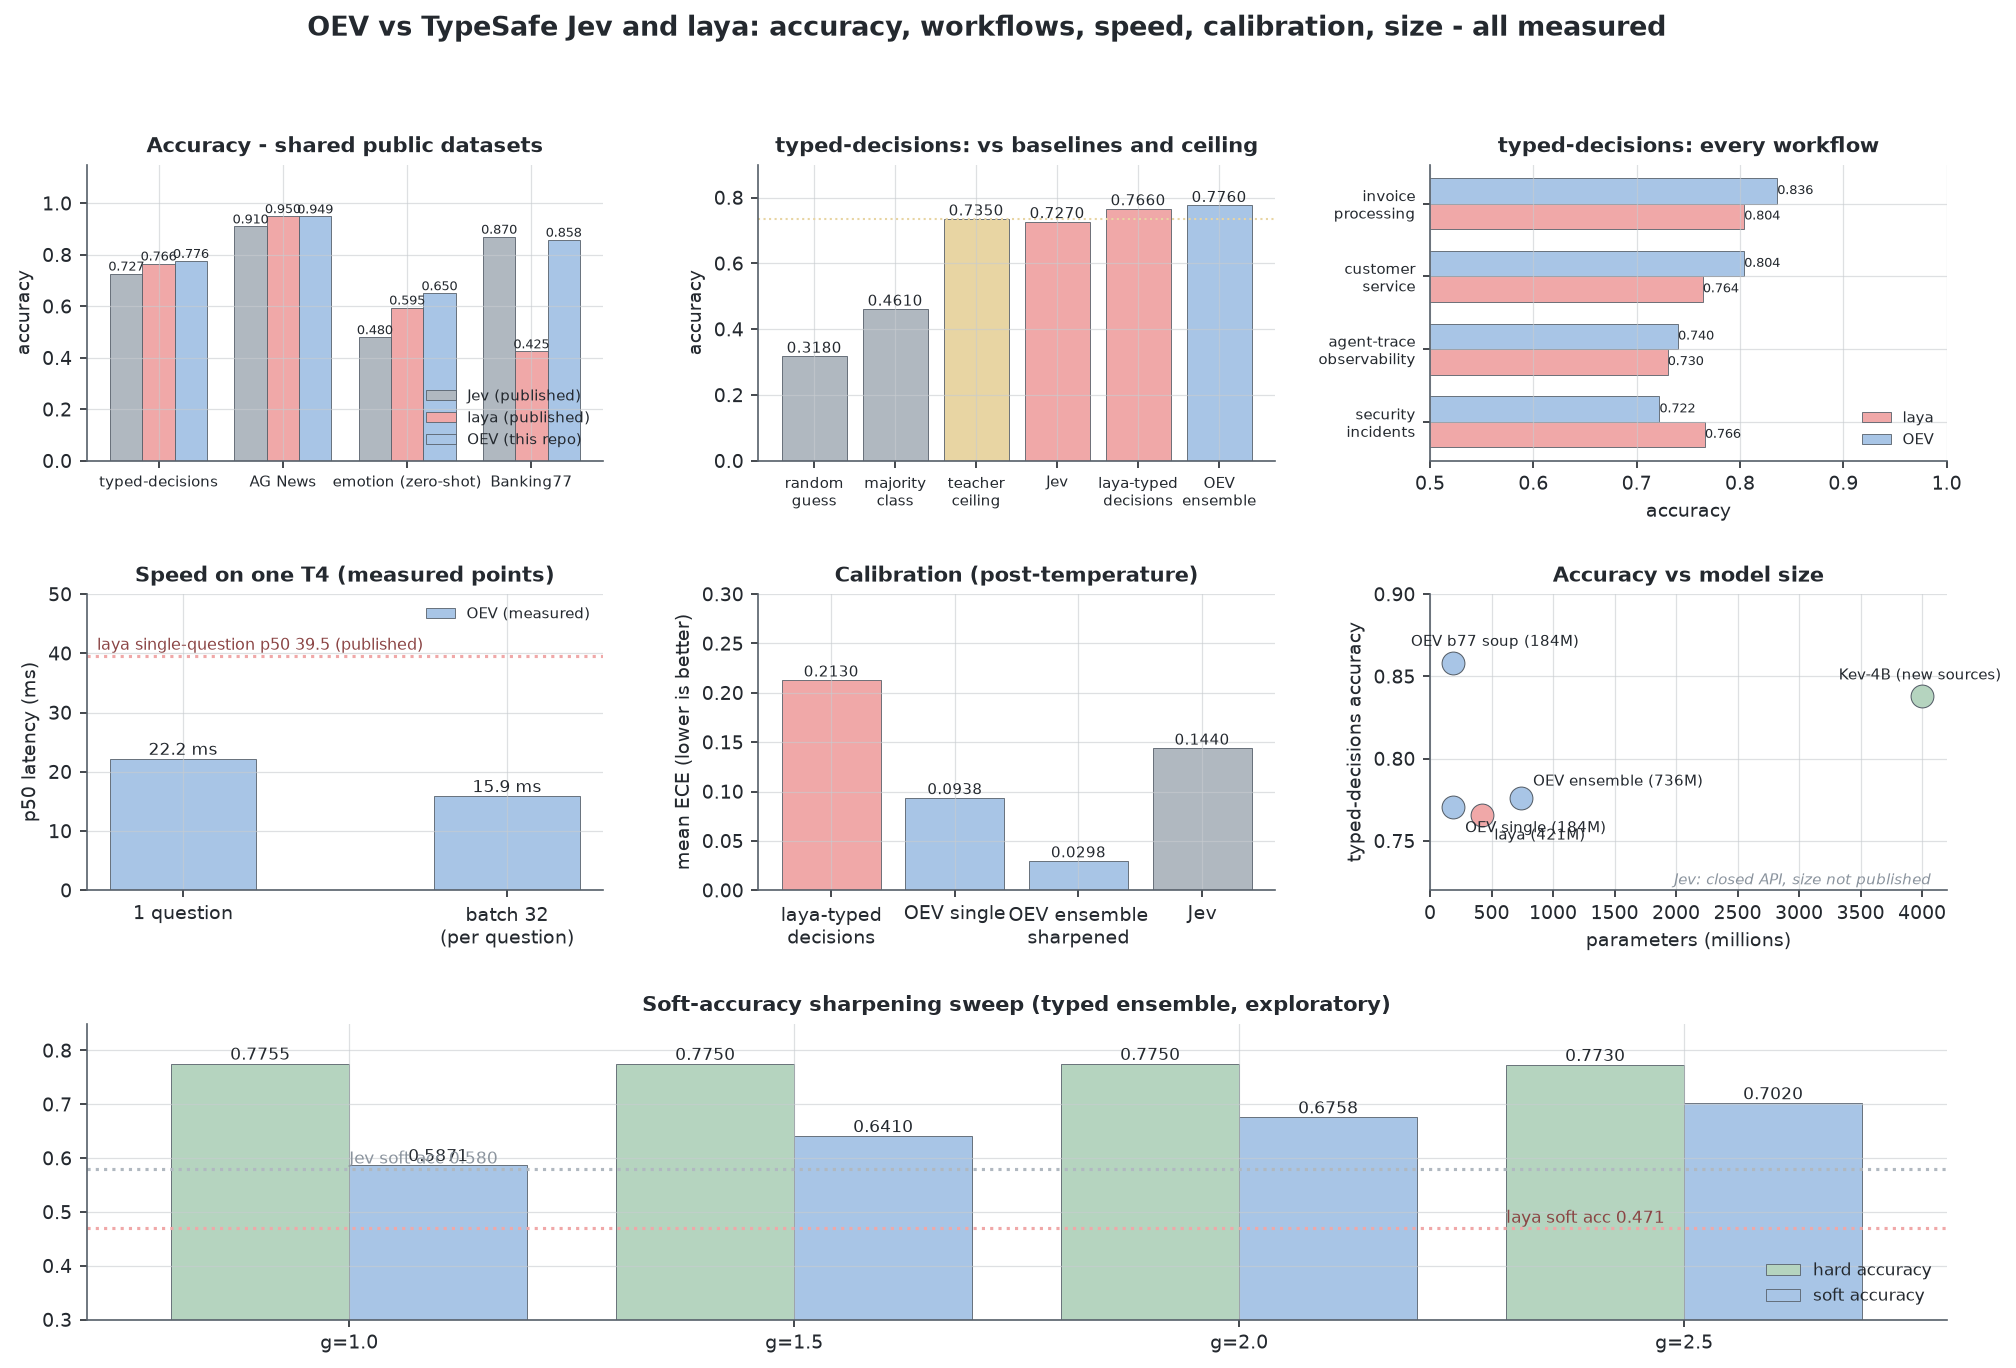
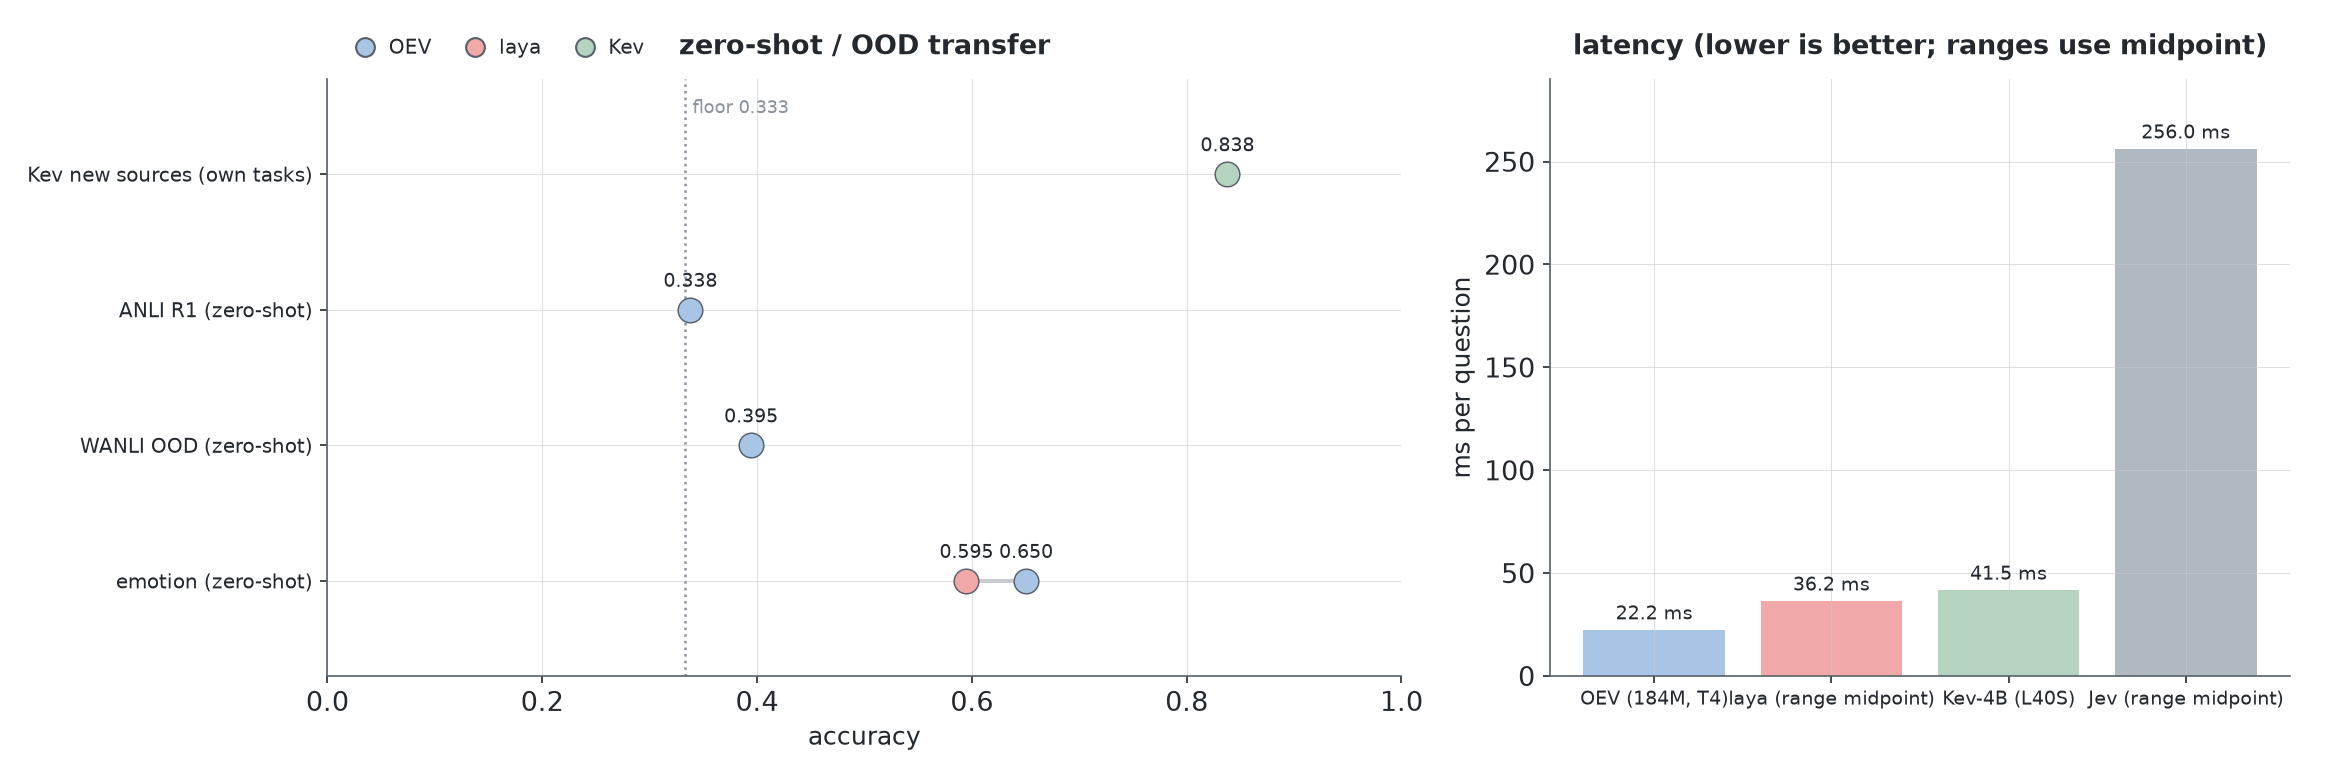
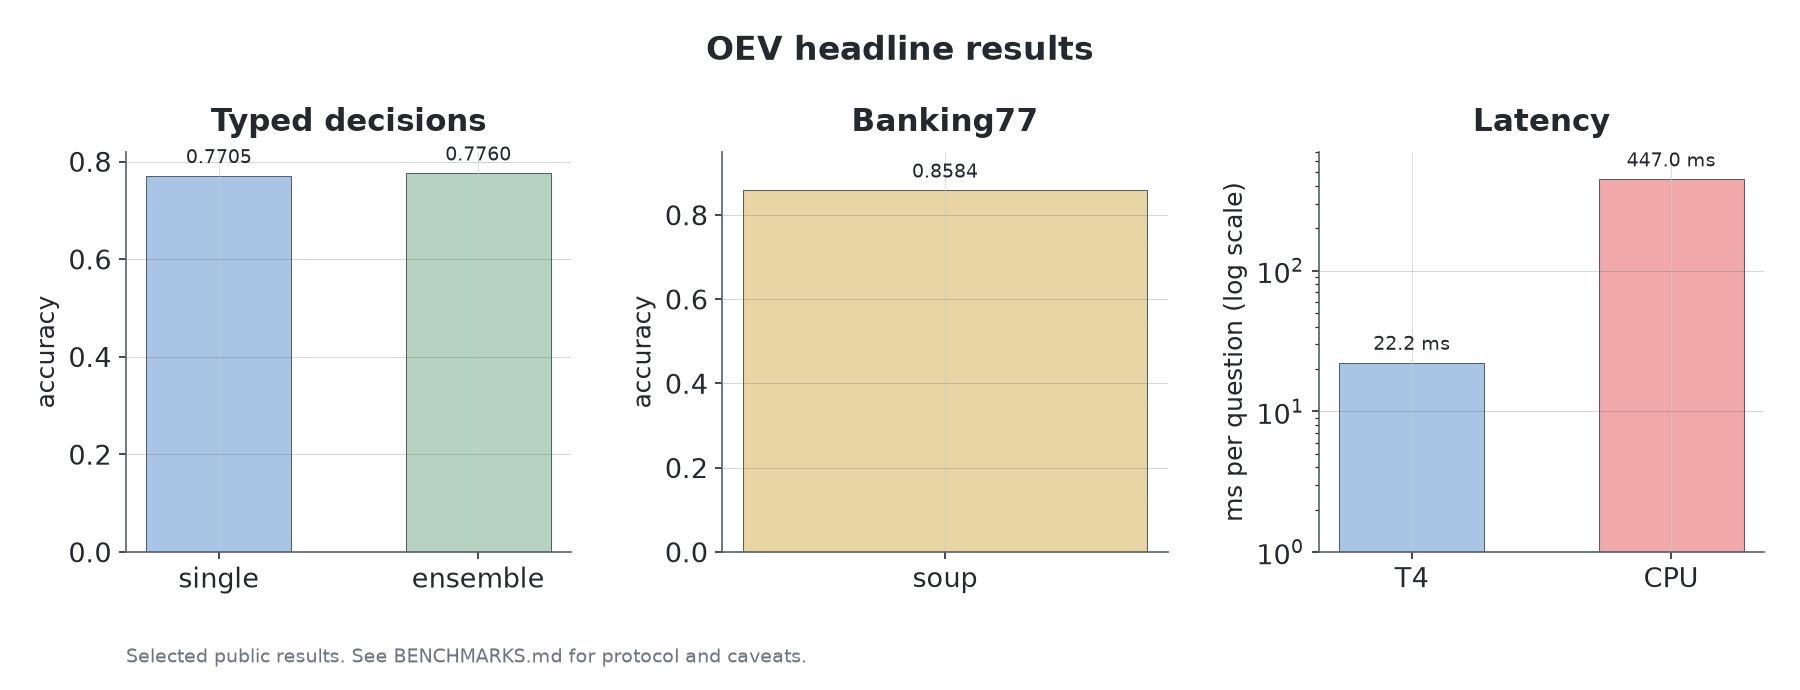
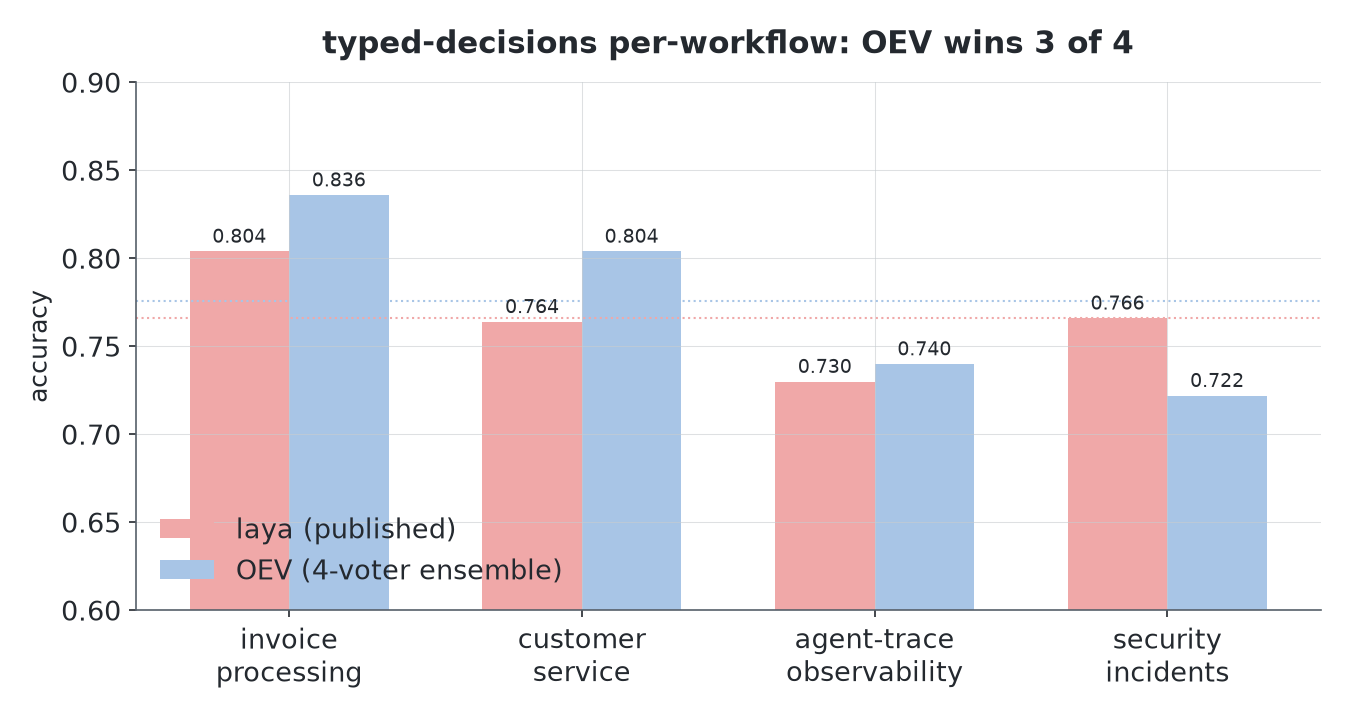
The single 184M model scores 0.7705 on typed-decisions, slightly above laya's published 0.766 from a 421M checkpoint. An ensemble of four 184M checkpoints reaches 0.7760, the highest reported result, and a single Banking77 soup checkpoint reaches 0.8584 (best ECE 0.0595 from the 3-checkpoint ensemble). Jev leads only on Banking77 (0.870).




At a glance
| claim | result |
|---|---|
| best accuracy | 0.7705 single model, 0.7760 ensemble - typed-decisions (laya 0.766 from 421M) |
| high-cardinality | 0.8584 Banking77, one soup checkpoint (ECE 0.0595 best ensemble; laya 0.425) |
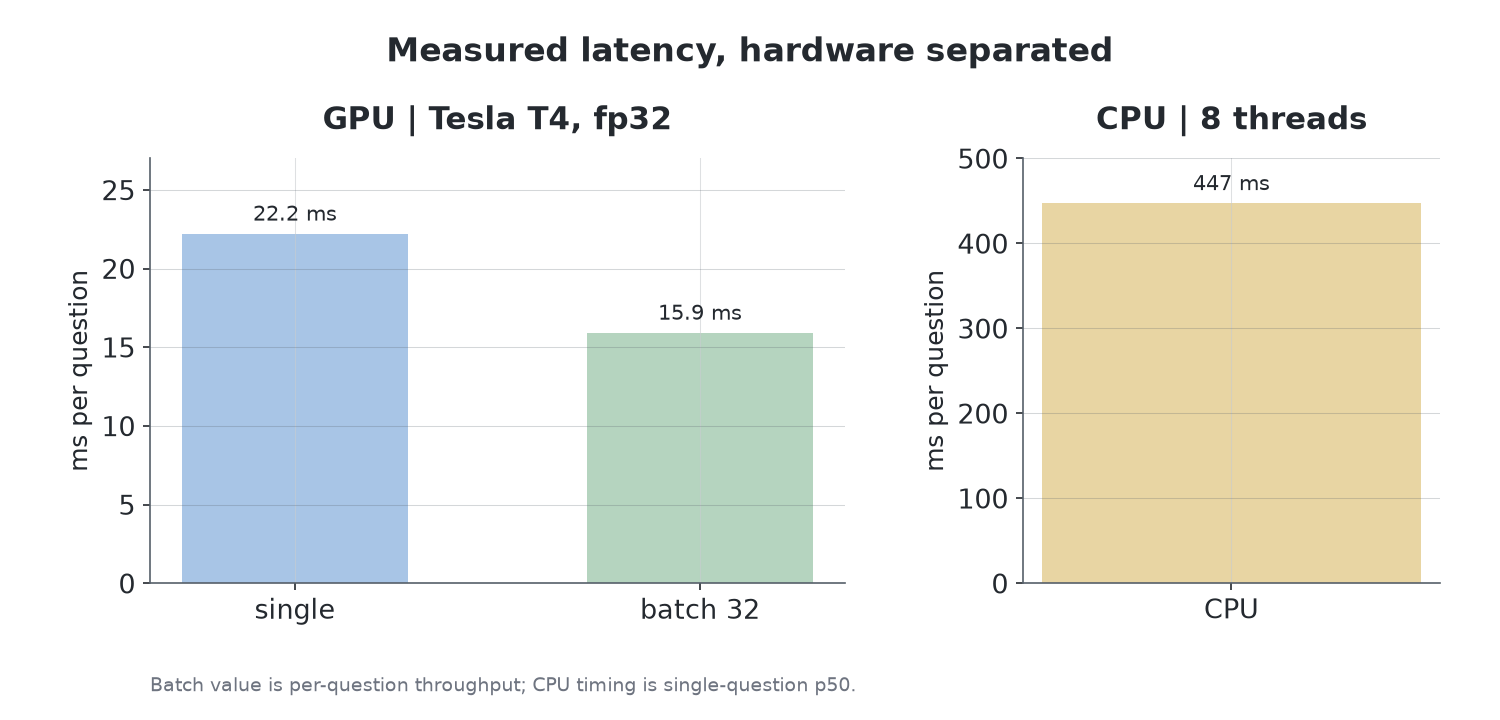
| speed | 22.2 ms single question (laya 32.8-39.5 ms published range) |
| size | 184M params, 0.44x laya |
| weights & checkpoints | Apache 2.0 - huggingface.co/divyanshudhruv/oev-typed |
22.2 msper question on aT4(GPU); on CPU the ONNX INT8 build runs at54.2 msp50 on 8 threads (228 MBartifact, 3.2x smaller)0.8584on 77-labelBanking77from a single soup checkpoint (the 3-checkpoint ensemble still holds best ECE0.0595): each option is embedded as its own anchor with full tokens, so accuracy scales with label count (gap to Jev 1.16 pts)184Mparams,Apache 2.0weights- Kev (0.8B / 4B) publishes no in-domain numbers on these datasets, so it is not in the tables; see BENCHMARKS.md for the like-for-like comparison plan
Architecture
flowchart LR
    subgraph input["Input"]
        direction TB
        S["state<br/>text or JSON"]
        Q["questions<br/>choice, noul, score"]
    end

    P["packer<br/>state + questions + anchors<br/>one packed sequence"]

    subgraph pass["One forward pass, 22 ms on T4"]
        direction TB
        E["encoder<br/>DeBERTa-v3-base, 184M<br/>or the from-scratch char model"]
        H["shared linear head<br/>scores every anchor"]
    end

    D["softmax per question<br/>calibrated distribution"]
    O["outputs<br/>choice / noul / score"]

    S --> P
    Q --> P
    P --> E
    E --> H
    H --> D
    D --> O
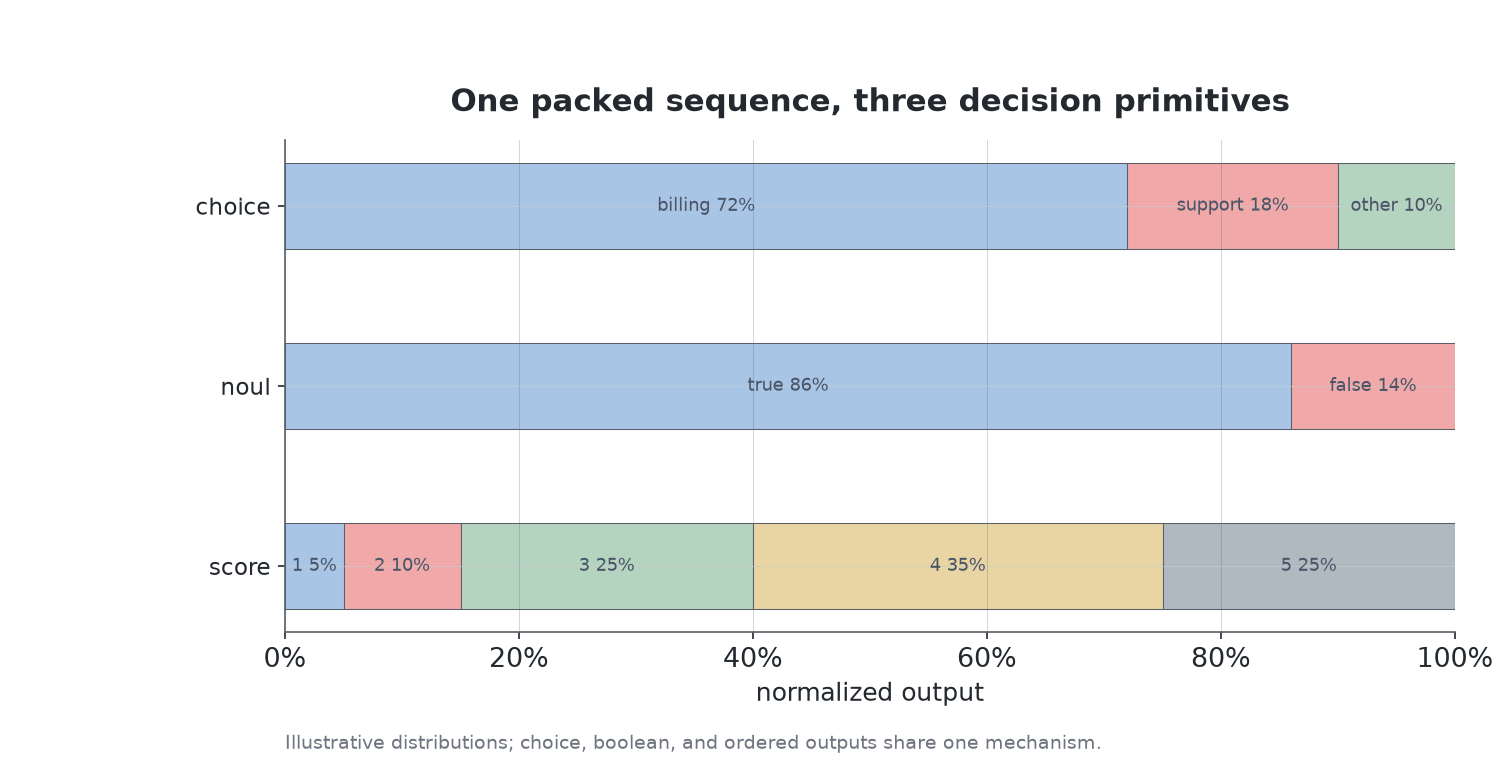
- One anchor mechanism covers all three primitives - options, yes/no pairs, and score levels are each embedded as anchors in one packed sequence
- No text generation - nothing to parse, nothing to hallucinate
- New question types need no new heads - new options are just new anchors
Benchmarks: OEV vs the published field
Fine-tuned on each benchmark's train split, following the same protocol as Laya's published runs. Selected results and evaluation notes are in BENCHMARKS.md.
| benchmark | OEV | laya | Jev | note |
|---|---|---|---|---|
| typed-decisions | 0.7760 | 0.766 | 0.727 | highest reported (ensemble); single model 0.7705 |
| Banking77 | 0.8584 | 0.425 | 0.870 | 2x laya; gap to Jev 1.16 pts |
| AG News | 0.9489 | 0.950 | 0.910 | label-noise ceiling (~0.95) |
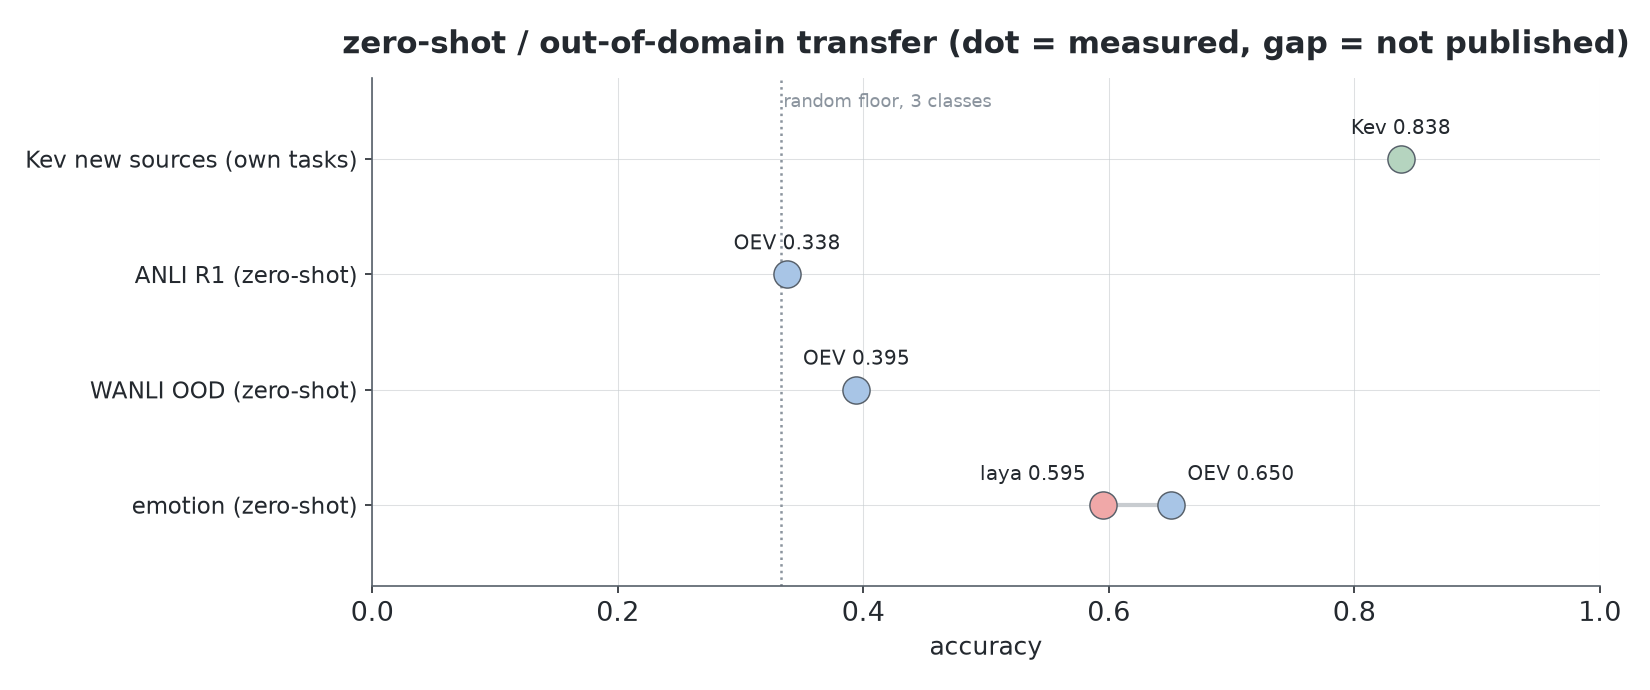
| DAIR Emotion | 0.9300 (fine-tuned) | 0.595 | 0.480 | zero-shot: OEV student 0.6505 beats laya's 0.595 head-to-head |
Quickstart
pip install oev          # from PyPI
# or from source:
pip install -e .
Optional extras:
pip install -e ".[dev]"- pytestpip install -e ".[data]"- dataset converterspip install -e ".[backbone]"- DeBERTa fine-tuningpip install -e ".[serve]"- FastAPI server (oev-serve)pip install -e ".[app]"- Gradio Space dependencies
from oev.infer import OEV

agent = OEV("checkpoints_td5/oev-tiny.pt", device="cpu")

result = agent.decide("We were charged twice for the same order.", {
    "department": {"type": "choice", "options": ["billing", "technical", "sales", "other"],
                   "instructions": "Which department should handle this?"},
    "refund_requested": {"type": "noul"},
    "severity": {"type": "score", "levels": [1, 2, 3, 4, 5]},
})

# Native schema above; the Jev/TypeSafe `criteria` schema (the one laya and Kev
# speak) works unchanged - drop-in for existing Jev clients:
result = agent.decide("We were charged twice for the same order.", {
    "department": {"type": "choice", "instructions": "Which department should handle this?",
                   "criteria": {"billing": "invoices, payments", "technical": "bugs, outages"}},
    "refund_requested": {"type": "noul"},
    "severity": {"type": "score", "criteria": ["minor", "soon", "blocking"]},
})
{
  "department": {
    "choice": "billing",
    "probabilities": {
      "billing": 0.94,
      "technical": 0.04,
      "sales": 0.01,
      "other": 0.01
    },
    "confidence": 0.94
  },
  "refund_requested": 0.91,
  "severity": {
    "value": 3,
    "probabilities": { "1": 0.02, "2": 0.08, "3": 0.61, "4": 0.22, "5": 0.07 }
  }
}
Confidence gating - automate when confident, escalate when not:
from oev.presets import triage_questions, gate

for name, payload, confident in gate(result, threshold=0.85):
    automate(name, payload) if confident else escalate_to_human(name)
HTTP server (native + Jev-compatible /v1/systemone endpoint - TypeSafe clients work by changing baseUrl):
pip install -e ".[serve]"
oev-serve --checkpoint checkpoints_td5/oev-tiny.pt --port 8000
curl -X POST localhost:8000/decide -H "Content-Type: application/json" \
  -d '{"state": "My payment failed twice", "questions": {"urgency": {"type": "score", "criteria": ["not urgent", "soon", "blocking"]}}}'
Docker:
docker compose up # checkpoint at ./checkpoints/oev-tiny.pt
Training
python -m oev.convert_typed

python -m oev.train --backbone microsoft/deberta-v3-base --epochs 4 --batch-size 8 --max-len 768 --data-dir data/typed --out checkpoints_td5

python -m oev.rlcd --checkpoint checkpoints_td5/oev-tiny.pt --data-dir data/typed --epochs 2 --batch-size 8 --out checkpoints_rlcd

python -m oev.ensemble --ckpts checkpoints_td5/oev-tiny.pt,checkpoints_rlcd/oev-tiny.pt,checkpoints_rlcd_soup/oev-tiny.pt,checkpoints_rlcd_seed1/oev-tiny.pt --data-dir data/typed

python -m pytest -q
train_colab.ipynb runs the entire pipeline end to end. Evaluation rules and scope notes are in BENCHMARKS.md.
Reading the numbers
- Each benchmark number comes from a checkpoint fine-tuned on that benchmark's train split, matching the baselines' published protocol
- Zero-shot emotion is a separate head-to-head win: shipped student
0.6505vs laya0.595(both zero-shot) - The
0.7760headline is a 4-checkpoint ensemble; the best single file is0.7705 - The Banking77 single-file best is the soup at
0.8584;0.8403is a historical re-tune, not the shipped artifact - Adversarial NLI (ANLI) stays near chance for now; WANLI reaches
0.5645and an ANLI specialist is next on the roadmap - The shipped generalist trails the typed specialist (
0.6480vs0.7705); closing that spread is round 4 - CPU: torch fp32 measured
447 msp50 at release; on the current workstation the same fp32 model runs252.5 msand the ONNX INT8 build54.2 ms(8 threads,scripts/bench_latency.py). Headline timings are GPU - English only
Roadmap
- Round 3 distillation: 6 teachers, 5 domains including NLI
- 4-member Banking77 ensemble: the live shot past
0.8584 - Round 4: one file near specialist numbers everywhere
- INT8 / ONNX CPU deployment (export + quantization scripts in
scripts/, bench pending) - Multi-question shared-state encoding (one pass, many questions)
- Robustness: reduce mild overconfidence on out-of-distribution inputs
- Non-English checkpoints (the interface is language-agnostic; the weights are not yet)
Full list: ROADMAP.md.
Credits
The interface and benchmark protocol follow Laya, Kev and the System One model category introduced by TypeSafe's Jev. Their published numbers are quoted here for comparison and remain their measurements.
1 maintainer

Metadata
1 maintainer
Release files for oev 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| oev-0.3.0.tar.gz | 63.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| oev-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 122.0 kB
Release files / oev-0.3.0.tar.gz
| Download URL | oev-0.3.0.tar.gz |
|---|---|
| Size | 63.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
980c708823ba80a194d4df1b1ad6bf5fa75cbae0a733279af7b9feab4c3bd709
|
|
BLAKE2b-256 checksum How to use checksums |
7e733853aab8737034ea6d4c1c439538ec63ab9278b52b35437262f71df99b60
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / oev-0.3.0-py3-none-any.whl
| Download URL | oev-0.3.0-py3-none-any.whl |
|---|---|
| Size | 58.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ccd084957e0f1db2395a172caf734e7c2dc8276656e71e45c2c5ff08445b5422
|
|
BLAKE2b-256 checksum How to use checksums |
38555cba4e9992dc811fadc0d9b4dad324ea832954505c5aec17b76a17726836
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













