
openaivec
AI text processing for pandas and Spark. Apply one prompt to many rows with automatic batching and caching.
Quick start
pip install openaivec
Apply one prompt to many values:
import os
import pandas as pd
from openaivec import pandas_ext

os.environ["OPENAI_API_KEY"] = "your-api-key"

fruits = pd.Series(["apple", "banana", "cherry"])
french_names = fruits.ai.responses(
    "Translate this fruit name to French.",
    reasoning={"effort": "none"},
)
print(french_names.tolist())
# ['pomme', 'banane', 'cerise']
The OpenAI Responses default is gpt-6-luna. These examples explicitly disable reasoning for routine row processing; omitting reasoning uses the model's medium default. See the GPT-6 migration guide for request settings, cache isolation, and rollback. Fabric built-in model defaults remain unchanged.
For Azure OpenAI and custom client setup, see pandas authentication options.
Pandas tutorial (GitHub Pages): https://microsoft.github.io/openaivec/examples/pandas/
Benchmarks
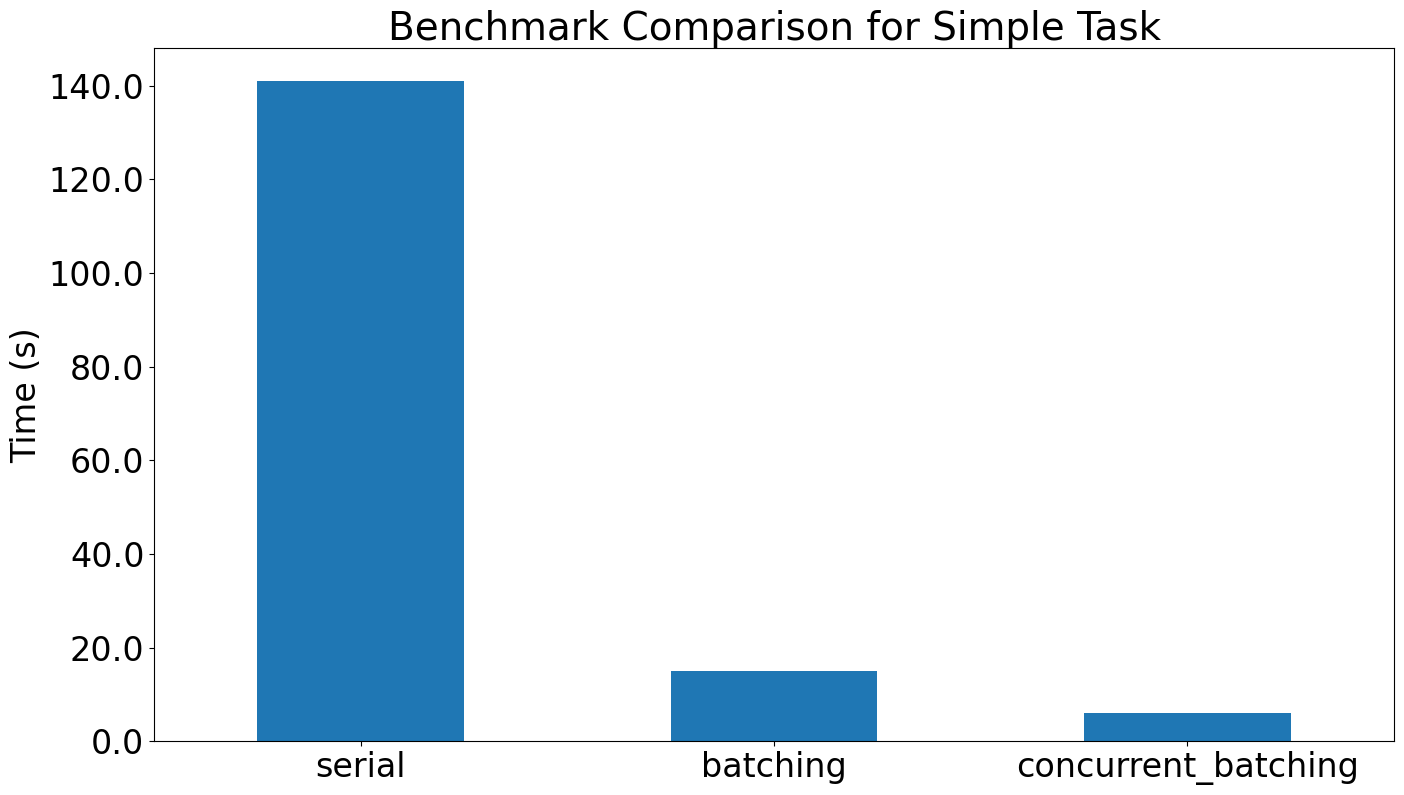
Historical simple task benchmark from benchmark.ipynb (100 numeric strings → integer literals, Series.aio.responses, model gpt-5.1):
| Mode | Settings | Time (s) |
|---|---|---|
| Serial | batch_size=1, max_concurrency=1 |
~141 |
| Batching | default batch_size, max_concurrency=1 |
~15 |
| Concurrent batching | default batch_size, default max_concurrency |
~6 |
These are previously recorded measurements, not GPT-6 results. Batching alone removes most HTTP overhead, and letting batching overlap with concurrency cuts total runtime to a few seconds while still yielding one output per input.
Contents
- Why openaivec?
- Overview
- Core Workflows
- GPT-6 migration guide
- Pandas authentication options
- Using with Apache Spark UDFs
- Spark authentication options
- Using with DuckDB
- Building Prompts
- Using with Microsoft Fabric
- Contributing
- Additional Resources
- Community
Why openaivec?
- Drop-in
.aiand.aioaccessors keep pandas analysts in familiar tooling. - OpenAI batch-optimized:
BatchCache/AsyncBatchCachecoalesce requests, dedupe prompts, preserve order, and release waiters on failure. - Reasoning support mirrors the OpenAI SDK; structured outputs accept Pydantic
response_format. - Built-in caches and retries remove boilerplate; pandas and async helpers can share caches explicitly, while Spark UDFs dedupe repeated inputs within each partition.
- Spark UDFs, DuckDB integration, and Microsoft Fabric guides move notebooks into production-scale ETL.
- Prompt tooling (
FewShotPromptBuilder,improve) and the task library ship curated prompts with validated outputs.
Overview
Vectorized OpenAI batch processing so you handle many inputs per call instead of one-by-one. Batching proxies dedupe inputs, enforce ordered outputs, and unblock waiters even on upstream errors. Shared-cache helpers reuse expensive prompts across pandas and async flows, while Spark UDF builders dedupe repeated inputs within each partition. Reasoning models honor SDK semantics. Requires Python 3.10+.
Core Workflows
Direct API usage
For maximum control over batch processing:
import os
from openai import OpenAI
from openaivec import BatchResponses

# Initialize the batch client
client = BatchResponses.of(
    client=OpenAI(),
    model_name="gpt-6-luna",
    system_message="Please answer only with 'xx family' and do not output anything else.",
    reasoning={"effort": "none"},
    # batch_size defaults to None (automatic optimization)
)

result = client.parse(["panda", "rabbit", "koala"])
print(result)  # Expected output: ['bear family', 'rabbit family', 'koala family']
pandas authentication options
Configure authentication once before using .ai or .aio.
OpenAI (API key)
import os

os.environ["OPENAI_API_KEY"] = "your-openai-api-key"
Azure OpenAI (API key)
import os

os.environ["AZURE_OPENAI_API_KEY"] = "your-azure-openai-api-key"
os.environ["AZURE_OPENAI_BASE_URL"] = "https://YOUR-RESOURCE-NAME.services.ai.azure.com/openai/v1/"
The base URL must end with /openai/v1/.
Azure OpenAI with Entra ID (no API key)
import os

os.environ["AZURE_OPENAI_BASE_URL"] = "https://YOUR-RESOURCE-NAME.services.ai.azure.com/openai/v1/"
os.environ.pop("AZURE_OPENAI_API_KEY", None)
Unset OPENAI_API_KEY as well when choosing Azure. Without either API key,
openaivec uses a configured service principal, or otherwise DefaultAzureCredential,
with a refreshable token provider. DefaultAzureCredential does not automatically
discover a Fabric notebook or workspace identity. See the
authentication guide.
Custom clients (optional)
import openaivec
from openai import AsyncOpenAI, OpenAI
from openaivec import pandas_ext

openaivec.set_client(OpenAI())
openaivec.set_async_client(AsyncOpenAI())
pandas integration (recommended)
The easiest way to get started with your DataFrames (after authentication):
import openaivec
import pandas as pd
from openaivec import pandas_ext

openaivec.set_responses_model("gpt-6-luna")

df = pd.DataFrame({"name": ["panda", "rabbit", "koala"]})

result = df.assign(
    family=lambda df: df.name.ai.responses(
        "What animal family? Answer with 'X family'",
        reasoning={"effort": "none"},
    )
)
| name | family |
|---|---|
| panda | bear family |
| rabbit | rabbit family |
| koala | marsupial family |
📓 Interactive pandas examples →
Using with reasoning models
For more complex analysis, evaluate gpt-6-sol with low reasoning against Luna on representative data. Pass reasoning explicitly to control the quality, cost, and latency tradeoff.
import openaivec

openaivec.set_responses_model("gpt-6-sol")

result = df.assign(
    analysis=lambda df: df.text.ai.responses(
        "Analyze the key issues in this text and give a concise conclusion",
        reasoning={"effort": "low"},
    )
)
Luna and Sol default to medium reasoning when the option is omitted. openaivec forwards request options unchanged. With reasoning other than none, omit temperature, top_p, and logprobs-related options. See the official migration guide. Configure the selected model before creating wrappers or UDFs.
Using pre-configured tasks
For common text processing operations, openaivec provides ready-to-use tasks that eliminate the need to write custom prompts:
from openaivec.task import nlp, customer_support

text_df = pd.DataFrame({
    "text": [
        "Great product, fast delivery!",
        "Need help with billing issue",
        "How do I reset my password?"
    ]
})

results = text_df.assign(
    sentiment=lambda df: df.text.ai.task(
        nlp.sentiment_analysis(),
        reasoning={"effort": "none"},
    ),
    intent=lambda df: df.text.ai.task(
        customer_support.intent_analysis(),
        reasoning={"effort": "none"},
    ),
)

# Extract structured results into separate columns
extracted_results = results.ai.extract("sentiment")
Asynchronous processing with .aio
High-throughput workloads use the .aio accessor for async versions of all operations:
import asyncio
import openaivec
import pandas as pd
from openaivec import pandas_ext

openaivec.set_responses_model("gpt-6-luna")

df = pd.DataFrame({"text": [
    "This product is amazing!",
    "Terrible customer service",
    "Good value for money",
    "Not what I expected"
] * 250})  # 1000 rows for demonstration

async def process_data():
    return await df["text"].aio.responses(
        "Analyze sentiment and classify as positive/negative/neutral",
        reasoning={"effort": "none"},  # Explicit setting for routine classification
        max_concurrency=12    # Allow up to 12 concurrent requests
    )

sentiments = asyncio.run(process_data())
Performance benefits: Parallel processing with automatic batching/deduplication, built-in rate limiting and error handling, and memory-efficient streaming for large datasets.
Using with Apache Spark UDFs
Scale to enterprise datasets with distributed processing.
Spark authentication options
Choose one setup path before registering UDFs.
OpenAI (API key)
from pyspark.sql import SparkSession
from openaivec.spark_ext import setup

spark = SparkSession.builder.getOrCreate()
setup(
    spark,
    api_key="your-openai-api-key",
    responses_model_name="gpt-6-luna",
    embeddings_model_name="text-embedding-3-small",
)
Azure OpenAI (API key)
from pyspark.sql import SparkSession
from openaivec.spark_ext import setup_azure

spark = SparkSession.builder.getOrCreate()
setup_azure(
    spark,
    api_key="your-azure-openai-api-key",
    base_url="https://YOUR-RESOURCE-NAME.services.ai.azure.com/openai/v1/",
    responses_model_name="my-gpt-deployment",
    embeddings_model_name="my-embedding-deployment",
)
The base URL must end with /openai/v1/.
Azure OpenAI with Entra ID (no API key)
import os

os.environ["AZURE_OPENAI_BASE_URL"] = "https://YOUR-RESOURCE-NAME.services.ai.azure.com/openai/v1/"
os.environ.pop("AZURE_OPENAI_API_KEY", None)
Unset OPENAI_API_KEY as well when choosing Azure. Configure credentials on the
Spark executors before registering UDFs; setting the driver's environment alone
does not grant executor access. openaivec uses a configured service principal or
DefaultAzureCredential, neither of which automatically inherits Fabric identity.
Create and register UDFs using the provided helpers:
from openaivec.spark_ext import responses_udf

spark.udf.register(
    "extract_brand",
    responses_udf(
        instructions="Extract the brand name from the product. Return only the brand name.",
        reasoning={"effort": "none"},
    )
)

products = spark.createDataFrame(
    [("Nike Air Max",), ("Apple iPhone 15",)],
    ["product_name"],
)
products.selectExpr("product_name", "extract_brand(product_name) AS brand").show()
Other helper UDFs are available: task_udf, embeddings_udf, count_tokens_udf, similarity_udf, and parse_udf.
Spark performance tips
- Duplicate detection automatically caches repeated inputs per partition for UDFs.
batch_size=Noneauto-optimizes; set 32–128 for fixed sizes if needed.max_concurrencyis per executor; total concurrency = executors × max_concurrency. Start with 4–12.- Monitor rate limits and adjust concurrency to your OpenAI tier.
Using with DuckDB
Register AI-powered functions as DuckDB UDFs and use them in pure SQL. Structured outputs are returned as native STRUCT types with direct field access.
import openaivec
import duckdb
from pydantic import BaseModel
from typing import Literal
from openaivec import duckdb_ext

openaivec.set_responses_model("gpt-6-luna")


class Sentiment(BaseModel):
    label: Literal["positive", "negative", "neutral"]
    confidence: float
    summary: str


conn = duckdb.connect()

duckdb_ext.responses_udf(
    conn,
    "analyze_sentiment",
    instructions="Analyze customer sentiment. Return label, confidence (0-1), and a one-sentence summary.",
    response_format=Sentiment,
    reasoning={"effort": "none"},
)

# Query CSV directly — structured fields, no JSON parsing
conn.sql("""
    SELECT
        customer,
        analyze_sentiment(response).label      AS sentiment,
        analyze_sentiment(response).confidence AS confidence,
        analyze_sentiment(response).summary    AS summary
    FROM 'survey.csv'
""")

# Aggregate with standard SQL
conn.sql("""
    WITH results AS (
        SELECT analyze_sentiment(response).label AS sentiment
        FROM 'survey.csv'
    )
    SELECT sentiment, COUNT(*) AS count
    FROM results
    GROUP BY sentiment
""")
Embedding UDFs work the same way:
duckdb_ext.embeddings_udf(conn, "embed")

conn.sql("""
    SELECT text, list_cosine_similarity(embed(a.text), embed(b.text)) AS similarity
    FROM docs a, queries b
""")
All UDFs use Arrow vectorized execution — DuckDB sends batches of rows that are processed with async concurrency and automatic deduplication.
Building Prompts
Few-shot prompts improve LLM quality. FewShotPromptBuilder structures purpose, cautions, and examples; improve() iterates with OpenAI to remove contradictions.
from openaivec import FewShotPromptBuilder

prompt = (
    FewShotPromptBuilder()
    .purpose("Return the smallest category that includes the given word")
    .caution("Never use proper nouns as categories")
    .example("Apple", "Fruit")
    .example("Car", "Vehicle")
    .improve(reasoning={"effort": "none"})  # optional API call
    .build()
)
📓 Advanced prompting techniques →
Using with Microsoft Fabric
Install openaivec from PyPI in your Fabric notebook or attached environment.
Choose between Fabric's built-in models and your own Azure OpenAI deployment.
Fabric built-in models
import pandas as pd
import openaivec
from openaivec import pandas_ext

openaivec.setup_fabric()

pd.Series(["apple", "banana"]).ai.responses("Translate to French.")
setup_fabric() uses the Fabric runtime's authentication and routing helpers.
No API key, Azure OpenAI resource, or service-principal secret is required.
The defaults are gpt-5.1 for Responses and text-embedding-ada-002 for embeddings;
override them with responses_model and embeddings_model.
- Built-in models are in preview, billed to Fabric capacity, and subject to tenant, capacity, and regional availability.
- Responses are sent with
store=False;store=Trueandprevious_response_idare rejected before sending, including when supplied throughextra_body. - Async access requires
get_openai_httpx_async_client()in the Fabric runtime. Spark UDFs require this helper on Python workers. - Configuration applies to the notebook driver, including local pandas and DuckDB operations. Use the Spark-specific setup below for executor authentication.
For Spark UDFs, install the package in a published Fabric Environment attached
to the notebook, without the spark extra. Then configure it before creating UDFs:
from openaivec.spark_ext import embeddings_udf, setup_fabric

setup_fabric(spark)
embed = embeddings_udf(batch_size=2, max_concurrency=1)
df.withColumn("embedding", embed("text")).show()
Each partition creates and closes its own runtime-authenticated client. No driver
tokens or HTTP clients are sent to workers. responses_udf, task_udf, and
parse_udf use the same route. See the
Spark authentication guide.
Your own Azure OpenAI deployment
Use an identity with Cognitive Services OpenAI User on your Azure OpenAI resource,
an /openai/v1/ base URL, and a refreshable bearer-token provider. This route is billed
to Azure OpenAI, not to Fabric's built-in model meter.
DefaultAzureCredential does not automatically discover the Fabric user or workspace
identity. If using a service-principal secret, store it in Key Vault. The identity
reading that secret needs Key Vault access; do not assume it is the workspace identity.
Secret retrieval is lazy and failures stop authentication instead of switching identities.
See the authentication guide for setup examples, identity requirements, lifecycle guidance, and official references.
Contributing
We welcome contributions! Please:
- Fork and branch from
main. - Add or update tests when you change code.
- Run formatting and tests before opening a PR.
Install dev deps:
uv sync --all-extras --dev
Lint and format:
uv run ruff check . --fix
Quick test pass:
uv run pytest -m "not slow and not requires_api"
Additional Resources
📓 Customer feedback analysis → - Sentiment analysis & prioritization
📓 Survey data transformation → - Unstructured to structured data
📓 Asynchronous processing examples → - High-performance async workflows
📓 Auto-generate FAQs from documents → - Create FAQs using AI
📓 All examples → - Complete collection of tutorials and use cases
Community
Join our Discord community for support and announcements: https://discord.gg/hXCS9J6Qek
1 maintainer

Metadata
1 maintainer
Release files for openaivec 2.7.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| openaivec-2.7.0.tar.gz | 619.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| openaivec-2.7.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 754.5 kB
Release files / openaivec-2.7.0.tar.gz
| Download URL | openaivec-2.7.0.tar.gz |
|---|---|
| Size | 619.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f94022588ebb4378d9239ad972c2dd6d749085051c791f91f5e8ad7c9936f312
|
|
BLAKE2b-256 checksum How to use checksums |
c043e13a9bd1c68f80ef513328225940a13919864e2202bc355693dbd553a1cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency logRelease files / openaivec-2.7.0-py3-none-any.whl
| Download URL | openaivec-2.7.0-py3-none-any.whl |
|---|---|
| Size | 134.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e619a1a8775952471b7fbf2870d3156e07a47a8aa3239ee2a161cf09f5a486f7
|
|
BLAKE2b-256 checksum How to use checksums |
4990881c6a57818d68f1162d6a98c5d2f4ba1413cb474a2f3844518bb8e791d7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency log













