
opencc_jieba_pyo3


opencc_jieba_pyo3 is a Python extension module powered
by Rust, Jieba and PyO3, providing
fast and accurate conversion between different Chinese text variants
using opencc-jieba-rs and OpenCC
algorithms.
Features
- Convert between Simplified Chinese, Traditional Chinese, Taiwan and Hong Kong variants, and Japanese Shinjitai/Kyujitai forms.
- Fast and memory-efficient, leveraging Rust's performance.
- Easy-to-use Python API.
- Supports punctuation conversion and automatic text code detection.
- Chinese word (Both Traditional and Simplified) segmentation (Jieba).
- Keyword extraction (TF-IDF, TextRank).
- Optional punctuation conversion and Chinese script detection.
- Custom OpenCC conversion dictionaries from in-memory mappings or UTF-8 files.
- Jieba user dictionaries from structured entries or UTF-8 files.
🔁 Supported Conversion Configs
| Code | Description |
|---|---|
s2t |
Simplified → Traditional |
t2s |
Traditional → Simplified |
s2tw |
Simplified → Traditional (Taiwan) |
tw2s |
Traditional (Taiwan) → Simplified |
s2twp |
Simplified → Traditional (Taiwan) with idioms |
tw2sp |
Traditional (Taiwan) → Simplified with idioms |
s2hk |
Simplified → Traditional (Hong Kong) |
s2hkp |
Simplified → Traditional (Hong Kong) with idioms |
hk2s |
Traditional (Hong Kong) → Simplified |
hk2sp |
Traditional (Hong Kong) → Simplified with idioms |
t2tw |
Traditional → Traditional (Taiwan) |
tw2t |
Traditional (Taiwan) → Traditional |
t2twp |
Traditional → Traditional (Taiwan) with idioms |
tw2tp |
Traditional (Taiwan) → Traditional with idioms |
t2hk |
Traditional → Traditional (Hong Kong) |
t2hkp |
Traditional → Traditional (Hong Kong) with idioms |
hk2t |
Traditional (Hong Kong) → Traditional |
hk2tp |
Traditional (Hong Kong) → Traditional with idioms |
t2jp |
Japanese Kyujitai → Shinjitai |
jp2t |
Japanese Shinjitai → Kyujitai |
Installation
Build and install the Python wheel using maturin:
# In project root
maturin build --release
pip install ./target/wheels/opencc_jieba_pyo3-<version>-cp<pyver>-abi3-<platform>.whl
Install from source distribution
Source distributions (.tar.gz) can be installed directly with pip. A Rust toolchain is required because the native
extension is compiled locally.
pip install opencc_jieba_pyo3-0.8.0.tar.gz
To force a source build from PyPI instead of using a prebuilt wheel:
pip install --no-binary opencc-jieba-pyo3 opencc-jieba-pyo3
The package uses the Python Stable ABI (abi3) with Python 3.8 as the minimum supported version. A source build
therefore produces a platform-specific cp38-abi3 wheel, for example:
opencc_jieba_pyo3-0.8.0-cp38-abi3-win_amd64.whl
Windows: Some RAM disks or non-standard temporary filesystems may cause
pipto fail withWinError 1during a source build. If this occurs, setTEMPandTMPto a normal local filesystem and retry.
Or for development:
maturin develop -r
See BUILD.md for detailed build and install instructions.
Usage
Basic conversion
from opencc_jieba_pyo3 import OpenCC

cc = OpenCC("s2t")

print(cc.convert("八千里路云和月"))
# 八千里路雲和月

print(cc.convert("“春眠不觉晓,处处闻啼鸟。”", punctuation=True))
# 「春眠不覺曉,處處聞啼鳥。」
The active configuration can be inspected or changed without creating a new instance:
from opencc_jieba_pyo3 import OpenCC

cc = OpenCC()

print(cc.get_config())  # s2t

cc.set_config("t2s")
print(cc.convert("八千里路雲和月"))
# 八千里路云和月
Use OpenCC.supported_configs() to enumerate the canonical configuration names and
OpenCC.is_valid_config() to validate a name.
Unicode compatibility normalization
v0.8.0 exposes three normalization APIs. Normalization is explicit and does not run automatically during
convert():
normalize_compat()normalizes CJK Compatibility Ideographs.normalize_unicode_compat()normalizes the extended Unicode compatibility/variant table.normalize_compat_extended()applies the extended table and CJK Compatibility Ideograph normalization together.
from opencc_jieba_pyo3 import OpenCC

cc = OpenCC("t2s")

text = "天龍八部書裡的喬峰是契丹人"
normalized = cc.normalize_compat(text)

print(normalized)
# 天龍八部書裡的喬峰是契丹人

print(cc.convert(normalized))
# 天龙八部书里的乔峰是契丹人
For broader compatibility/variant normalization:
from opencc_jieba_pyo3 import OpenCC

text = "聼聼竒羙⽟䂖甁噐⾳"
cc = OpenCC("t2s")
normalized = cc.normalize_compat_extended(text)
print(normalized)
# 聽聽奇美玉石瓶器音

print(cc.convert(normalized))
# 听听奇美玉石瓶器音
normalize_unicode_compat() is also available when only the extended Unicode table is wanted.
Jieba segmentation and tagging
from opencc_jieba_pyo3 import OpenCC

cc = OpenCC()
text = "我独自来到无人海岸线"

print(cc.jieba_cut(text, hmm=True))
# ['我', '独自', '来到', '无人', '海岸线']

print(cc.jieba_cut_for_search(text, hmm=True))
# ['我', '独自', '来到', '无人', '海岸', '岸线', '海岸线']

print(cc.jieba_segment_join(text, mode="cut", delim="/"))
# 我/独自/来到/无人/海岸线

print(cc.jieba_segment_join(text, mode="tag", delim=" ", separator=":"))
# 我:r 独自:d 来到:v 无人:n 海岸线:n
Supported jieba_segment_join() modes are cut, search, full, and tag.
Keyword extraction
from opencc_jieba_pyo3 import OpenCC

cc = OpenCC()
text = "我独自来到无人海岸线"

keywords = cc.jieba_keyword_extract_textrank(text, top_k=3)
print(keywords)

keywords_tfidf = cc.jieba_keyword_extract_tfidf(text, top_k=3)
print(keywords_tfidf)

weighted = cc.jieba_keyword_weight_textrank(text, top_k=3)
print(weighted)

weighted_tfidf = cc.jieba_keyword_weight_tfidf(text, top_k=3)
print(weighted_tfidf)
The keyword APIs also accept an optional allowed_pos list.
Custom dictionaries
v0.8.0 provides two complementary dictionary layers:
- Jieba user dictionaries teach the tokenizer how to keep domain-specific words together and can optionally assign POS tags. They affect segmentation, tagging, keyword extraction, and the token boundaries seen by conversion.
- Custom OpenCC dictionaries add or replace mappings in a conversion-dictionary slot. They affect conversion but do not modify the Jieba dictionary.
Both layers can be loaded into the same OpenCC instance. For a custom phrase that Jieba would otherwise split, add the
phrase to the Jieba user dictionary as well as the appropriate OpenCC conversion slot.
Typed dictionary specifications
The package exports UserDictEntry, CustomDictSpec, and CustomDictFileSpec for typed Python code:
from typing import List

from opencc_jieba_pyo3 import CustomDictSpec, UserDictEntry

user_dict: List[UserDictEntry] = [
    {
        "word": "細路哥",
        "freq": 3,
    }
]

custom_specs: List[CustomDictSpec] = [
    {
        "slot": "HKPhrasesRev",
        "pairs": [("細路哥", "小男孩")],
        "mode": "append",
    }
]
mode is optional and defaults to append. append merges mappings into the selected slot; override replaces the
contents of that slot. Use OpenCC.available_slots() to obtain the canonical slot names. Slot matching is
case-insensitive; surrounding whitespace and an optional .txt suffix are accepted.
In-memory dictionaries
from typing import List

from opencc_jieba_pyo3 import CustomDictSpec, OpenCC, UserDictEntry

user_dict: List[UserDictEntry] = [
    {
        "word": "細路哥",
        "freq": 3,
    }
]

custom_specs: List[CustomDictSpec] = [
    {
        "slot": "HKPhrasesRev",
        "pairs": [("細路哥", "小男孩")],
        "mode": "append",
    }
]

cc = OpenCC("hk2sp")
cc.load_user_dict_entries(user_dict)
cc.load_custom_dicts(custom_specs)

print(cc.jieba_cut("這個細路哥很靈活"))
# ['這個', '細路哥', '很', '靈活']

print(cc.convert("這個細路哥很靈活"))
# 这个小男孩很灵活
Convenience constructors are also available when the dictionaries are known at construction time:
from typing import List

from opencc_jieba_pyo3 import CustomDictSpec, OpenCC, UserDictEntry

user_dict: List[UserDictEntry] = [
    {
        "word": "細路哥",
        "freq": 3,
    }
]

custom_specs: List[CustomDictSpec] = [
    {
        "slot": "HKPhrasesRev",
        "pairs": [("細路哥", "小男孩")],
        "mode": "append",
    }
]

cc1 = OpenCC.from_user_dict_entries("hk2sp", user_dict)
cc2 = OpenCC.from_dicts("hk2sp", custom_specs)
Dictionary files
Jieba user-dictionary files are UTF-8 text with one entry per line. freq is required and tag is optional:
word freq [tag]
細路哥 3
帕兰蒂尔 100000 nz
Custom OpenCC dictionary files are UTF-8 tab-separated source/target mappings:
細路哥<TAB>小男孩
Use CustomDictFileSpec for strict typing:
from typing import List

from opencc_jieba_pyo3 import CustomDictFileSpec, OpenCC

custom_files: List[CustomDictFileSpec] = [
    {
        "slot": "HKPhrasesRev",
        "mode": "append",
        "files": ["tests/data/my_hk_dict.txt"],
    }
]

cc = OpenCC("hk2sp")
cc.load_user_dict_files(["tests/data/user_dict.txt"])
cc.load_custom_dict_files(custom_files)

print(cc.convert("這個細路哥很靈活"))
# 这个小男孩很灵活
File-based convenience constructors are also available:
from opencc_jieba_pyo3 import OpenCC

custom_specs = [
    {
        "slot": "STPhrases",
        "files": ["a.txt", "b.txt"],
        "mode": "append",
    }
]

cc1 = OpenCC.from_user_dict_files("s2t", ["jieba_user_dict.txt"])
cc2 = OpenCC.from_dict_files("s2t", custom_specs)
A single Jieba dictionary file can be loaded with load_user_dict(path). Multiple files are applied in the supplied
order.
Why Jieba and OpenCC dictionaries sometimes need each other
OpenCC phrase conversion operates on Jieba-tokenized text. If Jieba splits a custom phrase, a phrase mapping cannot match the complete source text.
For example, without a Jieba user entry:
這個 細路 哥 很 靈活
Adding 細路哥 3 to a Jieba user dictionary keeps the phrase together:
這個 細路哥 很 靈活
The HKPhrasesRev mapping 細路哥 → 小男孩 can then produce:
这个小男孩很灵活
This is why convert supports both -U and -D, while segment only needs -U.
CLI
The package can be invoked either as a module or through the installed opencc-jieba-pyo3 script:
python -m opencc_jieba_pyo3 <command> [options]
opencc-jieba-pyo3 <command> [options]
Available commands:
convert— convert text with OpenCC + Jieba.segment— segment/tag text with Jieba.office— convert supported Office/document formats.
Run opencc-jieba-pyo3 <command> --help for the complete option list.
Text conversion
opencc-jieba-pyo3 convert -i input.txt -o output.txt -c s2t --punct
Standard input and output are supported:
echo "這個細路哥很靈活" | opencc-jieba-pyo3 convert -c hk2sp
Normalization can be enabled before conversion:
opencc-jieba-pyo3 convert -c t2s -E -i input.txt -o output.txt
-n,--norm-compat— normalize CJK Compatibility Ideographs.-E,--norm-compat-extended— apply extended compatibility normalization; takes precedence over-n.
Custom Jieba and OpenCC dictionaries can be composed:
opencc-jieba-pyo3 convert -c hk2sp \
  -U tests/data/user_dict.txt \
  -D HKPhrasesRev:append:tests/data/my_hk_dict.txt
-U and -D may each be repeated. Windows drive-letter paths are supported in -D specifications, for example
STPhrases:append:R:\dicts\custom_st_phrases.txt.
Segmentation
opencc-jieba-pyo3 segment -i input.txt -o output.txt --delim "/" --mode search
The modes are cut, search, full, and tag. Use --no-hmm to disable HMM where applicable.
Jieba user dictionaries are supported with -U:
echo "這個細路哥很靈活" | opencc-jieba-pyo3 segment -U tests/data/user_dict.txt
Compatibility normalization is available with -n and -E before segmentation. Custom OpenCC -D mappings are not
used by segmentation.
Office/document conversion
opencc-jieba-pyo3 office -i input.docx -o output.docx -c s2t --punct --keep-font
opencc-jieba-pyo3 office -i input.epub -o output.epub -c s2tw --punct
Supported target formats are docx, xlsx, pptx, odt, ods, odp, and epub.
The Office command supports:
-c,--configfor the conversion configuration.-p,--punctfor punctuation conversion.-D,--custom-dictfor custom OpenCC dictionary files.-U,--user-dict-filefor Jieba user dictionaries.--auto-extto append the target extension automatically.--keep-fontto preserve font-family information.
API
OpenCC
OpenCC(config: str = "s2t")
The class combines OpenCC conversion dictionaries with a Jieba tokenizer.
Configuration
OpenCC.supported_configs() -> list[str]OpenCC.is_valid_config(config: str) -> boolOpenCC.canonicalise_config(config: str) -> strget_config() -> strset_config(config: str) -> None
Conversion and normalization
convert(input: str, punctuation: bool = False) -> strnormalize_compat(input: str) -> strnormalize_unicode_compat(input: str) -> strnormalize_compat_extended(input: str) -> strzho_check(input: str) -> int
zho_check() returns 1 for Traditional Chinese, 2 for Simplified Chinese, and 0 for other/undetermined text.
Jieba segmentation and tagging
jieba_cut(input: str, hmm: bool = True) -> list[str]jieba_cut_for_search(input: str, hmm: bool = True) -> list[str]jieba_cut_all(input: str) -> list[str]jieba_tag(input: str, hmm: bool = True) -> list[tuple[str, str]]jieba_segment_join(input: str, mode: str = "cut", delim: str = " ", hmm: bool = True, separator: str = "/") -> strjieba_cut_and_join(input: str, delimiter: str = "/") -> str— deprecated compatibility wrapper.
Keyword extraction
jieba_keyword_extract_textrank(input: str, top_k: int = 10, allowed_pos: list[str] | None = None) -> list[str]jieba_keyword_extract_tfidf(input: str, top_k: int = 10, allowed_pos: list[str] | None = None) -> list[str]
jieba_keyword_weight_textrank(input: str, top_k: int = 10, allowed_pos: list[str] | None = None) -> list[tuple[str, float]]
jieba_keyword_weight_tfidf(input: str, top_k: int = 10, allowed_pos: list[str] | None = None) -> list[tuple[str, float]]
Jieba user dictionaries
OpenCC.from_user_dict_entries(config="s2t", entries=None) -> OpenCCOpenCC.from_user_dict_files(config="s2t", files=None) -> OpenCCload_user_dict_entries(entries) -> Noneload_user_dict(path) -> Noneload_user_dict_files(files) -> None
Custom OpenCC dictionaries
OpenCC.from_dicts(config="s2t", specs=None) -> OpenCCOpenCC.from_dict_files(config="s2t", specs=None) -> OpenCCload_custom_dicts(specs) -> Noneload_custom_dict_files(specs) -> NoneOpenCC.available_slots() -> list[str]
The exported typing helpers are UserDictEntry, CustomDictSpec, and CustomDictFileSpec.
Development
- Rust source: src/lib.rs
- Python bindings: opencc_jieba_pyo3/ init.py, opencc_jieba_pyo3/opencc_jieba_pyo3.pyi
- CLI: opencc_jieba_pyo3/ main.py
Rust Module Required
opencc-jieba-rs : A Rust implementation of Jieba + OpenCC
Benchmarks
Package: opencc_jieba_pyo3
Python 3.13.4 (tags/v3.13.4:8a526ec, Jun  3 2025, 17:46:04) [MSC v.1943 64 bit (AMD64)]
Platform: Windows-11-10.0.26100-SP0
Processor: Intel64 Family 6 Model 191 Stepping 2, GenuineIntel
BENCHMARK RESULTS
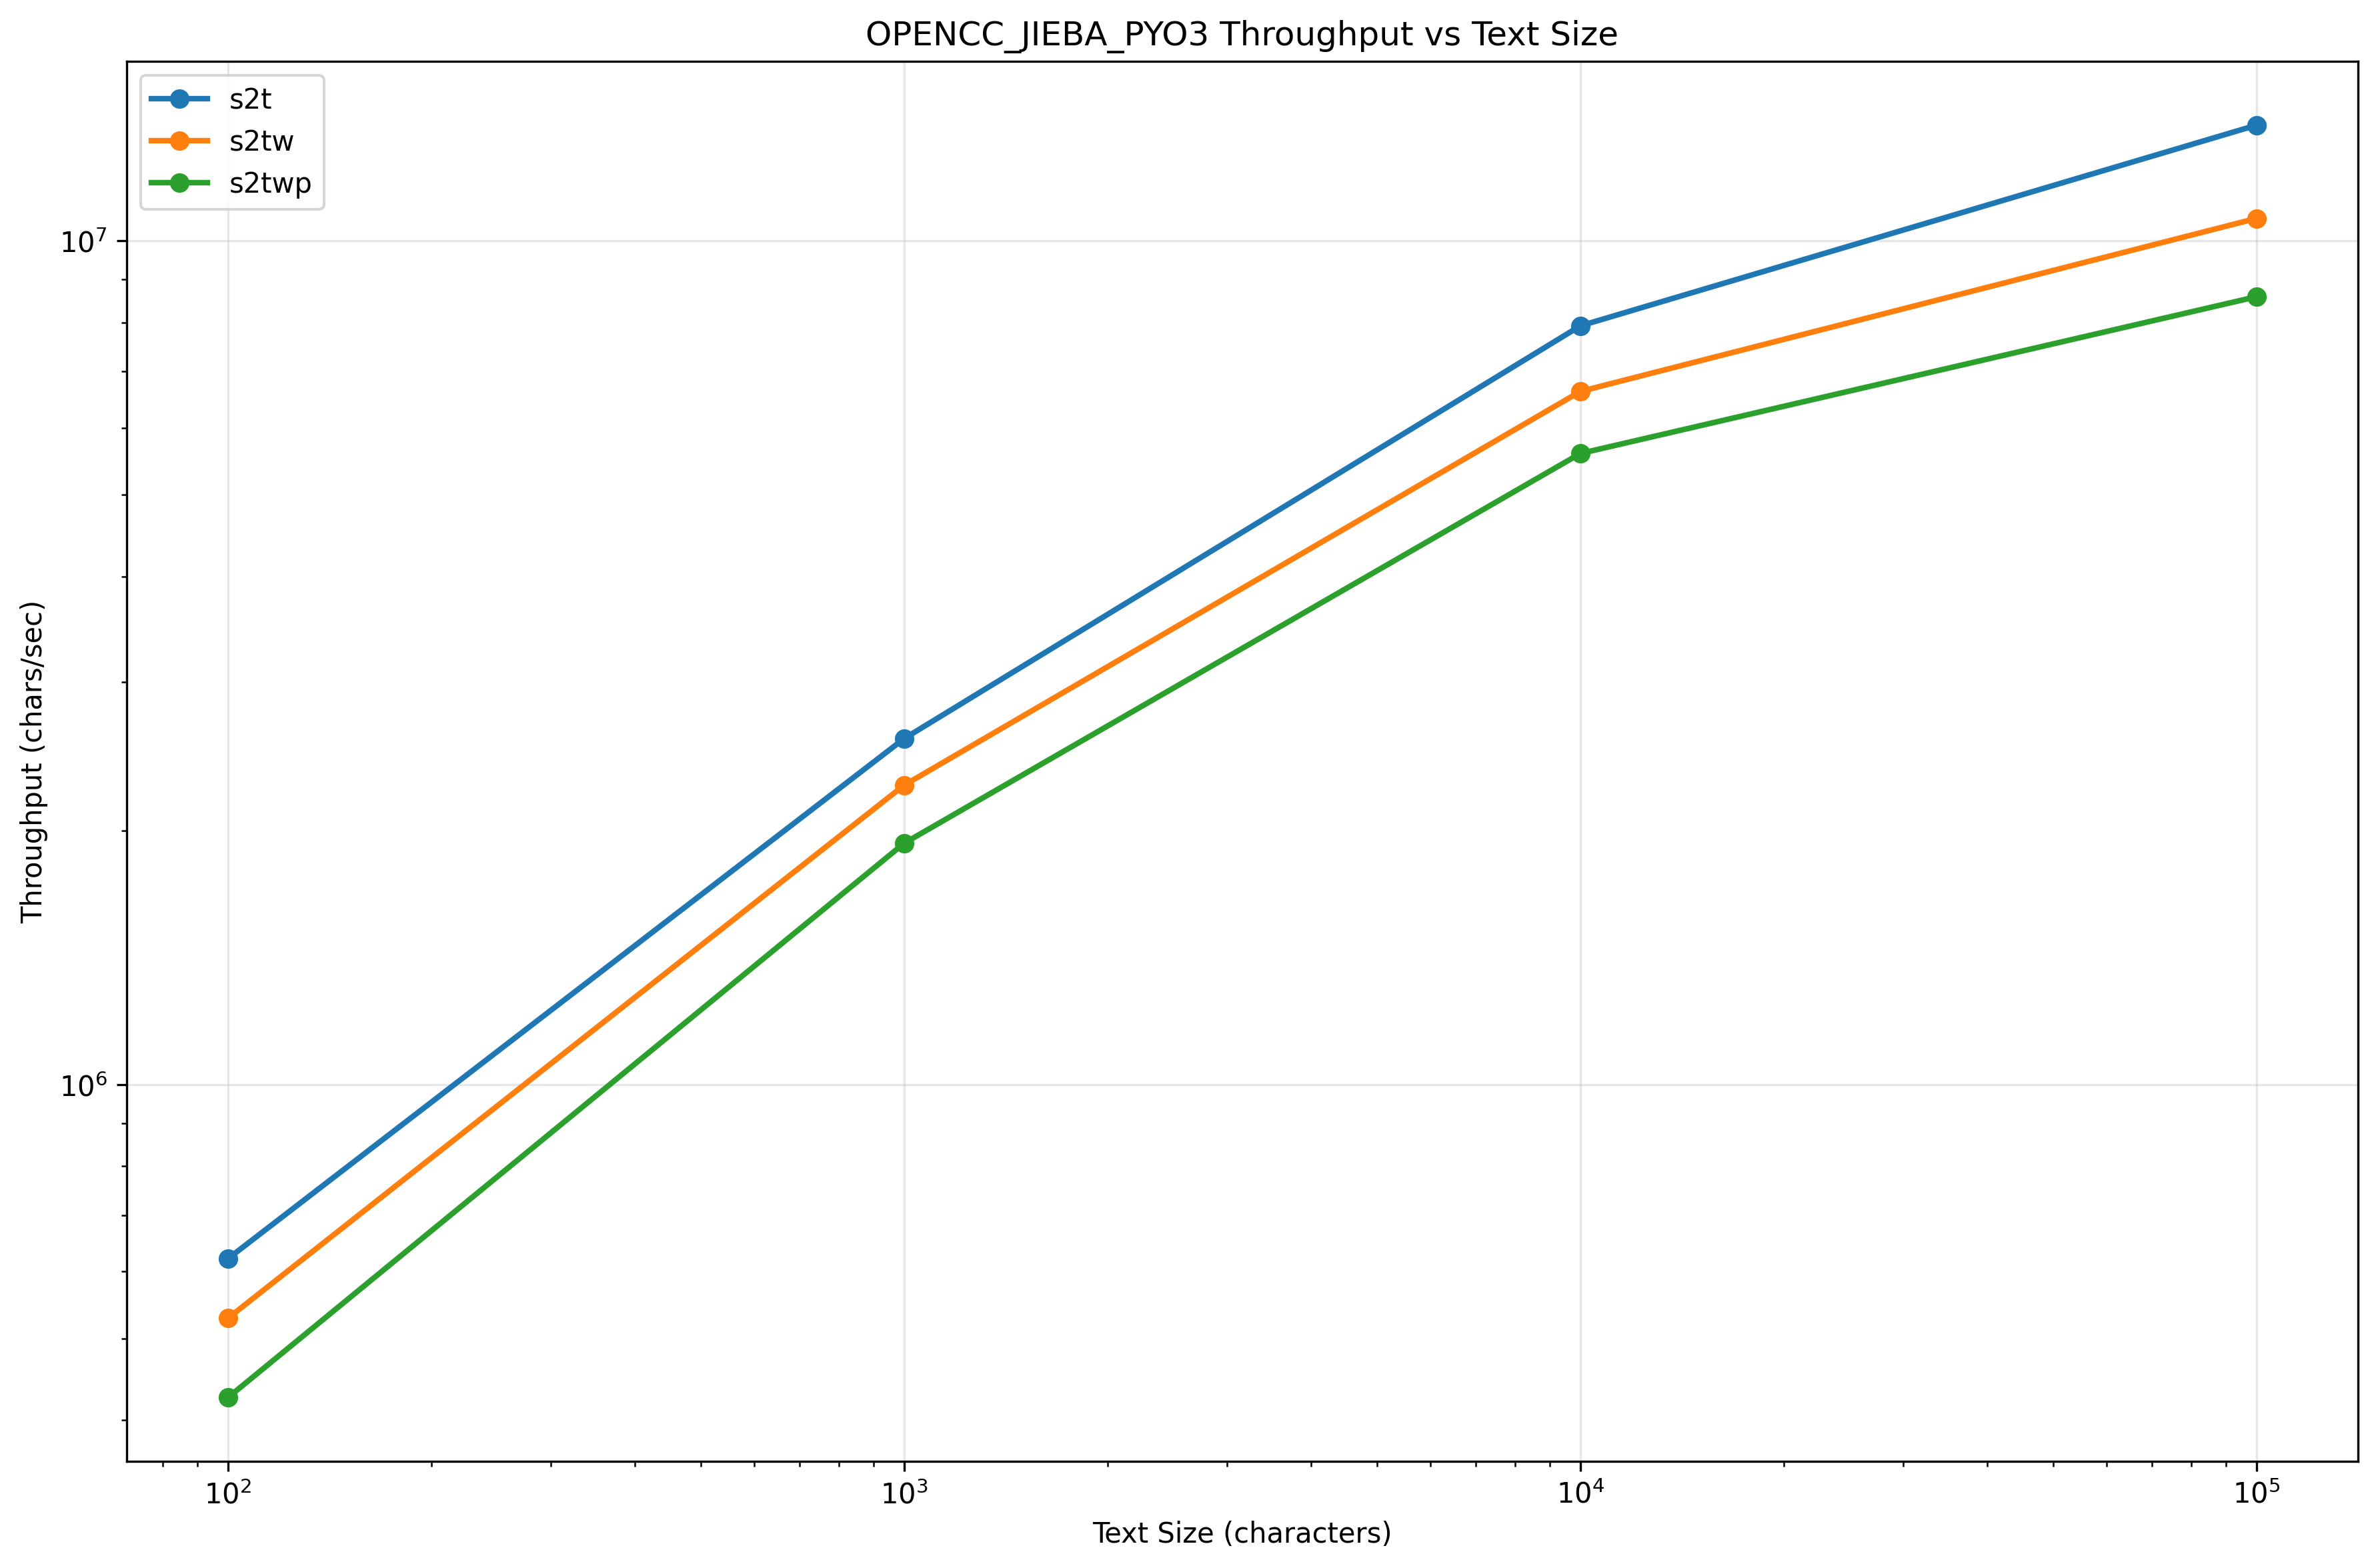
| Method | Config | TextSize | Mean | StdDev | Min | Max | Ops/sec | Chars/sec |
|---|---|---|---|---|---|---|---|---|
| Convert_Small | s2t | 100 | 0.161 ms | 0.109 ms | 0.080 ms | 0.794 ms | 6,217 | 621,740 |
| Convert_Medium | s2t | 1,000 | 0.389 ms | 0.092 ms | 0.286 ms | 0.829 ms | 2,571 | 2,571,236 |
| Convert_Large | s2t | 10,000 | 1.261 ms | 0.314 ms | 1.072 ms | 2.580 ms | 793 | 7,932,120 |
| Convert_XLarge | s2t | 100,000 | 7.290 ms | 0.464 ms | 6.864 ms | 9.848 ms | 137 | 13,716,798 |
| Convert_Small | s2tw | 100 | 0.189 ms | 0.104 ms | 0.103 ms | 0.620 ms | 5,285 | 528,519 |
| Convert_Medium | s2tw | 1,000 | 0.442 ms | 0.152 ms | 0.322 ms | 1.084 ms | 2,264 | 2,264,206 |
| Convert_Large | s2tw | 10,000 | 1.508 ms | 0.200 ms | 1.367 ms | 2.371 ms | 663 | 6,631,682 |
| Convert_XLarge | s2tw | 100,000 | 9.403 ms | 0.585 ms | 9.009 ms | 13.320 ms | 106 | 10,635,363 |
| Convert_Small | s2twp | 100 | 0.235 ms | 0.113 ms | 0.129 ms | 0.648 ms | 4,256 | 425,586 |
| Convert_Medium | s2twp | 1,000 | 0.518 ms | 0.112 ms | 0.363 ms | 0.913 ms | 1,932 | 1,932,266 |
| Convert_Large | s2twp | 10,000 | 1.786 ms | 0.209 ms | 1.590 ms | 2.739 ms | 560 | 5,598,571 |
| Convert_XLarge | s2twp | 100,000 | 11.644 ms | 0.979 ms | 10.892 ms | 17.130 ms | 86 | 8,588,034 |
Throughput VS Size
License
Powered by Rust, Jieba, PyO3, OpenCC and opencc-jieba-rs.
1 maintainer

Metadata
1 maintainer
Release files for opencc-jieba-pyo3 0.8.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| opencc_jieba_pyo3-0.8.0.tar.gz | 38.9 kB | Without provenance | Details for opencc_jieba_pyo3-0.8.0.tar.gz |
Built distributions (wheels)
Total release size: 50.3 MB
Release files / opencc_jieba_pyo3-0.8.0.tar.gz
| Download URL | opencc_jieba_pyo3-0.8.0.tar.gz |
|---|---|
| Size | 38.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7b74d0888ba97cfcf61fecf5c7f6213a4fd9f17452798e1d6b38a0488e468eb6
|
|
BLAKE2b-256 checksum How to use checksums |
a36801377c93ca94f4a10de596e57541f4d4d0448f511b943bed98e2ac0344d5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-win_arm64.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-win_arm64.whl |
|---|---|
| Size | 7.0 MB |
| Tags | CPython 3.8 Windows ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
d524598aadd9248249203a87cca075e5b77bccf5e3f19bc5f42dcddd8d0eeadc
|
|
BLAKE2b-256 checksum How to use checksums |
c7efd90612f7f86e53f422e3b1cd9cfbe264c9f701f99682c28f1843053c7cfe
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-win_amd64.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-win_amd64.whl |
|---|---|
| Size | 7.1 MB |
| Tags | CPython 3.8 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
5f54488c2a9b1b38eb2a3180894e7dce2394f48547ad3fc01009dd2bb71164c8
|
|
BLAKE2b-256 checksum How to use checksums |
f4ede7426fe1d4854cd79bf7902518728a1d491a6f4a978c9c8becf4c4a5db62
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-win32.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-win32.whl |
|---|---|
| Size | 6.9 MB |
| Tags | CPython 3.8 Windows x86-32 abi3 |
|
SHA-256 checksum How to use checksums |
e3b4dd2d36aef7d624fb8329fe906908602cd3ed810d58f10e1b896dc9aece43
|
|
BLAKE2b-256 checksum How to use checksums |
eb6b606e83001e14aa59695ce36ad940300059027eb50ae02986da8b4f991d4c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 7.4 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
ba47b2d8ff3eeaa5a8c56a2db91170c0bfc0d52dbd7c4e6c00d07d835f90126b
|
|
BLAKE2b-256 checksum How to use checksums |
a169b8e52d4c859e2d4054debd2bacb4b2cacf1a8ccfb060e64e7439024a0d32
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
|---|---|
| Size | 7.5 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
088f11e7c052e2fcecd29dd7d2a931a569a8a0ed242ca2ddeb0d038ded55f589
|
|
BLAKE2b-256 checksum How to use checksums |
a9e5facc72d383d03c442089a153534f0a02a313ba861e8c007637fc2ef48641
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-macosx_11_0_arm64.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 7.2 MB |
| Tags | CPython 3.8 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
47883258dbe169c8a478396cf6016bad4b649fab9d15e0c94a7b998de0110dca
|
|
BLAKE2b-256 checksum How to use checksums |
1ea450edee4064206744dac00892a55b45af7732edd532514a5bcec88dd95e7a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / opencc_jieba_pyo3-0.8.0-cp38-abi3-macosx_10_12_x86_64.whl
| Download URL | opencc_jieba_pyo3-0.8.0-cp38-abi3-macosx_10_12_x86_64.whl |
|---|---|
| Size | 7.2 MB |
| Tags | CPython 3.8 abi3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
f9675158718fb69ee8796fcd1ba9b721a9af81d89c183685ca14c655dc142e69
|
|
BLAKE2b-256 checksum How to use checksums |
c21335312a44930177aea14070818c0c20bb85801fe1e74e8f39c37a7b510753
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Security for opencc-jieba-pyo3 0.8.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














