
Ordifile



Batch-convert and consolidate scientific instrument results into one clean, ordered and auditable Excel workbook.
Is Ordifile right for my lab?
Ordifile is for researchers who need to combine explicit chromatography Result or structured peak tables locally while preserving measured values, units, source order, and per-file outcomes. It supports exact Experimental profiles only where fixture-backed evidence exists; other structured tables require explicit user mapping.
Ordifile is not a CDS replacement, acquisition controller, peak detector, compound identification or RT-alignment engine, statistics suite, quantitation/calibration engine, cloud platform, or LIMS. It does not infer missing scientific meaning. See the product concept, researcher documentation, and pilot checklist before evaluating it with laboratory exports.
Ordifile's proprietary-format direction is result-first: evidence-backed retention
time and area tables from Agilent, Shimadzu, YoungIn and LECO should converge on the same
Peaks / Peak_Matrix workbook model. Raw signals are an optional, independently
validated capability: a result export does not require its raw file to be present.
Each vendor result adapter remains a separate exact-format
reader, but its verified peak rows behave identically after canonical conversion. No
vendor result parser is claimed before an actual result fixture proves its field
boundaries and semantics.
Verified stable formats: CSV, TSV, semicolon-delimited TXT, and audited non-macro XLSX using Ordifile's documented schema. The current development source tree also includes eight narrowly bounded Experimental proprietary readers described below; this is not general vendor-format support. Published availability is shown by the PyPI badge.
sample_1.csv   sample_2.tsv   exported_peaks.xlsx
          \          |          /
           ordifile convert ...
                    |
                    v
          Ordifile_Result.xlsx
          ├── Manifest
          ├── Samples
          ├── Peak_Matrix
          ├── Peaks
          ├── Metadata
          └── Import_Log
Install
Install the latest published Ordifile release from PyPI. The PyPI badge above shows the
currently available version. The README on main may also describe capabilities listed
under Unreleased or prepared for a not-yet-published release; pip install
provides the version shown by the badge.
python -m pip install ordifile
The Experimental desktop interface is available through an optional extra, which keeps default CLI/API installations free of a Qt runtime dependency:
python -m pip install "ordifile[gui]"
ordifile-gui
This is a Python-package GUI, not a standalone .exe or .app.
Quick start
python -c "from pathlib import Path; p=Path('ordifile_demo'); p.mkdir(exist_ok=True); [(p / f'sample_{n}.csv').write_text(f'sample_id,retention_time,area,compound\nsample_{n},{n / 10:.1f},{n * 10},demo\n', encoding='utf-8') for n in (1, 2, 10)]"
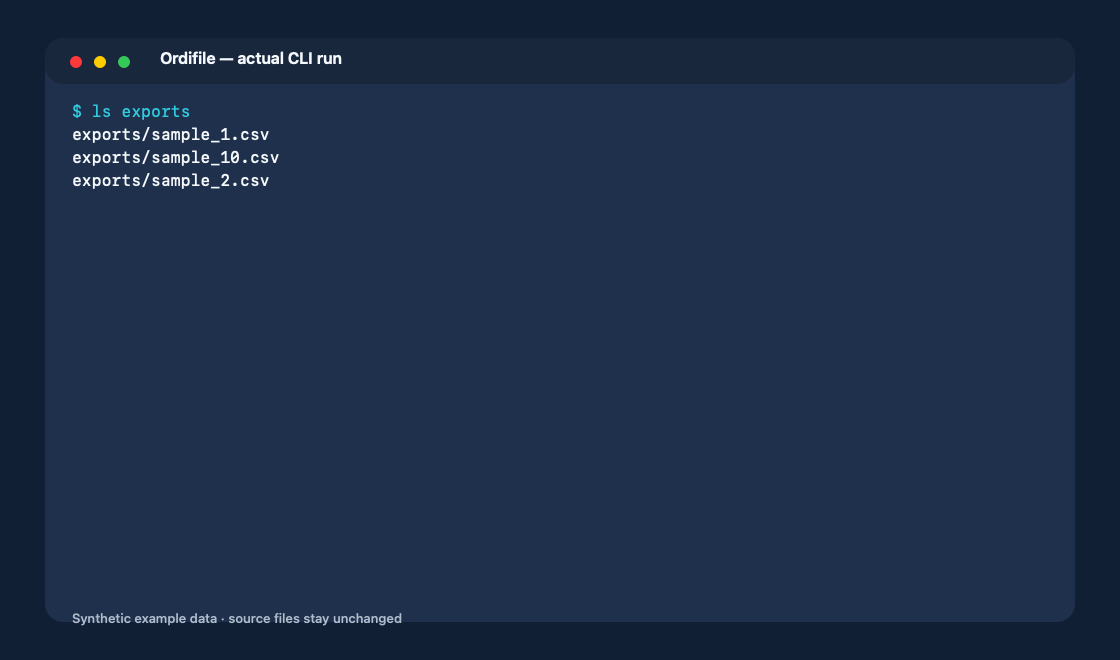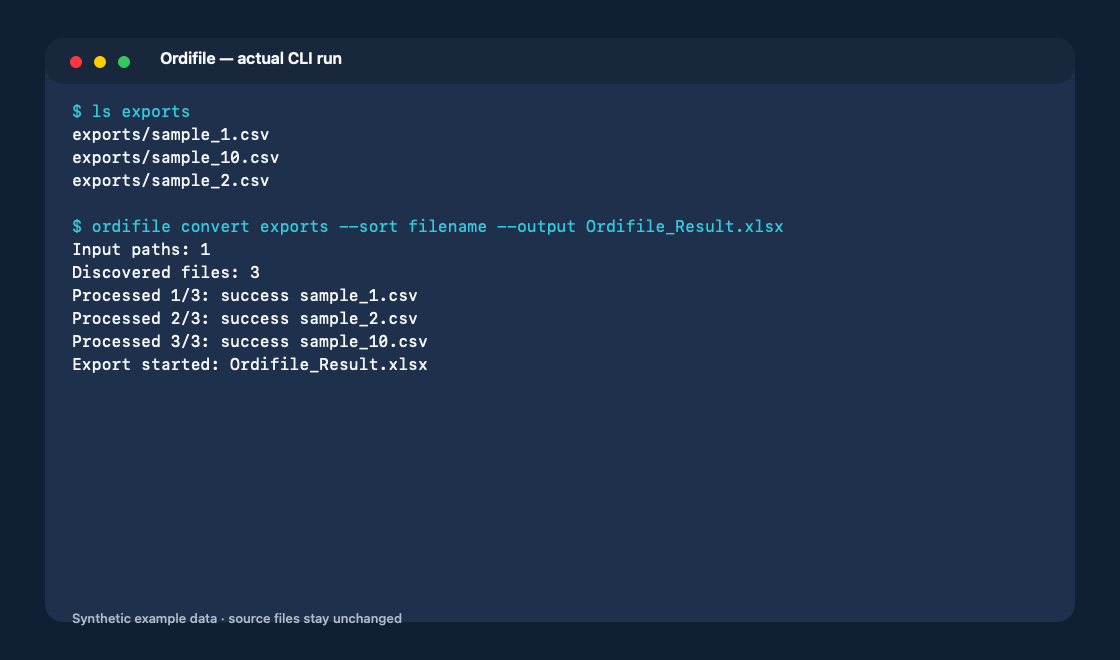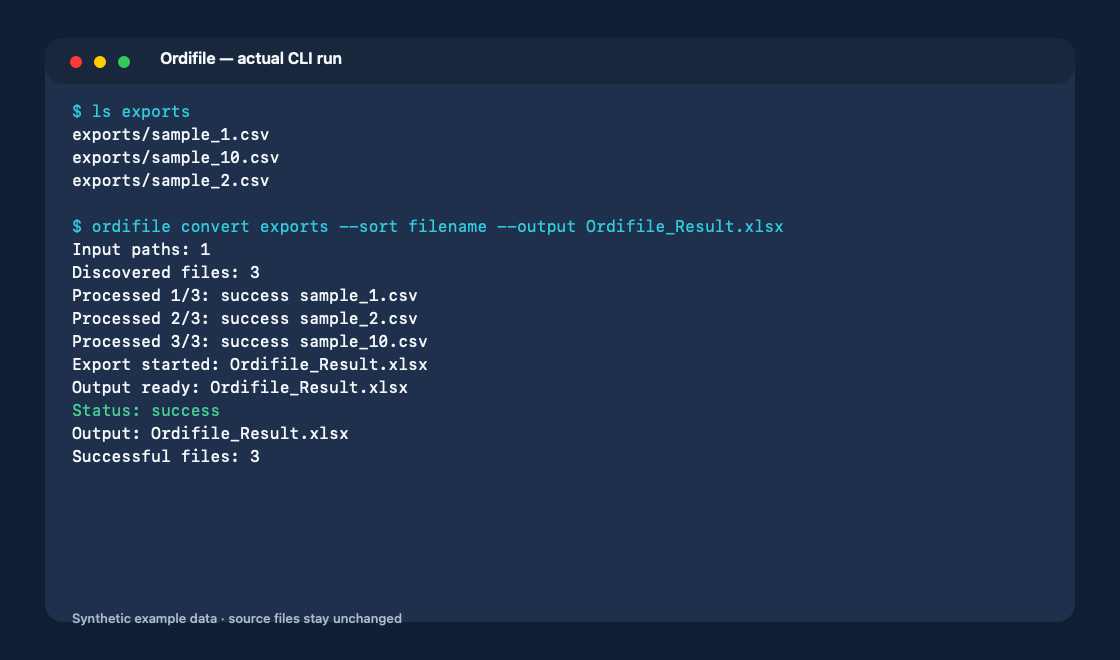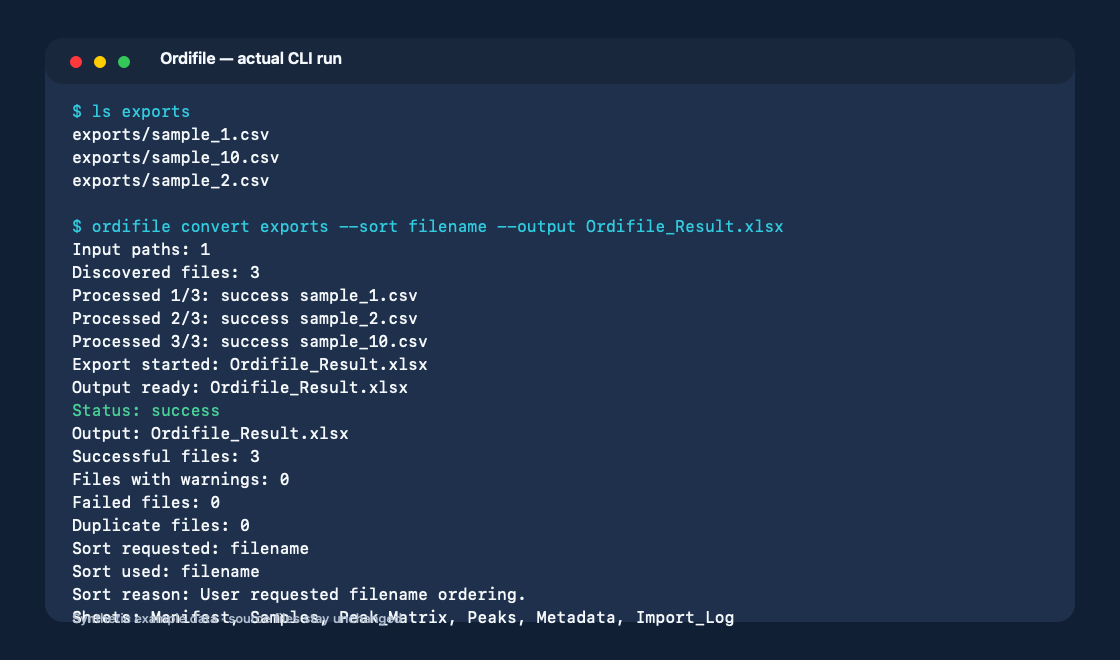
ordifile convert ordifile_demo --sort filename --output Ordifile_Result.xlsx
This package-independent synthetic example produces:
Input paths: 1
Discovered files: 3
Processed 1/3: success sample_1.csv
Processed 2/3: success sample_2.csv
Processed 3/3: success sample_10.csv
Export started: Ordifile_Result.xlsx
Output ready: Ordifile_Result.xlsx
Status: success
Output: Ordifile_Result.xlsx
Successful files: 3
Files with warnings: 0
Failed files: 0
Skipped files: 0
Duplicate files: 0
Samples: 3
Peaks: 3
Scientific signal series: 0
Structural record series: 0
Sort requested: filename
Sort used: filename
Sort reason: User requested filename ordering.
Sheets: Manifest, Samples, Peak_Matrix, Peaks, Metadata, Import_Log
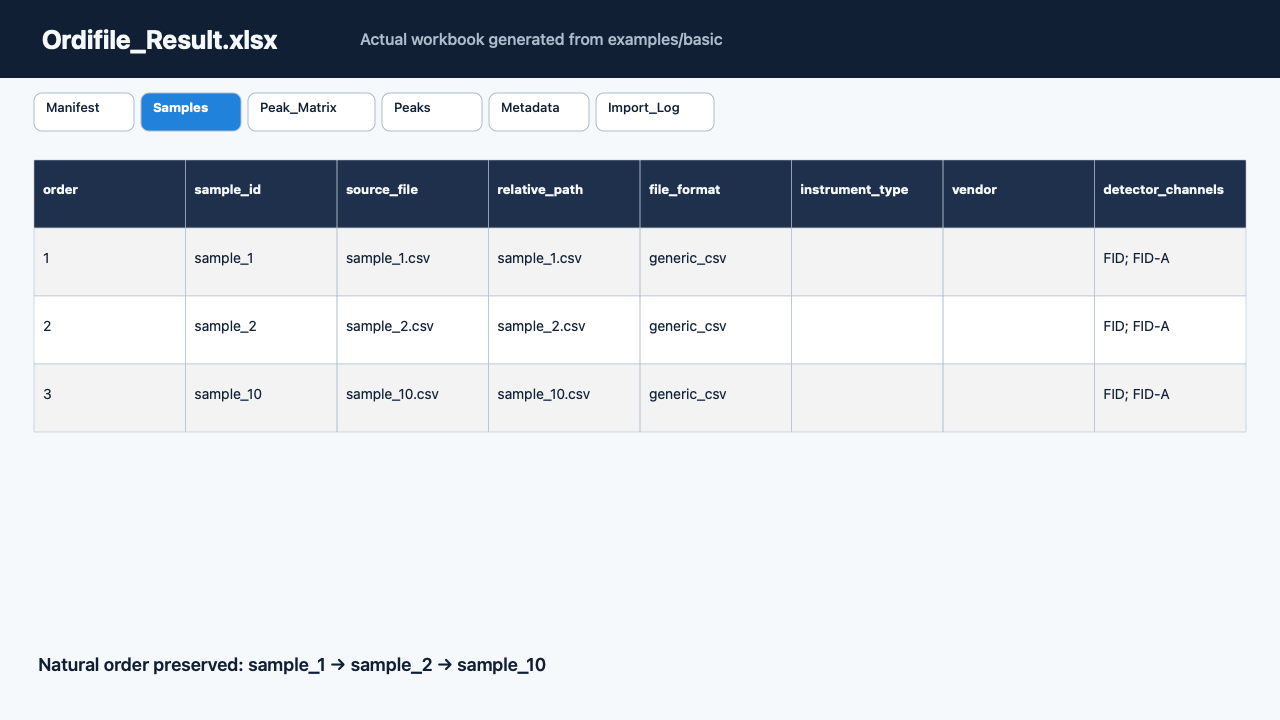
The source files remain unchanged. Natural filename ordering keeps sample_2 before
sample_10.
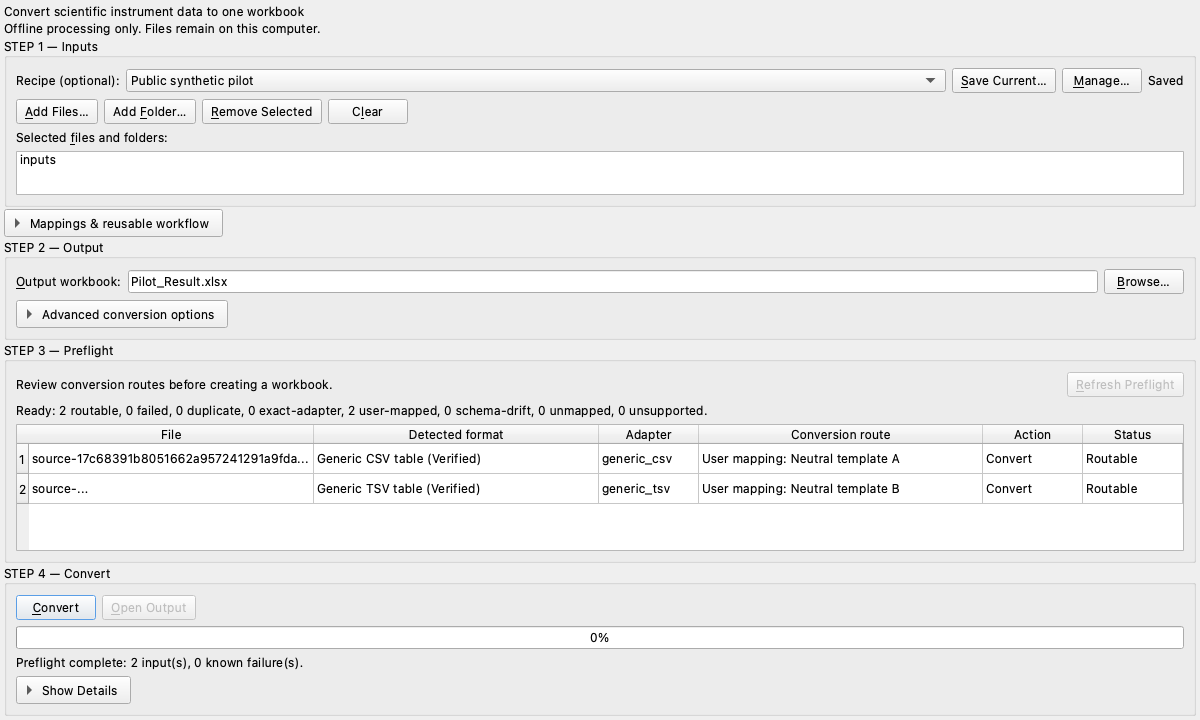
Experimental desktop interface
The optional desktop interface keeps the first workflow to four visible steps:
Inputs → Output → Preflight → Convert. Use Add Files, Add Folder, or local
file-manager drag and drop, choose an .xlsx output, review the authoritative routing
table, and convert in a background worker. Progress and per-file success, warning, or
failure remain visible. Mapping, Mapping Set, sort, drift review, and diagnostic details
remain available through collapsed or contextual controls instead of crowding first use.
The desktop writes parsed scientific signals and structural record series automatically,
so exact YoungIn 9.0 and 9.1 PRMs need no extra control beyond the ordinary four steps. The
CLI/API keep their explicit --include-signals / include_signals=True contract.
For repeated work, choose an optional local Saved setup, then use the same four steps.
After a successful conversion, Save this setup for reuse… asks only for a name. The same
action is available before conversion as Save current setup…. Confirming more than one
generic table layout automatically collects those mappings into one setup; ordinary GUI users
do not need to create a Mapping Set or locate JSON files. Manage… provides rename,
duplicate, delete, and advanced import/export portability. Saved setups use the operating
system's application configuration location, remain local, and are never applied without a
fresh Preflight review. They may contain private column labels or user metadata, but never
measured rows or source/output paths. CLI/API users retain the strict ConversionRecipe JSON
contract and --recipe workflow.
The interface is offline-only: it has no upload, cloud, telemetry, embedded browser,
or vendor-executable integration. It does not silently replace an existing workbook.
Add buttons, visible labels, keyboard focus order, and accessible names provide a
keyboard path equivalent to drag and drop. Forced cancellation is intentionally
omitted until the public core can preserve workbook transaction safety during
cancellation. Issue #6 now has a maintainer-only unsigned standalone prototype,
documented in the standalone runbook. No .exe or .app is
publicly released: publisher identity, signing, notarization, LGPL
replacement/relinking evidence and the final redistribution gate remain blocked. The
Python-package interface above is the supported installation path.
Verified formats
| Built-in format | Metadata | Peaks | Signals | Status | Synthetic fixture |
|---|---|---|---|---|---|
| Generic comma-delimited CSV | Yes | Explicit columns | Explicit time + signal rows |
Verified | Yes |
| Generic tab-delimited TSV | Yes | Explicit columns | Explicit time + signal rows |
Verified | Yes |
| Generic semicolon-delimited TXT | Yes | Explicit columns | Explicit time + signal rows |
Verified | Yes |
| Generic non-macro XLSX table | Yes | Explicit columns | Explicit time + signal rows |
Verified | Yes |
“Generic” means the first row uses the documented column
schema. It does not mean arbitrary vendor exports.
An extension is supporting evidence only; Ordifile also checks content and schema.
Run ordifile formats to see the adapters installed in the current environment.
Selected public real-data validation
Selected narrowly bounded Experimental adapters have been exercised against checksum-pinned public research datasets and external fixtures. The validation checks exact detection/parsing boundaries, measured fields and units, canonical records, and workbook round trips; it is not broad vendor conformance. Sources, DOI/URLs, licenses, checksums, exact files, access dates, and excluded or conditional candidates are recorded in the public source register. External source files are not silently bundled into the package, and each format page separates fixture-backed capability from unsupported versions or workflows.
Map an unsupported peak table explicitly
If a structured CSV, TSV, semicolon-TXT, or audited XLSX Result table has explicit RT and Area columns but no exact-profile adapter, choose those columns with Map Peak Columns in the desktop interface or reuse a mapping JSON in the CLI:
ordifile convert run001.csv run002.csv --peak-mapping peak-map.json -o results.xlsx
ordifile convert input/ --recursive --peak-mapping-set lab-mappings.json -o results.xlsx
The mapping must classify every header, declare the RT unit, and confirm the Area-unit
state. Ordifile preserves source row order and uses the same PeakRecord → Peaks →
ordered-matrix → workbook path as built-in Result adapters. It does not infer RT, Area,
units, compounds, or vendors. Manufacturer/software values are user-supplied provenance,
not verified compatibility, and this workflow does not add a vendor to the support table.
Mapping Sets reuse several user-approved templates by exact format/header structure in one
batch; zero or multiple matches fail rather than falling back. See the
explicit mapping contract.
If the local preview does not show the actual peak table, open Table Options to select a
bounded text encoding, header record, or visible worksheet. These settings are stored with the
Mapping/Profile and can be reused through a named Recipe; they never infer scientific roles.
When a saved structure drifts, bounded diagnostics explain fixed structural differences but
never apply a candidate. Desktop review can create a new user-confirmed profile while keeping
the original template available.
Review a conversion before writing it
Use the same conversion options with --dry-run to build a deterministic, route-only
preflight. It reports exact adapters, user mappings, generic routes, drift, ambiguity,
unsupported inputs, duplicates, and the current primary-output conflict state without
creating a workbook, sidecar, temporary file, or PeakRecord:
ordifile convert input/ --recursive --peak-mapping-set lab-mappings.json \
  --output results.xlsx --dry-run
The in-memory Python ConversionPlan is an immutable same-process snapshot. It stores
content SHA-256 identities and fixed routing decisions, but no scientific rows or public
absolute paths. convert_plan(plan) repeats discovery and routing and rejects a stale
source set, source content, adapter inventory, configuration, or output state before using
the existing converter. This is bounded TOCTOU hardening, not a claim that filesystem state
can never change. Requested scientific sorting and workbook/sidecar capacity remain
explicitly deferred until parsing and export planning; dry-run does not predict peak counts
or future write permission. Mapping-profile matching is header-only. Exact-adapter ownership
probes may decode and validate bounded source structures, including numeric row syntax, but
preflight does not construct, store, or export canonical scientific rows. Source hashes may
change when measurement bytes change. The public plan-summary SHA-256 covers only the
privacy-safe projection, not private path/config bindings or authentication. Executable plans
require a new output target; explicit overwrite remains available only through direct
conversion. On POSIX, output directories that are group/world-writable without the sticky
bit are rejected because another user could exchange private transaction entries. Processes
running as the same operating-system user remain inside the local trust boundary.
from ordifile.api import convert_plan, plan_conversion

plan = plan_conversion("input", "results.xlsx")
if plan.is_executable:
    result = convert_plan(plan)
Reuse a laboratory conversion recipe
A ConversionRecipe stores how to convert, not which scientific files to convert.
It is strict, bounded UTF-8 JSON containing stable discovery, routing, sorting, signal,
failure, sidecar, and optional embedded Mapping/Mapping Set settings. Inputs, output paths,
overwrite authorization, source identities, plans, and scientific rows are never stored.
Schema v1 allows at most 8 MiB; embedded Mapping Sets retain their existing 4 MiB and
32-profile limits. Unknown, duplicate, or malformed fields are rejected.
ordifile convert new-experiment/ --recipe laboratory-recipe.json \
  --output results.xlsx --dry-run
ordifile convert new-experiment/ --recipe laboratory-recipe.json \
  --output results.xlsx
Recipe conversion always builds and revalidates the existing ConversionPlan; it cannot
bypass exact-adapter precedence, exact Mapping Profile matching, drift diagnostics, or
ambiguity failures. Runtime inputs and output are required separately. To keep the effective
configuration deterministic, a stored adapter is considered only when no exact-profile adapter
owns the input. --recipe cannot be combined with separate behavior options such
as --recursive, --sort, --adapter, --sheet, or mapping flags. --dry-run and
--verbose remain runtime presentation choices. A Recipe never carries overwrite authority.
Embedded mappings may contain exact headers, worksheet titles, units, local labels, and user-provided manufacturer/software declarations. Treat Recipe JSON as privacy-bearing local configuration and do not attach it to public issues. Its exact semantic SHA-256 is local-only. Recipe-specific Plan and workbook provenance is limited to the Recipe schema and privacy-safe public fingerprint. Existing scientific and public-safe Mapping Set provenance keeps its established workbook contract. A direct single-Mapping semantic digest remains direct-only and is not recorded for a Recipe-embedded Mapping. Neither Recipe digest proves vendor support or predicts workbook bytes.
from ordifile import ConversionRecipe, save_conversion_recipe
from ordifile.api import convert_plan, plan_recipe
from ordifile.core.models import SortMode

recipe = ConversionRecipe(sort=SortMode.INPUT_ORDER)
save_conversion_recipe(recipe, "laboratory-recipe.json")
plan = plan_recipe("new-experiment", "results.xlsx", recipe=recipe)
if plan.is_executable:
    result = convert_plan(plan)
Experimental proprietary adapters
| Format boundary | Metadata | Peaks | Output | Status | Real fixture |
|---|---|---|---|---|---|
Agilent ChemStation .CH internal version 181, exact GC-FID profile |
Field-specific | No | All structural decoded records | Experimental | One external BSEE file |
Agilent ChemStation Result XML, exact C.01.10 [201] single FID1/A Percent/Area profile |
Scientific allowlist | ResultsGroup peaks | RT (min) + area (pA*s) + height (pA); no raw signal | Experimental | One external CeCILL-2.1 fixture |
Shimadzu LabSolutions 5.82 .GCD, GC-2014 / single SFID1 profile |
Field-specific | No | Retention time (min) + signal (uV) | Experimental | One external CC0-declared file + paired same-run ASCII reference |
Shimadzu LabSolutions result ASCII, exact 5.82 GC-2014 / single SFID1 Ch1 profile |
Scientific allowlist | Peak Table rows | RT/start/end (min) + area + height (units unresolved); no raw signal | Experimental | One external controlled-CI fixture + paired same-run GCD |
Shimadzu GCMSsolution .QGD, exact 4.00 TIC profile |
Field-specific | No | Retention time (min) + raw TIC (unit unknown); MS1 not exported | Experimental | One external Dryad CC0 file |
YoungIn YL-Clarity .PRM, validated scientific family |
Scientific fingerprint | No | Retention time (min) + direct stored response; 9.0 FID/TCD mV, 9.1 FID pA/TCD mV, compatible 9.x response unit may be unresolved | Experimental | 28 owner PRMs plus 15 same-run full-curve pairs across validated 9.0/9.1 profiles |
YoungIn YL-Clarity Result Table, exact owner-validated CP949/tab .csv profile |
Scientific allowlist | Source peak rows | RT (min) + area (mV.s) + height (mV); no raw signal | Experimental | Two owner-generated local-only exports |
| LECO ChromaTOF 4.72.0.0 GCxGC Result text, exact observed profile | Scientific allowlist | Source peak rows | RT1/RT2 (s) + area/height (AU); no raw signal | Experimental | One external Dryad CC0 non-human file |
These Experimental adapters have the bounded capability rules below. A compatible YL-Clarity family file may expose a narrower capability than an individually validated profile; incompatible structures are rejected rather than guessed.
The Agilent .CH adapter retains every
decoded record in source order. Its x values are decoded_record_index, not retention
time; its y values are decoded_raw_integer, not physically scaled intensity. Units,
scientific point count, and the final record's role remain unresolved. It does not
claim other .CH versions, .D directories, TCD, MS, peaks, calibrated values, or
write support. See the exact capability and safety boundary.
The separate Agilent Result XML adapter reads one exact ChemStation
C.01.10 [201], single FID1/A, Percent/Area report profile without requiring a
raw sibling. It maps the canonical ResultsGroup/Peak rows to source-order peaks,
retains explicit min, pA*s and pA units, and checks every RT/area/height decimal string
against its duplicate integration row. Peak boundaries are preserved, calibrated
nonblank Name values map to compound, and source labels FID1/A map separately
to canonical detector/channel FID/FID1A. Other revisions, multiple signals,
detectors, quantitation modes, raw chromatograms and write support are rejected or
unsupported. The external fixture remains controlled-CI only because it includes
privacy-bearing run metadata. See the exact capability and safety boundary.
The Shimadzu adapter is limited to an exact LabSolutions 5.82, GC-2014,
single-channel SFID1, uV, identity-factor profile. Its 66,255-point retention-time
and signal series were compared point by point with a same-run LabSolutions ASCII
reference. It does not claim other LabSolutions or GCsolution versions, detectors,
channels, factors, GCD profiles, peaks, .QGD, .LCD, or write support. See the
exact capability and safety boundary.
The separate Shimadzu result ASCII adapter reads one exact LabSolutions 5.82,
GC-2014, single SFID1 / Ch1 export without requiring a raw sibling. It preserves
all source Peak# values and independent source observation order, maps R.Time,
I.Time, and F.Time to retention/start/end time in minutes, and retains area and
height without inventing physical units. The exact fixture has no compound IDs or
names, so no compound identity is emitted. Its embedded private metadata is omitted
and its public source is a SHA-256 alias. Other software versions, instruments,
detectors, channels, identified-compound tables, multiple peak sections and arbitrary
LabSolutions text exports are unsupported. See the
exact capability and safety boundary.
The separate QGD adapter is limited to one exact GCMSsolution 4.00 compound-file
profile. It preserves all 16,800 TIC integers and the verified millisecond-derived
retention-time axis. The physical TIC unit is unknown. MS1 blocks are checked for
bounded scan structure and exact TIC-sum agreement, but spectra are not exported and
encoded mass values are not called m/z. It does not claim other QGD versions,
SIM/MRM, identifications, quantitation, or write support. See the
exact capability and safety boundary.
YoungIn PRM files contain chromatographic stored data. The adapter validates a common
scientific-layout fingerprint independently of producer provenance: bounded current blocks,
duplicate payloads, finite binary32 records, size equations, source-ordered stored labels,
and the validated DStep=1 / MinTicks=600 time metadata. Ten same-run 9.0 FID+TCD pairs
match all 263,520 time and response points; five 9.1 pairs match all 138,000. Both validated
profiles therefore use zero-origin i * DStep / MinTicks retention time in minutes and
identity numeric response. Physical response units remain profile-specific: exact
9.0.1.19 uses FID mV and TCD mV, while exact 9.1.0.76 uses FID pA and TCD mV.
A well-framed YL-Clarity 9.x file whose full scientific fingerprint matches can be converted
as an Experimental compatible profile without claiming that producer version was individually
validated; its physical response unit remains unresolved unless evidence resolves it. If only
the structural safety fingerprint matches, Ordifile preserves decoded records without a time
or physical-response claim. Invalid framing, payloads, sizes, history, or channel structures
still fail closed. No YL-Clarity installation, vendor DLL, or temporary CSV is required at
runtime. PRM never produces peaks, Area, or Height, and Ordifile does not integrate the curve
or run peak detection. Runtime sample IDs are content-derived. This is not a claim that all
YL-Clarity versions are supported. Recovery .RAW, Autochro, and write support remain
unsupported. See the
exact capability and safety boundary.
The separate YoungIn Result adapter reads the exact CP949-compatible, tab-delimited
Result Table grammar established by two owner-generated exports. It preserves six
source rows with explicit RT (min), area (mV.s), height (mV), signal number/name and
source order without requiring PRM. One observed FID section explicitly has no peaks;
the two populated TCD sections remain independent channels. Signal Name is not
promoted to detector identity, W05 is not an integration boundary, and Total,
percentage and empty compound-table rows are not peaks. The bytes contain no OEM or
software-version marker, so broader YL-Clarity/Clarity CSV support is not claimed. See
the exact capability and safety boundary.
Five additional composite exports supplied the 9.1 scientific-curve oracle and 21
research-only Result rows. They are not accepted by the standalone Result adapter because
their composite grammar and displayed Total semantics differ from its exact profile.
The LECO adapter reads one exact ChromaTOF 4.72.0.0 GCxGC tab-delimited Result profile
established by a Dryad CC0 non-human model-mixture file. It preserves all 100 source
rows, explicit first- and second-dimension retention times in seconds, area and height
in documented arbitrary units (AU), source order, names, spectra text, width values,
and retention-index lexemes. Peak_Order_Matrix_2D keeps atomic RT1/RT2/area triples;
the existing one-dimensional matrix remains unchanged. Software version is external
dataset provenance rather than an embedded byte marker, detector/channel are not
invented, and spectra are not claimed as supported mass-spectral data. Broader LECO,
ChromaTOF, Sync, CSV, TXT, or GCxGC support is not claimed. See the
exact capability and safety boundary.
CLI
Inspect one file without writing output:
ordifile inspect sample.csv
ordifile inspect exported.xlsx --sheet PeakTable --verbose
Convert files or folders:
ordifile convert sample_1.csv sample_2.tsv --output Ordifile_Result.xlsx
ordifile convert ./exports --recursive --sort acquired_at --include-signals \
  --output Ordifile_Result.xlsx
ordifile convert ./exports --extension .csv --extension .xlsx \
  --sheet-mode sidecar-csv --output Ordifile_Result.xlsx
ordifile convert ./exports --recursive --output Ordifile_Result.xlsx --dry-run
ordifile convert ./exports --recipe laboratory-recipe.json \
  --output Ordifile_Result.xlsx --dry-run
Important behavior:
- existing output is not replaced unless
--overwriteis present; --dry-runperforms bounded routing/output preflight and creates no workbook or sidecar;- folder discovery is non-recursive unless
--recursiveis present; --on-error continuepreserves valid files and reports partial success;--on-error stopstops after the first file failure and writes no workbook;--adapterforces one installed adapter;--sheetselects one XLSX worksheet;--peak-mapping FILE.jsonapplies one strict, local, user-confirmed mapping to matching generic tables in the batch;--peak-mapping-set FILE.jsonroutes mixed generic templates with reusable exact- structure profiles; it is mutually exclusive with--adapterand--peak-mapping;--recipe FILE.jsonloads one self-contained local configuration and always uses preflight; input/output remain runtime values and separate behavior flags are rejected;- signals are parsed when present but written only with
--include-signals; --verboseadds detection evidence and detailed structured diagnostics.
Exit codes are stable for automation:
| Code | Meaning |
|---|---|
| 0 | Workbook created with no failure, or dry-run is ready |
| 1 | Fatal/blocked result or no successful input |
| 2 | Usage or configuration error |
| 3 | Valid workbook created with failures, or dry-run has known partial failures |
| 130 | Interrupted |
Sorting
--sort auto uses acquisition time only when every successful file has a reliable,
timezone-aware timestamp. Otherwise it uses a complete sequence number, then natural
filename order. Explicit modes are acquired_at, sequence, filename, and
input_order. Missing or unreliable values receive a recorded filename fallback.
The effective mode, requested mode, reason, and per-file sort key are written to the workbook.
Workbook layout
| Sheet | Contents |
|---|---|
Manifest |
Version, UTC generation time, counts, options, sorting, limits, warnings, and sidecars |
Samples |
One row per discovered input, status, public source reference (relative path by default or core hash alias), adapter facts, peak count, and SHA-256 |
Peak_Matrix |
One row per sample only for explicit compound names; duplicate peaks remain separate |
Peak_Order_Matrix |
Conditional source-order RT/area pairs with sample, source, manufacturer, detector, channel and units; pairs split atomically before Excel limits |
Peak_Order_Matrix_2D |
Conditional two-dimensional streams with atomic source-order RT1/RT2/area triples; existing 1D pairs are not redefined |
Peaks |
All explicit peaks in long form, including manufacturer and evidence-backed units/boundaries; secondary retention columns appear only for 2D data, without retention-time identity inference |
Metadata |
Unknown fields, invalid raw lexemes, and provenance without invented semantics |
Import_Log |
Every public source reference, success, warning, failure, duplicate, skipped artifact, sort key, and hash |
Signals_<channel> |
Original uninterpolated x/y values, only when requested and actually parsed |
Signals_Records_<channel> |
Experimental structural decoded records, explicitly not a retention-time signal |
The workbook keeps Manifest as the first audit tab but opens on Samples as the
researcher entry point. Headers use a fixed style, identity columns remain visible while
scrolling, relevant long-form sheets have filters, and widths come from bounded schema
rules rather than scanning private values. Scientific numeric cells retain Excel's
General display so presentation never rounds or normalizes RT, area, or height values.
The Manifest also records count-only sample/peak/series totals. Conversions executed from
a revalidated preflight record only the plan schema and public plan-summary SHA-256; the
plan itself is never embedded.
When a Conversion Recipe is used, Recipe-specific Manifest provenance adds only its schema
version and public-safe configuration fingerprint. Existing scientific and Mapping provenance
keeps its established contract, except that a Recipe-embedded single Mapping does not repeat
its private semantic digest. Manifest never embeds the Recipe JSON, local Recipe path or label,
exact local Recipe semantic digest, raw mapped headers, or raw Recipe worksheet title.
Rows and columns are split into deterministic numbered sheets before Excel limits are
reached. Data is never silently truncated. If workbook storage is impractical,
--sheet-mode sidecar-csv can create explicit CSV sidecars; the Manifest records each
relative path, row count, formula-escape count, and SHA-256.
Python API
The CLI calls the same public API intended for future interfaces:
from ordifile import summarize_conversion
from ordifile.api import convert, inspect_file, inspect_inputs, list_formats

inspection = inspect_file("sample.csv")
preview = inspect_inputs(["sample_1.csv", "sample_2.tsv"], sort="auto")
result = convert(
    ["sample_1.csv", "sample_2.tsv"],
    "Ordifile_Result.xlsx",
    sort="auto",
    include_signals=False,
)
completion = summarize_conversion(result)

print(preview.outcome, result.success_count, result.failure_count, result.sort.effective)
print(completion.converted_sources, completion.sample_records, completion.peak_records)
inspect_inputs() performs the same bounded discovery, detection, parsing, validation,
and sorting without writing an artifact. convert() intentionally reads and validates
the inputs again, and also accepts folders, recursion, extension filters, explicit
adapters and XLSX sheets, error policy, overwrite policy, CSV sidecars, and a
presentation-neutral progress callback.
summarize_conversion() returns the same frozen, count-only canonical completion summary
used by the Manifest, CLI, and desktop; it contains no source identifiers or scientific
values.
Add an adapter
External packages can register a typed adapter through the
ordifile.adapters Python entry-point group. Adapters detect and parse; they do not
write worksheets or duplicate CLI logic. A new format needs bounded detection, format
evidence, structured errors, a redistributable or synthetic fixture, capability-specific
tests, and license review.
Actual Result exports should follow the privacy-first fixture intake guide.
Start with Adding a format adapter. Installed third-party adapters execute Python code and must be treated as trusted software.
Good first contributions include an additional synthetic delimiter fixture, a clearer error-message test, a documentation translation, or a small adapter proposal backed by an openly redistributable fixture.
YoungIn Result export confirmed: two owner-generated YL-Clarity exports establish the exact Result Table RT/area/height grammar used by the Experimental standalone adapter. The maintainer bridge remains available for future local batch generation, but it is not a runtime or CI dependency. Native PRM inputs and actual exports remain local-only; public tests use independent synthetic values.
On a normally licensed Windows workstation, the one-command pilot-gated batch is:
py scripts/local/youngin_yl_clarity_export_bridge.py <prm-or-directory-or-zip> `
  --output <outside-git-or-ignored-local-output> --batch `
  [--executable <vendor-executable>]
If a future pilot reports that explicit RT and Area headers are absent, enable Result
Table, Table Headers, Text File, and preferably In Fixed Format once in
YL-Clarity's Export Data settings, then rerun the bridge. Do not add the vendor
application, generated exports, or native inputs to the repository.
The bridge rejects output inside a Git worktree unless it is below Ordifile's fixed
.external-fixtures, .research-downloads, or fixture-cache ignored roots.
Integrity and security boundaries
- Inputs are opened read-only, SHA-256 is recorded, and content is checked again after parsing.
- Symbolic links are rejected. Duplicate paths and hard links are recorded instead of parsed twice; equal content hashes alone are not deduplicated.
- One ordinary parse failure is isolated from other inputs. Successful data can still
produce a workbook and the failed file remains visible in
Import_Log. - Formula-like strings are written as literal text with formula and URL conversion disabled.
- Values that the verified XLSX writer/reader combination cannot represent exactly are rejected for that file instead of being silently changed.
- Generic source identities in XLSX audit cells use a reversible display encoder:
unsafe code points become
~uXXXXXX;and a literal~is doubled. Privacy-sensitive adapters can instead request a core-ownedsource-<full SHA-256>alias; this also applies to API/CLI/progress and malformed-file issues. Input paths, bytes and hashes remain unchanged. See the source identity policy. - CLI output renders terminal control and bidirectional-format characters as visible, single-line escapes while preserving normal Unicode and Windows paths.
- XLSX packages pass ZIP, relationship, Content-Type, XML namespace, coordinate, dimension, cell-type, and resource audits before openpyxl reads a selected sheet.
- Normal conversion is offline and does not upload instrument data.
Limits
- One input file represents one sample.
- Automatic generic delimited-text input is UTF-8 or UTF-8 with BOM. Explicit mapped intake can select UTF-8, CP949, or Windows-1252 and a bounded header record. Exact proprietary text adapters use only their documented fixture-backed encoding. Delimiters remain fixed per container; encoding and delimiter guessing are not supported.
- Extension filters are normalized to lowercase dotted ASCII before discovery. At most 32 unique filters are accepted; each has at most 32 ASCII characters after the leading dot, and the Manifest form is capped at 1,024 characters.
- Automatic generic ingestion uses only documented headers. Explicit peak mapping uses exact user-selected label-plus-position selectors. Units are copied, not converted.
- Compound identity is never inferred from retention time. RT-tolerance matching and duplicate-compound aggregation are not enabled.
- XLSX support is limited to an audited transitional, non-macro
.xlsxworkbook with explicit uppercase row and cell coordinates. Templates, macros, implicit coordinates, and other OOXML variants are rejected. - XLSX formula text is preserved, but cached formula results are never treated as measured values.
- Numeric Excel date-style cells have no timezone and remain unreliable for automatic
acquisition-time sorting. An OOXML
t="d"ISO timestamp is parsed from its audited raw lexeme; an explicit offset can make that timestamp reliable. - OOXML numeric lexemes must use ASCII sign, decimal, and exponent characters without whitespace. A cell type incompatible with its documented field is preserved as raw Metadata with a warning, not converted through Python stringification.
- Files at or above 256 MiB receive a warning; files above 2 GiB are hashed but not parsed. Delimited inputs and declared XLSX uncompressed content are capped at 512 MiB.
- The XLSX audit additionally caps 10,000 archive members, 8 MiB control XML parts,
250,000 physical rows, 1,000,000 physical cells, a 250,000 logical row, 5,000,000
projected cells, XML depth 128, and raw cell lexemes at 32,767 characters. Raw
formula text is capped at 32,766 because the exported literal includes a leading
=. - Canonical integers are limited to 1,000 decimal digits; integer source lexemes are limited to 4,096 characters. Excel numbers beyond 15 exact integer digits are written as literal strings and counted.
- Mandatory audit cells are limited to 32,767 characters. A file that cannot fit its
own
Samples/Import_Logidentity or issue summary is isolated before workbook planning; batch summaries are bounded and report omitted-code counts. - The practical workbook cap is 512 sheets and the conservative portable output-path cap is 218 Unicode code points.
- Proprietary readers are limited to the exact Experimental profiles above. The optional Experimental GUI exposes only those same registry capabilities and does not broaden format support.
These practical bounds are Ordifile safety policies, not claims about every valid Excel file. See the exact generic format contract and the architecture decision.
Related scientific tools
These are related independent repositories, not a fully integrated suite:
- Ordifile — this instrument-data conversion tool
- ReactorCheck — catalytic reactor metrics and QC
- TPxLab — temperature-programmed signal and peak analysis
- OperandoMerge — heterogeneous timeline alignment
Direct interoperability is planned only where public schemas and real workflow evidence justify it.
Development
Ordifile targets Python 3.11–3.14. The required quality, release-build, wheel-smoke, and
external real-fixture jobs target Python 3.14 on a shared Linux DGX self-hosted runner;
the same runner also executes the full test suite without coverage on Python 3.11–3.13.
TestPyPI/PyPI publishing, byte verification, attestations, and
GitHub Release publication use GitHub-hosted Ubuntu. Core CI has no Windows or macOS
matrix. The maintainer-triggered standalone prototype path targets Windows x86-64
through an exact-SHA reusable workflow called by the existing runner's same-owner
repository and uses GitHub-hosted macos-15 for macOS. The existing runner
registration and assignment remain unchanged. The persistent Windows job uses a
run-scoped environment, bounded pre/post cleanup, and checkout-independent artifact smoke. Neither platform
uploads native candidate binaries; only path-free evidence is retained. The standalone
workflow runs only an allowlisted same-repository branch whose selected SHA, required
reviewed commit, workflow SHA, and checkout all match. It has no GitHub-hosted Windows fallback.
Caller assignment, capability labels, and online state must be confirmed before
dispatch; the workflow is not authorized for a personal workstation.
Public-fork and bot-authored pull-request jobs are deliberately skipped and never run on
the shared Linux runner. Maintainers review an external or dependency change before
reproducing it on an owner-authored same-repository branch;
ordinary CI receives read-only repository permission without publishing secrets or OIDC
permission.
Runner availability is an operational setting visible in GitHub Actions; this describes
the configured target, not a guarantee that the runner is currently online.
python -m pip install -e ".[dev]"
ruff format --check .
ruff check .
mypy
pytest
python -m build
ordifile --help
pip-audit
See CONTRIBUTING.md, CITATION.cff, SECURITY.md, the release runbook, GC fixture research, external-fixture policy, and the evidence register. Do not attach proprietary raw files or fixtures without confirmed redistribution permission to a public issue.
Project name and trademarks
Ordifile was selected after a technical collision screen on 2026-08-16. No exact-name record was found in the checked GitHub and package-registry searches at that time, but search absence is not a reservation or legal trademark clearance. See the renaming research. Vendor names, if mentioned in future compatibility notes, remain the property of their owners and do not imply affiliation or endorsement.
Agilent, ChemStation, Shimadzu, LabSolutions, GCsolution, YOUNG IN Chromass, ChroZen, YL-Clarity, AUTOCHRO, and related product names are trademarks or product names of their respective owners. Ordifile is not affiliated with or endorsed by Agilent, Shimadzu, or YOUNG IN Chromass.
License
Ordifile is licensed under Apache License 2.0. See LICENSE, NOTICE, and THIRD_PARTY_NOTICES.md.
1 maintainer

Metadata
1 maintainer
Release files for ordifile 0.5.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ordifile-0.5.1.tar.gz | 1.3 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ordifile-0.5.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / ordifile-0.5.1.tar.gz
| Download URL | ordifile-0.5.1.tar.gz |
|---|---|
| Size | 1.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
02c0ed9cb3ef08ec7b40e13b6759bb597e091317eff23c1ae31a109e2ab50115
|
|
BLAKE2b-256 checksum How to use checksums |
37077c6522597bde0d893a968e00c275fb83c18076ec86e1c721bb19fa7b0ad9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 25, 2026.
Transparency logRelease files / ordifile-0.5.1-py3-none-any.whl
| Download URL | ordifile-0.5.1-py3-none-any.whl |
|---|---|
| Size | 282.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d593ca2e4542666a66842c93efb2b4c6b25c22747f1f033e7bf7ebbb36a785f2
|
|
BLAKE2b-256 checksum How to use checksums |
402d0c273056c95eb43ee6f00f555bf7fe40883b47bc0fd6aa0db034a62f61b8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 25, 2026.
Transparency log













