
pandas-term
pandas-term is a CLI bringing pandas operations to the command line.
Note: Still in early experimental development and may change
Installation
pipx install pandas-term
or
uv tool install pandas-term
Usage
All commands accept an input file path (or - for stdin) and support -o/--output for file output (default: stdout).
Command Reference
| Command | Pandas Equivalent | Description |
|---|---|---|
pd select |
df[columns] |
Select columns |
pd drop |
df.drop() |
Drop columns |
pd rename |
df.rename() |
Rename columns |
pd sort |
df.sort_values() |
Sort by columns |
pd dedup |
df.drop_duplicates() |
Remove duplicate rows |
pd duplicated |
df.duplicated() |
Identify duplicate rows |
pd merge |
pd.merge() |
Merge two dataframes |
pd concat |
pd.concat() |
Concatenate dataframes |
pd batch |
df.iloc[] |
Split into batches |
pd query |
df.query() |
Filter with query expr |
pd head |
df.head() |
First n rows |
pd tail |
df.tail() |
Last n rows |
pd dropna |
df.dropna() |
Drop rows with nulls |
pd describe |
df.describe() |
Descriptive statistics |
pd unique |
df[col].unique() |
Unique values in column |
pd shape |
df.shape |
Dimensions (rows, columns) |
pd columns |
df.columns |
Column names |
pd dtypes |
df.dtypes |
Column data types |
pd value-counts |
df.value_counts() |
Count unique values |
pd groupby |
df.groupby().agg() |
Group by and aggregate |
Transform
# Select columns
pd select name,price data.csv

# Drop, sort & rename
pd drop unwanted_column data.csv
pd sort price data.csv --descending
pd rename "price:cost,name:product_name" data.csv

# Remove duplicates
pd dedup data.csv
pd dedup --subset category,aisle data.csv

# Merge two dataframes
pd merge left.csv right.csv --on id --how inner

# Concatenate files (supports glob patterns)
pd concat file1.csv file2.json
pd concat "data_*.csv"
pd concat "*"

# Split into batches (last repeats)
pd batch data.csv --sizes 10,20,50 -o "batch_{}.csv"
Filter
# Query expression
pd query "price > 4.5 and category == 'Fruit'" data.csv

# First/last N rows
pd head --n 100 data.csv
pd tail --n 50 data.csv

# Drop rows with nulls
pd dropna data.csv
pd dropna --subset "name,category" data.csv

# Identify duplicate rows
pd duplicated data.csv
pd duplicated --subset category data.csv
pd duplicated --keep last data.csv
Stats
pd describe data.csv
pd unique country data.csv
pd shape data.csv
pd columns data.csv
pd dtypes data.csv
Aggregate
# Count unique values
pd value-counts category data.csv
pd value-counts category,aisle data.csv --normalize

# Group by and aggregate
pd groupby category data.csv --col price --agg sum
pd groupby "category,ailse" data.csv --col price,stock --agg mean
Piping
All commands support piping through stdin/stdout. When piping, you can omit the input file argument (it defaults to stdin):
cat data.csv | pd query "stock > 30" | pd select name,category

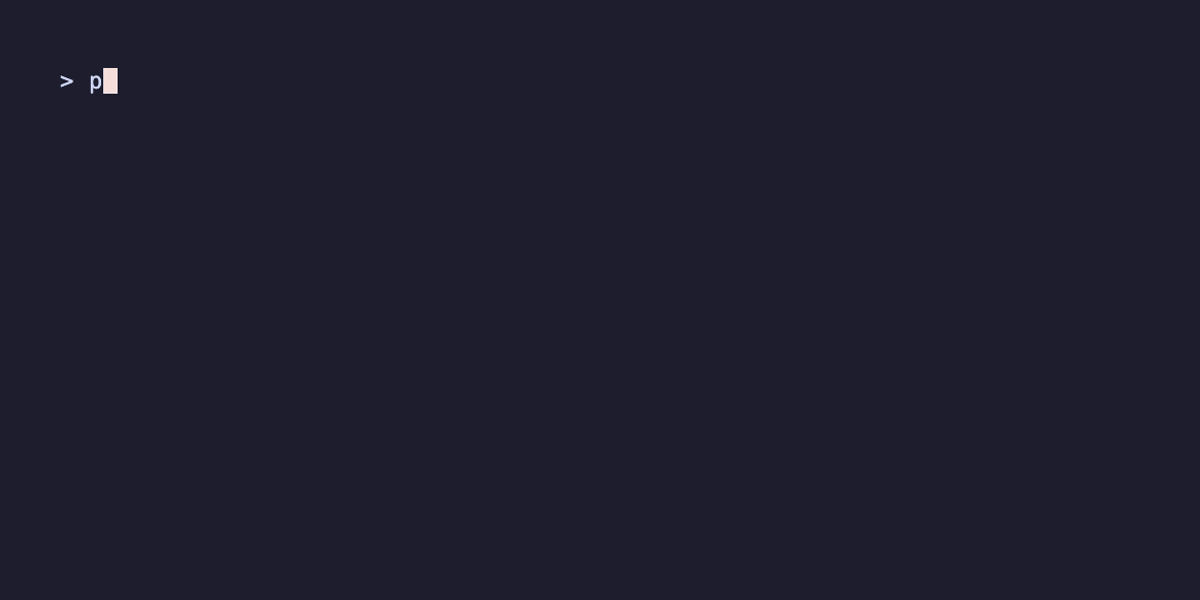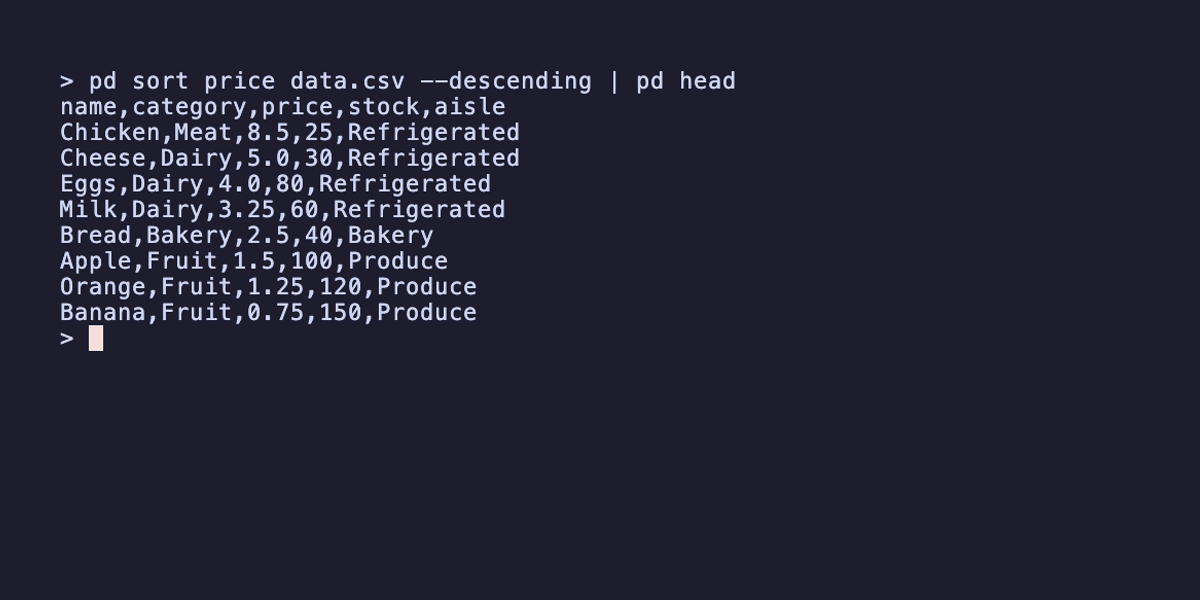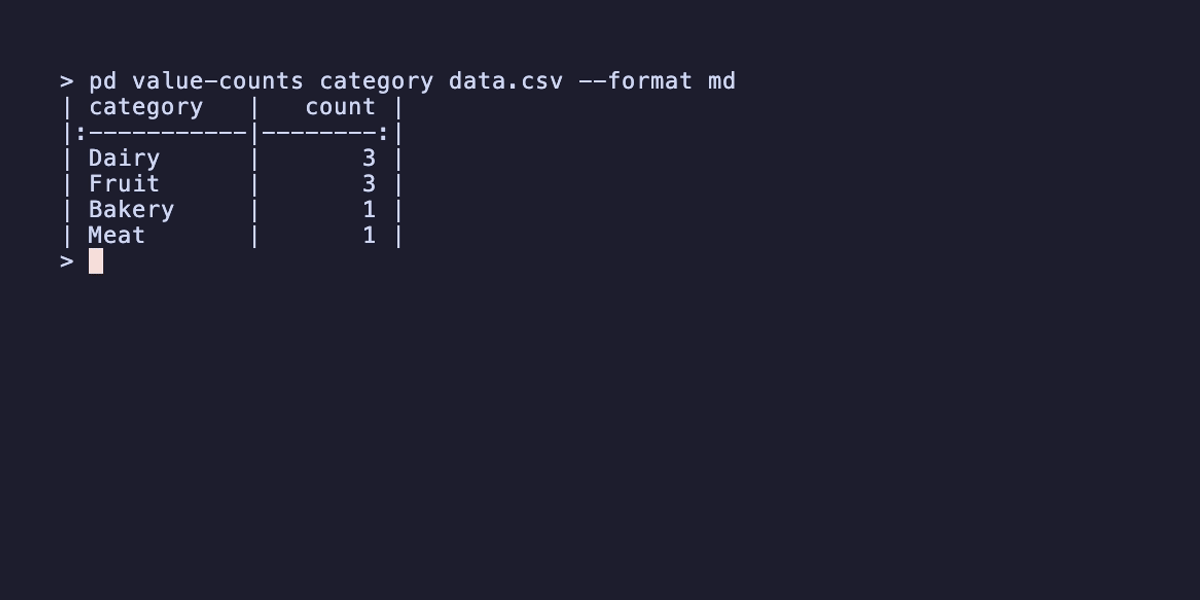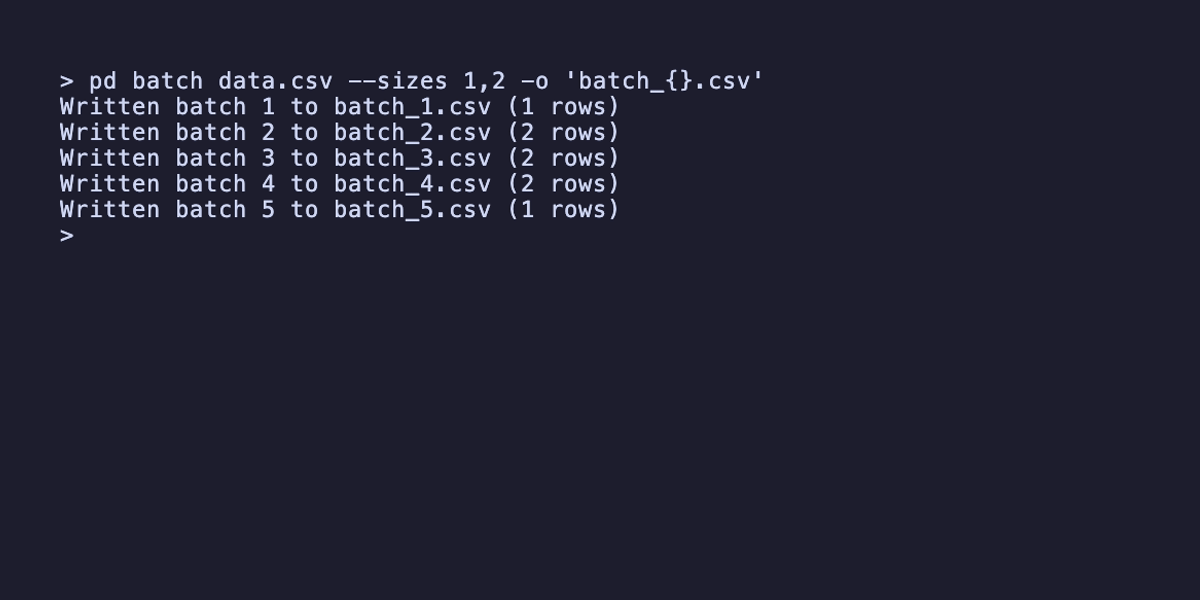
pd sort price data.csv --descending | pd head --n 10 | pd select name,category
Output Formats
Use -f/--format for stdout format (default: csv):
pd head --n 10 data.csv -f json
pd head --n 10 data.csv -f tsv
pd head --n 10 data.csv -f md
--json/-j is shorthand for -f json.
File output format is determined by extension:
pd select name,category data.csv -o output.xlsx
pd query "stock > 30" data.json -o filtered.parquet
Supported: csv, tsv, json, xlsx, parquet, md
For other extensions, use redirection: pd select name data.csv -f csv > output.txt
Dev setup
Requires uv
Install dependencies:
uv sync
| Command | Description |
|---|---|
make check |
Format, lint, and test |
make format |
Format code |
make lint |
Linting only |
make test |
Run tests |
make snapshots |
Regenerate test snapshots |
make coverage |
Tests with coverage |
make bump |
Bump version number |
make demo |
Regnerate demo gif from tape file |
1 maintainer

Metadata
1 maintainer
Release files for pandas-term 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pandas_term-0.1.2.tar.gz | 12.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pandas_term-0.1.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 26.4 kB
Release files / pandas_term-0.1.2.tar.gz
| Download URL | pandas_term-0.1.2.tar.gz |
|---|---|
| Size | 12.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8531a2f76b248f38b24559974a15bb5ad939c839321363ad8b6f5fe426566820
|
|
BLAKE2b-256 checksum How to use checksums |
3f04fc5276e8121e1041f17b836b853338efd530a7155b00be0c382834449d29
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Dec 27, 2025.
Transparency logRelease files / pandas_term-0.1.2-py3-none-any.whl
| Download URL | pandas_term-0.1.2-py3-none-any.whl |
|---|---|
| Size | 14.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4cc0fb01936d8dd8549930a3f2846695df3c5bc431446bcb6878fe5970bd3fe1
|
|
BLAKE2b-256 checksum How to use checksums |
033c1303a343cc9fb69be7f9cf4921f44f6b8f3ee4193a37b438e89ffaa318bf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Dec 27, 2025.
Transparency log













