
Local Privacy in Learning Analytics
This repository contains an adaptation of differential privacy algorithms applied to learning analytics.
Index
Project Description
Learning analytics involves collecting and analyzing data about learners to improve educational outcomes. However, this process raises concerns about the privacy of individual data. To address these concerns, this project implements differential privacy algorithms, which add controlled noise to data, ensuring individual privacy while maintaining the overall utility of the dataset. This approach aligns with recent advancements in safeguarding data privacy in learning analytics.
In this project, we explore two local differential privacy (LDP) algorithms designed for sketching with privacy considerations:
-
Single-User Dataset Algorithm: This algorithm is tailored for scenarios where data is collected from individual users. Each user's data is perturbed locally before aggregation, ensuring that their privacy is preserved without relying on a trusted central authority. Techniques such as randomized response and local perturbation are employed to achieve this.
-
Multi-User Dataset Algorithm: In situations involving data from multiple users, this algorithm aggregates the perturbed data to compute global statistics while preserving individual privacy. Methods like private sketching and frequency estimation are utilized to handle the complexities arising from multi-user data aggregation
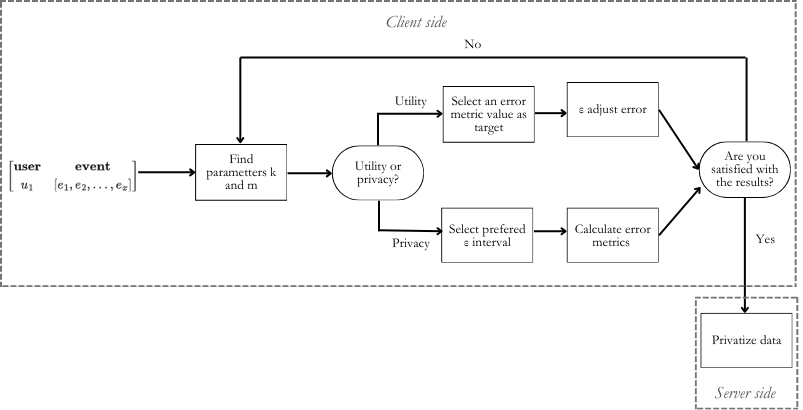
For the Single-User Dataset Algorithm, the next figure provides a high-level overview of the proposal workflow. At the end, an interest third party could ask the server a query over the frequency of certain events related to an individual. The estimation phase is simulated on the user side in order to adjust the ratio between privacy and utility before sending the information to the server. The algorithm first filters the information (Filter), then encodes the relevant events extracted (Data Processing) in order to be received for the PLDP-CSM method.
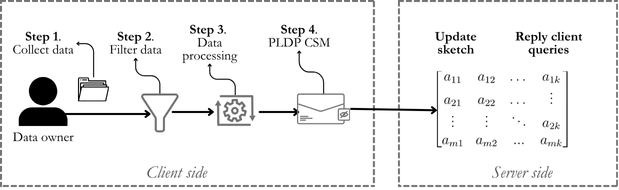
Then, the Cont Sketch based Personalized-LDP (PLDP-CSM) enables the adjustment of the relation between utility and privacy by iterating over data until the output of the simulator satisfies the constraints of users. This part of the algorithm produces the privatize dataset, which will be sent to the server.
Repository Structure
The repository is organized as follows:
Local_Privacy
┣ 📂 src
┣ ┣ 📂 privadjust
┃ ┃ ┣ 📂 count mean
┃ ┃ ┣ 📂 hadamard mean
┃ ┃ ┣ 📂 main
┃ ┃ ┃ ┣ individual_method.py # Single-user dataset algorithm
┃ ┃ ┃ ┗ general_method.py # Multi-user dataset algorithm
┃ ┃ ┣ 📂 scripts
┃ ┃ ┃ ┣ preprocess.py    # Data preprocessing routines
┃ ┃ ┃ ┗ parameter_fitting.py    # Parameter tuning for algorithms
┃ ┗ ┗ 📂 utils
┗ 📂 tests
Online Execution
You can execute the code online using Google Colab. Google Colab sessions are intended for individual users and have limitations such as session timeouts after periods of inactivity and maximum session durations.
-
For single-user dataset scenarios, click this link to execute the method: Execute in Google Colab (Single-User)
-
For multi-user dataset scenarios, click this link to execute the method: Execute in Google Colab (Multi-User)
Usage
These methods are included in PyPI as you can view here, and can be installed on your device with:
pip install privadjust
Once installed, you can execute the following commands to run the privacy adjustment methods.
For single-user dataset analysis:
To adjust the privacy of a single-user dataset, use the following command:
individualadjust <dataset> <output>
dataset: path to the input dataset (.xlsx) you want to privatize.output: path to where the privatized dataset will be saved.
Example:
individualadjust /path/to/dataset.xlsx /path/to/output
For multi-user dataset analysis:
To adjust the privacy of a multi-user dataset, use the following command:
generaladjust <dataset>
dataset: Path to the input dataset you want to privatize.
Important Notes
- Ensure that the paths provided are correct, and that the necessary permissions are granted for writing to the output location.
- In the single-user dataset analysis, the output will be a new file
.csvcontaining the privatized data.
Documentation
The complete documentation for this project is available online. You can access it at the following link:
This documentation includes detailed explanations of the algorithms, methods, and the overall structure of the project.
Authors
 Marta Jones 💻 |
 Anailys Hernandez 💡 |
1 maintainer

Metadata
1 maintainer
Release files for privadjust 1.0.13
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| privadjust-1.0.13.tar.gz | 11.3 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| privadjust-1.0.13-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 11.4 MB
Release files / privadjust-1.0.13.tar.gz
| Download URL | privadjust-1.0.13.tar.gz |
|---|---|
| Size | 11.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
bb67339df2e66918ecfbcb0e8bafda324d2312d647fed686c61dfc1b3759d05a
|
|
BLAKE2b-256 checksum How to use checksums |
770c3824f571cc44f06fe2a1b31cb46a5d74a8df106fb5d5f5f4ace7c398936e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.16
|
Release files / privadjust-1.0.13-py3-none-any.whl
| Download URL | privadjust-1.0.13-py3-none-any.whl |
|---|---|
| Size | 30.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
12c510ac2f40dc178d679c0f477ee0ecb619d74b4533f5b1a99c6f5305cdb79e
|
|
BLAKE2b-256 checksum How to use checksums |
fdf46124b0a659f25d2fd6bd8431a9d3f7e35fd0c7999d34b5f73e1ee7707ce0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.16
|














