
🔥 prompt-flamegraph
See where your LLM prompt tokens actually go.
Interactive flamegraphs · waste detection · prompt diffs — all local, zero-dependency.



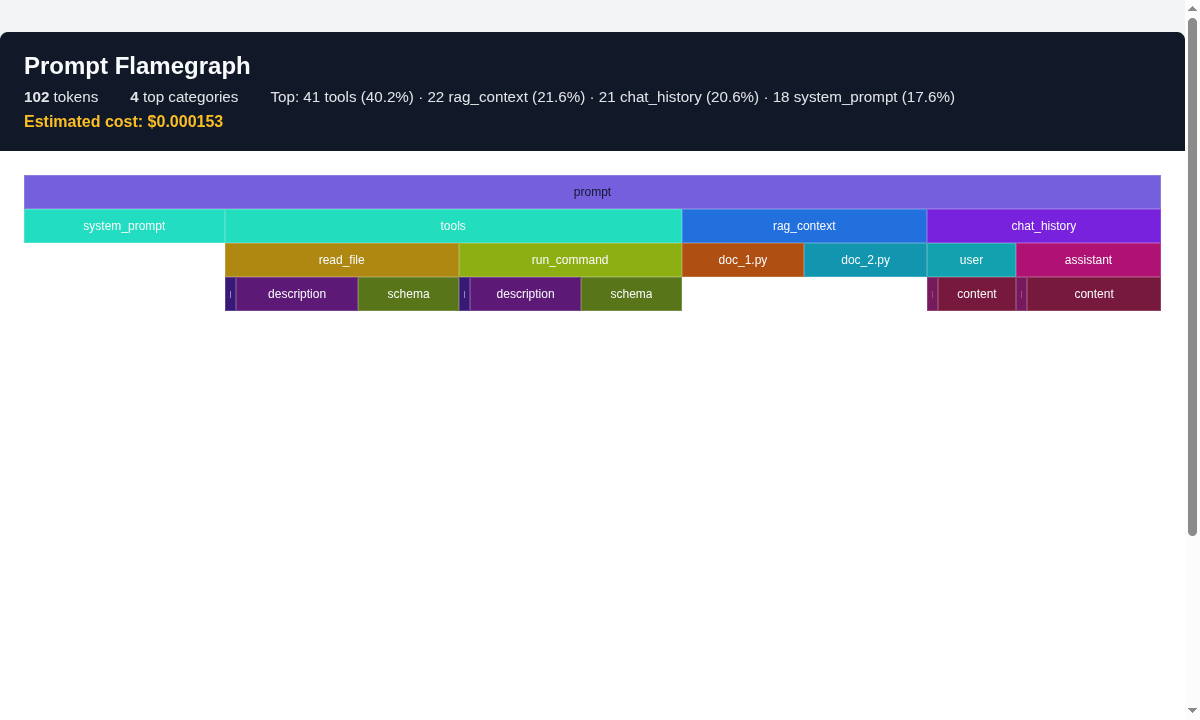
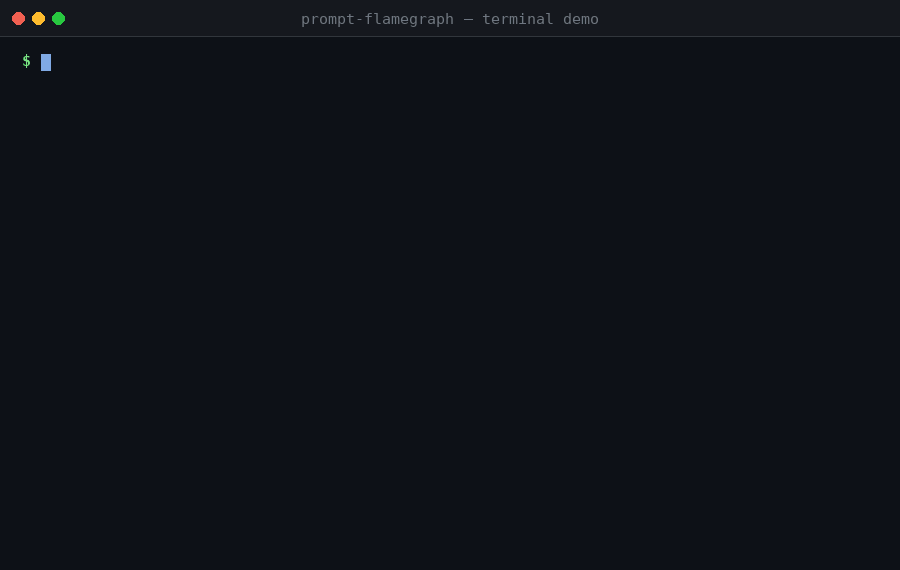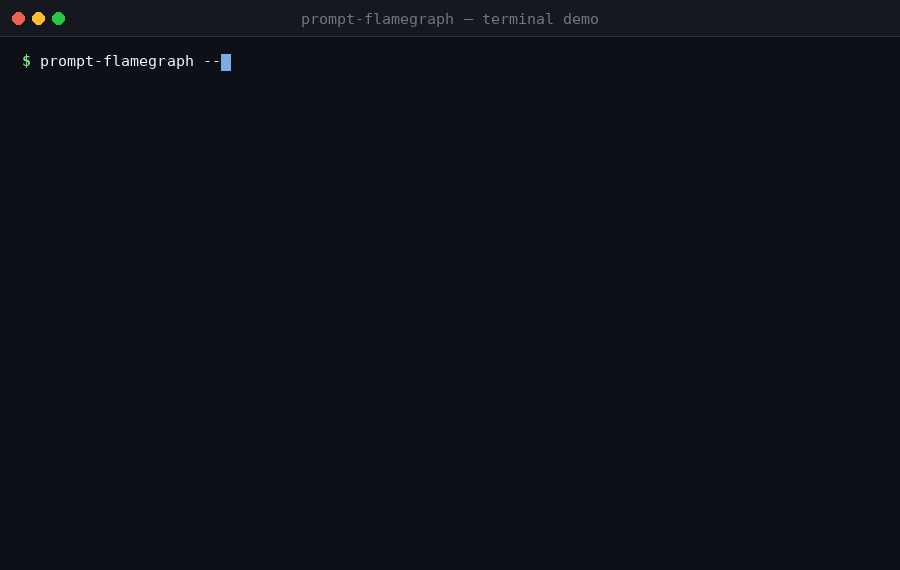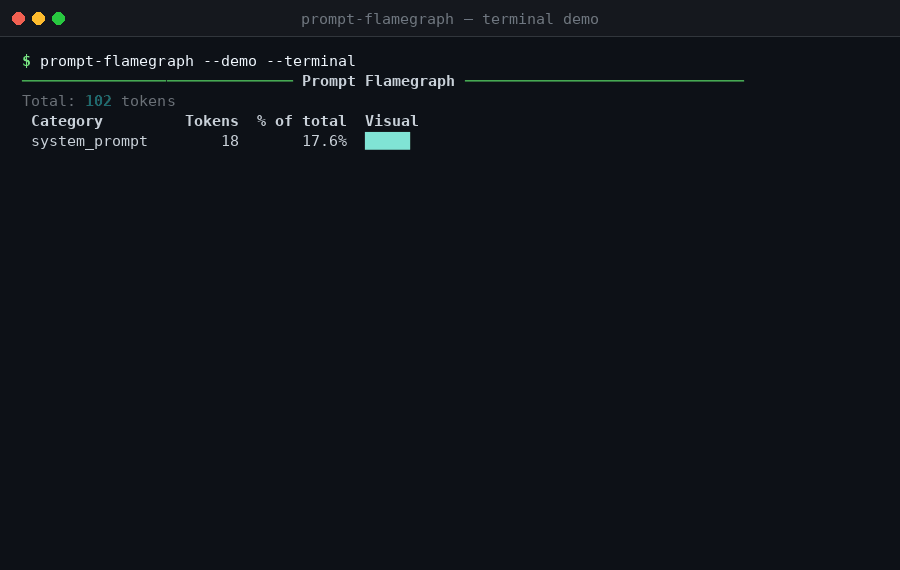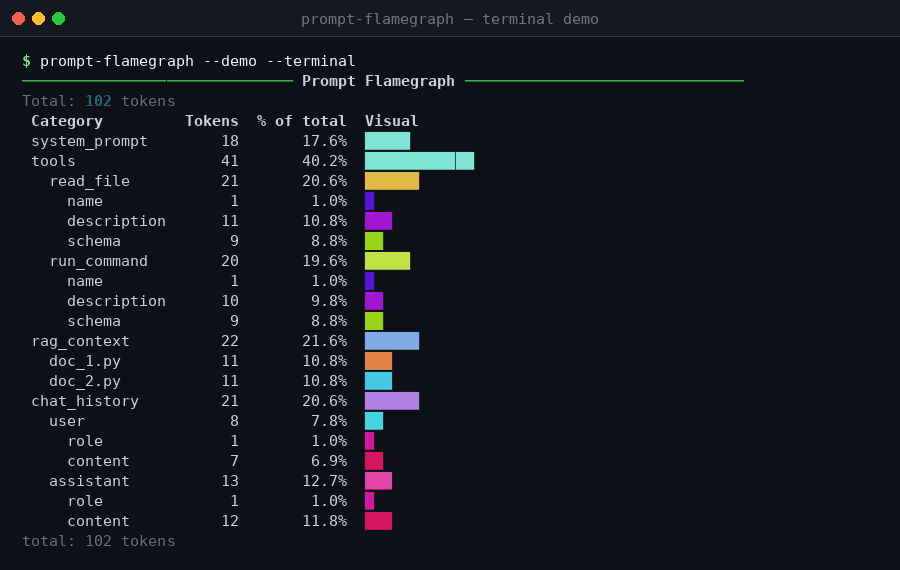
No proxy, no server, no dashboard, no telemetry — one function call, one output file. Feed it a structured prompt or a raw OpenAI/Anthropic payload and get an interactive flamegraph of your token usage, with waste findings and cost estimates.
Contents
- Install
- Quick start
- Works with your payloads
- CI budget gate
- Waste detection
- CLI
- Model pricing
- API
- Resources
Install
pip install prompt-flamegraph
| Extra | Why |
|---|---|
pip install prompt-flamegraph[tiktoken] |
accurate OpenAI-style token counts |
pip install prompt-flamegraph[rich] |
prettier terminal output |
Quick start
from prompt_flamegraph import profile_prompt

prompt = {
    "system_prompt": "You are a helpful coding assistant.",
    "tools": ["..."],
    "rag_context": {"doc_1": "..."},
    "chat_history": ["..."],
}

profile_prompt(prompt, output="context.html", model="gpt-4o")
Open context.html in your browser. Done.
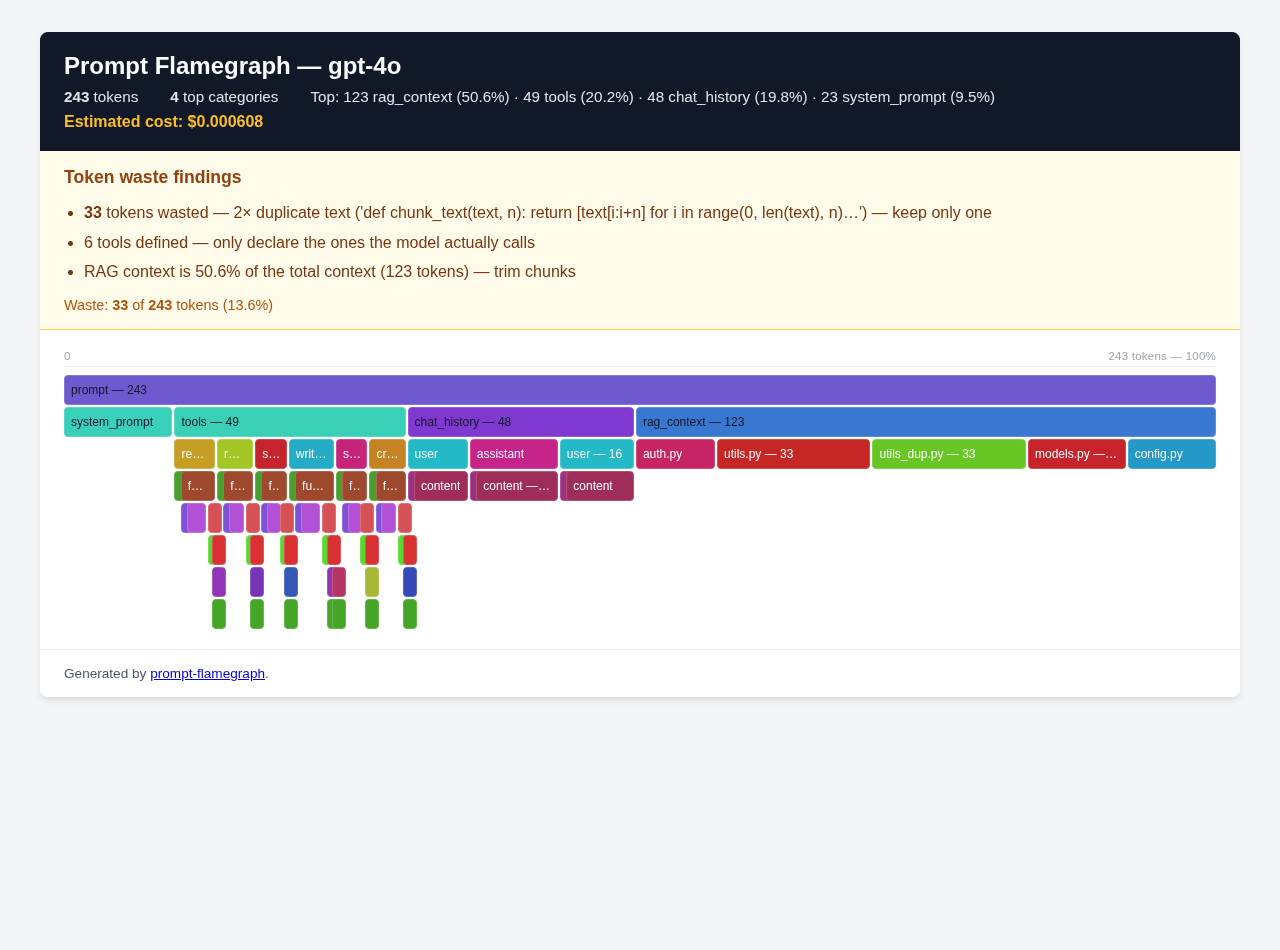
Reading the flamegraph — bar width = token share. Hover any bar (even a sub-pixel sliver) for its real name, token count and text. Nodes too thin to draw (<2% of their parent or <26px, or deeper than
max_depth=8) fold into striped· N more ·buckets; pass--no-aggregateon the CLI oraggregate=Falsetoto_html/to_svgto draw every node.
Works with your payloads
No restructuring needed — the CLI and normalize() auto-detect common shapes.
Raw OpenAI / Anthropic request bodies:
from prompt_flamegraph import normalize, profile_prompt

payload = {
    "system": "You are a helpful assistant.",
    "messages": [{"role": "user", "content": "Hello!"}],
}

profile_prompt(normalize(payload), output="context.html")
LangChain / LiteLLM objects — duck-typed, the framework is never imported:
from prompt_flamegraph import profile_any

# ChatPromptValue, rendered templates, BaseMessage lists...
profile_any(chat_prompt_value, output="context.html", model="gpt-4o")
CI budget gate
Fail a pipeline when a prompt outgrows its token budget — exit code 3 when exceeded, report still written:
prompt-flamegraph prompt.json --budget 100000 --format json -o report.json
Copy-paste GitHub Actions workflow: .github/workflows/prompt-budget.yml.example.
Waste detection
Find token waste before paying for it — duplicates, near-duplicates, oversized RAG, long histories, too many tools, context-window pressure:
from prompt_flamegraph import build_tree, detect_waste

tree = build_tree(prompt)
report = detect_waste(tree)

for finding in report.findings:
    print(f"- {finding.kind}: {finding.message}")
- duplicate: 3× duplicate text ("def helper(): …") — keep only one
- duplicate: 10× duplicate text ('Hi!') — keep only one
- too_many_tools: 6 tools defined — only declare the ones the model actually calls
- long_history: chat history is 33.3% of the total context — consider truncation
Findings are also embedded in the HTML report (detect_waste=True by default).
CLI
prompt-flamegraph prompt.json -o context.html        # HTML flamegraph
prompt-flamegraph prompt.json --terminal            # terminal bar chart
prompt-flamegraph v1.json --diff v2.json -o d.html  # diff (green/red/orange)
prompt-flamegraph prompt.json --format svg|md|json  # other exports
prompt-flamegraph prompt.json --model gpt-4o        # tokenizer + price + window
prompt-flamegraph prompt.json --no-aggregate        # draw every single node
prompt-flamegraph prompt.json --budget 100000       # CI gate (exit 3 if over)
prompt-flamegraph --list-models                     # supported models
prompt-flamegraph --demo                            # try it instantly
cat openai_request.json | prompt-flamegraph -       # stdin works too
Terminal output
────────────────────────────── Prompt Flamegraph ───────────────────────────────
Total: 102 tokens
 Category         Tokens  % of total  Visual
 system_prompt        18       17.6%  █████
 tools                41       40.2%  ████████████
   read_file          21       20.6%  ██████
   run_command        20       19.6%  █████
 rag_context          22       21.6%  ██████
   doc_1.py           11       10.8%  ███
   doc_2.py           11       10.8%  ███
 chat_history         21       20.6%  ██████
   …                  (nested rows truncated)
Without aggregation (--no-aggregate) — every sliver drawn, hover still shows each one's real name and tokens:
Model pricing
--model prices and context windows ship as a bundled snapshot — everything works offline. To refresh, fetch LiteLLM's crowd-updated pricing table into your user cache ($XDG_CACHE_HOME/prompt-flamegraph/models.json):
prompt-flamegraph --update-models
The cache extends --model/--list-models to hundreds of models — bundled entries win on conflicts, --list-models shows cache age. Normal runs never touch the network; only --update-models does. Use --offline or PROMPT_FLAMEGRAPH_OFFLINE=1 for bundled-only mode.
Prices — bundled and cached — are community-sourced estimates (LiteLLM's table), not official provider quotes. Check your provider's pricing page for billing-grade numbers.
Features at a glance
| 🪶 Zero dependencies | pure stdlib; tiktoken/rich optional |
| 📊 5 output formats | HTML · SVG · Markdown · JSON · terminal |
| 🔍 Waste detection | duplicates, near-dups, oversized RAG, long history, tool bloat |
| 🆚 Prompt diffs | before/after comparison with color-coded changes |
| 🔌 Payload adapters | OpenAI, Anthropic, LangChain, LiteLLM — no imports needed |
| 💰 Live pricing | bundled snapshot + LiteLLM refresh + offline mode |
| 🚦 CI gate | --budget N exits 3 when the prompt is too big |
| 🎛️ Pluggable tokenizers | tiktoken encodings, words, or any str -> int callable |
API
from prompt_flamegraph import (
    profile_prompt,   # dict → HTML flamegraph file
    profile_any,      # any payload/framework object → flamegraph
    normalize,        # OpenAI/Anthropic payload → structured dict
    from_messages,    # message list → structured dict
    from_langchain,   # LangChain-style object → structured dict
    build_tree,       # → internal Node tree
    detect_waste,     # tree → WasteReport
    diff_prompts,     # two prompts → diff HTML
    to_html, to_svg, to_markdown, to_json,  # tree → string
    resolve_model, list_models,             # model registry
    count_tokens, get_tokenizer,            # tokenizer utilities
)
Full signatures
profile_prompt(data, output="prompt_flamegraph.html", title=None,
               tokenizer=None, model=None, cost_per_token=None,
               detect_waste=True, context_window=None,
               width=1200, height=720)

# model= auto-derives tokenizer, pricing and context window
# (mutually exclusive with tokenizer=; falls back to the
# estimator with a warning when the encoding needs tiktoken)

build_tree(data, name="prompt", tokenizer=None, model=None)
detect_waste(tree, context_window=None)
diff_prompts(v1, v2, output="prompt_diff.html", ...)

to_html(tree, title="Prompt Flamegraph", cost_per_token=None, waste_report=None,
        width=1200, height=720, max_depth=8, aggregate=True)
to_svg(tree, title="Prompt Flamegraph", width=1200, row_height=34, max_depth=8,
       aggregate=True)
to_markdown(tree, title="Prompt Flamegraph", cost_per_token=None)
to_json(tree, title="Prompt Flamegraph", cost_per_token=None, waste_report=None)

profile_any(obj, output=None, model=None, **profile_kwargs)
from_messages(messages, tools=None, system_prompt=None)
# roles "system"/"developer" merge into system_prompt

normalize(data)   # extra top-level keys preserved; "model" dropped
Resources
- 🌐 Website / docs — https://fjjjuv.github.io/prompt-flamegraph/index.html
- 📦 PyPI — https://pypi.org/project/prompt-flamegraph/
- ✍️ Dev.to walkthrough — Stop Guessing Where Your LLM Prompt Tokens Go
Source
https://github.com/fjjjuv/prompt-flamegraph
License
LGPL-3.0-or-later — free to import into proprietary code; modifications to the library itself stay open. See LICENSE (full GPLv3 it builds on: LICENSE.GPL).
1 maintainer

Metadata
1 maintainer
Release files for prompt-flamegraph 0.3.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| prompt_flamegraph-0.3.3.tar.gz | 78.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| prompt_flamegraph-0.3.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 141.9 kB
Release files / prompt_flamegraph-0.3.3.tar.gz
| Download URL | prompt_flamegraph-0.3.3.tar.gz |
|---|---|
| Size | 78.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
befcf6a183a33c32e470bd65848b04fa04ea73194921d340b343db29590af1a0
|
|
BLAKE2b-256 checksum How to use checksums |
48506a7c0808ed0fc164a3df52f0a075d0266d5dd30a0102459970324aa93883
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.6
|
Release files / prompt_flamegraph-0.3.3-py3-none-any.whl
| Download URL | prompt_flamegraph-0.3.3-py3-none-any.whl |
|---|---|
| Size | 63.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5ce0ea737cf055bc4ad6d4f72374a3eeffc2d93bf3c9b5ebeda88e04814dcb84
|
|
BLAKE2b-256 checksum How to use checksums |
e2298e5304dbf89cd07ed8107e64c775d3473b1b82cb48ee1b25f60e2a0b9612
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.6
|














