
tokensaver
Find out what your prompt costs on every major AI model, and exactly which changes make it cheaper.


Most token counters stop at a number. tokensaver tells you what to change: every suggestion comes with a reason, the tokens it saves, and what that is worth in dollars. It runs 100% offline. Your prompt never leaves your machine.
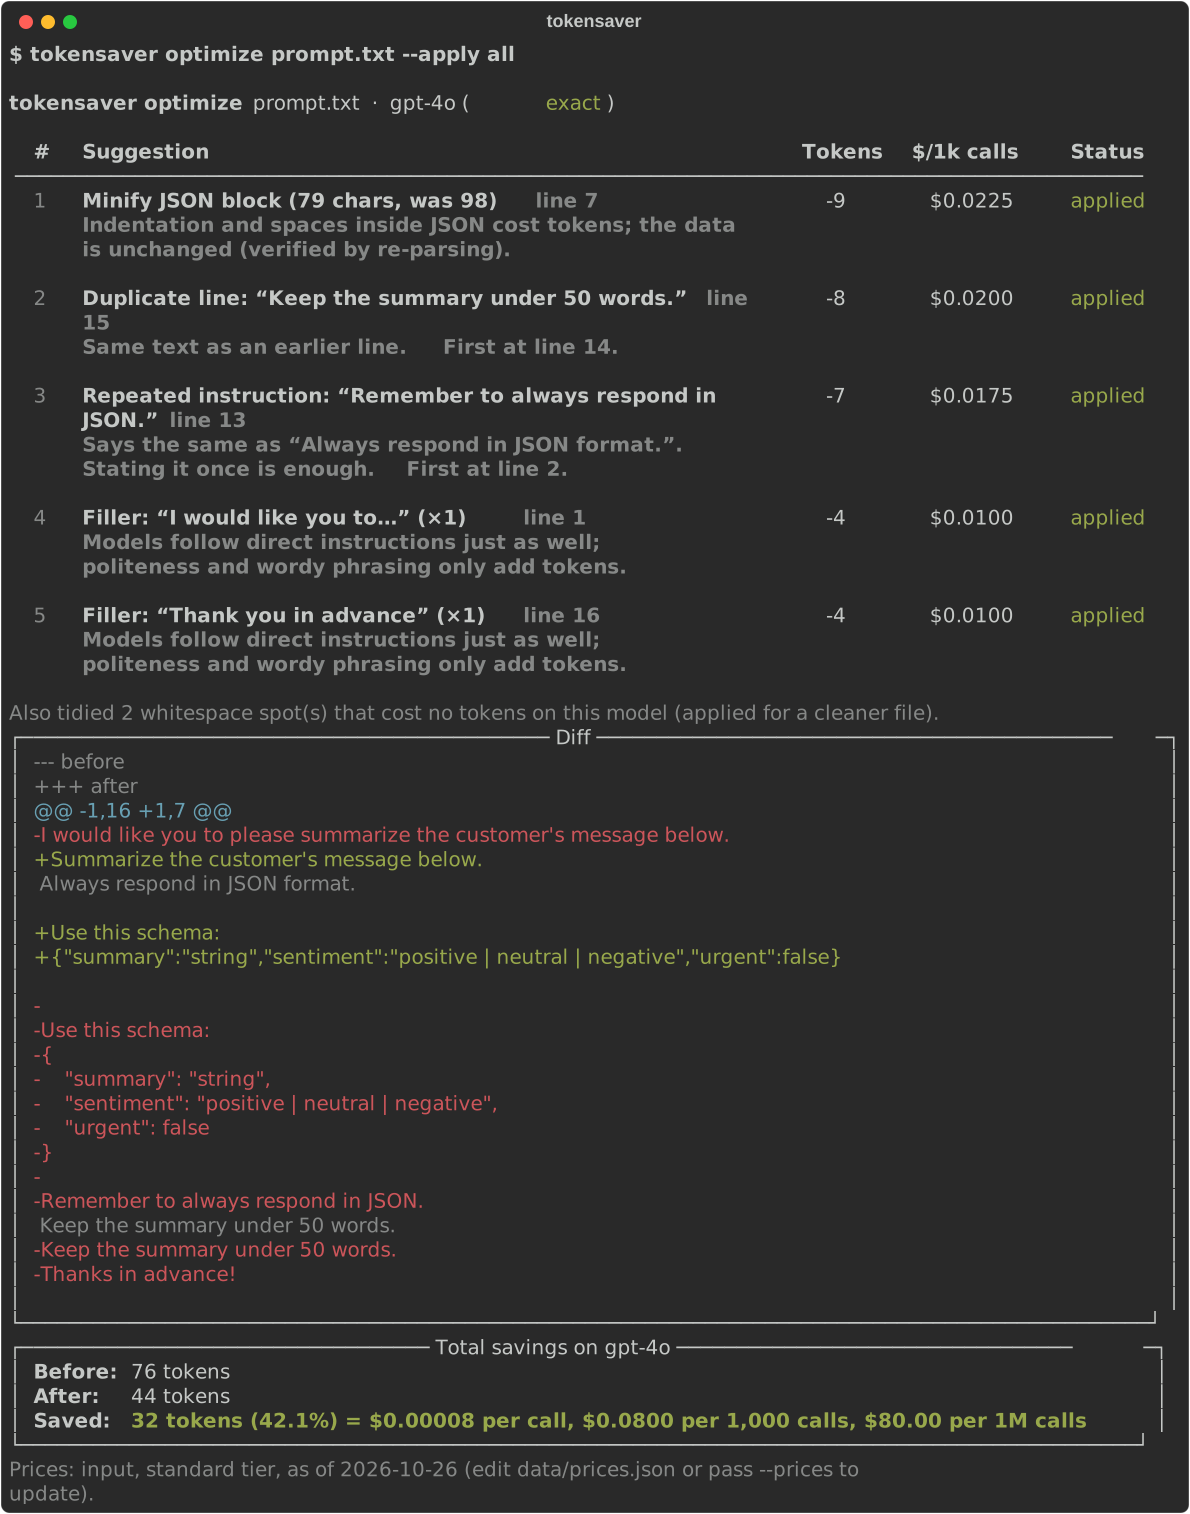
Before / after
examples/messy_prompt.txt is a typical customer-support system prompt: polite filler, a
rule written twice, a paragraph pasted twice, and pretty-printed JSON.
$ tokensaver optimize examples/messy_prompt.txt --apply all

  #  Suggestion                                                    Tokens  $/1k calls  Status
  1  Minify JSON block (140 chars, was 185)  line 13                  -18     $0.0450  applied
  2  Minify JSON block (200 chars, was 392)  line 39                  -43     $0.1075  applied
  3  Duplicate line: “- Never share internal information…”  line 30   -12     $0.0300  applied
  4  Duplicate paragraph: “Please note that you must only…”  line 34  -41     $0.1025  applied
  5  Repeated instruction: “Make sure you keep the answer…”  line 32  -12     $0.0300  applied
  7  Filler: “I would like you to…” (×1)  line 4                      -6     $0.0150  applied
 ...
 15  Long example (~198 tokens)  line 60                             ≤198     $0.4950  flag

╭──────────────────────── Total savings on gpt-4o ─────────────────────────╮
│ Before: 834 tokens                                                       │
│ After:  665 tokens                                                       │
│ Saved:  169 tokens (20.3%) = $0.000423 per call, $0.4225 per 1,000 calls, │
│ $422.50 per 1M calls                                                     │
╰──────────────────────────────────────────────────────────────────────────╯
What changed in the prompt:
-I would like you to please read the customer's message carefully and answer their question.
-As an AI language model, you should always be polite, friendly and professional.
+Read the customer's message carefully and answer their question.
+You should always be polite, friendly and professional.
...
-{
-    "answer": "string",
-    "category": "billing | technical | account | other",
-    ...
-}
+{"answer":"string","category":"billing | technical | account | other","confidence":0.0,...}
...
-- Never share internal information, discount codes or employee names.
-- Make sure you keep the answer under 120 words.
With only the default safe rules (no wording changes at all), the same prompt drops from 834 to 772 tokens. tokensaver then tells you that the review suggestions would save 107 more, so you decide.
Install
pip install prompt-tokensaver
The command is tokensaver. Requires Python 3.10 or newer. Works on Windows, macOS and
Linux.
Quick start (2 minutes)
# 1. How many tokens, and what does one call cost?
tokensaver count prompt.txt --model gpt-4o
tokensaver count "Summarize this article in three bullet points."

# 2. Which model is cheapest for this prompt?
tokensaver compare prompt.txt
tokensaver compare prompt.txt --models gpt-4o,claude-sonnet-5-5,gemini-2.5-flash

# 3. What should I change? (safe changes are applied, others are suggested)
tokensaver optimize prompt.txt

# 4. Apply everything you agree with and save a copy (the original is never overwritten)
tokensaver optimize prompt.txt --apply all --output prompt.optimized.txt
tokensaver optimize prompt.txt --apply json,whitespace,filler -o prompt.optimized.txt

# Pipe text in with "-", list models and prices
cat prompt.txt | tokensaver count -        # PowerShell: Get-Content prompt.txt | tokensaver count -
tokensaver models
Windows paths work as usual: tokensaver optimize examples\messy_prompt.txt.
Optimizer rules
Each rule is a small module in src/tokensaver/optimizer/.
Safe rules cannot change meaning and are applied by default. Review rules are shown
with their savings and applied only when you ask (--apply all or --apply <rule,...>).
Code blocks are never changed. Few-shot examples are never reworded.
| Rule | Risk | What it does |
|---|---|---|
json |
safe | Minifies pretty-printed JSON. Only whitespace outside strings is removed; the result is re-parsed and compared, so keys, values and number formats stay exactly the same. |
whitespace |
safe | Removes trailing spaces, extra blank lines and blank lines at the start and end. Indentation and spaces inside lines are kept. |
duplicates |
review | Finds duplicate lines and duplicate or near-duplicate (≥90% similar) paragraphs. |
repeated-instructions |
review | Finds the same instruction given twice in different words, such as "Always respond in JSON" and "Remember to always respond in JSON". |
filler |
review | Removes polite filler ("I would like you to please…", "As an AI language model…", "Thanks in advance!") and shortens wordy phrases ("in order to" → "to"). |
long-examples |
review | Flags few-shot examples over ~150 tokens and prompts with more than 3 examples. Only flags them; it never edits. |
Every saving is measured: tokensaver counts the prompt before and after each change on the model you chose. Changes that save nothing on that model are not listed. (Safe whitespace fixes that save 0 tokens are still applied for a tidy file, and reported in one line.)
Supported models
Prices are USD per 1M tokens, standard tier, as of 2026-10-26. They live in
src/tokensaver/data/prices.json with a source URL for
each model. Edit that file, or pass your own with --prices my_prices.json.
| Model | Provider | Input / 1M | Output / 1M | Token count |
|---|---|---|---|---|
| gpt-6-astra | OpenAI | $10.00 | $50.00 | estimated |
| gpt-6.1-sol | OpenAI | $2.00 | $10.00 | estimated |
| gpt-6-luna | OpenAI | $0.10 | $0.50 | estimated |
| gpt-5.5 | OpenAI | $5.00 | $30.00 | exact |
| gpt-5.4-mini | OpenAI | $0.75 | $4.50 | exact |
| gpt-5-mini | OpenAI | $0.25 | $2.00 | exact |
| gpt-4.1 | OpenAI | $2.00 | $8.00 | exact |
| gpt-4.1-mini | OpenAI | $0.40 | $1.60 | exact |
| gpt-4o | OpenAI | $2.50 | $10.00 | exact |
| gpt-4o-mini | OpenAI | $0.15 | $0.60 | exact |
| claude-fable-5-1 | Anthropic | $10.00 | $50.00 | estimated |
| claude-opus-5-5 | Anthropic | $4.00 | $20.00 | estimated |
| claude-sonnet-5-5 | Anthropic | $2.00 | $10.00 | estimated |
| claude-haiku-5-5 | Anthropic | $0.10 | $0.50 | estimated |
| claude-haiku-4-5 | Anthropic | $1.00 | $5.00 | estimated |
| gemini-4-argon | $2.00 | $10.00 | estimated | |
| gemini-3.8-flash | $0.75 | $3.75 | estimated | |
| gemini-3.1-pro-preview | $2.00 | $12.00 | estimated | |
| gemini-2.5-flash | $0.30 | $2.50 | estimated | |
| gemini-2.5-flash-lite | $0.10 | $0.40 | estimated |
Run tokensaver models to see the list for your installed version.
Limitations
Please read this before relying on the numbers.
- Exact vs estimated. Counts are exact only for OpenAI models that
tiktokenmaps to a tokenizer (shown as "exact"). Claude, Gemini and GPT-6 have no offline tokenizer, so tokensaver counts with OpenAI'so200k_baseand multiplies by a per-model factor fromprices.json. These are always shown with~and labelled "estimated". The factors are rough heuristics, not measurements; real counts can differ by 10–20% or more, especially for code and non-English text. For exact counts, use the provider's own token-counting API. - Input cost only.
count,compareandoptimizeprice the prompt you send. Output tokens, cached-input discounts, batch discounts and long-context surcharges (for example above 200K tokens on Gemini 3.1 Pro or 100K on Claude Haiku 5.5) are not included. - Prices go stale. Check the
last_updateddate in the output. Some listed prices are scheduled to change (see thenotesfield inprices.json). - Message overhead is not counted. Chat APIs add a few tokens per message for roles and formatting. tokensaver counts the text you give it.
- Rules are heuristics. Review suggestions can be wrong: a repeated sentence can be intentional emphasis, and "duplicate" lines can be real data. That is why they are never applied unless you ask.
- Offline by design. tokensaver makes no network calls. The tokenizer files ship inside the package and are checked against their published SHA-256 hashes.
Roadmap
- Calibrate the Claude and Gemini estimate factors against official token counters
-
--jsonoutput for CI pipelines and scripts - Output-token and prompt-caching cost estimates
- Directory mode: scan all prompts in a project
- More rules: verbose markdown, long URLs, unused template variables
- GitHub Action that comments token savings on pull requests
Ideas and votes are welcome in the issues.
How to contribute
⭐ If tokensaver saved you tokens, a star helps other developers find it.
Contributions are very welcome: new rules, better heuristics, price updates and bug reports. Read CONTRIBUTING.md for the 5-minute setup. Each rule is one small file with its own tests, so it is a good first contribution.
Need help cutting your AI costs? Work with me
tokensaver catches the easy wins. If your AI bill is growing and you want a deeper review of prompts, model choice, caching and architecture, I can help.
License
1 maintainer

Metadata
1 maintainer
Release files for prompt-tokensaver 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| prompt_tokensaver-0.1.1.tar.gz | 2.5 MB | With provenance | Details for prompt_tokensaver-0.1.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| prompt_tokensaver-0.1.1-py3-none-any.whl | Python 3 | none | any | Details for prompt_tokensaver-0.1.1-py3-none-any.whl |
Total release size: 5.0 MB
Release files / prompt_tokensaver-0.1.1.tar.gz
| Download URL | prompt_tokensaver-0.1.1.tar.gz |
|---|---|
| Size | 2.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
23fa15dd07ca30db43854941035cac85ed17beee64ceb5d1646d99f598e45a46
|
|
BLAKE2b-256 checksum How to use checksums |
d630cbe3e56ce08667c8b47d5fe98ab970ae23cce58a2da415ef147658008f99
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logRelease files / prompt_tokensaver-0.1.1-py3-none-any.whl
| Download URL | prompt_tokensaver-0.1.1-py3-none-any.whl |
|---|---|
| Size | 2.5 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d0acaa31f2f751daafb6cd9c1e86a95d03969008de0d2de937eb98e8e47beae0
|
|
BLAKE2b-256 checksum How to use checksums |
fbde5d59dbd18102138a921faf0fb766697000cefe0bee26e71294b116ae47eb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logSecurity for prompt-tokensaver 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for prompt_tokensaver-0.1.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














