
py-tbparse
Reads Tableau workbooks (.twb and .twbx) and gives you what's in them as pandas DataFrames: datasources, fields, calculated fields, joins, relationships, dashboards, custom SQL. It's plain Python. You don't need Tableau or R installed.
It began as a port of PrigasG's R package twbparser. The browser GUI, the command-line tool, workbook diffing and folder scanning are new here.
Install
pip install py-tbparse
Or from a checkout:
git clone https://github.com/DDSNA/py-tbparse.git
cd py-tbparse
pip install -e .
One name throughout: pip install py-tbparse, import py_tbparse, run py-tbparse or py-tbparse-gui. (Releases up to 0.2.0 imported twbparser_py and ran twbparser / twbparser-gui; those names are gone.)
Using it from Python
from py_tbparse import TwbParser

p = TwbParser("workbook.twb")    # or a .twbx
p.get_overview()                 # counts of everything
p.get_calculated_fields()        # each calculation and its formula
p.get_relationships()            # how the tables connect
Every getter returns a DataFrame. The rest are get_datasources, get_parameters, get_fields, get_raw_fields, get_joins, get_relations, get_inferred_relationships, get_dashboards, get_dashboard_sheets, get_custom_sql, get_initial_sql and get_published_refs. get_relationship_graph_dot() returns the data model as Graphviz text, and validate() looks for problems in the relationships. In Jupyter, a bare p shows the overview.
Two helpers work across workbooks:
from py_tbparse import diff_workbooks, scan_folder

diff_workbooks(TwbParser("v1.twb"), TwbParser("v2.twb"), table="datasources")
scan_folder("./workbooks", table="datasources")   # one table, every workbook in the folder
Cleaning field names after a datasource switch
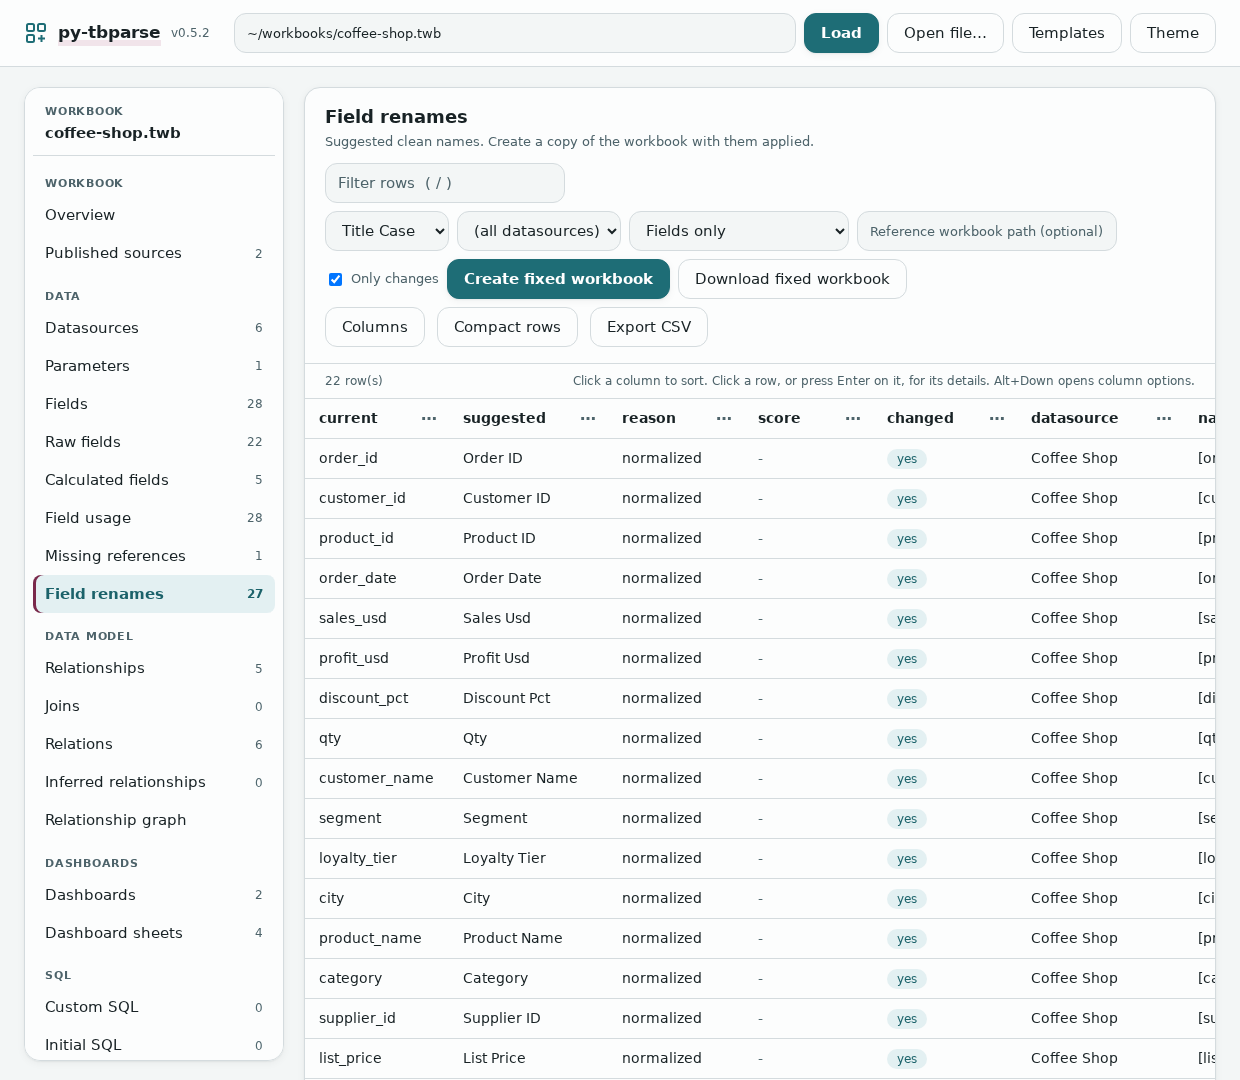
Pointing a workbook at a new datasource that only partly matches the old schema tends to leave ugly names: ORDER_ID, orderId, Order ID (Orders1), Order ID1. suggest_field_renames proposes a clean name for each field. It only reports; it never edits the workbook.
from py_tbparse import TwbParser, suggest_field_renames

new = TwbParser("after_switch.twb")
old = TwbParser("before_switch.twb")           # optional: the schema you want to match

suggest_field_renames(new, reference=old, only_changed=True)
#   name                      current                 suggested     reason             score
#   [ORDER_ID]                ORDER_ID                Order ID      matches reference  1.0
#   [Sales Amount (Orders1)]  Sales Amount (Orders1)  Sales Amount  matches reference  1.0
#   [orderDate]               orderDate               Order Date    normalized         NaN
With a reference (a workbook, a fields table or a plain list of names), fields that match by name ignoring case, separators and Tableau's duplicate suffixes take the reference's exact spelling, and near-misses above fuzzy_cutoff (default 0.85) are matched too. Everything else is tidied by normalize_name(name, style), where style is title (default), snake, lower or keep. Names that are already clean (YTD Sales, iPhone Units, Country/Region) are left alone. 1 and (Table1) suffixes are only dropped when the plain name exists in the same datasource (Address Line 2 and Q1 are never treated as duplicates), fuzzy matches never cross a different number, and two fields never get the same suggestion (the loser stays as it is, with reason set to conflict).
p.get_field_renames() does the same from a parser.
Edit the suggestions yourself. Export them, change the suggested column in a spreadsheet (blank means leave the field alone), then apply your version to a copy of the workbook:
py-tbparse rename new.twb -r old.twb -f csv -o mapping.csv
py-tbparse rename new.twb --apply mapping.csv      # writes new_renamed.twb; add --write-workbook PATH to choose the file
Your edits are applied as written, including rows the tool had marked conflict; two rows giving the same name in one datasource are rejected. From Python this is apply_field_renames(p, renames=load_rename_mapping("mapping.csv")).
What will stay broken. py-tbparse rename new.twb -r old.twb --missing (or compare_field_schemas(new, old)) lists the fields with no counterpart after the switch: old only fields that nothing in the new source matches, and new only fields nothing in the old workbook matches, each with the closest name on the other side as a hint. Sheets using an old only field stay red after Replace Data Source until you map or recreate it.
To save the result, p.write_renamed_workbook() (or apply_field_renames(p, ...)) writes <name>_renamed.twb / .twbx next to the original. It sets each field's caption, which is how Tableau renames a field; the internal names that formulas and sheets use are not touched, and a .twbx keeps all its other contents. A field that only exists as a physical column (typical right after a datasource switch) gets a new minimal <column> element carrying the caption; that shape follows what Tableau writes but I have not opened such files in Tableau itself. It never modifies the original and refuses to overwrite an existing file unless you pass overwrite=True.
When to run it. Add the new datasource to a copy of the workbook first, then run this with the old workbook as reference and datasource= set to the new source, so only its fields are renamed. Open the fixed copy and use Replace Data Source; fields with matching names should re-link on their own. It also works after references have already broken, but it only fixes names: sheets that point at missing fields stay broken until you replace the source again. (Check this on a copy first; I have not tested the re-linking in Tableau itself.)
.twbx files
A .twbx is read directly from the zip and nothing gets written to disk. That means p.twbx_dir is None, and p.path is a made-up <file>.twbx/<name>.twb that you can't open. If you want the files out, extract them yourself:
from py_tbparse import extract_twb_from_twbx, twbx_extract_files

extract_twb_from_twbx("workbook.twbx", extract_dir="out/")
twbx_extract_files("workbook.twbx", exdir="out/")    # everything in the package
Command line
py-tbparse workbook.twb                        # overview
py-tbparse workbook.twb tables                 # list the tables
py-tbparse workbook.twb calculated-fields
py-tbparse workbook.twb fields --format csv -o fields.csv
py-tbparse workbook.twbx dashboard-sheets --dashboard "Sales Overview"
py-tbparse workbook.twb validate               # exit code 2 if it finds a problem
py-tbparse workbook.twb graph > model.dot      # --include-inferred adds the guessed links
py-tbparse diff old.twb new.twb datasources
py-tbparse batch ./workbooks datasources
py-tbparse rename new.twb --reference old.twb --only-changed   # suggested clean field names
py-tbparse rename new.twb -r old.twb --datasource federated.abc123 --write-workbook   # and save new_renamed.twb
Tables: overview, datasources, parameters, fields, raw-fields, calculated-fields, joins, relations, relationships, inferred-relationships, dashboards, dashboard-sheets, custom-sql, initial-sql, published-refs.
--format takes table (default), csv or json. graph always prints Graphviz text. rename takes --reference, --datasource, --write-workbook [PATH], --style, --cutoff, --only-changed, --apply MAPPING.csv, --missing, --format and --output. diff and batch accept the same table names except graph, validate and tables.
GUI
py-tbparse-gui workbook.twb               # opens your browser with it loaded
py-tbparse-gui                            # starts empty, paste a path and hit Load
py-tbparse-gui --no-browser --port 8765   # server only, for a machine with no display
It uses only the standard library, so there's nothing more to install.
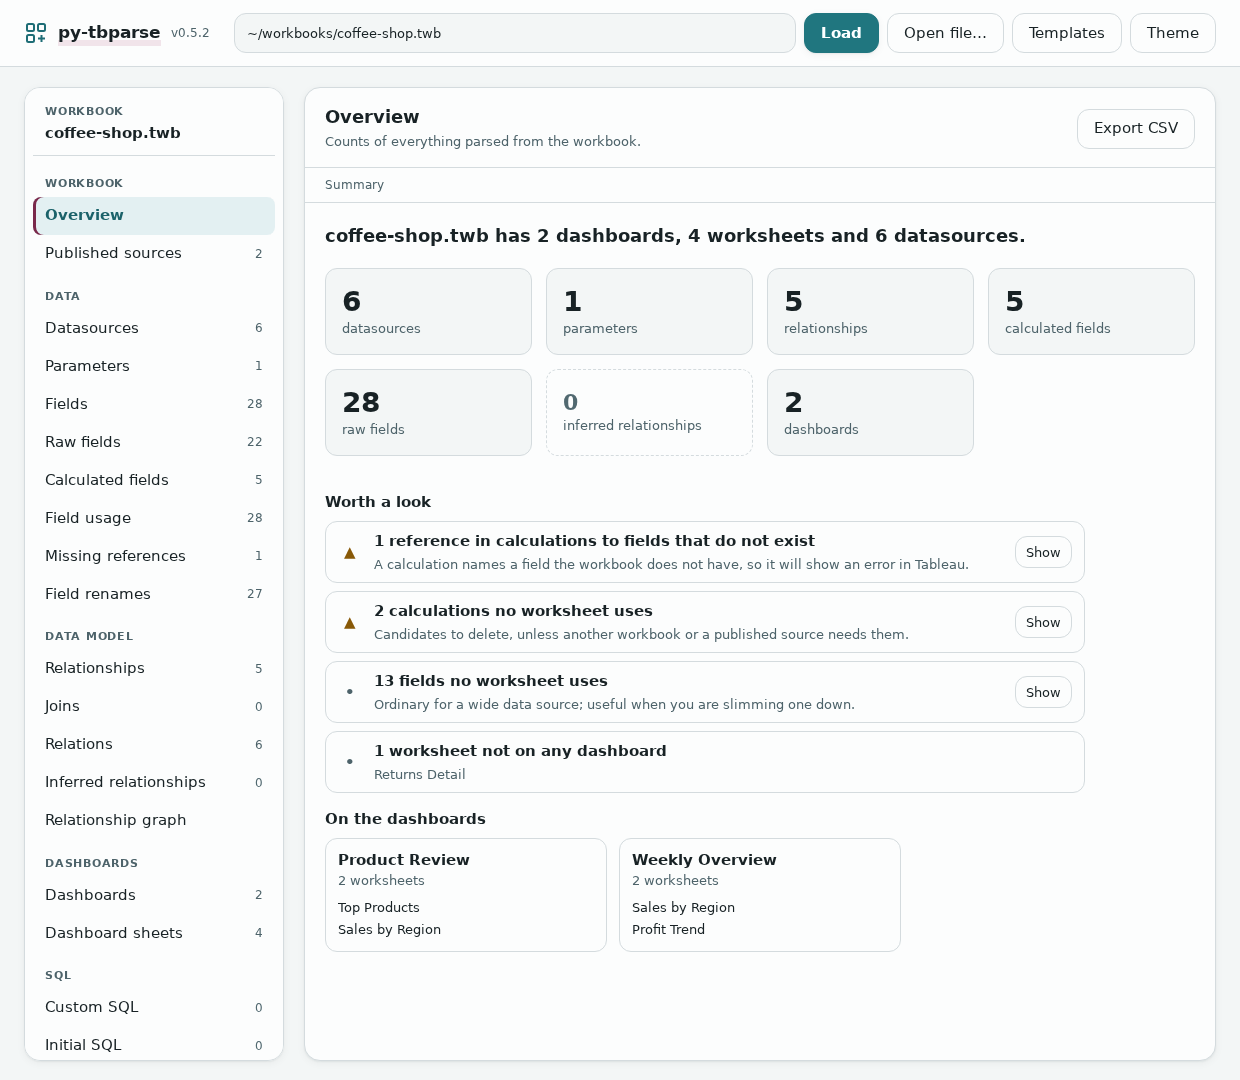
The sidebar lists every table with its row count. Click a column header to sort, type in the filter box to narrow rows (/ jumps to it), click a row to see a long formula or SQL statement in full. The tiles on the overview open their tables. The graph view lets you copy or download the DOT text. The Field renames view has the buttons for the feature above: pick a style, datasource and optional reference workbook, then Create fixed workbook saves <name>_renamed beside the original (and says so if that file already exists) or Download fixed workbook sends it to your browser without saving anything. Everything else exports as CSV. It has a dark theme and works in a narrow window.
It's meant to run on your own machine for one person. It refuses requests that come from other websites, but there's no login, so don't put it on a shared network.
Tests
pip install -e ".[test]"
pytest
The sample workbooks in tests/fixtures/ come from the R package. tests/fixtures/public/ holds real workbooks from Tableau's own document-api-python (MIT), used by the smoke tests.
The GUI tests run the page in headless Chromium through Playwright and fail on any JavaScript error. They skip if the browser isn't installed. To run them:
pip install -e ".[test,browser]"
playwright install chromium         # add --with-deps if you have root
./scripts/setup-browser-libs.sh     # without root, this unpacks the system libraries locally
pytest tests/test_gui_browser.py
Compared with the R package
The code follows the R original function by function, and the aim is the same output. Not everything is ported. Missing so far: formatting, tooltips, colors, axes and sorts, dashboard layout and actions, the analytics helpers (calculation complexity, field usage, replication brief) and the Shiny inspector. The GUI covers some of what the inspector did.
Where the R version has a bug, this one doesn't copy it. That currently covers joins and relationships on more than one key, nested joins, the include-parameters option, and calculations with brackets inside brackets.
Why a Tableau parser
A .twb is XML and a .twbx is a zip containing one, so reading them from Python isn't hard. Power BI's .pbix is a binary format built on a proprietary storage engine, and getting into it from code took reverse-engineering projects like PBIXRay and pbi-tools. On the server side it goes the other way: Tableau's own Python tooling (tableauserverclient and tabcmd) is more mature and more open than what Microsoft has for the Power BI REST API.
Credit
Based on twbparser by George Arthur, MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for py-tbparse 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| py_tbparse-0.3.0.tar.gz | 1.4 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| py_tbparse-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.5 MB
Release files / py_tbparse-0.3.0.tar.gz
| Download URL | py_tbparse-0.3.0.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
15acb7a737ad14c2eaf4e2cddff149087e2f3fb479817e51f03a075bef918a97
|
|
BLAKE2b-256 checksum How to use checksums |
3713af73e961968ccfbb1bbcacf3a7b2eef34eb8e1603b8b6e2a783f530d2db2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency logRelease files / py_tbparse-0.3.0-py3-none-any.whl
| Download URL | py_tbparse-0.3.0-py3-none-any.whl |
|---|---|
| Size | 59.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
77b6e24786bd8c56a62f2fd401a55165db6f37a448bd8b2bd9dd6e63a30945dd
|
|
BLAKE2b-256 checksum How to use checksums |
e91d29f7626b80e99be93dd4307bd2e5e7bcb0d8e9e3df7b3d61fdf5d3d09d70
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency log













