
PyraFuse


Paper · Model zoo · Inference · Mobile · Dataset · Training · Cite · Contribute
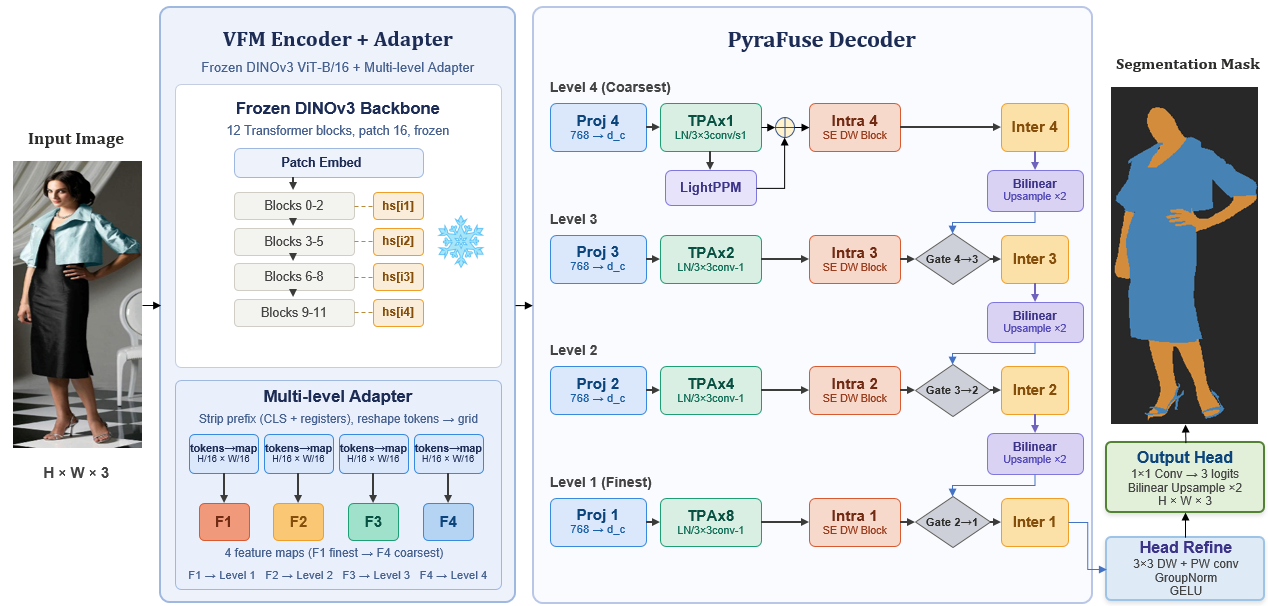
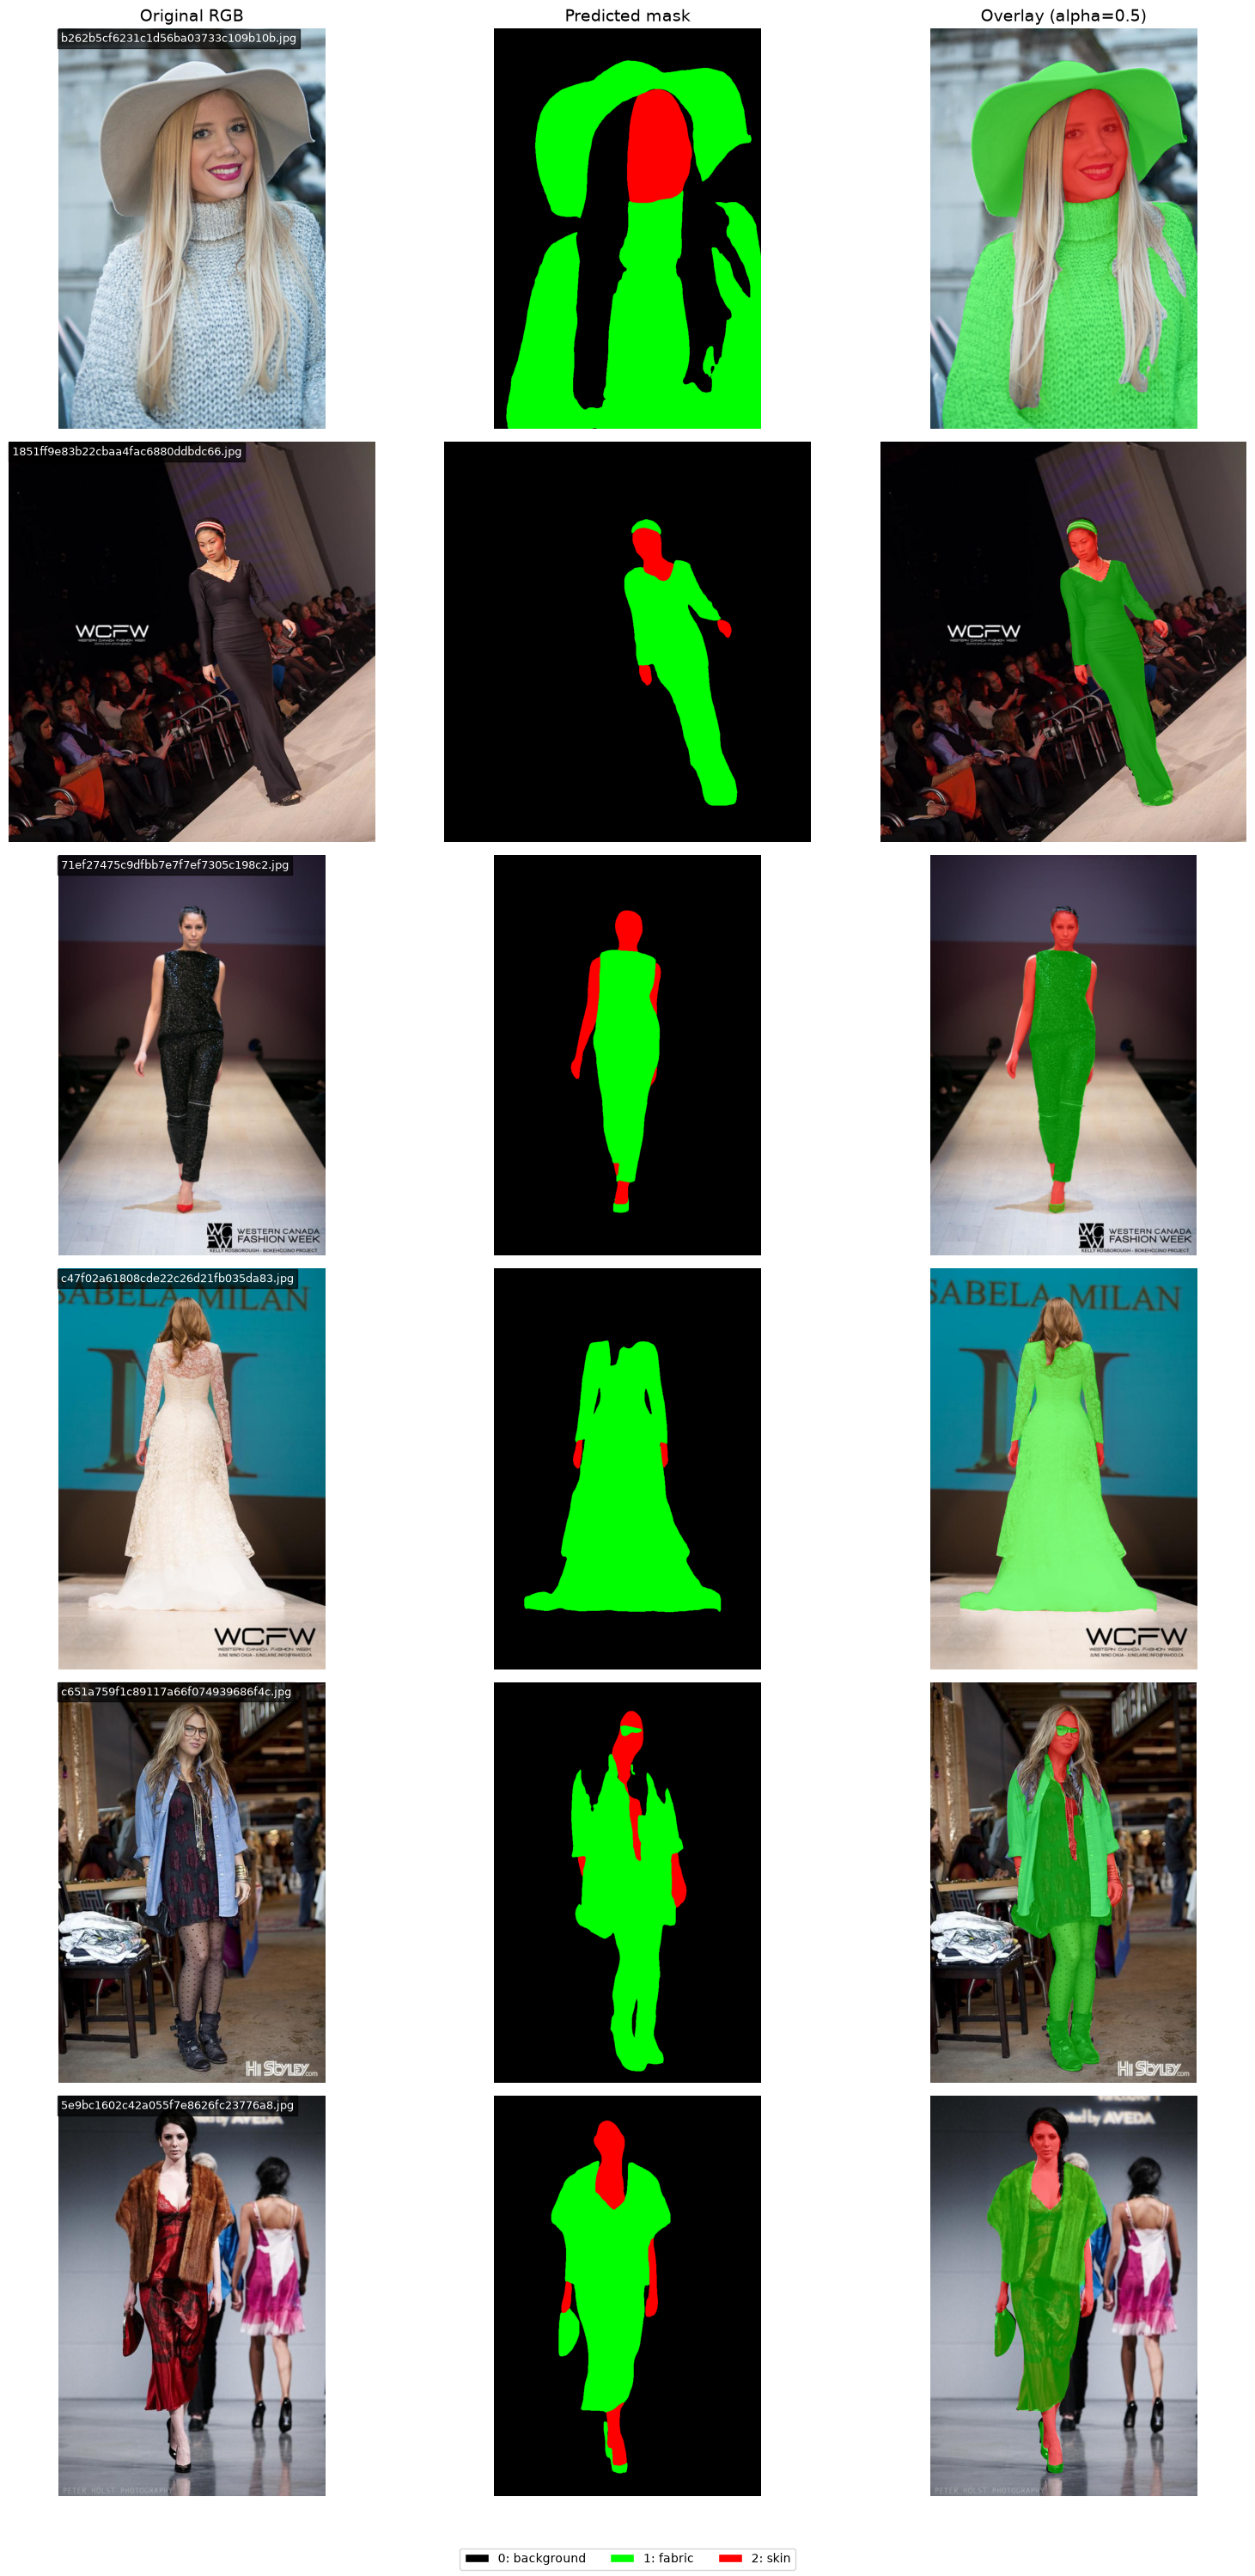
PyraFuse is an open-source DINOv3-based semantic-segmentation framework for skin, fabric, and background. It combines multi-scale vision-foundation-model features with a lightweight PyraFuse decoder, and supports research-grade PyTorch inference, GPU-specific TensorRT deployment, and on-device ExecuTorch programs for Android, iOS, and edge devices. The current release is v1.2.0.
The accompanying paper has been accepted at AIMLSystems 2026. This repository contains the code, reproducible data-preparation pipeline, inference notebooks, model-zoo interface, and accepted manuscript.
Highlights
- Three-class dense prediction:
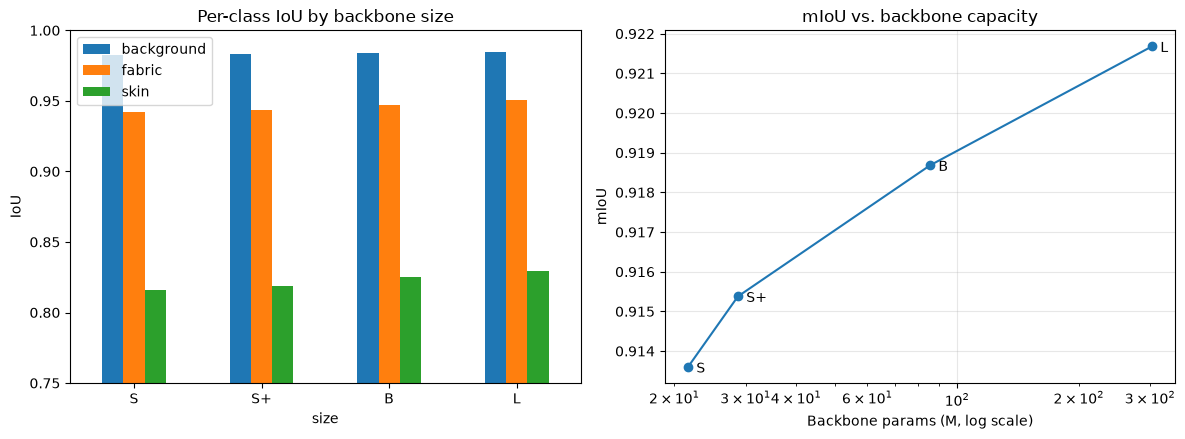
0 = background,1 = fabric,2 = skin. - DINOv3 ViT-S, ViT-S+, ViT-B, and ViT-L encoder variants.
- A self-contained checkpoint format: configuration, decoder, adapter calibration layers, complete backbone, and optional EMA weights.
- One model-zoo API for a local checkpoint or a Hugging Face model repository.
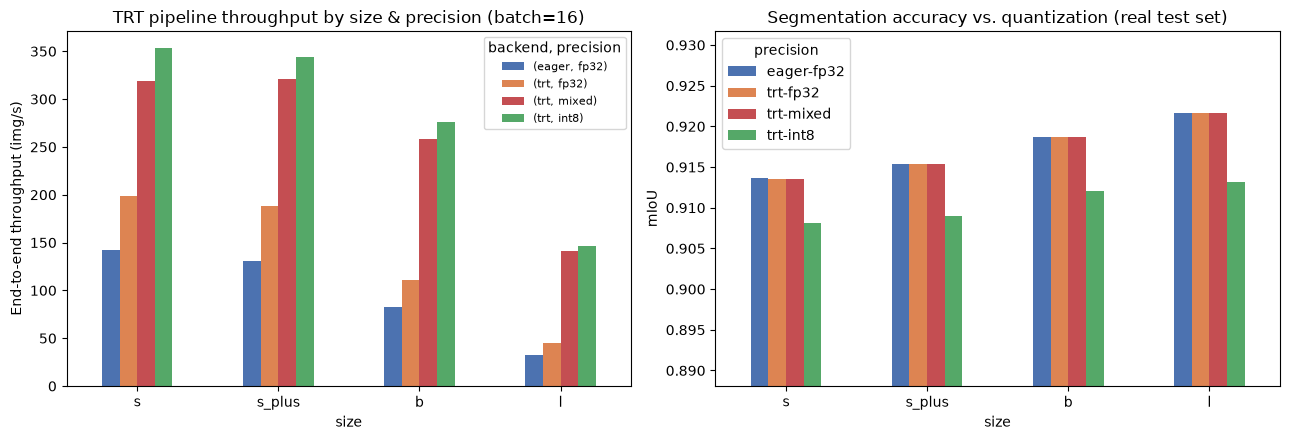
- ONNX/TensorRT export with FP32, mixed FP16, and INT8 build options.
- Ready-to-run ExecuTorch programs for Android, iOS, React Native, Flutter, and embedded Linux (CPU, Core ML, Vulkan).
Installation
Python 3.12+ is required. Install the base package for PyTorch/Hugging Face inference, then add the extras needed for data preparation or deployment.
Install the current package directly from PyPI:
python -m pip install pyrafuse
Optional extras are available through the same package name:
python -m pip install "pyrafuse[data,deploy]"
For a development checkout, install the local project in editable mode:
git clone https://github.com/jamal-saeedi/PyraFuse.git
cd PyraFuse
python -m venv .venv
source .venv/bin/activate
pip install --upgrade pip
pip install -e ".[data,deploy]"
For TensorRT, use the NVIDIA TensorRT package that matches the CUDA runtime on the deployment machine; it is intentionally an optional dependency:
pip install -e ".[trt]"
For ExecuTorch export and the on-device runtime, use the mobile extra in a
separate environment, because ExecuTorch pins its matching PyTorch release
(see Mobile and edge deployment):
pip install "torch==2.14.*" --index-url https://download.pytorch.org/whl/cpu
pip install -e ".[mobile]"
The package also exposes the data-mask builder as pyrafuse-data when the
data extra is installed:
pyrafuse-data --split val
Model zoo
The four checkpoint variants are directory bundles, not single pickled files. The bundles are excluded from Git because the full backbones are large. On a development checkout, place them under models/finals/; the public bundles are available in the jamal-one/PyraFuse Hugging Face model repository.
| Variant | Encoder | Local checkpoint directory |
|---|---|---|
small |
DINOv3 ViT-S/16 | models/finals/small |
small_plus |
DINOv3 ViT-S+/16 | models/finals/small_plus |
base |
DINOv3 ViT-B/16 | models/finals/base |
large |
DINOv3 ViT-L/16 | models/finals/large |
Each variant uses this portable layout:
<variant>/
├── config.json
├── decoder.pt
├── ema.pt                     # evaluation weights, when available
└── backbone/
    ├── config.json
    ├── model.safetensors
    └── feature_norms.pt
The official public model repository is jamal-one/PyraFuse. It is the default model source; set an environment variable only to use a private mirror or fork:
export PYRAFUSE_MODEL_REPO=your-namespace/PyraFuse
load_pretrained checks a local models/finals/<variant> first, then downloads only the requested variant from that Hub repository. Pin revision to a Hub tag or commit SHA when reproducing an experiment.
from pyrafuse import load_pretrained

model = load_pretrained(
    "base",
    revision="v1.0.0",  # recommended for reproducibility
    device="cuda",
)
The initial download is cached by huggingface_hub; later use can be offline:
model = load_pretrained("base", local_files_only=True, device="cuda")
See models/README.md for the release checklist and exact upload command. Do not commit .pt, .safetensors, ONNX, or TensorRT engine binaries to this Git repository.
Inference
PyraFuse expects ImageNet-normalised RGB tensors with spatial dimensions that are multiples of 16. The following minimal example predicts the class map for one image using an EMA checkpoint:
import numpy as np
import torch
from PIL import Image
from pyrafuse import load_pretrained

device = "cuda" if torch.cuda.is_available() else "cpu"
model = load_pretrained("base", device=device)

image = Image.open("example.jpg").convert("RGB").resize((448, 448))
array = np.asarray(image, dtype=np.float32) / 255.0
mean = torch.tensor((0.485, 0.456, 0.406)).view(3, 1, 1)
std = torch.tensor((0.229, 0.224, 0.225)).view(3, 1, 1)
pixel_values = (torch.from_numpy(array).permute(2, 0, 1) - mean) / std

with torch.inference_mode():
    prediction = model(pixel_values.unsqueeze(0).to(device)).argmax(1)[0]

# prediction values: 0=background, 1=fabric, 2=skin
Image.fromarray(prediction.cpu().numpy().astype(np.uint8)).save("prediction.png")
For a complete visual PyTorch/TensorRT walkthrough, use notebooks/inference_torch_and_tensorrt.ipynb.
TensorRT deployment
TensorRT engines are compiled artifacts, not portable checkpoints: an engine must match the target GPU architecture, TensorRT version, CUDA runtime, precision, and optimization profile. Distribute the eager PyTorch checkpoint as the source of truth and either build engines on the target host or publish them in a clearly labelled, separate Hub subfolder.
python scripts/export_trt.py \
  --ckpt models/finals/base \
  --out-dir models/trt_pipeline/base \
  --label base \
  --precision fp32 mixed int8 \
  --min-batch 1 --opt-batch 1 --max-batch 1 \
  --verify
INT8 should be calibrated with representative, preprocessed images for production. Always run --verify and evaluate on held-out images after building an engine.
Mobile and edge deployment
PyraFuse ships ExecuTorch programs (.pte) for
Android, iOS, React Native, Flutter, and embedded Linux. One file runs
unchanged in every framework that embeds the ExecuTorch runtime. The programs
are published under mobile/<variant>/ in the
Hugging Face repository;
large (ViT-L, 1.2 GB) is not exported for phones.
| Target | Runs on | Precision |
|---|---|---|
xnnpack_fp32 |
CPU: Android, iOS, macOS, Linux/ARM boards (Raspberry Pi, Jetson CPU) | FP32 |
xnnpack_int8 |
same CPUs, about 4× smaller | INT8 weights, dynamic INT8 activations |
coreml_fp32 |
iOS 17+ / macOS 14+ GPU and CPU via Core ML | FP32 |
vulkan_fp32 |
Android GPU via Vulkan | FP32 |
| Variant | Program | Size | mIoU | Agreement with PyTorch |
|---|---|---|---|---|
small |
PyTorch reference | 0.907 | ||
xnnpack_fp32 |
91 MB | 0.907 | 100.00% | |
xnnpack_int8 |
23 MB | 0.906 | 99.78% | |
coreml_fp32 |
92 MB | on device | on device | |
vulkan_fp32 |
91 MB | on device | on device | |
small_plus |
PyTorch reference | 0.908 | ||
xnnpack_fp32 |
119 MB | 0.908 | 100.00% | |
xnnpack_int8 |
31 MB | 0.907 | 99.74% | |
coreml_fp32 |
121 MB | on device | on device | |
vulkan_fp32 |
119 MB | on device | on device | |
base |
PyTorch reference | 0.912 | ||
xnnpack_fp32 |
348 MB | 0.912 | 100.00% | |
xnnpack_int8 |
88 MB | 0.912 | 99.80% | |
coreml_fp32 |
349 MB | on device | on device | |
vulkan_fp32 |
348 MB | on device | on device |
mIoU is measured on the first 200 images of the held-out test split at 448 px by executing each program with the ExecuTorch runtime; the Core ML and Vulkan programs need Apple or Android hardware and are not yet scored.
Choosing a program. Start with small + xnnpack_int8 (23 MB) for the
widest device coverage; use coreml_fp32 on iOS and vulkan_fp32 on Android
to run on the GPU. For NVIDIA Jetson GPUs, use the TensorRT path above.
Input and output contract
Every program has one forward method with static shapes:
- input
float32 [1, 3, 448, 448]: RGB, stretch-resized to 448 × 448, and divided by 255. ImageNet mean/std normalisation is inside the program. - output
float32 [1, 3, 448, 448]: logits for0 = background,1 = fabric,2 = skin. Takeargmaxover the class dimension and resize the class map back to the photo with nearest-neighbour interpolation.
Download
hf download jamal-one/PyraFuse --include "mobile/small/*" --local-dir pyrafuse-mobile
from pyrafuse import download_mobile_model

pte_path = download_mobile_model("small", "xnnpack_int8", revision="v1.2.0")
Python and embedded Linux
python -m pip install "pyrafuse[mobile]" # ExecuTorch 1.5 requires torch 2.14
import numpy as np
import torch
from PIL import Image
from executorch.runtime import Runtime
from pyrafuse import download_mobile_model

forward = Runtime.get().load_program(
    download_mobile_model("small", "xnnpack_int8")).load_method("forward")

image = Image.open("example.jpg").convert("RGB")
pixels = np.asarray(image.resize((448, 448)), dtype=np.float32) / 255.0
logits = forward.execute([torch.from_numpy(pixels).permute(2, 0, 1)[None]])[0]
mask = logits.argmax(1)[0].to(torch.uint8).numpy()  # 0=background, 1=fabric, 2=skin
Image.fromarray(mask).resize(image.size, Image.NEAREST).save("mask.png")
In C++ (for example on a Raspberry Pi), load the same file with the ExecuTorch
Module API: Module module("pyrafuse_small_xnnpack_int8.pte");, wrap the
input with from_blob(data, {1, 3, 448, 448}), and call module.forward(input).
React Native
react-native-executorch
(0.10+) runs the programs directly through its semantic-segmentation hook, which
handles resizing, scaling, argmax, and colouring:
import { useSemanticSegmenter } from 'react-native-executorch';

const PYRAFUSE_SMALL = {
  modelPath:
    'https://huggingface.co/jamal-one/PyraFuse/resolve/main/mobile/small/pyrafuse_small_xnnpack_int8.pte',
  modelOpts: {
    labels: ['background', 'fabric', 'skin'] as const,
    resizeMode: 'stretch' as const,
    interpolation: 'linear' as const,
    outInterpolation: 'nearest' as const,
    normalizeOpts: { alpha: 1 / 255, beta: 0 }, // mean/std is inside the model
  },
};

const { isReady, segment } = useSemanticSegmenter(PYRAFUSE_SMALL);
// `image` is an RGB/RGBA ImageBuffer, e.g. from a camera frame:
const { buffer } = await segment(image, {
  fabric: [242, 147, 62, 160],
  skin: [44, 177, 154, 160],
});
Use pyrafuse_small_coreml_fp32.pte on iOS by selecting the path with
Platform.OS.
Flutter
import 'package:executorch_flutter/executorch_flutter.dart';

final model = await ExecuTorchModel.load(ptePath);
final outputs = await model.forward([
  TensorData(
    shape: [1, 3, 448, 448],
    dataType: TensorType.float32,
    data: inputBytes, // Float32List(3 * 448 * 448) in CHW order, pixel / 255
  ),
]);
// outputs[0]: float32 logits [1, 3, 448, 448]; argmax over the class axis
Android (Kotlin)
// build.gradle: implementation("org.pytorch:executorch-android:<version>")
import org.pytorch.executorch.EValue
import org.pytorch.executorch.Module
import org.pytorch.executorch.Tensor

val module = Module.load(ptePath)
val input = Tensor.fromBlob(chwPixels, longArrayOf(1, 3, 448, 448)) // FloatArray, pixel / 255
val logits = module.forward(EValue.from(input))[0].toTensor().dataAsFloatArray
val plane = 448 * 448
val mask = ByteArray(plane) { i ->
    var best = 0
    for (c in 1 until 3) if (logits[c * plane + i] > logits[best * plane + i]) best = c
    best.toByte()
}
iOS (Swift)
// Swift Package: https://github.com/pytorch/executorch.git, branch "swiftpm-1.5.1"
// Products: executorch, backend_xnnpack, backend_coreml, kernels_optimized
import ExecuTorch

let module = Module(filePath: ptePath)
try module.load("forward")
let input = Tensor<Float>(chwPixels, shape: [1, 3, 448, 448]) // pixel / 255
let logits = try Tensor<Float>(module.forward(input)).scalars()
Exporting your own checkpoint
python -m pip install -e ".[mobile]"
python scripts/export_mobile.py --variants small small_plus base --eval
The script writes models/mobile/<variant>/*.pte and
models/mobile/manifest.json with sizes,
SHA-256 hashes, backend delegation, and held-out mIoU. It accepts checkpoint
directories and --image-size (a multiple of 16) for faster, lower-resolution
builds. notebooks/mobile_executorch.ipynb
runs the programs, compares them with PyTorch, and visualises the masks.
Why there are no FP16 programs. DINOv3's first transformer block has extreme activation outliers: its attention logits reach about 2.5 × 10⁶ for ViT-S and 1.4 × 10⁵ for ViT-B, far beyond the FP16 maximum of 65,504. Backends that store that product in FP16 (the Core ML Neural Engine, Vulkan FP16) output NaNs and a single-class mask. For the same reason, INT8 uses dynamic per-token activation scales; static per-tensor INT8 collapses to mIoU ≈ 0.25. The Core ML and Vulkan programs are validated at export time but still need on-device benchmarks; the XNNPACK programs were executed and scored locally.
Dataset
The training labels fuse Fashionpedia fashion annotations with visuAAL skin masks. Data is not versioned in Git. The preparation script downloads missing source files and builds three-class masks; it is safe to re-run.
python scripts/prepare_data.py
python scripts/prepare_data.py --help
The dataset notebook documents source data, label creation, dataloaders, class balance, and skin-tone analysis. Please comply with the licences and terms of the source datasets.
Training
scripts/train_segmenter.py is the reproducible training CLI. It combines the
train and validation sources, creates the fixed 75/15/15 split (seed 42 by
default), estimates class weights, trains with Focal+Dice and EMA, and writes
run_config.json, metrics.json, best/, and last/ to the run directory.
Install the data and development extras, then prepare the labels:
python -m pip install -e ".[data,dev]"
python scripts/prepare_data.py
Run a one-batch CPU smoke test using the published small checkpoint. The
checkpoint is intentionally not stored in Git; download it from the PyraFuse
Hub repository first:
hf download jamal-one/PyraFuse --include "small/**" --local-dir models/finals

python scripts/train_segmenter.py \
  --resume models/finals/small \
  --device cpu --batch-size 1 --num-workers 0 \
  --no-class-weights --mix-prob 0 --smoke --skip-test \
  --checkpoint-path /tmp/pyrafuse-train-smoke
Fine-tune a published checkpoint on CUDA, or train a fresh DINOv3-S encoder
after configuring your Hugging Face access in HF_TOKEN:
# Warm-start (architecture is read from config.json)
python scripts/train_segmenter.py \
  --resume models/finals/small --device cuda \
  --epochs 25 --batch-size 16 \
  --checkpoint-path models/checkpoints/pyrafuse-small-finetune

# Fresh DINOv3-S run (the backbone remains frozen unless --finetune-backbone)
python scripts/train_segmenter.py \
  --encoder-size s --decoder pyrafuse --loss focal_dice \
  --device cuda --epochs 150 --batch-size 16 \
  --checkpoint-path models/checkpoints/pyrafuse-s
Use --dry-run to validate paths, split sizes, model construction, and loss
configuration without fitting. Use --finetune-backbone only when the target
GPU and dataset size justify end-to-end fine-tuning. See
python scripts/train_segmenter.py --help for all data, augmentation,
precision, checkpoint, and monitoring options.
Repository layout
pyrafuse/
├── pyrafuse/       # model, data, training, deployment, and model-zoo code
├── scripts/        # data preparation, training, TensorRT and ExecuTorch export CLIs
├── notebooks/      # dataset, inference, and mobile (ExecuTorch) walkthroughs
├── models/         # ignored local checkpoints; tracked manifests and guidance
├── images/         # paper figures and qualitative results
├── paper/          # accepted AIMLSystems 2026 manuscript
└── tests/          # lightweight API tests
Reproducibility and release practice
- Use the EMA weights for evaluation (
load_pretrained(..., use_ema=True)). - Record the Git commit, Hub revision, model variant, input size, dataset split, metric implementation, CUDA/TensorRT versions, and precision.
- Tag each GitHub code release with a semantic version. Update the Hugging Face model revision when the published weights change; the PyTorch bundles are unchanged since
v1.0.0, and the ExecuTorch programs were added at Hub tagv1.2.0. - Keep raw data, credentials, experiment logs, and binary model artifacts out of Git. The current
.gitignoreenforces this policy.
PyPI package
The current package is published as pyrafuse 1.2.0:
python -m pip install pyrafuse
CI lints, tests, and builds a validated wheel on every push and pull request.
Releases are driven by tags: pushing vX.Y.Z runs the
release workflow, which checks that the
tag matches version in pyproject.toml, builds and validates the
distributions, publishes them to PyPI with Trusted Publishing (no stored
token), and creates the GitHub Release with the matching CHANGELOG.md notes.
For maintainers: bump version in pyproject.toml and CITATION.cff, add the
CHANGELOG.md section, commit, then tag and push:
git tag -a v1.2.0 -m "PyraFuse 1.2.0"
git push origin v1.2.0
For a local dry run, install the release tools and run the same checks:
python -m pip install -e ".[release]"
python -m build
twine check dist/*
Citation
GitHub recognises CITATION.cff and provides a ready-to-copy software citation from the repository's Cite this repository panel. The manuscript is accepted at AIMLSystems 2026 and is not yet formally published; please do not invent a DOI or page range before the camera-ready bibliographic details are available.
Licence
The original PyraFuse source code is released under Apache-2.0. The published checkpoint bundles include Meta DINOv3 backbone material and therefore remain subject to the DINOv3 License, provided alongside each public model release. Fashionpedia and visuAAL data are not redistributed and remain subject to their respective terms. See NOTICE before redistributing code or weights.
Tags
skin-fabric-detection · skin-segmentation · fabric-segmentation · semantic-segmentation · DINOv3 · TensorRT · ExecuTorch · on-device
1 maintainer

Metadata
1 maintainer
Release files for pyrafuse 1.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pyrafuse-1.2.0.tar.gz | 70.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pyrafuse-1.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 150.9 kB
Release files / pyrafuse-1.2.0.tar.gz
| Download URL | pyrafuse-1.2.0.tar.gz |
|---|---|
| Size | 70.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
af0b5210d99afd1efe32bacd591b90c110bf6017c444da2c8b7743cabe58d0c0
|
|
BLAKE2b-256 checksum How to use checksums |
74fcda8e7bd0d980a7f85ba531acc3fab3e05897249539154127a70bc54b2e81
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / pyrafuse-1.2.0-py3-none-any.whl
| Download URL | pyrafuse-1.2.0-py3-none-any.whl |
|---|---|
| Size | 80.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cab707398ee47686243fe09483aee2c536535f647a0d4a8298f84fbcbd8b225c
|
|
BLAKE2b-256 checksum How to use checksums |
1678d156ce14bc382891cdec46d5c94f6346dfce0ed4bb17cdf496a809e09d02
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













