




Python OpenCV Utilities
Python OpenCV Utilities provides useful extensions for OpenCV
and can be used as a drop-in replacement for cv2. It covers the everyday gaps (Unicode paths, aspect-ratio
resize, crop-free rotation, Unicode text) and whole workflows: video reading and editing, data augmentation,
annotation formats (COCO polygons, RLE, YOLO), running ONNX models with cv.dnn, camera calibration, document
scanning and OCR preprocessing, image statistics and visualization.
import cv2u as cv # instead of: import cv2 as cv
| PyPI package | python-opencv-utils |
| Import name | cv2u |
| Python | 3.11 – 3.15 |
| OpenCV | 4.10+ and 5.x, any distribution (normal, headless, contrib) |
| NumPy | 2.0+ |
| Documentation | https://076923.github.io/cv2-utils/ |
Installation
Choose the OpenCV distribution with an extra:
pip install "python-opencv-utils[opencv]"            # opencv-python
pip install "python-opencv-utils[headless]"          # opencv-python-headless (servers, Docker; no GUI)
pip install "python-opencv-utils[contrib]"           # opencv-contrib-python
pip install "python-opencv-utils[contrib-headless]"  # opencv-contrib-python-headless
pip install "python-opencv-utils[opencv,cluster]"    # also scikit-learn (meanShiftColors, dbscanColors, clusterPoints)
If the project already has OpenCV installed, pip install python-opencv-utils without an extra uses it.
Dependencies: OpenCV 4.10 or newer (including OpenCV 5), numpy>=2, pillow.
The optional cluster extra adds scikit-learn for meanShiftColors, dbscanColors and clusterPoints.
dominantColors, colorQuantize and kmeansColors work without it (they use cv.kmeans).
Usage
The official OpenCV Python tutorials import the module as
import cv2 as cv. Use the same pattern with cv2u: every OpenCV function and constant keeps working,
and the extensions below are available alongside them.
import cv2u as cv

src = cv.imread("image.jpg")  # plain OpenCV
dst = cv.rotateEx(src, 45)  # cv2u extension
If a name exists in both, the cv2u version wins. You can always reach the original module with import cv2.
cv is only a name, so import cv2u as cv2 also works if you prefer it.
Type checkers and IDEs see OpenCV's own signatures through cv2u, so autocompletion and type checking for
cv.imread and friends keep working. Names the OpenCV 5.0 stubs do not have (added later, or only in OpenCV 4) are typed as Any.
Everyday helpers
import cv2u as cv

src = cv.imreadEx("C:/사진/고양이.jpg")  # cv.imread fails on non-ASCII paths on Windows
small = cv.resizeEx(src, width=640)  # keeps the aspect ratio
boxed, scale, (left, top) = cv.letterbox(src, (640, 640))  # fit + pad, e.g. for a model input
logo = cv.imread("logo.png", cv.IMREAD_UNCHANGED)  # BGRA with transparency
stamped = cv.overlayImage(small, logo, org=(10, 10), alpha=0.8)
cv.imwriteEx("C:/사진/비교.png", cv.hconcatEx([small, stamped], gap=8))
Video and notebooks
import cv2u as cv

print(cv.videoInfo("input.mp4"))  # VideoInfo(width=1920, height=1080, fps=30.0, frameCount=900)
edges = (cv.autoCanny(frame) for frame in cv.readFrames("input.mp4", step=2))  # every 2nd frame
cv.writeVideo("edges.mp4", edges, fps=15)  # codec, size and color mode are detected

corners = [[120, 80], [980, 140], [940, 760], [90, 700]]  # e.g. from cv.approxPolyDP, in any order
page = cv.fourPointTransform(cv.imread("photo.jpg"), corners)
cv.imshowInline(page)  # in Jupyter, with the correct colors
Detection and web results
import cv2u as cv

img = cv.imread("street.jpg")
detections = [((40, 60, 120, 200), "person", 0.94), ((200, 90, 160, 110), "자동차", 0.88)]
crops = []
for box, name, score in detections:
    crops.append(cv.cropRect(img, box, margin=10, fill=0))  # safe even at the image border
    cv.drawLabel(img, box, f"{name} {score:.2f}", (0, 200, 255), fontPath="C:/Windows/Fonts/malgun.ttf")

hsv = cv.cvtColor(img, cv.COLOR_BGR2HSV)
red = cv.inRangeEx(hsv, (170, 80, 80), (10, 255, 255))  # red wraps around hue 0
cv.imwrite("result.png", cv.montage([img, cv.overlayMask(img, red, (255, 0, 255)), *crops], gap=8))

payload = {"image": cv.imencodeBase64(img, ".jpg", dataUri=True)}  # for a JSON API or an HTML <img>
Raw detector output to clean boxes on the original image:
import cv2u as cv

img = cv.imread("street.jpg")
small, scale, offset = cv.letterbox(img, (640, 640))  # what the network saw
boxes, scores = run_model(small)  # (N, 4) as (x, y, w, h) and (N,)
keep = cv.nms(boxes, scores, iouThreshold=0.5, scoreThreshold=0.3)
boxes = cv.scaleBoxes(boxes[keep], scale, offset, inverse=True)  # back to the original image
boxes = cv.clipBoxes(cv.expandBoxes(boxes, ratio=0.1), (img.shape[1], img.shape[0]))
cv.drawBoxes(img, boxes, labels=[f"{s:.2f}" for s in scores[keep]])  # one color per box

mask = cv.morphology(cv.binarize(img, "adaptive", invert=True), "open", 5)  # dark ink, speckles removed
heat = cv.mapTiles(img, (512, 512), run_model, overlap=32)  # a fixed-input model over a big image, seams averaged
images = cv.imreadAll(cv.listImages("photos/"))  # a folder in natural order; a bad file raises with its name
lines = cv.findLines(img, minLength=100)  # (N, 4) segments, longest first
aligned, M = cv.alignImages(cv.imread("scan.png"), cv.imread("template.png"))  # feature match + RANSAC + warp
Training data
import cv2u as cv

img = cv.imread("train/0001.jpg")
size = (img.shape[1], img.shape[0])
boxes, classIds = cv.readYoloLabels("train/0001.txt", size)  # normalized rows -> pixel (x, y, w, h)
img, boxes = cv.randomFlip(img, horizontal=0.5, boxes=boxes, seed=1)  # the boxes follow the image
img, boxes = cv.randomRotate(img, maxAngle=10, boxes=boxes, seed=1)
img = cv.randomHSV(cv.addNoise(img, "gaussian", seed=1), hue=10, seed=1)
cv.writeYoloLabels("aug/0001.txt", boxes, classIds, size, makeDirs=True)
cv.imwriteEx("aug/0001.jpg", cv.jpegArtifacts(img, quality=40))

tiles = cv.imreadAll(["train/0001.jpg", "train/0002.jpg", "train/0003.jpg", "train/0004.jpg"])
labels = [cv.readYoloLabels(f"train/{i:04d}.txt", (t.shape[1], t.shape[0]))[0] for i, t in enumerate(tiles, 1)]
big, bigBoxes = cv.mosaic(tiles, (640, 640), boxes=labels, seed=1)  # YOLO-style 4-image mosaic
polygons = cv.maskToPolygons(cv.binarize(img, "otsu", invert=True))  # COCO polygons from a mask
rle = cv.rleEncode(cv.polygonsToMask(polygons, size))  # and uncompressed RLE, no pycocotools needed
Running a model
import cv2u as cv

net = cv.dnn.loadModel("C:/모델/yolov8n.onnx")  # Unicode path; FileNotFoundError instead of a C++ assertion
names = cv.dnn.readClassNames("coco.names")
img = cv.imread("street.jpg")
blob, info = cv.dnn.preprocessImage(img, (640, 640))  # letterbox + blob; info remembers the geometry
output = cv.dnn.inferImage(net, blob)[0]  # every output layer, not just the first
dets = cv.dnn.postprocessDetections(
    output, info, scoreThreshold=0.3
)  # YOLO rows -> Detections(boxes, scores, classIds)
cv.imwrite("result.png", cv.dnn.drawDetections(img, dets, names))  # boxes on the original image
Everything else in cv.dnn (cv.dnn.readNet, cv.dnn.blobFromImage, cv.dnn.NMSBoxes, ...) is passed through from OpenCV.
Video tools
import cv2u as cv

fps = cv.FPSCounter()
with cv.VideoReader("input.mp4") as video, cv.VideoWriterEx("out.mp4", fps=video.fps) as writer:
    video.seekTime(5.0)  # start at 00:05
    for frame in video:
        fps.tick()
        writer.write(cv.drawFPS(cv.autoCanny(frame), fps.fps))  # codec, size and color mode from the first frame

cuts = cv.detectScenes("input.mp4", threshold=30)  # frame indices where a new shot starts
print([cv.formatTimestamp(cv.frameToTime(i, video.fps)) for i in cuts])  # "00:00:12.400", ...
cv.extractFrames("input.mp4", "frames/", step=30, ext=".png")  # one file every 30 frames
cv.videoToGif("input.mp4", "preview.gif", fps=10, size=(320, 180), maxFrames=50)
cv.imwrite("sheet.jpg", cv.videoThumbnail("input.mp4", count=6, cols=3))  # contact sheet
Documents and quality
import cv2u as cv

photo = cv.imread("receipt.jpg")
page = cv.scanDocument(photo)  # detect the page, warp it upright, clean the background
mask = cv.sauvolaThreshold(page, invert=True)  # local threshold for OCR, no contrib module needed
for x, y, w, h in cv.detectTextLines(page):  # one box per text line, top to bottom
    cv.drawDashedRectangle(page, (x, y, w, h), (0, 160, 255))

stats = cv.imageStats(photo)  # ImageStats(width, height, channels, dtype, mean, std, ..., sharpness, entropy, isGray)
if cv.isBlurry(photo) or cv.isBlank(photo):
    print("retake:", stats.sharpness, stats.contrast)
cv.imwrite("compare.png", cv.compareImages(photo, page, mode="side", labels=["photo", "scan"]))
rotateEx
Rotates an image without cropping its corners. The canvas grows to fit the result.
import cv2u as cv

src = cv.imread("image.jpg")
dst = cv.rotateEx(src, 45)

cv.imshow("src", src)
cv.imshow("dst", dst)
cv.waitKey()
| src | dst |
|---|---|
 |
 |
Masks, contours and templates
import cv2u as cv

scan = cv.cropToContent(cv.imread("scan.png"), tolerance=10)  # drop the white margin
mask = cv.inRange(cv.toGray(scan), 0, 100)  # dark ink; toGray works whatever the input is
mask = cv.fillHoles(cv.removeSmallObjects(mask, minArea=30))
contours = cv.findContoursEx(mask, minArea=500)  # largest first
round_ones = cv.filterContours(contours, minCircularity=0.8)  # by area, aspect ratio, solidity, ...
for i, contour in enumerate(cv.sortContours(round_ones, "left-to-right")):
    stats = cv.contourStats(contour)  # area, perimeter, rect, center, solidity, circularity, ...
    cv.drawLabel(scan, stats.rect, f"{i}: {stats.area:.0f} px", (0, 160, 255))
    cv.imwriteEx(f"out/piece_{i}.png", cv.cropContour(scan, contour, transparent=True), makeDirs=True)
debug = cv.drawContoursEx(cv.toBGR(scan), contours, labels=True)  # each contour in its own color, numbered

for x, y, w, h, score in cv.findTemplate(scan, cv.imread("logo.png"), threshold=0.9):
    print(f"logo at ({x}, {y}), score {score:.2f}")
cv.imwriteEx("out/annotated.png", scan, makeDirs=True)  # cv.imwrite would return False: no "out" folder
Color clustering
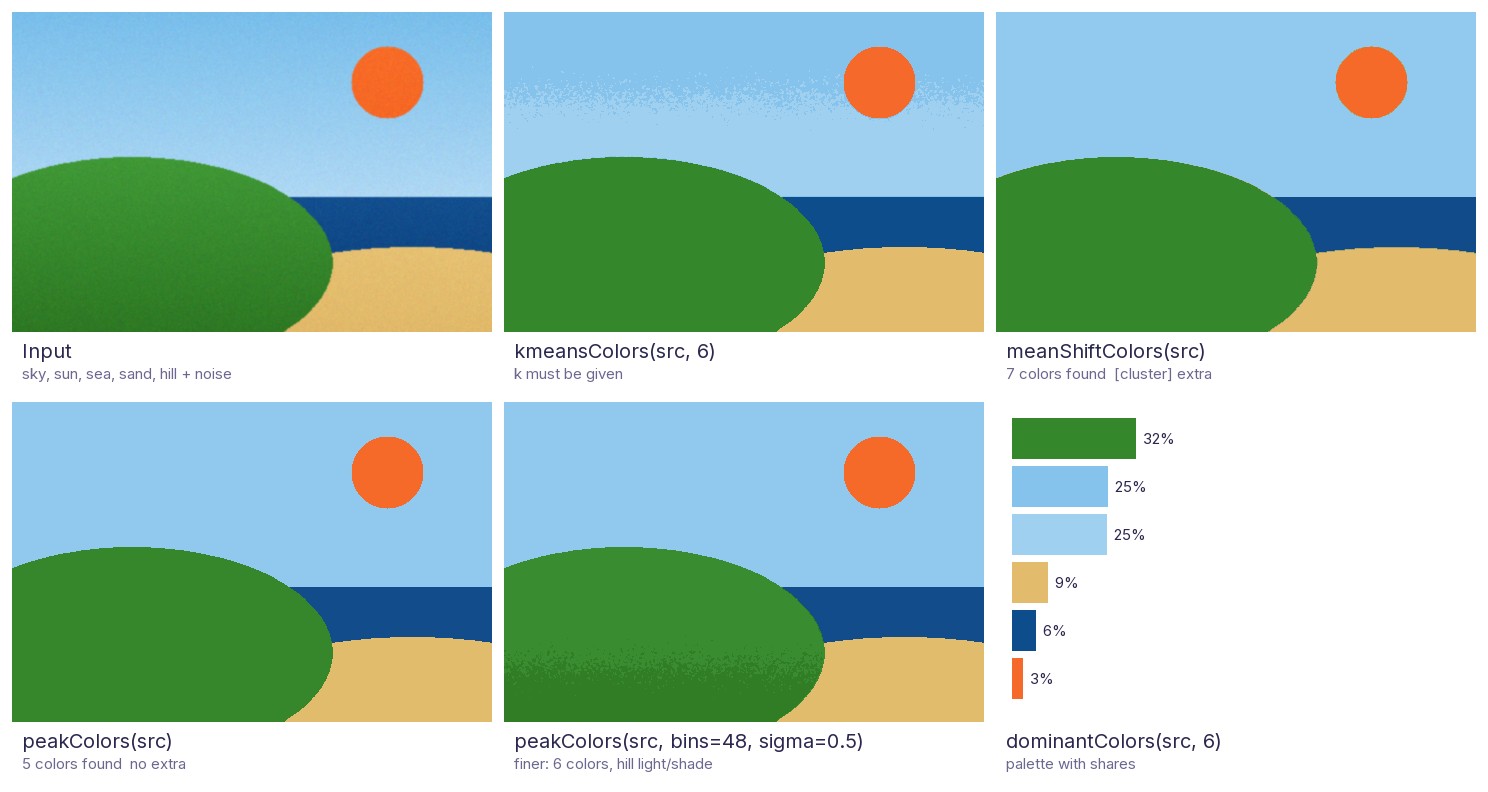
Every color clustering returns (maps, centers): a label image and one color per label, so centers[maps] paints
the result. They differ in how the number of colors is chosen:
kmeansColors |
meanShiftColors |
peakColors |
|
|---|---|---|---|
| Number of colors | You give k |
Found automatically | Found automatically |
Needs the [cluster] extra |
No | Yes | No |
| Deterministic | Yes (seed) |
Yes (seed) |
Yes (no randomness at all) |
| Pixels used to fit | A sample | A sample | Every pixel |
| 1 MP / 12 MP image | 0.25 s / 3.0 s | 0.53 s / 2.7 s | 0.13 s / 1.5 s |
Timings: the scene above at 1200x800 and 4200x2800, best of 3 runs, on one Windows PC with Python 3.14; use them to compare the methods, not as absolute numbers.
peakColors is cv2u's own method: it counts the pixels in a 3-D Lab color histogram, smooths it, and follows every
histogram cell uphill to its peak; each peak becomes one color. Identical colors, which are very common in 8-bit
images, simply add up, so it neither needs a sample nor splits flat colors apart. In the comparison it found the
5 regions of the scene, where kmeansColors (with a fixed k=6) cut the sky gradient with a noisy band, and
meanShiftColors added two clusters of 421 and 79 pixels. bins and sigma make it finer or coarser, and
minRegion absorbs small speckles into the surrounding region.
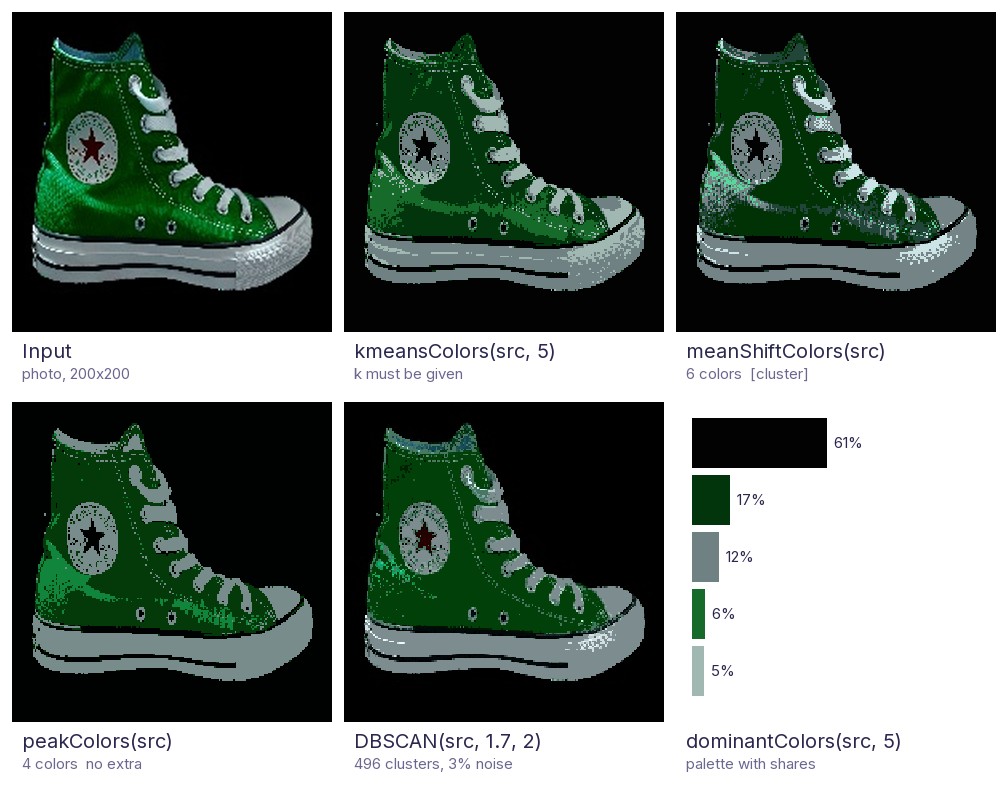
On a real photo of a sneaker, peakColors separates background, the dark and bright
greens and the white parts into 4 clean regions. meanShiftColors finds 6 colors but leaves the surface
speckled, and dbscanColors with eps=1.7 splits the image into 496 tiny clusters, which mostly reproduces the input.
Note that the dark-red star (15 pixels, 0.04% of the image, almost black) merges into the background with every
color clustering except that very fine dbscanColors; details this small are below what a palette can keep.
import cv2u as cv

img = cv.imread("photo.jpg")
maps, centers = cv.peakColors(img)  # number of colors found automatically, no extra needed
print(len(centers), "colors")
segmented = centers[maps]

for (b, g, r), share in cv.dominantColors(img, k=5):  # a palette
    print(f"#{r:02x}{g:02x}{b:02x} {share:.0%}")
poster = cv.colorQuantize(img, 8)
Named flags
import cv2u as cv

src = cv.imread("image.jpg")
mirrored = cv.flip(src, cv.FLIP_MODE_Y)  # instead of cv.flip(src, 1)
edges = cv.Sobel(src, cv.DDEPTH_SAME, 1, 0)  # instead of ddepth=-1
gray = cv.cvtColor(src, cv.COLOR_BGR2GRAY)
contours, _ = cv.findContours(cv.Canny(gray, 100, 200), cv.RETR_EXTERNAL, cv.CHAIN_APPROX_SIMPLE)
cv.drawContours(src, contours, cv.ALL_CONTOURS, (0, 255, 0), cv.FILLED)  # instead of contourIdx=-1

cv.imshow("mirrored", mirrored)
while cv.waitKey(cv.WAIT_FOREVER) != cv.KEY_ESC:  # instead of waitKey(0) != 27
    pass
Design principles
cv2u is what you wish OpenCV had, in the place you would look for it:
- Fill the gaps in OpenCV: only add what OpenCV lacks or makes you write boilerplate for.
- Look like OpenCV: same module names, camelCase,
Exfor extended versions,srcfirst, BGR, OpenCV parameter names. - Never shadow OpenCV: no extension has the same name as anything in
cv2. - Stay light: heavier dependencies are optional extras.
- Typed and validated: type hints everywhere, clear
ValueErrors for bad input. - Change carefully: after a release, renames get deprecated aliases and new behavior goes behind new parameters.
Details: https://076923.github.io/cv2-utils/principles/
API
Full reference with parameters and exceptions: https://076923.github.io/cv2-utils/api/
core
| Function | Description |
|---|---|
rotateEx(src, angle, scale=1.0, flags=cv.INTER_LINEAR, borderMode=cv.BORDER_CONSTANT, borderValue=0) |
Rotate around the center without cropping. Extra arguments go to cv.warpAffine. |
centerPoint(contour) |
Centroid (x, y) of a contour. Raises ValueError for zero area. |
isInside(p, polygon) |
Point-in-polygon test. polygon is (N, 1, 2) or (N, 2). |
cartesianToPolar(x, y, angleInDegrees=False) |
Returns (theta, rho) for scalars or arrays. Note: cv.cartToPolar returns (magnitude, angle). |
polarToCartesian(theta, rho, angleInDegrees=False) |
Returns (x, y) for scalars or arrays. |
imcolor(size, color, channels=3, dtype=np.uint8) |
Image of (width, height) filled with color. |
imcolorLike(src, color, dtype=None) |
Image with the shape (and dtype) of src, filled with color. |
makeGradient(size, start, end, direction="horizontal", channels=3) |
Linear gradient image of (width, height). direction is "horizontal", "vertical" or "raster". |
gammaCorrection(src, gamma=1.0) |
Gamma correction for 8-bit images through a lookup table. |
boldEdges(src) |
Bold, high-contrast edge map for 8-bit images (drawings, logos). |
dominantColors(src, k=5) |
The k most common colors with their share, most common first (a palette). |
colorQuantize(src, k) |
Reduce the image to k colors. |
kmeansColors(src, k, seed=0) |
Deterministic color k-means in Lab space. Returns Clusters(maps, centers). |
peakColors(src, bins=32, sigma=0.75, minShare=0.01, minRegion=0) |
Finds the number of colors itself from the peaks of the color histogram. Fast, deterministic, no extra. |
meanShiftColors(src, bandwidth=None) |
Like kmeansColors, but finds the number of colors itself. Needs [cluster]. |
dbscanColors(src, eps, minSamples=4) |
Cluster BGR pixels in Lab space with DBSCAN. Returns Clusters(maps, centers); noise is -1. Needs [cluster]. |
drawClusters(src, maps) |
Paint each cluster with its mean color, as a new image. |
clusterPoints(points, eps, minSamples=2) |
Group nearby points (keypoints, detections, ...) with DBSCAN. Needs [cluster]. |
hconcatEx(images, color=0, gap=0) |
Side by side, for images of different heights and channels. |
vconcatEx(images, color=0, gap=0) |
Stacked vertically, for images of different widths and channels. |
overlayImage(src, overlay, org=(0, 0), alpha=1.0) |
Alpha-blend a (transparent) image onto another, clipped at the borders. |
montage(images, cols=None, gap=0, color=0, cellSize=None) |
Arrange images in a grid. |
cropRect(src, rect, margin=0, fill=None) |
Crop safely when the box extends outside the image (clip, or pad with fill). |
boxIoU(boxesA, boxesB) |
IoU of every pair of boxes (x, y, w, h), as an (N, M) array. |
nms(boxes, scores, iouThreshold=0.5, scoreThreshold=0, maxCount=None) |
Non-maximum suppression; the indices to keep, best first. |
xywhToXyxy(boxes), xyxyToXywh(boxes) |
Convert between (x, y, w, h) and corner boxes. |
clipBoxes(boxes, size), scaleBoxes(boxes, scale, offset=(0, 0), inverse=False), expandBoxes(boxes, ratio=0, margin=0, size=None) |
Clip to the image, undo a resize or letterbox, grow for context. |
cropCenter(src, size, fill=None) |
Crop (width, height) from the middle. |
inRangeEx(src, lowerb, upperb) |
cv.inRange for HSV hue ranges that wrap around, such as red (170 to 10). |
cropToContent(src, background=None, tolerance=0, margin=0) |
Trim a uniform border (scan margins, black bars). |
padToMultiple(src, multiple, color=0), padToSize(src, size, color=0) |
Pad to a multiple (e.g. 32 for networks) or to an exact size, without scaling. |
splitTiles(src, tileSize, overlap=0), mergeTiles(tiles, size) |
Split a large image into full-size tiles and merge processed tiles back (overlaps averaged). |
mapTiles(src, tileSize, func, overlap=0, progress=None) |
Run a function (e.g. a model) over a large image tile by tile and merge the results. |
rotatePoints(points, angle, center=(0, 0), scale=1.0), scalePoints(points, scale, center=(0, 0)), translatePoints(points, dx, dy) |
Transform a point set, in any point layout. |
flipPoints(points, size, flipCode), clipPoints(points, size) |
Flip points together with cv.flip; clip them to the image. |
normalizePoints(points, size), denormalizePoints(points, size) |
Pixels to 0..1 coordinates and back. |
pointsBoundingBox(points), polygonCentroid(points), orderPoints(points) |
Box (x, y, w, h) of a point set; centroid of a polygon; 4 corners in top-left, top-right, bottom-right, bottom-left order. |
distancePoints(a, b), nearestPoints(a, b) |
(N, M) distance matrix; the nearest point in b for every point of a, with distances. |
angleBetween(p1, p2, degrees=True), lineIntersection(line1, line2), pointLineDistance(point, line, segment=False) |
Angle of a segment; where two lines cross (None if parallel); distance to a line or segment. |
maskToPolygons(mask, epsilon=0.0, minArea=0), polygonsToMask(polygons, size, value=255) |
COCO-style polygons from a mask and back. |
boxesToPolygons(boxes), polygonsToBoxes(polygons) |
Boxes as 4-point polygons; bounding boxes of polygons as an (N, 4) array. |
polygonArea(polygon), polygonIoU(polygonA, polygonB, resolution=1024), maskIoU(maskA, maskB) |
Exact area, overlap of two polygons (concave too) and of two masks. |
rleEncode(mask), rleDecode(rle) |
COCO uncompressed RLE ({"size", "counts"}, pycocotools-compatible) without pycocotools. |
boxesToYolo(boxes, size, classIds=None), yoloToBoxes(rows, size) |
Pixel boxes to normalized class cx cy w h rows and back. |
readYoloLabels(filename, size), writeYoloLabels(filename, boxes, classIds, size, makeDirs=False) |
YOLO .txt label files, on any path. Returns (boxes, classIds). |
flipBoxes(boxes, size, flipCode), flipPolygons(polygons, size, flipCode) |
Flip annotations together with cv.flip. |
labelMapToColor(labels, palette=None, background=0), colorToLabelMap(image, palette, background=0) |
Paint a class-id map with distinct colors and recover it from the painted image. |
instanceMasksToLabelMap(masks), labelMapToMasks(labels, background=0) |
Instance masks to one label map (later masks on top) and back. |
drawPolygons(src, polygons, color=None, thickness=2, fill=False, alpha=1.0, labels=None), drawSegmentation(src, labels, alpha=0.5, palette=None) |
Polygons in their own colors with labels; a label map blended over the image. Both return a new image. |
imgcodecs
| Function | Description |
|---|---|
imreadEx(filename, flags=cv.IMREAD_COLOR) |
cv.imread that also works with non-ASCII (e.g. Korean) paths on Windows. |
imwriteEx(filename, img, params=(), makeDirs=False) |
cv.imwrite that also works with non-ASCII paths on Windows, and can create missing folders. |
listImages(path, recursive=False) |
The image files in a folder, in natural order (img2 before img10). |
imreadAll(filenames, flags=cv.IMREAD_COLOR, strict=True), imwriteAll(filenames, images, params=(), makeDirs=False, strict=True) |
Read or write many files; unreadable files raise with the file name (or give None). |
imreadUrl(url, flags=cv.IMREAD_COLOR, timeout=None, headers=None, maxBytes=None) |
Read an image from a URL. Returns None if decoding fails, like cv.imread. |
toPillow(src), fromPillow(image) |
Convert to/from Pillow with the right channel order. Every Pillow mode is accepted; 16-bit, int32, float32 and bool images round-trip unchanged. |
imencodeBase64(img, ext=".png", dataUri=False), imdecodeBase64(data) |
Images as base64 text or data URIs, e.g. for web APIs. |
imageInfo(filename), exifOrientation(filename) |
ImageInfo(width, height, channels, mode, format, fileSize, exifOrientation) from the file header, without decoding. |
imreadOriented(filename, flags=cv.IMREAD_COLOR) |
cv.imread with the EXIF orientation applied for every flag and format. |
imreadResized(filename, size=None, scale=None, width=None, height=None, flags=cv.IMREAD_COLOR) |
Read and resize in one step; 1/2, 1/4 and 1/8 scales decode reduced for speed. |
imencodeEx(ext, img, params=()), imdecodeEx(data, flags=cv.IMREAD_COLOR) |
Encode to bytes (errors raise) and decode any bytes-like object. |
convertImageFormat(src, dst, quality=None, background=(255, 255, 255), makeDirs=False) |
Convert a file between formats; alpha is flattened for JPEG and the EXIF orientation applied. |
imgproc
| Function | Description |
|---|---|
adjustBrightnessContrast(src, brightness=0, contrast=1.0) |
Brightness/contrast like a photo editor (contrast pivots around mid-gray). |
adjustHSV(src, hue=0, saturation=1.0, value=1.0) |
Rotate the hue (degrees) and scale saturation/brightness. |
autoContrast(src, clip=0.01), whiteBalance(src) |
Auto levels that ignore outliers; remove a color cast. |
sharpnessScore(src), ssim(a, b), diffMask(a, b, threshold=25) |
Blur detection, structural similarity, changed pixels. |
imageHash(src, hashSize=8, method="difference"), hashDistance(a, b) |
Perceptual hashes (dHash, aHash, pHash) for finding near-duplicate images. |
matchHistograms(src, reference), colorTransfer(src, reference) |
Give an image the tones or the color mood of another one. |
translate(src, dx, dy) |
Shift an image, keeping its size. |
transformPoints(points, M) |
Map points through a 2x3 affine or 3x3 perspective matrix, in any point layout. |
cropRotatedRect(src, rect, borderMode=cv.BORDER_CONSTANT, borderValue=0) |
Cut out a rotated box from cv.minAreaRect as an upright image. |
deskew(src, maxAngle=45.0) |
Straighten a tilted page from its text lines. Returns (dst, angle). |
pixelate(src, blockSize=16, rect=None) |
Mosaic the image or one box, e.g. to anonymize faces. |
drawDashedLine(img, pt1, pt2, color), drawDashedRectangle(img, rect, color) |
Dashed lines and boxes, in place. |
drawRoundedRectangle(img, rect, color, thickness=1, radius=8, lineType=cv.LINE_8) |
A box with rounded corners, in place. |
drawHistogram(src, size=(512, 200)) |
Plot the histogram as an image. |
largestComponent(mask), skeletonize(mask), cutout(src, mask, feather=0) |
Keep the main object, thin to 1-pixel lines, cut out with transparency. |
hexToBGR("#ff8800"), bgrToHex(color) |
Convert between hex colors and BGR tuples. |
toGray(src), toBGR(src), toBGRA(src, alpha=None) |
Convert from any channel count; no error when the image is already in that format. |
flattenAlpha(src, fill=(255, 255, 255)) |
Composite a transparent image onto a color or image, e.g. before saving as JPEG. |
findContoursEx(image, mode=cv.RETR_EXTERNAL, method=cv.CHAIN_APPROX_SIMPLE, minArea=0, sort=True) |
cv.findContours for any image, largest first, small ones dropped. |
binarize(src, method="otsu", invert=False) |
Any image to a 0/255 mask: Otsu, adaptive, triangle or a fixed threshold. |
morphology(src, op, ksize=3, shape="ellipse", iterations=1) |
cv.morphologyEx by name ("open", "close", ...) with the kernel built for you. |
maskBoundingRect(mask), applyMask(src, mask, fill=0) |
Box of the nonzero pixels; keep the masked pixels, fill the rest. |
findLines(src, minLength=30, maxGap=10), findCircles(src, minRadius=0, maxRadius=0), findBlobs(src, minArea=10) |
Hough lines and circles and blob detection as plain (N, 4) / (N, 3) arrays. |
matchFeatures(src, reference, method="ORB", ratio=0.75), alignImages(src, reference, motion="homography") |
Keypoint matching with the ratio test; register one image onto another. |
fillHoles(mask, maxHoleArea=None), removeSmallObjects(mask, minArea) |
Mask clean-up. |
contourStats(contour) |
Area, perimeter, rect, center, aspect ratio, extent, solidity, circularity, equivalent diameter and orientation in one named tuple. |
sortContours(contours, method="left-to-right"), filterContours(contours, minArea=0, ..., minCircularity=0) |
Reading order or size order; keep the shapes whose measurements are in range. |
contoursToMask(contours, size), cropContour(src, contour, margin=0, fill=0, transparent=False) |
Contours back to a mask; crop one object with the outside blanked or transparent. |
approxContour(contour, epsilon=0.02), mergeContours(contours) |
cv.approxPolyDP with a relative tolerance; one hull around several pieces. |
drawContoursEx(img, contours, colors=None, labels=False), boundingRects(contours), asContour(points) |
Each contour in its own color with labels, in place; all boxes as an (N, 4) array; points to an OpenCV contour. |
findTemplate(src, templ, threshold=0.8, maxCount=None) |
cv.matchTemplate as an (N, 5) array of non-overlapping matches (x, y, w, h, score). |
resizeEx(src, width=None, height=None, interpolation=None) |
Resize keeping the aspect ratio; picks INTER_AREA/INTER_LINEAR automatically. |
letterbox(src, size, color=0, interpolation=None) |
Fit into (width, height) keeping the aspect ratio and pad. Returns Letterbox(image, scale, (left, top)). |
fourPointTransform(src, pts, size=None) |
Warp a quadrilateral (corners in any order) to an upright rectangle, e.g. a photographed document. |
autoCanny(src, sigma=0.33) |
cv.Canny with thresholds chosen from the median brightness. |
equalizeHistEx(src, clahe=False) |
cv.equalizeHist for color images too (on the Lab lightness), optionally CLAHE. |
unsharpMask(src, sigma=1.0, amount=1.0, threshold=0) |
Unsharp-mask sharpening. |
drawLabel(img, rect, text, color, fontPath=None) |
Draw a box with a label tag, in place like cv.rectangle. Unicode labels with fontPath. |
overlayMask(src, mask, color=(0, 0, 255), alpha=0.5) |
Tint the masked pixels, e.g. to show a segmentation. |
drawBoxes(img, boxes, labels=None, colors=None), drawPoints(img, points, labels=False), drawGrid(img, step) |
Many boxes or points at once, each in its own color; a pixel grid. |
distinctColors(count) |
BGR colors that are easy to tell apart, for classes, tracks or clusters. |
putTextEx(img, text, org, fontPath, fontSize, color) |
Draw Unicode text (e.g. Korean) with a TrueType font, in place like cv.putText. org is the top-left corner. |
addNoise(src, kind="gaussian", amount=None, seed=None), motionBlur(src, size=15, angle=0.0), vignette(src, strength=0.5, radius=1.0), jpegArtifacts(src, quality=30) |
Photo degradations for augmentation. |
randomErase(src, size=None, count=1, fill=0, seed=None), solarize(src, threshold=128), posterize(src, bits=4) |
Erase random patches; invert above a threshold; reduce the bit depth. |
randomCrop(src, size, boxes=None, seed=None), randomFlip(src, horizontal=0.5, vertical=0.0, boxes=None, seed=None), randomRotate(src, maxAngle=15, boxes=None, seed=None, ...), randomScale(src, scaleRange=(0.8, 1.2), boxes=None, seed=None, ...), randomPerspective(src, distortion=0.1, boxes=None, seed=None, ...) |
Seeded geometric augmentations; with boxes, return (dst, boxes) with the boxes transformed too. |
randomBrightnessContrast(src, brightness=0.2, contrast=0.2, seed=None), randomHSV(src, hue=10, saturation=0.3, value=0.3, seed=None), randomBlur(src, maxKernel=7, seed=None) |
Seeded photometric augmentations. |
mosaic(images, size, boxes=None, seed=None), mixup(a, b, alpha=0.5, lam=None, seed=None), cutMix(a, b, alpha=1.0, seed=None) |
YOLO-style 4-image mosaic (boxes follow); mixup and CutMix return (dst, lam) for the labels. |
imageStats(src) |
ImageStats(width, height, channels, dtype, mean, std, minVal, maxVal, brightness, contrast, sharpness, entropy, isGray) in one call. |
isGrayscale(src, tolerance=0), isBlank(src, tolerance=2.0), isBlurry(src, threshold=100.0) |
Dataset triage: color-less, flat or out-of-focus images. |
brightnessScore(src), contrastScore(src), exposureScore(src, lowThreshold=0.05, highThreshold=0.95), colorfulness(src) |
Mean brightness 0..1, contrast, share of under/over-exposed pixels, Hasler-Süsstrunk colorfulness. |
entropy(src, bins=256), estimateNoise(src) |
Shannon entropy of the gray histogram; noise standard deviation (Immerkær). |
mse(a, b), mae(a, b) |
Mean squared / absolute error between two images, overflow-safe. |
histogramEx(src, bins=256, mask=None, channels=None, normalize=False), histogramCompare(a, b, method=cv.HISTCMP_CORREL, bins=32, colorSpace="hsv") |
Per-channel (channels, bins) histogram of any dtype; similarity of two images through cv.compareHist. |
dominantHue(src, bins=36), meanColor(src, mask=None) |
The most common hue in degrees; mean color, optionally under a mask. |
applyColorMapEx(values, colormap=cv.COLORMAP_JET, normalize=True, mask=None), heatmap(src, values, alpha=0.5, colormap=cv.COLORMAP_JET), colorBar(colormap=cv.COLORMAP_JET, size=(256, 20), vertical=False, minVal=None, maxVal=None) |
Colorize a float map of any size, overlay it on an image, draw a legend strip. |
drawArrow(img, pt1, pt2, color, thickness=2, headSize=10, heads="end"), drawCrosshair(img, center, color, size=20, gap=4) |
Arrows with pixel-sized heads ("end", "start", "both"); a crosshair. In place. |
drawRotatedRect(img, rect, color, thickness=2), drawRotatedBoxes(img, rects, colors=None, labels=None) |
Draw cv.minAreaRect results, one or many with labels. In place. |
drawPolygon(img, points, color, thickness=2, closed=True, fill=False, alpha=1.0) |
A polygon from float points, outline or translucent fill. In place. |
drawSkeleton(img, keypoints, connections=COCO_SKELETON, colors=None, radius=4, minScore=0.0), COCO_SKELETON |
A pose from keypoints (x, y[, score]); the 17-keypoint COCO connection list. |
drawTrajectory(img, points, color=None, thickness=2, fade=True, maxPoints=None) |
A track that fades toward its start. In place. |
drawTextBlock(img, lines, org=(10, 10), fontScale=0.5, color=(255, 255, 255), background=(0, 0, 0), alpha=0.6), drawFPS(img, fps, org=(10, 10)), drawProgressBar(img, progress, org, size=(200, 12)), drawLegend(img, labels, colors=None, org=(10, 10)) |
HUD panels with a translucent background: multi-line text, FPS, a progress bar, a color legend. In place. |
compareImages(a, b, mode="side", split=0.5, labels=None, gap=0) |
Before/after view: "side", "vertical", "split", "blend" or "diff". |
labeledMontage(images, labels, cols=None, cellSize=None, gap=4), blendImages(images, weights=None) |
montage with a title over each image; weighted average of N images. |
removeShadow(src, kernelSize=21, blurSize=21), enhanceDocument(src, mode="gray") |
Even out the lighting of a photographed page; clean it up ("gray", "color", "binary"). |
sauvolaThreshold(src, windowSize=25, k=0.2, r=128.0, invert=False), niblackThreshold(src, windowSize=25, k=-0.2, invert=False) |
Local thresholds for OCR, built from cv.integral2 (no contrib module). |
removeSpeckles(src, maxArea=10), removeLines(src, horizontal=True, vertical=True, minLength=None, thickness=3), removeBorder(src, threshold=None, margin=0) |
Drop dust, table rules and the dark scanner border from a page. |
detectTextLines(src, minHeight=5, dilateWidth=None), detectTextBlocks(src, minHeight=5, dilateSize=None) |
Text lines or paragraphs as (N, 4) boxes in reading order. |
estimateSkew(src, maxAngle=45.0), detectPage(src, minAreaRatio=0.2) |
The angle behind deskew; the 4 corners of the page in a photo (None if not found). |
scanDocument(src, size=None, enhance=True, minAreaRatio=0.2) |
Photo of a document to an upright, cleaned page (detectPage + fourPointTransform + enhanceDocument). |
stitchImages(images, mode="panorama", confidence=None), stitchPair(a, b, method="ORB", ratio=0.75, ...) |
cv.Stitcher that raises with the status name; a homography stitch of two images on a canvas that fits both. |
CSS_COLORS, colorName(color), nearestColor(color, palette, space="lab"), colorDistance(a, b, space="lab") |
The CSS color names as BGR; the closest name or palette index; distance between two colors. |
lightenColor(color, amount), darkenColor(color, amount), blendColors(a, b, t=0.5), complementaryColor(color), invertColor(color), textColorFor(background) |
Arithmetic on one BGR color; black or white text for a background. |
randomColors(count, seed=None, saturation=1.0, value=1.0), gradientPalette(start, end, count), colormapPalette(colormap, count) |
Palettes: random, between two colors, or sampled from an OpenCV colormap (e.g. cv.COLORMAP_VIRIDIS). |
videoio
| Function | Description |
|---|---|
readFrames(source, step=1, start=0) |
Iterate over the frames of a file, stream or camera; the capture is released automatically. |
writeVideo(filename, frames, fps, fourcc=None) |
Write frames; size, color mode and codec (from the extension) are detected. Returns the frame count. |
readFrameAt(source, index=None, seconds=None) |
Read one frame by number or time, e.g. for a thumbnail. |
videoInfo(source) |
VideoInfo(width, height, fps, frameCount) with a duration property. |
VideoReader(source) |
cv.VideoCapture as a context manager and iterator with width, height, fps, frameCount, read(), seek(index), seekTime(seconds) and frames(step, start, end). Raises OSError if it cannot open. |
VideoWriterEx(filename, fps, fourcc=None, isColor=None, makeDirs=False) |
cv.VideoWriter that infers codec, size and color mode from the first write(frame); a context manager. |
CameraStream(source, maxWait=5.0) |
Threaded camera reader whose read() always gives the latest frame (no stale buffer). |
FPSCounter(window=30) |
tick() every frame; fps is the moving average. |
frameToTime(index, fps), timeToFrame(seconds, fps), formatTimestamp(seconds, ms=True) |
Frame/time conversions and HH:MM:SS.mmm stamps. |
extractFrames(source, outDir, step=1, start=0, end=None, ext=".jpg", prefix="frame_", digits=6, progress=None) |
Dump frames to numbered files. Returns the paths. |
trimVideo(source, dst, start, end=None, byTime=True, fourcc=None), concatVideos(sources, dst, fourcc=None), resizeVideo(source, dst, size=None, scale=None, width=None, height=None, ...) |
Cut, join and resize video files. Return the frame count. |
videoToGif(source, dst, fps=None, size=None, step=1, maxFrames=None, loop=0), imagesToVideo(images, dst, fps=30, fourcc=None) |
Animated GIF from a video (OpenCV cannot write GIFs); time-lapse from image files or arrays. |
detectScenes(source, threshold=30.0, minLength=15, step=1) |
Frame indices where a new shot starts. |
sampleFrames(source, count), videoThumbnail(source, count=4, size=None, cols=None, gap=0) |
Evenly spaced frames; a contact sheet of them. |
calib3d
| Function | Description |
|---|---|
makeChessboard(patternSize, squareSize=50, border=1), objectPointsGrid(patternSize, squareSize=1.0) |
A printable chessboard image; the (N, 3) object points of its inner corners. |
findChessboardEx(src, patternSize, refine=True, flags=None) |
cv.findChessboardCorners on any image, sub-pixel refined; the (N, 1, 2) corners or None. |
calibrateCameraEx(views, patternSize, squareSize=1.0, imageSize=None, flags=0) |
Calibrate from chessboard photos. Returns CameraCalibration(cameraMatrix, distCoeffs, imageSize, rms, rvecs, tvecs). |
reprojectionErrors(calib, patternSize, squareSize, cornersList) |
RMS reprojection error per view. |
undistortEx(src, calib, distCoeffs=None, alpha=0.0, crop=True) |
cv.undistort with the optimal new camera matrix and the valid region cropped (no black borders). |
saveCalibration(filename, calib), loadCalibration(filename) |
A JSON calibration file, on any path. |
dnn
cv2u.dnn mirrors cv.dnn: the helpers are used as cv.dnn.loadModel(...), and every OpenCV name
(cv.dnn.readNet, cv.dnn.blobFromImage, cv.dnn.NMSBoxes, ...) still passes through.
| Function | Description |
|---|---|
dnn.loadModel(path, config=None, backend=None, target=None, preferGpu=False) |
cv.dnn.readNet for ONNX, TFLite, TF, Caffe and Darknet on any path; FileNotFoundError instead of a C++ assertion. |
dnn.readClassNames(path) |
The class names of a .names/.txt file, one per line. |
dnn.preprocessImage(src, size, letterboxPad=True, color=(114, 114, 114), scale=1 / 255, mean=(0, 0, 0), swapRB=True) |
Letterbox + blobFromImage. Returns (blob, PreprocessInfo(scale, pad, inputSize, originalSize)). |
dnn.inferImage(net, src, outputNames=None, size=None) |
setInput + forward for every output layer, from a blob or an image. Returns a list of arrays. |
dnn.postprocessDetections(output, info, scoreThreshold=0.25, iouThreshold=0.45, maxCount=None, boxFormat="cxcywh", hasObjectness=False, ...) |
Decode YOLO-style output ((1, N, 4 + C) or transposed), undo the letterbox, per-class NMS. Returns Detections(boxes, scores, classIds) on the original image. |
dnn.postprocessClassification(output, topK=5, softmax=True) |
[(classId, score), ...] for the best topK classes. |
dnn.softmax(x, axis=-1), dnn.sigmoid(x) |
Numerically stable activations for raw outputs. |
dnn.drawDetections(src, detections, classNames=None, colors=None, thickness=2, showScore=True, fontPath=None) |
Boxes with class names and scores, one color per class, as a new image. Unicode names with fontPath. |
highgui
| Function | Description |
|---|---|
imshowInline(img, maxSize=None) |
Show an image in a Jupyter notebook, in its real colors (no BGR/RGB mix-up). |
imshowEx(winname, img, maxSize=(1280, 720)) |
cv.imshow that shrinks images larger than the screen. |
flag
Named constants for magic numbers that OpenCV takes without a constant of its own.
| Constant | Value | Use |
|---|---|---|
FLIP_MODE_X, FLIP_MODE_Y, FLIP_MODE_XY |
0, 1, -1 |
cv.flip(src, flipCode) |
DDEPTH_SAME |
-1 |
ddepth of cv.filter2D, cv.Sobel, ...: same depth as the source |
ALL_CONTOURS |
-1 |
contourIdx of cv.drawContours |
REDUCE_TO_ROW, REDUCE_TO_COL |
0, 1 |
dim of cv.reduce |
WAIT_FOREVER |
0 |
delay of cv.waitKey |
KEY_ESC, KEY_ENTER, KEY_SPACE, KEY_TAB, KEY_BACKSPACE |
27, 13, 32, 9, 8 |
Return value of cv.waitKey |
Development
See CONTRIBUTING.md. Release notes are in CHANGELOG.md. Please follow the Code of Conduct, and report security issues as described in SECURITY.md. To cite this project, use CITATION.cff (GitHub shows a "Cite this repository" button).
Authors
Daehee Yun (s076923@gmail.com)
License
1 maintainer

Metadata
1 maintainer
Release files for python-opencv-utils 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| python_opencv_utils-1.0.0.tar.gz | 360.5 kB | With provenance | Details for python_opencv_utils-1.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| python_opencv_utils-1.0.0-py3-none-any.whl | Python 3 | none | any | Details for python_opencv_utils-1.0.0-py3-none-any.whl |
Total release size: 596.1 kB
Release files / python_opencv_utils-1.0.0.tar.gz
| Download URL | python_opencv_utils-1.0.0.tar.gz |
|---|---|
| Size | 360.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
63258ef223df27e29d2da1e61e27a664d6b9ec0d0c47bb76c8566c862d52b73e
|
|
BLAKE2b-256 checksum How to use checksums |
4a2d3d4c1447166f53fa03d785a913cf708fa277ba6ab8bfd399f51b2c85a4f2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 8, 2026.
Transparency logRelease files / python_opencv_utils-1.0.0-py3-none-any.whl
| Download URL | python_opencv_utils-1.0.0-py3-none-any.whl |
|---|---|
| Size | 235.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
be5c9231ff5a3927d81c78f3bf46082bdb96003125beb4c758136df7b242153b
|
|
BLAKE2b-256 checksum How to use checksums |
4b0ca797f882e39753d18cec0b602ebfd3adaa95374520a7efdc48248ce766ca
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 8, 2026.
Transparency logSecurity for python-opencv-utils 1.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for python_opencv_utils-1.0.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 8, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














