


What is qjax?
Most machine learning tools quietly assume a single shape for randomness and uncertainty: the bell curve, softmax attention, Shannon entropy. These are baked in as fixed rules, and real data often doesn't follow them. Labels are noisy, outcomes have heavy tails, and attention sometimes needs to focus sharply on a few inputs instead of spreading weight over everything. qjax replaces that fixed rule with a single tunable parameter, q, so these familiar tools can stretch to fit the data instead of forcing the data to fit them. Because q is fully differentiable, a model can learn the right setting during training instead of you having to guess it. In practice this means classifiers that resist memorizing mislabeled data, distributions that capture heavy tails a standard Gaussian would miss, and attention that can be as sparse or as dense as the problem needs, all as drop-in JAX functions compatible with jit, vmap, and the training code you already have.
Tsallis (non-extensive) statistics generalizes Boltzmann–Gibbs–Shannon statistics through a single entropic index $q$. As $q \to 1$ every construction collapses back to its classical counterpart (Shannon entropy, the Gaussian, softmax, the Kullback–Leibler divergence), while $q \neq 1$ opens up heavy tails, sparse attention, and tunable exploration.
qjax exposes these $q$-deformed primitives as pure, differentiable, jit/vmap-friendly JAX functions. Because $q$ is just another argument, you can hold it fixed or learn it end-to-end by gradient descent.
import jax, jax.numpy as jnp
import qjax

# q-deformed functions (recover log / exp as q -> 1)
qjax.q_log(2.0, q=1.5)
qjax.q_exp(1.0, q=1.5)

# Tsallis information measures
p = jnp.array([0.5, 0.3, 0.2])
qjax.tsallis_entropy(p, q=2.0)         # -> Shannon entropy as q -> 1
qjax.tsallis_divergence(p, p, q=2.0)   # -> KL divergence as q -> 1

# q-Gaussian distribution (heavy-tailed for 1 < q < 3)
x = jnp.linspace(-4, 4, 100)
qjax.q_gaussian_pdf(x, q=1.5, beta=1.0)
samples = qjax.sample(jax.random.PRNGKey(0), q=1.5, beta=1.0, shape=(1000,))

# Sparse softmax: q=1 -> softmax, q=2 -> sparsemax (exact zeros)
qjax.tsallis_entmax(jnp.array([2.0, 1.0, -1.0]), q=2.0)
Contents
- Building blocks
- A learnable
q - Label-noise robustness
- Statistical physics
- Installation
- Contributing
- License
Building blocks
qjax is organized as a small set of composable, fully differentiable primitives. Each is a pure function of $(x, q)$. Every primitive is a single closed form in the entropic index $q$, and each recovers its Boltzmann–Gibbs–Shannon counterpart in the $q \to 1$ limit:
qjax |
Definition | Limit $q \to 1$ |
|---|---|---|
q_log |
$\ln_q x = \dfrac{x^{1-q} - 1}{1 - q}$ | $\ln x$ |
q_exp |
$\exp_q x = \big[1 + (1-q),x\big]_+^{\frac{1}{1-q}}$ | $e^{x}$ |
tsallis_entropy |
$S_q(p) = \dfrac{1 - \sum_i p_i^{,q}}{q - 1}$ | $-\sum_i p_i \ln p_i$ |
tsallis_cross_entropy |
$H_q(y, p) = -\sum_i y_i \ln_q p_i$ | $-\sum_i y_i \ln p_i$ |
tsallis_divergence |
$D_q(p ,\Vert, r) = \dfrac{\sum_i p_i^{,q}, r_i^{,1-q} - 1}{q - 1}$ | $\mathrm{KL}(p ,\Vert, r)$ |
q_gaussian_pdf |
$\mathcal{G}_q(x) = \dfrac{\sqrt{\beta}}{C_q},\exp_q(-\beta x^2)$ | $\sqrt{\tfrac{\beta}{\pi}},e^{-\beta x^2}$ |
tsallis_entmax |
$entmax_q(z) = \arg\max_{p \in \Delta},\langle p, z\rangle + S_q(p)$ | $softmax(z)$ |
where $[,\cdot,]_+ = \max(\cdot, 0)$ is the Tsallis cut-off, $C_q$ the $q$-Gaussian normalization, and $\Delta$ the probability simplex
(tsallis_entmax is exactly sparsemax at $q = 2$).
qjaxis a research library. The numerics are tested across the $q \to 1$ limit, gradients, andjit/vmap, but the API may still evolve.
Deformed functions and $q$-algebra
q_log and q_exp are inverse deformations of log/exp; the accompanying $q$-algebra turns them into homomorphisms (q_log(a·b) = q_add(q_log a, q_log b)).
qjax.q_log(x, q=1.5)                                   # (x**(1-q) - 1) / (1-q)
qjax.q_add(qjax.q_log(2.0, 1.4), qjax.q_log(3.0, 1.4), 1.4)   # == q_log(6.0, 1.4)
Information measures
p = jnp.array([0.5, 0.3, 0.2])
r = jnp.array([0.25, 0.25, 0.5])

qjax.tsallis_entropy(p, q=2.0)           # -> Shannon entropy as q -> 1
qjax.tsallis_cross_entropy(p, r, q=2.0)  # q-deformed cross-entropy loss
qjax.tsallis_divergence(p, r, q=2.0)     # -> KL(p || r) as q -> 1
The $q$-Gaussian
A maximum-Tsallis-entropy distribution: heavy-tailed (Student-$t$) for $1 < q < 3$, compactly supported for $q < 1$, Gaussian at $q = 1$.
x = jnp.linspace(-4, 4, 100)
qjax.q_gaussian_pdf(x, q=1.5, beta=1.0)
qjax.q_gaussian_logpdf(x, q=1.5, beta=1.0)
qjax.sample(jax.random.PRNGKey(0), q=1.5, beta=1.0, shape=(1000,))
Sparse activations
tsallis_entmax spans the whole family: $q = 1$ is softmax, $q = 2$ is sparsemax
(exact zeros), larger $q$ is sparser still, and $q < 1$ is denser than softmax.
A drop-in for sparse attention, with exact gradients w.r.t. both $z$ and $q$.
z = jnp.array([2.0, 1.0, 0.1, -1.0])
qjax.tsallis_entmax(z, q=0.5)   # denser than softmax
qjax.tsallis_entmax(z, q=1.0)   # softmax
qjax.tsallis_entmax(z, q=2.0)   # sparsemax (exact zeros)
A learnable $q$
Because $q$ is an ordinary differentiable argument, it is finite everywhere, including the $q = 1$ limit, so it can be optimized like any other parameter:
import jax

x = jnp.linspace(-3, 3, 200)
nll = lambda q: -jnp.mean(qjax.q_gaussian_logpdf(x, q, 1.0))
grad_q = jax.grad(nll)(1.5)     # well-defined gradient w.r.t. the entropic index
This is what makes $q$ more than a hyperparameter: the right amount of non-extensivity can be discovered from data.
Label-noise robustness
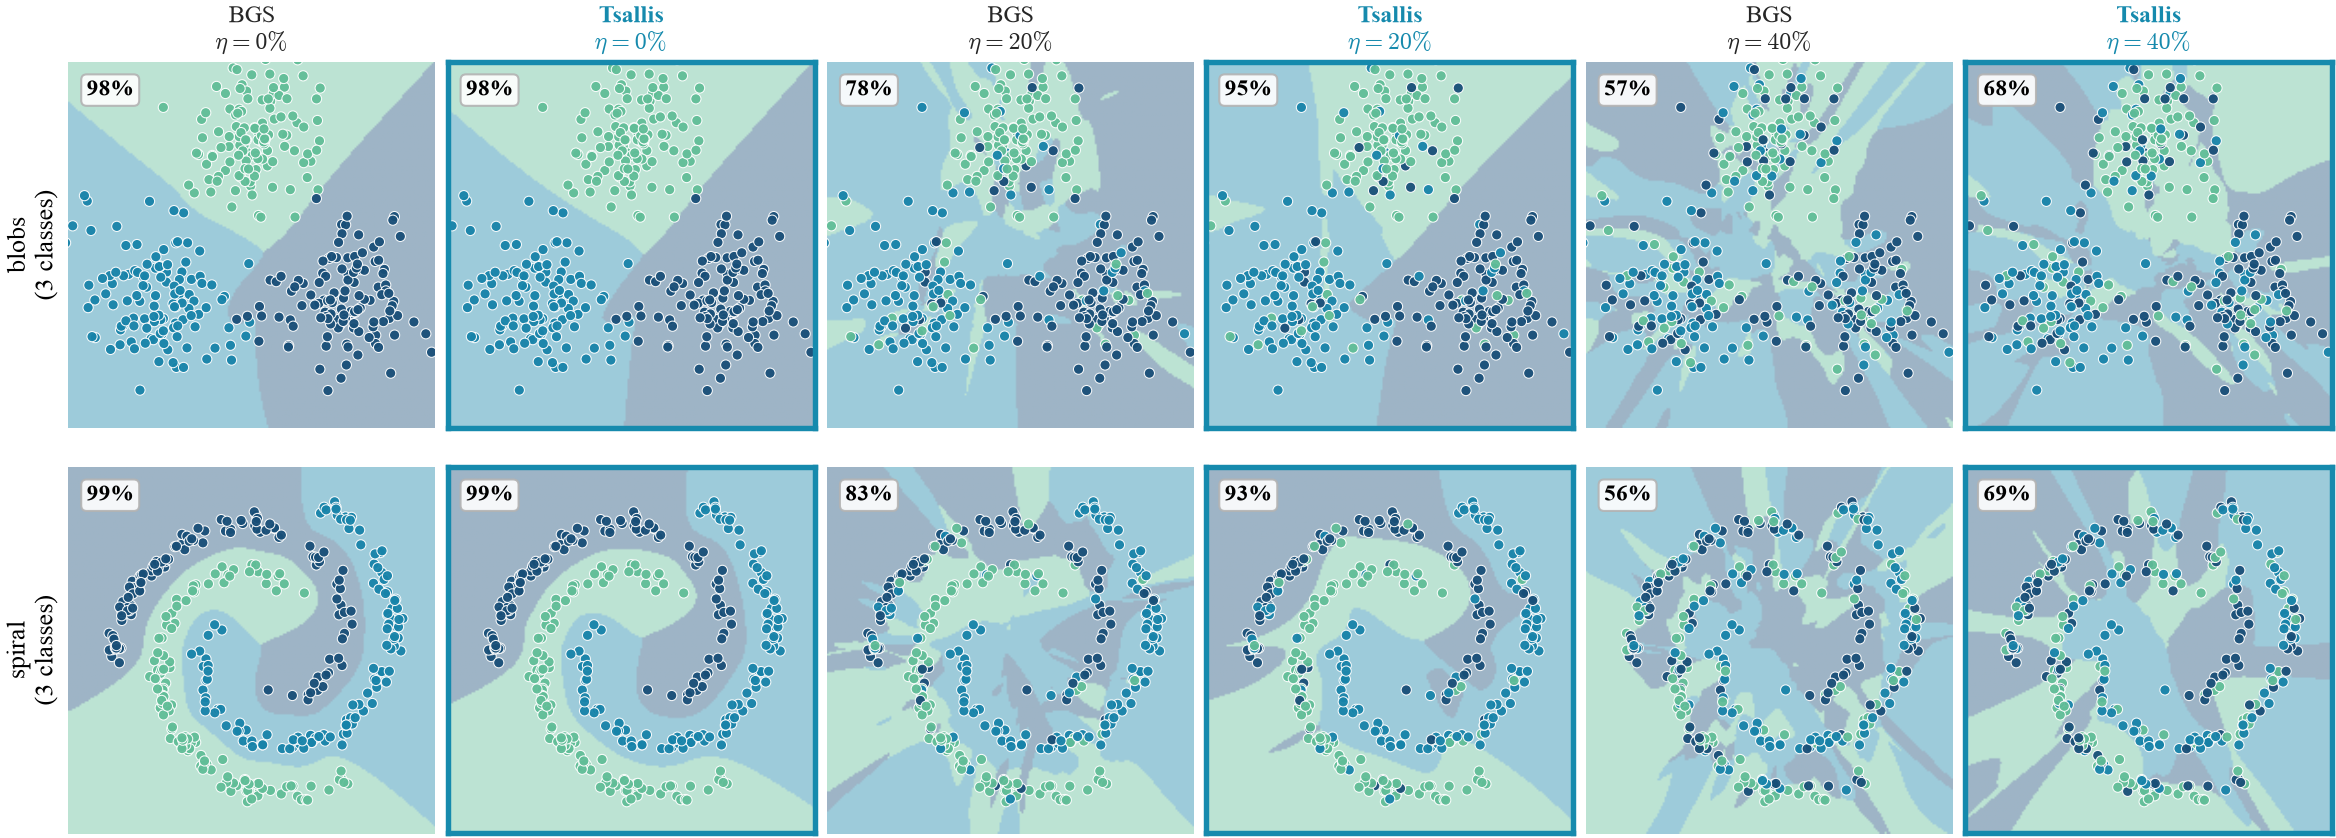
When training labels are noisy, ordinary softmax cross-entropy is unbounded: a confidently mislabeled example incurs an arbitrarily large loss, so an over-parameterized network ends up memorizing the noise. Replacing the logarithm with the deformed $q$-logarithm gives the Tsallis cross-entropy, which is bounded for $q < 1$: its gradient saturates on unfittable points, so the model ignores label noise instead of fitting it.
For a one-hot target with true class $c$ and softmax probabilities $p$,
$$\mathcal{L}_q(p, c) = -\ln_q p_c = \frac{1 - p_c^{,1-q}}{1 - q}, \qquad \ln_q x = \frac{x^{1-q} - 1}{1 - q}.$$
As $q \to 1$ this is exactly the standard cross-entropy $-\log p_c$; for $q < 1$ the per-example loss is bounded above by $1/(1-q)$, so mislabeled points cannot dominate the gradient.
The figure trains a small 3-class classifier on two shapes (blobs, spiral) from clean data up to 40% label noise, comparing the Boltzmann–Gibbs–Shannon baseline ($q = 1$) with Tsallis ($q = 0.3$). The comparison is fair: both share the same initialization, data, noisy labels and optimizer, and only $q$ differs. Without noise the two match (≈98–99%); as noise grows the baseline carves spurious wrong-class islands while Tsallis keeps clean regions and higher accuracy.
See the classification example for the full setup.
Statistical physics
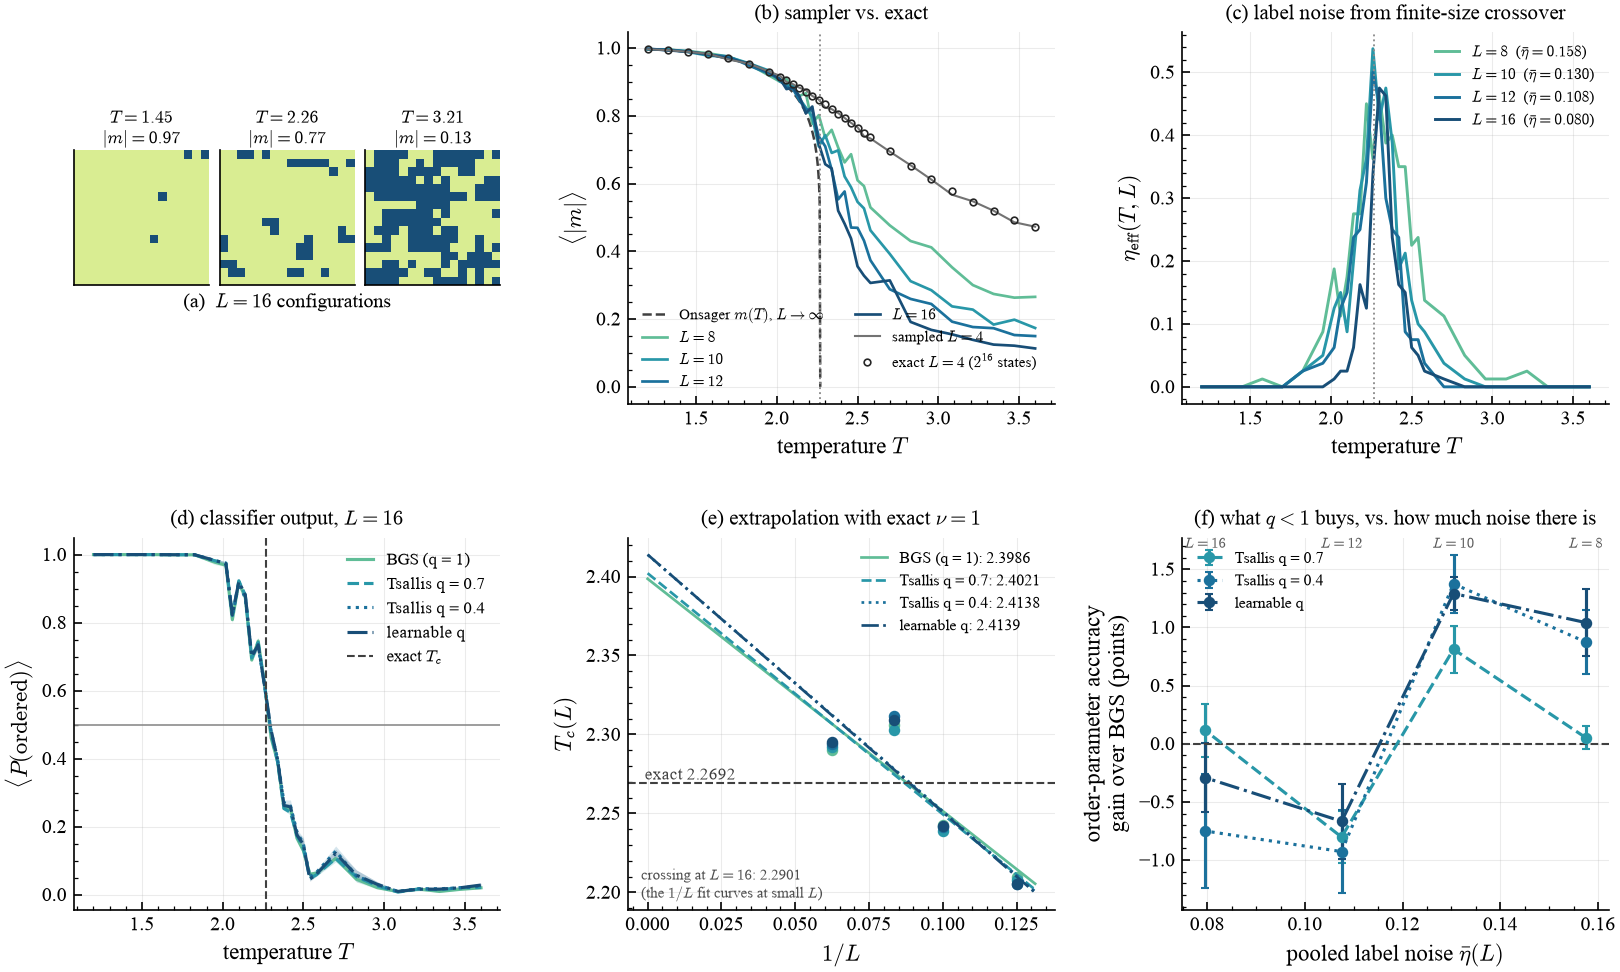
qjax.physics pairs the q-primitives with the systems they are meant to
describe, each with something exact to be checked against: Onsager's closed
forms for the 2-D Ising model, a transfer matrix, exhaustive enumeration of a
whole state space, the tabulated Lennard-Jones cluster minima, and the anomalous
diffusion scaling relation $\alpha = 2/(3-q)$.
import qjax.physics as qp

qp.ISING_TC                      # 2 / ln(1 + sqrt 2) = 2.2691853, exact
configurations = qp.sample_ising(key, size=16, temperatures=grid,
                                 num_samples=80, sweeps=700)
qp.onsager_free_energy_per_site(2.5)          # exact, thermodynamic limit
qp.ising_transfer_matrix_log_z(8, 2.5)        # exact, finite lattice
qp.sk_exact_observables(couplings, 0.4)       # all 2**N states, streamed

# The Tsallis-Stariolo annealing schedule is a ratio of two q-logarithms, so its
# q -> 1 limit is the Geman-Geman log schedule *exactly*, with no branch on q.
qp.visiting_temperature(step, initial=0.9, q_visit=1.0)
Five examples build on it — and report negative results where that is what the numbers say:
| example | the physics | measured against |
|---|---|---|
| Ising phases and $T_c$ | finite-size crossover as physical label noise | Onsager $T_c$ (0.6 %), $\nu$ and $\beta$ (3 %) |
| Variational free energy at $q$ | nonextensive variational autoregressive networks | two independent exact codes; $(q-1)N$ collapse |
| Generalized simulated annealing | Tsallis & Stariolo (1996) on LJ clusters | closed forms and the Cambridge Cluster Database |
| Anomalous diffusion | $q$ as a measured quantity | exact stationary $q$; Lutz's cold-atom law |
| Heavy-tailed PINN residuals | an ICML 2026 Student-$t$ residual model, read as Tsallis | the closed-form solution; score correspondence to $10^{-15}$ |
Neural-network building blocks
qjax.nn holds the pieces that every Tsallis model ends up needing. It is
framework-agnostic, using plain arrays and pytrees, so it composes with Flax,
Equinox, Haiku, or hand-rolled JAX without pulling in any of them.
from qjax.nn import bounded_q, entmax_attention, tsallis_cross_entropy_loss

# Keep a learnable q inside its valid range, whatever the optimizer does.
q = bounded_q(params["q_raw"], 1.0, 3.0)

# Attention normalized by entmax instead of softmax.
context, attn = entmax_attention(queries, keys, values, q=q)

# A q-deformed classification loss; q < 1 bounds the penalty on bad labels.
loss = tsallis_cross_entropy_loss(logits, targets, q=0.5, normalizer_q=1.0)
Installation
qjax requires Python 3.10+ and depends only on jax. Plotting is optional. It is managed with uv.
| Use case | Command |
|---|---|
| As a dependency | uv add qjax |
| With plotting | uv add "qjax[plots]" (adds matplotlib) |
| Development | uv sync --extra dev (tests + linter + mypy) |
| Building the docs | uv sync --extra docs (Material for MkDocs) |
For GPU/TPU acceleration, install the matching JAX build by following the JAX installation guide.
Contributing
Contributions are welcome: new $q$-deformed primitives, examples, docs, and fixes. See CONTRIBUTING.md for the development setup, design principles (purity, the $q \to 1$ limit, finite gradients), and the checks CI runs.
Cite this work
@misc{dacosta2026tsallis,
      title={Perspectives on Tsallis Statistics for Artificial Intelligence},
      author={Kleyton da Costa and Bernardo Modenesi},
      year={2026},
      eprint={2608.01223},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2608.01223},
}
License
Released under the MIT License.
1 maintainer

Release files for qjax 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| qjax-0.2.0.tar.gz | 14.7 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| qjax-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 14.8 MB
Release files / qjax-0.2.0.tar.gz
| Download URL | qjax-0.2.0.tar.gz |
|---|---|
| Size | 14.7 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
69c4e002af6d9944bf422bd0900adb7a24bb94a3b53507c114f9ac4dcb334767
|
|
BLAKE2b-256 checksum How to use checksums |
2352041427e6a6fe3920032cfa05f2a9f6917692408fa4e1f72090ee1020712b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 2, 2026.
Transparency logRelease files / qjax-0.2.0-py3-none-any.whl
| Download URL | qjax-0.2.0-py3-none-any.whl |
|---|---|
| Size | 67.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e9838f752e047d7d84d64302b547af2893c51f998b6d796781e5063bf56e6f19
|
|
BLAKE2b-256 checksum How to use checksums |
7d397ad6b09e3dfacb60e64019a82c9c4bc4cdfdeb417ca9729508770ae0a2af
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 2, 2026.
Transparency log













