
Raw Speech Classification

Trains CNN (or any neural network based) classifiers from raw speech using Keras and tests them. The inputs are lists of wav files, where each file is labelled. It then creates fixed length signals and processes them. During testing, it computes scores at the utterance or speaker levels by averaging the corresponding frame-level scores from the fixed length signals.
Installation
Installing from PyPI
If you want to install the last release of this package in your current environment (we recommend using Conda to manage virtual environments, e.g. to have a specific version of Python), you can run either of the following commands, depending on your desired framework:
pip install raw-speech-classification[torch]
or
pip install raw-speech-classification[tensorflow]
or
pip install raw-speech-classification[jax]
If you already have an environment with PyTorch, TensorFlow, or Jax installed, you can simply run:
pip install raw-speech-classification
Installing from source in a virtual environment
To install the following repository from source, clone this repository, then run (according to the Keras backend you desire):
pip install -e .[torch]
or
pip install -e .[tensorflow]
or
pip install -e .[jax]
You will also need to set the KERAS_BACKEND environment variable to
the correct backend before running rsclf-train or rsclf-test (see
below), or globally for the current bash session with:
export KERAS_BACKEND=torch
Replace torch by tensorflow or jax accordingly.
Using the code
-
Create lists for training, cross-validation and testing. Each line in a list must contain the path to a wav file (relative to the
-Ror--rootoption), followed by its integer label indexed from 0, separated by a space. E.g. if your data files are in/home/bob/data/my_dataset/part*/file*.wav, therootoption could be/home/bob/data/my_datasetand the content of the files would then be like:part1/file1.wav 1 part1/file2.wav 0
Full list files for IEMOCAP are available in the repository as example in
datasets/IEMOCAP/F1_lists. -
You can now run the following commands (use the
--helpoption of each command to get more details):rsclf-wav2feat --wav-list-file list_files/cv.list --feature-dir output/cv_feat --mode train --root path/to/dataset/basedir rsclf-wav2feat --wav-list-file list_files/train.list --feature-dir output/train_feat --mode train --root path/to/dataset/basedir rsclf-wav2feat --wav-list-file list_files/test.list --feature-dir output/test_feat --mode test --root path/to/dataset/basedir KERAS_BACKEND=torch rsclf-train --train-feature-dir output/train_feat --validation-feature-dir output/cv_feat --output-dir output/cnn_subseg --arch subseg --splice-size 25 --verbose 2 KERAS_BACKEND=torch rsclf-test --feature-dir output/test_feat --model-filename output/cnn_subseg/cnn.keras --output-dir output/cnn_subseg --splice-size 25 --verbose 0 rsclf-plot --output-dir output/ output/cnn_subseg
Using run.sh (only with Conda)
run.sh allows to run all these steps in one command when using Conda as virtual
environment manager. This examples shows how to use the IEMOCAP lists shipped in the
repository:
bash run.sh -C ~/miniforge3 -n rscl -D datasets/IEMOCAP/F1_lists -a seg -o results/seg-f1 -R <IEMOCAP_DATA_ROOT>
Replace <IEMOCAP_DATA_ROOT> by the path to the IEMOCAP data directory containing
IEMOCAP_full_release/Session*.
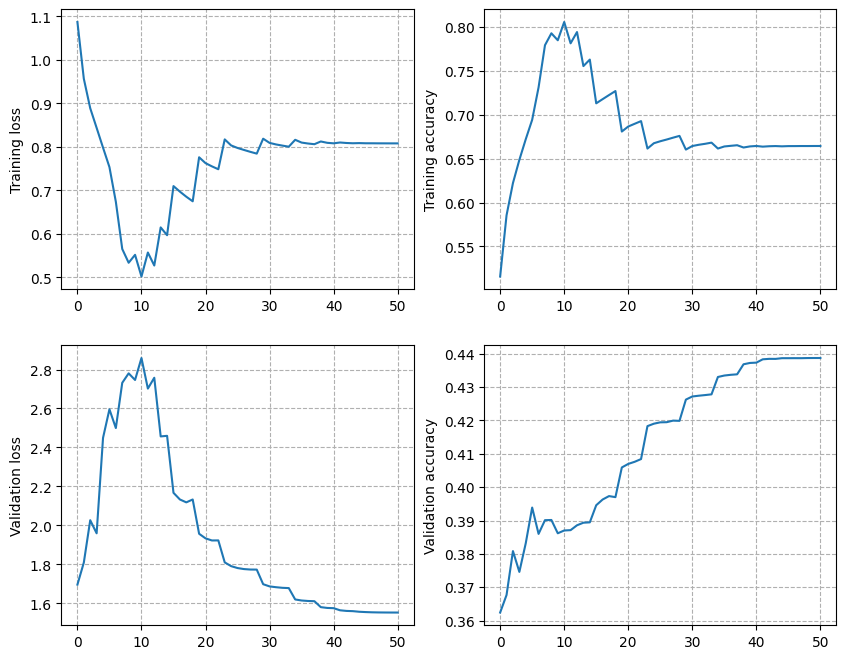
Here is an example of the log printed to the terminal, and you should
obtain the following curve in results/seg-f1/plot.png:
Code components
-
wav2feat.pycreates directories where the wav files are stored as fixed length frames for faster access during training and testing. -
train.pyis the Keras training script. -
Model architecture can be configured in
model_architecture.py. -
rawdataset.pyprovides an object that reads the saved directories in batches and retrieves mini-batches for training. -
test.pyperforms the testing and generates scores as posterior probabilities. If you need the results per speaker, configure it accordingly (see the script for details). The default output format is:<speakerID> <label> [<posterior_probability_vector>]
-
plot.pygenerates and saves the learning curves.
Training schedule
The script uses stochastic gradient descent with 0.5 momentum. It starts with a learning rate of 0.1 for a minimum of 5 epochs. Whenever the validation loss reduces by less than 0.002 between successive epochs, the learning rate is halved. Halving is performed until the learning rate reaches 1e-7.
Contributors
Idiap Research Institute
Authors: S. Pavankumar Dubagunta and Dr. Mathew Magimai-Doss
License
GNU GPL v3
1 maintainer

Metadata
1 maintainer
Release files for raw-speech-classification 1.0.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| raw_speech_classification-1.0.4.tar.gz | 24.7 kB | With provenance | Details for raw_speech_classification-1.0.4.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| raw_speech_classification-1.0.4-py3-none-any.whl | Python 3 | none | any | Details for raw_speech_classification-1.0.4-py3-none-any.whl |
Total release size: 51.2 kB
Release files / raw_speech_classification-1.0.4.tar.gz
| Download URL | raw_speech_classification-1.0.4.tar.gz |
|---|---|
| Size | 24.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
df1e0c1e57f37bc8cb9eeec53e2dac0d40cc2e7e0d86c7ee9d10c2d4c5dcfc6a
|
|
BLAKE2b-256 checksum How to use checksums |
7e195ff46c856b35d7f90812878cc80a6057981c430daedd400ab5e185638be5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.12.9
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Apr 10, 2025.
Transparency logRelease files / raw_speech_classification-1.0.4-py3-none-any.whl
| Download URL | raw_speech_classification-1.0.4-py3-none-any.whl |
|---|---|
| Size | 26.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7918022d893e85d410d920d6dc7cfb7276172b65fd7dd6cfe842062ac306b1e9
|
|
BLAKE2b-256 checksum How to use checksums |
c1f359a20e7bd19e115781d7e54d3b59e68c47cfe55629ebd7d1366fdad02ade
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.12.9
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Apr 10, 2025.
Transparency logSecurity for raw-speech-classification 1.0.4
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for raw_speech_classification-1.0.4.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Apr 10, 2025.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














