
runboard
Pre-registered machine-learning experiments, from the plan to the paper.
runboard is a dashboard you run on your own computer. You write down what your study asks and what you expect before training anything, lock that plan, run the experiments on your GPU, Kaggle, a rented machine over SSH or a university SLURM cluster, and watch them live. When the evaluations are in, runboard decides each hypothesis with a bootstrap confidence interval (supported, refuted or indistinguishable) and writes the tables, the methods and deviations sections and a reproducibility checklist for your paper.
Everything is a readable file in your project folder and goes into git: no account, no server, no hidden database.
Contents
- Why
- Try it in five minutes
- How a study works
- What is in a project
- Writing hypotheses
- Where runs go
- Features
- Command line
- Tablets and security
- Running it permanently
- Your own training script
- Development
Why
Most ML papers decide what counts as a success after seeing the numbers: a different metric, another seed, one more baseline. Experiment trackers record what happened; they do not record what you expected, so a reader cannot tell a confirmed hypothesis from a story told afterwards.
runboard keeps the two apart:
| Before training | After training |
|---|---|
| Questions, hypotheses written as criteria a machine can check, the evaluation protocol | Each criterion computed on the evaluations, with a 95 % interval over bootstrap replicates |
| A lock: the time, the git commit and fingerprints of the plan, the runs and the scripts | Every later change of the plan, with its reason, as a deviation |
| A sealed test set | A ledger of every evaluation on it |
The rest (launching runs, live progress, queues, results tables) is there so that one tool covers the whole study.
Try it in five minutes
pip install runboard-ml numpy
runboard demo        # a small pre-registered study in ~/runboard-demo, added to the dashboard
runboard             # opens the dashboard at http://localhost:8000
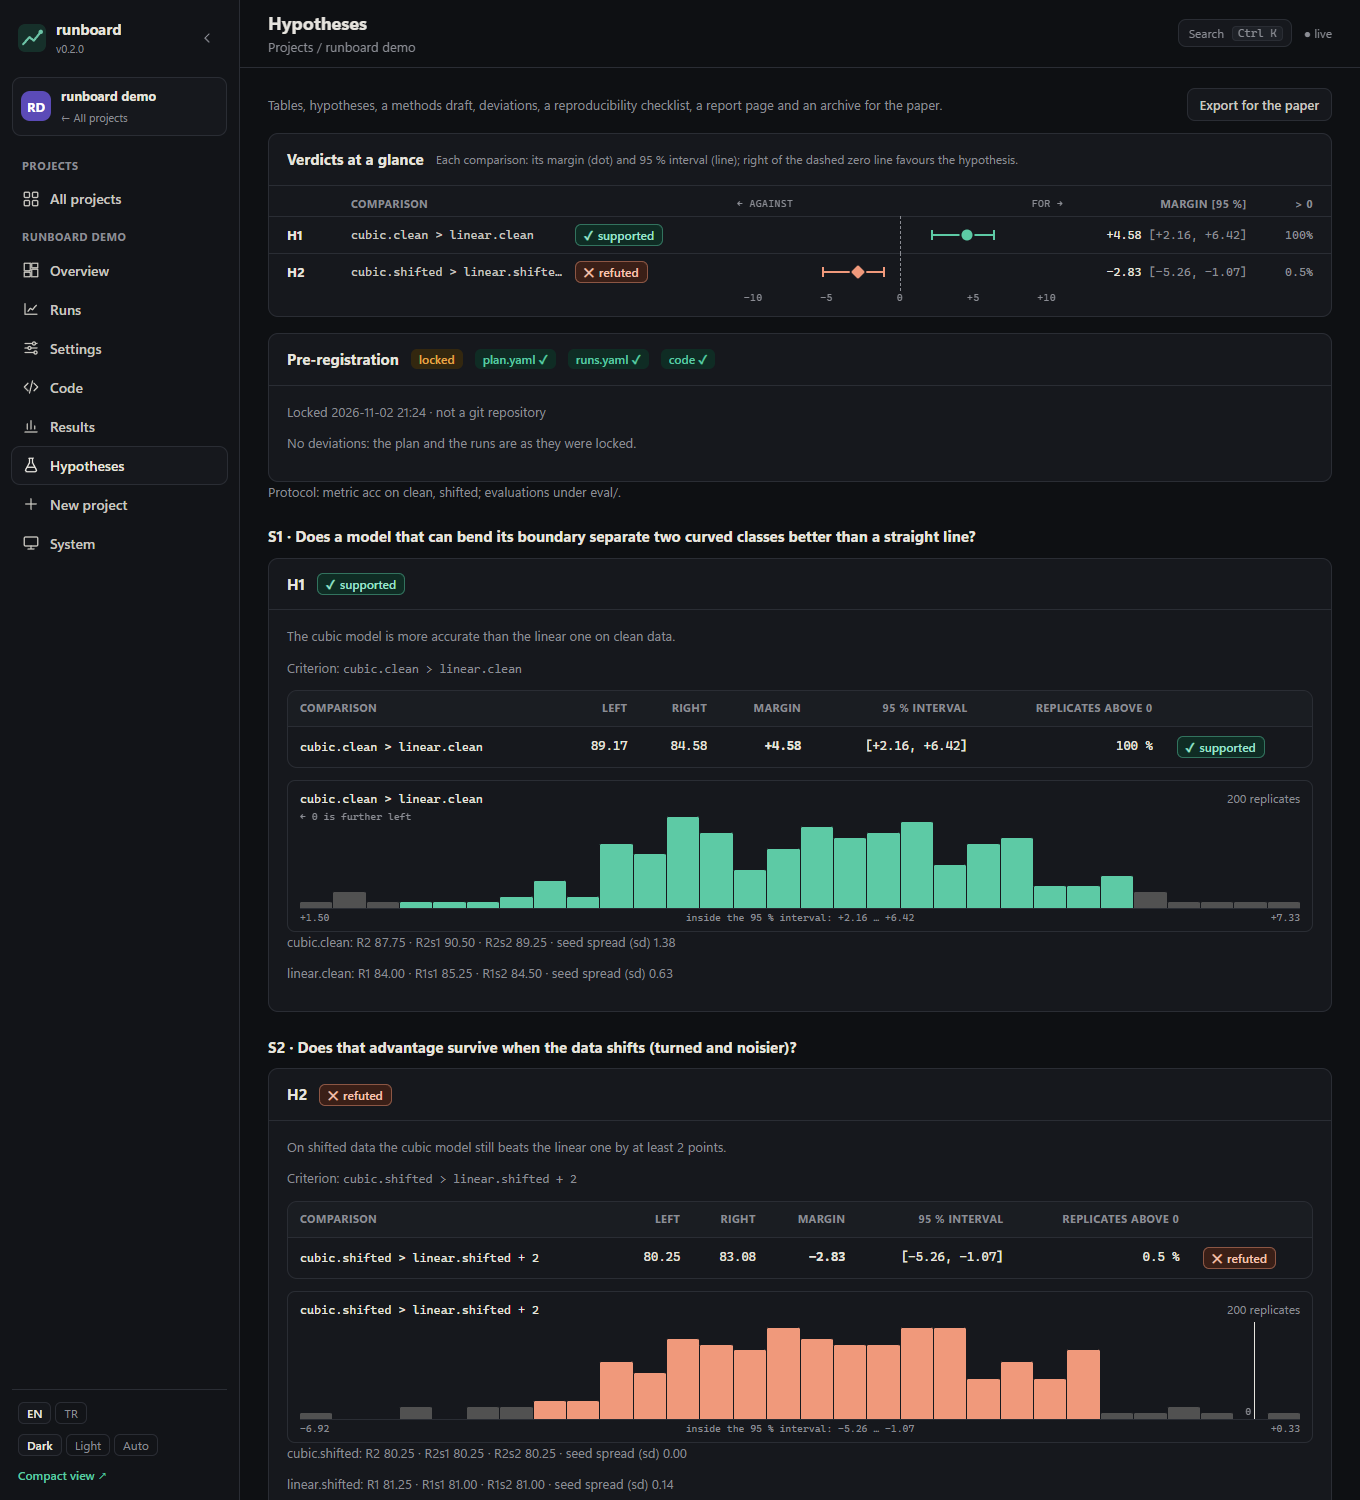
The demo needs no GPU and downloads nothing: two models (linear and cubic) on synthetic data, three seeds each, two hypotheses. Lock the plan, queue the six runs (about ten seconds each), evaluate them, and read the verdicts: one hypothesis comes out supported, the other refuted. The tutorial walks through every screen.
The package is called runboard-ml on PyPI because
runboardbelongs to another project; the command and the Python module arerunboard. Do not install both in one environment. Python 3.11 or newer;pip install "runboard-ml[kaggle]"adds the Kaggle client.
How a study works
 plan.yaml            lock              runs                 evaluation             verdicts            paper/
 questions,    ──►  plan.lock.json ──►  your GPU, Kaggle, ──►  eval/<run>/<set>  ──►  supported /   ──►  tables, methods,
 hypotheses,        commit +           SSH, SLURM;          per-run scores on     refuted /          deviations,
 protocol           fingerprints       live progress        shared replicates     indistinguishable   checklist, report
- Plan. In the dashboard (New project → Pre-registered study) or in
plan.yaml: the questions, the hypotheses, the evaluation sets and metric, and the experiment designs that become runs (R1, R2, …). - Lock. Hypotheses → Lock the plan. From here on, the plan, the runs and the evaluation scripts change only with a written reason, and each change is listed as a deviation.
- Run. Start or queue runs on any backend. The dashboard shows the log, epoch, batch, speed, metrics and time left, second by second.
- Evaluate. An evaluation script (written by runboard for YOLO, or your own) scores every run on each evaluation set. All runs share one resampling plan per set, so the k-th bootstrap replicate of every run uses the same images and comparisons between runs are paired.
- Decide. The Hypotheses page computes every criterion on the full set and on each replicate and gives the verdict with its interval.
- Report. Export for the paper writes
paper/: Markdown and LaTeX tables, the hypotheses table, a methods draft, the deviations section, a reproducibility checklist, a one-page registered report and an archive for Zenodo.
What is in a project
A project is any folder with a runboard.yaml. runboard adds a few files and never changes yours.
| File | What it holds | Locked |
|---|---|---|
runboard.yaml |
how runs start (commands, backends), what they report, phases and tables, jobs | no |
plan.yaml |
questions, hypotheses, evaluation protocol, seed groups, decisions | yes |
runs file (runs.yaml or your own) |
the runs and their shared settings, in your format | yes |
plan.lock.json |
when the plan was locked, at which commit, and the fingerprints | written once |
deviations.md |
every change after the lock, with its reason and diff | appended |
eval/ |
the shared resampling plans and each run's scores on each set | — |
| scripts from templates | split, check, subsets, evaluate, speed, convert: ordinary Python you can read and change | yes |
paper/ |
what Export for the paper writes | — |
State that is not part of the study (run records, logs, paired devices) lives in ~/.runboard, never in the project.
Writing hypotheses
A hypothesis is a sentence for people and a criterion for the machine:
hypotheses:
  - id: H1
    question: S1
    text: The ground-only model collapses on aerial images more than the aerial-only one does on ground images.
    criterion: "collapse(R4, ground, aerial) > collapse(R5, aerial, ground)"
  - id: H2
    question: S2
    text: A quarter of the aerial data reaches 90 % of the aerial specialist.
    criterion: "R7.aerial >= 0.9 * R5.aerial"
  - id: H3
    question: S2
    text: Accuracy grows with the logarithm of the aerial share.
    criterion: "log_fit({R6: 10, R7: 25, R8: 50}, aerial).r2 >= 0.9"
R7.aerial is run R7's metric on the evaluation set aerial; R7.aerial@person is one class; a seed group such as
cubic stands for the mean of its runs. Numbers, + - * /, comparisons, and, and a few functions (collapse,
mean, min, max, abs, log_fit) are allowed; nothing else is, and criteria are never run as Python. Every
criterion is checked against the planned runs and sets while you type it.
Each comparison is decided by its margin on the bootstrap replicates: supported when the whole 95 % interval is above zero, refuted when it is below, indistinguishable otherwise. The details are in the design notes.
Where runs go
| Backend | For | How |
|---|---|---|
| Local | the GPU (or CPU) of this computer | a detached process that survives dashboard restarts; can be stopped |
| Kaggle | free cloud GPUs (about 30 h a week) | private script kernels, live logs, the weekly quota in the queue, private dataset upload with forbidden-path checks; Python files are compiled before a run is sent |
| SSH | a rented GPU, a lab server | your own ssh and keys (runboard never sees a password); code sent as a tar, the run detached on the remote side, logs streamed, outputs brought home |
| SLURM | a university cluster | jobs through sbatch on the login node, followed with sacct, stopped with scancel; as many in the queue as you like |
A project can use several; each run records where it ran and what it started from (commit, uncommitted changes, fingerprints of the plan, runs, scripts and data).
Features
Planning
- Research wizard: questions, data packages, experiment designs (specialists, data-size curve, architectures, ablation, seed repeats), protocol and hypotheses become a ready project, with suggested criteria.
- Plan editing in the dashboard: edit, copy, add and remove runs, sweeps (one run per combination of values), shared settings and the whole file; every change is previewed as a diff and backed up; started runs keep their settings.
Running
- One queue across projects: each backend starts its next entry when free; Kaggle entries wait when the quota would not cover them.
- Live progress between log lines, metric and loss charts with zoom and comparison between runs, resume after a stop.
- Smoke test: one short epoch on a little data before a real run uses cloud quota.
Code
- Templates: split (seeded, keeps videos or scenes in one split), check (broken labels, leaks between splits, look-alike images), convert (COCO / VOC to YOLO), subsets (nested data-size lists), evaluate (YOLO, for the verdicts), speed. Written once from a form; rewritten only while you have not changed them.
- A Code page: read the project's files anywhere, change them on this computer, with syntax checks before saving.
Results
- Results tables and seed summaries from
runboard.yaml, the Hypotheses page with verdicts, the paper export.
Everywhere
- A tablet view (
/mini) and pairing with a QR code; English and Türkçe; light and dark.
Command line
| Command | Does |
|---|---|
runboard / runboard serve |
start the dashboard (and its watchdog) |
runboard stop |
stop both |
runboard demo [folder] |
set up the five-minute demo study |
runboard add PATH / remove PATH / list |
manage the projects on the dashboard |
runboard lock [folder] |
lock a plan |
runboard verdicts [folder] |
print every hypothesis's verdict |
runboard export [folder] |
write paper/ |
runboard template NAME [folder] --set key=value |
write a script from a template |
runboard migrate [folder] |
move an older project's decisions and lock into plan.yaml |
Tablets and security
By default runboard listens only on this computer (127.0.0.1) and asks for nothing. To follow runs from a tablet on
the same Wi-Fi, turn on System → Tablet access, press Pair a device and scan the QR code, or type the 6-digit
code (valid once, for two minutes). Paired devices can follow, start and stop runs and edit the plan; tokens, new
projects, code, the project file, locking and the folder browser stay on this computer. The Kaggle token is kept in
~/.kaggle. Outside your home network, use a VPN such as Tailscale. See
SECURITY.md.
Running it permanently
System → Start runboard when Windows starts (Windows), or a systemd/launchd service running runboard serve.
runboard serve also starts a watchdog that restarts the dashboard if it stops answering, and writes every start,
stop and error to ~/.runboard/server.log.
Your own training script
The wizard's My own training code runs any script with per-run arguments. To show live progress, print one line
per event, or use rb.py (stdlib only; the wizard and the demo copy it next to your scripts):
import rb
rb.ultralytics(model)            # Ultralytics: one line adds everything below
rb.start(epochs=100, batches=798)
rb.epoch(3, epochs=100, metrics={"map": 48.2}, best=48.2)
For hypotheses, an evaluation writes each run's scores in the shared format with rb.write_eval (values on bootstrap
replicates) or rb.write_samples (one value per item). A project by hand is a short runboard.yaml:
version: 2
name: My detector
runs: {file: configs/runs.yaml, section: runs, defaults: train, name: "{id}"}
backends:
  local:  {command: '"{python}" train.py --run {id}', output_dir: runs/local}
  slurm:  {host: login.cluster.edu, sbatch: {partition: gpu, gres: "gpu:1"}, command: 'python train.py --run {id}'}
results:
  report: "{out}/summary.json"
  metrics: {primary: map50_95}
Every option is in the reference.
Development
git clone https://github.com/alperentoker/runboard-ml
cd runboard-ml
pip install -e .[dev]
pytest                # about 200 tests, including a real headless browser when Chrome or Edge is installed
Plans: ROADMAP.md · releases: RELEASING.md · MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for runboard-ml 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| runboard_ml-0.3.0.tar.gz | 263.8 kB | With provenance | Details for runboard_ml-0.3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| runboard_ml-0.3.0-py3-none-any.whl | Python 3 | none | any | Details for runboard_ml-0.3.0-py3-none-any.whl |
Total release size: 510.1 kB
Release files / runboard_ml-0.3.0.tar.gz
| Download URL | runboard_ml-0.3.0.tar.gz |
|---|---|
| Size | 263.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d3aa75f45e5561d4309303a0a0bc2ad78cb10a6f8a5fe4edca4d813b8a5430ab
|
|
BLAKE2b-256 checksum How to use checksums |
b29abbbda182b19df88e9e8682e82cc815e73d95b690cbd370ff4d26c78accb9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 2, 2026.
Transparency logRelease files / runboard_ml-0.3.0-py3-none-any.whl
| Download URL | runboard_ml-0.3.0-py3-none-any.whl |
|---|---|
| Size | 246.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9e18f1d32a8045d92bf35b4c3c7813a9a442737b924065604c872a4c2cb4124f
|
|
BLAKE2b-256 checksum How to use checksums |
8c8f598ec5adeaf3f7ea8f9b44e87e015cbf23080bfeec7b2340c595af7d580b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 2, 2026.
Transparency logSecurity for runboard-ml 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for runboard_ml-0.3.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 2, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














