

RunRail
Give the scripts, notebooks and queries you already have schedules, retries, approvals and a full run history. One process, one SQLite file, no rewrites.




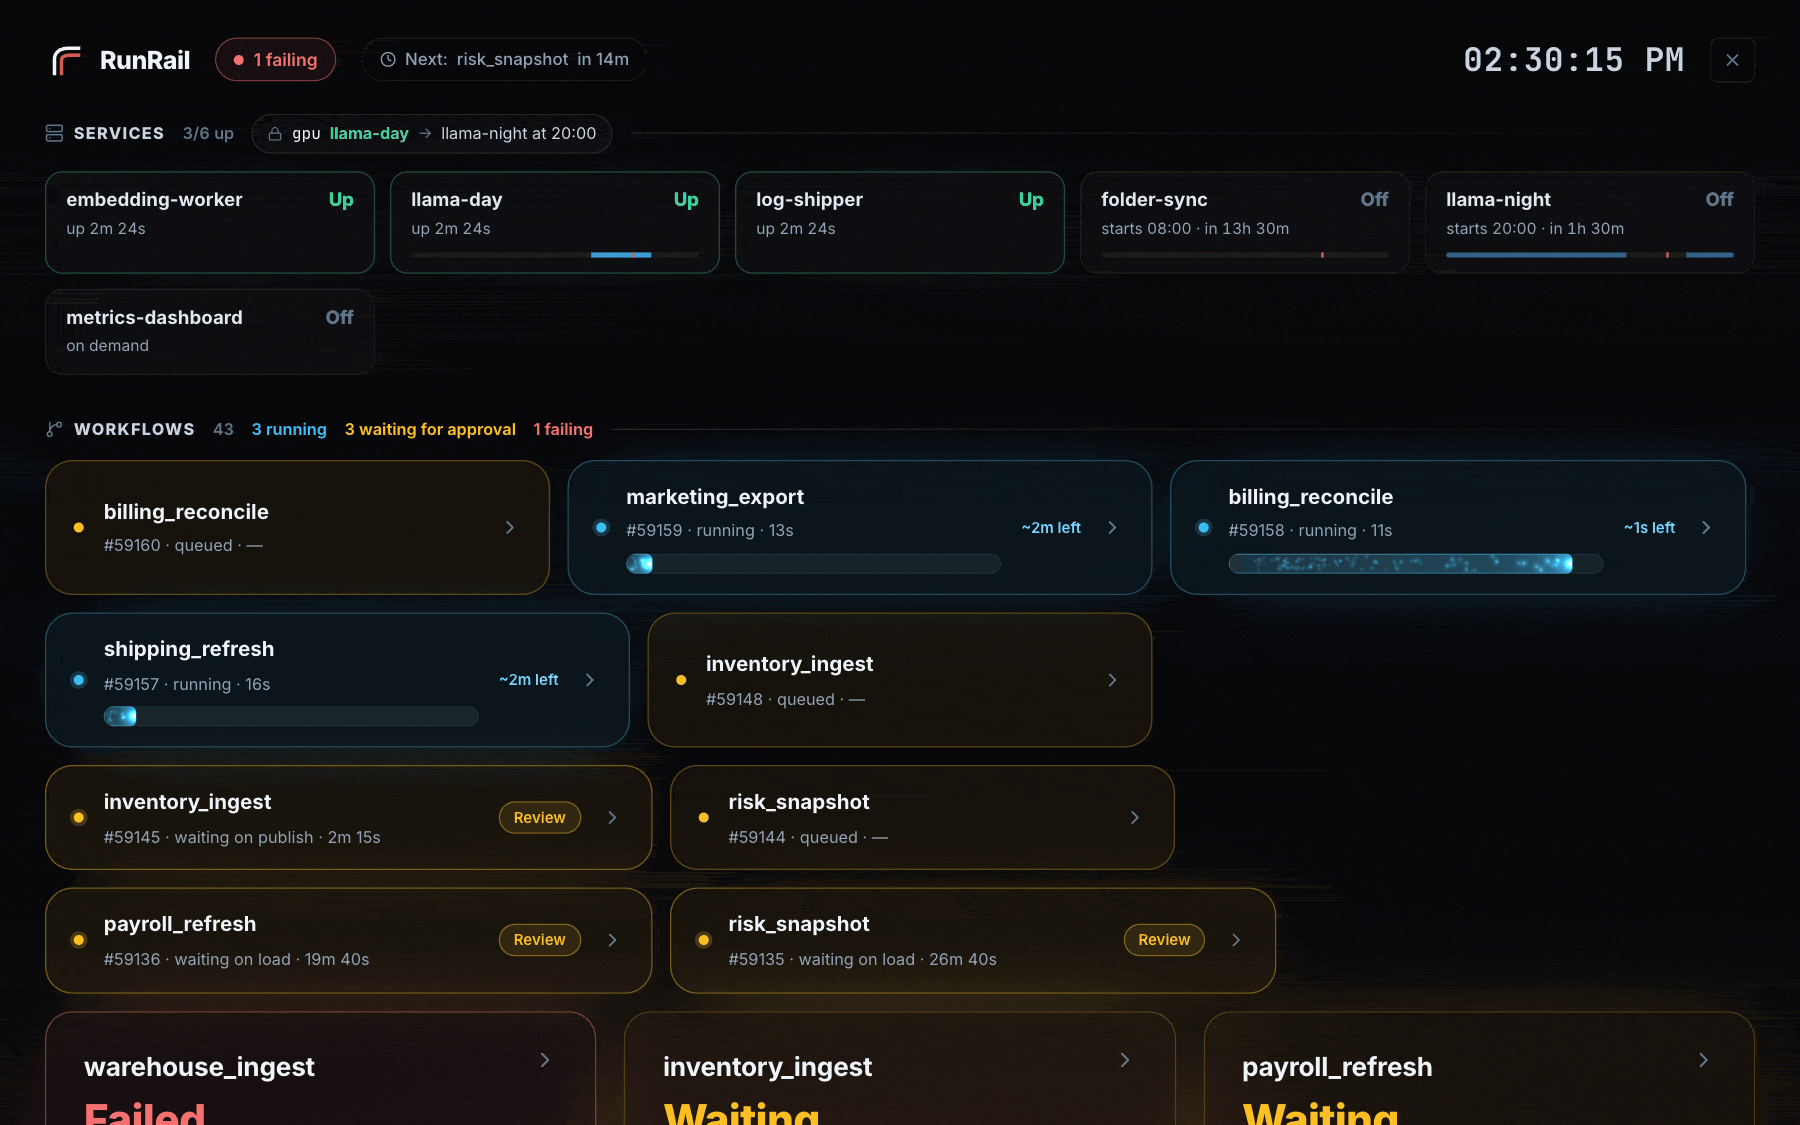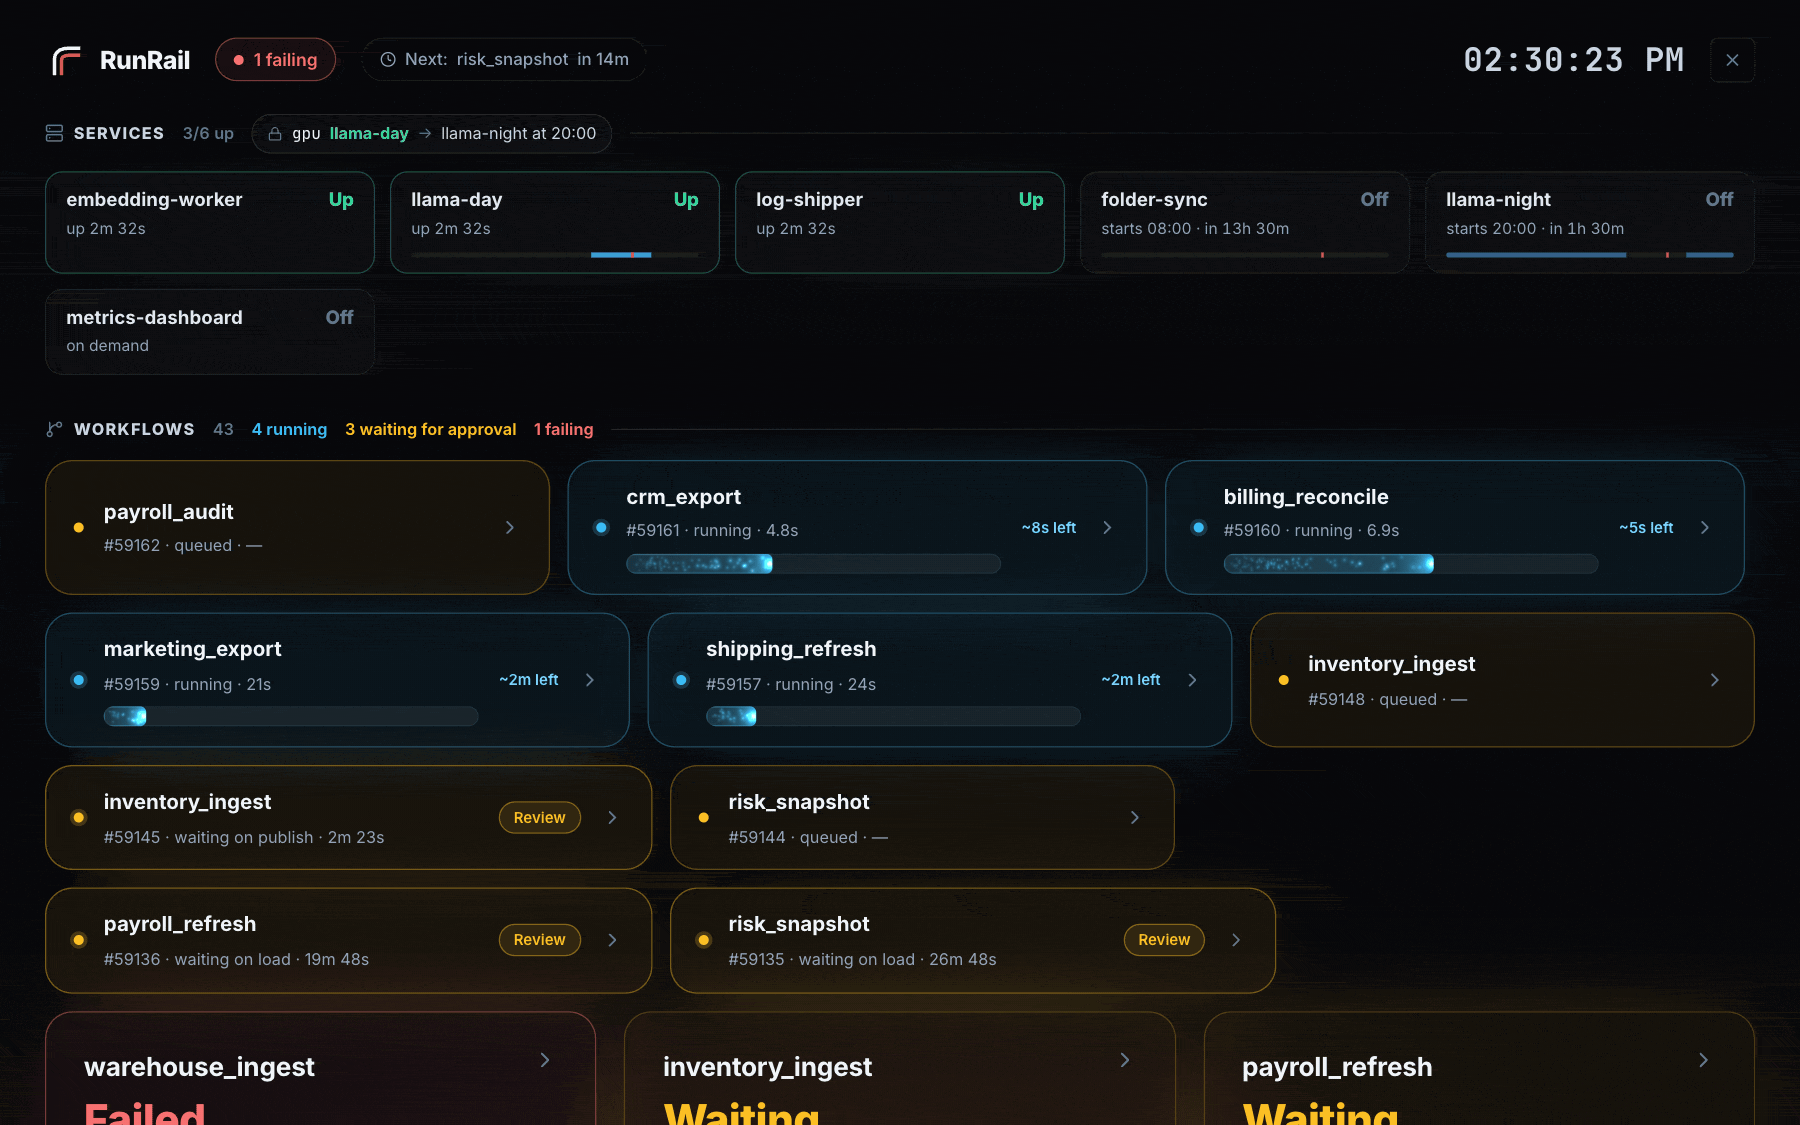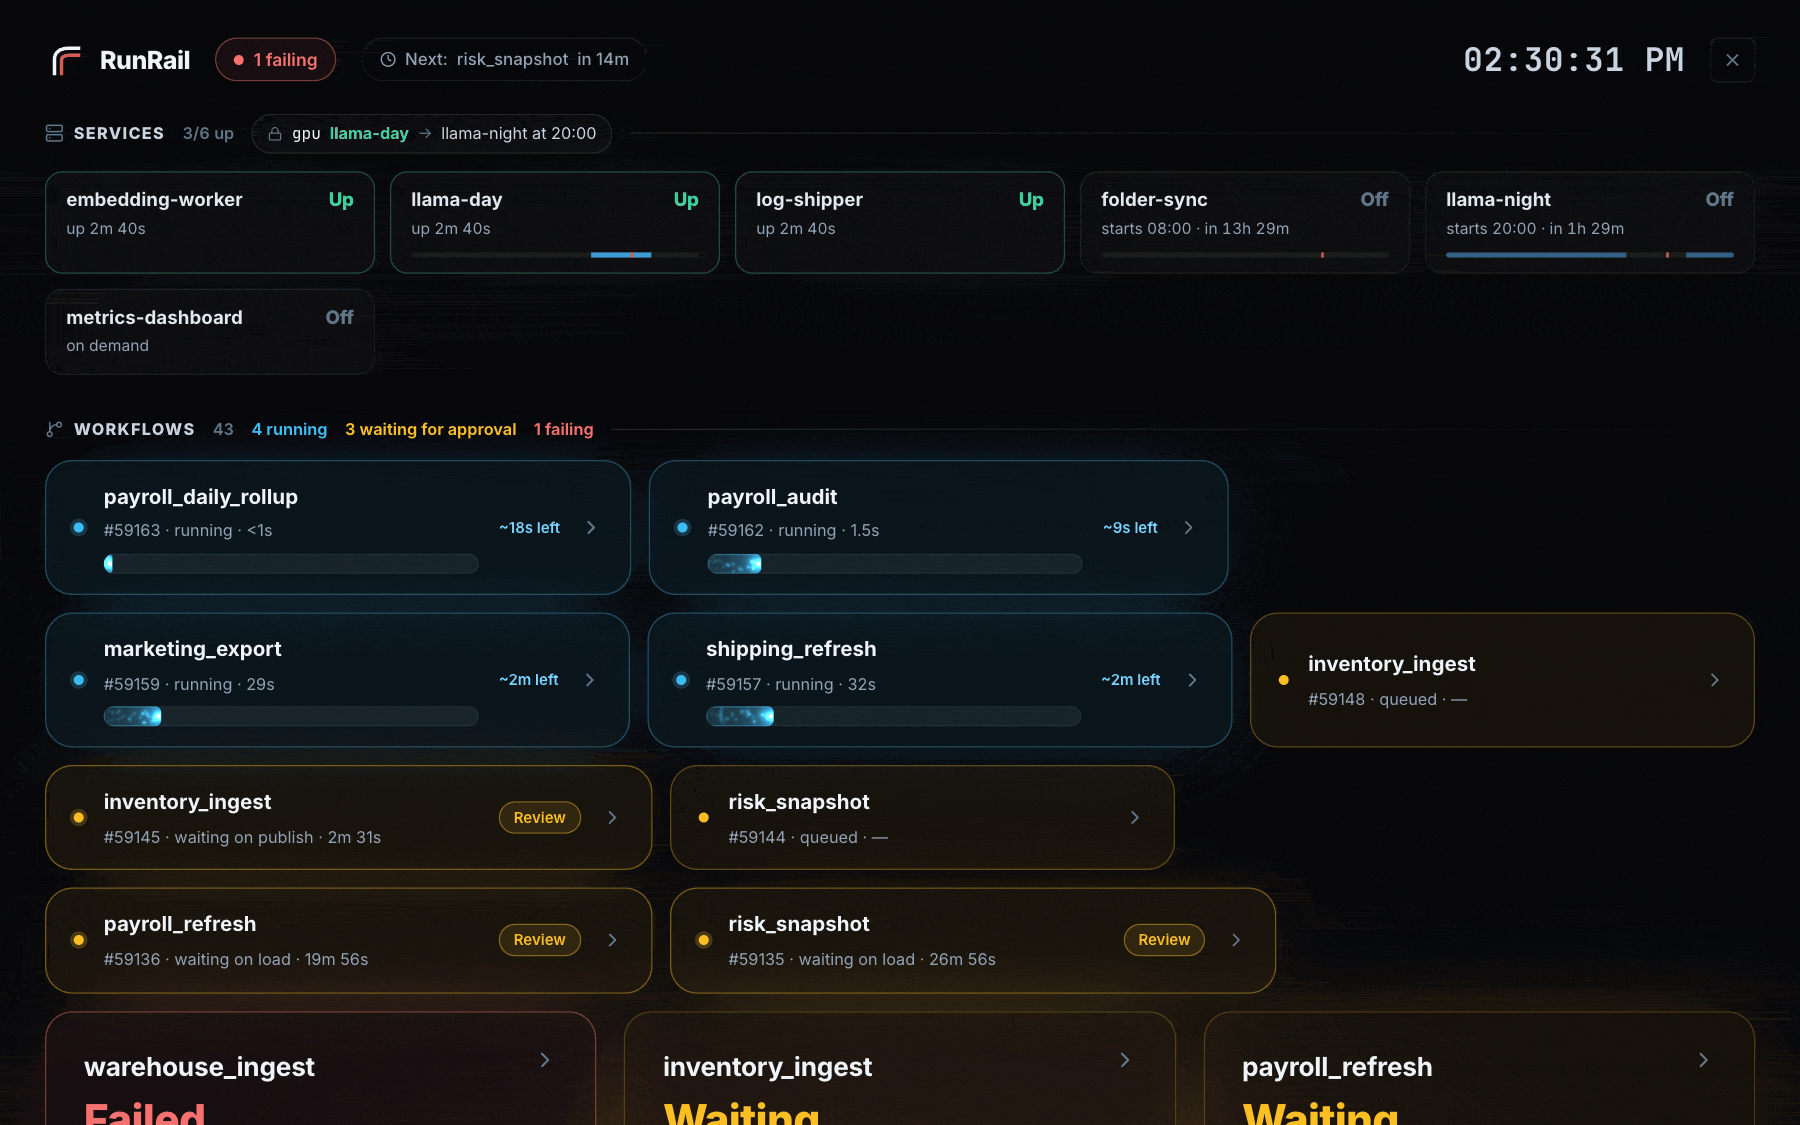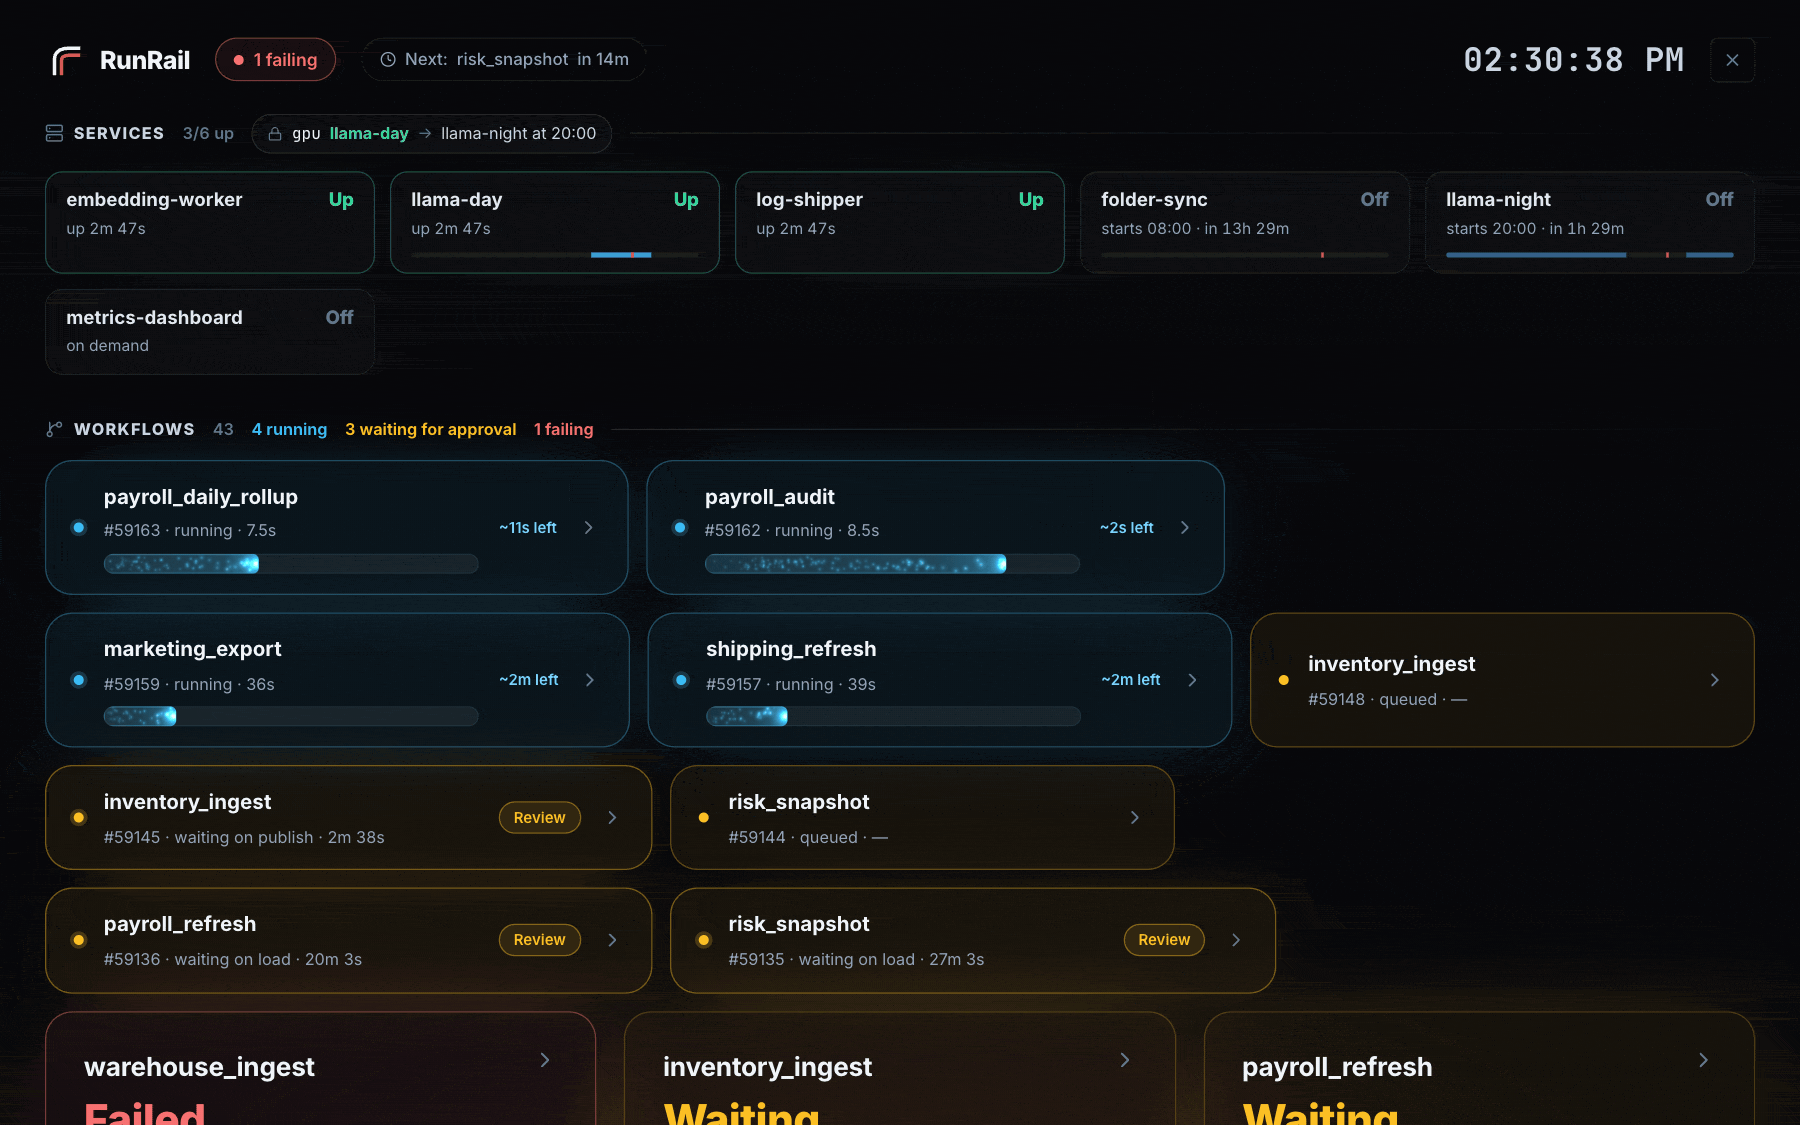
The wallboard: services along the top, then every workflow. Each run's bar is measured against that workflow's own median duration and turns amber when it goes over.
A task in RunRail is a command:
python scripts/refresh_sales.py --date {{ ds }}
That is the whole configuration. Nothing is imported into your code, and there is no DAG file to keep in sync with it. RunRail runs that command on a schedule, in a Python environment you declare, and keeps the logs, the timings and the history.
A service is a command RunRail keeps running instead:
llama-server -m models/qwen2.5-7b-q5.gguf --port 8081
Started with RunRail, inside weekly windows, or by hand; restarted if it crashes; stopped politely when its window closes; and able to take turns with your workflows on a shared GPU.
Sixty seconds to a first run
pipx install runrail     # or: pip install runrail
runrail serve            # first launch asks about importing; press Enter to start fresh
Then, in a second terminal:
cat > hello.yml <<'YAML'
workflows:
  - name: hello
    schedule_cron: "*/5 * * * *"
    tasks:
      - name: say-hello
        task_type: shell
        command: echo "hello from RunRail at {{ ts }}"
YAML

runrail apply hello.yml
runrail run hello
Open http://127.0.0.1:8080. The run is in the history with its logs, and the schedule fires again inside five minutes. The YAML is optional, by the way: everything in that file can be done in the UI, and most things are easier there.
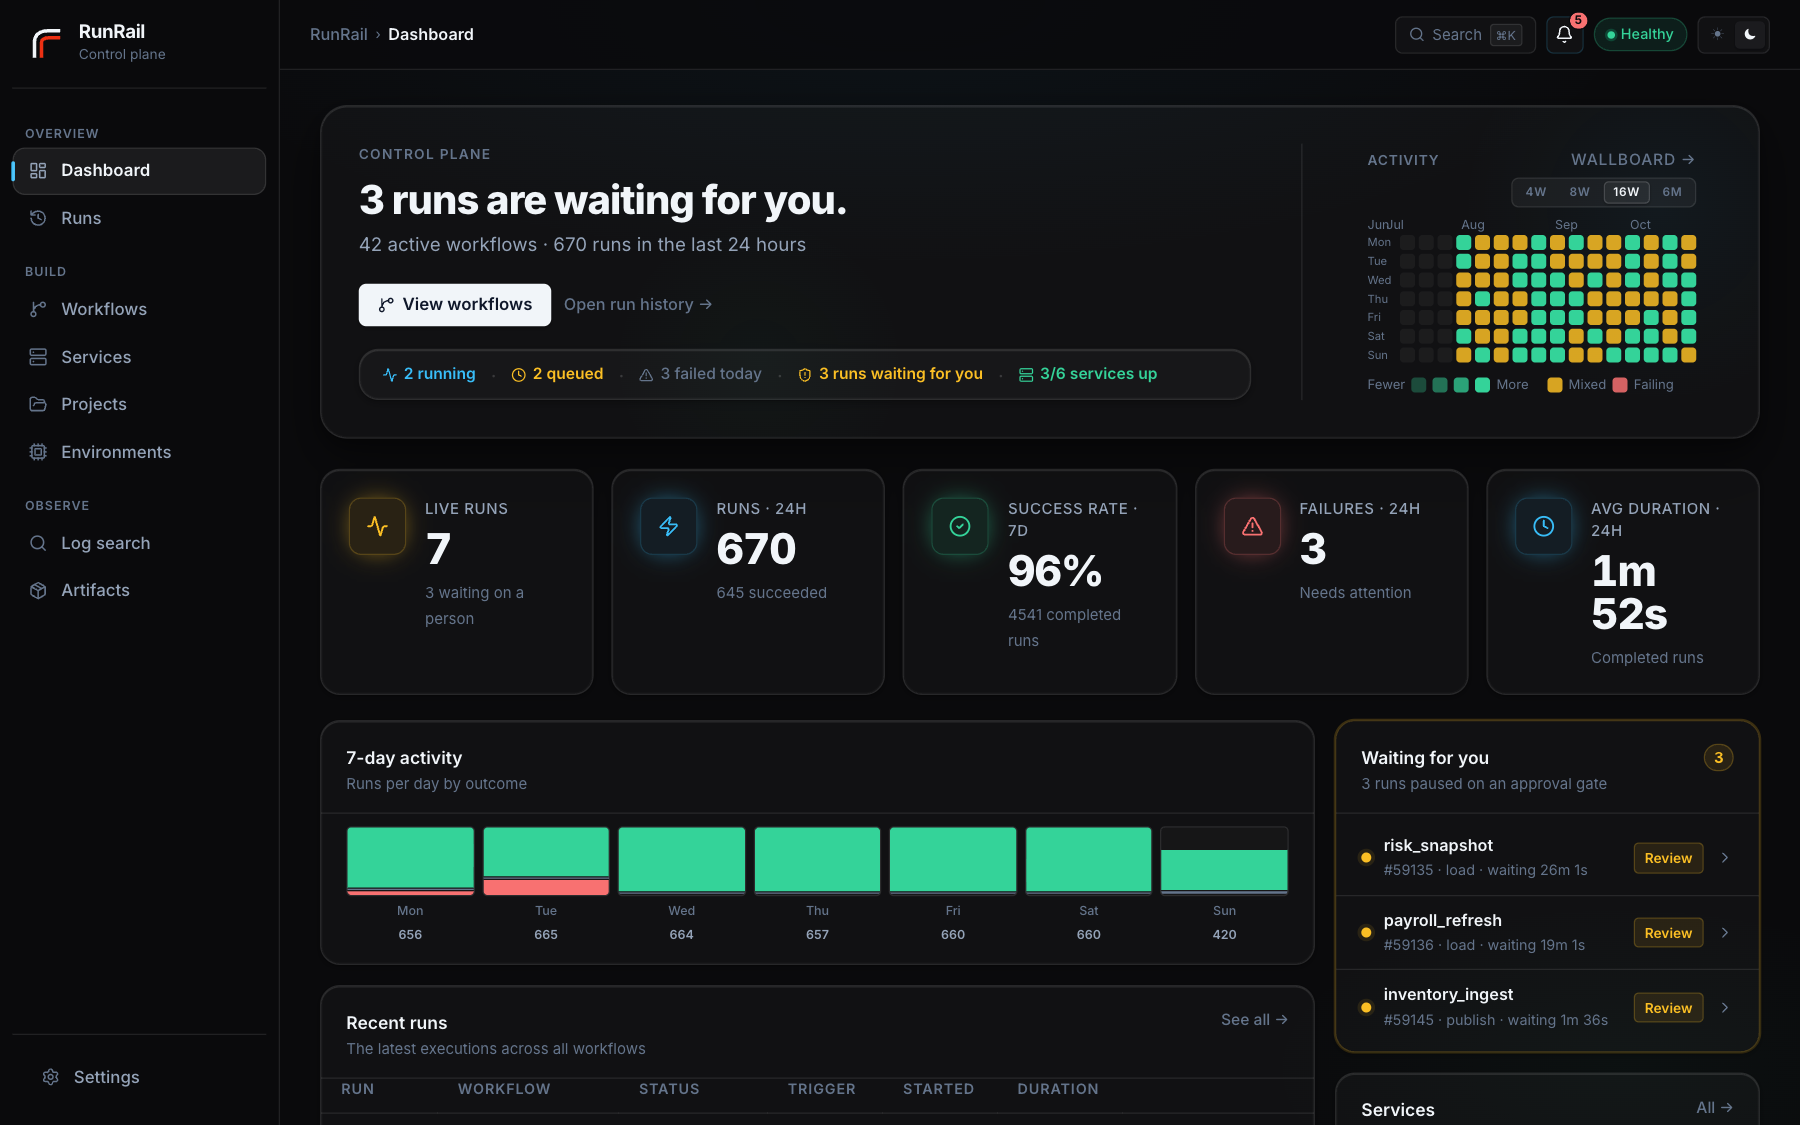
A few workflows later, the dashboard looks like this:
The parts that matter
Your code doesn't change. Point RunRail at a folder. Shell commands, Python scripts, notebooks and SQL files run as they are, each in its own subprocess with its own logs and timeout. Your dependencies are installed into an environment you declare, never into RunRail's own.
Nothing quietly disappears. Every run keeps its logs, its timings and its place in the history, with independent tasks laid out in parallel on a timeline. You can search the logs of every run at once, which is usually how you find out when something actually started going wrong. And a schedule that came due while the machine was asleep is recorded as missed, because a run that never happened is more interesting than one that did.
A failed run picks up where it stopped. Resume re-executes the task that broke and everything downstream, keeping what already succeeded. A three-hour first step doesn't run again because the fourth one failed.
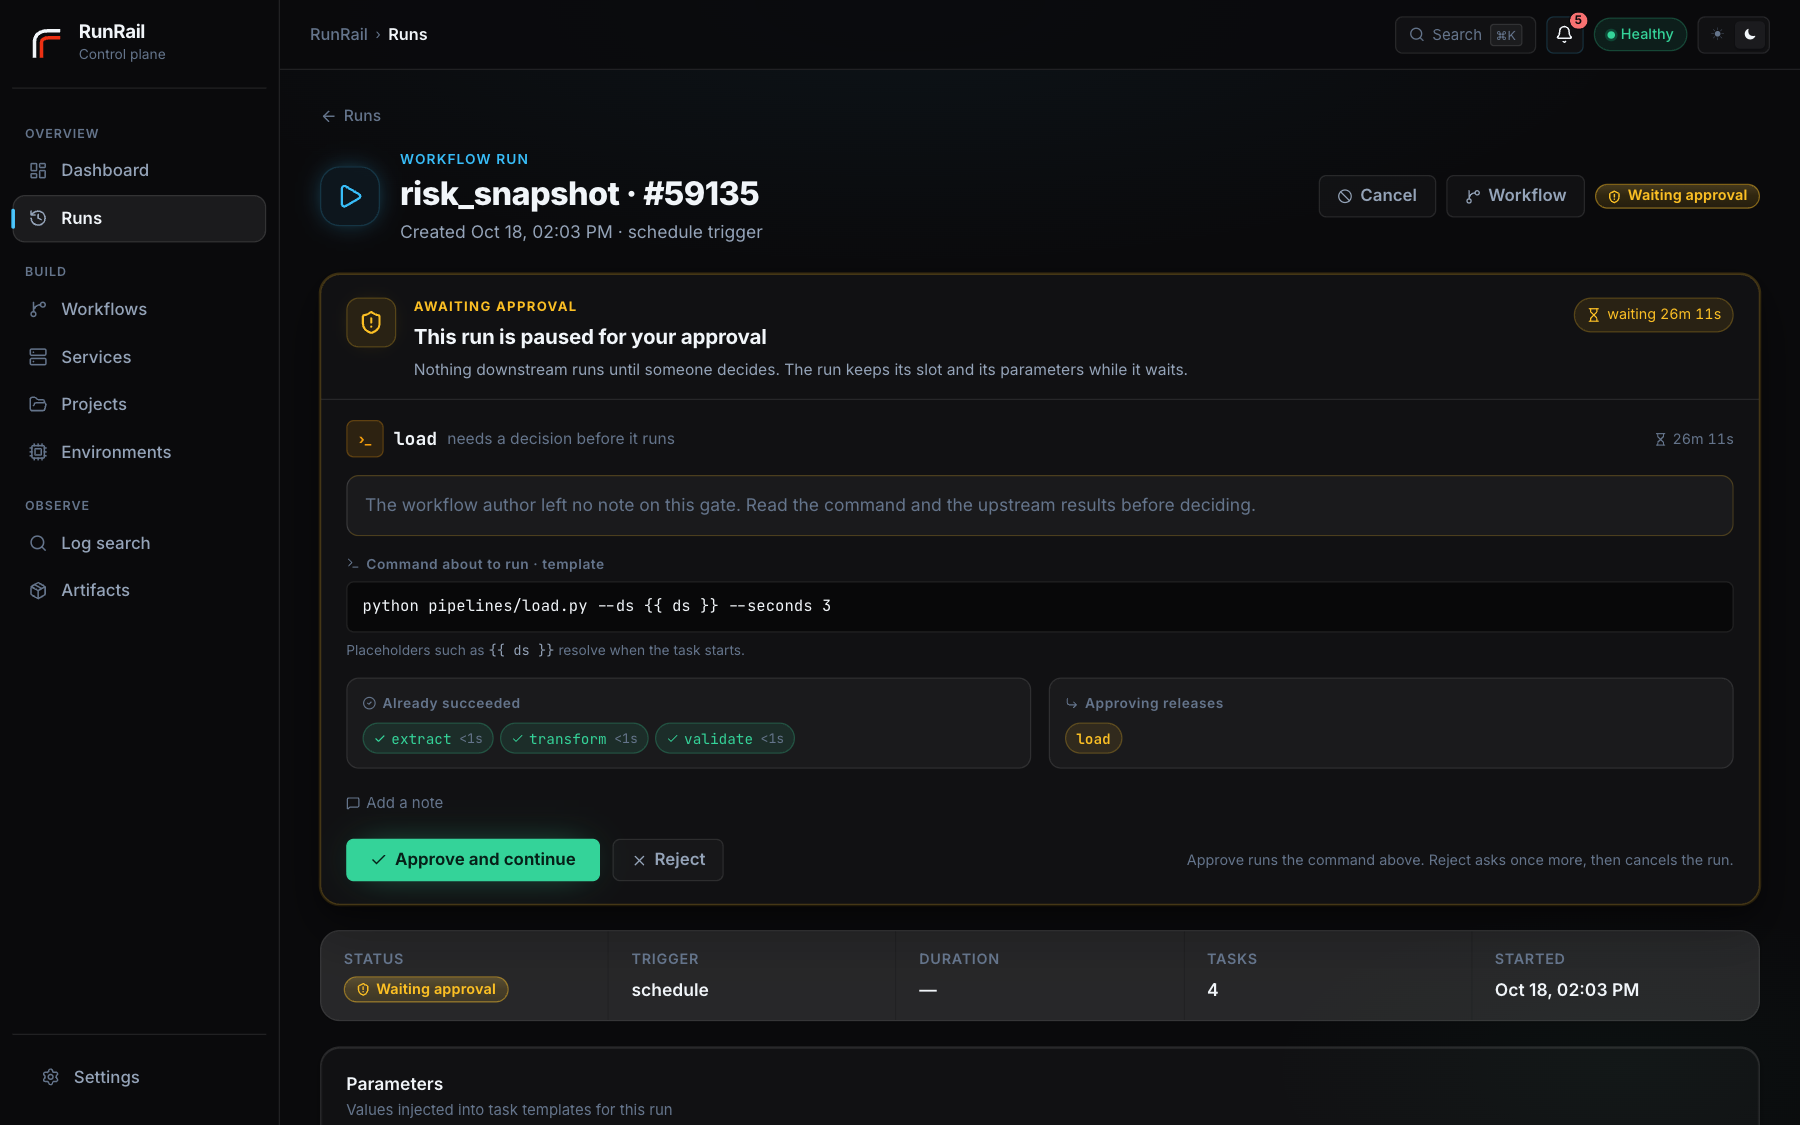
Some things should wait for a person. Mark a task as needing approval and the run parks there, showing the prompt and the exact command it is about to run. It gives up its worker thread while it waits, so a gate left open overnight holds nothing else up.
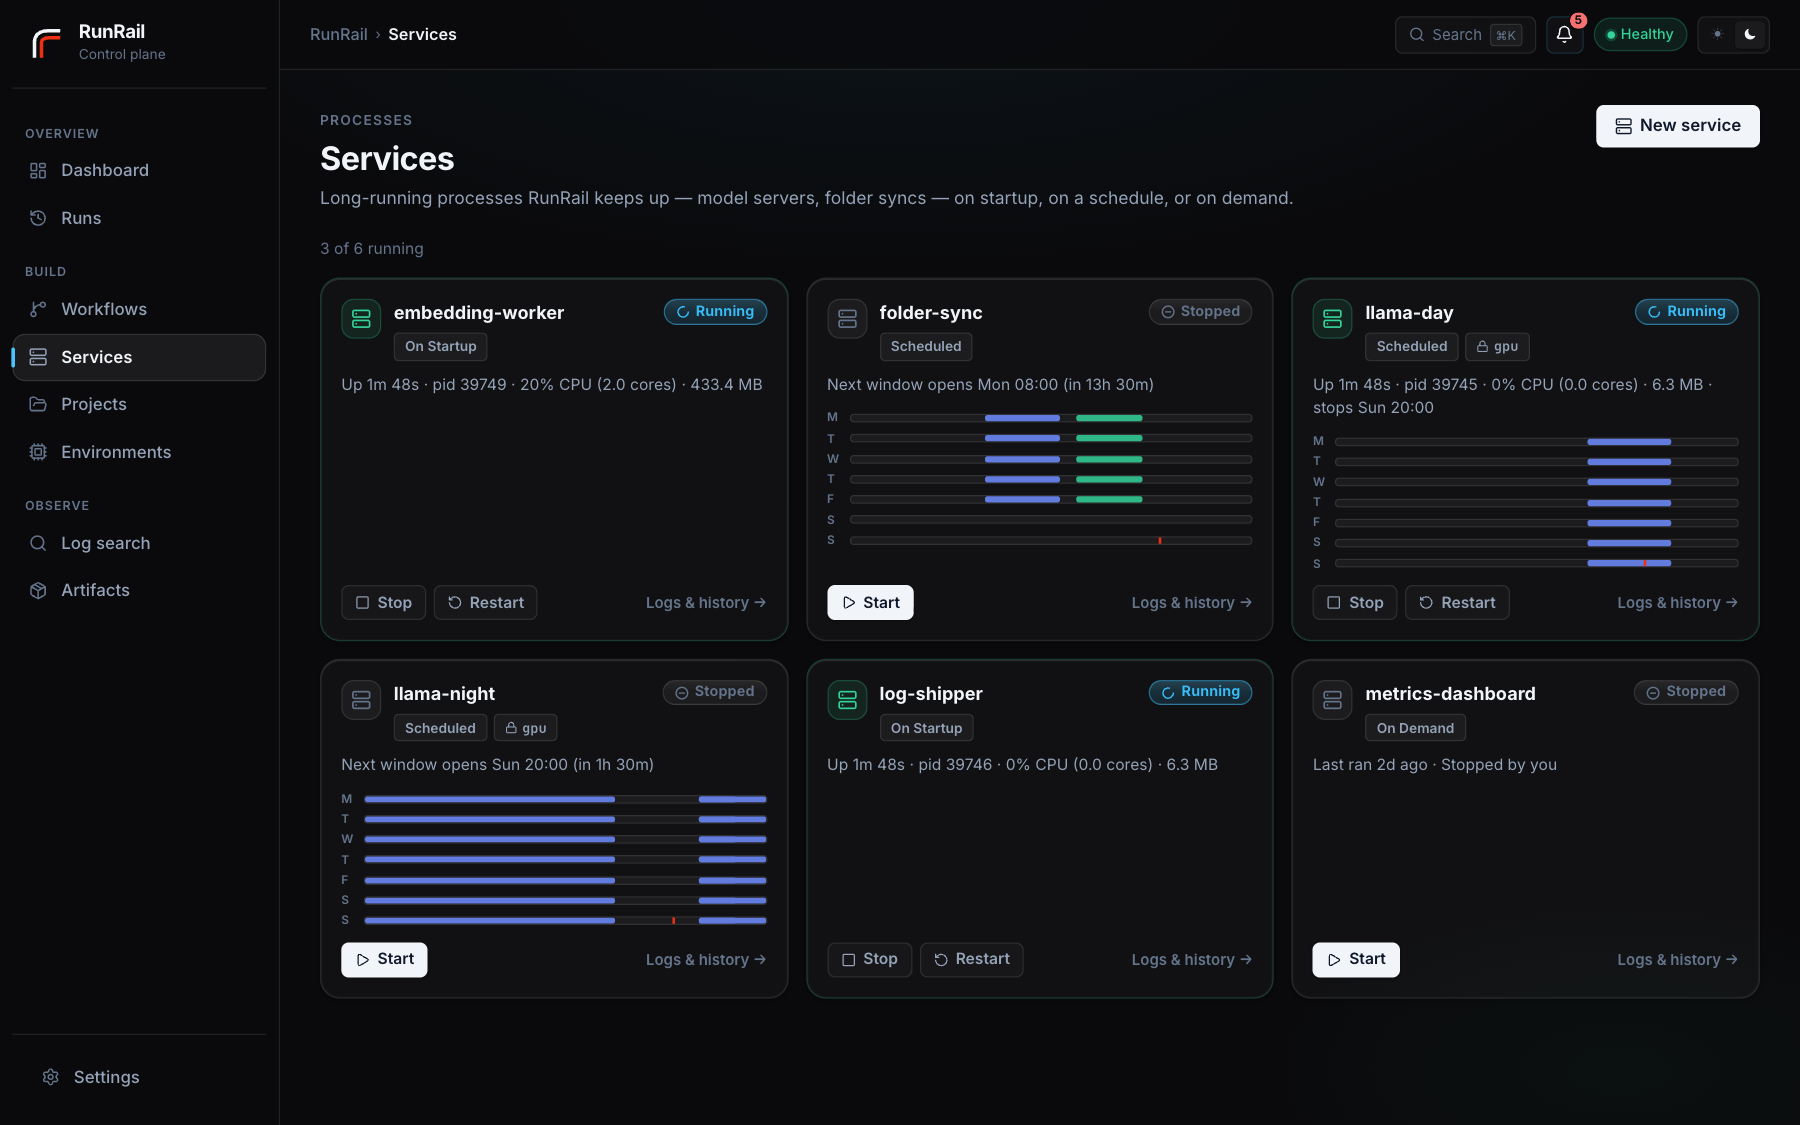
Some things should stay up rather than finish. A model server, a folder sync, a dashboard. A service runs on RunRail's startup, inside weekly windows (any number, overnight included), or on demand, with a live log and a history of every start and stop. A crashing one is restarted with a growing delay and held after five crashes in ten minutes, with a notification. Two model servers on an exclusive gpu lock take turns, and a GPU workflow waits for whichever one is running, because nothing in RunRail interrupts anything else.
Notebooks come out the other end as reports. An executed notebook renders to HTML on the run page, charts and tables included. /reports/<workflow>/latest always resolves to the newest successful run, so a link you shared last month still shows this morning's numbers.
Also in the box: retries and backfills, per-workflow concurrency, resource locks so two jobs never enter the same database at once, snooze, auto-pause after repeated failures, deadlines that alert while a run is still going, per-task duration trends, notes on a run, webhooks for Slack and Microsoft Teams, YAML export and apply, and a REST API with live docs at /docs.
A look around
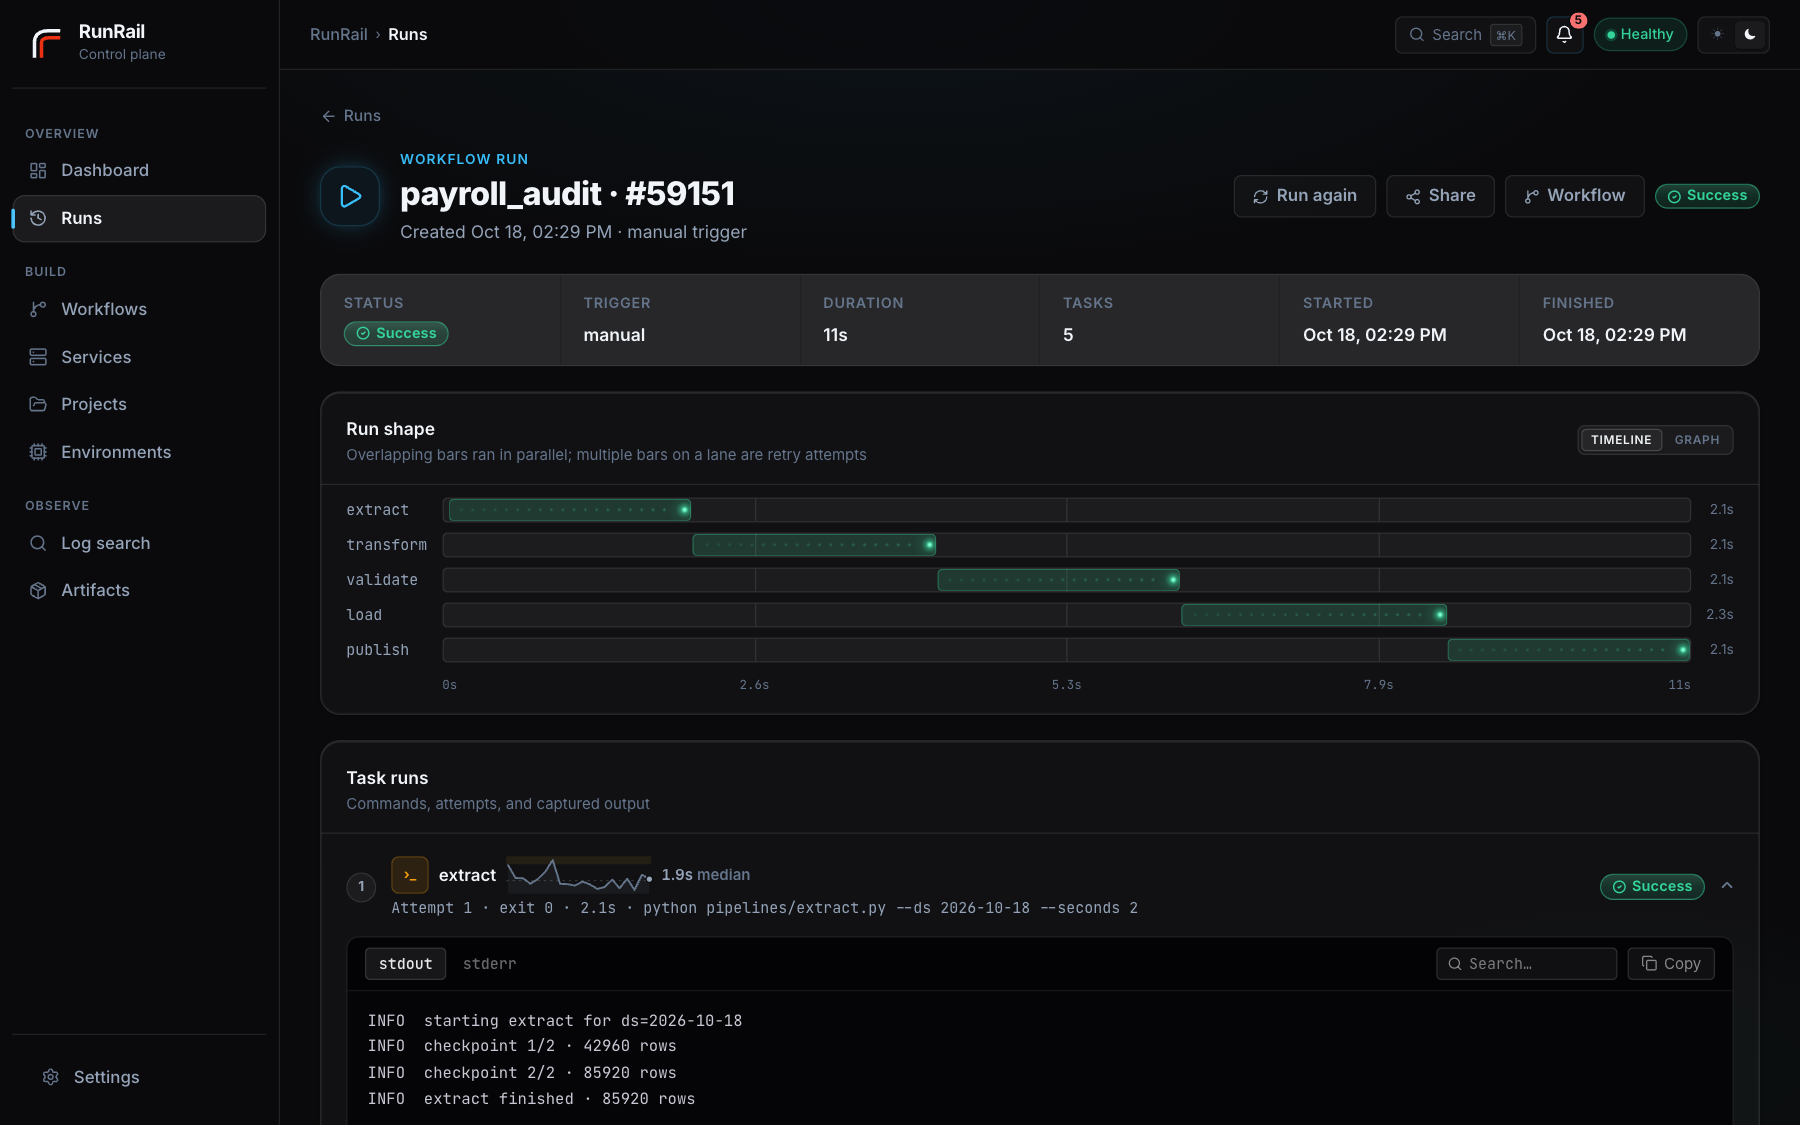
A run in progress. Independent tasks overlap on the timeline, and every attempt keeps its own logs.
A run waiting on approval, showing the prompt from whoever built the workflow and the command about to execute.
Services. Each card says what the process is doing and why, in the supervisor's own words: up and until when, waiting for a resource and who holds it, stopped by you and when its schedule takes over again.
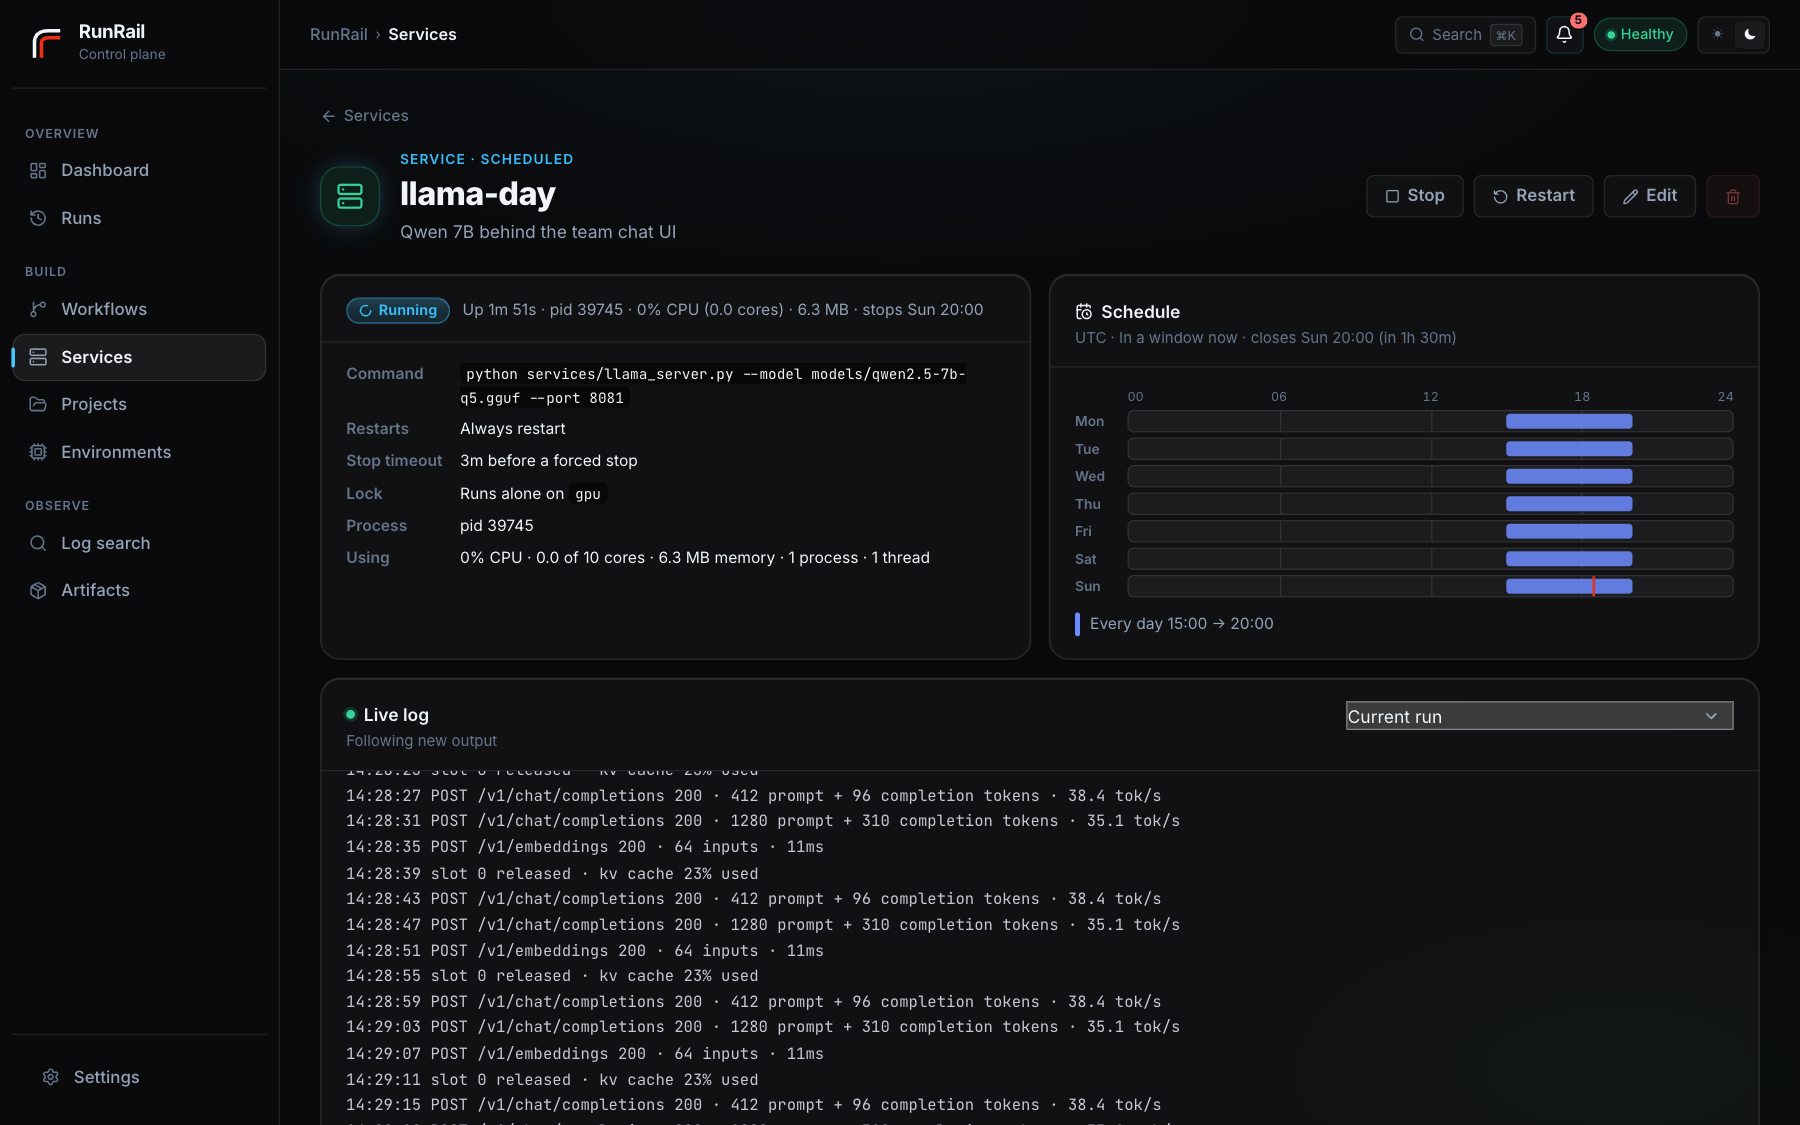
One service, with its schedule as a week, its live log, and every start and stop it has had.
Install
One package with the web UI already built into it. Python 3.11 or newer, nothing else. Startup takes about 0.6 seconds, including creating the database and applying migrations, and the whole thing settles at roughly 96 MB as a single process.
Data lives in a per-user directory:
| OS | Location |
|---|---|
| macOS | ~/Library/Application Support/RunRail |
| Linux | ~/.local/share/RunRail (honours $XDG_DATA_HOME) |
| Windows | %LOCALAPPDATA%\RunRail |
RUNRAIL_HOME moves it, for example RUNRAIL_HOME=./.runrail to keep it beside a project. RunRail also reads a .env from the directory you start it in, which matters if you launch it from more than one place.
Rendering notebooks as HTML reports needs an extra: pipx install "runrail[notebook]". Running notebooks does not; papermill goes into the task's own environment for that.
How it fits together
Projects point at the directories your code lives in. Environments say how Python runs: a managed virtualenv built from pip requirements, an interpreter you already have, or a Conda environment. Workflows group tasks into a dependency graph with an optional schedule. Services are single commands kept running, using the same projects and environments.
Environments resolve per task, then per workflow, then per project. Python and notebook tasks will not fall back to RunRail's own interpreter. That is deliberate: your dependencies are not its dependencies.
For most setups, Environments → New environment → Managed Python is the one to use. Declare pandas==2.3.0 and RunRail builds an isolated virtualenv, records the build log and Python version, and rebuilds atomically when the requirements change. A failed rebuild keeps the last working one. Every managed environment also carries papermill and ipykernel so notebook tasks work, which is about 127 MB before your own packages.
Templating
Commands and paths are Jinja templates. Every run gets:
| Variable | Meaning |
|---|---|
ds |
Logical date (2026-07-08), set per-date during backfills |
ts / ts_nodash |
Run timestamp, ISO and compact (20260708T141005) |
run_id, task_run_id |
Identifiers for this execution |
project_root, artifacts_dir |
Resolved paths for the run |
| your parameters | Run and per-task parameters, merged |
CLI
runrail serve                                    # API, UI, scheduler and worker together
runrail run daily-refresh --param region=ca      # queue a run now
runrail backfill daily-refresh --from 2026-06-01 --to 2026-06-30
runrail export -o workflows.yml                  # workflows as YAML you can commit
runrail apply workflows.yml                      # declarative upsert (survives renames)
runrail import ~/old/.runrail                    # bring an existing setup into this home
runrail cleanup --older-than-days 30 --dry-run   # prune old runs, logs and artifacts
runrail status

# or split the process up
runrail api
runrail scheduler
runrail worker --concurrency 8
Notifications
Set RUNRAIL_NOTIFY_WEBHOOK_URL, or a webhook per workflow. RunRail posts on the first failure after a success, and again when it recovers. A schedule that breaks at midnight sends one message, not three hundred. Nine event kinds go out in all, covering failures, recoveries, auto-pause, approvals, missed schedules and deadlines.
Slack and custom receivers get JSON whose text field renders directly. For Microsoft Teams, make a Workflow from the "when a webhook request is received" template (Teams → channel → Workflows) and paste the URL. RunRail recognises Teams URLs and sends the Adaptive Card envelope that flow expects.
Architecture
FastAPI serves the API and the prebuilt React UI. APScheduler is used purely as a clock, writing due runs into the database. While a run executes, the next scheduled iteration collapses into a single queued run rather than stacking up or vanishing, and a 60-second watchdog looks for schedules that have gone quiet and runs that have missed a deadline.
A bounded worker pool (RUNRAIL_WORKER_CONCURRENCY) claims queued runs atomically, so different workflows execute at the same time and a long job never blocks a frequent one. Runs of the same workflow are serialised by its max_concurrent_runs. Inside a run, the task graph executes with real parallelism (RUNRAIL_TASK_PARALLELISM).
Services have a supervisor of their own, beside the worker. Once a second it compares each service's process with what the service should be doing (its mode, its windows, any Start or Stop you pressed) and starts, stops, restarts or waits accordingly. It holds a lease in the database, so with serve and a separate worker running only one of them manages services, and a supervisor taking over from one that died first stops whatever that one left running.
All of it happens on one machine, using threads and subprocesses. There are no remote workers.
SQLite in WAL mode is the default. For PostgreSQL, set RUNRAIL_DB_URL=postgresql+psycopg://user:password@host:5432/runrail; the +psycopg matters, because a bare postgresql:// looks for psycopg2, which isn't installed. CI runs the whole suite against both. Logs live under $RUNRAIL_HOME/logs/, artifacts under $RUNRAIL_HOME/artifacts/<id>/, timestamped so retries never overwrite each other.
Docker is available (docker compose up --build starts RunRail with PostgreSQL on port 8080) and entirely optional.
Configuration
| Variable | Default |
|---|---|
RUNRAIL_HOME |
Per-user data directory (see Install) |
RUNRAIL_DB_URL |
SQLite at $RUNRAIL_HOME/runrail.db |
RUNRAIL_HOST / RUNRAIL_PORT |
127.0.0.1 / 8080 |
RUNRAIL_WORKER_CONCURRENCY |
4 concurrent runs |
RUNRAIL_TASK_PARALLELISM |
4 concurrent tasks per run |
RUNRAIL_WORKER_POLL_SECONDS |
1.0 |
RUNRAIL_RETENTION_DAYS |
unset; when set, finished runs older than this are deleted with their logs and artifacts |
RUNRAIL_NOTIFY_WEBHOOK_URL |
unset; default webhook |
RUNRAIL_PUBLIC_URL |
unset; base URL for links inside exported files and reports |
RUNRAIL_BROWSE_ROOT |
user home; limits the UI file picker |
RUNRAIL_SQLITE_DB_PATH |
unset; the database SQL tasks run against, unless the task sets sqlite_db_path |
Schedules evaluate in each workflow's own timezone, so "daily at 9:00" stays 9:00 on that workflow's clock across DST. The UI shows occurrences in yours.
Worth knowing
- It's built for one person on one machine. There are no accounts and no roles, by choice rather than omission. If you expose the port beyond localhost, put something in front of it that handles authentication, and narrow
RUNRAIL_BROWSE_ROOTwhile you're there. - Work runs on a single machine. Plenty happens in parallel there, but there are no remote workers.
- SQL tasks run against SQLite only.
- Services are managed by
runrail serveorrunrail worker.runrail apion its own shows them but starts and stops nothing, and the Services page says so. - Environment variables, including anything secret, are stored unencrypted in the database.
- Log search is a bounded grep rather than an index. Every limit is capped and the response says which cap it hit, so a partial answer never looks like a complete one.
- Missed-run history is recomputed from the current schedule, so editing a cron expression redraws the past under the new one.
Development
pip install -e '.[dev,notebook]'
pytest                                        # 379 backend tests
ruff check src tests

cd frontend
npm install
npm run build     # needed from a clone; the built UI is gitignored, not committed
npm test          # 165 frontend tests
npm run test:e2e  # browser tests against a real `runrail serve` (needs the build above)
The frontend tests check cron previews against fire times generated by the backend's own scheduler, so if the UI ever promises a run time the scheduler wouldn't produce, the build fails. scripts/seed_demo.py fills a throwaway home with a realistic history if you want something to look at.
Licensed under Apache-2.0.
1 maintainer

Metadata
1 maintainer
Release files for runrail 0.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| runrail-0.7.1.tar.gz | 700.7 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| runrail-0.7.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.4 MB
Release files / runrail-0.7.1.tar.gz
| Download URL | runrail-0.7.1.tar.gz |
|---|---|
| Size | 700.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0e9ba541bc2bda64e778873e273baecb6a0950c3766d710af6c203d1d9014322
|
|
BLAKE2b-256 checksum How to use checksums |
38347eaae71f9551d42328ce7dca57418d05485fdd39b842ef3d40190e05dbc5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logRelease files / runrail-0.7.1-py3-none-any.whl
| Download URL | runrail-0.7.1-py3-none-any.whl |
|---|---|
| Size | 717.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
dc7a15453429bdb1ade813d7af313d2199e90ea79ef9925255f037e12f689418
|
|
BLAKE2b-256 checksum How to use checksums |
5d18e66197f399059f837f0d2803e8dfc95e42d6eae208265d8f98438eda5025
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logSecurity for runrail 0.7.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for runrail-0.7.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














