
screenscribe


Turn screen recordings into actionable engineering reports.
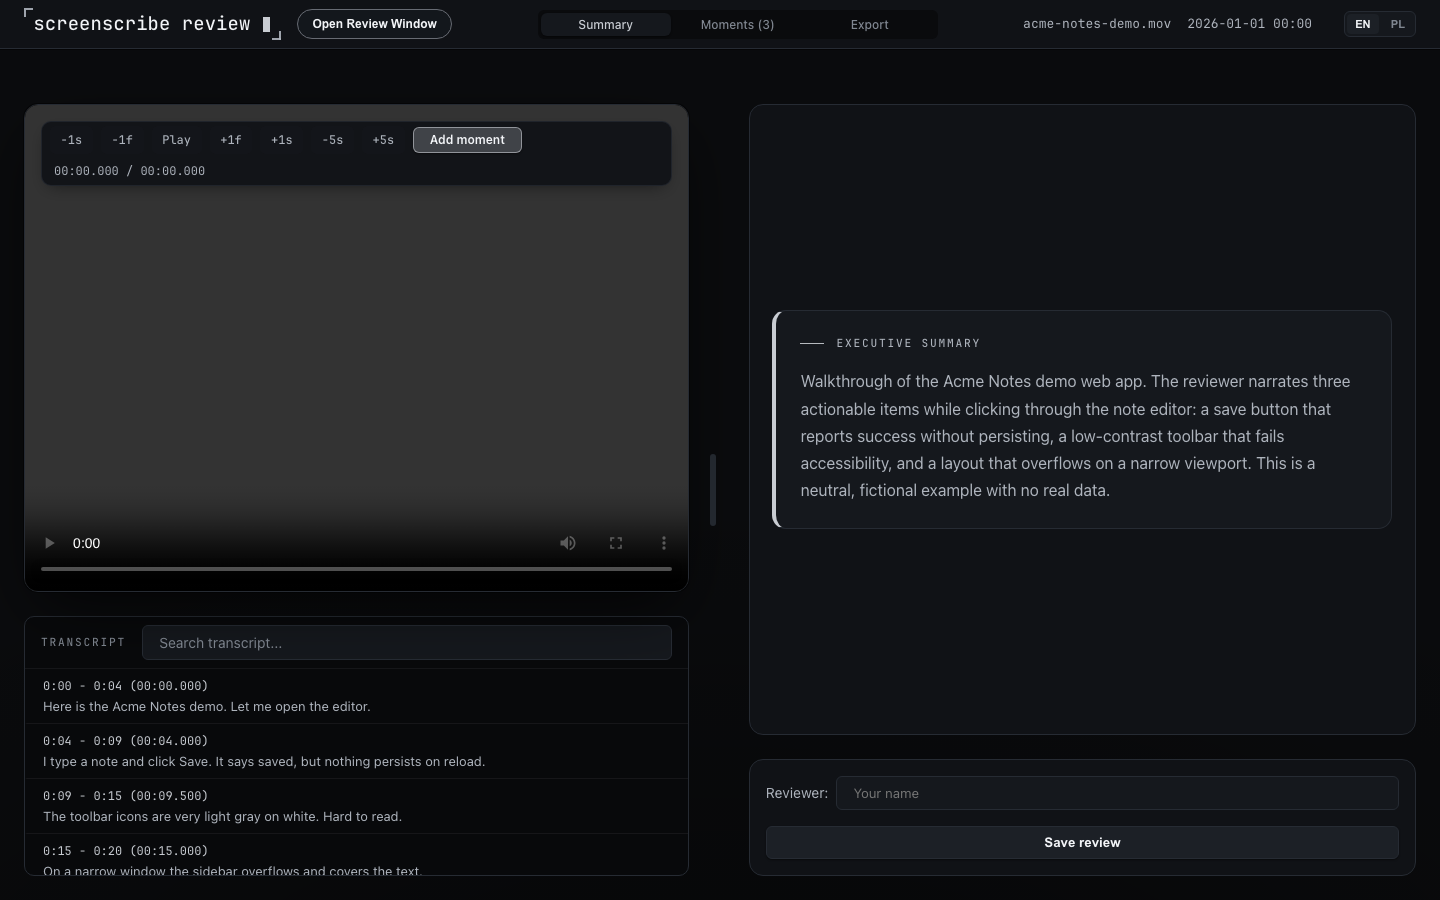
See a live example report: browse the
showcase
for a rendered screenshot, or clone the repo and run
uv run python examples/generate_example.py to generate and open a live,
self-contained example_report.html. It is a neutral, fictional sample — no
real recordings, keys, or personal data.
Record yourself walking through your app, talk through the bugs and changes you see, and screenscribe transcribes the narration, matches it to what is on screen, and produces a structured report you (or your AI agent) can act on — JSON, Markdown, and an interactive HTML report.
screenscribe runs a STT → LLM → VLM pipeline: speech-to-text for the narration, a language model to find the actionable moments, and a vision-language model to confirm them against captured frames.
screenscribe ships with LibraxisAI as its first-party default provider (an OpenAI-compatible API). To run it yourself, bring any OpenAI-compatible key — from OpenAI or another provider — and point screenscribe at that endpoint with two environment variables. See Providers.
Why screenscribe
Screen recordings are a fast, natural way to report bugs and review changes — but a video is not actionable. Someone still has to watch it, scrub to the right moment, and write down what was said. screenscribe automates that last mile:
- Just speak. Narrate your recording in plain language.
- Get structure. Receive a report with findings, timestamps, screenshots, and an executive summary.
- Hand off cleanly. The Markdown output is designed to be readable by both humans and AI fixer agents.
Typical users: developers doing self-review, QA engineers filing bug demos, product owners capturing feedback walkthroughs.
Features
- Two analysis modes
review— automatic pipeline: transcribe → find → screenshot → confirm → report.analyze— interactive, human-first dashboard: you scrub the video, mark frames, add voice/text notes, and trigger AI analysis only where it matters.
- STT → LLM → VLM pipeline with response-ID chaining so each stage shares context with the next.
- Interactive HTML report with synchronized video player, subtitle sync, screenshot annotations, and a human review workflow (on by default).
- Transcript-first lane (
preprocess) — extract audio and transcribe into stable artifacts (TXT, timestamped TXT, segments JSON, WebVTT) before any AI analysis, ideal for agent handoff. - Batch mode — review multiple videos with shared context across files.
- Auto-versioning — re-running a review preserves prior output as
_2,_3, … instead of overwriting. - Checkpointing — resume interrupted runs with
--resume. - Multi-provider, OpenAI-compatible — per-endpoint keys, endpoints, and models; optional opt-in STT fallback to a second provider.
Requirements
- Python 3.11+
- uv for dependency sync and source-checkout commands.
- macOS:
brew install uv - Standalone installer:
curl -LsSf https://astral.sh/uv/install.sh | sh
- macOS:
- FFmpeg (provides
ffmpegandffprobe) — a system-level prerequisite, not a Python dependency. It is never installed bypip/uv tool install; you must install it separately before the first run. Used for audio extraction and duration probing; input videos can be anything FFmpeg decodes, including.mp4,.mov,.mkv, and.webm.- macOS:
brew install ffmpeg - Debian/Ubuntu:
sudo apt install ffmpeg - Windows:
choco install ffmpeg(community/untested — CI and package classifiers cover macOS and Linux only; Windows is not an officially supported platform) - Shared Mac: if your account cannot modify the Homebrew prefix, ask the
Homebrew owner or an administrator to run
brew install ffmpeg. Do not change ownership of the Homebrew prefix.
- macOS:
- An API key for an OpenAI-compatible provider, or a signed-in xAI account
configured through
screenscribe config setup(covers STT + LLM + vision). The self-serve path is to bring your own key from OpenAI (or any other OpenAI-compatible provider) and point the endpoints at that provider — see Providers. LibraxisAI is the built-in default endpoint. A signed-in ChatGPT account can run LLM + vision without any key; STT then stays on one of the providers above (ChatGPT has no speech-to-text).
Quickstart
uv tool install screenscribe

# choose LibraxisAI, OpenAI, xAI, a custom OpenAI-compatible provider, or a
# ChatGPT account (LLM + vision); keys use a hidden prompt; signed-in xAI
# accounts can supply the bearer
screenscribe config setup

# FFmpeg is required before the first video run (see Requirements above)

# review a narrated screen recording
screenscribe review demo.mov
Want to try it without a persistent install? Run uvx screenscribe --help.
If uv/uvx is not installed yet, follow the official
uv installation guide.
uv tool install screenscribe installs the CLI and its runtime dependencies
from PyPI in an isolated environment. If uv reports that its tool directory is
not on PATH, run uv tool update-shell once and restart your terminal.
FFmpeg/ffprobe are a system prerequisite and are not installed by this
command — see Requirements above.
Upgrade to the latest release: uv tool upgrade screenscribe. Remove it:
uv tool uninstall screenscribe.
No screen recording handy?
screenscribe review demo.mov above assumes you already have a narrated
screencast. If you don't, generate a synthetic clip with FFmpeg and run the
full pipeline against it end to end:
ffmpeg -f lavfi -i testsrc=duration=30:size=1280x720:rate=30 -f lavfi -i sine=frequency=440:duration=30 -c:v libx264 -pix_fmt yuv420p -shortest demo.mp4

screenscribe review demo.mp4
This exercises audio extraction, STT, the LLM/VLM findings pipeline, and report generation against a real 30-second video. Honest expectation: the synthetic clip carries a test pattern and a 440Hz tone, not narration, so screenscribe reports "No speech detected in this recording" and generates an empty-state report (0 findings) instead of fabricating results. That's the correct outcome — it confirms your install and API keys work end to end. Point the same command at a real narrated recording to get actual findings.
Development / install from source
To work on screenscribe itself instead of installing the published package:
git clone https://github.com/vetcoders/screenscribe.git
cd screenscribe
make dev
# Optional: keep the globally available CLI linked to this checkout.
make dev-link
make install installs the current source checkout as a normal, non-editable
tool. It does not install the development dependency group or Git hooks.
Providers
The self-serve path is the provider setup wizard:
screenscribe config setup
Choose LibraxisAI, OpenAI, xAI, a Custom OpenAI-compatible
provider (advanced), or a ChatGPT account. The custom path asks for a
base URL and provider-specific STT, LLM, and vision model names, with an example beside every prompt. The xAI
preset routes STT to https://api.x.ai/v1/stt (word-level timing, no model
name), LLM/vision to https://api.x.ai/v1/responses (grok-4.6), and enables
screenscribe tts and screenscribe transcribe --live.
For account-based xAI access, run screenscribe auth login xai first, then
choose xAI in screenscribe config setup and accept the signed-in account.
No API key is needed for that path. Signing in alone leaves the current
provider configuration unchanged.
A signed-in ChatGPT account runs LLM + vision on your ChatGPT plan through
the ChatGPT Codex backend (https://chatgpt.com/backend-api/codex/responses).
Select it with screenscribe config auth chatgpt,
screenscribe config auth openai --login, or option 5 in
screenscribe config setup; each one starts screenscribe auth login openai
(device flow) first when you are not signed in.
STT stays on the provider you had configured, because ChatGPT has no
speech-to-text. The default model is gpt-5.6-luna (override with
SCREENSCRIBE_LLM_MODEL / SCREENSCRIBE_VISION_MODEL). No API key is ever sent
to chatgpt.com, and api.openai.com still rejects ChatGPT account tokens, so
the OpenAI preset keeps needing an OpenAI API key.
The wizard reads API keys through a hidden prompt when needed and atomically writes one coherent set of credentials, endpoints, and compatible models. A known OpenAI↔LibraxisAI mismatch blocks before any request is sent. Custom endpoints remain available with a warning when provider compatibility cannot be verified.
Remote provider endpoints require HTTPS (WSS for live STT). HTTP/WS is allowed
only for localhost or a literal loopback address, including IPv6. Private LAN
addresses still require TLS. Provider identity is restricted to the exact API
hosts api.libraxis.cloud, api.openai.com, and api.x.ai, plus chatgpt.com
for the ChatGPT account route (account token only); other gateways are
custom providers and need explicitly configured credentials. Provider redirects
are not followed; configure the final endpoint directly.
Plaintext loopback HTTP/WS connects directly: environment proxy settings cannot
route these requests elsewhere, even with an empty NO_PROXY. HTTPS/WSS keeps
configured proxy support. OAuth device/code exchange and token refresh require
HTTPS even on loopback; issuer overrides must point to a trusted HTTPS service.
The legacy config --set-key option remains for advanced compatibility, but it
changes only the generic key and exposes its argument to shell history. It is
not the recommended onboarding path.
The existing config and its exact-byte backup are each replaced atomically with
owner-only permissions. A failed backup leaves the config unchanged; a failed
config replacement preserves the old config and the completed backup.
Billing — bring-your-own-key (BYOK). screenscribe does not resell or proxy AI capacity. You bring your own provider key and you pay that provider directly — LibraxisAI (the default) or OpenAI — for the STT, LLM, and vision calls each run makes. There is no screenscribe account, subscription, or charge in between: the tool only forwards your requests to the endpoints you configure and never sees or handles payment. On the ChatGPT account route, LLM and vision calls run on your own ChatGPT plan.
screenscribe transcribes the narration, finds the actionable moments, captures matching screenshots, confirms them with the vision model, writes the report artifacts, and (by default) opens the interactive HTML report in your browser.
Prefer to drive the AI yourself? Use the interactive dashboard:
screenscribe analyze demo.mov
This opens a browser where you scrub the video, mark interesting frames, add voice or text notes, and trigger VLM analysis only on what you point at.
How it works
flowchart LR
    A[Screen recording<br/>+ narration] --> B[Extract audio<br/>FFmpeg]
    B --> C[STT<br/>speech-to-text]
    C --> D[LLM<br/>find actionable moments]
    D --> E[Capture screenshots<br/>at finding timestamps]
    E --> F[VLM<br/>confirm against frames]
    F --> G[Report<br/>JSON / Markdown / HTML]
- Extract audio from the video with FFmpeg.
- STT transcribes the narration into timestamped segments.
- LLM reads the full transcript and surfaces the actionable moments (bugs, changes, points of interest).
- Screenshots are captured at the relevant timestamps.
- VLM inspects each frame alongside the spoken context to confirm the finding and describe what is actually on screen.
- Report artifacts are written (and optionally served in the browser).
Each stage chains a response ID into the next, so later stages reason with the
earlier context instead of starting cold. The ChatGPT account route is the
exception: its backend keeps no state (store: false), so nothing is chained
there and every call carries its full context.
Terminology — moments vs findings. The interactive report and the
analyzedashboard call these items moments (the "Moments" tab, the "Add moment" button); the data artifacts —<video>_report.json, the Markdown export, and the config flags — call the same items findings. They are one thing under two labels: moment is the UI-facing name, finding is the data-facing name.
Commands
screenscribe ships 9 commands. In a source checkout, prefix copy-paste
commands with uv run as shown below. If you installed the package or activated
its virtualenv, the bare screenscribe command is equivalent. Running
screenscribe with no command opens an interactive prompt; running
screenscribe <video> is a shortcut for screenscribe review <video>.
| Command | What it does |
|---|---|
review |
Full automatic pipeline → interactive review report. |
analyze |
Interactive, human-first dashboard (FastAPI server in your browser). |
transcribe |
Transcribe audio to text only (no analysis). |
preprocess |
Build a transcript-first artifact bundle for downstream review. |
keywords |
Manage keywords passed to the AI as hints during detection. |
config |
Manage configuration and API keys. |
auth |
Sign in to a provider account and inspect or remove its stored session. |
tts |
Synthesize speech with the configured xAI provider. |
version |
Show version information. |
screenscribe review
Analyze one or more screencasts and generate an interactive review report.
uv run screenscribe review demo.mov
uv run screenscribe review clip1.mov clip2.mov clip3.mov        # batch, shared context
uv run screenscribe review ./recordings/session.mov --no-serve
uv run screenscribe review demo.mov --force
uv run screenscribe review demo.mov --keywords-file my-keywords.yaml
By default this produces a JSON, Markdown, and interactive HTML report and opens the HTML report in your browser. Key options:
--lang / -l— transcription language (defaulten; pass--lang plfor Polish).--no-serve— write the report without starting the browser server.--transcript-source auto|audio|ocr— where transcript segments come from: audio STT or VLM OCR of frames.auto(default) picks audio when the file has an audio stream and switches to OCR when that stream carries no speech, so silent recordings are analyzed instead of rejected;--no-audiois the shortcut forocr, and--frame-intervalsets the seconds between OCR'd frames (default 5).--ocr-max-frames— cap the billable vision calls of one OCR transcript (default 720, one hour at the default frame interval). Checked before the first paid call, so a too-small--frame-intervalcannot quietly run up a bill.--no-vision(alias--no-vlm) — skip the visual/screenshot (VLM) step; the semantic LLM detection still runs.--keywords-file— per-run keywords file. Keywords are always-on AI hints (see Keywords below); an empty or missing file is safe.--preset— switch the whole analysis profile (keyword dictionary, finding categories, prompt focus):programming(default),casual,medical,veterinary, orcustom(requires--keywords-file).--resume/--force— resume from a checkpoint, or overwrite a prior screenscribe review (never a folder screenscribe does not own).
See USAGE.md for every flag.
screenscribe analyze
Start the interactive, human-first analysis dashboard. screenscribe boots a local FastAPI server and opens a browser with a video player where you:
- watch the video and pause at interesting moments,
- record voice comments describing issues,
- mark frames for AI analysis,
- get real-time VLM analysis on exactly the frames you choose,
- export the session as JSON or a Markdown report.
uv run screenscribe analyze demo.mov
uv run screenscribe analyze demo.mov --port 9000
uv run screenscribe analyze demo.mov --lang pl
The dashboard defaults to English (--lang en); a PL/EN toggle switches the
UI and the language used for new frame analyses. This is the recommended mode
when you want to guide the AI instead of letting it process the whole video
blindly — and it works even on recordings with no audio track.
screenscribe transcribe
Transcribe a video's audio to plain text, with no analysis.
uv run screenscribe transcribe demo.mov                 # print to stdout
uv run screenscribe transcribe demo.mov -o transcript.txt
uv run screenscribe transcribe demo.mov --local --lang en
screenscribe tts
Synthesize speech from text through xAI TTS (POST /v1/tts). Requires the xAI
preset or SCREENSCRIBE_TTS_ENDPOINT + SCREENSCRIBE_TTS_API_KEY.
screenscribe tts "Dzień dobry" --out hello.mp3 --language pl --voice eve
screenscribe preprocess
Build a transcript-first artifact bundle — the non-AI handoff lane. Extracts audio, transcribes it, and writes stable transcript artifacts, then stops before any semantic or vision analysis.
uv run screenscribe preprocess demo.mov
uv run screenscribe preprocess demo.mov -o ./demo_preprocess
uv run screenscribe preprocess demo.mov --no-audio --lang en
Output bundle: transcript.txt, transcript.timestamped.txt,
transcript.segments.json, transcript.vtt, a preprocess.json manifest, and
(by default) the extracted audio.mp3. It goes to <video>_preprocess next to
the video; -o names the bundle directory, and an existing folder that is not a
previous preprocess bundle is used as a parent (<folder>/<video>_preprocess).
Existing files or folders that are not screenscribe bundles are never written
into: they are skipped for the next missing _2, _3, …, and --force refuses them.
Existing empty bundle paths are skipped too because another live process may
have created one immediately before writing its artifacts.
An output folder that cannot be created or written, or no free version left,
stops with an "Output Directory Error" (exit 1) instead of a traceback.
screenscribe config
Manage configuration and API keys. The config file lives at
~/.config/screenscribe/config.env.
uv run screenscribe config --show           # display current configuration
uv run screenscribe config setup            # safe provider + hidden-key wizard
uv run screenscribe config auth chatgpt     # LLM + vision on your ChatGPT account
uv run screenscribe config --init           # create a default config file
uv run screenscribe config --set-key KEY     # advanced compatibility; shell-history risk
You can also open the config in your editor with uv run screenscribe --config.
screenscribe keywords
Keywords are always-on hints for the AI. They are a dictionary of the words and phrases your team uses to describe problems (e.g. "klikam i nic" = bug, "potworek" = UI, "za ciężkie" = perf). During detection screenscribe passes them to the LLM as hints — they never replace the semantic analysis, never auto-create a finding on their own, and an empty or missing dictionary is a safe no-op. They are used by default if present.
The active dictionary is a single global file at
~/.config/screenscribe/keywords.yaml. It groups phrases under six categories
(bug, change, ui, performance, accessibility, other) and may mix
languages. A built-in default is used until you create your own.
uv run screenscribe keywords init                 # create the global file from defaults
uv run screenscribe keywords edit                 # open it in $EDITOR
uv run screenscribe keywords add bug "klikam i nic" # append one phrase to a category
uv run screenscribe keywords list                 # show the active dict + per-category counts
For a one-off run with a different keywords file, pass --keywords-file /path to
review or analyze instead of editing the global file.
screenscribe version
uv run screenscribe version
uv run screenscribe --version    # short form
Configuration
screenscribe is configured via environment variables or a config file at
~/.config/screenscribe/config.env (created by uv run screenscribe config --init).
Environment variables always override the config file.
API key
Set any one of these — the first non-empty value wins:
export SCREENSCRIBE_API_KEY=YOUR_API_KEY   # generic key (all endpoints)
export OPENAI_API_KEY=YOUR_OPENAI_KEY      # → LLM + vision
export LIBRAXIS_API_KEY=YOUR_LIBRAXIS_KEY  # → STT (and generic fallback)
For multi-provider setups you can set per-endpoint keys explicitly:
SCREENSCRIBE_STT_API_KEY, SCREENSCRIBE_LLM_API_KEY,
SCREENSCRIBE_VISION_API_KEY.
Note:
OPENAI_API_KEYfills the LLM/vision keys but does not change the endpoints, which default to LibraxisAI. Setting onlyOPENAI_API_KEYtherefore sends your OpenAI key to the LibraxisAI endpoint. screenscribe does not re-route silently — it emits a key/endpoint mismatch warning. To use OpenAI directly, also point the endpoints athttps://api.openai.com(viaSCREENSCRIBE_API_BASEor the explicitSCREENSCRIBE_*_ENDPOINTvars).
Endpoints
Point screenscribe at any OpenAI-compatible provider. Either set a base URL and let it derive the standard paths, or set each endpoint explicitly:
# Derive endpoints from a base URL
export SCREENSCRIBE_API_BASE=https://api.openai.com

# Or set explicit full URLs
export SCREENSCRIBE_STT_ENDPOINT=https://api.openai.com/v1/audio/transcriptions
export SCREENSCRIBE_LLM_ENDPOINT=https://api.openai.com/v1/responses
export SCREENSCRIBE_VISION_ENDPOINT=https://api.openai.com/v1/responses
The LLM and vision endpoints use the Responses API (/v1/responses), which
enables response-ID chaining across pipeline stages. The default provider is
LibraxisAI (https://api.libraxis.cloud); override the variables above to use
OpenAI or any compatible provider.
Models
export SCREENSCRIBE_STT_MODEL=whisper-1
export SCREENSCRIBE_LLM_MODEL=gpt-4o          # provider-specific
export SCREENSCRIBE_VISION_MODEL=gpt-4o       # provider-specific
export SCREENSCRIBE_LLM_REASONING_EFFORT=none  # none|low|medium|high|xhigh|max for text-LLM calls
Defaults: STT whisper-1, LLM and vision programmer (the LibraxisAI
default — change these to your provider's model names, e.g. gpt-4o).
The ChatGPT account preset sets LLM and vision to gpt-5.6-luna.
Text-LLM Responses API calls (pre-filter, text-only analysis, summaries,
merge) use a configured reasoning effort. When unset, the default is low
for xAI and none for OpenAI/LibraxisAI; custom endpoints omit the option
until you explicitly configure support.
Lower it to low if detection fails after the model reasons for a long time
without answering.
Processing options
export SCREENSCRIBE_LANGUAGE=en               # default transcription language (use pl for Polish)
export SCREENSCRIBE_VISION=true               # enable visual/screenshot (VLM) analysis (false = LLM-only)
export SCREENSCRIBE_LLM_MERGE=true            # semantic LLM-merge of near-duplicate findings (false = heuristic-only dedup)
Optional STT fallback (opt-in)
You can configure a second STT provider that is tried only when the primary STT endpoint fails (e.g. a rate limit). It is off by default because a fallback routes your audio to another provider — set all three to enable:
export SCREENSCRIBE_STT_FALLBACK_ENDPOINT=https://api.openai.com/v1/audio/transcriptions
export SCREENSCRIBE_STT_FALLBACK_API_KEY=YOUR_OPENAI_KEY
export SCREENSCRIBE_STT_FALLBACK_MODEL=whisper-1
See USAGE.md for the full configuration reference and troubleshooting.
Language defaults
screenscribe was built international-first, with Polish available as an opt-in:
analyze,review,transcribe, andpreprocessall default to English (--lang en);analyzeadditionally offers a PL/EN toggle in the UI.- Pass
--lang pl(or setSCREENSCRIBE_LANGUAGE=pl) for Polish.
Output artifacts
A review run writes, per video, into its review directory (<video>_review
next to the video by default; -o names it, and an existing folder that is not a
previous review is used as a parent, giving <folder>/<video>_review):
<video>_report.json— machine-readable findings, transcript, and summary.<video>_report.md— human- and agent-readable Markdown report.<video>_report.html— interactive HTML report (video player, subtitle sync, annotations, human review workflow).- captured screenshots for each finding.
A preprocess run writes a transcript-first bundle (transcript.txt,
transcript.timestamped.txt, transcript.segments.json, transcript.vtt,
preprocess.json, and optionally audio.mp3) into <video>_preprocess next to
the video, or <folder>/<video>_preprocess when -o names an existing folder
that is not a previous preprocess bundle.
Documentation
- USAGE.md — comprehensive command and flag reference, workflows, and troubleshooting.
- docs/ARCHITECTURE.md — pipeline, servers, report layer, CLI, and module map for developers and contributors.
- docs/SHOWCASE.md — feature showcase and sample artifacts.
- See an example report:
examples/— a neutral sample report (JSON, VTT); from a source checkout, runuv run python examples/generate_example.pyto build the self-contained interactive HTML and open it in a browser. - CHANGELOG.md — release history.
Contributing
Contributions are welcome. See CONTRIBUTING.md to get started, and please review our Code of Conduct. To report a security issue, see SECURITY.md.
License
Business Source License 1.1 (BUSL-1.1) — see LICENSE.
Built by Vetcoders.
1 maintainer

Metadata
1 maintainer
Release files for screenscribe 0.1.21
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| screenscribe-0.1.21.tar.gz | 3.6 MB | With provenance | Details for screenscribe-0.1.21.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| screenscribe-0.1.21-py3-none-any.whl | Python 3 | none | any | Details for screenscribe-0.1.21-py3-none-any.whl |
Total release size: 4.3 MB
Release files / screenscribe-0.1.21.tar.gz
| Download URL | screenscribe-0.1.21.tar.gz |
|---|---|
| Size | 3.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
60964d40485cb5d2399b8a99d6266959b7634be208b7f6b317b46a57069a6657
|
|
BLAKE2b-256 checksum How to use checksums |
dc9a0b70edadd5222df989e131ba6435a6a12beed119c6bc0e6b7631aaec7567
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logRelease files / screenscribe-0.1.21-py3-none-any.whl
| Download URL | screenscribe-0.1.21-py3-none-any.whl |
|---|---|
| Size | 627.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
876d3edbcc0b18efde41ee23e9b37710086c76f9b93df409ae1ce0a2eb267d9f
|
|
BLAKE2b-256 checksum How to use checksums |
99dff7f2b1607b496ec440fd5a8eaa1c3fc2c127f07a0c32ffcf3b4c1fb4a2d7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logSecurity for screenscribe 0.1.21
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for screenscribe-0.1.21.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 3, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














