
Sillage
Your language model forgets everything. Sillage gives it a memory — and a way to keep learning — in a fixed handful of megabytes, with no gradients and no datastore of hidden states that grows.
sillage (n., French) — the trace left behind by something that has passed: a ship's wake, a scent in a room. What a model keeps of what it read.
A frozen language model reads your documents, remembers them, and predicts better next time. No gradients, no fine-tuning, no vector database. One Hebbian matrix written as the model reads, a semantic tier routed by confidence, a cold store that consolidates by surprise, and a rank-16 adapter on the readout — four mechanisms, eight preprints, one command-line tool. Everything runs on a laptop CPU, and on a GPU when there is one.
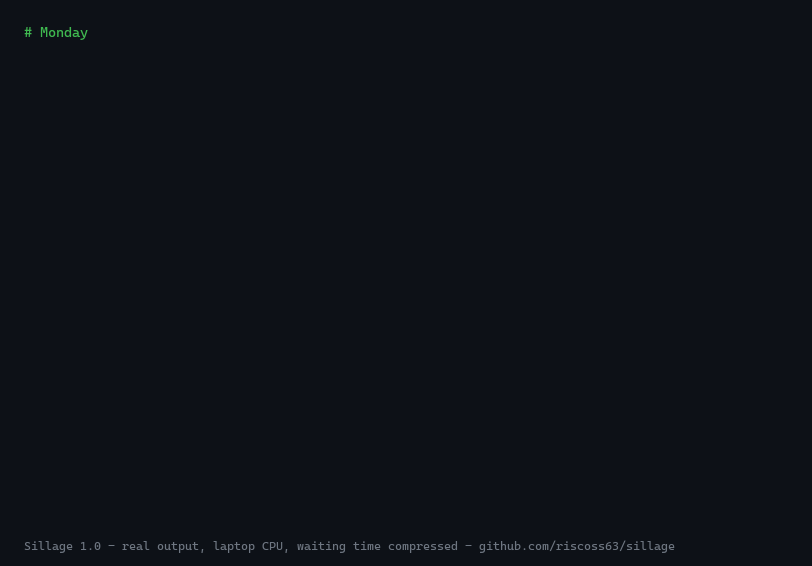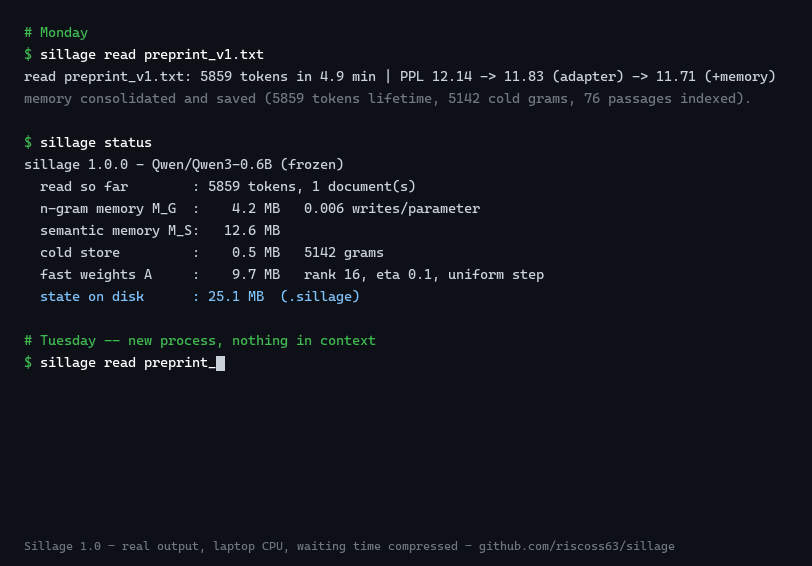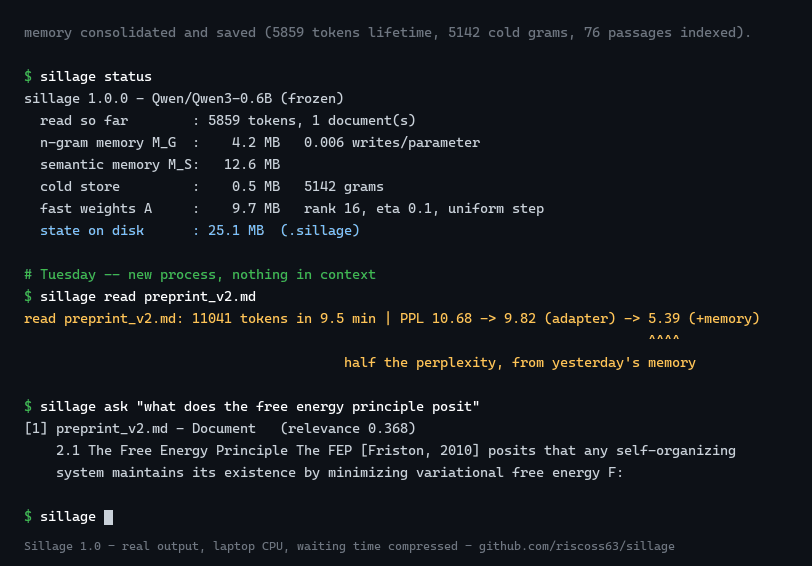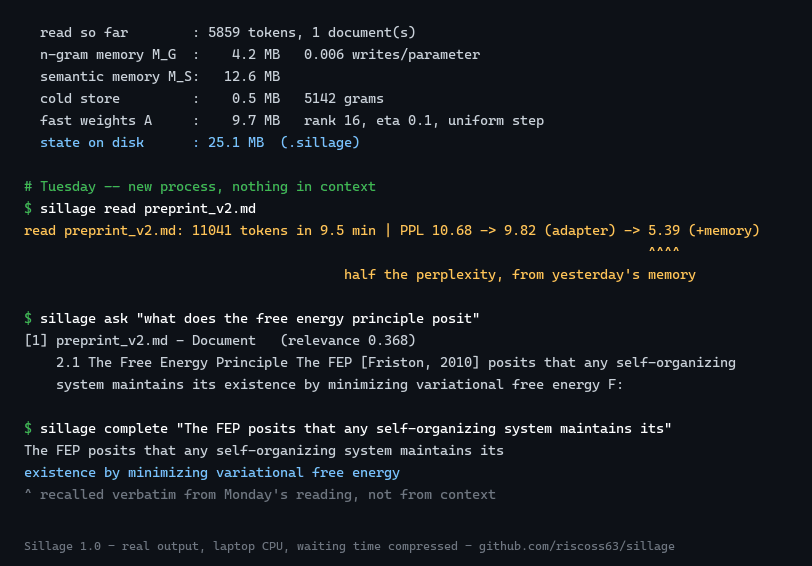
Try it in your browser first — no install, no account.
Install
pip install sillage
Use
sillage index notes.md                # instant: no model, already queryable
sillage ask "what did the report say?"

sillage read notes.md                 # memorize it (CPU: ~8 min per 10k tokens)
sillage read big_corpus.md --fast     # writes only, ~40x (half with --sem2)
sillage complete "The report said"    # generate WITH the memory
sillage complete "The report said" --fast   # same output, speculative (paper 5)
sillage complete "..." --cold-mass    # weight recalls by surprise, not counts (paper 6)
sillage read notes.md --sem2 auto     # keys from an early layer: paraphrases recall too (paper 8)
sillage serve                         # OpenAI endpoint for any client (paper 7)
sillage watch ~/notes                 # read a folder as it changes, ranked by how unusual
sillage review                        # what is about to be forgotten (paper 6)
sillage export cartridge/             # share the matrices, not your text
sillage pull user/cartridge           # open somebody else's, from the Hub
sillage read notes.md --reflow        # rejoin wrapped lines: 7/8 -> 8/8 facts recalled
sillage complete "..." --readout family     # louder recall, more locality cost (paper 5)
sillage read notes.md --dtype bfloat16  # quantise so a bigger model fits (not for speed)
sillage status                        # what it knows, tier by tier
sillage chat                          # ask and generate in one session
sillage demo notes.md                 # two sessions on one document, start to finish
sillage forget --all
$ sillage read preprint_v1.txt                    # Monday, memory empty
read preprint_v1.txt: 5859 tokens in 4.9 min | PPL 12.14 -> 11.83 (adapter) -> 11.71 (+memory)

$ sillage read preprint_v2.md                     # Tuesday, a new process
read preprint_v2.md: 11041 tokens in 9.5 min | PPL 10.68 -> 9.82 (adapter) -> 5.39 (+memory)
Three numbers per file: what the frozen model alone predicts, what the
rank-16 adapter adds, and what the memory of everything read so far adds on
top. The state lives in ./.sillage and survives restarts. Its size is fixed
the day you start, because the shape of the matrices is: 7.4 MB with GPT-2
and 26.5 MB with Qwen3 (25 MiB — the figure paper 5 quotes) — 4.2 MB of
n-gram matrix, 12.6 MB of semantic tier (on by default with --model qwen,
opt-in elsewhere) and a vocab x 16 adapter that is 3.2 MB at GPT-2's
vocabulary and 9.7 MB at Qwen3's; --sem2-whiten adds 2-4 MB. The file on
disk is compressed, so it starts smaller and grows toward that ceiling as the
matrices fill — the same after one document or ten thousand. It never learns
from its own generations — only from what you give it to read.
The grounded-retrieval index (index.json — the verbatim passages
sillage ask quotes) sits beside the memory and does grow with what you
read. It is not what the model predicts from, and sillage forget --all
clears both.
From Python:
from sillage import Sillage

s = Sillage(model="gpt2")          # any causal LM; omit it and the state
                                   # says which model it belongs to
s.read("notes.md")                 # read, memorize, index -- then save
s.ask("what did the report say?")  # exact passages, nothing generated
print(s.complete("The report said"))
How much better, exactly?
On 36k tokens of technical text the model had never seen (frozen GPT-2 124M, every system tuned identically on a held-out prefix, 95 % bootstrap CIs):
| system | perplexity | change | memory used |
|---|---|---|---|
| frozen GPT-2 | 31.2 | — | 0 |
| + RAG-style retrieve & rescore | 29.9 | −4 % | corpus + index |
| + kNN-LM, unbounded store | 23.6 | −24 % | 55 MB, grows forever |
| + this memory (fixed) | 19.2 | −38 % | 4.2 MB, constant |
| + memory and fast weights | 16.8 | −46 % | 7.4 MB, constant |
(The last row is the rank-16 adapter the tool ships. Paper 4's +0.633-nat headline uses a rank-256 adapter — 51 MB of adapter for the last 0.015 nats (perplexity 16.8 -> 16.6).)
The fixed 4.2 MB memory beats the unbounded datastore it was designed to approximate — paired bootstrap P = 1.000, replicated over 5 random seeds. On a second model (Qwen3-0.6B) it statistically matches that unbounded store at one-sixteenth the memory; every internal ordering replicates.
Where it does not win: on long, low-repetition narrative text, kNN-LM still beats it. This memory captures verbatim recurrence; that is its regime, and it is measured and published rather than hidden.
Any causal language model, on CPU or GPU
sillage read notes.md --model qwen                          # shortcut
sillage read notes.md --model HuggingFaceTB/SmolLM2-135M    # any hub id
sillage read notes.md --model ./my-finetuned-llama          # any local folder
sillage read notes.md --device cuda                         # if you have one
Verified across three architectures (GPT-2, Qwen3, GPT-NeoX). Three things worth knowing before pointing it at a new model:
- The readout tunes itself. For a model nobody has tuned, it calibrates on a rolling window of what you read, following the papers' protocol: the winner governs the next read, never the one it was fitted on. For the two models the papers did tune, their published settings are kept — refitting those on a cold memory measurably loses (+0.109 against +0.120 nats).
- A memory lives in one model's token space. Give each model its own
--statedirectory; the state remembers which model it belongs to and refuses to be opened by another. - The GPU only does the frozen forward passes.
--device cudamoves the model; the mechanisms stay in numpy on the CPU, where they belong — they are rank-1 updates, not matrix multiplications. Defaults to the GPU when there is one.
Requires Python 3.10+, numpy, torch and transformers. Nothing else, and
no network at all for reading, asking or generating once the frozen model is
cached — sillage pull is the one command that goes to the Hub, by design.
The eight preprints
| # | title | DOI |
|---|---|---|
| 1 | Sillage: Surprise-Gated Amplitude Memory for Frozen Language Models | 10.5281/zenodo.22079016 |
| 2 | Route the Scores, Not the Keys | 10.5281/zenodo.22079444 |
| 3 | One Signal, Three Tiers | 10.5281/zenodo.22079471 |
| 4 | Memory Remembers, Fast Weights Adapt | 10.5281/zenodo.22079481 |
| 5 | The Memory Pays for Itself | 10.5281/zenodo.22109220 |
| 6 | Stored Is Not Recalled | 10.5281/zenodo.22125859 |
| 7 | Found Is Not Formulated | DOI pending |
| 8 | The Key Was in the Wrong Layer | DOI pending |
Sources, figures, every number as committed JSON, the reproduction pipeline and the three negative results are on GitHub: https://github.com/riscoss63/sillage
Citation
@article{sghairi2026sillage,
  title  = {Sillage: Surprise-Gated Amplitude Memory
            for Frozen Language Models},
  author = {Sghairi, Abderrahmane},
  year   = {2026},
  doi    = {10.5281/zenodo.22079016},
  url    = {https://doi.org/10.5281/zenodo.22079016}
}
MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for sillage 1.9.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sillage-1.9.1.tar.gz | 92.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sillage-1.9.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 169.8 kB
Release files / sillage-1.9.1.tar.gz
| Download URL | sillage-1.9.1.tar.gz |
|---|---|
| Size | 92.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f1fd30b506a74b806606dcad5890c4bfc2e6fb2bc4fdea12d9350da1923c3540
|
|
BLAKE2b-256 checksum How to use checksums |
f3ae592c96df2d6926c88a3198ac8ced22d4f46c367ef907e72d9ac7db5c0ab4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.11
|
Release files / sillage-1.9.1-py3-none-any.whl
| Download URL | sillage-1.9.1-py3-none-any.whl |
|---|---|
| Size | 77.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
02f4b46bd7f07e2a1c360517d41ef87cdff3c96cdee7aa225673a7548a423e57
|
|
BLAKE2b-256 checksum How to use checksums |
3f69f254b8c0d15c0071d5aacaad527bea913a59c9f3670901429f08bf8adf7c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.11
|














