
sklearn-genetic-opt
Hyperparameter tuning and feature selection for scikit-learn models using genetic algorithms.


sklearn-genetic-opt is a scikit-learn-compatible optimization toolkit for users who want an evolutionary alternative to GridSearchCV and RandomizedSearchCV. Its genetic algorithm evaluates complete parameter configurations and uses promising candidates to guide later generations. It also provides GAFeatureSelectionCV, a wrapper-based selector that evaluates feature subsets with cross-validation.
If sklearn-genetic-opt saves you time, consider starring the GitHub repository. It helps more practitioners discover the project.
Why use sklearn-genetic-opt?
Familiar scikit-learn API — GASearchCV supports fit / predict / best_params_ and works with sklearn estimators and scoring.
Adaptive search — genetic operators recombine complete configurations using feedback from earlier evaluations.
Joint feature selection and tuning — run GAFeatureSelectionCV and GASearchCV in a two-stage workflow; no separate feature-selection library needed.
Mixed search spaces — Integer, Continuous (uniform or log-uniform), and Categorical types in the same search.
Smart initialization — Latin hypercube seeding, estimator defaults, warm-start configs, and duplicate avoidance diversify the first generation.
Early stopping callbacks — ConsecutiveStopping, DeltaThreshold, and TimerStopping end the search automatically when it converges or runs out of time.
Adaptive schedules — crossover and mutation rates anneal over generations, shifting from exploration to exploitation.
Optimization history and plots — per-generation fitness, diversity, and telemetry stored in history; built-in plots visualize the full search.
MLflow integration — optionally log evaluated candidates as child runs for experiment comparison.
Parallel execution — n_jobs=-1 parallelizes candidate or fold evaluation.
When should you use it?
You can budget several generations of cross-validated evaluations.
Your search space contains mixed parameter types or suspected interactions.
You want feature selection and hyperparameter tuning in a reproducible workflow.
You want optimization history, convergence plots, callbacks, or MLflow tracking built in.
You have known-good configurations to warm-start from (prior runs, published defaults).
You want an adaptive search to compare with a fixed-budget random-search baseline.
When should you NOT use it?
You need a fast baseline — start with a fixed configuration or RandomizedSearchCV(n_iter=20); it’s faster and good enough to validate your pipeline.
Your grid is tiny (fewer than 50 combinations) — GridSearchCV covers it exhaustively and is simpler to reason about.
Your fits are very cheap — population management may cost more than it saves compared with a simple baseline.
You need conditional or distributed optimization — consider Optuna’s define-by-run search and distributed storage.
How it compares
Tool |
Best for |
Key limitation |
Where sklearn-genetic-opt helps |
|---|---|---|---|
GridSearchCV |
Small, fully discrete grids; guaranteed complete coverage |
Combinatorial explosion on 4+ params; no continuous params natively |
Large, mixed, or continuous spaces with interacting parameters |
RandomizedSearchCV |
Larger budgets; simple independent parameter spaces |
No learning from past evaluations; treats each parameter independently |
Recombines promising configurations; adaptive schedules; early stopping |
Optuna |
Sequential Bayesian (TPE) search; distributed optimization; neural architecture search |
Usually needs an objective function or an integration wrapper for sklearn CV |
Familiar sklearn search API; built-in GAFeatureSelectionCV |
RFE |
Greedy feature elimination for models with coef_ or feature_importances_ |
Greedy and sequential; can miss non-greedy optimal subsets |
Searches candidate subsets; works with sklearn-compatible estimators |
SelectFromModel |
Fast embedded selection via a threshold on feature importance |
Tied to model-specific importances; no cross-estimator comparison |
Estimator-agnostic wrapper; combinable with hyperparameter tuning in one workflow |
sklearn-genetic-opt |
Mixed spaces; two-stage feature selection and tuning; history, plots, callbacks |
Slower than Bayesian methods on small smooth spaces; population size needs tuning |
— |
Quick Start
Install
pip install sklearn-genetic-opt
# With optional plotting, MLflow, and TensorBoard extras:
# pip install sklearn-genetic-opt[all]
Hyperparameter search
from sklearn.datasets import load_breast_cancer
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import StratifiedKFold, train_test_split

from sklearn_genetic import GASearchCV, EvolutionConfig, RuntimeConfig
from sklearn_genetic.space import Categorical, Continuous, Integer

X, y = load_breast_cancer(return_X_y=True)
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, stratify=y, random_state=42
)

search = GASearchCV(
    estimator=RandomForestClassifier(random_state=42),
    param_grid={
        "n_estimators": Integer(50, 300),
        "max_depth":    Integer(3, 20),
        "max_features": Continuous(0.1, 1.0),
        "class_weight": Categorical([None, "balanced"]),
    },
    cv=StratifiedKFold(n_splits=5, shuffle=True, random_state=42),
    scoring="roc_auc",
    evolution_config=EvolutionConfig(population_size=15, generations=12),
    runtime_config=RuntimeConfig(n_jobs=-1, verbose=True),
    random_state=42,
)
search.fit(X_train, y_train)

print(search.best_params_)          # best hyperparameter configuration
print(search.best_score_)           # best cross-validated ROC-AUC
print(search.score(X_test, y_test)) # test-set score
Use a starter preset
from sklearn_genetic import random_forest_classifier_space, xgboost_classifier_space

rf_param_grid = random_forest_classifier_space(profile="balanced")
xgb_param_grid = xgboost_classifier_space(profile="balanced")
Convert a RandomizedSearchCV-style space
from scipy import stats

from sklearn_genetic.space import from_sklearn_space

param_grid = from_sklearn_space({
    "n_estimators": stats.randint(50, 300),
    "max_depth": [3, 5, 10, None],
    "max_features": stats.uniform(0.1, 0.9),
})
Feature selection
import numpy as np
from sklearn.datasets import load_iris
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import StratifiedKFold, train_test_split

from sklearn_genetic import GAFeatureSelectionCV, EvolutionConfig, RuntimeConfig

X, y = load_iris(return_X_y=True)
# Add 8 noise features — the selector should drop them
X = np.hstack([X, np.random.default_rng(42).uniform(0, 1, (X.shape[0], 8))])
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, stratify=y, random_state=42
)

selector = GAFeatureSelectionCV(
    estimator=RandomForestClassifier(n_estimators=100, random_state=42),
    cv=StratifiedKFold(n_splits=5, shuffle=True, random_state=42),
    scoring="accuracy",
    evolution_config=EvolutionConfig(population_size=20, generations=15),
    runtime_config=RuntimeConfig(n_jobs=-1, verbose=True),
    random_state=42,
)
selector.fit(X_train, y_train)

print(selector.support_)                    # boolean mask of selected features
print(selector.score(X_test, y_test)) # accuracy on selected featuresWhat you can do
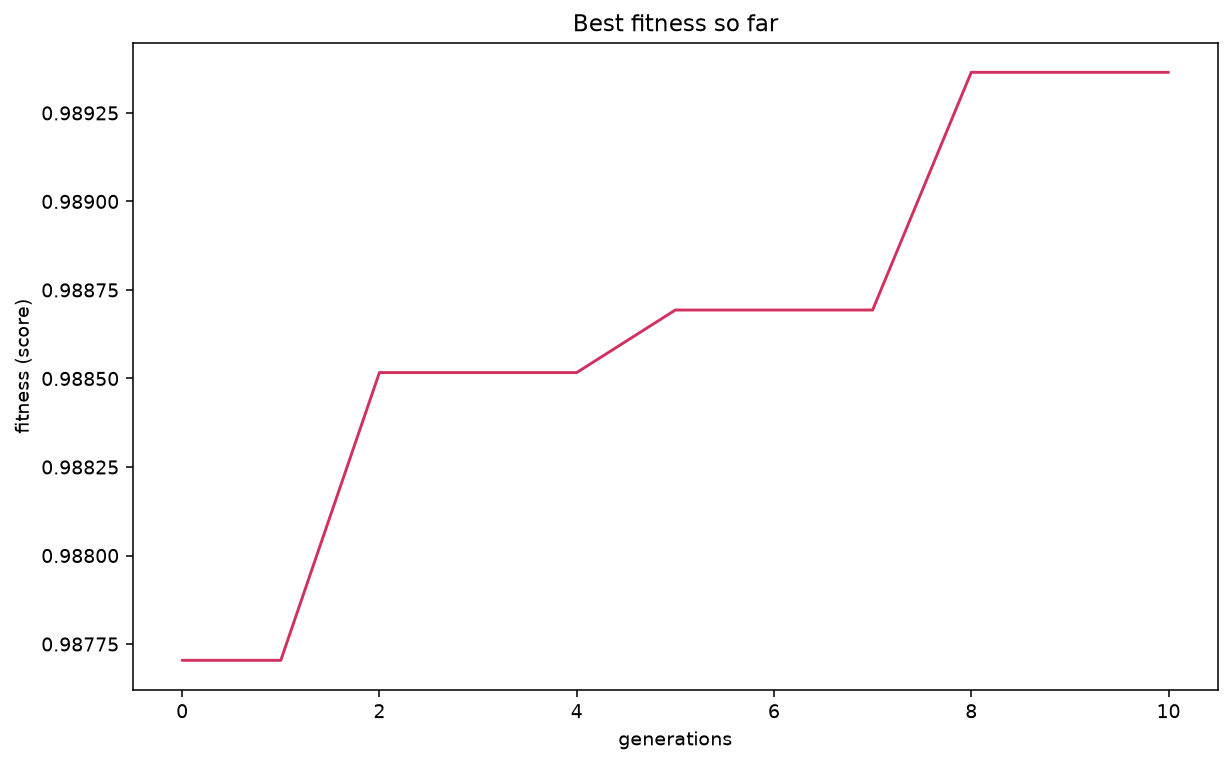
Track optimization progress generation by generation. The fitness curve shows when the search converges so you know whether to add more generations or stop early.
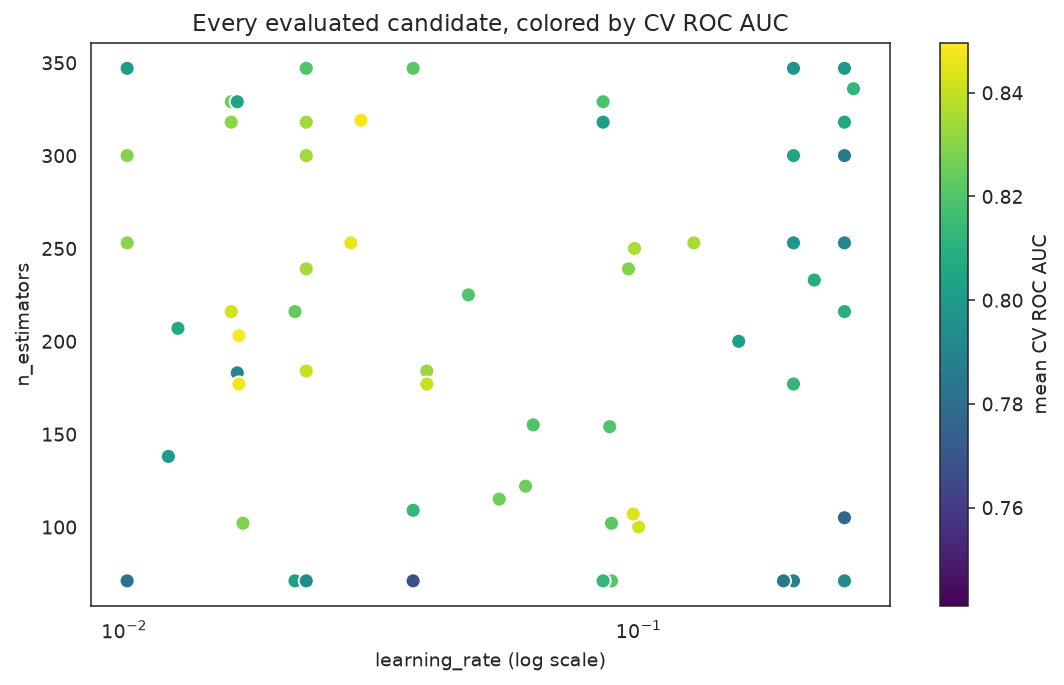
See where the search explored and which parameter combinations scored highest. The scatter plot reveals the productive region of the learning_rate × n_estimators interaction — a band a one-at-a-time sweep cannot find.
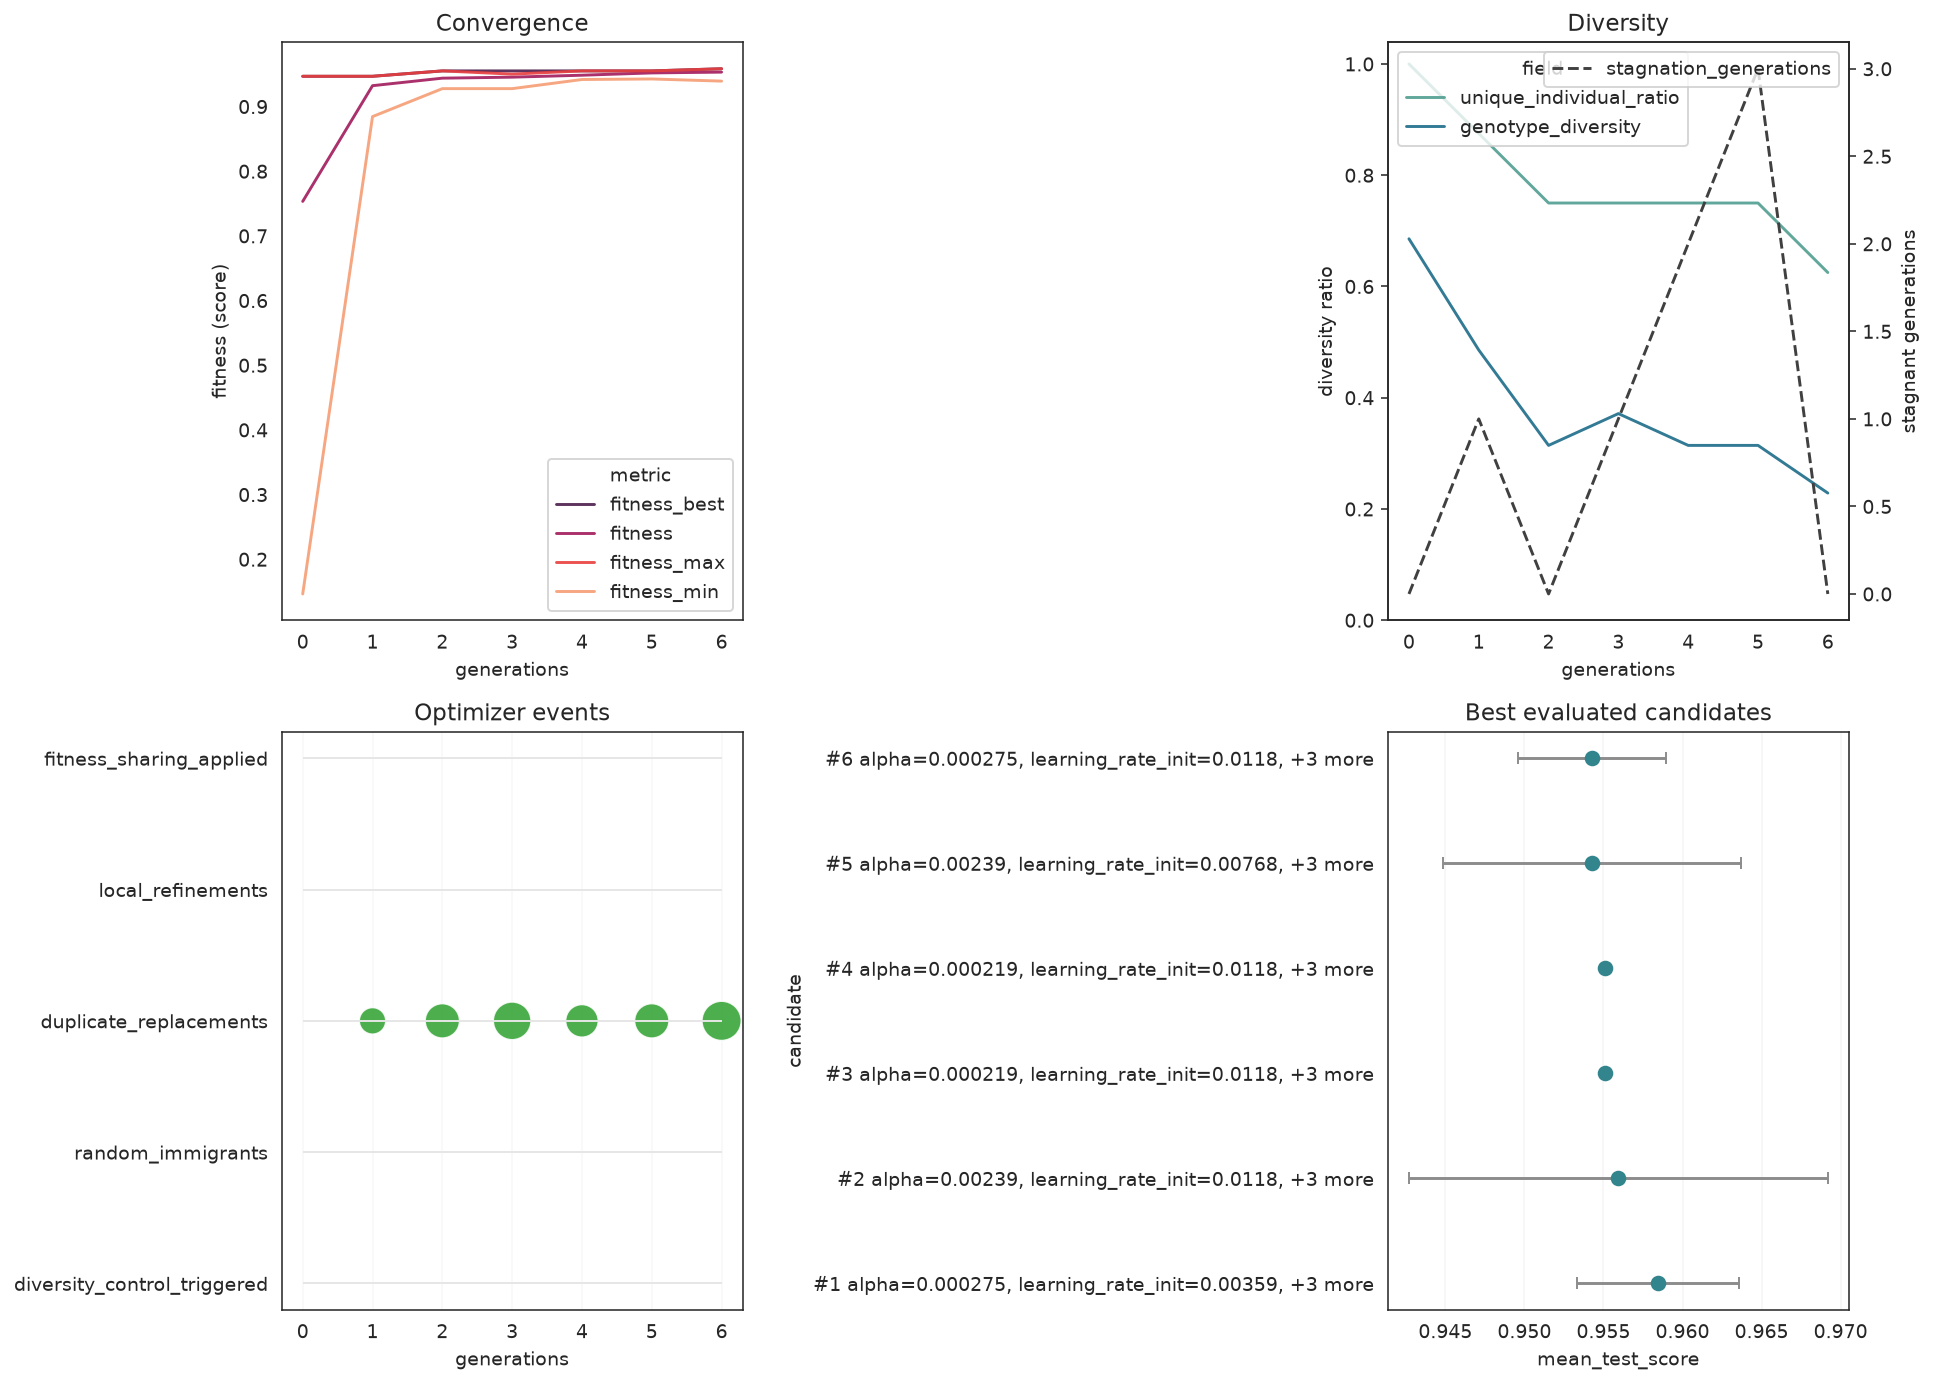
Inspect the full search in one view. The search overview panel combines scores, parameter distributions, diversity, and candidate decisions.
Common use cases
Hyperparameter tuning
Tune RandomForestClassifier — 7-parameter joint search, classification and regression
Tune XGBoost — 9 interacting params, n_jobs=1 oversubscription fix, interaction visualization
Tune LightGBM — num_leaves / max_depth interaction, parameter scatter plots
Tune CatBoost — bagging_temperature, border_count, GPU tip
Tune Gradient Boosting (sklearn) — HistGBM vs classic GBM, speed comparison
Tune Logistic Regression — solver / penalty compatibility, multi-penalty with SAGA
Tune SVM (C, kernel, gamma) — C–gamma interaction, mandatory Pipeline + StandardScaler
Tune a scikit-learn Pipeline — step prefix patterns, ColumnTransformer
Tune for imbalanced datasets — class_weight as a search param, balanced accuracy
Feature selection
Feature selection with genetic algorithms — 3-stage: select, retune, validate
Combine feature selection + hyperparameter tuning — two-stage pipeline recipe
Experiment tracking and tooling
MLflow experiment tracking — log every candidate as a child run
Callbacks and early stopping — ConsecutiveStopping, TimerStopping, DeltaThreshold
Checkpointing and resume — save and continue long searches
Visualize optimization progress — full gallery of available plots
Citation
If sklearn-genetic-opt supports your research or a published project, please cite the software version you used. GitHub can generate a citation from CITATION.cff through the “Cite this repository” button, and citation managers can read the same metadata directly from the repository.
Recommended citation:
Arenas, R. (2026). sklearn-genetic-opt: Hyperparameter tuning and feature
selection using genetic algorithms, built on top of scikit-learn (Version
0.14.0) [Computer software].
https://github.com/rodrigo-arenas/Sklearn-genetic-opt
BibTeX:
@software{arenas_2026_sklearn_genetic_opt,
  author = {Arenas, Rodrigo},
  title = {{sklearn-genetic-opt}: Hyperparameter tuning and feature selection
    using genetic algorithms, built on top of scikit-learn},
  year = {2026},
  version = {0.14.0},
  url = {https://github.com/rodrigo-arenas/Sklearn-genetic-opt}
}
Learning paths
- New user
Install → Getting Started with GASearchCV → How Hyperparameter Optimization Works → Pick a Recipe
- ML practitioner
When to Use Genetic Algorithm Search → Choosing the Right Search Space → Model-specific Tutorials → Optuna vs sklearn-genetic-opt
- Contributor
Benchmarks
The repository includes benchmark scripts that compare GASearchCV against RandomizedSearchCV, GridSearchCV, and Optuna (TPE) using the Bayesmark experimental design — same datasets, same search spaces, equal evaluation budget:
pip install sklearn-genetic-opt[benchmark]
python benchmarks/benchmark_bayesmark.py --quick
See the Benchmarks documentation for methodology and full results.
Installation
# Core package
pip install sklearn-genetic-opt

# With plotting, MLflow, and TensorBoard:
pip install sklearn-genetic-opt[all]

# conda
conda install -c conda-forge sklearn-genetic-opt
Requires Python ≥ 3.12 and scikit-learn ≥ 1.5.0. See Installation for the full requirements table and optional extras.
Contributing
Contributions of all sizes are welcome — from fixing a typo to adding a new tutorial or benchmark.
Good ways to start:
Add a Recipe for an estimator or workflow not yet covered — see existing Recipes.
Write or improve a tutorial (new models, edge cases, regression examples).
Test with a new estimator from another framework and report the results.
Add a benchmark comparing search methods on a real dataset.
Fix typing, CI, or formatting — black . keeps the style consistent.
Answer questions in open issues.
Share your work — add a blog post, article, or video to the Community Articles page.
git clone https://github.com/rodrigo-arenas/Sklearn-genetic-opt.git
cd Sklearn-genetic-opt
pip install -r dev-requirements.txt
pytest sklearn_genetic
Read the contribution guide before opening a pull request. If you are not sure where to start, open an issue and ask — small contributions are very welcome.

Links
1 maintainer

Metadata
1 maintainer
Release files for sklearn-genetic-opt 0.14.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sklearn_genetic_opt-0.14.0.tar.gz | 90.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sklearn_genetic_opt-0.14.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 183.4 kB
Release files / sklearn_genetic_opt-0.14.0.tar.gz
| Download URL | sklearn_genetic_opt-0.14.0.tar.gz |
|---|---|
| Size | 90.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cd0ac5648e0b0b0ea883752d8fbd17469459762e48d0db6fd154d879b013ba23
|
|
BLAKE2b-256 checksum How to use checksums |
3868f595e3f5f5c82643a4dfac7f32889e828e95563323d8aa670d70568ab10b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency logRelease files / sklearn_genetic_opt-0.14.0-py3-none-any.whl
| Download URL | sklearn_genetic_opt-0.14.0-py3-none-any.whl |
|---|---|
| Size | 93.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9ee52edddd5a5e0915eb3c64a94adb726419d880c64a9d04ff24212cd9ec353f
|
|
BLAKE2b-256 checksum How to use checksums |
4b2e083ee59e59790723fd5d1fa189f8c55e5752e1efa07f90bcbf004823d350
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 10, 2026.
Transparency log













