
Turn any web page, or a whole site, into structured data.
No model, no API key, no bill.





Documentation · In your agent · Scoreboards · Why Sluicer · Discussions · Changelog
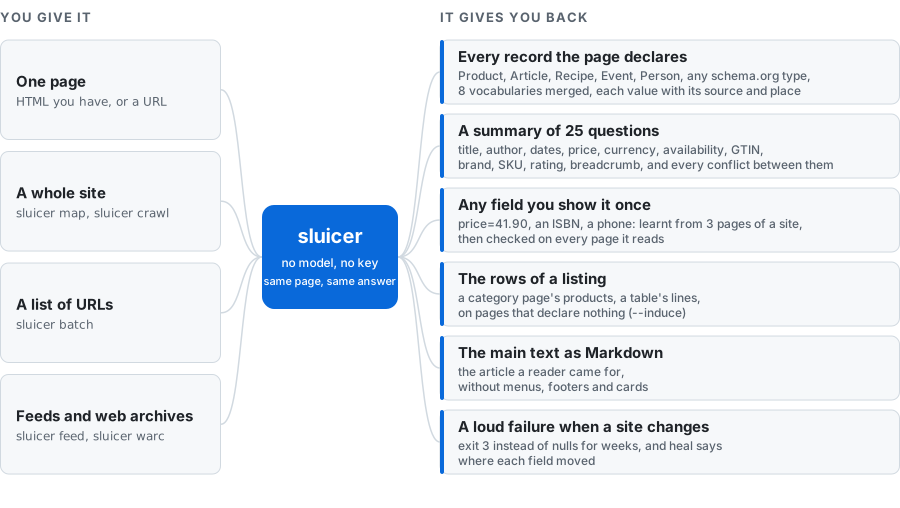
Sluicer reads everything a web page declares about itself -- products, articles, recipes, events, people, prices, dates, in JSON-LD, microdata, RDFa, OpenGraph and four more vocabularies -- and merges it into one record per thing, every value naming the vocabulary and the place on the page it came from. Where a page declares nothing, show it one example of the value you want and it learns where that value sits on every page of the site, then says so when the site changes. One page, a list of URLs, or a whole site: no model reads any of them, so the same page always gives the same answer.
📏 Why the scoreboards below talk about title, author and date. Those are the fields public test sets label by hand, so they are what can be scored against a right answer somebody else wrote. They measure a part of what Sluicer reads, not all of it. The products scoreboard measures prices and availability, and SWDE the fields you teach an extractor: 32 kinds, from prices, ISBNs and engines to phone numbers, addresses and job locations, on 80 sites.
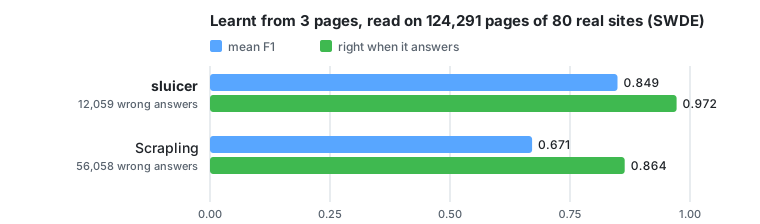
SWDE: cars, books, cameras, jobs, films, NBA players, restaurants and universities, 32 kinds of field on 80 sites. On the half of the sites never read while the rules were made, Sluicer scores 0.845. Every number, and how it was made.
Which way in
| you have | run | and get |
|---|---|---|
| a page, as HTML or a URL | sluicer extract page.html |
every record it declares, the 25-question summary, its conflicts, each value with where it came from |
| a page that declares nothing | sluicer extract page.html --induce |
the rows its markup repeats: a listing's cards, a table's lines |
| a whole site | sluicer map URL, sluicer crawl URL -o site.jsonl |
its addresses from its sitemaps, or every page it links to, each read as above, politely |
| a list of URLs, a feed, a web archive | sluicer batch urls.txt, sluicer feed URL, sluicer warc crawl.warc.gz |
one JSON line per page |
| many pages of one template | sluicer compile a.html b.html c.html --want price=41.90 -o shop.json, then sluicer run shop.json URL |
any field you gave an example of, from every page, checked, and exit 3 when the site changes |
| an article | sluicer markdown URL |
its main text as Markdown |
| an AI agent | claude mcp add sluicer -- uvx --with "sluicer[mcp]" sluicer mcp |
ten read-only tools, in any MCP client |
| another language | sluicer serve |
the same tools over HTTP, described at /openapi.json |
Highlights
- 🧩 Eight vocabularies, one record. JSON-LD, microdata, RDFa, Dublin Core, OpenGraph, the Twitter card, HTML's meta names and microformats2, merged into one record per thing.
- 🌐 A page or a whole site.
mapreads a site's sitemaps,crawlfollows its links,batchreads a list,feedandwarcread feeds and web archives: every page comes out with all it declares, one JSON line each. - 📍 Provenance for every value. The vocabulary, the key, and the place on the page: an XPath, and inside JSON-LD a pointer to the very value.
- ❓ A summary of 25 questions -- title, author, date, price, currency, availability, GTIN and the rest -- each answer naming where it came from, and a conflict reported when the page answers one of them two ways.
- 🛡️ Extractors that check every page. Learn one from a few pages of a
template; a page that drifted exits 3 instead of returning nulls for weeks,
and
healsays what moved where. On 44 real redesigns none failed silently. On pages of one template they are right on 97% of their answers, and most of the 3% they get wrong pass their checks: the SWDE scoreboard says which. - ⚡ Deterministic and light. No model and no key: the 511 pages of the WCXB test set are read in 1.4 s, and the base install is three packages.
- 👀 What the page shows, when you ask.
--visibleguesses the heading, byline and dates a page shows a reader, by rules and no model, each guess naming its element and rule and kept apart from what is declared. - 🤝 Polite by construction. It announces itself, obeys robots.txt and
Crawl-delay, waits a site'sRetry-Afterin a crawl, and honours TDMRep reservations when asked. - 🤖 Made for agents. An MCP server with ten read-only tools, tried in Claude Code, Codex and Gemini CLI, and the same tools over HTTP for any language.
- 📊 Measured in public, losses included. Six scoreboards against trafilatura, newspaper4k, metascraper, extruct, Scrapling, Zyte and Diffbot.
Install
uv pip install "sluicer[fetch,markdown,mcp]"
With pip, pip install "sluicer[fetch,markdown,mcp]"; as a command in an
environment of its own, uv tool install "sluicer[fetch,markdown,mcp]". The
base install, uv pip install sluicer, reads HTML you already have with lxml
and click alone. Each extra adds one job:
What each extra adds
| extra | adds |
|---|---|
fetch |
fetching: plain HTTP first, a browser only when a measurement says the page needs one |
markdown |
a page's main content as markdown, by trafilatura |
mcp |
the MCP server, with fetch and markdown |
api |
the HTTP API, with mcp |
microformats |
microformats2, which is off by default |
For the browser rung, once: uvx --from "sluicer[fetch]" scrapling install.
Without it, plain HTTP still works, and a page that wanted a browser comes back
from the HTTP rung with the failed climb recorded.
Quick start
The product page read here is
examples/brake-pads.html.
>>> import sluicer
>>> page = open("examples/brake-pads.html", "rb").read()
>>> result = sluicer.extract(page, url="https://example.com/p/bp-2210")
>>> price = result.summary["price"]
>>> price.value, price.source, price.key
('41.90', 'jsonld', 'Product.offers.price')
>>> price.where
'/html/head/script[1]#/offers/price'
>>> result.normalised
{'price': '41.90', 'currency': 'EUR', 'gtin': '4006381333931'}
>>> [(answer.value, answer.source) for answer in result.conflicts[0].answers]
[('41.90', 'jsonld'), ('39.90', 'opengraph')]
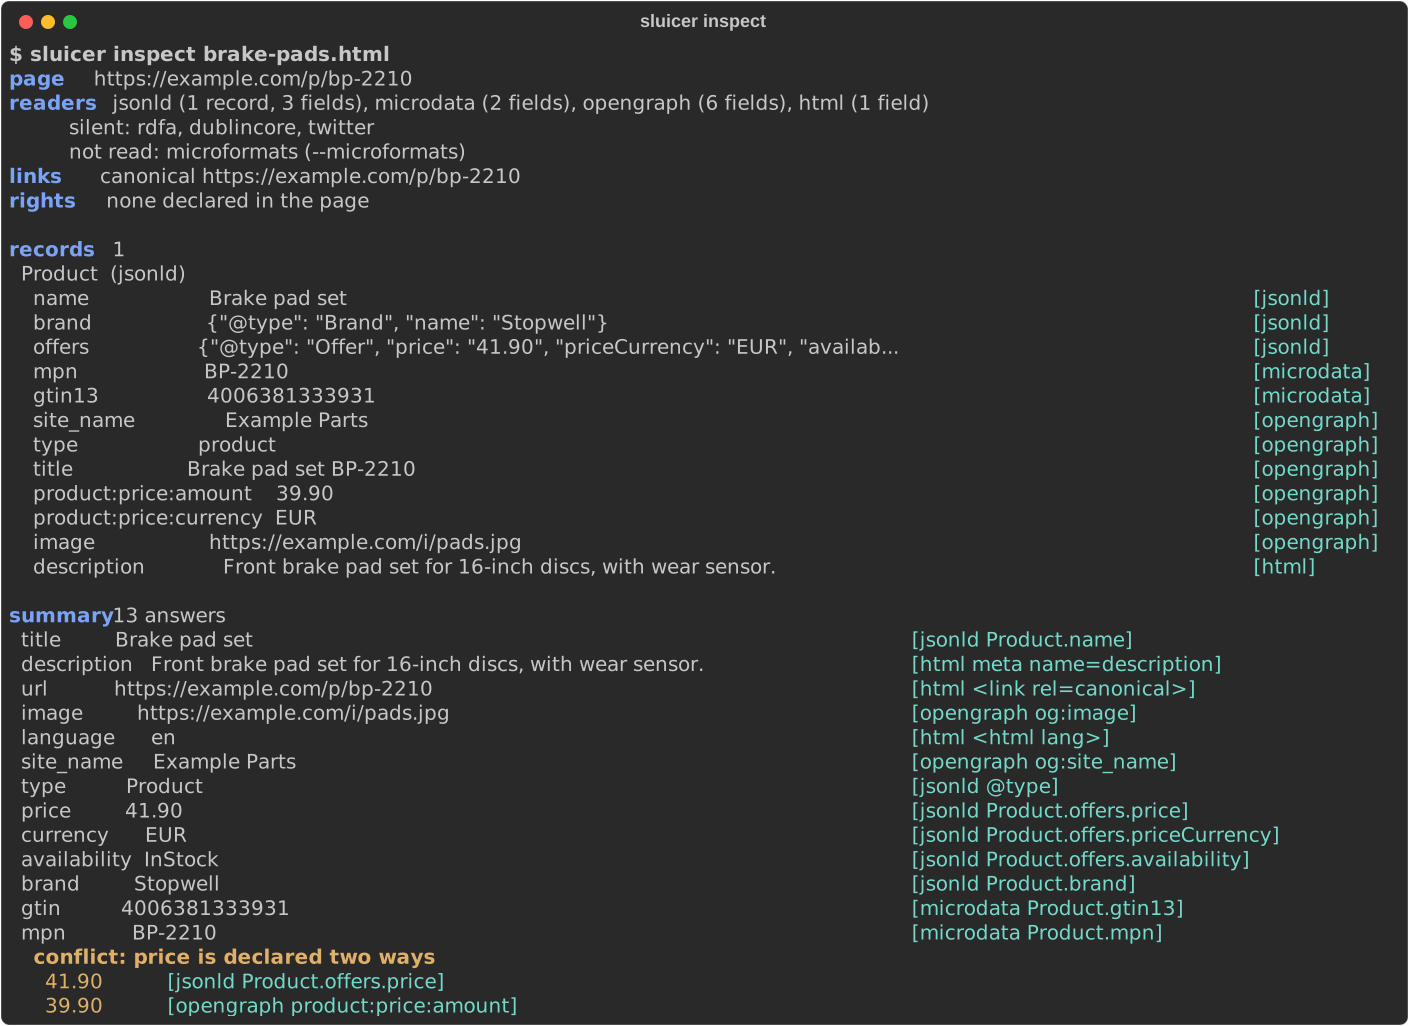
The page describes one product in three vocabularies; result.records holds it
once, each field with its source and place. The same reading from the command
line is sluicer extract for JSON, or sluicer inspect for this:
See it meet a redesign
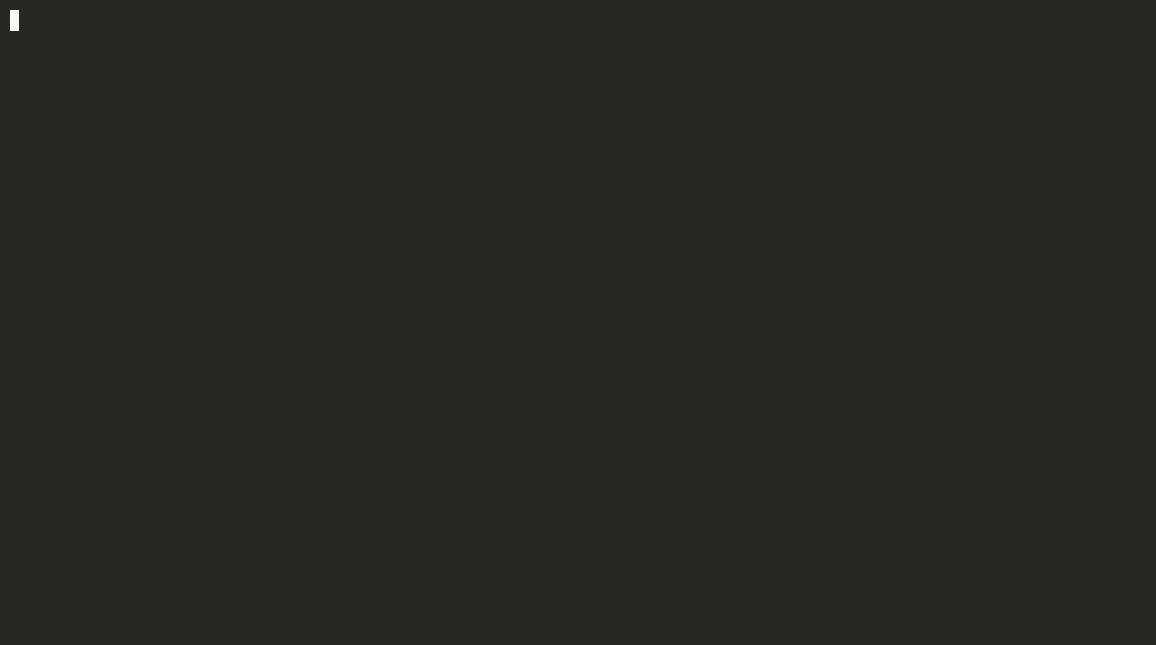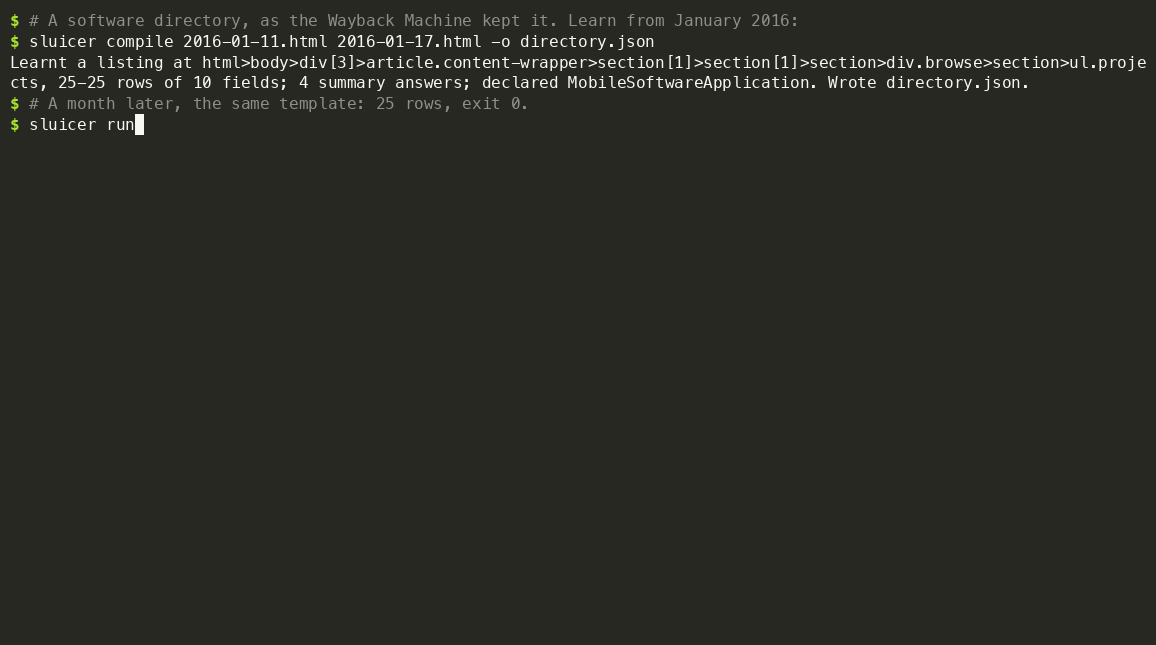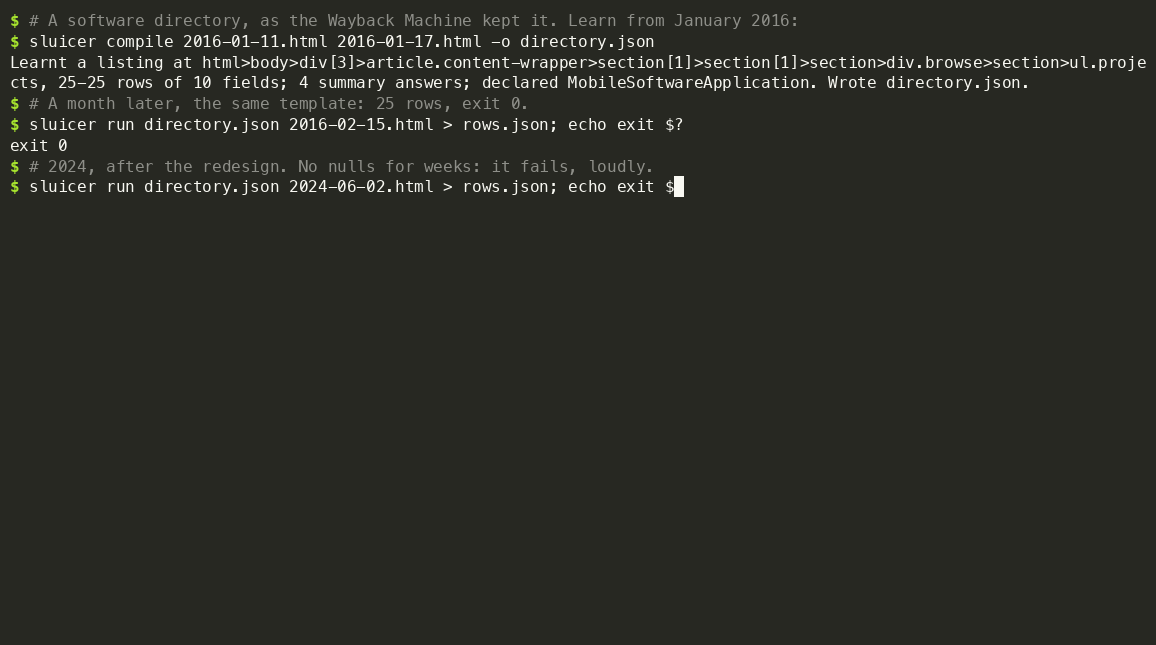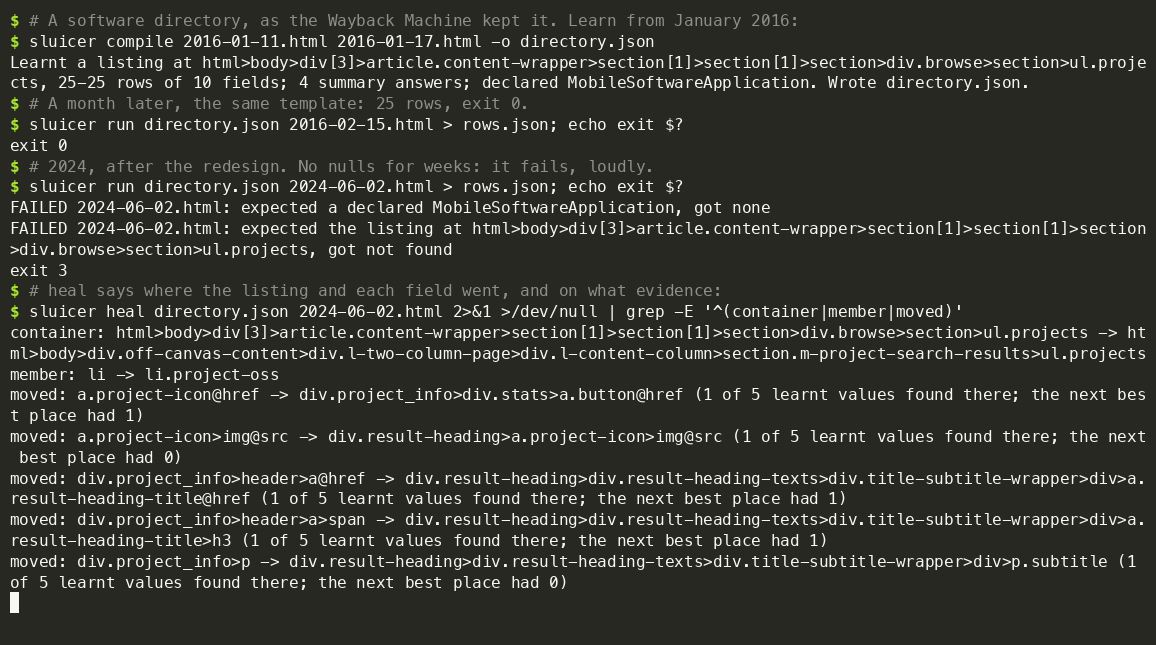
A real site's software directory, as the Wayback Machine kept it. An extractor
learnt from two pages of January 2016 replays a page of February 2016 and exits
0; on the page of June 2024, after the site's redesign, it fails loudly and
exits 3, where a selector would have returned nulls. heal then says where the
listing and each field went, and on how many of the values it learnt each move
rests. Every command ran for real; scripts/demo.py records them again.
Use it
From the command line
sluicer extract page.html                           # a file, a URL, or - for stdin
sluicer inspect https://example.com/product         # the same, for a person to read
sluicer markdown https://example.com/article        # the readable content
sluicer compile page1.html page2.html -o shop.json  # learn an extractor
sluicer run shop.json https://shop.example/c?p=7    # replay it, checked
sluicer heal shop.json https://shop.example/c -o shop.json  # after a redesign
More commands
sluicer extract listing.html --induce               # rows of a page that declares nothing
sluicer diff yesterday.html https://shop.example/p  # what changed, and where from
sluicer diff URL URL --at 2024-01                   # since the Wayback Machine's capture
sluicer extract URL --cache ~/.cache/sluicer        # ask the site if it changed (304)
sluicer audit https://example.com/product           # its markup against Google's documentation
sluicer compile p1.html p2.html -o shop.json --want price=41.90 --want title="Brake pads"
sluicer map https://shop.example/                   # a site's addresses, from its sitemaps
sluicer crawl https://shop.example/ -o shop.jsonl   # follow its links, politely; --resume
sluicer batch urls.txt -o pages.jsonl               # read a list, one JSON line per page
sluicer warc crawl.warc.gz > pages.jsonl            # the pages a web archive holds
sluicer feed https://blog.example/                  # a feed's items, from the page that declares it
Exit codes follow grep: 0 found, 1 nothing declared, 2 could not read, and 3 for a page that broke its extractor, a heal that lost a field, or an audit that found a documented rule broken. A drifted page never exits 0.
In your agent
claude mcp add sluicer -- uvx --with "sluicer[mcp]" sluicer mcp   # Claude Code
codex mcp add sluicer -- uvx --with "sluicer[mcp]" sluicer mcp    # Codex
Cursor, VS Code, Gemini CLI, Claude Desktop and Zed, and LangChain, the OpenAI Agents SDK and Pydantic AI, are in In your agent. The repository is also a Claude Code plugin, with a skill in the open Agent Skills format that Codex reads too. The server has ten tools, all read-only.
The ten tools
| tool | answers |
|---|---|
extract_declared |
what a page declares, with provenance, the summary and its conflicts |
page_markdown |
the page's main content as markdown |
fetch_page |
the page's HTML, and whether it took plain HTTP or a browser |
compile_extractor |
an extractor learnt from pages of one template |
run_extractor |
an extractor replayed on a page, checked against what it learnt |
heal_extractor |
the extractor learnt again after a redesign, and what moved |
audit_page |
the page's markup against what Google documents |
read_feed |
a feed's items: RSS, Atom or JSON Feed |
map_site |
a site's addresses, from its sitemaps or its start page's links |
crawl_site |
a site's pages, following its links, each summarised |
Every answer carries ok, true exactly when it can be used as it is, and an
output schema; every tool says in its annotations that it only reads. The
server fetches nothing on localhost, a private network or a cloud's metadata
endpoint -- redirects and a browser's requests included -- unless started with
SLUICER_ALLOW_PRIVATE=1.
From any other language
sluicer serve answers the same tools over HTTP, POST /v1/tools/<name> with
the tool's arguments as JSON, and describes them at /openapi.json. It listens
on loopback; anywhere else it needs SLUICER_API_TOKEN. See
the HTTP API.
sluicer serve                                       # 127.0.0.1:8000
curl -s http://127.0.0.1:8000/v1/tools/extract_declared \
  -H 'Content-Type: application/json' -d '{"html_or_url": "https://example.com/p"}'
How it compares
| Sluicer | extruct | trafilatura, newspaper4k | CSS-selector scrapers | LLM extraction | |
|---|---|---|---|---|---|
| Structured data merged into one record per thing | yes | no, one list per vocabulary | for a few metadata fields | no | depends on the prompt |
| Where each value came from | vocabulary, key and place | no | no | no | no |
| A whole site, a list of URLs, feeds, web archives | yes, politely | no | sitemaps, feeds and a crawler | with a crawler framework | depends on the service |
| Bylines and dates from the visible text, where nothing is declared | with --visible, as guesses kept apart |
no | yes | where you write selectors | yes |
| The same answer for the same page | yes | yes | yes | yes | not guaranteed |
| A site's changed layout noticed | fails loudly, then heal |
-- | -- | not by itself | not by itself |
| A model or an API key needed | no | no | no | no | yes |
from sluicer.compat import extruct answers extruct's own calls in its own
shapes, for code written against it: see
moving from extruct.
Why Sluicer has the
full comparison, and says when another tool is the better choice.
Measured, losses included
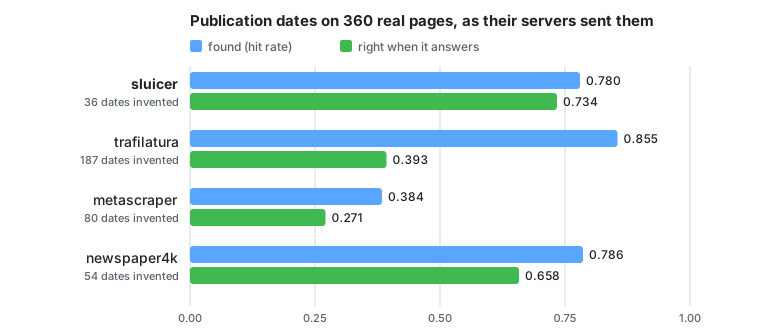
Five of these scoreboards measure title, author and date, because those are the fields their test sets label; products measure price and availability, and SWDE the fields you teach an extractor. On the first five Sluicer reads only what a page declares, so it answers less often than tools that also read the visible page, and is wrong less often when it answers. A hit rate is right answers over the pages that carry a label; an invention is an answer on a page whose label is empty.
| scoreboard | pages | measures | Sluicer | beside it |
|---|---|---|---|---|
| WCXB | 511 | title, author, date, scripts stripped | 0.727, 0.532, 0.581; 8 dates invented | trafilatura 0.745, 0.750, 0.838; 216 invented |
| As served | 360 | the same pages, scripts intact | right on 0.734 of its dates | newspaper4k 0.658, metascraper 0.573, trafilatura 0.393 |
| Products | 140 | price, availability, by Zyte's evaluator | F1 0.750, 0.907 | extruct 0.685, 0.626; Zyte's paid API 0.918, 0.957 |
| News | 263 in 21 languages | title, author, date | 0.871, 0.829, 0.970; never a wrong date | trafilatura finds more authors, 0.879 |
| trafilatura's set | 990 | title, author, date | the most titles, 0.776 | trafilatura 0.738, and more bylines and dates |
| SWDE | 124,291 | extractors learnt from three pages | F1 0.849; 12,059 wrong | Scrapling 0.671; 56,058 wrong |
| Drift | 44 redesigns | a site's change noticed | none failed silently, no false alarm | -- |
Title, author and date, tool by tool
On the 511 annotated test pages of the public WCXB corpus:
| title | author | date | dates invented | seconds | packages | |
|---|---|---|---|---|---|---|
| sluicer 0.7.0 | 0.727 | 0.532 | 0.581 | 8 | 1.4 | 3 |
| trafilatura 2.2.0 | 0.745 | 0.750 | 0.838 | 216 | 16.2 | 17 |
| newspaper4k 0.9.6 | 0.768 | 0.532 | 0.645 | 52 | 29.6 | 22 |
| metascraper 5.58.1 | 0.654 | 0.787 | 0.725 | 84 | 2.8 | 125 |
WCXB strips every <script>, and with it JSON-LD, the vocabulary Sluicer reads
first. The same labels on the 360 of those pages a web archive holds as their
servers sent them, scripts intact:
| as served | title | author | date | right when it answers a date | dates invented |
|---|---|---|---|---|---|
| sluicer 0.7.0 | 0.708 | 0.690 | 0.780 | 0.734 | 36 |
| trafilatura 2.2.0 | 0.756 | 0.860 | 0.855 | 0.393 | 187 |
| newspaper4k 0.9.6 | 0.767 | 0.705 | 0.786 | 0.658 | 54 |
| metascraper 5.58.1 | 0.667 | 0.845 | 0.811 | 0.573 | 80 |
33 of Sluicer's 36 invented dates are dates the page declares in its own JSON-LD and does not show a reader, which is what the labels describe.
Every scoreboard says how it was made and the command that makes it again;
bench/PREREG.md says what each fixes before it is run.
FAQ
Does Sluicer use an LLM anywhere?
No. A test fails the build if a model client is ever imported, and no feature needs anybody's API key. That is what makes the same page give the same answer, and a run cost only CPU.
What if a page declares nothing?
sluicer extract --induce reads the rows the page's markup repeats, a listing's
cards or a table's lines, marked source="induced". And
sluicer compile --want price=41.90 learns where values sit from examples of
them, on listings and on product pages that declare nothing; what it learns is
checked on every page it reads, so a price slot that starts saying "Add to
basket" fails instead of being returned.
Will it get past a site's bot protection?
It is not built to. Every request says Sluicer/<version> with the project's
address, robots.txt is obeyed, and a crawl never climbs to the one rung that
does not announce itself, which a single-page command reaches only with
--stealth. In a crawl, a site that answers 429 or 503 is asked again only
after its Retry-After.
Does it work in my language?
Declared data is the same in every language, and the news scoreboard measures 21 of them; no miss there was down to a page's language. Dates written in words are read with the month names of the 430 languages and regions the Unicode CLDR covers at its modern level, and the numbers with units Chinese, Japanese and Korean write.
Can I get a guess from the visible page when nothing is declared?
Yes, when you ask: sluicer extract --visible, extract(..., visible=True)
or extract_declared with visible read the heading, the byline and the
publication and update dates the page shows, by Sluicer's own rules and no
model. Each answer is a guess naming its element and rule, in a field of its
own, visible, never in the summary, where it would look exactly like a
declared one. An update date is never given as a publication date. On WCXB's
development pages, the only ones the rules were made on, what is declared and
then the guesses find the author on 0.701 of pages, right on 0.849 of answers
with 58 invented, where trafilatura finds 0.698, right on 0.756, with 86; and
the date on 0.736, right on 0.779 with 83 invented, where trafilatura finds
0.833, right on 0.441, with 630. The scoreboards have not measured it yet.
Is it ready for production?
It is Beta: the interface may still change before 1.0, and every change is in the changelog. Each release passes the full test suite on Python 3.10 to 3.14 and property tests that draw thousands of hostile pages, and is measured again on every scoreboard, before it is tagged. Known limits lists what it does not do, measured.
Principles
- No LLM call, anywhere in the path. A test fails the build if a model client is ever imported.
- No paid API. A feature that needs somebody's key does not ship.
- Deterministic. The same page always gives the same answer, which is what makes the scoreboards reproducible.
- Honest about failure. A page that cannot be read says so, and nothing returns a plausible answer where the truth was unavailable.
Documentation
At https://gi0tto.github.io/sluicer/, or in the repository: Why Sluicer · Extractors · In your agent · HTTP API · Audit · Crawling · Scoreboard · Scoreboard, as served · Scoreboard, products · Scoreboard, news · Scoreboard, trafilatura's set · Drift · Moving from extruct · Known limits · Design notes · Examples · Roadmap · Changelog · Security · Contributing
Community
Questions, ideas and what you built with Sluicer go to Discussions. A page Sluicer read wrong is an issue, with the page attached, so that the fix comes with a test. A vulnerability is reported privately, as SECURITY.md says. CONTRIBUTING.md says how to set up, what CI checks and where each part of the code lives.
Sluicer is built and kept up by one person. If it saves you time or a bill, sponsoring it keeps the scoreboards measured and the extractors honest as the web changes.
Licence
MIT, with no vendored code, and two exceptions: sluicer/audit/schema_org.py
holds schema.org's type and enumeration names, which schema.org publishes
under CC BY-SA 3.0, and sluicer/calendar_names.py holds CLDR's month and
weekday names, which Unicode publishes under the Unicode License v3; each of
the two files is distributed under its own (the package's licence expression
is MIT AND CC-BY-SA-3.0 AND Unicode-3.0). The base install needs lxml
and click, both BSD-3-Clause. The extras pull a wider tree that is not all
permissive: tld is tri-licensed MPL-1.1, GPL-2.0-only or LGPL-2.1-or-later,
orjson is MPL-2.0 alongside Apache-2.0 or MIT, and certifi is MPL-2.0. CI
lists every licence in that tree and fails on one nobody has read; see
the licence notes.
1 maintainer

Release files for sluicer 0.7.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sluicer-0.7.0.tar.gz | 2.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sluicer-0.7.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.3 MB
Release files / sluicer-0.7.0.tar.gz
| Download URL | sluicer-0.7.0.tar.gz |
|---|---|
| Size | 2.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d96a0e3dbb17ab9d931016c3ff774268f1bbc62c39eaa30e8f70b6d5ae6805c4
|
|
BLAKE2b-256 checksum How to use checksums |
d1e892128c95958ade1208cffc9d5014aeb8df72e55797ea2f296a0dc4184d81
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency logRelease files / sluicer-0.7.0-py3-none-any.whl
| Download URL | sluicer-0.7.0-py3-none-any.whl |
|---|---|
| Size | 339.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4b2f7f45f335ab5cbe35a80cc16babe4f217fce85c6534e1dd6c703ee3f7ed00
|
|
BLAKE2b-256 checksum How to use checksums |
d4b94c6d4414f9d8e296bd30ff0af2c6689f4e90e728f63b7b6787df0bb4ff08
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency log













