
sonore
Signals and stimuli for auditory research, built for Jupyter.
sonore is a small Python library for making, manipulating, and analyzing sounds
the way hearing scientists think about them. Its analysis and synthesis tools
cover tones, harmonic complexes, shaped and correlated noises, ERB-spaced
subbands, invertible spectrograms, a phase vocoder, interaural cues, HRIR
spatialization of moving sources, synthetic room reverberation, and sound
texture synthesis. Levels are written as levels (snd + 6*dB), times as
seconds (snd[0.1:0.5]), and any sound at the end of a notebook cell plays.
It brings the sounds and representations of hearing research together in one coherent system, held to the following standard: every frame inverts exactly, the mathematics in its design documents is checked by standalone scripts and the code by its tests, and every example in the gallery can be heard beside the code that made it. It is built to learn from and to build on.
The name comes from Pierre Schaeffer's objet sonore, the "sound object": a
sound taken as a thing in its own right and studied for how it is heard rather
than for what produced it. The Sound object at the center of this library is
meant in the same spirit.
▶ Listen to the gallery: every sound in this README and more, each playable next to its plots, with a playhead that follows the sound.

|
Contents |
What it's for
- Psychophysical stimuli. Pure tones, harmonic complexes with any phase
scheme (cosine, sine, alternating, random, Schroeder±), band-limited square,
sawtooth and pulse trains, all on a fixed F0 or following any F0 contour
(an
F0Track, or window times and values) without aliasing, chirps, band-limited and spectrally tilted noise, iterated rippled noise. Everything is reproducible from a seed. - Binaural and spatial hearing. Exact fractional ITDs, ILDs, interaurally correlated noise, Oscor and Phasewarp, windowed ITD/ILD/coherence analysis (broadband or per band), and rendering of static or moving sources through measured HRIRs (PKU-IOA, downloaded on first use, or any SOFA file), with each ear's delay sliding continuously so a source can change distance (level, travel time, Doppler) in a room.
- Synthetic speech. A Klatt-style cascade/parallel formant synthesizer (Klatt, 1980) driven by named parameter tracks (F0, formant frequencies and bandwidths, voicing, aspiration and frication levels), for vowels, consonant continua and breathy voice with every acoustic cue set exactly.
- Speech in noise. Speech-shaped noise from a long-term average spectrum, mixing at a target SNR, ideal binary and ratio masks with exact resynthesis.
- Cochlear-implant and envelope/TFS studies. A perfect-reconstruction ERB filterbank, Hilbert envelopes and fine structure, and a channel vocoder.
- Spectrotemporal modulation. Moving ripples, sums of ripples, and dynamic moving ripples, specified as patterns in time and log-frequency and rendered on tone, harmonic, noise, or low-noise carriers (or any sound's fine structure), plus a modulation spectrum in cycles/octave to verify them.
- Time and pitch manipulation. A phase vocoder (Gordon & Strawn, 1985) with phase locking: time-stretch without changing pitch, pitch-shift without changing duration, and oscillator-bank resynthesis with arbitrary frequency remapping (e.g. shifting a harmonic complex to make it inharmonic).
- Rooms. Synthetic impulse responses with frequency-dependent decay from the statistics of real rooms (Traer & McDermott, 2016), with a controllable DRR and decorrelated binaural tails, plus the paper's "unnatural" variants (time-reversed and linear decays; inverted, exaggerated and reduced frequency dependence) and a per-band RT60 measurement.
- Sound textures. The texture model of McDermott & Simoncelli (2011):
measure a recording's envelope, modulation and correlation statistics, and
synthesize new samples that share them. A clean-room implementation with
analytic gradients; every deviation from the MATLAB toolbox is documented
(
so.texture.DIFFERENCES_FROM_TOOLBOX). - Teaching and demos. One-call overview plots (waveform, spectrum, spectrogram, modulation spectrum) next to an audio player.
sonore is not an experiment runner, does not calibrate to dB SPL, and has no models of the ear or of perception; see "Related projects" below for those.
Install
pip install "sonore[notebook]" # extras: sofa (HRIR files), play (sounddevice), dev (tests)
or, for the development version:
git clone https://github.com/choyun1/sonore
cd sonore
pip install -e ".[notebook]"
Requires Python ≥ 3.10, numpy, scipy ≥ 1.12, matplotlib, and soundfile.
To try it without installing anything, open the starter notebook on Google Colab: its first cell installs sonore from PyPI.
A short tour
import sonore as so
from sonore import dB

fs = 44100

# Stimuli: every generator returns a Sound with RMS = 1
tone = so.pure_tone(0.5, fs, 1000).ramp(10e-3)
complex_ = so.harmonic_complex(0.5, fs, f0=200, harmonics=range(1, 21), phases="schroeder+")
noise = so.gaussian_noise(0.5, fs, band=(100, 8000), tilt=-3, rng=0)  # pink, band-limited

# Levels are dB units: + changes level, + with a Sound mixes
target_in_noise = tone + (noise + 5 * dB)  # tone at -5 dB SNR
quieter = complex_ - 12 * dB

# Time is in seconds
middle = target_in_noise[0.1:0.4]

# Binaural: positive ITD/ILD = toward the right
lateral = so.apply_itd_ild(noise, itd=300e-6, ild=6)
cues = so.interaural_cues(lateral, win_dur=20e-3)
cues.plot()

# Time and pitch (phase vocoder)
longer = so.time_stretch(complex_, 1.5)  # same pitch, 50% longer
up_a_fifth = so.pitch_shift(complex_, 7)  # same duration, +7 semitones

# Analysis
so.overview(target_in_noise)  # waveform, spectrum, spectrogram, modulation spectrum
target_in_noise  # in a notebook: an audio player
Every example in the gallery is a runnable script like this one, with its code shown beside the sound it makes.
Gallery
The listening gallery has every sound beside plots of the same audio, with a playhead that follows it, and the code for each example. Three of the kinds of plot sonore draws:
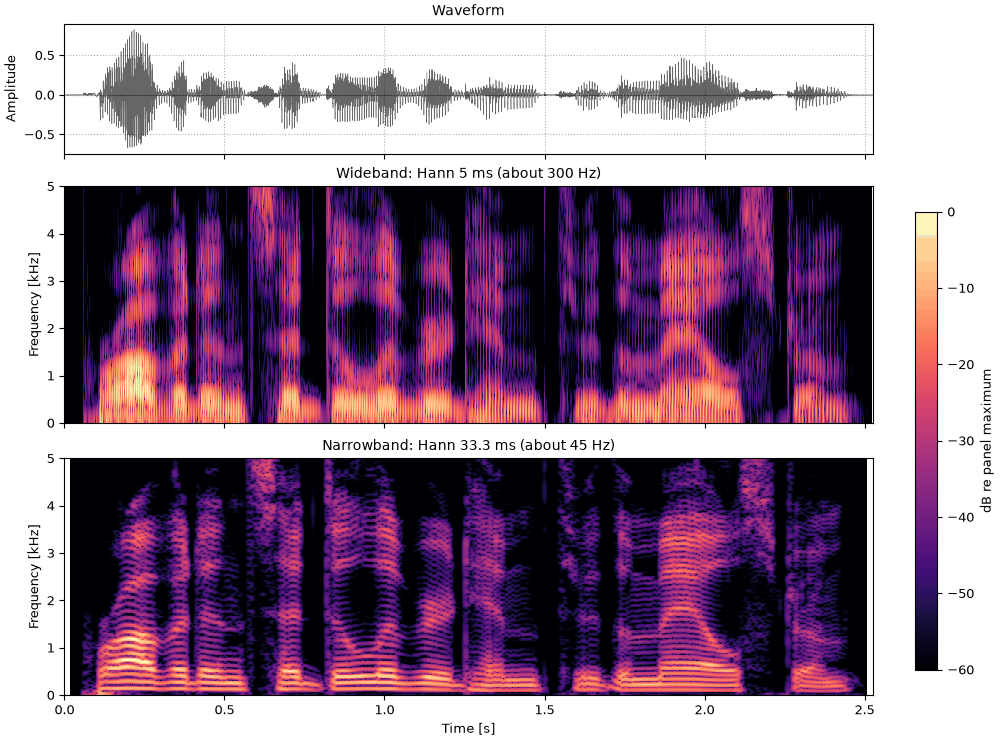
Spectrograms. One sentence through a wideband (5 ms) and a narrowband (33 ms) Gabor frame: the first resolves the glottal pulses, the second the harmonics. ▶ listen
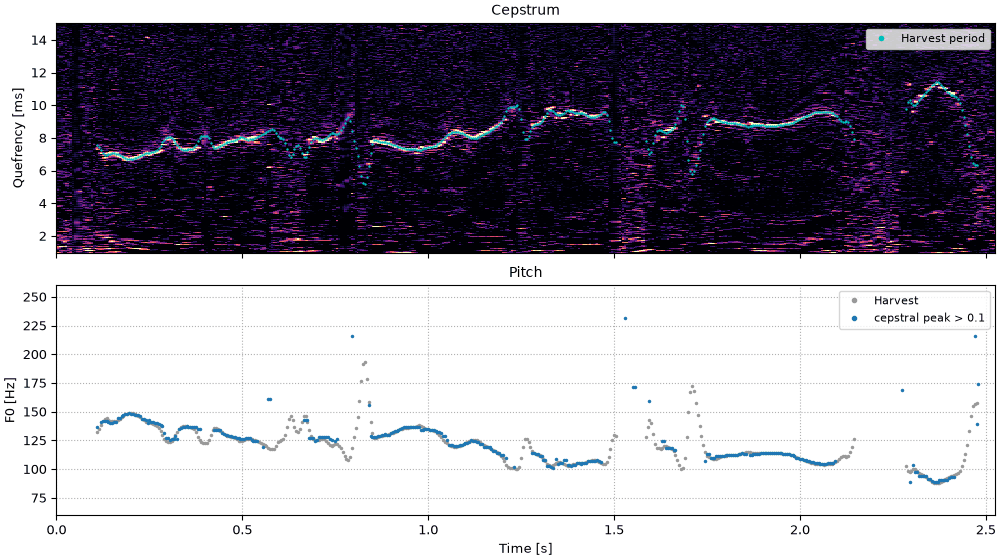
Cepstrum. The cepstrogram of the same sentence, with so.Cepstrum's F0
beside WORLD's Harvest. ▶ listen
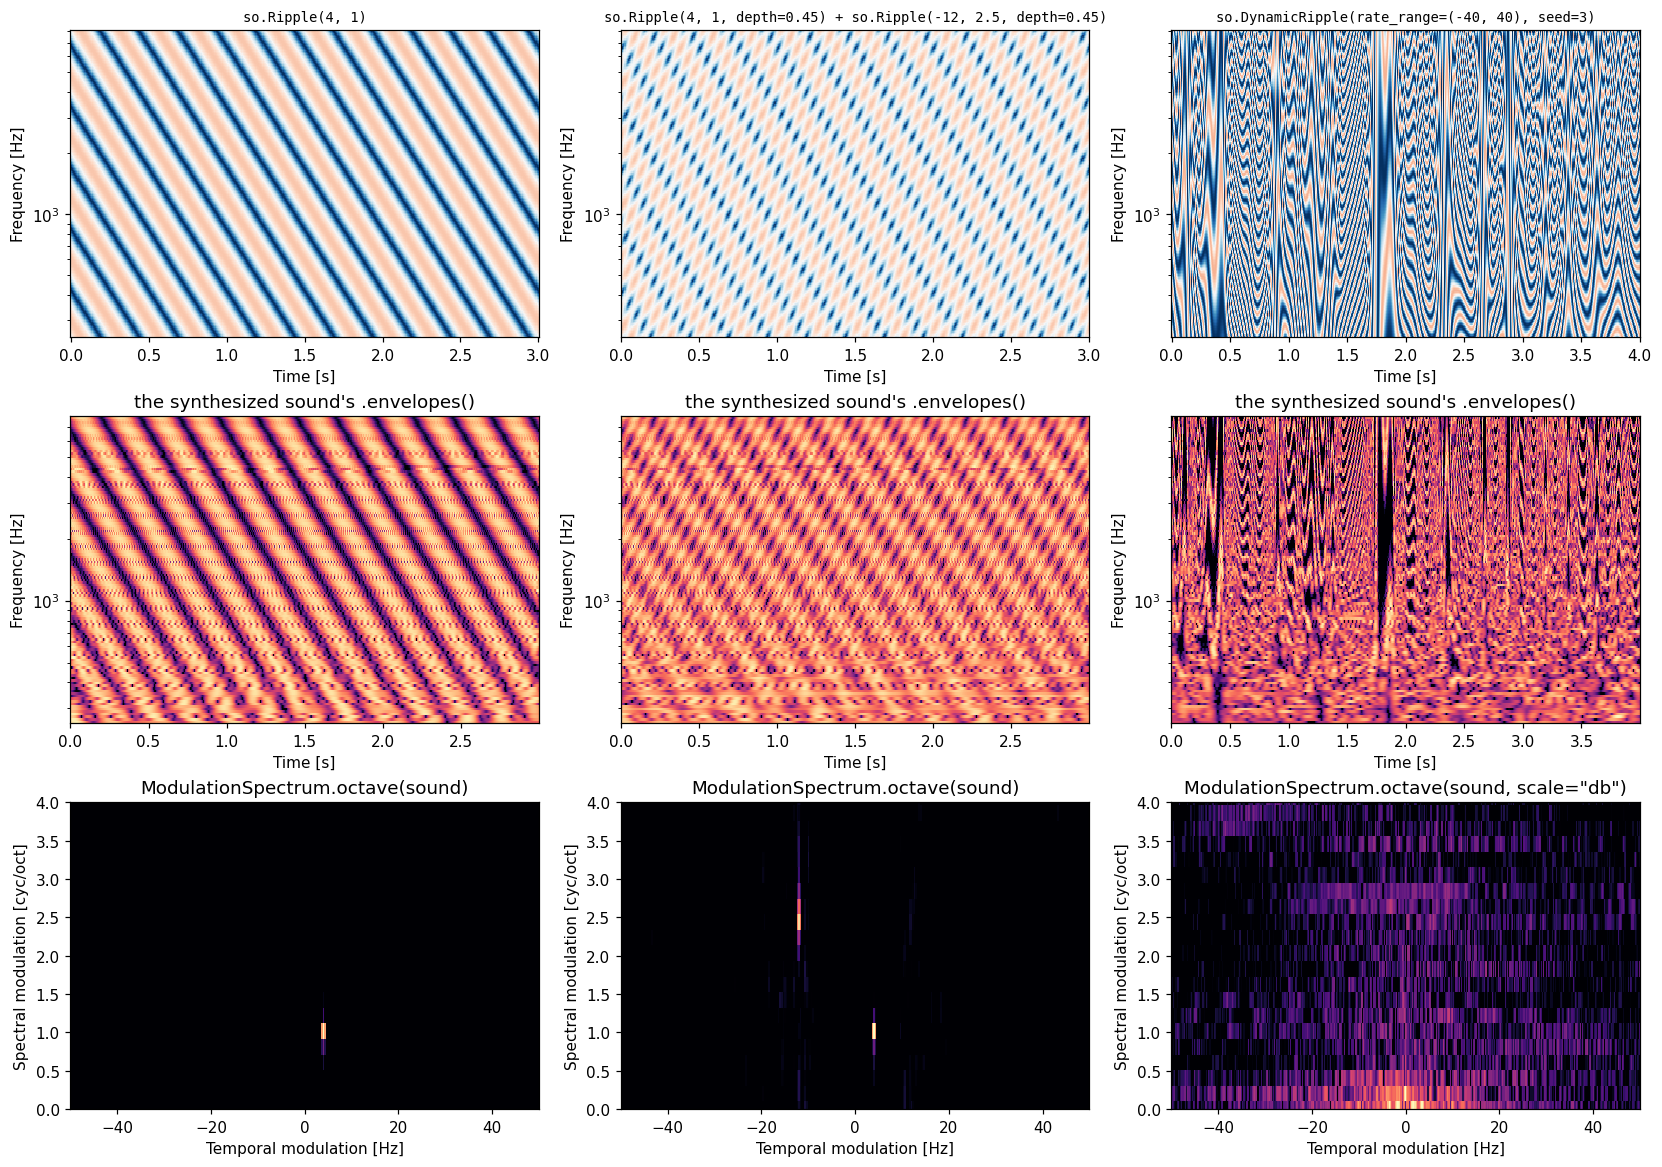
Modulation spectra. Three ripple patterns as specified (top), the
synthesized sounds' subband envelopes (middle), and their measured
so.ModulationSpectrum (bottom), which peaks at each specified rate and density.
▶ single ▶ sum of two ▶ dynamic
More in the gallery:
Stimuli
- Classic stimuli: ▶ speech-shaped noise, beats and roughness, and ▶ binaural beats 🎧.
- Iterated rippled noise: a pitch made from noise and a delay (Yost, 1996), from ▶ one iteration to ▶ sixteen.
- Spectrotemporal ripples: moving ripples on different carriers, and a ▶ dynamic moving ripple.
- Sound textures: recordings and their syntheses from statistics (McDermott & Simoncelli, 2011), such as a ▶ stream.
Seeing and changing sound
- Seeing speech: a short course in time-frequency analysis on one sentence, from ▶ window length to ▶ reassignment.
- Analysis and resynthesis: a filterbank's ▶ perfect reconstruction, and the ▶ ideal binary mask.
- Hearing through a vocoder: cochlear-implant simulation, from ▶ one band to ▶ sixteen.
- Modulation spectrogram: how fast and how deeply each band's envelope moves, moment by moment, from a ▶ gliding modulation rate to ▶ speech, babble and noise.
- Phase vocoder: how it works, and duration, pitch and partials changed independently, such as ▶ up a fifth.
Voices
- Formant synthesis: Klatt's synthesizer taken apart, from ▶ the source alone through ▶ five formants, then ▶ six vowels and ▶ /da/ from its formant transitions, and ▶ one vowel in three voices from LF glottal pulses.
- Cepstral analysis: separating a voice's pitch from its timbre, ▶ envelope only and ▶ harmonics only, and the same sentence as ▶ MFCCs.
- Voices from harmonics: a voice rebuilt from a pitch track and a spectral envelope, from ▶ a buzz on the pitch track to the ▶ full resynthesis, then ▶ up a fifth with the formants kept.
- Source, filter and aperiodicity: how much of a voice is noise, frequency by frequency, from ▶ a breathy vowel whose aperiodicity is known to the sentence ▶ rebuilt by WORLD's synthesis and ▶ whispered.
- Changing a voice: pitch and formants moved separately, from ▶ a higher pitch and ▶ higher formants to ▶ one talker toward another, with the pitch and the envelope from different analyses.
Spatial hearing
- Binaural cues 🎧: ▶ timing alone, and correlation that changes, such as ▶ Oscor.
- Synthetic reverberation: rooms built from the statistics of real ones (Traer & McDermott, 2016), from a ▶ natural room to ones that break the rules, such as a ▶ time-reversed decay.
- Moving talkers 🎧: three talkers rendered through measured HRIRs, ▶ one of them moving, a talker ▶ walking in, in a room, and a ▶ pass-by.
Conventions
- Sounds.
Sound= immutable(n_samples, n_channels)float array +fs. Operations return new Sounds. - Arithmetic.
a + bmixes,a * bmultiplies sample-wise,2 * ascales, mono broadcasts to stereo. - Bands and envelopes. A filterbank's output (
Subbands) is a collection of Sounds, and so is its fine structure (.tfs()). Envelopes are not sounds:EnvelopeandEnvelopesare their own types, non-negative, often at a low sampling rate, and applied to sounds by multiplication.Envelopes(one envelope per band) is what the field calls a cochleagram. The Hilbert decomposition is literal:sb == sb.envelopes() * sb.tfs(). - Levels.
a + 6*dB,a - 3*dB. Adding a bare number is an error, so it can't be mistaken for a DC offset. dB is always20*log10(amplitude). - Time.
snd[0.1:0.5]slices by seconds;snd.datafor samples. - Randomness. Every stochastic function takes
rng=(a seed ornp.random.Generator). - Binaural. Positive ITD = right ear leads; positive ILD = right ear louder.
- Space. Meters, head-centered, x = right, y = front, z = up.
hcc= (distance cm, elevation °, azimuth ° clockwise from front). - Threads. The large FFTs (filterbanks, Hilbert envelopes, resampling) use every available core. Results don't depend on it; when running several jobs in parallel,
so.set_fft_workers(1)(also as awithblock) keeps them from competing. - Plots. Every plotting function takes an optional
axand returns it; global matplotlib settings are never touched.
What's in it
The folders follow meaning. core holds Sound and the processing that
needs no analysis; sources makes sounds from parameters; frames are
analyses with an exact inverse, and views are one-way analyses together
with the routes back to sound they have (the channel vocoder, WORLD's
synthesis, the phase vocoder); spatial and texture are topics built on
those. Imports between modules never form a cycle, and core imports
nothing above it at module level. plotting is called from every object's
.plot(). docs/design/layout.md has the diagram.
Most names are also at the top level as so.name; the texture ones are
under so.texture and sonore.texture.synth.
| Module | Contents |
|---|---|
core.sound |
Sound, load |
core.units |
dB, Decibels |
core.utils |
rms, amp_to_db, power_to_db, db_to_amp, db_to_power, freq_to_erb, erb_to_freq, freq_to_mel, mel_to_freq (HTK or Slaney mel) |
core.fft |
set_fft_workers, fft_workers (threads for the large FFTs; default every available core; results identical for any setting) |
core.processing |
pad, truncate, concat, mix, normalize, match_fs, match_channels, relative_db, bandpass, butter_filter, amplitude_modulate, resonator and antiresonator (Klatt's formant and antiformant; frequency and bandwidth may glide, with no clicks) |
sources.waveforms |
silence, pure_tone, harmonic_complex, schroeder_complex, square_wave, sawtooth_wave, pulse_train, linear_chirp, exponential_chirp, gaussian_noise, correlated_noise, iterated_ripple_noise, glottal_source (Liljencrants-Fant glottal pulses on a fixed F0 or a contour, shape set by Fant's Rd, which may change over time; no aliasing), lf_harmonics (the pulse's Fourier coefficients in closed form), lf_pulse (one period, to draw) |
sources.klatt |
klatt_synthesize (a Klatt-style cascade/parallel formant synthesizer: harmonic voicing with Klatt's glottal spectrum or LF pulses (SS, RD), aspiration and frication noise modulated at F0, nasal pole and zero, formants 1-5 in cascade and 1-6 in parallel, radiation; every parameter a number or a (times, values) track), klatt_continuum (evenly spaced parameter sets between two endpoints), KLATT_DEFAULTS |
sources.ripples |
Ripple, RippleSum, DynamicRipple, ripple_sound; patterns can also be any function f(t, x) of time and octaves, and pattern.render(filterbank, dur, fs) gives their Envelopes |
frames.frame |
Frame (invertible analyses: analyze, synthesize as least squares, frame_bounds, energy, adjoint) |
frames.filterbank |
Filterbank (frequency-domain filters, any shape; canonical dual), ERBFilterbank, OctaveFilterbank (perfect-reconstruction cosine banks sharing CosineFilterbank, a tight Filterbank), GammatoneFilterbank (exact 4th-order gammatone responses, causal or zero-phase; envelope_peak_delay gives each filter's latency), MorletFilterbank (log-spaced Morlet wavelets); both add edge filters by default so synthesis is exact on the whole band, and edges=False gives the bare bank for cochleagrams. subbands, Subbands (a collection of Sounds: .envelopes(), .tfs(), .synthesize()) |
frames.gabor |
GaborFrame (the STFT as a frame; any window, zero-padded FFTs), TVGaborFrame (a Gabor frame whose window changes over time, from an explicit schedule, from_function, or pitch_adaptive from an F0 track; exact inverse; coefficients are a TVSTFT), STFT (a GaborFrame analysis: exact inverse, fast Griffin-Lim), TVSTFT (a TVGaborFrame analysis) |
frames.mask |
Mask, ideal_binary_mask, ideal_ratio_mask |
views.view |
View (the base of every view: a discards sentence saying what it drops, and a synthesize that raises NotInvertibleError with that reason and the route back to sound, if any) |
views.spectrum |
Spectrum (.to_sound with a noise, a sound's phase or the minimum phase as carrier), long_term_spectrum, tandem_power (TANDEM-STRAIGHT-style pitch-adaptive power, after Kawahara et al., 2011; magnitude only, a TFPower) |
views.reassigned |
reassigned_spectrogram (Kodera et al., 1978; Auger & Flandrin, 1995: spectrogram cells moved to their reassigned time and frequency, binned for display; not invertible) |
views.envelopes |
Envelope (one envelope; env * snd modulates), Envelopes (one per band, i.e. a cochleagram; .plot(), .modulation_spectrum(), env * subbands); noise_vocode (the channel vocoder of cochlear-implant simulations, after Shannon et al., 1995: band envelopes, lowpassed at any cutoff, on a carrier of noise, tones at the band centres, or any sound) |
views.modulation |
ConstantQModulationFilterbank, OctaveModulationFilterbank (circular, analytic output optional), HannModulationFilterbank (Hann-windowed complex kernels of a whole number of cycles, defined in time: constant Q or one fixed window, centred or causal), ModulationSpectrum (linear-frequency from an STFT, or .octave() in cycles/octave) |
views.modspectrogram |
ModulationSpectrogram (a modulation spectrum per time window: power, local mean and depth for every acoustic band and modulation rate, from any Envelopes, with a valid mask; .plot() as rate against time, one band, or band against time at one rate; .at(t), .slices(t), .animate(); not invertible) |
views.cepstrum |
Cepstrum (the real cepstrum of an STFT or TVSTFT: rectangular liftering with a fixed or per-time-window cutoff, the cepstral envelope, resynthesis with the original phase, exact when unliftered, or the minimum phase, and classic cepstral F0 after Noll, 1967) |
views.mfcc |
MFCC (mel-frequency cepstral coefficients of a Sound, with the usual speech settings, or of any STFT or TVSTFT: HTK or Slaney mel, height- or area-normalised triangles straight in mel or in Hz, the mel spectrogram, deltas, the smoothed envelope the coefficients keep, .plot(); reproduces Kaldi's and librosa's numbers to rounding error; not invertible) |
views.f0 |
f0_track → F0Track (F0 every 5 ms with a voiced/unvoiced decision: candidates from YIN's difference function, refinement by the instantaneous frequency of six harmonics, a periodicity score, a Viterbi pass; .plot(); checked against laryngograph F0), scale_f0 (a pitch change on any F0 contour, with a range factor) |
views.spectral_envelope |
cheaptrick → SpectralEnvelope (WORLD's CheapTrick, ported exactly: it matches WORLD to floating-point precision), warp_frequency (formants moved along frequency on any envelope or aperiodicity, by a ratio, a ratio over time or any frequency map), GridEnvelope (any envelope as power on a grid, as Cepstrum.envelope_view() and MFCC.envelope_view() give) |
views.aperiodicity |
d4c → Aperiodicity (WORLD's D4C, ported exactly), harmonic_aperiodicity (the share of noise, by fitting the harmonics) |
views.world |
world_synthesize (WORLD's synthesis, sample for sample, from an F0 track, envelope and aperiodicity; WORLD's own noise stream by default, or fresh noise from an rng; reads any F0 track and any envelope), DIFFERENCES_FROM_WORLD |
views.phasevocoder |
time_stretch, pitch_shift (identity phase locking), pv_analyze → PVAnalysis (instantaneous frequency; oscillator-bank to_sound with time_scale and freq_map) |
spatial.binaural |
apply_itd_ild, simple_bir, interaural_cues, oscor, phasewarp |
spatial.spatialization |
HRIRSet (PKU-IOA, SOFA; onset-aligned interpolation), spatialize, move_sound (paths as functions of time, continuous ear delays, room tail), hcc_trajectory and other trajectories, coordinate conversions, distance_gain_db |
spatial.hrir_data |
load_hrirs: public HRIR databases (PKU-IOA) downloaded on first use, checksum-verified and cached |
spatial.reverb |
synth_ir (natural rooms, or the paper's atypical decay_shape / rt60_profile / drr_profile variants), band_rt60s, measure_rt60 |
texture.stats |
TextureModel, TextureStats (.measure, .snr, .replace for hybrids, .save/.load) |
texture.synth |
synthesize (full loop), impose_channel; gradients in texture.grad |
plotting |
overview and the plot_* functions behind each object's .plot(); plot_tf_db draws any time-frequency level on non-uniform time windows; modulation spectrograms draw invalid cells grey and animate with their sound; cochleagrams take align="peak" (draw causal gammatone bands without their latency) and fscale="linear" (to match spectrograms) |
Related projects
Where to go for what sonore leaves out:
-
slab: calibrated levels in dB SPL, playback, trial sequences and adaptive staircases. Its sound making overlaps with sonore's, and the two share the same sample layout (samples × channels), so a sound passes between them in one line:
s = slab.Sound(snd.data, samplerate=snd.fs)  # sonore to slab; then set s.level in dB SPL
snd = so.Sound(s.data, s.samplerate)  # slab to sonore
slab reads samples as pascals, so a sonore sound at RMS 1 shows as 94 dB SPL until you set its level.
-
PsychoPy: running experiments.
-
Auditory Modeling Toolbox (MATLAB/Octave) and torch_amt (PyTorch): models of the auditory system that predict what a listener hears.
-
brian2hears: auditory periphery and spiking models.
-
MoSQITo: loudness, sharpness, roughness and other sound quality metrics.
-
Parselmouth (Praat in Python) and pyworld (WORLD): speech analysis and synthesis.
-
librosa: music and audio analysis.
-
pyroomacoustics: geometric room simulation.
Roadmap
What is planned comes first, in the order it will be done; finished work is listed at the end.
Next, in order
- Release 0.4.0, with the moved import paths and the
to_soundrenames in its notes. - Texture modulation convergence. Rebalance the objective so modulation power converges (see Texture synthesis below).
Texture synthesis
- Rebalance the objective so modulation power converges (it reaches 30 dB SNR when imposed without the correlation classes, but 18-23 dB in full synthesis); try joint imposition of all channels.
- Impose several channels at once; the per-channel objective is overhead-bound (about 2 s per iteration for 5 s of sound).
- Validate against the MATLAB toolbox's published examples by running both on the same original recordings.
Architecture
- Folders follow meaning, and imports between modules never form a cycle;
tests/test_layers.pykeeps enforcing it. A voice is not a separate kind of sound, so there is novoicesubpackage: synthesizers live insourcesand analyses of a voice inviews. Heavy dependencies go in optional extras. - Split a component into its own distribution only when it needs a heavy dependency, a different release cadence, or a separate audience.
- Bayesian inference of sound sources will be a separate package built on sonore (JAX plus a probabilistic-programming layer), using sonore's generators, frames and texture statistics as its differentiable forward model.
Other
- The rest of KLSYN88's voice-quality controls (Klatt & Klatt, 1990) for the formant synthesizer: open quotient, spectral tilt, flutter, double pulsing, and its KLGLOTT88 source.
- Free-form modulation patterns: specify a modulation spectrum and synthesize it.
- A decimated, invertible constant-Q transform (nonstationary Gabor frames in frequency).
- Peak-based sinusoidal modeling (McAulay & Quatieri, 1986) alongside the channel oscillator bank.
- On-demand download of other public HRIR databases.
- A block-by-block (streaming) modulation spectrogram, as the reference for a live version on a phone: the modulation spectrum of everyday sounds as they happen.
Done, oldest first
-
Frames. A
Framecontract for invertible time-frequency analyses:analyze,synthesize(canonical dual, least-squares for modified coefficients),frame_bounds()andadjoint. The STFT (GaborFrame), the cosine, gammatone and Morlet filterbanks, and a time-varying Gabor frame with pitch-adaptive windows are all frames; tests enforcesynthesize(analyze(x)) == xand the reported bounds. Reassigned spectrograms and a TANDEM-STRAIGHT-style power spectrum are drawn beside them in the Seeing speech page. -
Package layout. One subpackage per layer (
core,signals,analysis,stimuli,texture), with imports pointing down a layer, enforced bytests/test_layers.py; seedocs/design/layout.md. -
CI and releases. Tests and lint on Python 3.10 and 3.14 for every push and pull request, a check that the PyPI files build and pass their tests, and a trusted-publishing release workflow (
docs/releasing.md). -
HRIRs on demand.
so.load_hrirs()downloads the PKU-IOA database (Qu et al., 2009) on first use, checks each file's checksum and caches it, correcting the left-right mirroring of its SOFA copy; seedocs/design/hrir-data.md. -
Cepstrum.
Cepstrumon any STFT: liftering, resynthesis with the original or minimum phase, and classic cepstral F0; seedocs/design/cepstrum.md. -
The MSM archive. The experiment code behind Cho & Kidd (2022), written with sigtools 0.1, stays a separate archive at choyun1/MSM rather than being folded in; the Moving talkers page carries its stimuli forward.
-
JAX trial, decided against for now. A JAX port of the texture channel objective matched the NumPy gradient to about 1e-15 but ran no faster (about 2 ms per call either way, plus compile time), and float32 would break bit-for-bit output. The core stays NumPy. An optional
sonore[jax]extra is worth revisiting only if inference work needs gradients through the whole model. -
PyPI, Zenodo and Colab. sonore is on PyPI from 0.3.0, and each GitHub release is archived on Zenodo with a DOI (from 0.3.1). A starter notebook runs in Colab with nothing to install.
-
Modulation spectrogram.
ModulationSpectrogram: how strongly each band's envelope is modulated at each rate, in every time window, with linked slices and an animation; seedocs/design/modulation-spectrogram.mdand the Modulation spectrogram gallery page. -
Gallery pages. Seventeen pages, listed under Gallery, each a runnable script shown with its code. The Cepstral analysis page is cross-checked against SciPy, MATLAB's
rcepsand Praat bytools/crosscheck_cepstrum.py; the Moving talkers page follows Cho & Kidd (2022), with interaural cues and a top-down view that follows playback. -
Faster filterbanks. FFT lengths padded to fast sizes and the large FFTs spread over all cores (
so.set_fft_workers); subbands and envelopes are 3 to 4 times faster, and texture synthesis is unchanged bit for bit. -
F0 tracking.
so.f0_track: YIN-style candidates refined by instantaneous frequency (after WORLD's StoneMask), a periodicity score and a Viterbi voicing decision. Against laryngograph reference F0 (the FDA database, Bagshaw et al., 1993) it gets the voicing of 5.6% (male) and 1.5% (female) of time windows wrong, where WORLD's Harvest gets about 21%; seedocs/design/f0.md. -
Harmonic complexes on an F0 contour.
so.harmonic_complextakes an F0 contour as well as a number: the phase is the contour's exact running integral, unvoiced gaps are bridged and switched off with 5 ms ramps (or filled with noise), and harmonics fade out belowf_maxso a rising pitch never aliases. The square, sawtooth, pulse train and Schroeder complexes follow contours too. Withso.noise_vocode(snd, 16, carrier=...)it puts a sound's band envelopes on harmonics that follow its own F0 track. The harmonic half of the pulse-plus-noise synthesis in item 1 of Next; seedocs/design/harmonic-source.mdand the Voices from harmonics gallery page. -
Klatt-style formant synthesizer.
so.klatt_synthesizeafter Klatt (1980): harmonic voicing with Klatt's glottal spectrum, aspiration and frication noise, formants in cascade and in parallel (alternating signs, which match the cascade between peaks to 0.15 dB where equal signs miss by 15 dB), radiation, and parameters as tracks interpolated to every sample.so.resonatorandso.antiresonatorare its formants. A vowel's harmonics equal source x formants x radiation to 1e-6 dB; seedocs/design/klatt.mdand the Formant synthesis gallery page. -
WORLD vocoder.
so.cheaptrick(spectral envelope; Morise, 2015),so.d4c(aperiodicity; Morise, 2016) andso.world_synthesizereproduce WORLD (Morise et al., 2016, the successor of STRAIGHT, Kawahara et al., 1999) in NumPy, including its own noise generator: on the gallery sentence they match pyworld to 4e-9 dB, 7e-12 dB and 1e-13 of the peak, and the tests compare against stored WORLD output, so pyworld is not a dependency. Options that depart from WORLD are listed inso.DIFFERENCES_FROM_WORLD.so.harmonic_aperiodicitymeasures the share of noise directly, beside D4C. Seedocs/design/world.mdand the Source, filter and aperiodicity gallery page. -
LF glottal source.
so.glottal_sourcemakes Liljencrants-Fant pulses (Fant, Liljencrants & Lin, 1985) from their exact harmonics, whose coefficients have a closed form that depends only on the harmonic number, so the source does not alias and each period takes its own length on a moving F0. One control, Fant's (1995) Rd, runs from tense to lax voice and may change over time.so.klatt_synthesizetakes it withSS = 3andRD, as in KLSYN88 (Klatt & Klatt, 1990); the default source is unchanged. Seedocs/design/glottal-source.md. -
Moving-sound renderer.
so.move_soundtakes a path as a function of time (so.hcc_trajectory, with any coordinate a number, a contour or a function, such as the azimuth swing of Cho & Kidd, 2022), a(times, points)pair, or evenly spread points. Each ear reads the sound through its own delay, the HRIR onset, which slides from sample to sample instead of being cross-faded between fixed delays, which comb-filters when distance changes; Doppler comes out of the same read. The PKU-IOA responses already hold travel time and 1/r level, and beyond the measured distances distance acts through both alone. An optional room tail keeps its level while the direct sound falls. Seedocs/design/moving-sound.md. -
Moving sounds in the gallery. The Moving talkers page has a talker walking in from 3 m, dry and in a room, and a buzz passing at 15 m/s whose measured pitch follows the Doppler shift.
-
MFCCs.
so.MFCCon a sound or any STFT: mel band powers, their log and a DCT, deltas, the mel spectrogram and the smoothed envelope the coefficients keep. Tests compare it with Kaldi's and librosa's stored output; seedocs/design/mfcc.md. The Cepstral analysis page shows how much a vowel's MFCCs move with its pitch. -
Voice changes, any method.
so.scale_f0changes the pitch andso.warp_frequencymoves the formants, on any F0 contour (f0_track, Harvest,Cepstrum.f0) and any envelope (CheapTrick, the cepstrum, MFCCs), and both synthesizers take any envelope.tools/compare_voice_methods.pycompares the trackers and envelopes at resynthesis and voice change; seedocs/design/voice-change.mdand the Changing a voice gallery page. -
API reference and test layout. An API reference built from the docstrings in CI, and a test folder that mirrors
src/sonore. -
Faster gallery build. Each figure is drawn once rather than twice; the images are byte for byte the same.
-
More moving talkers and rooms. Straight paths across the plane and a path no real source could take on the Moving talkers page, and the gallery sentence in each rule-breaking room on the Synthetic reverberation page.
-
Gallery in four groups. Stimuli; Seeing and changing sound; Voices; Spatial hearing, one script folder per group, with page URLs unchanged.
-
Frames and views.
analysissplit into frames (invertible) and views (one-way), and aViewbase class whosesynthesizeraisesNotInvertibleError, saying what the view discards and naming the route back to sound where one exists; seedocs/design/reorganization.md. -
Sound first. Folders follow meaning (
core,sources,frames,views,spatial,texture), with import order kept module by module. A view goes back to sound throughto_soundwhere a canonical route exists, taking what the view discarded (Spectrum.to_sounda carrier,PVAnalysis.to_sounda time scale and a frequency map), and refuses otherwise; seedocs/design/sound-first.md.
References
Each entry is the citation and a link to the work: the DOI where one is confirmed, otherwise
the publisher or another stable page. After it come tags naming the module(s) in
What's in it that implement or follow the work, linked to the source: a tag such
as representations.reassigned_spectrogram goes to that definition, a bare module name to the
whole file. Last, set apart by a ·, are the gallery pages (▶) and roadmap items that cite it.
Works with no tag are not implemented yet.
- Atlas & Shamma (2003). Joint acoustic and modulation frequency. EURASIP J. Appl. Signal Processing 2003(7). doi:10.1155/S1110865703305013.
modspectrogram.ModulationSpectrogram.at· ▶ Modulation spectrogram - Auger & Flandrin (1995). Improving the readability of time-frequency and time-scale representations by the reassignment method. IEEE Trans. Signal Processing 43(5). doi:10.1109/78.382394.
reassigned.reassigned_spectrogram· ▶ Seeing speech - Bagshaw, Hiller & Jack (1993). Enhanced pitch tracking and the processing of F0 contours for computer aided intonation teaching. Proc. Eurospeech 1993. CSTR, FDA database. Its laryngograph F0 is the reference in
tools/check_f0_fda.py(data not in the repository).f0.f0_track - Balazs, Dörfler, Jaillet, Holighaus & Velasco (2011). Theory, implementation and applications of nonstationary Gabor frames. J. Comput. Appl. Math. 236(6). doi:10.1016/j.cam.2011.09.011.
gabor.TVGaborFrame - Boersma & Weenink. Praat: doing phonetics by computer (computer program). praat.org. Cross-checks
Cepstrum(see Reference implementations). · ▶ Cepstral analysis - Bogert, Healy & Tukey (1963). The quefrency alanysis of time series for echoes: cepstrum, pseudo-autocovariance, cross-cepstrum and saphe cracking. In M. Rosenblatt (ed.), Time Series Analysis, Wiley. Semantic Scholar.
cepstrum.Cepstrum· ▶ Cepstral analysis - Brandtsegg, Saue & Lazzarini (2018). Live convolution with time-varying filters. Applied Sciences 8(1), 103. MDPI. Reviews the ways of filtering with a changing filter;
move_soundis one of them.spatialization.move_sound· ▶ Moving talkers · Roadmap - Byrne et al. (1994). An international comparison of long-term average speech spectra. JASA 96(4), 2108–2120. doi:10.1121/1.410152.
spectrum.long_term_spectrum· ▶ Classic stimuli - Chi, Gao, Guyton, Ru & Shamma (1999). Spectro-temporal modulation transfer functions and speech intelligibility. JASA 106. JASA.
ripples.Ripplemodulation.ModulationSpectrum· ▶ Spectrotemporal ripples - Carlile & Leung (2016). The perception of auditory motion. Trends in Hearing 20. doi:10.1177/2331216516644254. Reviews which cues listeners use to judge motion; level and interaural differences outweigh Doppler. · ▶ Moving talkers
- Cho & Kidd (2022). Auditory motion as a cue for source segregation and selection in a "cocktail party" listening environment. JASA 152(3), 1684–1694. doi:10.1121/10.0013990. Its experiment code is archived at choyun1/MSM.
spatialization.move_soundbinaural.interaural_cues· ▶ Moving talkers · Roadmap - Christensen (2003). An Introduction to Frames and Riesz Bases. Birkhäuser. doi:10.1007/978-0-8176-8224-8.
frame.Frame - Cuevas-Rodríguez, Picinali, González-Toledo et al. (2019). 3D Tune-In Toolkit: an open-source library for real-time binaural spatialisation. PLOS ONE 14(3), e0211899. doi:10.1371/journal.pone.0211899. Removes the interaural delay before interpolating HRIRs, as sonore's onset alignment does.
spatialization.HRIRSet· ▶ Moving talkers - Davis & Mermelstein (1980). Comparison of parametric representations for monosyllabic word recognition in continuously spoken sentences. IEEE Trans. Acoust., Speech, Signal Process. 28(4), 357–366.
mfcc.MFCC· ▶ Cepstral analysis ▶ Changing a voice - Daubechies, Grossmann & Meyer (1986). Painless nonorthogonal expansions. J. Math. Phys. 27(5). doi:10.1063/1.527388.
gabor.GaborFrame - Dau, Kollmeier & Kohlrausch (1997). Modeling auditory processing of amplitude modulation. I. Detection and masking with narrow-band carriers. JASA 102(5), 2892–2905. PubMed.
modulation.HannModulationFilterbank· ▶ Modulation spectrogram - de Cheveigné & Kawahara (2002). YIN, a fundamental frequency estimator for speech and music. JASA 111(4). doi:10.1121/1.1458024.
f0.f0_track· ▶ Voices from harmonics - Dolson (1986). The phase vocoder: A tutorial. Computer Music Journal 10(4). Semantic Scholar.
phasevocoder· ▶ Phase vocoder - Dorman, Loizou & Rainey (1997). Speech intelligibility as a function of the number of channels of stimulation for signal processors using sine-wave and noise-band outputs. JASA 102(4), 2403–2411. doi:10.1121/1.420354.
envelopes.noise_vocode· ▶ Hearing through a vocoder - Escabí & Schreiner (2002). Nonlinear spectrotemporal sound analysis by neurons in the auditory midbrain. J. Neurosci. 22. doi:10.1523/JNEUROSCI.22-10-04114.2002.
ripples.DynamicRipple· ▶ Spectrotemporal ripples - Fant (1995). The LF-model revisited. Transformations and frequency domain analysis. STL-QPSR 36(2–3), 119–156. The Rd parameter.
waveforms.glottal_sourceklatt.klatt_synthesize· ▶ Formant synthesis · Roadmap - Fant, Liljencrants & Lin (1985). A four-parameter model of glottal flow. STL-QPSR 26(4), 1–13.
waveforms.lf_harmonicswaveforms.lf_pulse· ▶ Formant synthesis · Roadmap - Flanagan & Golden (1966). Phase vocoder. Bell System Technical Journal 45. doi:10.1002/j.1538-7305.1966.tb01706.x.
phasevocoder· ▶ Phase vocoder - Friesen, Shannon, Baskent & Wang (2001). Speech recognition in noise as a function of the number of spectral channels: comparison of acoustic hearing and cochlear implants. JASA 110(2), 1150–1163. PubMed.
envelopes.noise_vocode· ▶ Hearing through a vocoder - Gabor (1946). Theory of communication. Part 1: The analysis of information. J. IEE 93(26). doi:10.1049/ji-3-2.1946.0074.
gabor.GaborFrame· ▶ Seeing speech - Gamper (2013). Head-related transfer function interpolation in azimuth, elevation, and distance. JASA 134(6), EL547. doi:10.1121/1.4828983. The HRIR interpolation used in Cho & Kidd (2022); sonore interpolates onset-aligned responses instead.
spatialization.HRIRSet.at - Glasberg & Moore (1990). Derivation of auditory filter shapes from notched-noise data. Hearing Research 47. doi:10.1016/0378-5955(90)90170-T.
filterbank.ERBFilterbank· ▶ Seeing speech ▶ Classic stimuli - Gordon & Strawn (1985). An introduction to the phase vocoder. In J. Strawn (ed.), Digital Audio Signal Processing: An Anthology. Also Stanford CCRMA report STAN-M-55. CCRMA.
phasevocoder· ▶ Phase vocoder - Greenberg & Kingsbury (1997). The modulation spectrogram: in pursuit of an invariant representation of speech. Proc. ICASSP 1997, vol. 3, 1647–1650. Semantic Scholar.
modspectrogram.ModulationSpectrogram· ▶ Modulation spectrogram - Griffin & Lim (1984). Signal estimation from modified short-time Fourier transform. IEEE TASSP 32. doi:10.1109/TASSP.1984.1164317.
gabor.STFT.griffin_lim - Hillenbrand, Getty, Clark & Wheeler (1995). Acoustic characteristics of American English vowels. JASA 97(5), 3099–3111. doi:10.1121/1.411872. Male and female formants, used for the synthetic vowels in
tools/compare_voice_methods.py. · ▶ Source, filter and aperiodicity ▶ Changing a voice - Kawahara, Masuda-Katsuse & de Cheveigné (1999). Restructuring speech representations using a pitch-adaptive time-frequency smoothing and an instantaneous-frequency-based F0 extraction. Speech Communication 27. doi:10.1016/S0167-6393(98)00085-5.
gabor.TVGaborFrame.pitch_adaptive· Roadmap - Kawahara et al. (2011). Technical foundations of TANDEM-STRAIGHT, a speech analysis, modification and synthesis framework. Sādhanā 36(5). doi:10.1007/s12046-011-0043-3.
spectrum.tandem_power· ▶ Seeing speech - Kingsbury, Morgan & Greenberg (1998). Robust speech recognition using the modulation spectrogram. Speech Communication 25(1–3), 117–132. doi:10.1016/S0167-6393(98)00032-6.
modspectrogram.ModulationSpectrogram· ▶ Modulation spectrogram - Klatt (1980). Software for a cascade/parallel formant synthesizer. JASA 67(3). doi:10.1121/1.383940.
klatt.klatt_synthesizeprocessing.resonator· ▶ Formant synthesis · Roadmap - Klatt & Klatt (1990). Analysis, synthesis, and perception of voice quality variations among female and male talkers. JASA 87(2), 820–857. doi:10.1121/1.398894. The
SSsource switch.klatt.klatt_synthesize· ▶ Formant synthesis · Roadmap - Kodera, Gendrin & de Villedary (1978). Analysis of time-varying signals with small BT values. IEEE Trans. ASSP 26(1). doi:10.1109/TASSP.1978.1163047.
reassigned.reassigned_spectrogram· ▶ Seeing speech - Kominek & Black (2004). The CMU Arctic speech databases. Proc. 5th ISCA Speech Synthesis Workshop (SSW5), 223–224. ISCA Archive. The gallery's speech (speakers bdl and rms; see
docs/speech/SOURCES.md). · ▶ Seeing speech ▶ Cepstral analysis ▶ Hearing through a vocoder ▶ Moving talkers ▶ Synthetic reverberation ▶ Phase vocoder ▶ Classic stimuli ▶ Modulation spectrogram ▶ Voices from harmonics ▶ Changing a voice - Kowalski, Depireux & Shamma (1996). Analysis of dynamic spectra in ferret primary auditory cortex. I. J. Neurophysiol. 76. doi:10.1152/jn.1996.76.5.3503.
ripples.Ripple· ▶ Spectrotemporal ripples - Laroche & Dolson (1999). Improved phase vocoder time-scale modification of audio. IEEE Trans. Speech Audio Process. 7(3). IEEE Xplore.
phasevocoder.time_stretch· ▶ Phase vocoder - Licklider, Webster & Hedlun (1950). On the frequency limits of binaural beats. JASA 22(4), 468–473. doi:10.1121/1.1906629. · ▶ Classic stimuli
- McAulay & Quatieri (1986). Speech analysis/synthesis based on a sinusoidal representation. IEEE TASSP 34. Internet Archive. · Roadmap
- McDermott & Simoncelli (2011). Sound texture perception via statistics of the auditory periphery. Neuron 71. doi:10.1016/j.neuron.2011.06.032.
texturefilterbank.CosineFilterbankmodulation· ▶ Sound textures - Morise (2015). CheapTrick, a spectral envelope estimator for high-quality speech synthesis. Speech Communication 67. doi:10.1016/j.specom.2014.09.003.
spectral_envelope.cheaptrickgabor.TVGaborFrame.pitch_adaptive· ▶ Cepstral analysis ▶ Voices from harmonics ▶ Source, filter and aperiodicity ▶ Changing a voice · Roadmap - Morise (2016). D4C, a band-aperiodicity estimator for high-quality speech synthesis. Speech Communication 84, 57–65. doi:10.1016/j.specom.2016.09.001.
aperiodicity.d4c· ▶ Source, filter and aperiodicity ▶ Changing a voice · Roadmap - Morise (2017). Harvest: a high-performance fundamental frequency estimator from speech signals. Proc. Interspeech 2017. doi:10.21437/Interspeech.2017-68. Compared with
f0_trackintools/check_f0_fda.py. · ▶ Voices from harmonics ▶ Source, filter and aperiodicity ▶ Changing a voice - Morise, Yokomori & Ozawa (2016). WORLD: A vocoder-based high-quality speech synthesis system for real-time applications. IEICE Trans. Inf. & Syst. E99-D(7). doi:10.1587/transinf.2015EDP7457. Its synthesis is reproduced by
world_synthesize, and its StoneMask refinement followed byf0_track.world.world_synthesizef0.f0_track· ▶ Cepstral analysis ▶ Voices from harmonics ▶ Source, filter and aperiodicity ▶ Changing a voice · Roadmap - Noll (1967). Cepstrum pitch determination. JASA 41(2). PubMed.
cepstrum.Cepstrum.f0· ▶ Cepstral analysis ▶ Voices from harmonics ▶ Changing a voice - Oppenheim & Schafer (2010). Discrete-Time Signal Processing, 3rd ed., ch. 13. Pearson. Pearson.
cepstrum.Cepstrum.to_stft - Patterson, Robinson, Holdsworth, McKeown, Zhang & Allerhand (1992). Complex sounds and auditory images. In Auditory Physiology and Perception (Proc. 9th International Symposium on Hearing). doi:10.1016/B978-0-08-041847-6.50054-X.
filterbank.GammatoneFilterbank - Perraudin, Balazs & Søndergaard (2013). A fast Griffin-Lim algorithm. IEEE WASPAA. doi:10.1109/WASPAA.2013.6701851.
gabor.STFT.griffin_lim - Peterson & Barney (1952). Control methods used in a study of the vowels. JASA 24(2), 175–184. ASA. Average formant frequencies of ten vowels. · ▶ Formant synthesis ▶ Cepstral analysis
- Plomp & Levelt (1965). Tonal consonance and critical bandwidth. JASA 38(4), 548–560. doi:10.1121/1.1909741. · ▶ Classic stimuli
- Qu et al. (2009). Distance-dependent head-related transfer functions measured with high spatial resolution using a spark gap. IEEE TASLP 17. PKU Scholar.
spatialization.HRIRSet.from_pku_ioahrir_data.load_hrirs· ▶ Moving talkers - Schroeder (1970). Synthesis of low-peak-factor signals and binary sequences with low autocorrelation. IEEE Trans. Inf. Theory 16. doi:10.1109/TIT.1970.1054411.
waveforms.schroeder_complex· ▶ Voices from harmonics - Shannon et al. (1995). Speech recognition with primarily temporal cues. Science 270. doi:10.1126/science.270.5234.303.
envelopes.noise_vocode· ▶ Hearing through a vocoder ▶ Voices from harmonics - Singh & Theunissen (2003). Modulation spectra of natural sounds and ethological theories of auditory processing. JASA 114(6). doi:10.1121/1.1624067.
modulation.ModulationSpectrumenvelopes.Envelopes.modulation_spectrum· ▶ Spectrotemporal ripples - Siveke et al. (2008). Psychophysical and physiological evidence for fast binaural processing. J. Neurosci. 28. J. Neurosci..
binaural.oscorbinaural.phasewarp· ▶ Binaural cues - Traer & McDermott (2016). Statistics of natural reverberation enable perceptual separation of sound and space. PNAS 113. doi:10.1073/pnas.1612524113.
reverb.synth_ir· ▶ Synthetic reverberation - Wang (2005). On ideal binary mask as the computational goal of auditory scene analysis. In Speech Separation by Humans and Machines. doi:10.1007/0-387-22794-6_12.
mask.ideal_binary_mask· ▶ Analysis and resynthesis - Wilson, Finley, Lawson, Wolford, Eddington & Rabinowitz (1991). Better speech recognition with cochlear implants. Nature 352, 236–238. PubMed.
envelopes.noise_vocode· ▶ Hearing through a vocoder - Yost (1996). Pitch of iterated rippled noise. JASA 100. JASA (PDF).
waveforms.iterated_ripple_noise· ▶ Iterated rippled noise
Reference implementations
Implementations by a paper's authors or widely used ports, with how sonore
relates to each. "Cross-checked" means a script in tools/ compares the two
numerically; "consulted" means the code was read for behavior but not copied.
- Sound Texture Synthesis Toolbox v1.7 (MATLAB), McDermott lab: the
authors' implementation of McDermott & Simoncelli (2011). Consulted; sonore
is a clean-room implementation from the paper, and every deliberate
difference is listed in
so.texture.DIFFERENCES_FROM_TOOLBOX.texturefilterbank.CosineFilterbankmodulation - wil-j-wil/texture_stats (Python, MIT): a port of the toolbox's
statistics. Cross-checked by
tools/crosscheck_texture_stats.py.texture.TextureStats - mcdermottLab/pycochleagram (Python): the lab's port of the
toolbox's cochleagram code, including the cosine filterbank. Not yet
cross-checked.
filterbank.CosineFilterbank - LTFAT (MATLAB/Octave, GPLv3):
frsynabswith'fgriflim'is the fast Griffin-Lim from the group of Perraudin, Balazs & Søndergaard (2013);librosa.griffinlimis a widely used Python version. Neither is cross-checked yet.gabor.STFT.griffin_lim - SciPy
ShortTimeFFT(BSD-3): wrapped byGaborFrame. Its frame operator, bounds and least-squares inverse are cross-checked against dense matrices in the tests and intools/check_frames_step1_claims.py(docs/design/frames.md, step 1).gabor.GaborFramegabor.STFT - Gammatone filterbanks in Slaney's Auditory Toolbox and MATLAB's
gammatoneFilterBankare time-domain IIR approximations;GammatoneFilterbankuses the exact frequency response instead (derivation in docs/design/frames.md, step 2). Consulted for conventions only.filterbank.GammatoneFilterbank - SciPy
minimum_phase(homomorphic method), the real-cepstrum definition MATLAB'srcepsdocuments, and Praat's PowerCepstrogram through parselmouth (GPLv3): cross-checked bytools/crosscheck_cepstrum.py, Praat at development time only.cepstrum.Cepstrum - Kaldi's
compute-mfcc-feats, through kaldi-native-fbank (Apache-2.0), a C++ re-implementation of Kaldi's feature code: its MFCCs and log mel energies are stored bytools/make_kaldi_fixtures.py, and the tests compareMFCCwith them to float32 precision (no DC removal, pre-emphasis or energy, which sonore leaves to the sound). The primary reference, standing in for HTK, whose download site was unreachable.mfcc.MFCC - librosa (ISC)
feature.mfcc,feature.melspectrogramandfeature.delta: their output for three settings is stored bytools/make_mfcc_fixtures.py, and the tests compareMFCCwith it (mel power to 3e-7, coefficients to 1e-8, both relative to the largest value).tools/crosscheck_mfcc.pyalso reproduces python_speech_features 0.6 exactly. Both are development-time only.mfcc.MFCC - LTFAT (GPLv3) and nsgt (Artistic License 2.0):
frame theory in code, for dev-time cross-checks only because of their licenses. Not yet cross-checked.
frame
Migrating from sigtools
sonore was previously sigtools, renamed to avoid a clash with an unrelated
PyPI package of that name. Version 0.2 also redesigned the API:
| sigtools 0.1 | sonore |
|---|---|
from sigtools.sounds import * etc. |
import sonore as so |
PureTone(dur, fs, f), GaussianNoise(...), ... |
so.pure_tone(dur, fs, f), so.gaussian_noise(...), ... |
GaussianNoise(dur, fs, lo, hi, tilt) |
so.gaussian_noise(dur, fs, band=(lo, hi), tilt=...); tilt is now dB/octave |
SchroederPhase(dur, fs, f0, n) |
so.schroeder_complex(dur, fs, f0, n) |
SoundLoader(path), Silence(dur, fs) |
so.load(path), so.silence(dur, fs) |
snd + 6 (dB gain) |
snd + 6*dB |
snd.make_binaural(), snd.extract_envelope() |
snd.to_stereo(), snd.envelope() (now returns an Envelope, not a Sound) |
ramp_edges(snd, d) |
snd.ramp(d) |
butter_bandpass_filter(snd, lo, hi) |
so.bandpass(snd, lo, hi) (no longer RMS-normalizes) |
equalize_fs, zeropad_sounds, center_sounds, truncate_sounds |
so.match_fs, so.pad(align="start"/"center"), so.truncate |
normalize_rms, zero_mean, concat_sounds, compare_relative_db |
so.normalize, snd.zero_mean(), so.concat, so.relative_db |
sum(zeropad_sounds([a, b])) |
so.mix([a, b]) |
MagnitudeSpectrum(s).to_Noise(dur, fs) |
so.long_term_spectrum(s).to_sound(dur, fs) |
STFT(snd, win), S.to_Sound(), method="GLA" |
so.STFT(snd, win), S.to_sound(), S.griffin_lim() |
IBM = S_t > S_m + lc; IBM * S_mix |
so.ideal_binary_mask(S_t, S_m, lc_db=lc); S_mix * mask |
Subbands(snd, n), .extract_envelopes(), .to_Sound() |
so.subbands(snd, n), .envelopes(), .synthesize() |
InterauralCues(snd, win) |
so.interaural_cues(snd, win) |
SimpleBIR(fs, itd, ild) |
so.simple_bir(fs, itd, ild) or so.apply_itd_ild(snd, itd, ild) |
SynthIR(drr, rt60, dB_thresh, fs) |
so.synth_ir(rt60, fs, drr_db=..., decay_db=-dB_thresh) |
move_sound(traj, snd) |
so.move_sound(snd, traj, hrirs) with so.load_hrirs() (downloads PKU-IOA), so.HRIRSet.from_pku_ioa(dir) or .from_sofa(path) |
display_STFT(x, S), AudioControl(snd).display() |
so.overview(x); put snd at the end of a cell |
Results computed with 0.1 can differ, because these 0.1 bugs were fixed:
spectrum and STFT "dB" were half the true value; the bandpass filter filtered
stereo across channels; SimpleBIR was a sample short and got louder with
larger ITDs; SynthIR's DRR had no effect and its resynthesis filters were
shifted in frequency; tone frequencies were off by a factor of (n-1)/n;
move_sound summed ~100 unwindowed overlapping convolutions per sample; and IAC
was never computed. The ILD in apply_itd_ild is now split ±ILD/2 across the
ears (0.1 applied it to the right ear only).
Development
pip install -e ".[dev]"
pytest                             # ~40 s; one test file per module
ruff check . && ruff format .
python docs/gallery/build.py       # regenerate the listening gallery (a few minutes)
How sonore was developed
sonore began as sigtools, the code I (Adrian Cho) wrote in graduate school to make psychoacoustic stimuli. The 0.2 redesign and everything since were developed together with Claude, Anthropic's AI assistant, in chat sessions during 2026.
What Claude did. Wrote most of the code, tests, documentation, and gallery since 0.2, delivered as patches; drafted design documents; ran numerical checks and profiling; and looked up and checked citations.
What I did. Decided what sonore is for and what goes in it, including its API conventions, the texture work and its milestones, and the roadmap and architecture. I chose and documented the texture recordings and set the working rules: implement from the papers, verify every claim numerically, document every deviation and data choice, and write a design document before large features. I reviewed and applied each patch. The design principles that came out of this are summarized in docs/design/philosophy.md.
How it is verified. I have not read every line by hand. What I rely on instead is the following:
- The test suite, with one file per module.
- Finite-difference and dense-matrix checks of the mathematics.
- Cross-checks against independent implementations (see "Reference implementations").
- Written records of every decision (
DIFFERENCES_FROM_TOOLBOX,docs/textures/SOURCES.md,docs/design/). - The listening gallery, since these are sounds and should be heard.
I am responsible for sonore's correctness. If something is wrong, please open an issue.
License and citation
MIT; see LICENSE. If sonore is useful in your research, please cite it using CITATION.cff; the Cite this repository button in the GitHub sidebar gives the same citation in APA and BibTeX.
Every release is archived on Zenodo. 10.5281/zenodo.23086165 always points to the latest version; each version also has its own DOI, listed on that page (0.3.1 is 10.5281/zenodo.23086166). Cite the version you used.
1 maintainer

Metadata
1 maintainer
Release files for sonore 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sonore-0.4.0.tar.gz | 832.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sonore-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.0 MB
Release files / sonore-0.4.0.tar.gz
| Download URL | sonore-0.4.0.tar.gz |
|---|---|
| Size | 832.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0212ea01f3b2281e93f74a2cdd2ba6e0e9878d62ded6678350078f54ee9f9306
|
|
BLAKE2b-256 checksum How to use checksums |
cbd7925534015c1e4fc6b3bf94774f2e52aa72b64dbd6ecb8169c7564ebfc849
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 3, 2026.
Transparency logRelease files / sonore-0.4.0-py3-none-any.whl
| Download URL | sonore-0.4.0-py3-none-any.whl |
|---|---|
| Size | 194.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
76c0118d522bac41a979e526ac9f8fa4f46742e45b8207d147abbd49fa8b9711
|
|
BLAKE2b-256 checksum How to use checksums |
48d5e9abcc326c48dd6bfb3737e6696002ba67b2421c0fb75c912a01e2087cf4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 3, 2026.
Transparency log













