


Overview
Speculators is a library for training speculative decoding draft models that deploy directly to LLM inference engines like vLLM. Speculative decoding is a lossless technique that speeds up LLM inference by using a smaller, faster draft model (i.e. "the speculator") to propose tokens, which are then verified by the larger base model, reducing latency without compromising output quality. The speculator intelligently drafts multiple tokens ahead of time, and the base model verifies them in a single forward pass. This approach boosts performance without sacrificing output quality, as every accepted token is guaranteed to match what the main model would have generated on its own.
Speculators standardizes this process by providing a productionized end-to-end framework to train draft models with reusable formats and tools. Trained models can seamlessly run in vLLM, enabling the deployment of speculative decoding in production-grade inference servers.

💬 Join us on the vLLM Community Slack and share your questions, thoughts, or ideas in:
#speculators#feat-spec-decode
🎥 Watch our Office Hours presentation: Video | Slides
🚀 What's New!
Big updates have landed in Speculators! To get a more in-depth look, check out the Speculators documentation.
Some of the exciting new features include:
- Multi-Node Online Training via hs_connectors: Added the
hs_connectorsplugin package with pluggable backends for transferring hidden states between vLLM and the trainer across nodes. The file-based backend uses a shared filesystem, while the Mooncake backend leverages a distributed store for environments without shared storage, enabling online speculator training at multi-node scale. - DSpark Training Algorithm: Added support for the DSpark training algorithm, which extends DFlash's anchored-block drafting with a Markov head that conditions each draft position on the previous token within the block, plus a confidence head that predicts per-position acceptance probability. DSpark checkpoints can warm-start from existing DFlash checkpoints.
- P-EAGLE Training Support: Added support for the P-EAGLE training algorithm, which extends EAGLE-3's architecture with parallel multi-token prediction via Conditional-On-Distribution (COD) sampling. Rather than generating draft tokens sequentially, P-EAGLE predicts multiple tokens in a single forward pass, reducing drafting latency. The Red Hat team published a P-EAGLE speculator for Qwen3-8B.
- MTP Finetuning Support: Added support for finetuning the native Multi-Token Prediction (MTP) heads of models like Qwen3-Next on domain-specific data, following the FastMTP approach. Because the MTP head is small (~100M–400M params), it can be trained on pre-extracted hidden states without loading the full verifier
- Sliding Window Attention for DFlash and DSpark: DFlash and DSpark speculators use sliding window attention on all draft layers by default. Use
--sliding-windowto set the window size and--full-attention-indicesto opt specific layers into full attention. Sliding window attention reduces KV cache allocation for long-context sequences and can improve per-position acceptance rates compared to full attention. - DFlash Training Algorithm: Added support for the DFlash training algorithm with anchored-block drafting, using auxiliary hidden states from multiple verifier layers. Includes CLI options for block size and max anchors, plus DFlash metrics, utilities, and draft model. DFlash models trained through Speculators can now run seamlessly in vLLM as of vLLM PR #38300.
Key Features
- Offline Training Data Generation using vLLM: Enable the generation of hidden states using vLLM. Data samples are saved to disk and can be used for draft model training.
- Draft Model Training Support: E2E training support of single and multi-layer draft models. Training is supported for MoE, non-MoE, and Vision Language models.
- Standardized, Extensible Format: Provides a Hugging Face-compatible format for defining speculative models, with tools to convert from external research repositories into a standard speculators format for easy adoption.
- Seamless vLLM Integration: Built for direct deployment into vLLM, enabling low-latency, production-grade inference with minimal overhead.
[!TIP] Read more about Speculators features in this vLLM blog post.
Supported Models
The following table summarizes the models that have been trained end-to-end by our team as well as others in the roadmap:
| Verifier Architecture | Verifier Size | Training Support | vLLM Deployment Support |
|---|---|---|---|
| Llama | 8B-Instruct | EAGLE-3 ✅ | ✅ |
| 70B-Instruct | EAGLE-3 ✅ | ✅ | |
| Qwen3 | 8B | EAGLE-3 ✅ DFlash ✅ P-EAGLE ✅ |
✅ |
| 14B | EAGLE-3 ✅ | ✅ | |
| 32B | EAGLE-3 ✅ | ✅ | |
| gpt-oss | 20b | EAGLE-3 ✅ | ✅ |
| 120b | EAGLE-3 ✅ | ✅ | |
| Qwen3 MoE | 30B-Instruct |
EAGLE-3
✅ DFlash ✅ |
✅ |
| 30B | DFlash ✅ | ✅ | |
| 235B-Instruct | EAGLE-3 ✅ | ✅ | |
| 235B | EAGLE-3 ✅ | ✅ | |
| Qwen3-VL | 235B-A22B | EAGLE-3 ✅ | ✅ |
| Mistral Small 4 | 119B | DFlash ✅ DSpark ✅ |
✅ |
| Gemma 4 | 31B-it | EAGLE-3 ✅ DFlash ✅ |
✅ |
| Gemma 4 MoE | 26B-A4B-it | EAGLE-3 ✅ | ✅ |
| NVIDIA Nemotron 3 Ultra | 550B-A55B | DFlash ✅ | ✅ |
| NVIDIA Nemotron 3 Super | 120B-A12B | DFlash ✅ | ✅ |
| Kimi K3 | - | DSpark ✅ | ✅ |
| Qwen3.6 MoE | 35B-A3B | DSpark ✅ | ✅ |
| GLM 5.2 | - | DSpark ✅ | ✅ |
✅ = Supported, ⏳ = In Progress, ❌ = Not Yet Supported
vLLM Inference
Models trained through Speculators can run seamlessly in vLLM using a simple vllm serve <speculator_model> command. This will run the model in vLLM using default arguments, defined in the speculator_config of the model's config.json.
vllm serve RedHatAI/Qwen3-8B-speculator.eagle3
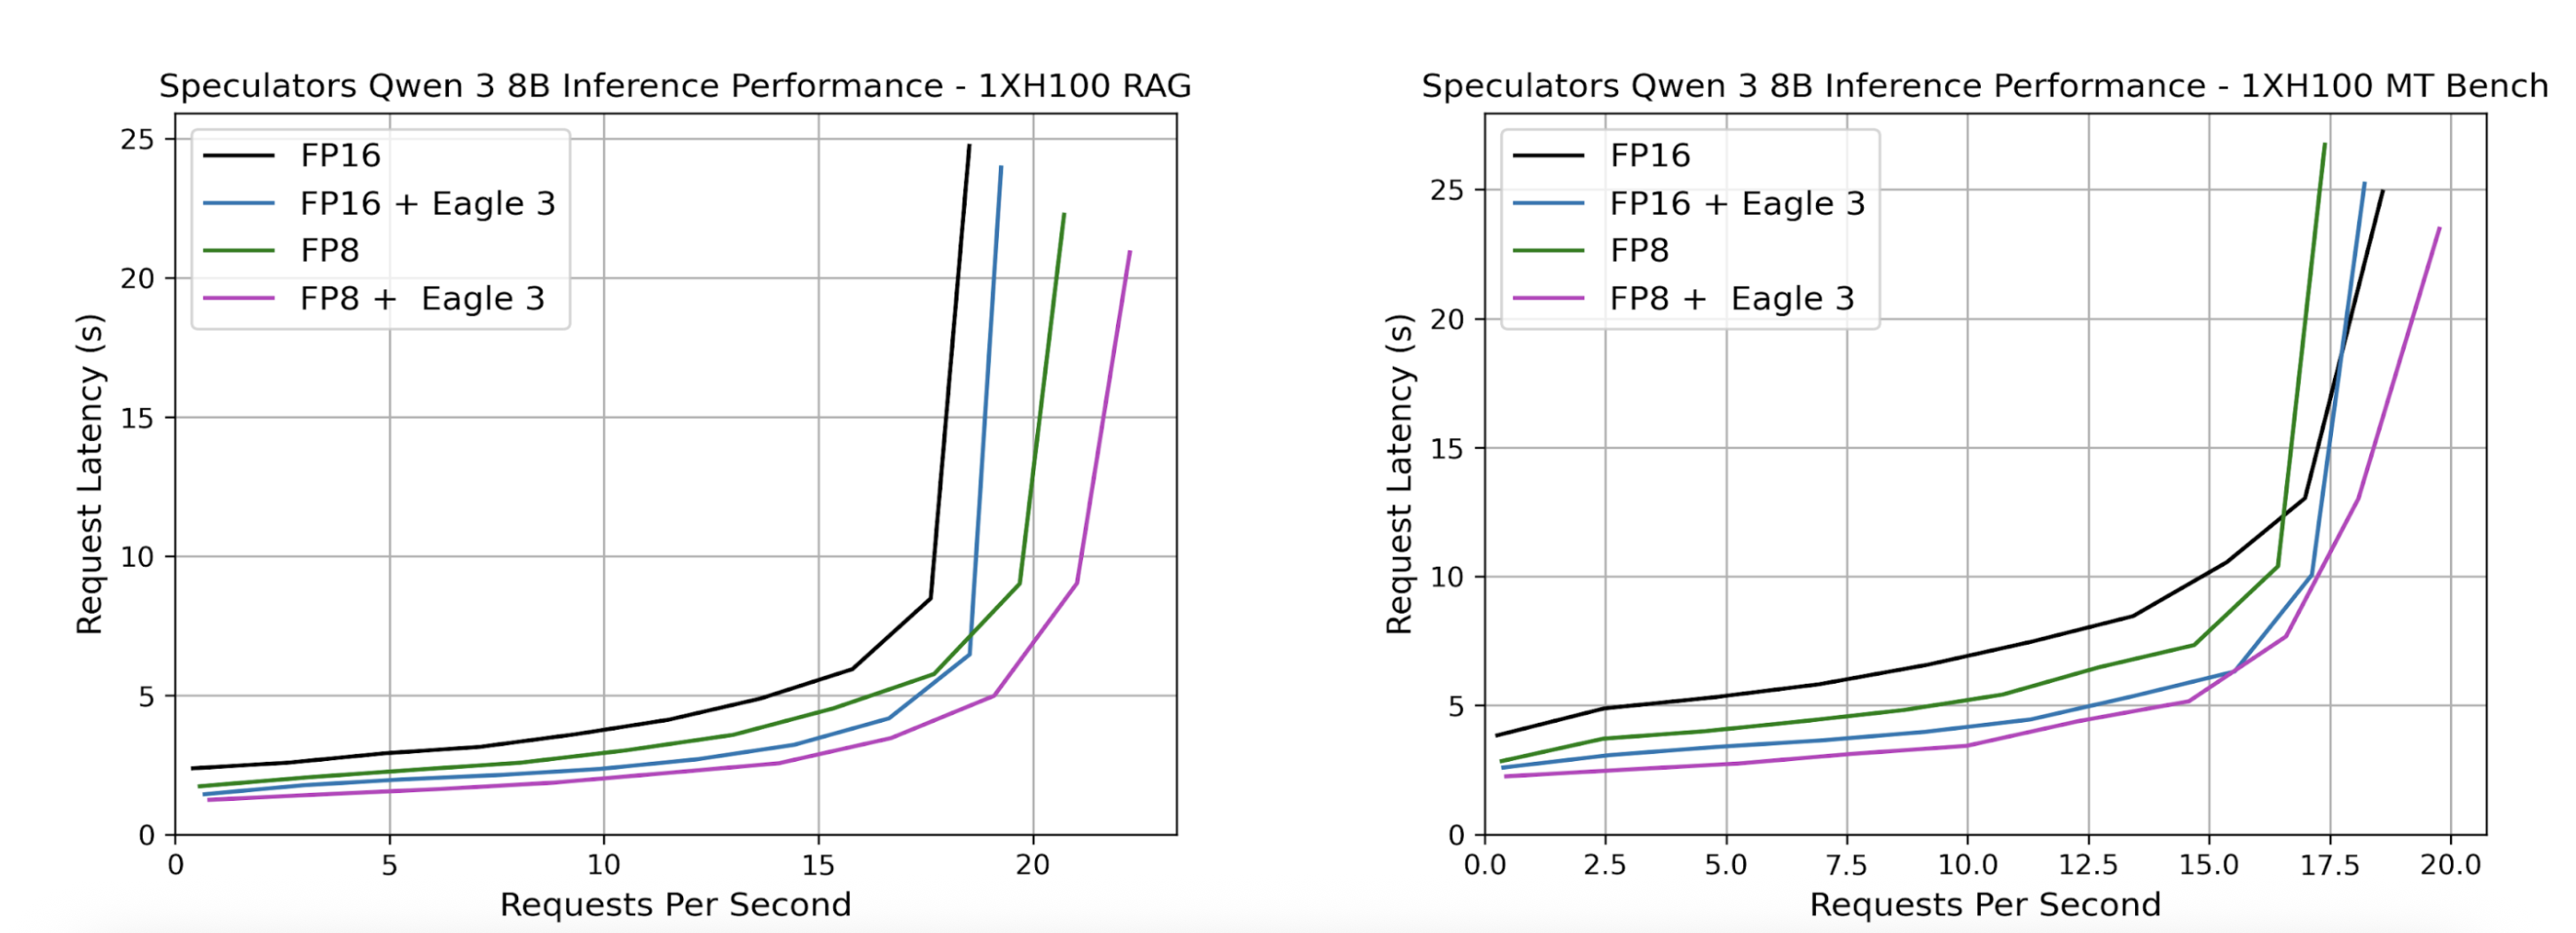
Served models can then be benchmarked using GuideLLM. Below, we show sample benchmark results where we compare our speculator with its dense counterpart. We also additionally compare quantization to explore additional performance improvements by swapping the dense verifier, Qwen/Qwen3-8B with the quantized FP8 model, RedHatAI/Qwen3-8B-FP8-dynamic in the speculator_config.
Additional Utility Scripts
Getting Started
Installation
Prerequisites
Before installing, ensure you have the following:
- Operating System: Linux or macOS
- Python: 3.10 or higher
- Package Manager: pip (recommended) or conda
Install from PyPI (Recommended)
Install the latest stable release from PyPI:
pip install speculators
Install from Source
For the latest development version or to contribute to the project:
git clone https://github.com/vllm-project/speculators.git
cd speculators

pip install -e .
For development with additional tools:
pip install -e ".[dev]"
Verify Installation
You can verify your installation by checking the version:
speculators --version
Or by importing the package in Python:
import speculators
print(speculators.__version__)
License
Speculators is licensed under the Apache License 2.0.
Cite
If you find Speculators helpful in your research or projects, please consider citing it:
@misc{speculators2025,
  title={Speculators: A Unified Library for Speculative Decoding Algorithms in LLM Serving},
  author={Red Hat},
  year={2025},
  howpublished={\url{https://github.com/vllm-project/speculators}},
}
1 maintainer

Metadata
1 maintainer
Release files for speculators 0.8.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| speculators-0.8.0.tar.gz | 214.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| speculators-0.8.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 460.7 kB
Release files / speculators-0.8.0.tar.gz
| Download URL | speculators-0.8.0.tar.gz |
|---|---|
| Size | 214.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c42a30578abfef54040695930571f91e7866d4936980ed4686796e67abee69f9
|
|
BLAKE2b-256 checksum How to use checksums |
f8edb4de3aaaf7cc47f5eb1c7c5150272c2244323042cd9c47d39885a9bfd77b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 3, 2026.
Transparency logRelease files / speculators-0.8.0-py3-none-any.whl
| Download URL | speculators-0.8.0-py3-none-any.whl |
|---|---|
| Size | 246.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f3c35a74c31b3aa219f26016405ef55ea7dcdf710d7d25473304f7b981e9f596
|
|
BLAKE2b-256 checksum How to use checksums |
f3099e41a0ac86df806b6ad462ab97c6ef622488a8dbf2d6b011509ea1f2e99a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 3, 2026.
Transparency log













