
Starlet
Turn large geospatial datasets into fast, interactive maps. Starlet partitions a geospatial dataset (GeoParquet, GeoJSON, CSV, vector files, GPX tracks, or GeoLife PLT trajectories) into spatial tiles, generates Mapbox Vector Tiles, and serves them over HTTP with a built-in web viewer — all from a single command-line tool.
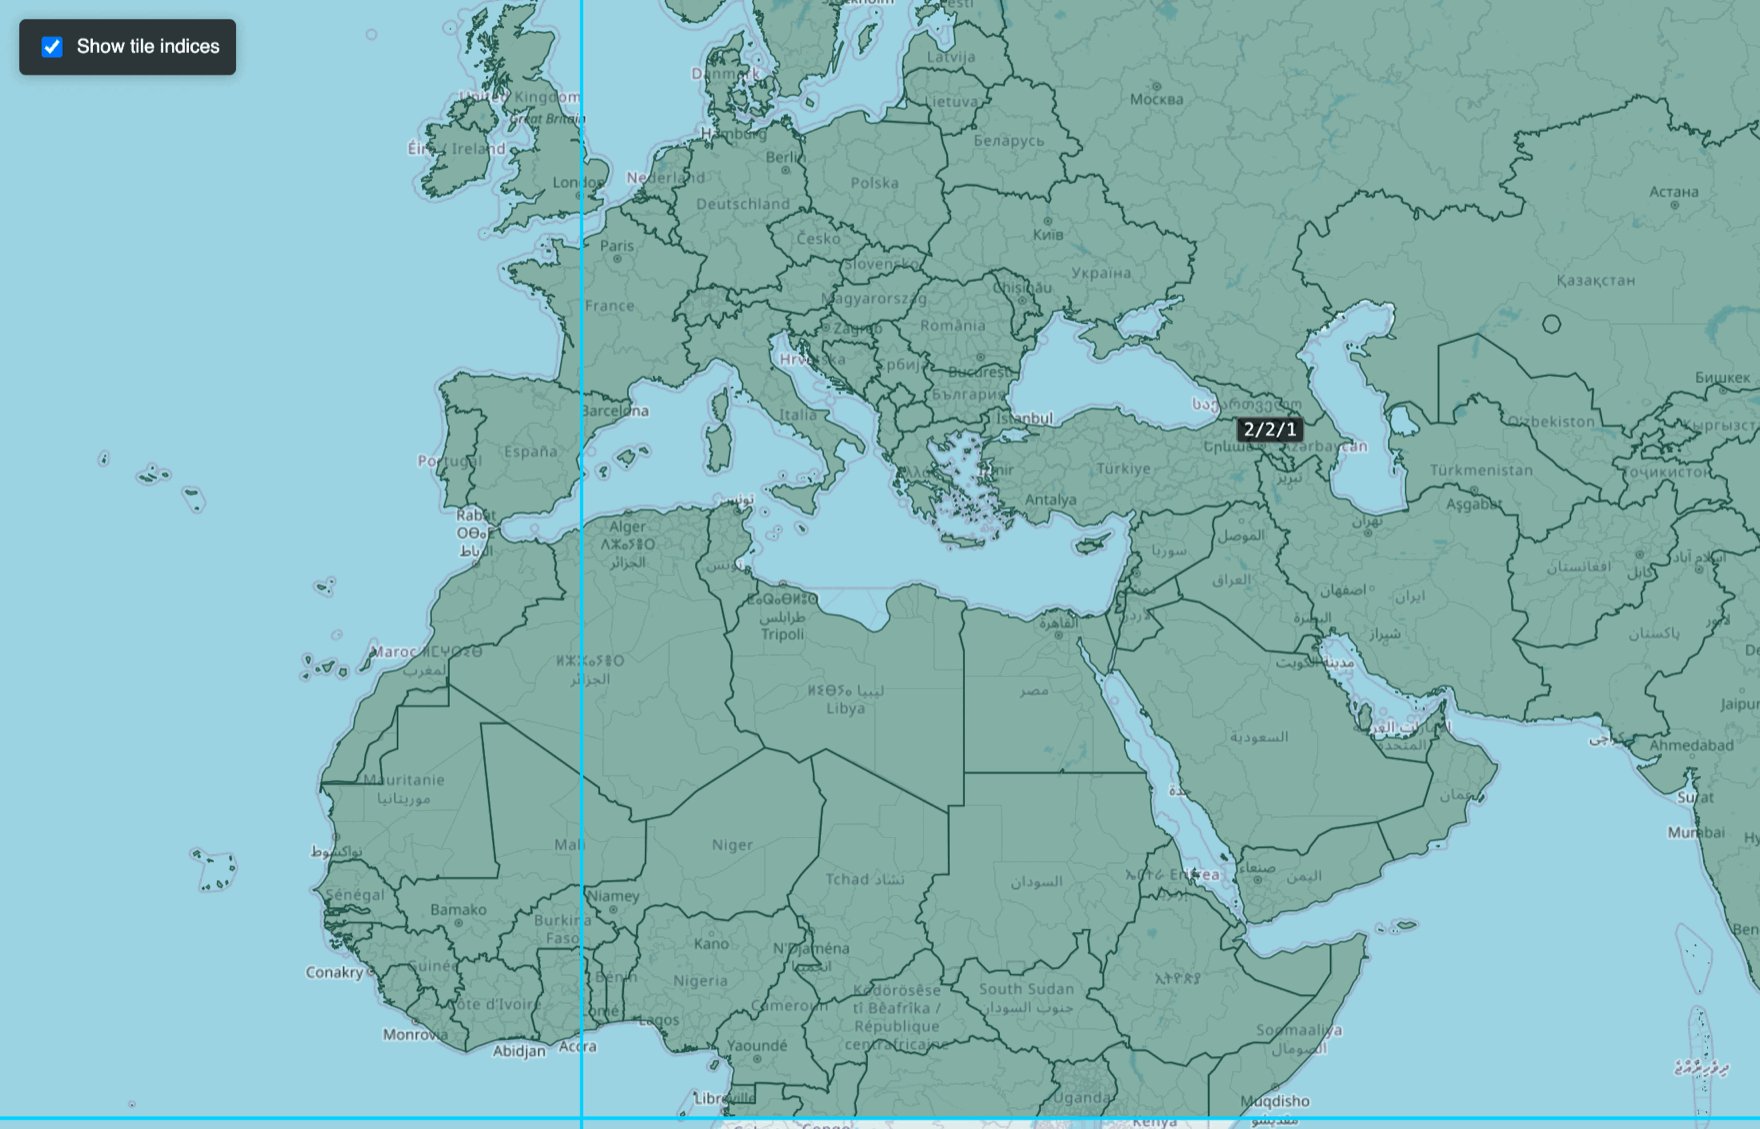
Install
pip install starlet
Requires Python 3.10+. On systems where pip points at Python 2, use pip3:
pip3 install starlet
This installs the starlet command-line tool. Check it:
starlet --version
For local development and testing, install the project with dev dependencies:
pip install -e ".[dev]"
Quick start
Go from a data file to a live map in two commands:
# 1. Build a dataset: partition into tiles + pre-generate vector tiles
starlet build --input data.parquet --outdir datasets/mydata

# 2. Serve it
starlet serve --dir datasets --port 8765
Open http://localhost:8765 and pick your dataset to explore it on a map.
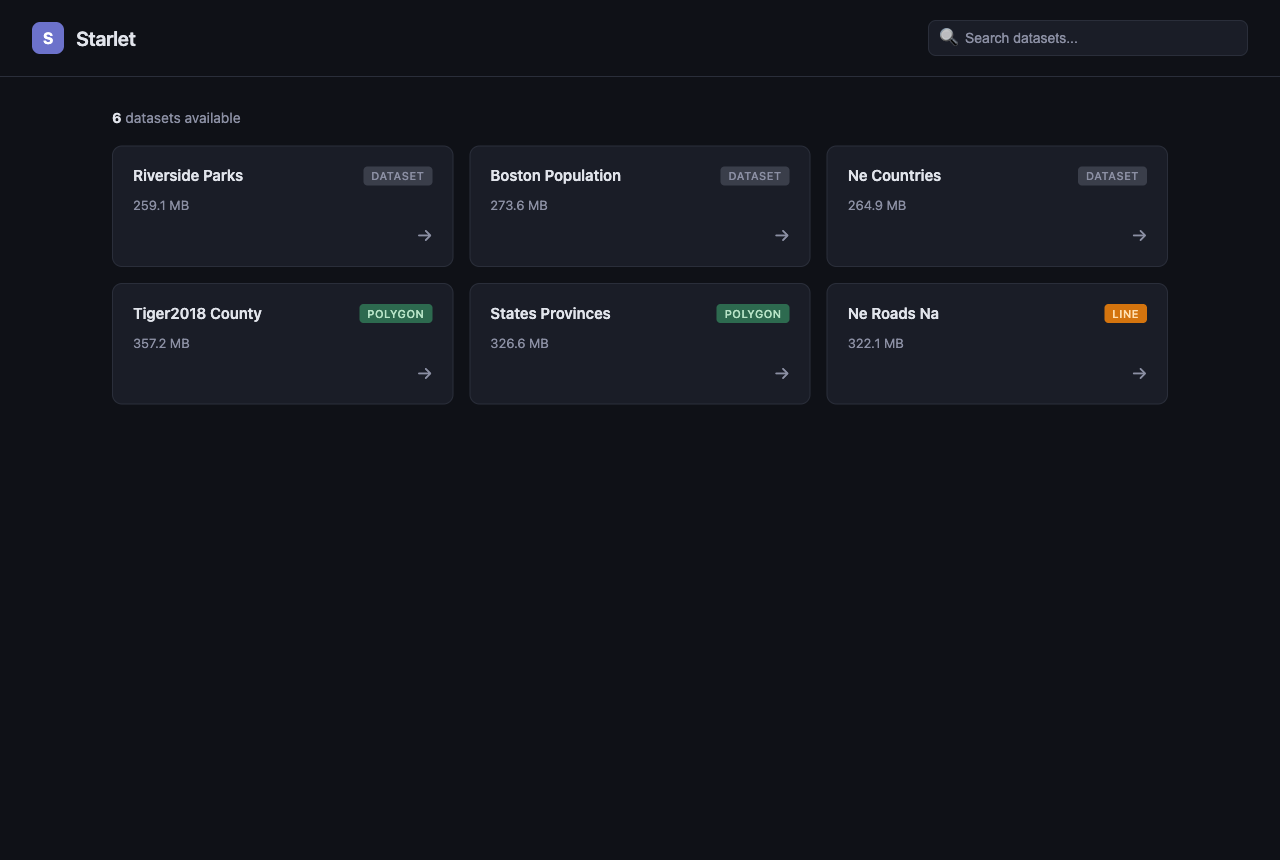
📖 Read the Guide → — using Starlet inside another project (CLI, Python API, embedded server) and styling the tiles with MapLibre (categorical, gradient, and label recipes, with screenshots).
Commands
Everything runs through the starlet CLI. Run starlet <command> --help for the
full option list.
| Command | What it does |
|---|---|
starlet build |
Full pipeline: partition and generate vector tiles |
starlet tile |
Partition a dataset into spatial Parquet tiles only |
starlet mvt |
Generate vector tiles from an already-tiled dataset |
starlet serve |
Run the HTTP tile server + web viewer |
starlet info |
Print a summary of a dataset (tiles, bbox, zoom levels) |
The options you'll actually use
| Option | Commands | Default | Description |
|---|---|---|---|
--input / --outdir |
build, tile | required | Source file and output dataset directory |
--zoom |
build, mvt | 7 |
Maximum vector-tile zoom level (an upper bound with --min-tile-bytes) |
--min-tile-bytes |
build, mvt | off | Size-threshold mode: pre-generate every tile estimated to be at least this large (e.g. 50kb), whatever its zoom; smaller tiles are served on the fly (see below) |
--geom-col |
build, tile | geometry |
Geometry column name (use wkb_geometry for OGR/ogr2ogr exports) |
--partition-size |
build, tile | 128mb GeoParquet / 512mb GeoJSON |
Target tile size, e.g. 256mb, 1gb |
--pmtiles |
build, mvt | off | Also export a single .pmtiles archive |
--threshold |
build, mvt | 0 |
Minimum estimated density (vertices or covering features) for a tile to be generated |
--feature-capacity |
build, mvt | 10000 |
Max features larger than a pixel kept per tile (see below) |
--tile-attributes |
build, mvt, serve | all |
Attribute columns written into tiles: all, none, or name,class,… (see below) |
--mvt-memory-budget |
build, mvt | auto |
Total memory target for concurrent MVT mappers, e.g. 24gb, or none |
--dir |
serve, mvt, info | required | Dataset directory (or the root of several, for serve) |
--port |
serve | 8765 |
Port to bind the server |
How tiles stay small without going sparse
A tile is selected per display pixel, the way a rasterised plot would be:
every feature that fits inside one pixel competes only with the other
sub-pixel features of the same pixel, and one survives, so a low-zoom tile
shows every occupied pixel with a bounded feature count. Sub-pixel polygons
and lines are drawn as one-pixel shapes of their own type (a tiny park is
still a polygon, styled like the big ones) and carry no attributes. Features
larger than a pixel keep their simplified shape and attributes; only they
are subject to --feature-capacity. Selection is deterministic (a hash of
the geometry), so neighbouring tiles and zoom levels agree on what they keep.
Attributes are usually the bulk of a tile (on OSM extracts, the tag blob can
be 70% of the bytes). --tile-attributes none writes geometry-only tiles
(several times smaller); --tile-attributes name,class keeps just the
columns your style needs. Clicking a record in the viewer fetches its full
attributes from the server
(GET /datasets/<dataset>/features/at.json?mbr=minx,miny,maxx,maxy), so they
are always available, whatever the tiles carry.
Which tiles get pre-generated: by zoom or by size
Starlet pre-generates a pyramid of vector tiles and renders everything else on the fly when it is served. Two mutually exclusive modes decide what goes into the pyramid; one option switches between them:
| Mode | How to select it | What is pre-generated |
|---|---|---|
| Zoom mode (default) | --min-tile-bytes unset or 0; --zoom N (default 7) |
Every non-empty tile from zoom 0 to N (subject to --threshold) |
| Size mode | --min-tile-bytes SIZE, e.g. 50kb |
Every tile, at any zoom, estimated to be at least SIZE uncompressed bytes; --zoom becomes only an upper bound (default 22) |
In the config file the same switch is [mvt] min_tile_bytes (0 = zoom
mode) next to zoom; in Python it is the min_tile_bytes argument of
starlet.build() / starlet.generate_mvt(). Switching modes changes only
which tiles are written ahead of time: tile content is identical in both
modes and identical to what the server renders on the fly.
A fixed --zoom either stops too early for dense areas or wastes time on
thousands of tiny tiles elsewhere. --min-tile-bytes turns the pyramid into a
size-threshold build: zoom 0 is always written, then zoom by zoom only the
tiles whose encoded size is estimated to reach the threshold are generated
and descended into. Tiles that cannot reach the threshold are pruned with a
bound from the dataset's vertex and coverage histograms; the rest are
estimated from a handful of probe tiles generated and measured at the same
zoom (so it adapts to the data and to --feature-capacity /
--tile-attributes), and below the histogram resolution every candidate is
simply generated and measured. Everything below the threshold is cheap to
render and is left to the on-the-fly server. --zoom still caps the depth
(default 22 in this mode). Sizes are uncompressed MVT bytes; the estimate
errs towards pre-generating some small tiles rather than missing large ones.
# Zoom mode: every tile up to zoom 8
starlet build --input states.parquet --outdir datasets/states --zoom 8

# Size mode: every tile that would be ~50 KB or more, at any zoom up to 22
starlet build --input states.parquet --outdir datasets/states --min-tile-bytes 50kb

# Size mode, but never deeper than zoom 14
starlet build --input states.parquet --outdir datasets/states --min-tile-bytes 50kb --zoom 14
Examples
# Build to a deeper zoom (more detail when you zoom in)
starlet build --input roads.parquet --outdir datasets/roads --zoom 12

# GeoJSON input, custom geometry column
starlet build --input places.geojson --outdir datasets/places --geom-col wkb_geometry

# Serve a whole folder of datasets; the viewer lists them all
starlet serve --dir datasets --port 8765

# Inspect what got built
starlet info --dir datasets/roads
Input formats
Starlet reads GeoParquet (WKB or native GeoArrow geometry encodings),
GeoJSON / GeoJSON Lines, Shapefile (.shp, zipped), File
Geodatabase, GeoPackage, FlatGeobuf (and other single-file OGR
formats such as GML/KML), and CSV (with either x/y columns or a WKT
column — see starlet tile --help). Gzip/bzip2/xz-compressed files
(.geojson.gz, ...) are decompressed on the fly. The CRS is taken from the
file (GeoParquet metadata, the GeoJSON crs member, OGR layer CRS) and
defaults to longitude/latitude (EPSG:4326); tiles are produced in Web
Mercator (EPSG:3857). GeometryCollection features are split into one feature
per geometry type, since vector tiles have no collection type.
One-file distribution with PMTiles
Pass --pmtiles to pack every generated tile into a single
PMTiles archive — handy for shipping a
dataset as one file or hosting it on static storage:
starlet build --input data.parquet --outdir datasets/mydata --pmtiles
Server API
While starlet serve is running:
| Method | Path | Description |
|---|---|---|
GET |
/ |
Interactive dataset browser |
GET |
/api/datasets |
List available datasets |
GET |
/<dataset>/<z>/<x>/<y>.mvt |
A Mapbox Vector Tile |
GET |
/datasets/<dataset>.json |
Dataset metadata (bbox, zoom range) |
GET/POST |
/datasets/<dataset>/features.<csv|geojson> |
Download features (optional geometry filter) |
GET |
/api/datasets/<dataset>/stats |
Per-attribute statistics |
GET |
/datasets/<dataset>/features/at.json?mbr=… |
Records under a point (click-to-inspect), with attributes |
Tiles are served in tiers — an in-memory LRU cache, then a pre-generated
PMTiles archive or .mvt files on disk, then generated on the fly from the
Parquet tiles when you zoom past the pre-built levels — so you can serve a
dataset even without pre-generating every zoom.
Tile generation is vectorised (numpy + shapely arrays, a numpy MVT encoder,
a bounded cache of decoded Parquet row groups), so the pure-Python install
serves on-the-fly tiles in milliseconds at high zoom and builds pyramids
without intermediate files. An optional Rust core (starlet_core, in
rust/starlet-core) produces the same tiles another 5–30× faster and is used
automatically when installed. See
DEVELOPMENT.md.
Configuration
Settings you reuse often (partition size, zoom, worker count, …) can live in a
starlet.toml file instead of being passed on every command. Copy
starlet.toml.example to starlet.toml and edit it;
Starlet loads it automatically. CLI flags always override the file. See
docs/CONFIGURATION.md for the full list of keys.
Deploying a server
docs/DEPLOYMENT.md walks through standing up a production tile server, including a no-root recipe behind an existing Apache install.
Using Starlet from Python
starlet is also importable — tile(), generate_mvt(), build(),
export_pmtiles(), and create_app() are documented in
docs/PUBLIC_API.md.
For worked examples — using the CLI or API inside another project, embedding the tile server, and styling the tiles with MapLibre (categorical, gradient, and label recipes) — see the Guide.
Want to work on Starlet itself — run it from a clone, run the tests, or contribute a change? See DEVELOPMENT.md.
License
Starlet is distributed under the MIT License.


Release files for starlet 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| starlet-0.5.0.tar.gz | 203.4 kB | With provenance | Details for starlet-0.5.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| starlet-0.5.0-py3-none-any.whl | Python 3 | none | any | Details for starlet-0.5.0-py3-none-any.whl |
Total release size: 425.1 kB
Release files / starlet-0.5.0.tar.gz
| Download URL | starlet-0.5.0.tar.gz |
|---|---|
| Size | 203.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5d3165fa1aa8d4ac53f6ea6bd388ffe4080e38d2dd7f6dc586b4282eddfdb348
|
|
BLAKE2b-256 checksum How to use checksums |
3092839147345d7528e25220f4be41d8e70d1b1de4cdf699d013a03fea44ef5e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 27, 2026.
Transparency logRelease files / starlet-0.5.0-py3-none-any.whl
| Download URL | starlet-0.5.0-py3-none-any.whl |
|---|---|
| Size | 221.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e527641e2382157874caa05c74ad6fbd5005e927b283cf6d41afa4040d8a3a07
|
|
BLAKE2b-256 checksum How to use checksums |
2b36faf977571cd6848a0f1ec7a3bdce0561cc34eee5a7833a95720ee30a8d39
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 27, 2026.
Transparency logSecurity for starlet 0.5.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for starlet-0.5.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 27, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














