
sttop


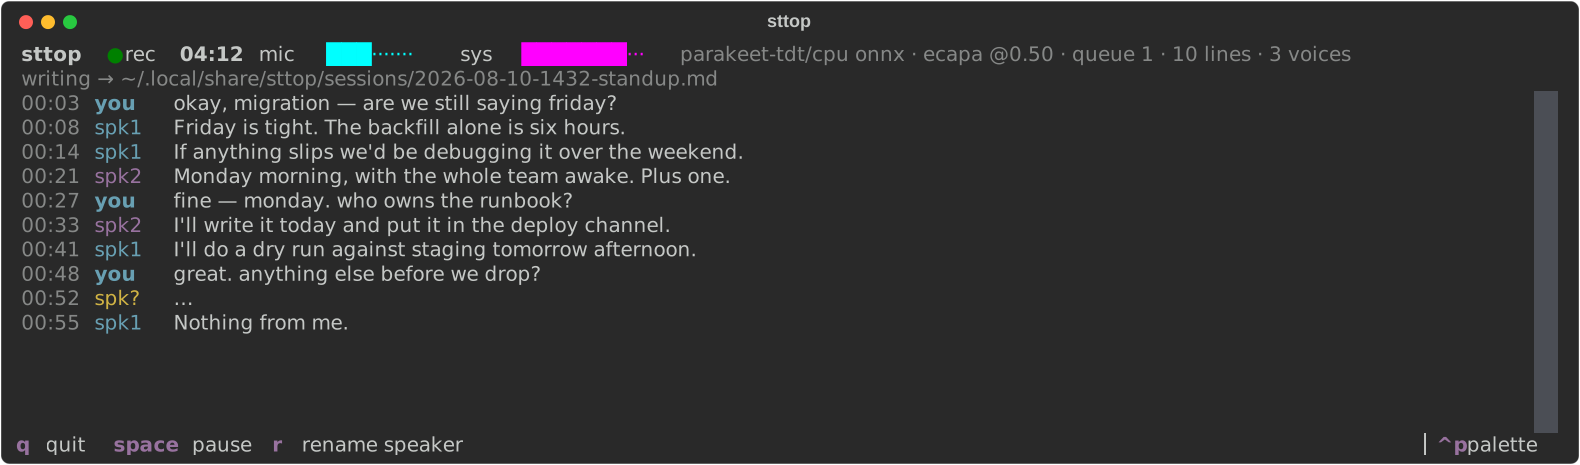
Live speech-to-text monitor for the terminal — htop, but for what is being said.
Taps your microphone and your system audio output as two independent streams, transcribes both in real time, labels who is speaking, and appends every line to a Markdown file as it happens. Fully local: no network, no API keys, nothing leaves the machine.
Why two streams
Capturing the mic and the speaker output separately means you are identified for free — anything on the mic is you, no model required, never wrong. Voice embeddings then only have to split the remote side into individual participants, which is a much easier problem than diarizing a single mixed track.
Install
uvx --index https://download.pytorch.org/whl/cpu sttop
The --index flag matters. Speaker labelling needs torch, and the stock PyPI torch
bundles CUDA — about 2.5GB of nvidia wheels that buy nothing here, since
CTranslate2 has no ROCm backend and CPU inference keeps up with live audio fine.
The flag points torch at the CPU builds and falls back to PyPI for everything else.
That is the whole install on Linux. There is nothing to apt install first: if
the machine has no ffmpeg, sttop fetches a static one into its own data
directory on first run, and pactl is optional — the audio server resolves the
default mic and monitor itself, so pactl is only needed to pick a source by
name. Run sttop doctor to see what it found.
macOS needs nothing installed either. The mic comes from AVFoundation and system audio from ScreenCaptureKit — no BlackHole, no Multi-Output Device, and your output device and volume keys keep working, because nothing is rerouted. It does need permission, granted once to the terminal you run sttop in:
System Settings → Privacy & Security → Screen & System Audio Recording
Restart the terminal afterwards; macOS only re-reads that permission at launch. Requires macOS 13 (Ventura) or newer — on anything older, or before the permission is granted, sttop records the mic only and says so rather than refusing to start.
To install it permanently rather than running it ad hoc:
uv tool install --index https://download.pytorch.org/whl/cpu sttop
From a checkout, uv sync reads the CPU index out of pyproject.toml already:
git clone https://github.com/v4rgas/sttop && cd sttop
uv sync
Use
uv run sttop                       # record with defaults
uv run sttop -t "standup"          # title the session (used in the filename)
uv run sttop --backend whisper -m small
uv run sttop devices --test        # list audio sources, record 1s from each
uv run sttop doctor                # check the audio deps, explain anything missing
uv run sttop sessions              # list past transcripts
uv run sttop read                  # open the latest transcript (decrypting it if needed)
uv run sttop read standup          # ...or any session, by filename substring
uv run sttop sync                  # encrypted cloud backup; first run sets everything up
uv run sttop config                # write ~/.config/sttop/config.toml
uv run sttop theme                 # show the detected terminal colour scheme
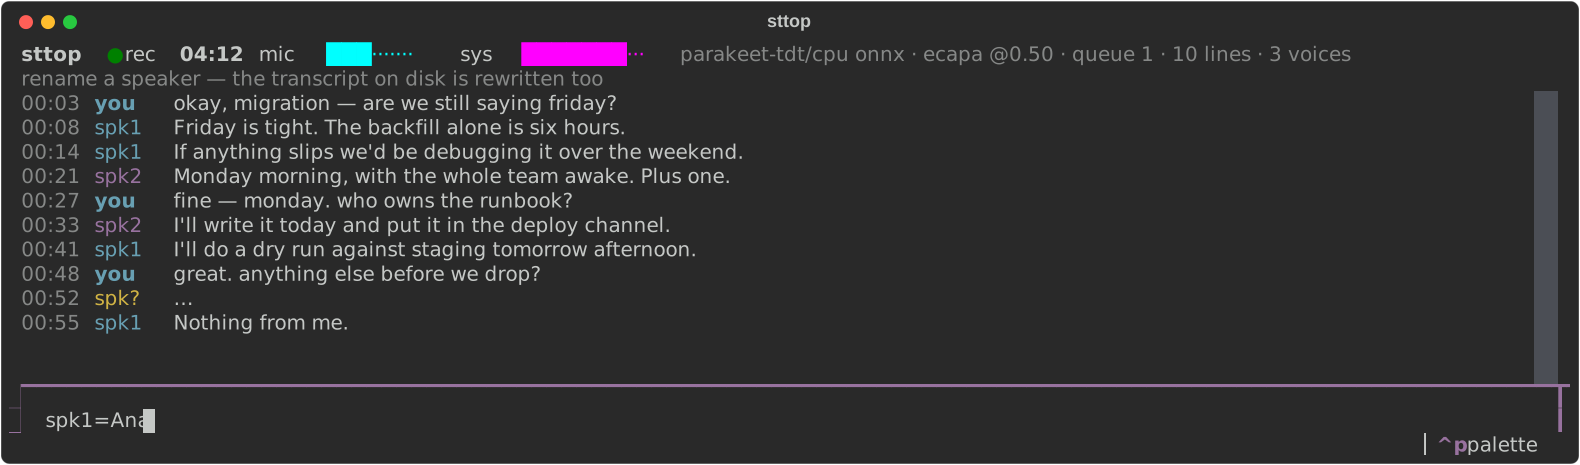
Keys: q name the session & quit (micelio/daily → micelio/daily.DATE.md, tab completes) · ctrl+c quit unnamed · space pause · r rename a speaker · y copy the transcript so far.
y puts everything transcribed up to this moment on the clipboard — for pasting
into notes or an assistant while the meeting is still going, without stopping the
recording. It goes out as OSC 52, so it reaches your system clipboard even over
ssh on terminals that support it.
A rename is retroactive — spk1=Ana relabels the live view and rewrites every
line already written to the Markdown file, so you can name people once you
recognise them rather than before you start.
Output
One Markdown file per session in ~/.local/share/sttop/sessions/, flushed after every
line — kill it mid-meeting and the transcript so far is already on disk.
# standup

- started: 2026-08-10 14:32:01 -04
- mic: `alsa_input.pci-0000_08_00.6.analog-stereo`
- system: `alsa_output.pci-0000_08_00.6.analog-stereo.monitor`
- backend: `parakeet-tdt/cpu onnx`

## Transcript

- `03:58` **you** — so the migration lands friday?

- `04:02` **spk1** — friday is tight, monday is safer
Encrypted cloud sync
One command, once:
uv run sttop sync
The first run is the setup: it asks for a private repo to push to — leave it
empty and, if the gh CLI is logged in, sttop offers to create one for you
(gh repo create <name> --private); decline and history stays local-only. Then
it asks for a vault passphrase — leave that empty and a strong random one is
generated and kept in the sessions' .env, ready to copy to another machine.
Both answers are remembered, the first push happens, and every run after that —
including the automatic one after each recording — is the same command with
nothing left to ask. To change the repo later, edit storage.git_remote in
the config.
After every session sttop commits to a git repo it manages inside the sessions
directory and pushes. On your machine nothing changes: sessions stay plain
Markdown, sttop read and grep work as always, and no passphrase is ever
asked while you work. What enters the repo is a sealed twin of each transcript
(*.md.enc — the same Markdown, encrypted with AES-256-GCM under a
scrypt-derived key), so reading the cloud copy takes sttop read plus the
passphrase, not a browser.
The passphrase is chosen once, at your first sync, and then remembered in a
.env beside the sessions (owner-readable only) — typed once ever per machine.
That is safe because the plaintext already lives on the same disk: the stored
key protects the remote exactly as well, it just stops the prompting. The salt
travels in .sttop-vault, which is committed — so a fresh clone on another
machine carries everything decryption needs except the passphrase.
The repo's .gitignore is a whitelist — everything is ignored except
*.md.enc and .sttop-vault — so plaintext transcripts, WAVs, logs and the
.env key can never enter history, even by accident, and sttop repairs the
file if it drifts. If a push fails (offline, say), the commit is still local
and sttop sync retries later; two machines pushing to one remote reconcile
by rebase. A lost passphrase makes the cloud copies unrecoverable — the
local plaintext is unaffected.
Multiple machines share one repo and one passphrase. On a new PC, run
sttop sync, give it the same remote, and it adopts the existing repo —
sessions and vault come down before anything local is created — then asks for
the passphrase once and remembers it. From then on every machine converges on
its own: opening sttop pulls other machines' sessions in the background while
the model loads, quitting waits for any pull still in flight, and every sync
integrates the remote before pushing. Histories that diverge are rebased
automatically; if the same session was rewritten on two machines (a rename on
each side, say), the machine holding its plaintext wins — it can always
re-seal — and anything else defers to the remote.
If you want ciphertext on disk too — a stolen-laptop threat model — set
storage.encrypt = "always": sessions are then written as *.md.enc directly
(still flushed per utterance, so a hard kill loses nothing), the passphrase is
asked each run (STTOP_PASSPHRASE skips it), nothing is remembered in .env,
and mid-meeting y is the way to plaintext.
How it works
mic     (pulse / avfoundation)  ─┐
                                 ├─ webrtcvad ─→ queue ─→ parakeet ─→ ecapa ─→ journal.md
system  (monitor / ScreenCaptureKit) ─┘
The mic is always an ffmpeg subprocess. System audio is one too on Linux, where the monitor source is just another pulse device; on macOS it is an in-process ScreenCaptureKit stream, converted to the same 16 kHz mono frames before it reaches the segmenter, so everything downstream sees one format.
Audio is cut into utterances by voice-activity detection (a segment closes after 700 ms of silence, or at 15 s for a monologue), and only speech reaches the model.
One thread boundary, and it is the model. The two capture readers and the
consumer are asyncio tasks — they are blocking pipe I/O, which is what an event
loop is for — while transcription and voice embedding run in a single-worker
ThreadPoolExecutor. So the UI needs no cross-thread marshalling, shutdown is
ordinary task cancellation, and utterances stay in the order they were spoken. The
executor is single-worker on purpose: transcription is CPU-bound and already
internally parallel, so a second worker would only thrash the cache. When it falls
behind, the queue absorbs the lag — visible as queue N in the status bar — rather
than dropping audio.
Speaker labels come from online clustering of ECAPA-TDNN voice embeddings: each
utterance is embedded as overlapping windows, averaged, and matched against running
centroids by cosine similarity. A confident match (≥ threshold) joins that speaker;
a near miss (within margin below it) joins too, but without touching a settled
centroid; only a clearly distant voice opens a new speaker.
Opening a speaker is a much stronger claim than recognising one, so it takes more
evidence — which is what keeps one person from turning into eight. A short utterance
that matches nobody is held rather than acted on: two words embed to mostly noise,
and noise resembles nothing, including the next piece of noise. It becomes a speaker
only once something later looks like it. Until then the line reads spk?, which is
the honest answer. If you already know who is in the room, --speakers N caps the
count outright and the nearest voice always wins.
Assignments are greedy, but they are not final. Once two settled speakers look like
the same person (≥ merge_threshold) they are merged, and the losing label is
rewritten throughout the transcript — the file on disk is corrected, and the TUI notes
the relabelling rather than silently disagreeing with it. Deciding now and revising
when the evidence arrives is what keeps real-time labels from freezing an early
mistake. Segments under min_speech_s are too short to embed at all and inherit the
previous speaker, or show as spk?.
Backends
parakeet (default) — NVIDIA Parakeet TDT 0.6b v3 through onnxruntime. Multilingual
across 25 European languages with autodetection, punctuated output, and roughly 19×
real time on CPU. Needs neither torch nor the NeMo toolkit, since onnx-asr runs the
exported graph directly. On the same 11 s clip where whisper tiny produced a
hallucinated lead-in and lost its punctuation, Parakeet returned the sentence verbatim.
whisper — faster-whisper/CTranslate2, if you want Whisper's language coverage.
CTranslate2 ships CUDA and CPU backends only — there is no ROCm build, so on an AMD
GPU this runs on CPU no matter what torch reports. The device is detected at startup
(cuda if CTranslate2 sees one, else cpu) and shown in the status bar.
To push a Radeon card at the diarization half, resync torch against the ROCm index
(see the comment in pyproject.toml).
Config
~/.config/sttop/config.toml. Run sttop config to write a default with every
knob and its documentation in it; the comments come from the source, so the file
never drifts from the code. Anything you leave out keeps its default, and blank
means "you decide" wherever a default is picked for you.
sessions_dir = "~/.local/share/sttop/sessions"

[audio]
mic_source = ""        # substring match against source names; blank = default
system_source = ""     # blank = the default monitor; ignored on macOS
save_wav = false

[vad]
aggressiveness = 2     # 0 permissive .. 3 strict
silence_ms = 700
max_segment_s = 15.0

[stt]
backend = "parakeet"   # parakeet | whisper
model = ""             # blank = the backend's default model
device = "auto"        # whisper only
language = ""          # blank = autodetect

[ui]
theme = "auto"         # auto follows your terminal; or gruvbox, nord, ...

[storage]
encrypt = "sync"       # "sync": plaintext here, ciphertext in the repo; "always": ciphertext on disk too
git_sync = false       # auto-commit sessions to a managed git repo
git_remote = ""        # push there after each session; implies git_sync

[diarize]
enabled = true
threshold = 0.30       # lower = fewer, broader speakers
margin = 0.10          # grey zone that attaches instead of opening a speaker
merge_threshold = 0.45 # two settled speakers this alike are one person
warmup = 3             # utterances before a speaker's centroid is trusted
new_speaker_min_s = 4.0 # shorter than this must be corroborated to open a speaker
max_speakers = 0       # 0 = no cap; same as --speakers N
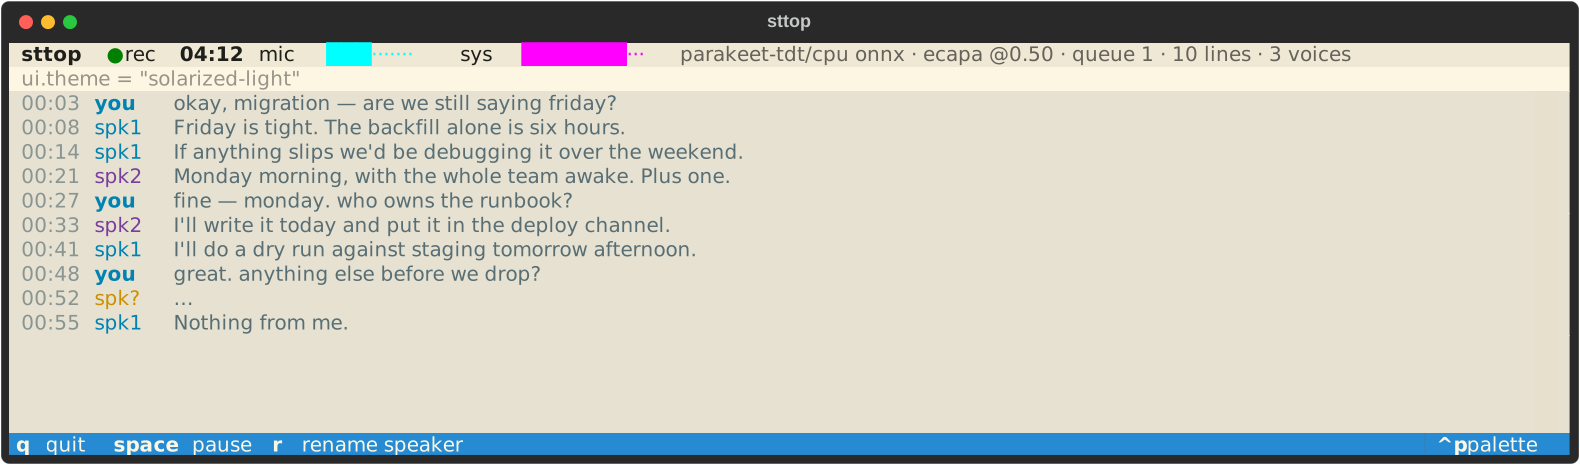
Theming
By default sttop paints with the ansi-dark / ansi-light Textual themes, which
use only the terminal's own 16 ANSI colours — so it inherits whatever palette you
already have rather than imposing its own. Which of the two is picked by reading
COLORFGBG, and failing that by asking the terminal for its background colour over
OSC 11 (supported by ghostty, kitty, alacritty, wezterm, foot, xterm). If nothing
answers, it assumes dark. Run sttop theme to see what was detected.
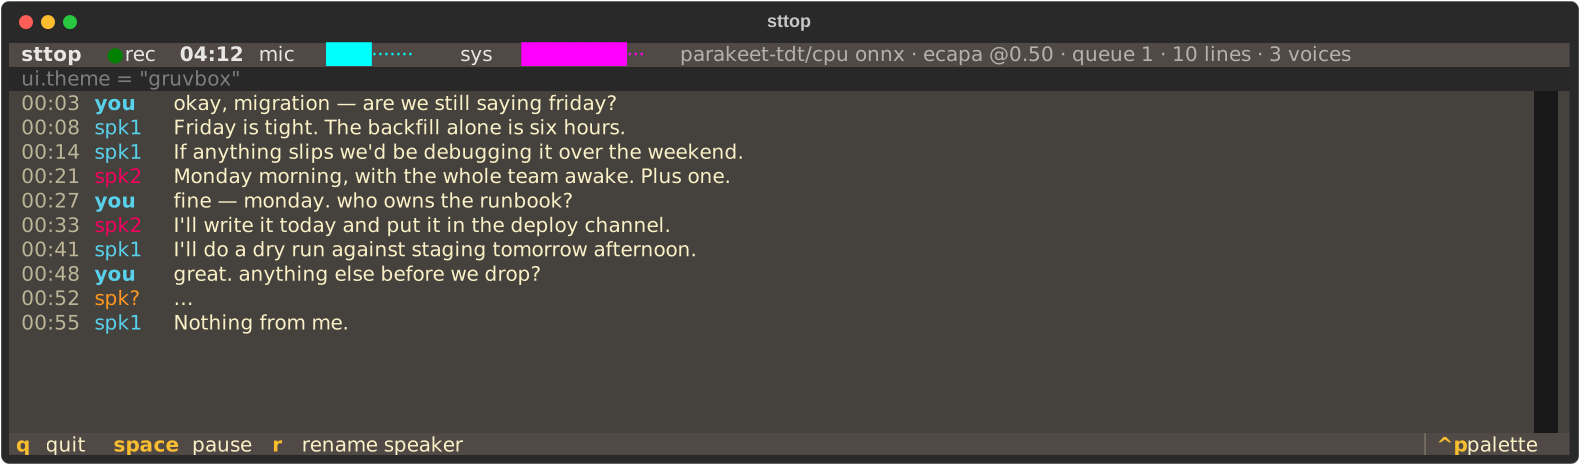
Set ui.theme to any Textual theme name (gruvbox, nord, catppuccin-mocha,
solarized-light, …) to override the terminal-following behaviour.
Tests
uv run --extra dev pytest
The audio-dependent path is exercised by tests/test_pipeline.py, which plays a speech
sample into the default sink and reads it back off the monitor. It needs real audio
hardware and downloads a model, so it is opt-in:
STTOP_INTEGRATION=1 uv run --extra dev pytest
Screenshots
The images above are rendered from the real widgets by
uv run --extra dev python scripts/screenshots.py
which drives sttop.tui with a scripted transcript instead of a live engine, so
docs/*.svg cannot drift from the UI it documents.
License
MIT
1 maintainer

Release files for sttop 0.8.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sttop-0.8.0.tar.gz | 206.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sttop-0.8.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 281.5 kB
Release files / sttop-0.8.0.tar.gz
| Download URL | sttop-0.8.0.tar.gz |
|---|---|
| Size | 206.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a17e3729b11076c56a8cd8e7cfbcd2ed0a2bd85f6bc0bf0fcfabe842beda790b
|
|
BLAKE2b-256 checksum How to use checksums |
7fd12a755546f5db8e064acd8cd4ea018b3ee0a82786c5abcea98e7ca8bb5021
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 14, 2026.
Transparency logRelease files / sttop-0.8.0-py3-none-any.whl
| Download URL | sttop-0.8.0-py3-none-any.whl |
|---|---|
| Size | 74.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b368a7143b8696a666a51a3c2a39f6c349501803f6a1eb7042a3435486466cfb
|
|
BLAKE2b-256 checksum How to use checksums |
e3b8e5bb5bce3b69af49643475d894a4f03917488963e7a0b793ec0f561b6872
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 14, 2026.
Transparency log













