
syntax-parser-prototype

spp provides a generic schema implementation for syntax parsers whose structure and behavior can be defined flexibly and complexly using derived objects.
spp also provides some advanced interfaces and parameterizations to meet complex syntax definition requirements.
pip install syntax-parser-prototype --upgrade
pip install syntax-parser-prototype[debug] --upgrade
Quick Start
The main entry points for the phrase configuration are the methods Phrase.starts and Phrase.ends.
Their return value tells the parser whether a phrase starts and, if so, where and in what context.
The structural logic of a syntax is realized by assigning phrases objects to other phrases objects as under phrases.
demos/quickstart/main.py (source)
# Represents a simplified method for parsing python syntax.
# The following paragraph is to be parsed:
#   foo = 42
#   baz = not f'{foo + 42 is foo} \' bar'

import keyword
import re

from src.syntax_parser_prototype import *
from src.syntax_parser_prototype.features.tokenize import *


# simple string definition
class StringPhrase(Phrase):
    id = "string"

    # token typing
    class NodeToken(NodeToken):
        id = "string-start-quotes"

    class Token(Token):
        id = "string-content"

    TDefaultToken = Token

    class EndToken(EndToken):
        id = "string-end-quotes"

    # backslash escape handling
    class MaskPhrase(Phrase):
        id = "mask"

        def starts(self, stream: Stream):
            if m := re.search("\\\\.", stream.unparsed):
                # baz = not f'{foo + 42 is foo} \' bar'
                #                               ↑ prevents closure
                return MaskToken(m.start(), m.end())
                # could also be implemented as a stand-alone token or
                # independent phrase if the pattern is to be tokenized separately
            else:
                return None

    PH_MASK = MaskPhrase()

    def __init__(self, *args, **kwargs):
        super().__init__(*args, **kwargs)
        # creates the logic during initialization
        self.add_subs(self.PH_MASK)

    def starts(self, stream: Stream):
        # searches for quotation marks and possible prefix and saves the quotation mark type
        # switches to a different phase configuration if the f-string pattern is found
        if m := re.search("(f?)(['\"])", stream.unparsed, re.IGNORECASE):
            # baz = not f'{foo + 42 is foo} \' bar'
            #           ↑
            if prefix := m.group(1):
                switchto = PH_FSTRING
            else:
                switchto = self
            return self.NodeToken(m.start(), m.end(), SwitchTo(switchto), quotes=m.group(2))
        else:
            return None

    def ends(self, stream: Stream):
        # searches for the saved quotation mark type
        if m := re.search(stream.node.extras.quotes, stream.unparsed):
            # baz = not f'{foo + 42 is foo} \' bar'
            #                                     ↑
            return self.EndToken(m.start(), m.end())
        else:
            return None


# modified string definition for f-string pattern
class FstringPhrase(StringPhrase):
    id = "fstring"

    # format content handling
    class FstringFormatContentPhrase(Phrase):
        id = "fstring-format-content"

        # token typing
        class NodeToken(NodeToken):
            id = "fstring-format-content-open"

        class EndToken(EndToken):
            id = "fstring-format-content-close"

        def starts(self, stream: Stream):
            if m := re.search("\\{", stream.unparsed):
                # baz = not f'{foo + 42 is foo} \' bar'
                #             ↑
                return self.NodeToken(m.start(), m.end())
            else:
                return None

        def ends(self, stream: Stream):
            # baz = not f'{foo + 42 is foo} \' bar'
            #                             ↑
            if m := re.search("}", stream.unparsed):
                return self.EndToken(m.start(), m.end())
            else:
                return None

    PH_FSTRING_FORMAT_CONTENT = FstringFormatContentPhrase()

    def __init__(self, *args, **kwargs):
        super().__init__(*args, **kwargs)
        # creates the logic during initialization
        self.add_subs(self.PH_FSTRING_FORMAT_CONTENT)


NUMBER42 = list()


# simple word definition
class WordPhrase(Phrase):
    id = "word"

    # token typing
    class KeywordToken(Token):
        id = "keyword"

    class VariableToken(Token):
        id = "variable"

    class NumberToken(Token):
        id = "number"

    class WordNode(NodeToken):
        id = "word"

        def atConfirmed(self) -> None:
            assert not self.inner

        def atFeaturized(self) -> None:
            # collect 42 during the parsing process
            if self.inner[0].content == "42":
                NUMBER42.append(self[0])

    def starts(self, stream: Stream):
        if m := re.search("\\w+", stream.unparsed):
            # foo = 42
            # ↑     ↑
            # baz = not f'{foo + 42 is foo} \' bar'
            # ↑     ↑      ↑     ↑  ↑  ↑
            return self.WordNode(
                m.start(),
                m.end(),
                # forwards the content to tokenize
                RTokenize(len(m.group()))
            )
            # could also be implemented as a stand-alone token,
            # but this way saves conditional queries if the token is not prioritized
        else:
            return None

    def tokenize(self, stream: TokenizeStream):
        token = stream.eat_remain()
        if token in keyword.kwlist:
            # baz = not f'{foo + 42 is foo} \' bar'
            #       ↑               ↑
            return self.KeywordToken
        elif re.match("^\\d+$", token):
            # foo = 42
            #       ↑
            # baz = not f'{foo + 42 is foo} \' bar'
            #                    ↑
            return self.NumberToken
        else:
            # foo = 42
            # ↑
            # baz = not f'{foo + 42 is foo} \' bar'
            # ↑            ↑           ↑
            return self.VariableToken

    def ends(self, stream: Stream):
        # end the phrase immediately without content after the start process
        # foo = 42
        #    ↑    ↑
        # baz = not f'{foo + 42 is foo} \' bar'
        #    ↑     ↑      ↑    ↑  ↑   ↑
        return super().ends(stream)  # return InstantEndToken()


MAIN = Root()
PH_STRING = StringPhrase()
PH_FSTRING = FstringPhrase()
PH_WORD = WordPhrase()

# MAIN SETUP
#  - configure the logic at the top level
MAIN.add_subs(PH_STRING, PH_WORD)
#  - recursive reference to the logic of the top level
PH_FSTRING.PH_FSTRING_FORMAT_CONTENT.add_subs(MAIN.__sub_phrases__)

if __name__ == "__main__":
    from demos.quickstart import template

    with open(template.__file__) as f:
        # foo = 42
        # baz = not f'{foo + 42 is foo} \' bar'
        #
        content = f.read()

    # parse the content
    result = MAIN.parse_string(content)

    if PROCESS_RESULT := True:
        # some result processing
        assert content == result.tokenReader.branch.content
        token = result.tokenIndex.get_token_at_coord(1, 19)
        assert token.content == "42"
        assert token.column_end == 21
        assert token.data_end == 30
        assert token.node.phrase.id == "word"
        assert token.next.next.next.next.content == "is"
        assert token.node.node[0].tokenReader.inner.content == "foo"

        assert isinstance(result, NodeToken)
        for inner_token in result:
            if isinstance(inner_token, NodeToken):
                assert isinstance(inner_token.inner, list)
                assert isinstance(inner_token.end, EndToken)
            else:
                assert not hasattr(inner_token, "inner")
        assert isinstance(result.end, EndToken) and isinstance(result.end, EOF)

        assert len(NUMBER42) == 2

    if DEBUG := True:
        # visualisation
        print(*(f"std.  repr: {t} {t!r}" for t in NUMBER42), sep="\n")

        from src.syntax_parser_prototype import debug

        print(*(f"debug repr: {t} {t!r}" for t in NUMBER42), sep="\n")

        debug.html_server.token_css[WordPhrase.KeywordToken] = "font-weight: bold;"
        debug.html_server.token_css[WordPhrase.NumberToken] = "color: blue; border-bottom: 1px dotted blue;"
        debug.html_server.token_css[StringPhrase.NodeToken] = "color: green;"
        debug.html_server.token_css[StringPhrase.Token] = "color: green;"
        debug.html_server.token_css[StringPhrase.EndToken] = "color: green;"
        debug.html_server.token_css[FstringPhrase.FstringFormatContentPhrase.NodeToken] = "color: orange;"
        debug.html_server.token_css[FstringPhrase.FstringFormatContentPhrase.EndToken] = "color: orange;"

        debug.html_server(result)
Concept
General
Configuration Overview
The basic parser behavior is defined by
- the structure definition in the form of assignments of phrases to phrases as sub- or suffix phrases
and assignments of root subphrases to
Root; - the return values of
Phrase.starts()andPhrase.ends().
Advanced Features
Phrase.tokenize()(hook)[...]Token.atConfirmed()(hook)[...]Token.atFeaturized()(hook)[...]Token(..., features: LStrip | RTokenize | SwitchTo | SwitchPh | ForwardTo)(advanced behavior control)
Parser Behavior
The entries for starting the parsing process are Root.parse_rows() and Root.parse_string(),
which return a RootNode object as the result.
The parser processes entered data row1 by row:
The more detailed definition of a row can be left to the user (
Root.parse_rows()). The line break characters are NOT automatically interpreted at the end of a row and must therefore be included in the transferred data.In
Root.parse_string(), lines are defined by line break characters by default.
Phrases Start and End Values
Within a process iteration, starts() of sub-phrases and the ends() of the currently active phrase are queried
for the unparsed part of the current row1 (defined from viewpoint (a cursor) to the end of the row1).
The methods must return a token object that matches the context as a positive value (otherwise None).
- Valid node tokens from
Phrase.starts()are:NodeTokenMaskNodeTokenInstantNodeToken
- Valid standalone2 tokens from
Phrase.starts()are:TokenInstandTokenMaskToken
Standalone tokens are token types that do not trigger a phrase change and are assigned directly to the parent phrase.
- Valid end tokens from
Phrase.ends()are:EndTokenInstandEndToken
Token Priority
The order in which phrases are assigned as sub-phrases is irrelevant;
the internal order in which the methods of several sub-phrases are queried is random
and in most cases is executed across the board for all potential sub-phrases.
Therefore - and to differentiate from EndToken's - positive return values (tokens) must be
differentiated to find the one that should actually be processed next.
The project talks about token priority3:
InstandToken's have the highest priority. These would- as
InstandEndTokenfromPhrase.ends()prevent the search for starts and close the phrase immediately at the defined point. - as
InstandNodeTokenorInstandTokenas a standalone2 Token fromPhrase.starts(), immediately interrupt the search for further starts and process this token directly.
- as
- Tokens with the smallest
atparameter (the start position relative to the viewpoint of the stream) have the second-highest priority. - The third-highest priority is given to so-called null tokens4.
Null tokens are tokens for which no content is defined. null tokens that are returned for the position directly at the viewpoint (
at=0) are only permitted asEndTokens, as otherwise the parser might get stuck in an infinite loop. An exception to this is the extended feature configuration withForwardTo, where only one of the tokens has to advance the stream. - Finally, the Token with the longest content has the highest priority.
Value Domains and Tokenization
The domain of values within a phrase defined by starts() and ends() is referred to as a branch and can be nested
by sub- or suffix phrases. The domain at phrase level is then separated by the NodeToken's of these phrases.
By default, the parser parses this domain row1 by row1 as single tokens. The Phrase.tokenize() hook is
available for selective token typing.
Therefore, before processing a Node, End or standalone2 Token or at the end of a row1,
the remaining content is automatically assigned to the (still) active node/phrase.
Token Types
Control Tokens
Control tokens are returned as positive values of the configured phrase methods
for controlling the parser and — except the Mask[Node]Token's — are present in the result.
In general, all tokens must be configured with the definition of at <int> and to <int>.
These values tell the parser in which area of the currently unparsed row1 part the content for
the token is located.
Except the Mask[Node]Token's, all control tokens can be equipped with extended
features that can significantly influence the parsing process.
In addition, free keyword parameters can be transferred to [...]NodeToken's,
which are assigned to the extras attribute in the node.
class Token
(standard type) Simple text content token and base type for all other tokens.
Tokens of this type must be returned by Phrase.tokenize
or can represent a standalone2 token via Phrase.starts.
These are stored as a value in the inner attribute of the parent node.
class NodeToken(Token)
(standard type) Represents the beginning of a phrase as a token and contains subordinate tokens and the end token.
Phrase.starts() must return tokens of this type when a complex phrase starts.
These are stored as a value in the inner attribute of the parent node.
class EndToken(Token)
(standard type) Represents the end of a phrase.
Phrase.ends() must return tokens of this type when a complex phrase ends.
These are stored as a value as the end attribute of the parent node.
class MaskToken(Token)
(special type) Special standalone2 token type that can be returned by Phrase.starts().
Instead of the start of this phrase, the content is then assigned to the parent node. This token type will never be present in the result.
Note: If Phrase.start() returns a MaskToken, sub-/suffix-phrases of this Phrase are NOT evaluated.
class MaskNodeToken(MaskToken, NodeToken)
(special type) Special node token type that can be returned by Phrase.starts().
Starts a masking phrase whose content is assigned to the parent node. This token type will never be present in the result.
Note: If Phrase.start() returns a MaskToken, sub-/suffix-phrases of this Phrase are NOT evaluated.
class InstantToken(Token)
(special type) Special standalone2 token type that can be returned by Phrase.starts().
Prevents comparison of priority3 with other tokens and accepts the token directly.
class InstantEndToken(InstantToken, EndToken)
(special type) Special end token type that can be returned by Phrase.ends().
Prevents comparison of priority3 with other tokens and accepts the token directly.
class InstantNodeToken(InstantToken, NodeToken)
(special type) Special node token type that can be returned by Phrase.starts().
Prevents comparison of priority3 with other tokens and accepts the token directly.
Internal Token Types
Internal token types are automatically assigned during the process.
class OpenEndToken(Token)
Represents the non-end of a phrase.
This type is set to NodeToken.end by default until an EndToken replaces it
or remains in the result if none was found until the end.
Acts as an interface to the last seen token of the phrase for duck typing.
class RootNode(NodeToken)
Represents the root of the parsed input and contains all other tokens (has no content but is a valid token to represent the result root).
class OToken(Token)
Represents an inner token for the root phrase when no user-defined phrase is active.
class OEOF(OpenEndToken)
Represents the non-end of the parsed input, set to RootNode.end.
This type is set by default until the EOF replaces it at the end of the process
(will never be included in the result).
class EOF(EndToken)
Represents the end of the parsed input, set to RootNode.end
(has no content but is a valid token to be included in the result).
Visualization Tools
The debug module (source) provides some support for visualization. All necessary packages can be installed separately:
pip install syntax-parser-prototype[debug] --upgrade
Overview
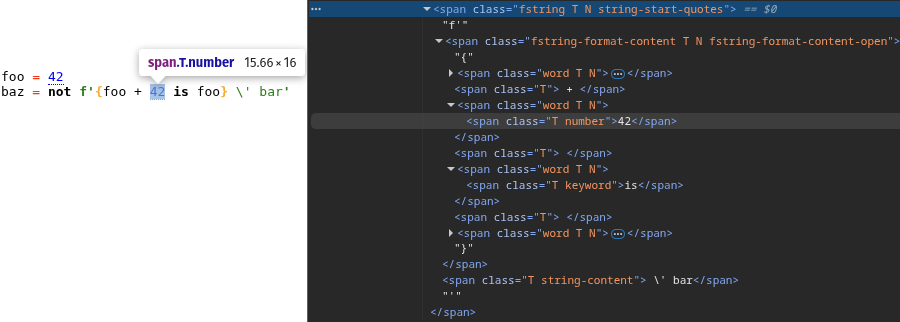
HTML Server
from src.syntax_parser_prototype import debug
debug.html_server(result)
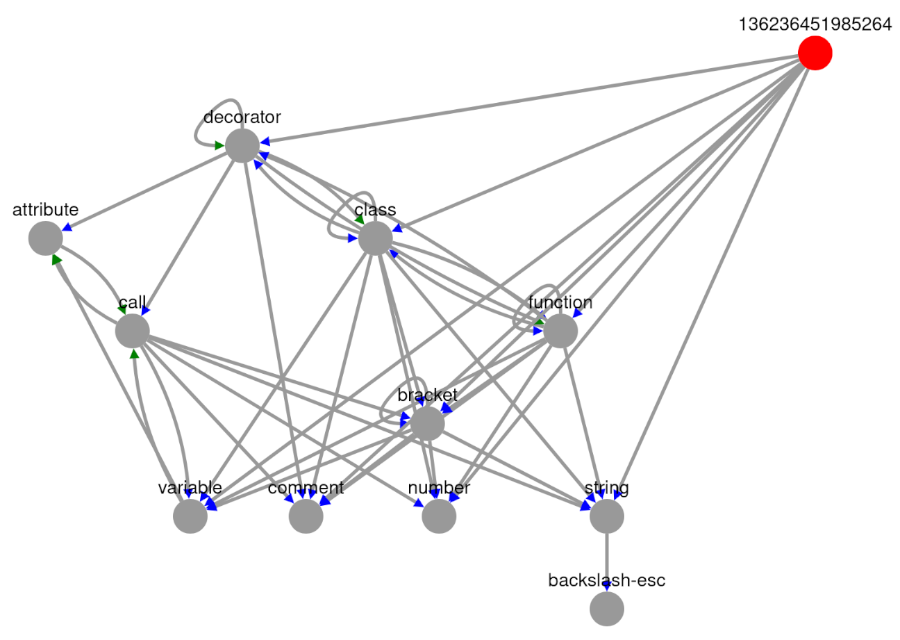
Structure Graph App
from src.syntax_parser_prototype import debug
debug.structure_graph_app(MAIN)
Pretty XML
from src.syntax_parser_prototype import debug
print(debug.pretty_xml(result))
<?xml version="1.0" ?>
<R phrase="130192620364736" coord="0 0:0">
	<word phrase="word" coord="0 0:0">
		<variable coord="0 0:3">foo</variable>
		<iE coord="0 3:3"/>
	</word>
	<o coord="0 3:6"> = </o>
	<word phrase="word" coord="0 6:6">
		<number coord="0 6:8">42</number>
		<iE coord="0 8:8"/>
	</word>
	<o coord="0 8:9">
</o>
	<word phrase="word" coord="1 0:0">
		<variable coord="1 0:3">baz</variable>
		<iE coord="1 3:3"/>
	</word>
	<o coord="1 3:6"> = </o>
	<word phrase="word" coord="1 6:6">
		<keyword coord="1 6:9">not</keyword>
		<iE coord="1 9:9"/>
	</word>
	<o coord="1 9:10"> </o>
	<string-start-quotes phrase="fstring" coord="1 10:12">
		f'
		<fstring-format-content-open phrase="fstring-format-content" coord="1 12:13">
			{
			<word phrase="word" coord="1 13:13">
				<variable coord="1 13:16">foo</variable>
				<iE coord="1 16:16"/>
			</word>
			<T coord="1 16:19"> + </T>
			<word phrase="word" coord="1 19:19">
				<number coord="1 19:21">42</number>
				<iE coord="1 21:21"/>
			</word>
			<T coord="1 21:22"> </T>
			<word phrase="word" coord="1 22:22">
				<keyword coord="1 22:24">is</keyword>
				<iE coord="1 24:24"/>
			</word>
			<T coord="1 24:25"> </T>
			<word phrase="word" coord="1 25:25">
				<variable coord="1 25:28">foo</variable>
				<iE coord="1 28:28"/>
			</word>
			<fstring-format-content-close coord="1 28:29">}</fstring-format-content-close>
		</fstring-format-content-open>
		<string-content coord="1 32:39"> \' bar</string-content>
		<string-end-quotes coord="1 36:37">'</string-end-quotes>
	</string-start-quotes>
	<o coord="1 37:38">
</o>
	<EOF coord="1 38:38"/>
</R>
Change Log
3.0 — major release
-
added
nodeshortcut inTokenizeStream -
added less restrictive type hints in
PhraseandRootgenerics -
added support for
PhraseandNodetype hints forStream's andToken's viaGeneric[TV_PHRASE, TV_NODE_TOKEN]to ensure stronger type binding between phrase implementations and token/node types(Application example in a
Phrase.startsmethod definition:def starts(self, stream: streams.Stream[MyPhrase, MyNode1 | MyNode2]): stream.node.my_attribute stream.node.phrase.my_attribute ...
-
fixed
OpenEndTokeninterface -
added/fixed unpacking in
Phrase.add_suffixes()
3.0a3 — fix type hint
- 3.0a3 fixes a type hint error in
Phrase.tokenize()
3.0a2 — security update
- 3.0a2 closes a gap in the protection against infinite loops
With the configuration of the extended feature
ForwardToto anEndToken, the parser would not have recognized if it did not advance.
3.0a1 — initial pre-release
- Version 3 differs fundamentally from its predecessors
-
A row is not necessarily a line as it is generally understood. ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7
-
Standalone tokens are token types that do not trigger a phrase change and are assigned directly to the parent phrase. ↩ ↩2 ↩3 ↩4 ↩5 ↩6
-
InstandEndToken<InstandNodeToken<InstandToken< smallestat< Null tokens < longestcontent↩ ↩2 ↩3 ↩4 -
Null tokens are tokens for which no content is defined. Null tokens that are returned for the position directly at the viewpoint (
at=0) are only permitted asEndTokens. ↩
1 maintainer

Metadata
1 maintainer
Release files for syntax-parser-prototype 3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| syntax_parser_prototype-3.0.tar.gz | 36.0 kB | Without provenance | Details for syntax_parser_prototype-3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| syntax_parser_prototype-3.0-py3-none-any.whl | Python 3 | none | any | Details for syntax_parser_prototype-3.0-py3-none-any.whl |
Total release size: 69.8 kB
Release files / syntax_parser_prototype-3.0.tar.gz
| Download URL | syntax_parser_prototype-3.0.tar.gz |
|---|---|
| Size | 36.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
484b91a97a1923c3aa67d4f644f14509488b74ff8c279a46fd29a2d4a3fb194d
|
|
BLAKE2b-256 checksum How to use checksums |
5e152d5b0bd7dc53568afc08c1ddb674d4b23162f054124d56c305382d58c97f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.13.8
|
Release files / syntax_parser_prototype-3.0-py3-none-any.whl
| Download URL | syntax_parser_prototype-3.0-py3-none-any.whl |
|---|---|
| Size | 33.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
49088a704d5d242ddf13176df67a137d57bd37579461981746814635129d91dd
|
|
BLAKE2b-256 checksum How to use checksums |
e212a99c2b3806f468c0924ebfea9413aef7b18673fe0dd7bede17c1b58ba9ba
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.13.8
|
Security for syntax-parser-prototype 3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














