
tabaudit
Find the problems in your dataset before your model does.
tabaudit is a command-line tool that audits a tabular ML dataset for the defects that
quietly inflate metrics and break models in production — target leakage, train/test
contamination, duplicates, label noise, class imbalance and schema problems — and gives it
a single Data Health Score with concrete, prioritised fixes.
pip install tabaudit
tabaudit audit train.csv --target churn --test test.csv --html report.html
Why
A model that scores 99% on a leaked dataset is worse than useless: it looks finished and
fails silently in production. Most of these defects take one line of pandas to fix — the
hard part is noticing them. tabaudit makes the check automatic, fast, and repeatable
(it runs in CI with --fail-under / --fail-on).
What it checks
| check | finds | severity |
|---|---|---|
leakage |
single features that predict the target almost perfectly on their own (incl. missingness leaks), identifier columns, columns named after the target | CRITICAL / HIGH / MEDIUM |
duplicates |
exact duplicate rows, feature-identical rows with conflicting labels, test rows that also appear in train | CRITICAL → LOW |
label_noise |
probably-mislabeled rows from an out-of-fold model's self-confidence, thresholds calibrated by fault injection, ranked and tiered | HIGH → INFO |
imbalance |
class ratio, classes with < 10 examples | HIGH → LOW |
schema |
≥ 50 % missing columns, missing labels, constant / near-constant columns, numbers stored as text, leftover index columns | HIGH → INFO |
Every finding carries a plain-English explanation of why it matters and what to do. Findings are weighted into a 0–100 score and an A–F grade.
Quick start
pip install tabaudit

# See every check fire on a synthetic dataset with planted defects
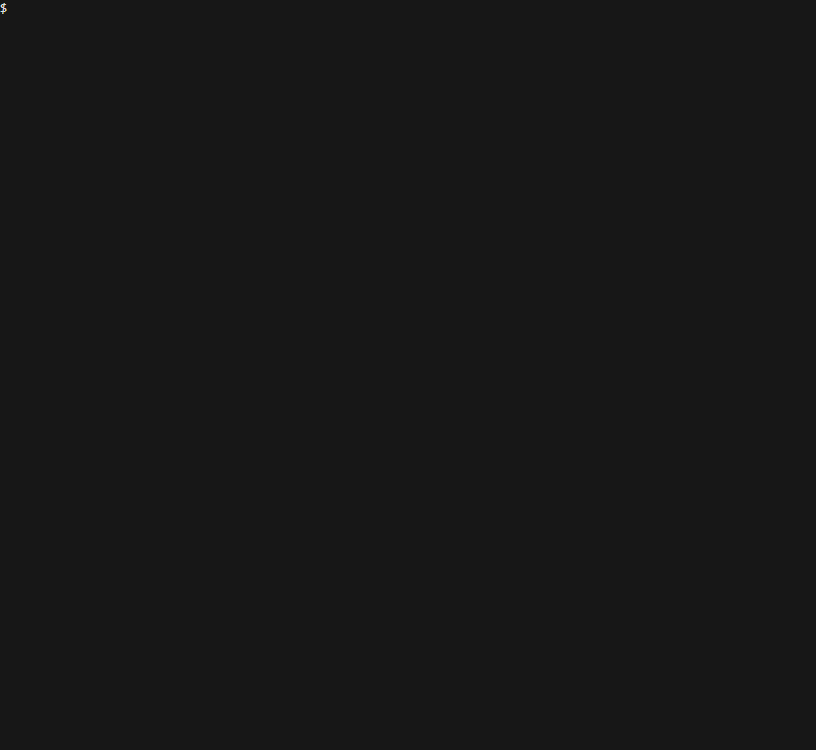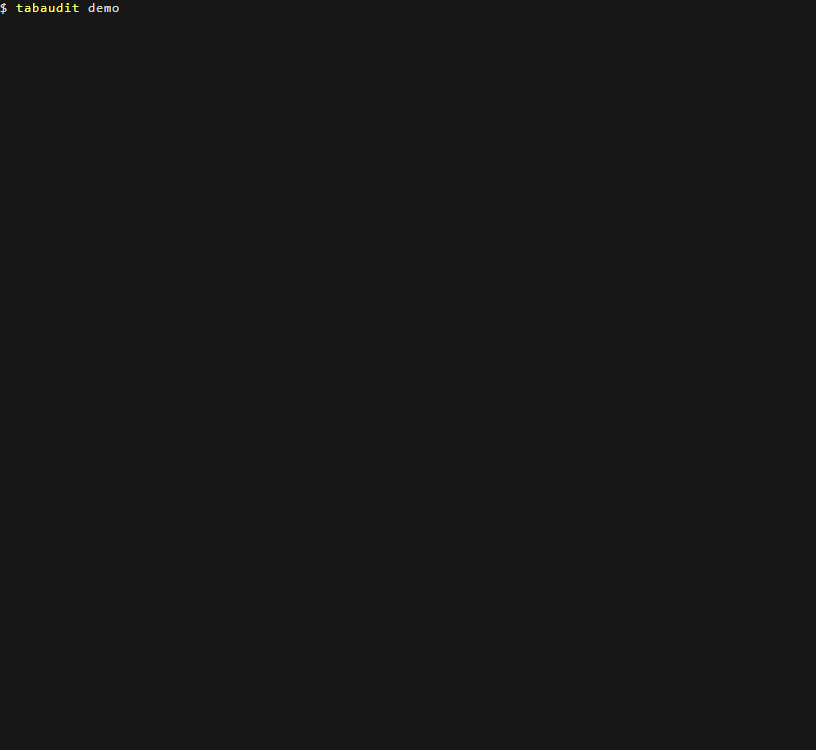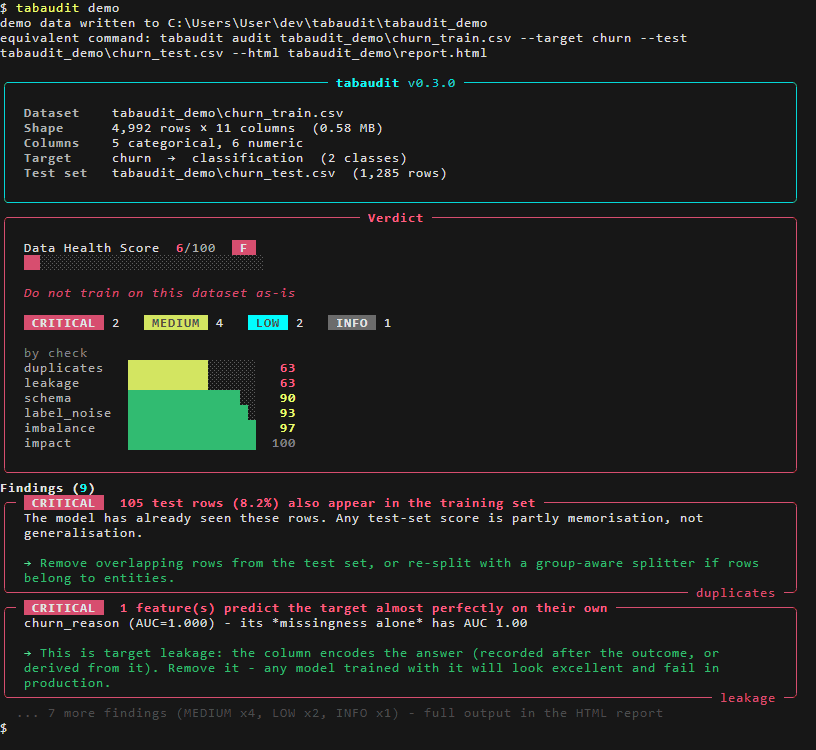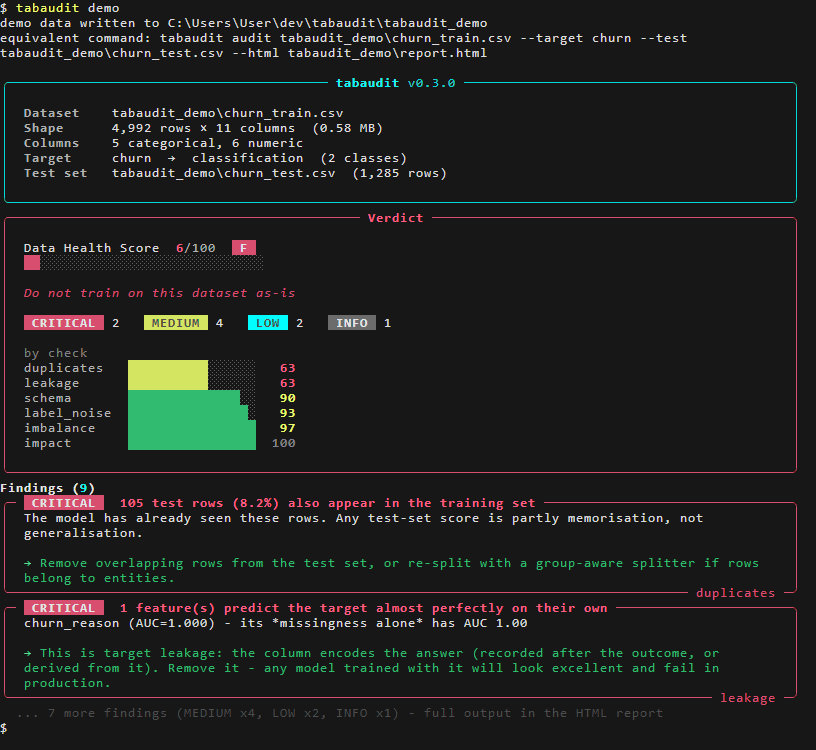
tabaudit demo

# Audit your own data
tabaudit audit data.csv --target label
tabaudit audit train.parquet -t label --test test.parquet --html report.html --json report.json

# Only some checks, sampled for speed, gate a CI pipeline:
# exit 1 if the score is under 75 OR any finding is HIGH/CRITICAL
tabaudit audit data.csv -t label -c leakage,duplicates --max-rows 20000 --fail-under 75 --fail-on high
Supported inputs: CSV, TSV, Parquet, Feather, JSON-lines. Classification and regression
targets are inferred automatically; omit --target to run only the unsupervised checks.
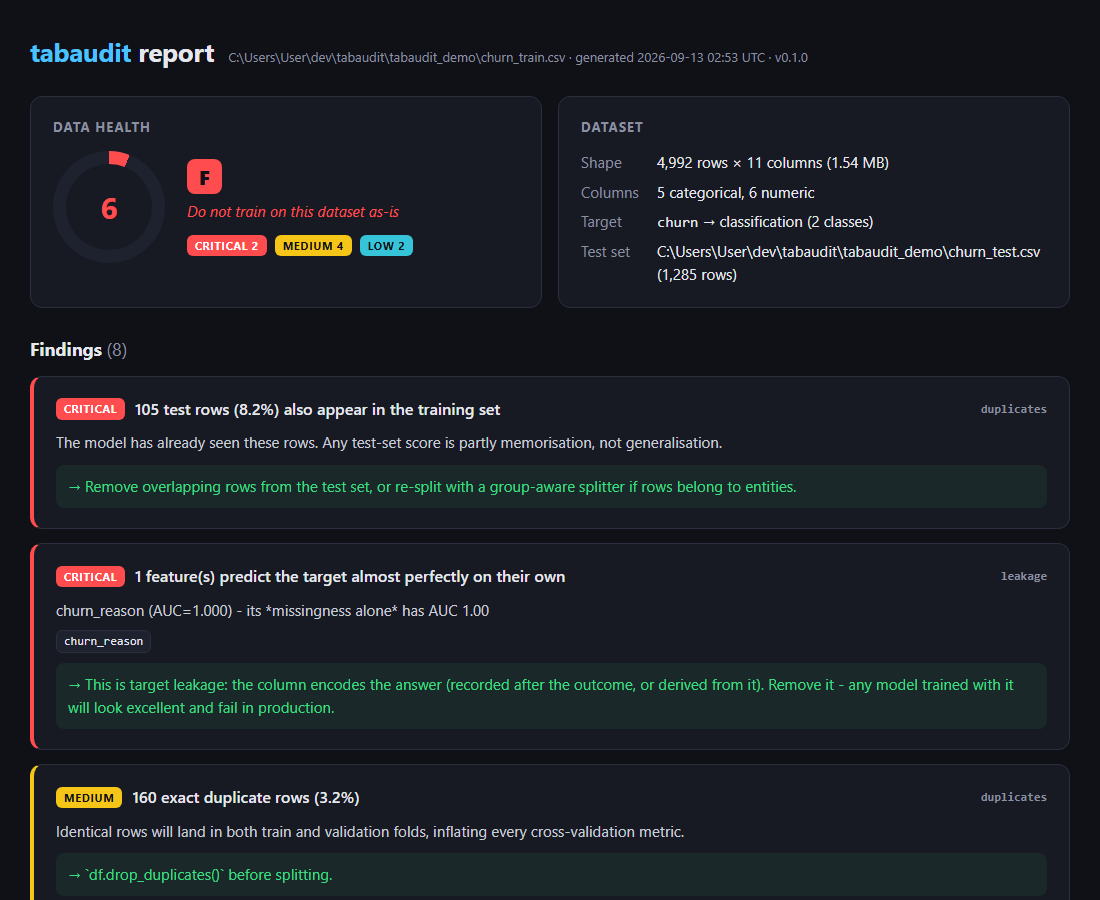
--html writes a self-contained report you can send to whoever owns the data:
Python API
from tabaudit import run_audit

report = run_audit("train.csv", target="churn", test="test.csv")
print(report.score, report.grade)          # 6 'F'
for f in report.sorted_findings():
    print(f.severity.value, f.title, f.columns)
report.to_dict()                            # JSON-serialisable
Example output
┌────────────────────────────────── Verdict ──────────────────────────────────┐
│  Data Health Score  6/100   F                                               │
│  ██░░░░░░░░░░░░░░░░░░░░░░░░░░░░                                             │
│  Do not train on this dataset as-is                                         │
│   CRITICAL  2    MEDIUM  4    LOW  2                                        │
└─────────────────────────────────────────────────────────────────────────────┘
┌─  CRITICAL   105 test rows (8.2%) also appear in the training set ──────────┐
│  The model has already seen these rows. Any test-set score is partly        │
│  memorisation, not generalisation.                                          │
│  → Remove overlapping rows from the test set, or re-split with a            │
│  group-aware splitter if rows belong to entities.                           │
└──────────────────────────────────────────────────────────────── duplicates ─┘
┌─  CRITICAL   1 feature(s) predict the target almost perfectly on their own ─┐
│  churn_reason (AUC=1.000) - its *missingness alone* has AUC 1.00            │
│  → This is target leakage: the column encodes the answer (recorded after    │
│  the outcome, or derived from it). Remove it - any model trained with it    │
│  will look excellent and fail in production.                                │
└─────────────────────────────────────────────────────────────────── leakage ─┘
Results on real datasets
Ten well-known public datasets, loaded straight from OpenML and audited with default
settings — no tuning, no column dropping. Full write-up, including what the tool got
wrong on the first run and how it was fixed: docs/benchmarks.md.
| dataset | rows | score | headline finding |
|---|---|---|---|
| titanic | 1 309 | 64 C | HIGH boat predicts survival alone (AUC 0.97 vs next-best 0.74) — target leakage |
| spambase | 4 601 | 75 B | HIGH 391 exact duplicate rows (8.5 %) |
| creditcard | 284 807 | 78 B | HIGH 578 : 1 class imbalance; 9 144 duplicate rows |
| telco-customer-churn | 7 043 | 80 B | TotalCharges is numeric but stored as text; 18 conflicting-label groups |
| breast-w | 699 | 82 B | HIGH 236 exact duplicate rows (34 %) |
| bank-marketing | 45 211 | 83 B | duration stands far above every other feature (AUC 0.81 vs 0.65) — a documented leak |
| adult | 48 842 | 84 B | 5 groups of rows with identical features but different labels |
| credit-g | 1 000 | 93 A | ~6 % of rows likely mislabeled |
| heart-statlog | 270 | 93 A | ~6 % of rows likely mislabeled |
| diabetes | 768 | 93 A | ~5 % of rows likely mislabeled |
- 4 of 10 have a CRITICAL/HIGH finding; 10 of 10 have at least one MEDIUM. Every HIGH is a documented property of the dataset (Titanic's lifeboat column, spambase and breast-w duplicates, creditcard's 0.17 % fraud rate).
- The leakage check catches both the near-perfect leak (
boat) and the soft one (bank-marketingduration, which the dataset's own documentation says to drop), while correctly reporting breast-w's six strong-but-honest features as "easy task", not leakage. - Label-noise suspects were checked by hand on two datasets: of the 10 top-ranked rows, 5 look genuinely mislabeled, 5 are ambiguous, 0 look like false alarms (review sheet).
Reproduce with python benchmarks/run_benchmarks.py (~6 min, downloads ~50 MB).
Use it as a gate
tabaudit gate audits one or more files and prints a pass/fail line each; exit code 1 if
any file fails, so it plugs into anything that reads exit codes.
GitHub Actions — one step, pinned to a release tag:
- uses: sadiasamia121912/tabaudit@v0.2.0
  with:
    data: data/*.csv        # one or more files / globs
    target: label           # omit for unsupervised checks only
    fail-on: high           # any HIGH or CRITICAL finding fails the job
    fail-under: 75          # optional score bar (0-100)
pre-commit — every data file you commit gets audited:
- repo: https://github.com/sadiasamia121912/tabaudit
  rev: v0.2.0
  hooks:
    - id: tabaudit
      args: ["--target", "label", "--fail-on", "high"]
      files: ^data/.*\.csv$
Anything else — tabaudit gate data/*.csv -t label --fail-on high --fail-under 75.
Use --fail-on none to gate on the score alone.
How well does it detect things?
Finding real problems is one thing; knowing what the tool misses is another. So faults were planted in the same ten datasets — 5 % duplicate rows, 3 % random label flips, a noisy copy of the target, a column filled in only for one class — with known locations, and the audit was scored against them (3 seeds each, 120 runs, ~3 min):
| check | planted fault | result |
|---|---|---|
| duplicates | 5 % exact copies | found 30 / 30, precision 1.00 |
| leakage | target copy + noise | detected 30 / 30, 0 innocent columns accused |
| leakage | column present only for one class | detected 30 / 30, 0 innocent columns accused |
| label noise ("likely") | 3 % random flips | precision 0.80 (excluding the dataset's own pre-existing noise), recall 0.64 |
The first run of this harness found a blind spot (leaks confined to a class smaller than
the tree's leaf size — creditcard's 36 fraud rows) and showed that the cleanlab filter used
in v0.1.0 added nothing over the model's own self-confidence; both were fixed, and the ten
real-data scores did not change. What these numbers do and do not show — random flips are
an upper bound on real recall — is spelled out in
docs/evaluation.md.
Reproduce with python benchmarks/evaluate.py.
How it compares
Measured 2026-09-15 on a laptop, adult (48 842 rows × 15 columns) loaded from CSV, each
tool at its defaults, best of 2–3 runs. "Adds" = install size on top of the
numpy + pandas + scikit-learn stack (314 MB) that all four need.
| tabaudit | ydata-profiling 4.18 | deepchecks 0.19 | cleanlab 2.9 | |
|---|---|---|---|---|
| what it is | dataset auditor, CLI-first | EDA report generator | ML validation suites (data, train/test, model) | label-quality library |
| target leakage (single feature) | ✅ AUC/R² + missingness, gap rule | ❌ | ✅ feature–label PPS | ❌ |
| train/test overlap | ✅ | ❌ | ✅ TrainTestSamplesMix |
❌ |
| exact duplicates | ✅ | ✅ | ✅ | ✅ (+ near-duplicates) |
| conflicting labels | ✅ | ❌ | ✅ | ❌ |
| class imbalance | ✅ target-aware | ⚠️ per-column alerts | ✅ | ✅ |
| label noise (per-row suspects) | ✅ out-of-fold self-confidence | ❌ | ❌ | ✅ confident learning, you supply the probabilities |
| schema: missing / constant / numeric-as-text | ✅ | ✅ | ✅ | ⚠️ nulls only |
| drift, outliers, model evaluation | ❌ | ❌ | ✅ | ✅ outliers |
| one overall score | ✅ 0–100 + grade | ❌ | ❌ per-check pass/fail | ❌ per-issue-type scores |
| CI gate out of the box | ✅ --fail-on / --fail-under, Action, pre-commit |
❌ | ⚠️ via conditions + your code | ❌ |
| needs a model / probabilities from you | ❌ | ❌ | ❌ | ✅ for label issues |
| measured detection quality published | ✅ docs/evaluation.md |
❌ | ❌ | ✅ papers |
| adds to install | 14 MB | 338 MB | 176 MB | 2 MB (124 MB with [datalab]) |
time on adult |
9.8 s (all 5 checks) | 18.8 s (default report), 8.1 s (minimal) |
7.9 s (data_integrity, 12 checks) |
10.0 s (label issues; 99 s with features for near-duplicates/outliers) |
| worked with current numpy 2 / scikit-learn 1.9 / pandas 3 | ✅ | ⚠️ pins pandas<3 (downgraded it); project marked deprecated in favour of a successor |
❌ needed numpy<2 and scikit-learn<1.8 to import |
✅ |
Where tabaudit loses. deepchecks covers far more ground — drift, outliers, model evaluation, weak segments, date/index leakage — and has a mature suite/condition system; if you already have a model and a train/test split, it is the more complete tool. ydata-profiling is a much richer exploration report (distributions, correlations, interactions) and is the right thing for the first look at unfamiliar data. cleanlab's label-issue detection is more general (multi-class, near-duplicates, outliers, images, text) and comes with a decade of research behind it; tabaudit's own evaluation found that on tabular binary targets its filter added nothing over self-confidence, which says more about that setting than about cleanlab. tabaudit is the small, opinionated one: five checks, one number, an exit code, and a published measurement of what it misses.
How the hard checks work
Short version. Every threshold, and the reason for it, is in docs/checks.md.
Leakage. For each feature alone, a shallow decision tree is cross-validated against the target. A single column with out-of-fold AUC ≥ 0.98 (or R² ≥ 0.98 for regression) is almost never a legitimate signal — it is the answer written down after the fact. Below that, a leak has to be an outlier: the sorted single-feature scores are split at their largest gap, and only a feature that sits ≥ 0.15 above every other one is flagged (HIGH if it scores ≥ 0.90, MEDIUM "soft leak" if ≥ 0.75). Several strong features bunched together mean the task is easy, not leaky — that case is reported at INFO. Missing values are encoded so the tree can split on missingness itself, which catches the common "this field is only filled in for positives" leak.
Label noise. An out-of-fold gradient-boosting model produces class probabilities for
every row; a row is a suspect when the model gives its given label little probability.
The model is deliberately regularised so its own mistakes are not read as label errors.
Leaky and identifier columns found by the leakage check are excluded first — otherwise
the leak makes the model agree with every wrong label and the noise is invisible.
Suspects are reported in two tiers: likely (model gives the given label < 20 %
probability) and suspected (< 30 %), ranked most-confident first. The thresholds were
set by planting label flips in 10 public datasets and measuring precision/recall
(docs/checks.md); the same test showed cleanlab's confident-learning filter, used in
v0.1.0, added nothing over self-confidence, so it was removed.
Measured on known ground truth
The demo generator knows exactly which labels it flipped, so the detector can be scored
honestly (python examples/validate_label_noise.py <noise_rate>; 6 000 rows, clean-data
AUC ≈ 0.88):
| planted noise | flipped rows | "likely" flagged | likely precision / recall | top-25 precision |
|---|---|---|---|---|
| 2.2 % | 110 | 299 | 24 % / 66 % | 60 % |
| 6.4 % | 317 | 380 | 54 % / 65 % | 72 % |
| 10.3 % | 514 | 425 | 71 % / 59 % | 76 % |
Random label flips on rows the model is genuinely unsure about are indistinguishable from
correct labels, so no detector can reach high precision and recall here. The point is
the ranked review list, not the raw count — and the count is a useful estimate at realistic
noise rates. The same measurement on ten real datasets, with the dataset's own noise
accounted for, is in docs/checks.md (label noise) and docs/evaluation.md.
Development
git clone https://github.com/sadiasamia121912/tabaudit && cd tabaudit
python -m venv .venv && .venv/Scripts/activate      # or source .venv/bin/activate
pip install -e ".[dev]"
pytest
ruff check src tests examples && ruff format --check src tests examples
Adding a check: drop a module in src/tabaudit/checks/ exposing
run(ctx: AuditContext) -> list[Finding] and register it in checks/__init__.py.
Checks run in registry order and may communicate through ctx.excluded_features.
Roadmap
- Group / time leakage: entity IDs shared across splits, features that peek into the future
- Near-duplicate detection (fuzzy text, numeric tolerance)
- Label-noise support for regression targets
- Audit results for popular public benchmark datasets — see Results on real datasets
-
pre-commithook and GitHub Action — see Use it as a gate - Measured detection quality by fault injection — see How well does it detect things?
License
MIT
1 maintainer

Release files for tabaudit 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| tabaudit-0.2.0.tar.gz | 47.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tabaudit-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 85.8 kB
Release files / tabaudit-0.2.0.tar.gz
| Download URL | tabaudit-0.2.0.tar.gz |
|---|---|
| Size | 47.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b9481495d1cd637e2d756197f2683d52b92e7c2ceff173de7138b99a1b549c57
|
|
BLAKE2b-256 checksum How to use checksums |
0852b73a3e24abff7534633e217e52b7904c35e41a78e8a898deb807d5e52b6b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.3
|
Release files / tabaudit-0.2.0-py3-none-any.whl
| Download URL | tabaudit-0.2.0-py3-none-any.whl |
|---|---|
| Size | 38.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d1fd8706668dd105330921990e0ac92bc18a48f8f95da427a01df16e26911315
|
|
BLAKE2b-256 checksum How to use checksums |
f80bbb24d7fe52628da460a43ac5e5434ed95aff9305460537affa48206616b1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.3
|














