

ThinkBooster: A Unified Framework for Seamless Test-Time Scaling of LLM Reasoning


Quick Start | Key Features | Strategies | Visual Debugger | Documentation
ThinkBooster is an open-source framework for test-time compute scaling of large language models. It implements nine state-of-the-art scaling strategies — beam search, best-of-N, self-consistency, DeepConf, MUR, phi-decoding, and more — scored by process reward models (PRMs), uncertainty estimators, LLM-as-a-critic, and ReProbes. The framework includes an evaluation pipeline for math, science, and coding benchmarks, an OpenAI-compatible endpoint gateway, and an interactive visual debugger for inspecting strategy behavior step by step.
Key Features
- 9 scaling strategies — beam search, best-of-N, self-consistency, DeepConf, MUR, phi-decoding, extended thinking, uncertainty CoT, and adaptive scaling (online and offline)
- 4 scorer families — process reward models (PRMs), uncertainty/confidence scores, LLM-as-a-critic, and ReProbes; with configurable aggregation (min, mean, max, product) and sliding window
- OpenAI-compatible endpoint gateway — drop-in replacement for any OpenAI SDK; select strategy and scorer via URL path; enables "Pro reasoning mode" for any LLM deployment
- Visual debugger — interactive web UI for comparing strategies, inspecting step-by-step reasoning traces and confidence signals
- Evaluation pipeline — math (MATH-500, OlympiadBench, GaoKao, AIME), science (GPQA-Diamond), and coding (HumanEval+, MBPP+, KernelBench) with crash-resistant resume
Quick Start
Installation
pip install thinkbooster
Or install from source for development:
git clone https://github.com/IINemo/thinkbooster.git
cd thinkbooster
pip install -e ".[dev]"
Optional: additional scorers (UHead, KernelAct)
Some advanced scorers require GitHub-only dependencies. Run setup.sh after pip install:
./setup.sh
This installs llm-uncertainty-head, vllm-speculators, and KernelAct. Core functionality (all strategies, PRM/entropy/probability scorers, evaluation) works without these.
# Configure API keys (optional, for LLM judge and OpenRouter)
cp .env.example .env
Python API
# Strategies
from thinkbooster.strategies.strategy_baseline import StrategyBaseline
from thinkbooster.strategies.strategy_self_consistency import StrategySelfConsistency
from thinkbooster.strategies.strategy_beam_search import StrategyBeamSearch
from thinkbooster.strategies.strategy_offline_best_of_n import StrategyOfflineBestOfN

# Evaluation utilities
from thinkbooster.evaluation.grader import math_equal
from thinkbooster.evaluation.parser import extract_answer
REST API
git clone https://github.com/IINemo/thinkbooster.git
cd thinkbooster
pip install -e ".[service]"
python service_app/main.py   # starts on http://localhost:8001
Use with any OpenAI SDK:
from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:8001/v1/beam_search/prm",
    api_key="<YOUR_API_KEY>",
)
response = client.chat.completions.create(
    model="Qwen/Qwen3-30B-A3B",
    messages=[{"role": "user", "content":
        "Find the number of ordered pairs (x, y) of "
        "positive integers satisfying x + 2y = 2xy."}],
    extra_body={
        "max_tokens": 8192, "tts_beam_size": 4,
    },
)
print(response.choices[0].message.content)
The base_url encodes the scaling strategy and scorer (beam_search/prm). To switch strategy, just change the URL — no other code changes needed.
See Service API Guide for the full reference.
Run an Experiment
# Beam search on GSM8K (3 samples for quick verification)
python scripts/run_tts_eval.py \
  --config-name experiments/beam_search/gsm8k/window_all/mean/beam_search_vllm_qwen25_math_7b_instruct_gsm8k_prm \
  dataset.subset=3
Results are saved to outputs/ with full config snapshots for reproducibility. Add --resume to continue interrupted runs.
Visual Debugger
The interactive debugger lets you compare multiple TTS strategies side by side on the same problem. Inspect per-step decisions (escalate, stop, prune, select), view confidence and uncertainty signals, and drill into sampled candidates and tree expansions.
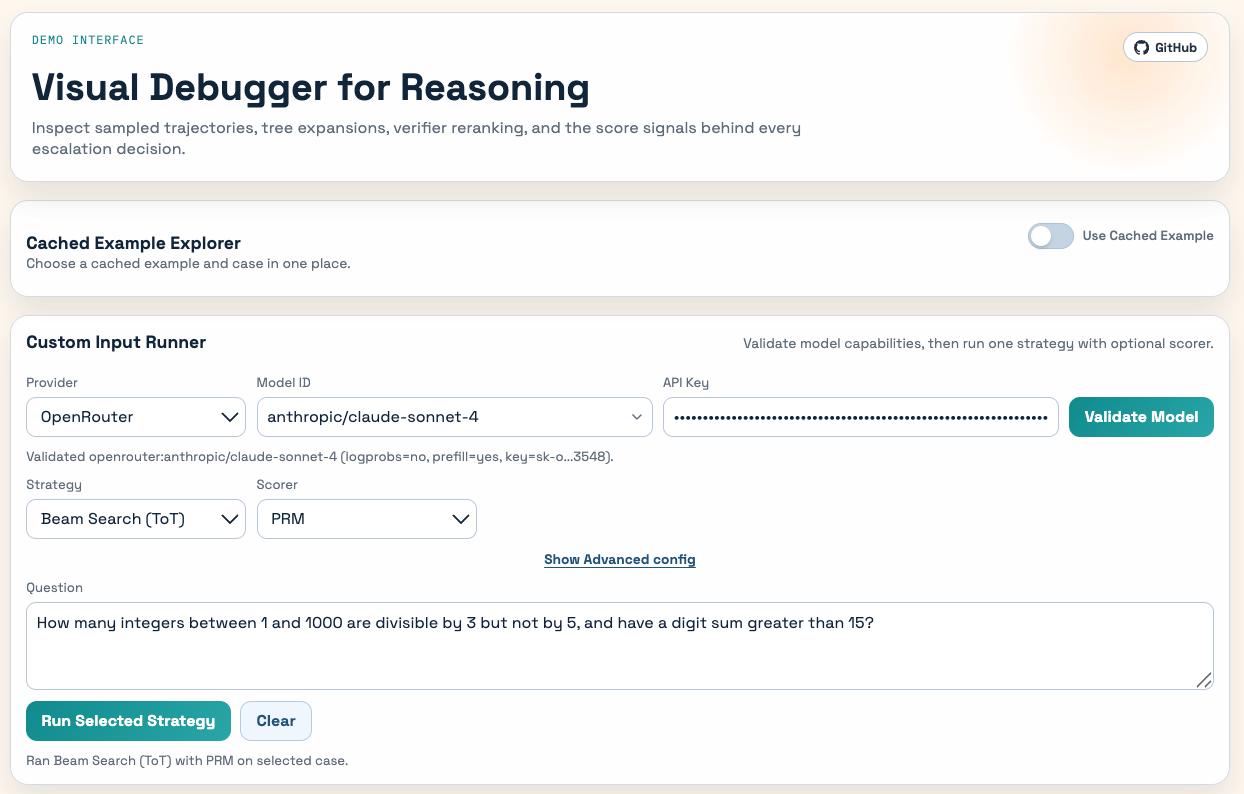 |
Main interface. Select a cached example or enter a custom math/science/coding problem. Choose any strategy (beam search, best-of-N, MUR, …) and scorer (PRM, uncertainty, LLM-as-a-critic) and run it directly from the browser. |
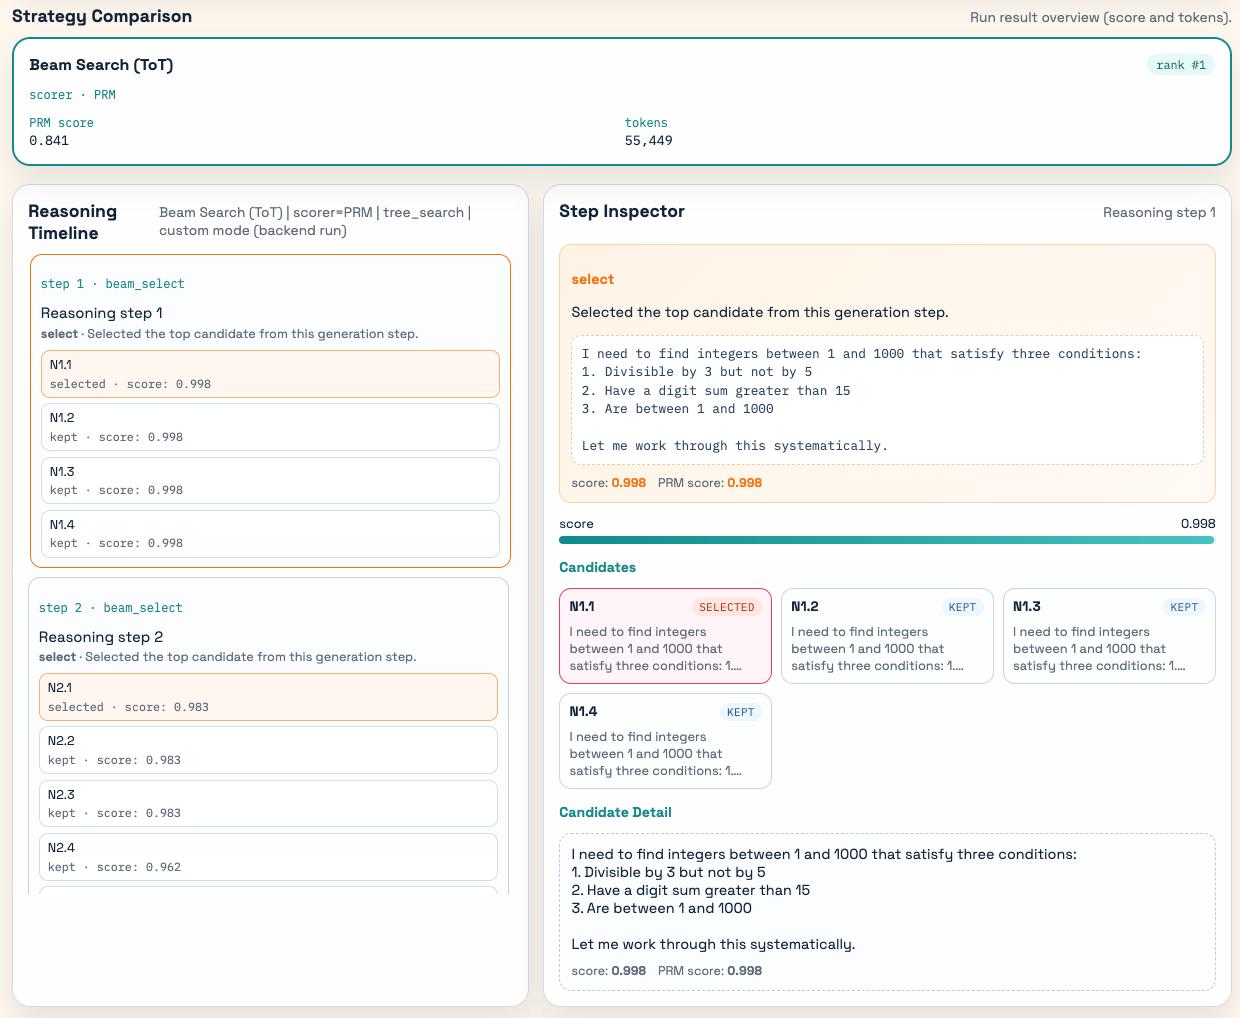 |
Step inspector. Replay the strategy execution step by step. Each entry in the reasoning timeline shows the operation (select, prune, escalate), the candidates considered, their scores, and the full text of the chosen step. |
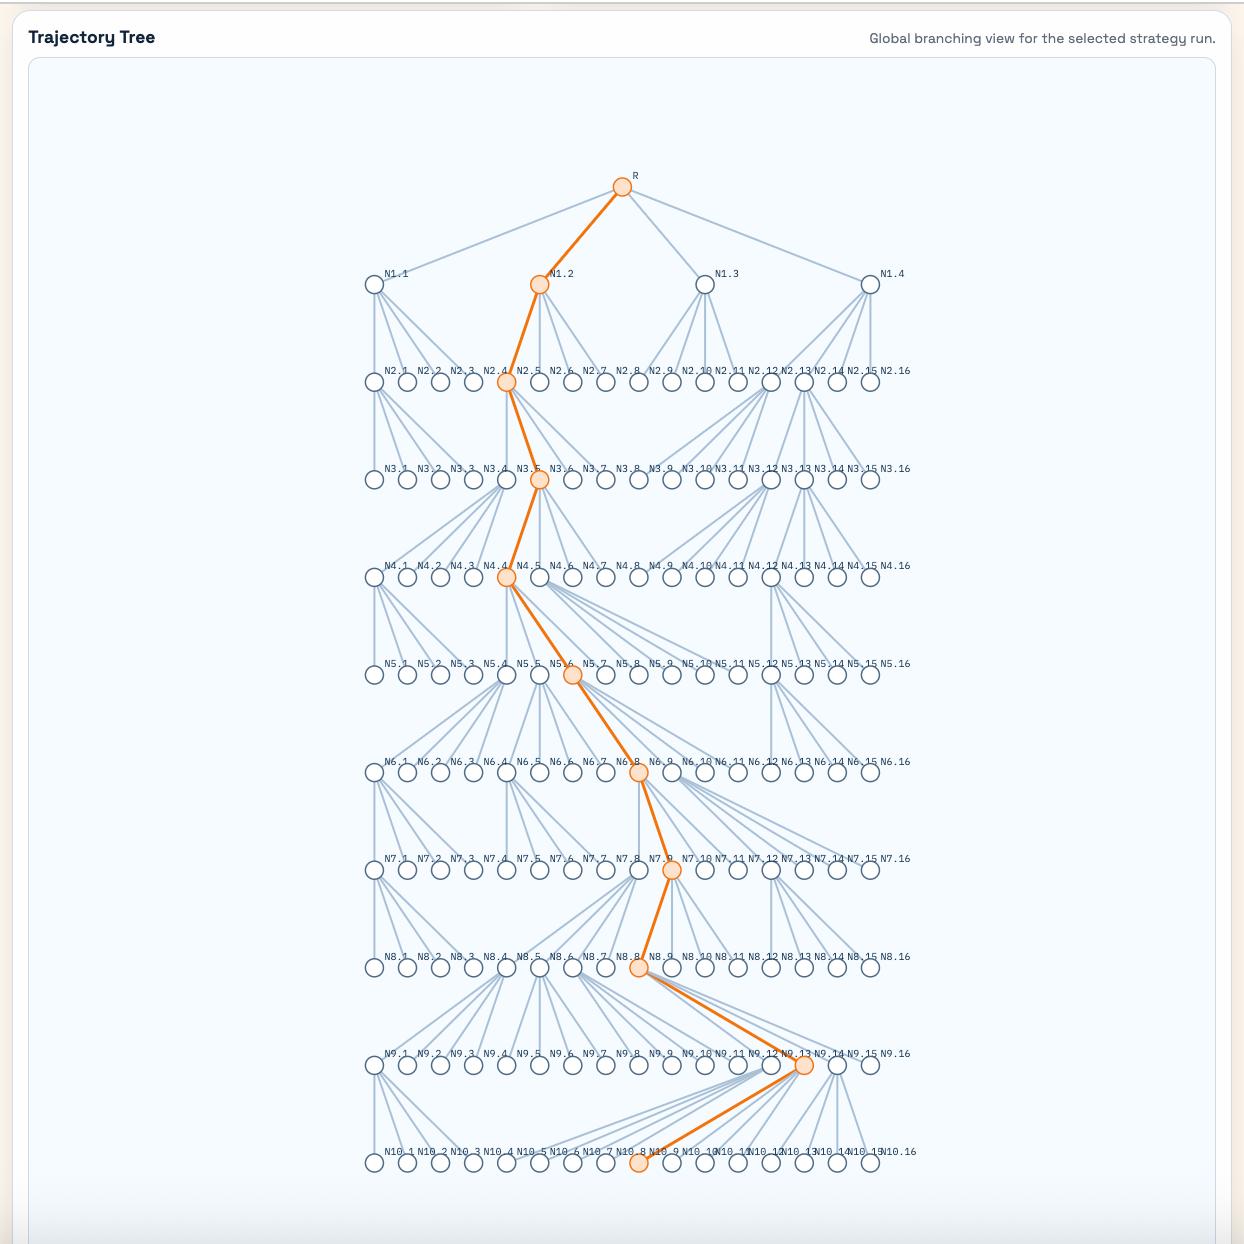 |
Trajectory tree. Global branching view of the entire strategy run. Nodes represent reasoning steps; the orange path highlights the final selected trajectory. Useful for understanding how beam search or tree-of-thought explores and prunes the search space. |
After starting the REST API service, open:
http://localhost:8001/debugger
See service_app/README.md for details on cached examples and custom input modes.
Supported Strategies
| Strategy | Online/Offline | LLM Access | Prefill | Description |
|---|---|---|---|---|
| Best-of-N | Offline | Black-box | No | Sample N solutions, select best by scorer |
| Majority Voting | Offline | Black-box | No | Sample N solutions, select answer by majority vote |
| Beam Search (ToT) | Online | Black-box | Yes | Explore tree of reasoning paths, prune by score |
| Extended Thinking | Online | Black-box | Yes | Control reasoning budget to force longer CoT |
| MUR | Online | White-box | Yes | Allocate more compute only on uncertain steps |
| DeepConf Online | Online | White-box | Yes | Steer generation toward high-confidence tokens |
| DeepConf Offline | Offline | White-box | No | Rerank candidates by model confidence scores |
| Phi-decoding | Online | White-box | Yes | Foresight sampling and adaptive pruning |
| Uncertainty CoT | Online | White-box | Yes | Generate multiple trajectories when uncertain |
Project Structure
thinkbooster/
├── thinkbooster/         # Core library (pip install thinkbooster)
│   ├── strategies/       # TTS strategy implementations
│   ├── models/           # Model wrappers (vLLM, HuggingFace, API)
│   ├── scorers/          # Step scoring (PRM, uncertainty, voting)
│   ├── evaluation/       # Correctness evaluation (exact match, LLM judge)
│   └── datasets/         # Dataset loaders and utilities
├── config/               # Hydra configuration system
├── scripts/              # Evaluation scripts (run_tts_eval.py)
├── service_app/          # REST API service + visual debugger
├── tests/                # Test suite with strategy registry
├── docs/                 # Documentation
└── setup.sh              # Optional: install GitHub-only deps (UHead, KernelAct)
See Project Structure for a detailed architecture overview.
Documentation
- Project Structure — architecture and component descriptions
- Evaluation Protocol — datasets, metrics (accuracy, tokens, FLOPs), and reporting
- Strategy Registration — how to add new strategies with tests
- Service API Guide — REST API reference and configuration
- DeepConf Guide — confidence-based test-time scaling
Contributing
We welcome contributions! Whether it's a new strategy, scorer, dataset, or bug fix — see the Contributing Guide for setup instructions, development workflow, and coding standards.
Citation
If you use ThinkBooster in your research, please cite:
@misc{thinkbooster2026,
  title     = {ThinkBooster: A Unified Framework for Seamless Test-Time Scaling of LLM Reasoning},
  author    = {Smirnov, Vladislav and Nguyen, Chieu and Senichev, Sergey and Ta, Minh Ngoc and Fadeeva, Ekaterina and Vazhentsev, Artem and Galimzianova, Daria and Rozanov, Nikolai and Mazanov, Viktor and Ni, Jingwei and Wu, Tianyi and Kiselev, Igor and Sachan, Mrinmaya and Gurevych, Iryna and Nakov, Preslav and Baldwin, Timothy and Shelmanov, Artem},
  booktitle = {Preprint},
  year      = {2026},
  url       = {https://thinkbooster.s3.us-east-1.amazonaws.com/thinkbooster.pdf}
}
Troubleshooting
vLLM engine fails to start
Corrupted torch compile cache: If you see RuntimeError: Engine core initialization failed:
rm -rf ~/.cache/vllm/torch_compile_cache/
Missing C compiler: If Triton can't find gcc:
conda install -c conda-forge gcc_linux-64 gxx_linux-64 -y
ln -s $CONDA_PREFIX/bin/x86_64-conda-linux-gnu-gcc $CONDA_PREFIX/bin/gcc
ln -s $CONDA_PREFIX/bin/x86_64-conda-linux-gnu-g++ $CONDA_PREFIX/bin/g++
ANTLR version mismatch warnings
ANTLR runtime and generated code versions disagree: 4.9.3!=4.7.2
This is expected — Hydra uses ANTLR 4.9.3, latex2sympy2 was built with 4.7.2. Both work correctly.
License
This project is licensed under the MIT License — see the LICENSE file for details.
2 maintainers


Metadata
2 maintainers
Release files for thinkbooster 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| thinkbooster-0.1.1.tar.gz | 315.6 kB | Without provenance | Details for thinkbooster-0.1.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| thinkbooster-0.1.1-py3-none-any.whl | Python 3 | none | any | Details for thinkbooster-0.1.1-py3-none-any.whl |
Total release size: 680.3 kB
Release files / thinkbooster-0.1.1.tar.gz
| Download URL | thinkbooster-0.1.1.tar.gz |
|---|---|
| Size | 315.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c9e4641bbf78b179cb7e66327d198d45399f246f7469f0c685c8b307b2d50e67
|
|
BLAKE2b-256 checksum How to use checksums |
9ac160157854e26cbd4b8e0a94de8fcc938581f264608164dba28ddd43ed1df6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Release files / thinkbooster-0.1.1-py3-none-any.whl
| Download URL | thinkbooster-0.1.1-py3-none-any.whl |
|---|---|
| Size | 364.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c93aeeab1c8e6501b0cb8ebd1af0b9f986648293000d41e7e834b16a505e2c92
|
|
BLAKE2b-256 checksum How to use checksums |
8ee7a0675e93faf81f344113399ce75f252388f2e7e16c27f6e42afb04be34ad
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Security for thinkbooster 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














