
TokenSight
Local-first, zero-infra observability for AI agents. pip install, add one
decorator, and see every LLM call's cost, latency, and tokens in a local
dashboard. No cloud account, no Docker, no signup — your prompts never leave
your machine.
Why TokenSight?
Developers running LLM agents have zero visibility into cost, latency, and failure points — until the bill arrives. The existing tools all have friction:
- LangSmith / Langfuse / Datadog / Arize require cloud accounts, per-seat pricing, or heavy infra (ClickHouse, Docker Compose).
- Helicone — the one lightweight option — went into maintenance mode after its 2026 acquisition.
TokenSight fills that gap: local-first, zero-infra. A single pip install,
SQLite for storage, and one local FastAPI process is the entire backend. It
works fully offline (except your own LLM calls), sends no telemetry, and stores
nothing outside ~/.tokensight/.
Install
pip install tokensight
For the LangChain callback handler, install the optional extra:
pip install "tokensight[langchain]"
The OpenAI and Anthropic auto-instrumentation works with whatever provider SDK
you already have installed — no extra is required. (Convenience extras
tokensight[openai] and tokensight[anthropic] exist if you want pip to install
them for you.)
Quickstart
1. The @trace decorator
Wrap any function and it becomes one traced run. Every LLM call inside it is logged automatically.
from tokensight import trace


@trace
def run_agent():
    # ... your agent logic ...
    return "done"


run_agent()
You can also name the run and attach metadata:
@trace(name="nightly_summary", metadata={"env": "prod"})
def run_agent():
    ...
@trace works on both sync and async functions. If the TokenSight server is not
running, your function still executes normally — tracing simply no-ops.
2. auto_instrument() with OpenAI
Call auto_instrument() once at startup to monkey-patch the OpenAI (and
Anthropic) SDKs. Every client.chat.completions.create(...) is then traced with
zero code changes.
from tokensight import auto_instrument, trace
from openai import OpenAI

auto_instrument()  # patches installed provider SDKs (safe if some are missing)


@trace(name="openai_test")
def run():
    client = OpenAI()
    response = client.chat.completions.create(
        model="gpt-4o-mini",
        messages=[{"role": "user", "content": "say hi in 3 words"}],
    )
    return response.choices[0].message.content


print(run())
The dashboard now shows an openai_test run with one call: model
gpt-4o-mini, token counts, cost, and input/output previews.
3. TokenSightCallbackHandler with LangChain
For LangChain, pass the callback handler in your invocation config — no changes to your chain logic.
from tokensight import TokenSightCallbackHandler

handler = TokenSightCallbackHandler(run_name="my_chain")
chain.invoke(input, config={"callbacks": [handler]})
TokenSightCallbackHandler is imported lazily, so import tokensight never
requires langchain-core. Instantiating it without the langchain extra raises
a clear ImportError telling you to pip install tokensight[langchain].
See it in the dashboard
tokensight start
This opens http://localhost:4242 in your browser with your runs, a cost chart, and a per-run call timeline.
CLI Commands
| Command | What it does |
|---|---|
tokensight start |
Start the local server and open the dashboard at localhost:4242. |
tokensight stats |
Print a cost/latency/token summary table plus the top 5 most expensive runs. |
tokensight export |
Dump all runs and calls to a JSON file (-o/--output to choose the path). |
tokensight clear |
Delete all trace data (prompts for confirmation; -y/--yes to skip). |
Dashboard
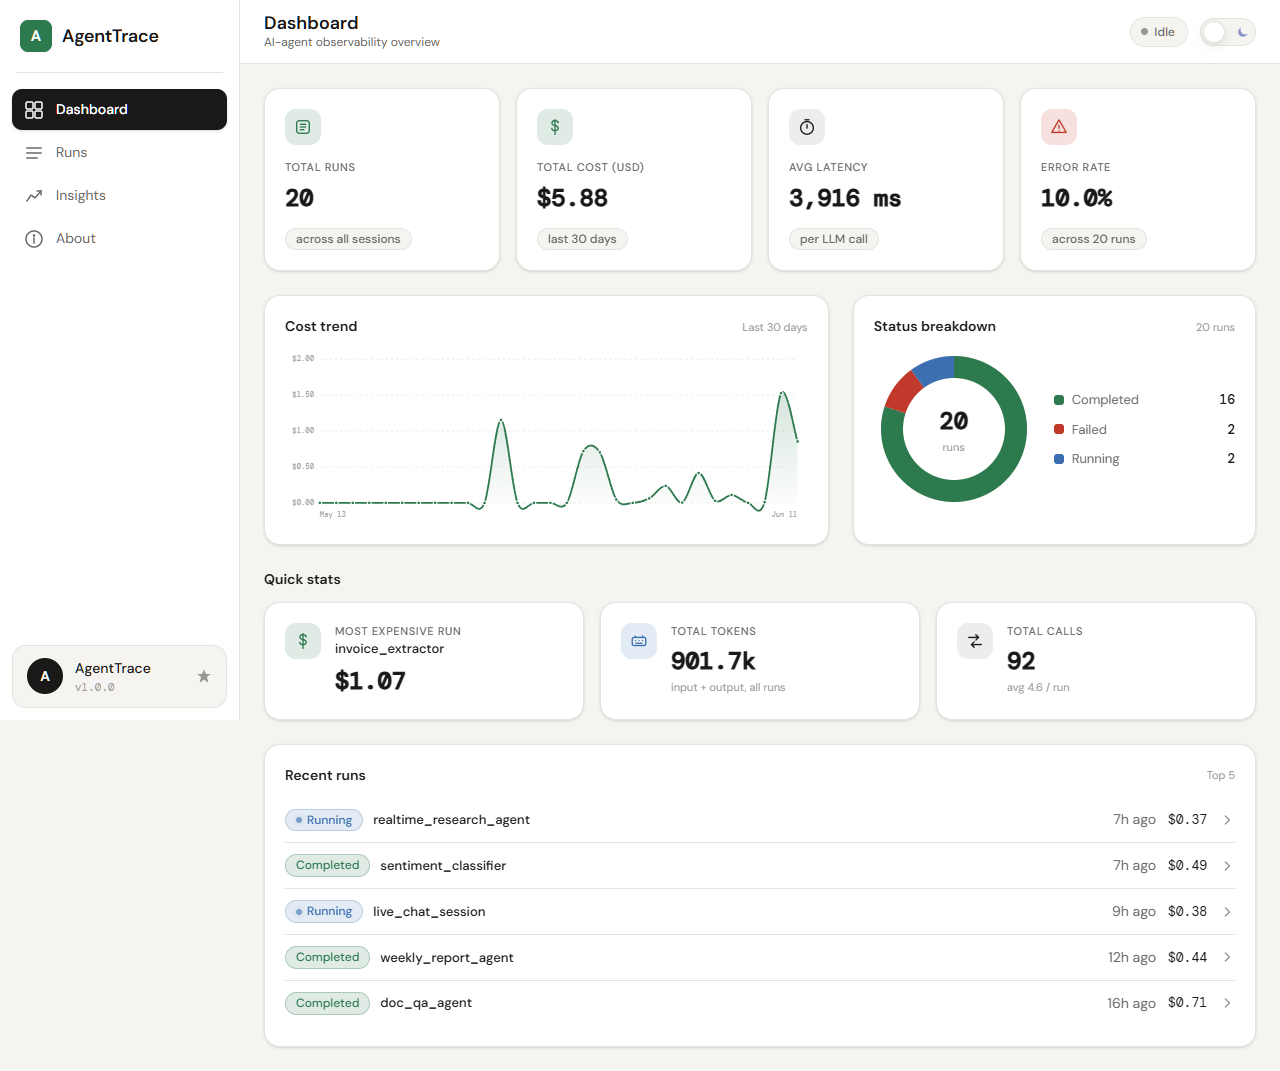
tokensight start serves a single-page dashboard: a stats bar (total runs, cost,
tokens, average latency, error rate), a 30-day cost chart, a paginated runs
list, and a per-run timeline showing each LLM call's model, latency, tokens,
cost, and truncated input/output previews.
Configuration
All configuration is via environment variables:
| Variable | Default | Purpose |
|---|---|---|
TOKENSIGHT_DB_PATH |
~/.tokensight/runs.db |
SQLite database file location. |
TOKENSIGHT_PORT |
4242 |
Port the server listens on. |
TOKENSIGHT_BUDGET_USD |
unset | Per-run budget; prints a terminal warning if a run's cost exceeds it. |
TOKENSIGHT_SERVER_URL |
http://127.0.0.1:4242 |
SDK target URL — override if the server runs on a different port/host. |
TOKENSIGHT_DISABLED |
unset | Set to 1 to make the SDK a complete no-op (for CI/tests). |
How it works
Your agent (@trace / auto_instrument / LangChain handler)
        │  synchronous, short-timeout HTTP POST (never crashes or slows your agent)
        ▼
Local FastAPI server  (127.0.0.1:4242)
        │
        ▼
SQLite  (~/.tokensight/runs.db)
        ▲
        │  read directly (no HTTP)
Dashboard  +  CLI (stats / export / clear)
- Resilient SDK. The SDK sends trace data to the local server over a
synchronous, short-timeout HTTP call wrapped in
try/except, with a circuit breaker that skips tracing instantly when the server is unreachable. If the server is down or anything goes wrong, your agent's result (or exception) is returned unchanged — TokenSight never crashes or meaningfully slows your code. - One local process. FastAPI serves both the JSON API and the bundled static dashboard from a single port. SQLite handles all persistence in one file.
- Privacy by design. Input and output previews are truncated to 500 characters — full prompts and completions are never stored. This is a deliberate privacy feature: nothing sensitive is persisted in bulk.
- Fully local, no telemetry. TokenSight makes no outbound network calls of its own. Your data stays on your machine.
License
MIT
1 maintainer

Release files for tokensight 1.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| tokensight-1.1.0.tar.gz | 313.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tokensight-1.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 493.0 kB
Release files / tokensight-1.1.0.tar.gz
| Download URL | tokensight-1.1.0.tar.gz |
|---|---|
| Size | 313.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
67b26bcba82a548ae1deb025baf9081051ff106e7c354f8aea4553013bed6029
|
|
BLAKE2b-256 checksum How to use checksums |
8600d27f848141f1580a87156b564a27a70a414904ad6c9e60340ccb73a688bc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 10, 2026.
Transparency logRelease files / tokensight-1.1.0-py3-none-any.whl
| Download URL | tokensight-1.1.0-py3-none-any.whl |
|---|---|
| Size | 179.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6cdf321196b90bc6609b15804eb5ae6dd5ad71c34efae7bf259886bcaf69a9bd
|
|
BLAKE2b-256 checksum How to use checksums |
b71a46f26dce18e240904f087029323c07e895fa9179a58c1c9224307a91b24f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 10, 2026.
Transparency log













