
TokenSpeed-MLA
Speed-of-light TokenSpeed MLA kernels for SM100/SM103/SM107 with:
MLA prefill:- CuTe DSL JIT backend for ragged varlen FMHA (no padding)
- BF16 output, optional LSE output, causal/non-causal modes, PDL support
MLA decode:- CuTe DSL decode kernels for FP16/BF16/FP8 input paths
- FP8 decode writes BF16 output for better downstream stability
- Split-KV + workspace path with runtime auto-sizing and compile caching
MLA K/V pack + FP8 quantize:- Fused Triton kernel replacing
cat + cast + castin chunked prefill - Supports strided views and optional pre-allocated output buffers
- Fused Triton kernel replacing
This package includes performance-oriented optimizations for latency-sensitive
serving workloads, especially coding agent style use cases with high request
concurrency, short decode steps, and strict time-to-first-token/next-token
requirements. For the MLA decode kernel, small q_len * num_heads
configurations can fold a query-token group (fold_sq_factor) into heads for
better tile utilization; the scheduler places remaining query groups across
the query sequence dimension.
SM107 support requires CuTe DSL 4.8.0 or newer and a compatible CUDA toolkit. Decode compilation and GPU regression tests also reject CuTe DSL warnings.
Performance numbers
Prefill performance
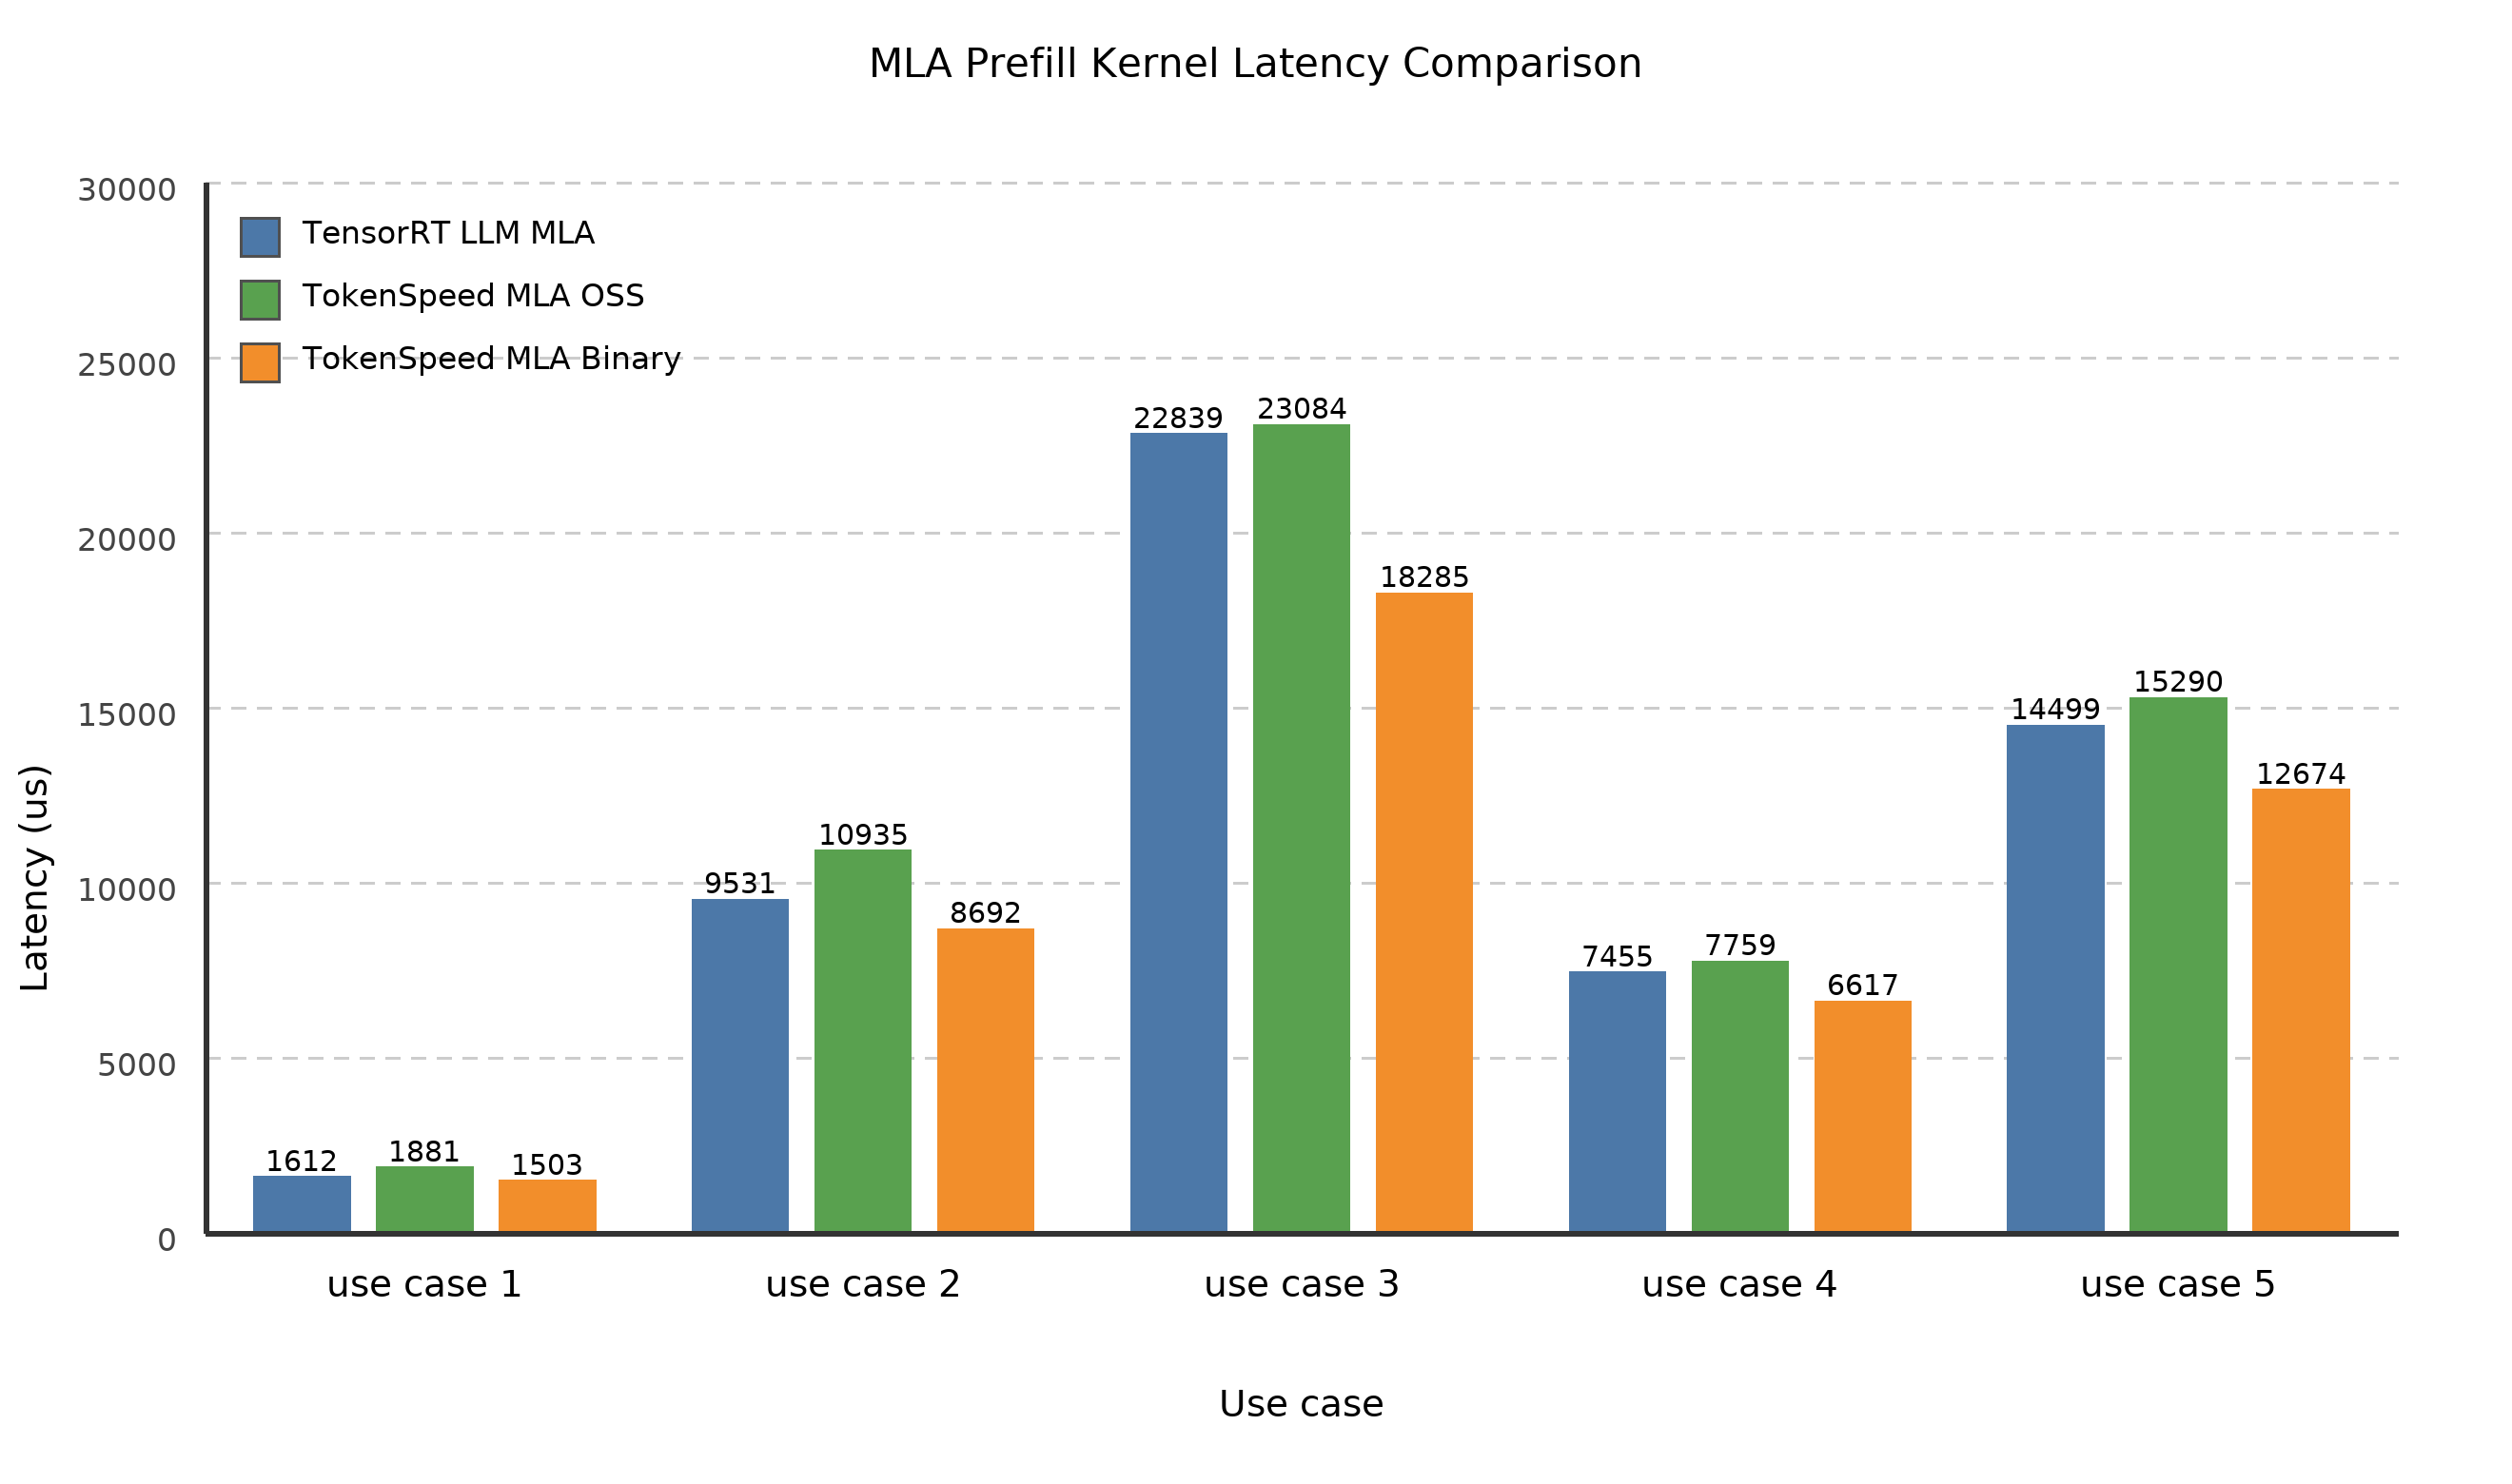
Where:
use case 1: batch_size = 1, seqlen_qo = 8 * 1024, seqlen_kv = 8 * 1024
use case 2: batch_size = 1, seqlen_qo = 8 * 1024, seqlen_kv = 32 * 1024
use case 3: batch_size = 1, seqlen_qo = 8 * 1024, seqlen_kv = 64 * 1024
use case 4: batch_size = 4, seqlen_qo = 512,      seqlen_kv = 80 * 1024
use case 5: batch_size = 4, seqlen_qo = 1024,     seqlen_kv = 80 * 1024
The preceding prefill comparison includes historical results from an AOT implementation. Current releases ship the public CuTe DSL JIT implementation; the historical AOT backend is not included in the package.
Collect the performance numbers with this command line:
python ./tokenspeed-mla/python/tokenspeed_mla/fmha.py \
  --is_causal \
  --bottom_right_align \
  --in_dtype Float8E4M3FN \
  --out_dtype Float8E4M3FN \
  --q_shape 1,8192,128,192 \
  --k_shape 1,8192,128,192 \
  --warmup_iterations 10 \
  --iterations 10 \
  --skip_ref_check
Decode performance
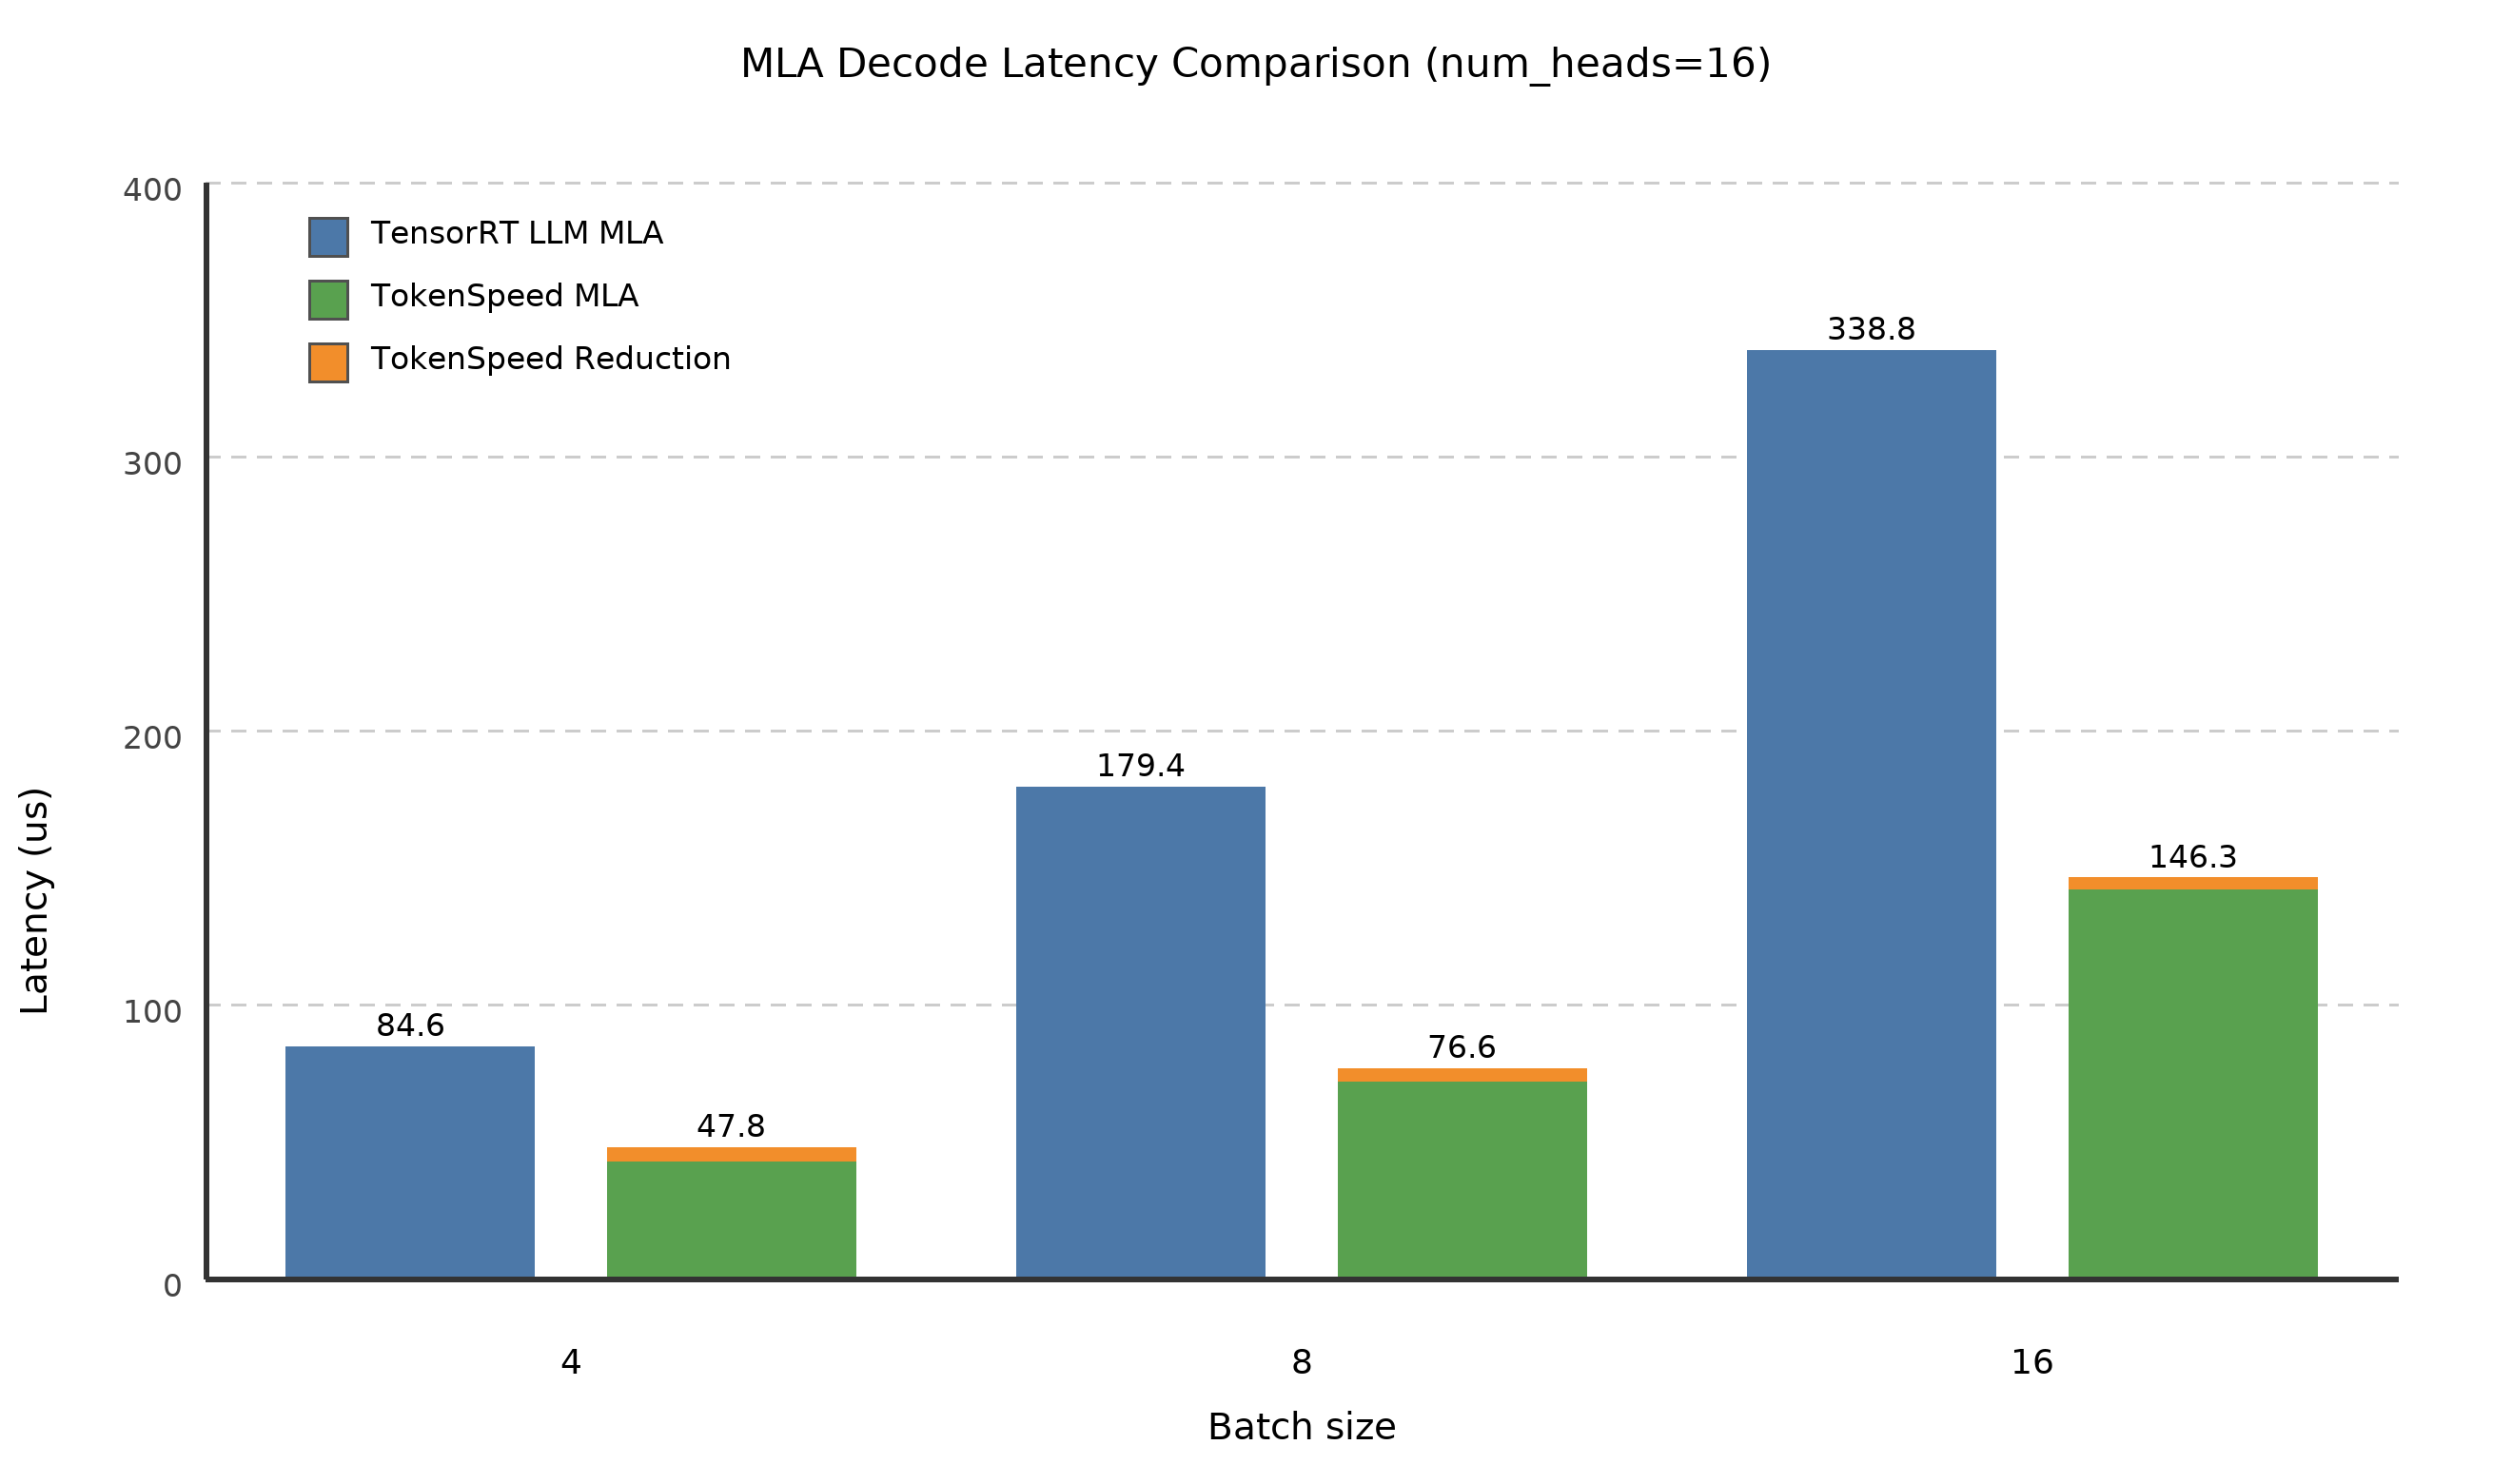
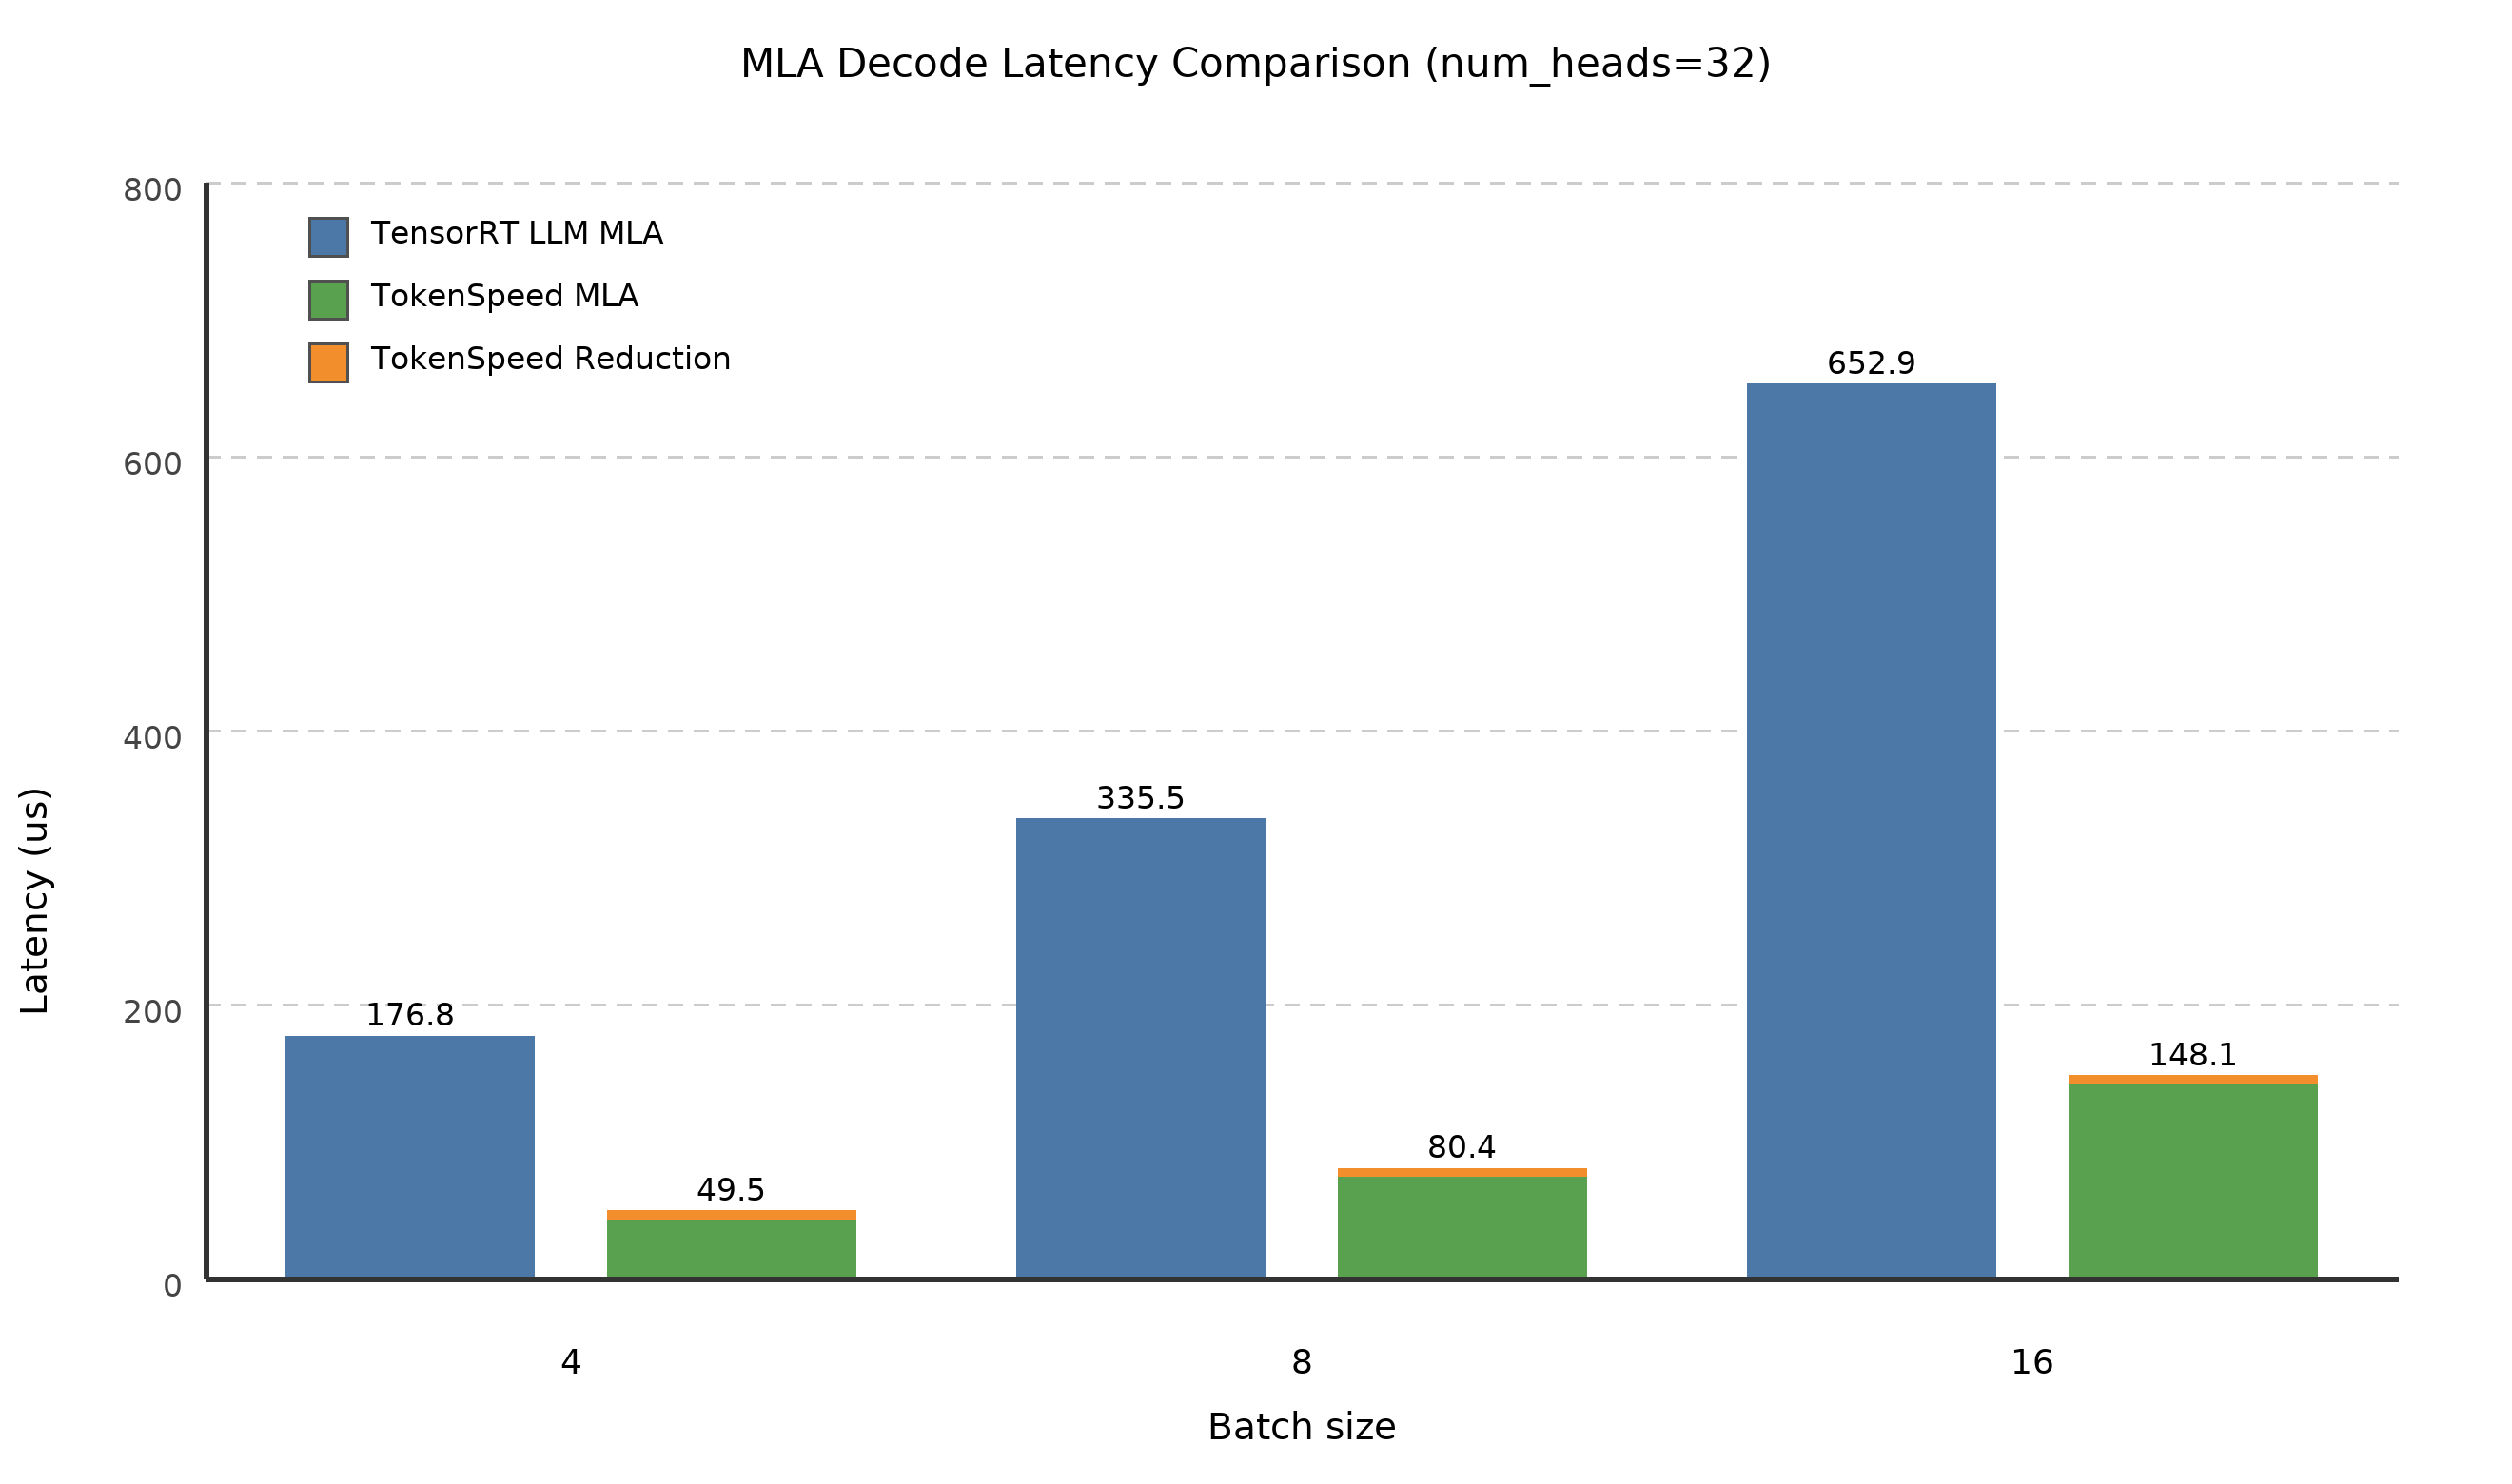
In these test cases, q_seqlen = 4 and kv_seqlen = 80K.
TensorRT-LLM uses a single kernel for MLA decode, which appears to adopt a swap-AB strategy in the tested cases. In contrast, TokenSpeed’s MLA decode kernel uses a two-kernel implementation: one kernel computes the MLA decode with split-KV, and a second kernel performs the reduction of the split-KV partial results.
Key Optimization of TokenSpeed MLA decode kernel: Group q_seqlen and num_heads into BMM1 M
In mla_decode.py, mla_decode_fp16.py, and mla_decode_fp8.py, decode uses
fold_sq_factor to partially fold query tokens into the head axis when
num_heads < 128. q_seqlen can be any positive length; the runtime chooses
the largest factor F such that: q_seqlen % F == 0 and
num_heads * F <= 128. If no factor greater than one divides q_seqlen, the
kernel does not fold and schedules the full query sequence dimension directly.
The folded execution shape becomes:
H_eff = num_heads * Fq_seqlen_eff = q_seqlen / F
This improves BMM1 M-dimension utilization and reduces tile waste in small-head
decode scenarios, especially token-by-token agent traffic. Example: with
num_heads=64, q_seqlen=4, the runtime chooses F=2, so the kernel folds two
query tokens into M (H_eff=128) and schedules the remaining two query
groups on the scheduler second dimension (q_seqlen_eff=2).
The public tokenspeed_mla_decode also accepts enable_packed_q=True to
opt into continuous query/head packing on the FP8 and FP16/BF16 M128 paths, adapted from
FlashInfer PR #4178. The default is False, preserving the folded-query
implementation. M64 and token-gapped Q/output views continue to
use that implementation even when the option is enabled.
The packing orders rows as query_token * num_heads + head. Each 2-CTA
group owns 128 consecutive rows, including across query boundaries. Thus
H96/Sq4 uses three query tiles instead of four, and H96/Sq8 uses six
instead of eight. Only the final tile may contain padding. This is a tensor
view transformation, with no additional packing kernel. The kernel uses
per-row causal positions and predicates partial output/LSE rows.
For packed queries, auto split-KV uses ceil(H * q_len / 128) query tiles,
and workspace needs B * 128 * ceil(H * q_len / 128) * split_kv * 513 * 4
bytes for D512/FP32 partials, or zero when split-KV is one. Callers enabling
this option must provide sufficient workspace. Output shape, output dtype
(BF16 for FP8; input dtype for FP16/BF16), and base-2 LSE semantics are unchanged.
The FP16/BF16 implementation retains its existing split-KV heuristic, reducer
capacity and PDL waits. The option is part of the
compile cache key. Existing direct kernel callers retain the old layout;
opting in through the public wrapper keeps tiling and workspace consistent.
Sliding-window and DCP masking remain supported; window boundaries use the packed row's original query-token position.
Regression coverage is in tests/test_mla_decode.py. It checks packed-query geometry, split-KV workspace sizing, FP8/FP16/BF16 outputs and LSE, reducer variants, CUDA-graph replay, sliding windows and DCP. From the repository root, select this checkout's sources explicitly:
PYTHONPATH=tokenspeed-mla/python python -m pytest -q tokenspeed-mla/tests/test_mla_decode.py
GPU cases require SM100, SM103 or SM107; pytest skips them on other devices.
Add -k 'not TestGPU and not TestCompile' for CPU checks, -k TestCompile
for compilation checks across all three architectures, or -k TestGPU for
GPU checks. Compilation checks require a CuTe DSL and CUDA toolchain that
support the target architecture, even when no GPU is visible.
SM107 decode
FP8 and FP16/BF16 decode share the existing kernel classes, scheduler,
split-KV reducer and masking logic across SM100, SM103 and SM107. The public
wrapper selects the architecture from query.device and includes it in the
compile cache key and compiler target. Direct kernel construction requires
an explicit compute_capability=(10, 0), (10, 3) or (10, 7).
On SM107, an out tensor with dtype torch.float8_e4m3fn selects
mla_decode_fp8_sm107.py.
The kernel packs query/head rows into M256 tiles and uses 4-CTA clusters
to separate QK/softmax from PV, with a 2-CTA fallback. BF16 output keeps
using the shared kernel.
The M256 kernel and its 2-CTA fallback also support native BF16 output for
direct launches through _sm107_fp8_out_decode. The compilation helper takes
an explicit output_dtype, which determines the output tensor type and is
part of the compile cache key. Epilogues, the split-KV reducer and empty-row
stores write the selected dtype directly; no conversion kernel is needed.
Q/KV and probabilities remain FP8, and split-KV partials remain FP32. Changing
the output dtype does not change split selection or softmax precision.
BF16 results are checked against an FP32 reference; bitwise equality with
the shared M128 kernel is not guaranteed because the computation order and
normalization parameters differ.
The public wrapper uses FP32 for softmax exponentials and row sums. Packed FP16 softmax remains an explicit option for direct kernel construction. In the mixed-cluster kernel, both precisions handle each softmax group's final tile in the masked tail loop. This removes final-sum exchange branches from the full-tile loop while preserving causal masks and odd/even tile counts. Unsplit walks retain the normalization base for maximum increases of up to 4 log2 units; split chunks use 8. This reduces PV rescaling and bounds the unnormalized probabilities by 16 and 256 respectively, within FP8 E4M3's range. The normalization base affects FP8 rounding, so output and LSE accuracy are checked against an FP32 reference.
Automatic split-KV planning uses the capacity of full 4-CTA clusters, reserves
clusters // 16 slots, and targets one wave of work. The wrapper preserves
an explicit min_split_kv and normalizes the result to nonempty partitions.
This limits workspace traffic and reduction work, but can reduce parallelism
too far for some shapes. The H96/B16/Q4 cases regress when the split count
drops from three to one.
The M256 kernel supports up to four tiles per request for either output dtype.
By default, H must divide 256 and q_len must be a multiple of 256 / H;
enable_packed_q=True accepts other shapes such as H96 and partial tiles.
The kernel supports causal/non-causal attention, split-KV, LSE, PDL and CUDA
graphs; it does not support sliding windows, DCP, or local_visible_lens.
Rows with no visible keys produce zero output and -inf LSE.
SM107 FP8/BF16-output compilation and GPU regression tests reject CuTe DSL warnings. The mixed-cluster kernel issues CLC queries directly and owns its unswizzled grid and response decoding, avoiding the deprecated example scheduler classes.
H96/Q4 fills 75% of M256 tiles; H96/Q8 fills them completely. M128 packing fills three and six tiles respectively, so relative performance depends on tile utilization as well as batch size and split-KV scheduling.
Other optimizations include:
- FP8 split-KV candidates are normalized to nonempty K partitions before workspace allocation and kernel launch. The reducer uses a 32/64-split capacity for the M128/M64 paths and selects 1/2/4 disjoint D512 output bands when the real output rows do not fill the GPU. These changes adapt the split-KV and reducer optimizations from FlashInfer PR #4178 to TokenSpeed's folded-query layout; both reducer settings are included in the compile cache.
- Using 2CTA UTCMMA instruction to reduce shared memory usage.
- Try to use as few mbarriers as possible.
- Split the KV loading warp to get more latency-hiding ability. After loading K, V is already in the L2 cache. Loading K of the next tile does not have to wait for the completion of V loading.
- Using multiple stages (sub-tiling) for STG in the epilogue.
Collect the performance numbers with this command line:
python ./tokenspeed-mla/python/tokenspeed_mla/mla_decode_fp8.py \
  --batch_size 4 \
  --softmax_scale 0.07216882 \
  --page_size 64 \
  --seq_len_k 81920 \
  --in_dtype Float8E4M3FN \
  --out_dtype Float8E4M3FN \
  --seq_len_q 4 \
  --warmup_iterations 1 \
  --iterations 10 \
  --num_heads 16 \
  --skip_ref_check
MLA 2 decode benchmarks
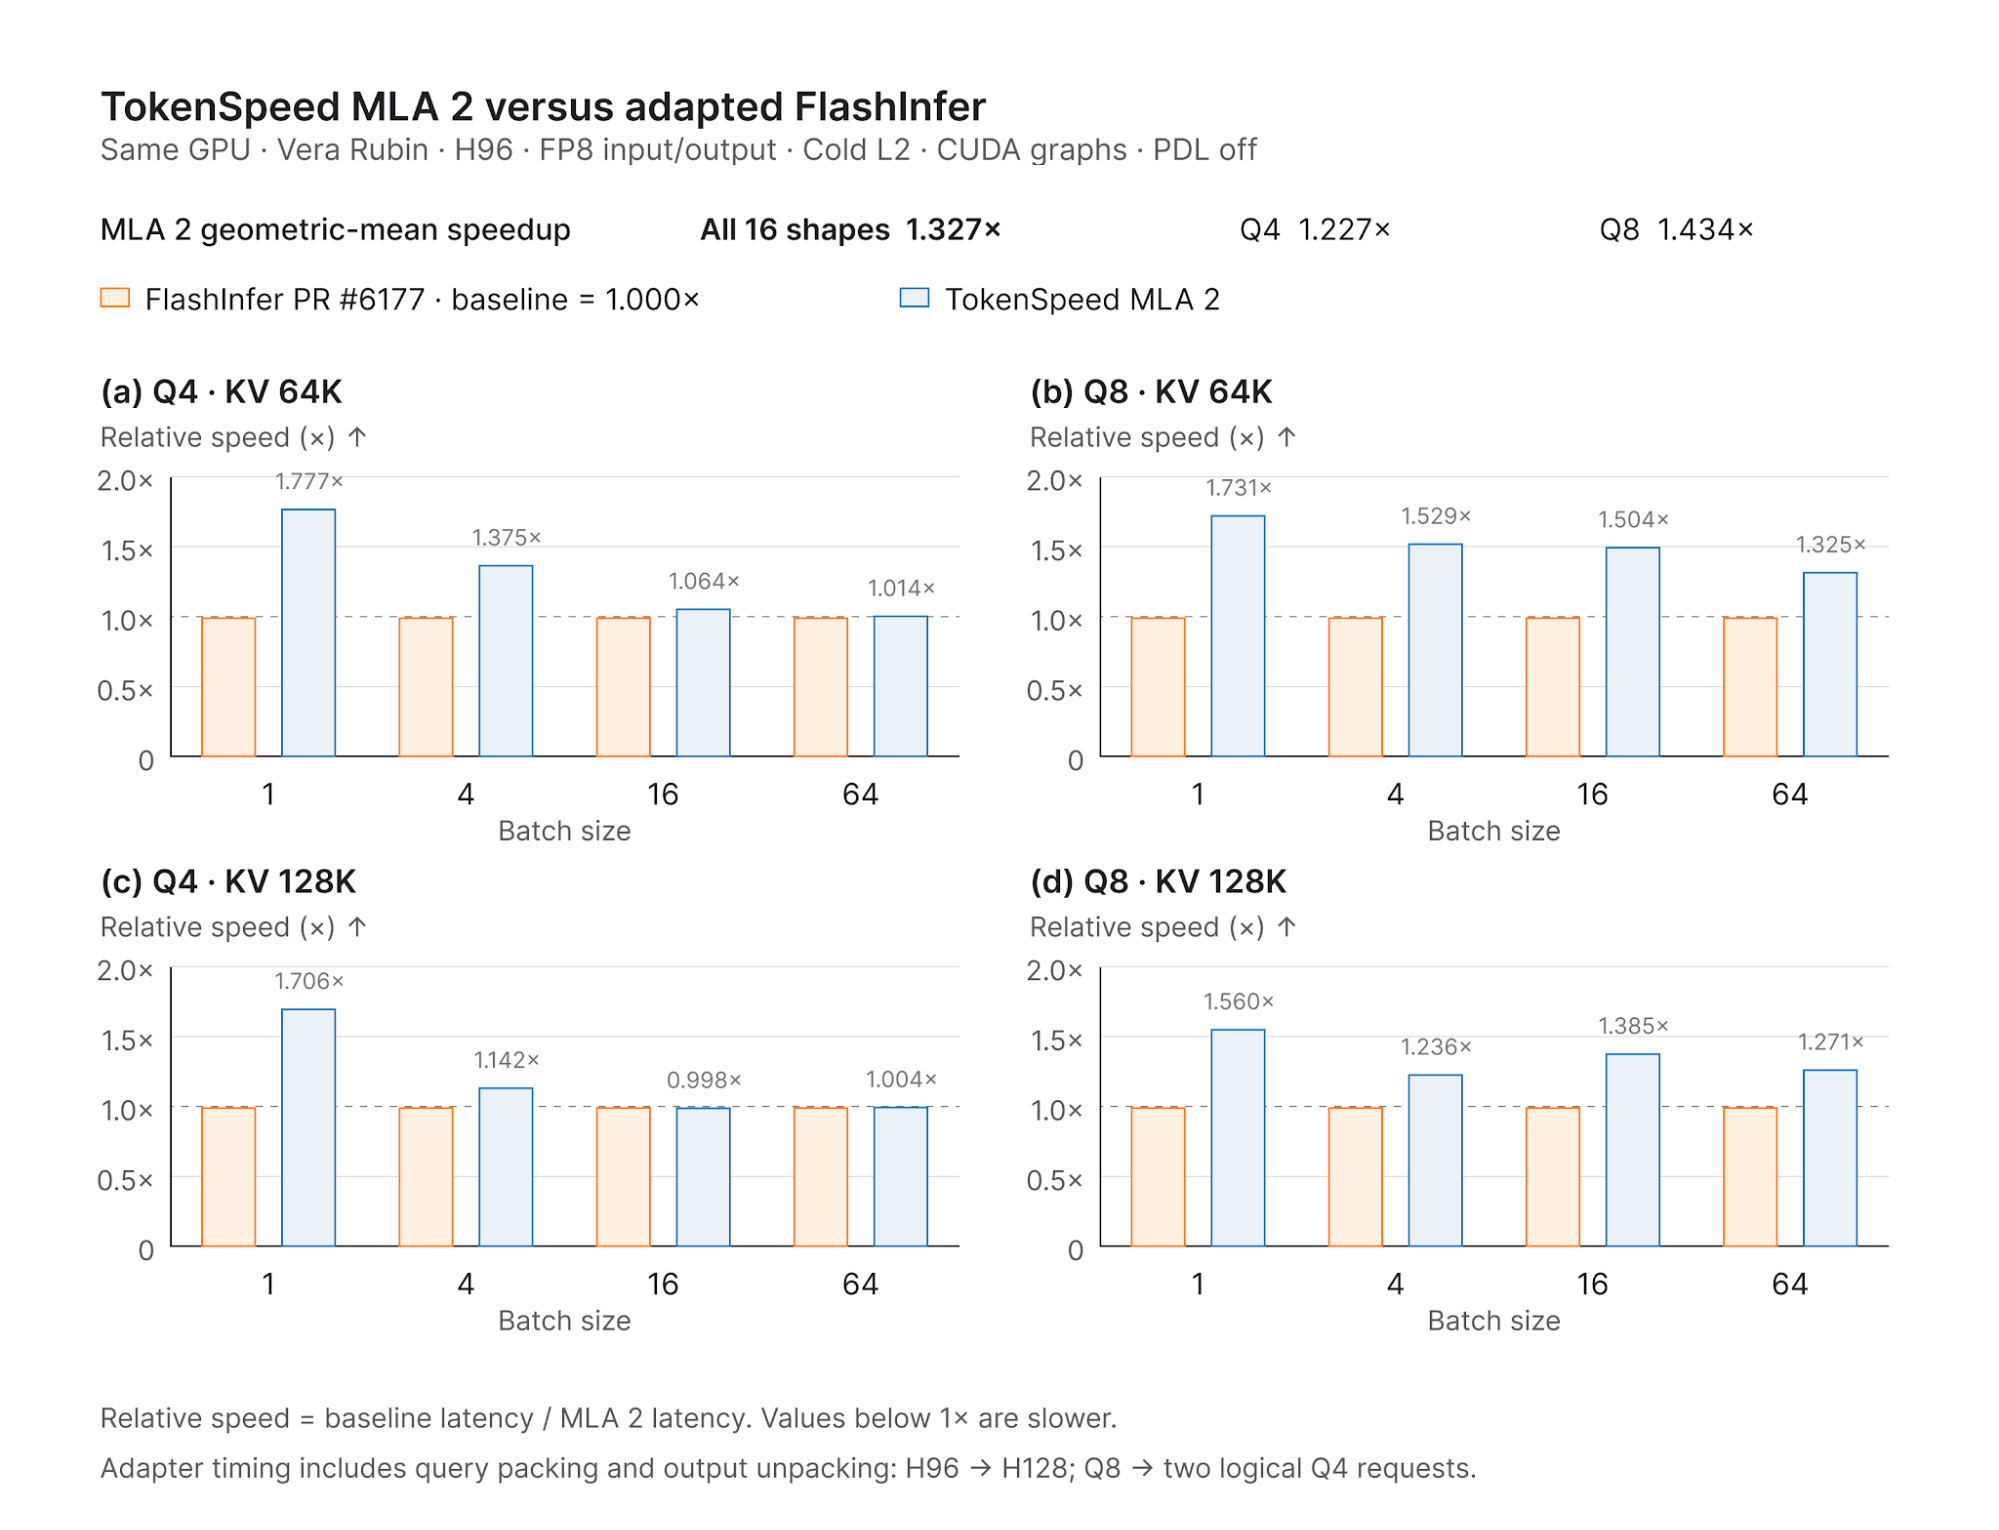
The MLA 2 benchmark article compares the M256, four-CTA MLA 2 implementation for NVIDIA Vera Rubin with MLA 1, the Blackwell M128 implementation. The 16 workloads use 96 query heads (H96), 4 or 8 query tokens (Q4 or Q8), batch sizes 1, 4, 16, and 64, and KV context lengths of 65,536 or 131,072 tokens (KV64K or KV128K). Speedup is baseline latency divided by MLA 2 latency for the same workload; summary values are geometric means, while peaks are individual results.1
Same-GPU comparisons
Both comparisons below run on the same NVIDIA Vera Rubin GPU with FP8 inputs and outputs; they do not measure the default BF16-output path.
| Baseline | Overall speedup | Q4 speedup | Q8 speedup |
|---|---|---|---|
| MLA 1 recompiled for NVIDIA Vera Rubin | 1.142× | 1.027× | 1.271× |
| Adapted FlashInfer | 1.327× | 1.227× | 1.434× |
MLA 2 has lower median latency than recompiled MLA 1 in 13 of 16 workloads, including all eight Q8 workloads. Three Q4 workloads are slower. Native Q8 packing fills three M256 tiles, while Q4 fills only 75% of two tiles.
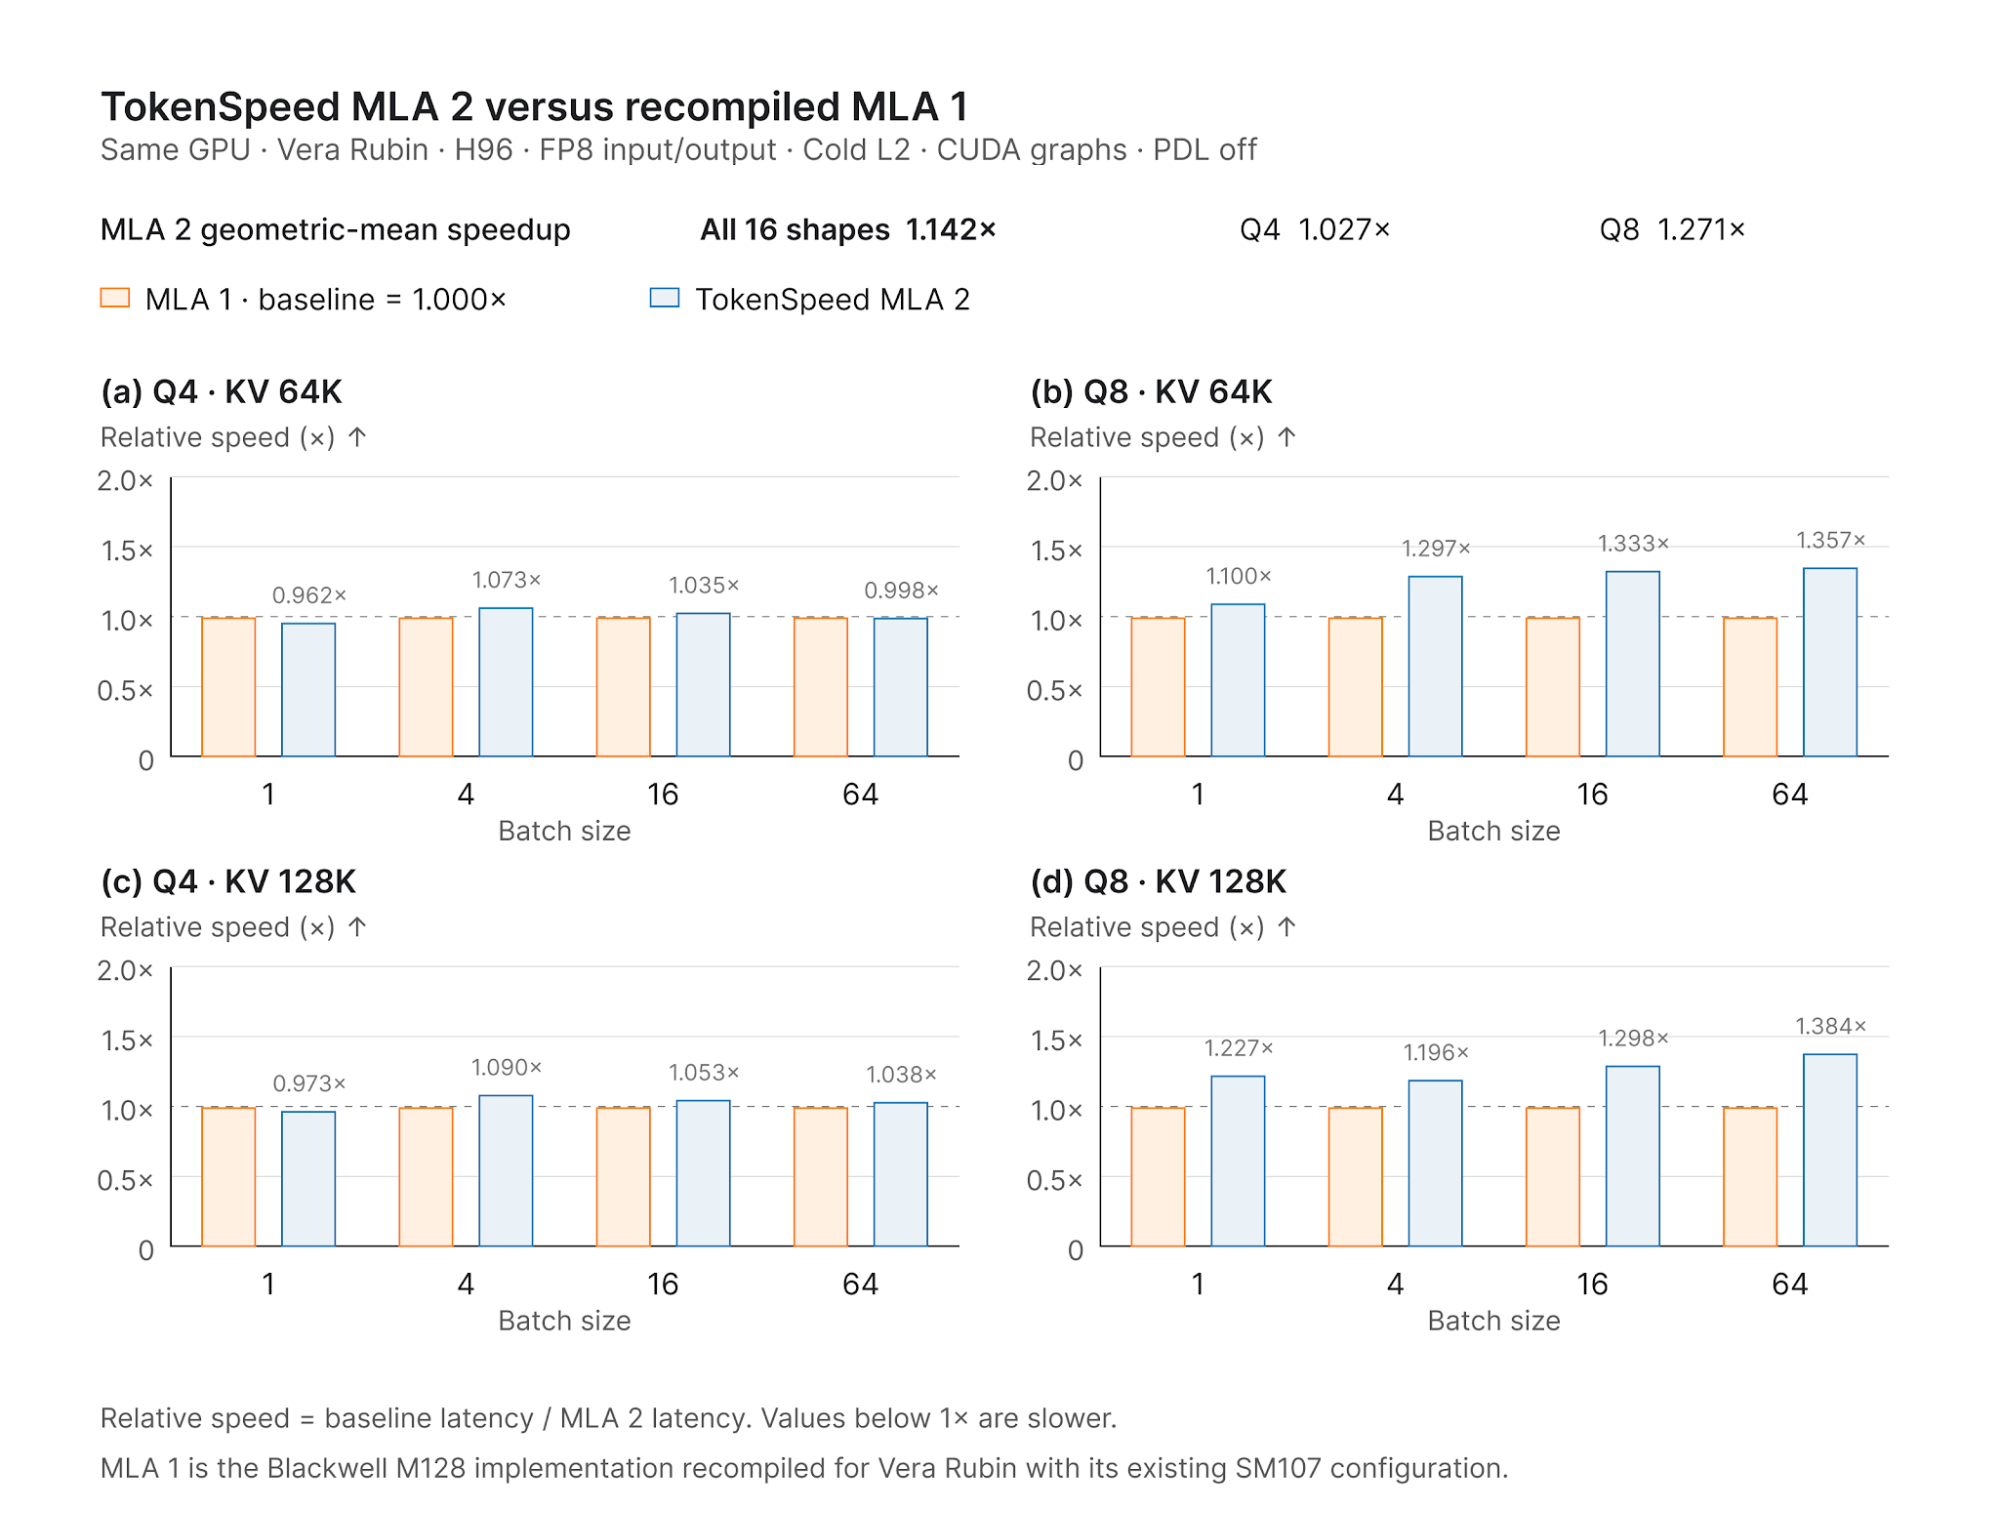
The FlashInfer comparison uses the benchmarked PR #6177 implementation with an H96-to-H128 adapter that splits Q8 into two Q4 requests. Timing includes query packing and output unpacking. It compares native H96 support and tuning against that adapted baseline, not native H128 performance or current FlashInfer releases.
Cross-hardware comparison
Across the same 16 workloads, MLA 2 on NVIDIA Vera Rubin achieves:
| Baseline | Geometric mean speedup | Peak speedup |
|---|---|---|
| MLA 1 on NVIDIA B200 | 2.62× | 3.44× |
| MLA 1 on NVIDIA GB200 | 2.05× | 2.84× |
Both peaks occur at batch size 16, Q8, and KV64K. Each run uses one GPU. Hardware, power, clocks, and implementations differ, so these ratios include both hardware and software changes and do not isolate architectural gains. These are kernel-latency results, not end-to-end serving results.
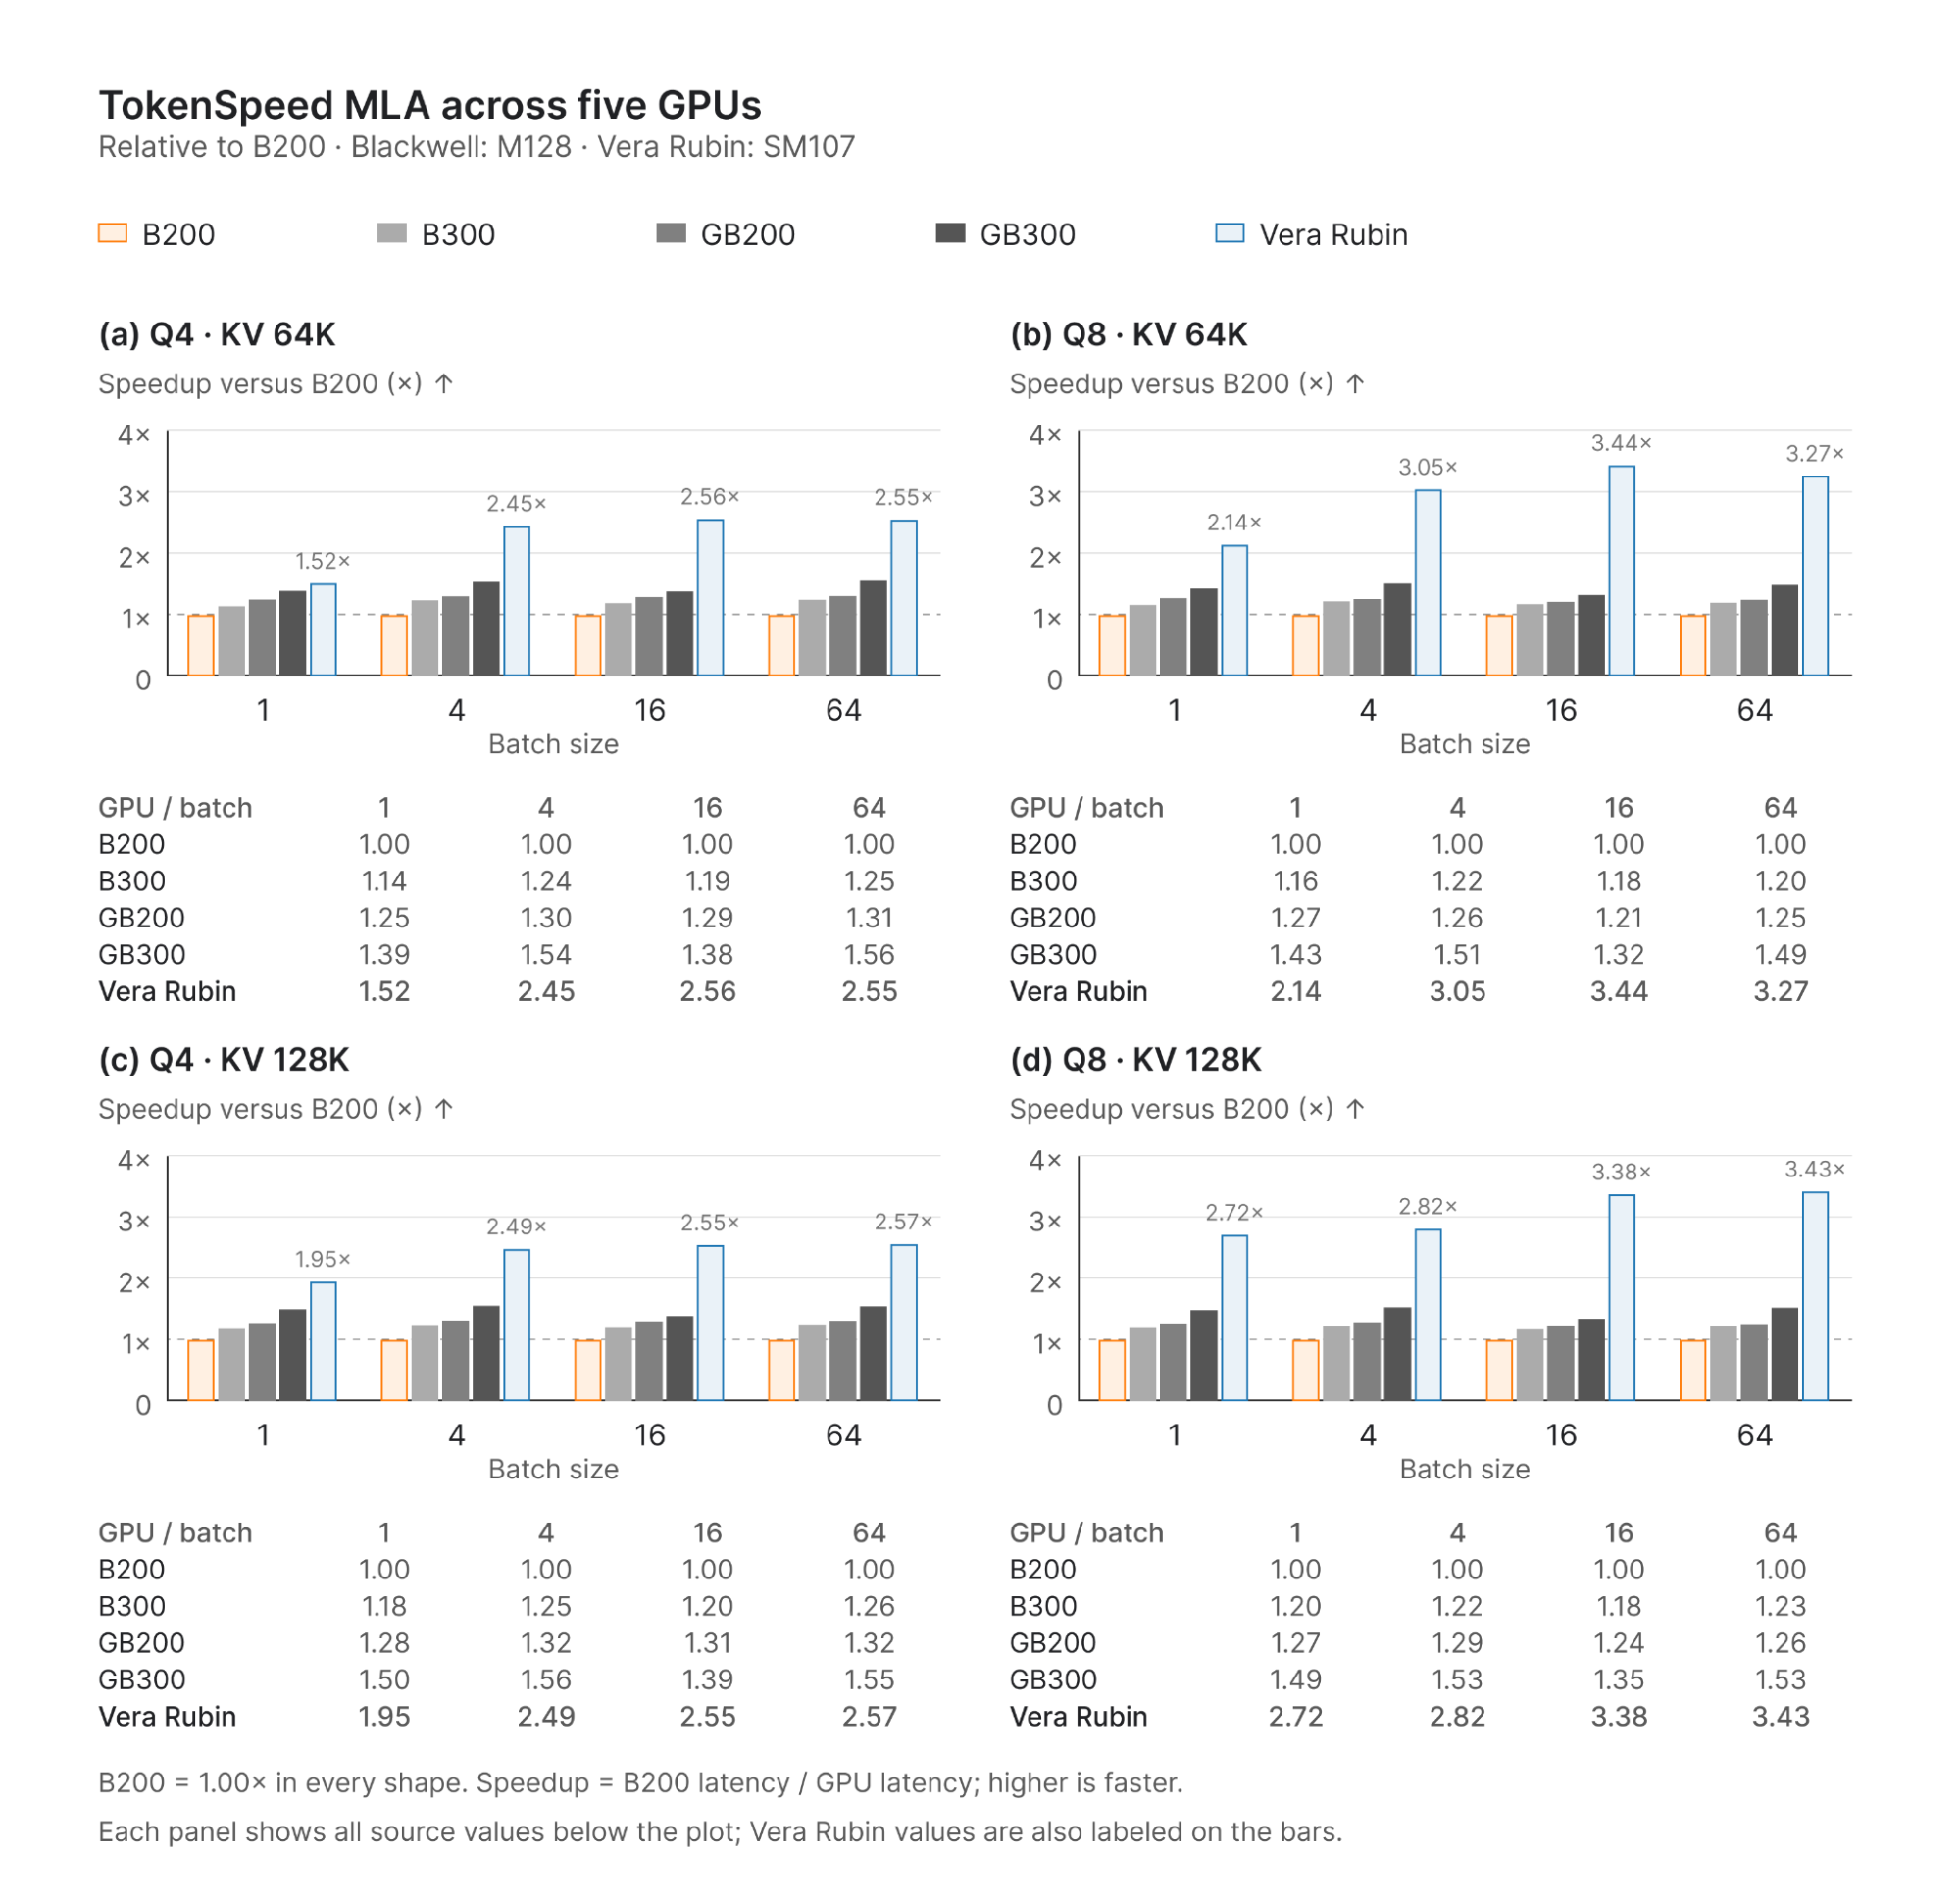
The chart normalizes every series to B200 at 1×. For a comparison with GB200, divide the NVIDIA Vera Rubin ratio by the GB200 ratio for the same workload. Cross-hardware ratios are separate comparisons, not additional factors to multiply by the same-GPU speedups.
Kernel capability summary
MLA Prefill (tokenspeed_mla_prefill)
What it supports:
- Ragged varlen prefill without padding:
Q: [sum(q_lens), h_q, d_qk]K: [sum(kv_lens), h_k, d_qk]V: [sum(kv_lens), h_k, d_v]
- Different Q/KV sequence packs (
cum_seq_lens_qandcum_seq_lens_kvcan differ) - Causal and non-causal execution
- Optional LSE return (
return_lse=True) - PDL enable/disable (
enable_pdl) - Kernel compile cache keyed by static config (such as
dtype,d_qk,d_v, causal, LSE, and PDL) - The wrapped FMHA path enables skip-correction.
- ex2-emulation (disabled by default on B200, and not supported on B300)
- CuTe DSL JIT backend
Input/output dtype behavior:
- The CuTe DSL backend accepts these input dtypes:
torch.float16,torch.bfloat16,torch.float8_e4m3fn,torch.float8_e5m2- MLA Prefill supports only
torch.float8_e4m3fn
- Prefill output tensor is BF16 (
torch.bfloat16) - Optional LSE output is FP32
MLA Decode (tokenspeed_mla_decode)
What it supports:
- Query shape:
[B, q_len, H, kv_lora_rank + qk_rope_head_dim] - KV cache shape:
- 3D:
[num_pages, page_size, D_total] - 4D accepted and normalized internally
- 3D:
- Auto
split_kv+ workspace sizing and caching - Supports FP16/BF16/FP8; FP8 path writes BF16 output, or FP8 output on
SM107 when
outis FP8 (see SM107 decode). - Supports
H <= 128and1 <= q_len <= 4; for example,H=64, q_len=4is supported. - The wrapper computes and caches
split_kvandworkspace_sizefrom runtime shape/device info. is_var_seq,is_persistent, andenable_pdlaffect scheduling/compile variants.causal_masksupports causal and non-causal execution on FP16/BF16/FP8 paths.window_leftbounds each block row's history: rowisees keys[max(0, K - q_len - window_left + i), k_bound), the wholeq_lenblock pluswindow_lefttokens of context. The kernel starts its KV walk at the window rather than at key 0, so cost tracks the window, not the cache.-1(the default) is full history and compiles the same kernel it always did.- Optional
outtensor reuse is_var_seqandenable_pdlcontrols
Minimal usage
1) Decode
import torch
from tokenspeed_mla import tokenspeed_mla_decode

# query: [B, q_len, H, D_qk]
# kv_cache: [num_pages, page_size, D_total]
out = tokenspeed_mla_decode(
    query=query,
    kv_cache=kv_cache,
    workspace_buffer=workspace_buffer,  # torch.int8, 1D
    kv_lora_rank=kv_lora_rank,
    qk_rope_head_dim=qk_rope_head_dim,
    block_tables=block_tables,          # [B, max_pages]
    seq_lens=seq_lens,                  # [B]
    max_seq_len=max_seq_len,
    softmax_scale=softmax_scale,
    enable_pdl=False,
)
2) Prefill
import torch
from tokenspeed_mla import tokenspeed_mla_prefill

# query: [sum(q_lens), h_q, d_qk]
# key:   [sum(kv_lens), h_k, d_qk]
# value: [sum(kv_lens), h_k, d_v]
out, lse = tokenspeed_mla_prefill(
    query=query,
    key=key,
    value=value,
    seq_lens=seq_lens,
    cum_seq_lens=cum_seq_lens_kv,
    max_seq_len=max_kv_len,
    batch_size=batch_size,
    softmax_scale=softmax_scale,
    is_causal=True,
    return_lse=True,
    cum_seq_lens_q=cum_seq_lens_q,  # optional, when Q/KV lengths differ
    max_seq_len_q=max_q_len,        # optional
    enable_pdl=False,
)
Releases
The release-tokenspeed-mla workflow
builds a source-only py3-none-any wheel from this repository and publishes it to
PyPI. Packaging does not require a GPU or CUDA compiler; the kernels compile with
CuTe DSL and Triton at runtime.
Before the first release through this workflow, configure a
PyPI Trusted Publisher
for the existing tokenspeed-mla project:
- Owner:
lightseekorg - Repository:
tokenspeed - Workflow filename:
release-tokenspeed-mla.yml - Environment:
pypi
Release steps:
- Merge kernel changes, then update
[project].versionintokenspeed-mla/pyproject.tomlwhen a release is needed. Prefer a separate version-bump PR; multiple code changes can share one release. - After merging the version bump, dispatch from
main:gh workflow run release-tokenspeed-mla.yml -R lightseekorg/tokenspeed --ref main. The workflow refuses versions already present on PyPI and checks the wheel's metadata, JIT sources, and license notices before publishing. - Wait for PyPI publication, then use
update-tokenspeed-kernel-mla.ymlwithmla_version=<version>to open the dependency-update PR.
For local packaging checks, use Python 3.12 and install build, packaging,
pytest, and twine in a virtual environment. From the repository root:
(cd tokenspeed-mla && python -m pytest tests/test_release.py -q)
python -m build tokenspeed-mla --wheel --outdir dist
python -m twine check --strict dist/*
python tokenspeed-mla/scripts/check_release.py --package-dir tokenspeed-mla --dist-dir dist
FP8 split-KV partial storage
FP8 decode keeps split-KV partial outputs in FP32 by default. Set
TOKENSPEED_MLA_FP16_PARTIALS=1 before importing the package to opt into FP16
partial storage. Accumulation and log-sum-exp remain FP32; the reducer applies
output_scale after combining normalized partials. Direct FP8 kernel callers
must explicitly specify partial_fp16 and a reducer_max_splits capacity that
covers every split in their launches.
-
The same-GPU tests use FP8 queries, KV data, and outputs; 64-token pages; a cold L2 cache through KV rotation; and disabled programmatic dependent launch (PDL). Latency is the median of 15 repeats of 20 CUDA graph iterations, including split-KV reduction and, for adapted FlashInfer, query packing and output unpacking. MLA 1 is recompiled with four key and four value stages. Overall geometric means weight all 16 workloads equally; Q4 and Q8 means each cover eight workloads. See the linked article for the full benchmark context. ↩
1 maintainer

Metadata
1 maintainer
Release files for tokenspeed-mla 2.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tokenspeed_mla-2.0.1-py3-none-any.whl | Python 3 | none | any | Details |
Release files / tokenspeed_mla-2.0.1-py3-none-any.whl
| Download URL | tokenspeed_mla-2.0.1-py3-none-any.whl |
|---|---|
| Size | 239.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c657a86827d1d30f0be7fb2622882e6945d0c3a17acfda06cfa8c9aed03fa361
|
|
BLAKE2b-256 checksum How to use checksums |
6ec58304eca83161ff18f3cb5135ef5855e103710c5e3e825497558184984f5e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 13, 2026.
Transparency log













