
TokLens: A Multilingual Lens on Tokenizer Quality for LLMs

Accepted to ACL 2026 SRW. 🎉
Open-source toolkit for evaluating tokenizer quality across languages using six intrinsic metrics. We evaluate 24 tokenizers from major LLM families across 15 typologically diverse languages and correlate with downstream performance.
Key Findings
- Stark cross-lingual disparities persist. GPT-2 produces 56x more tokens per word in Japanese than English. Qwen2.5 and Gemma-2 reduce this gap to under 4x.
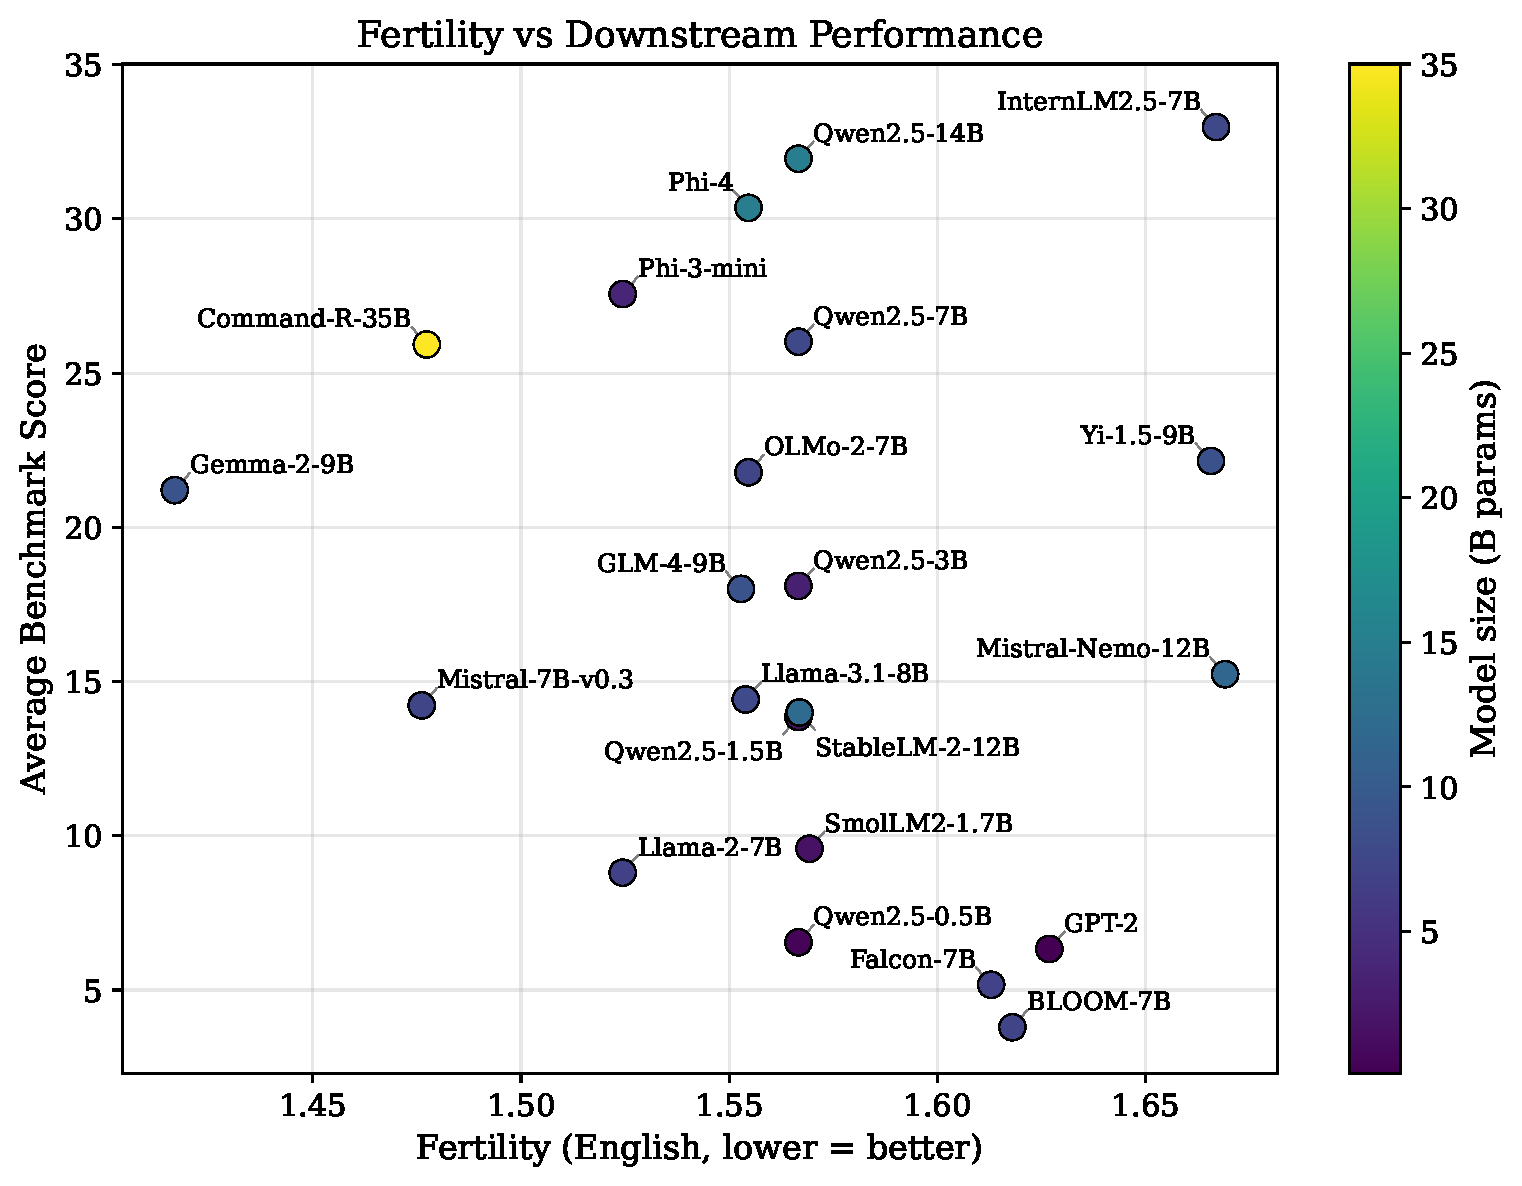
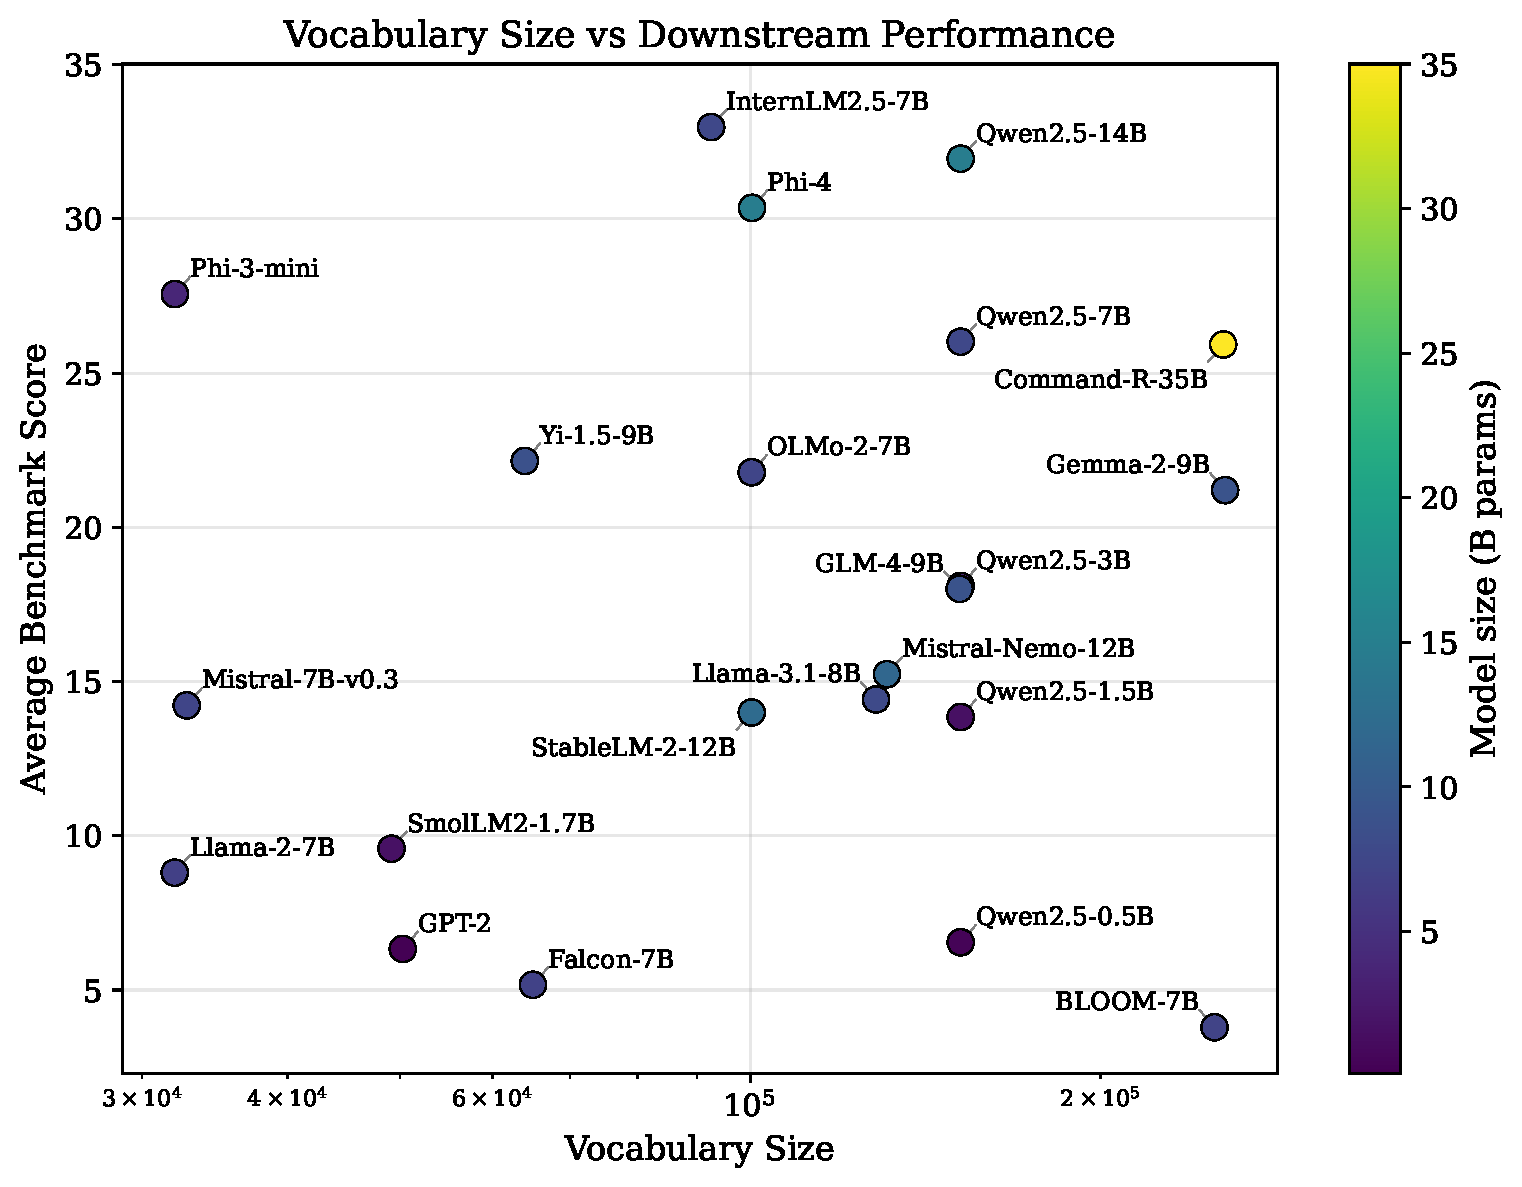
- No metric predicts English benchmark performance after controlling for model size (Bonferroni-corrected). Tokenizer quality does not drive English leaderboard scores.
- STRR significantly predicts multilingual performance. On MMLU-ProX, linear mixed-effects models show STRR has a large positive effect (β = +5.7, z = 18.5, p < 0.001).
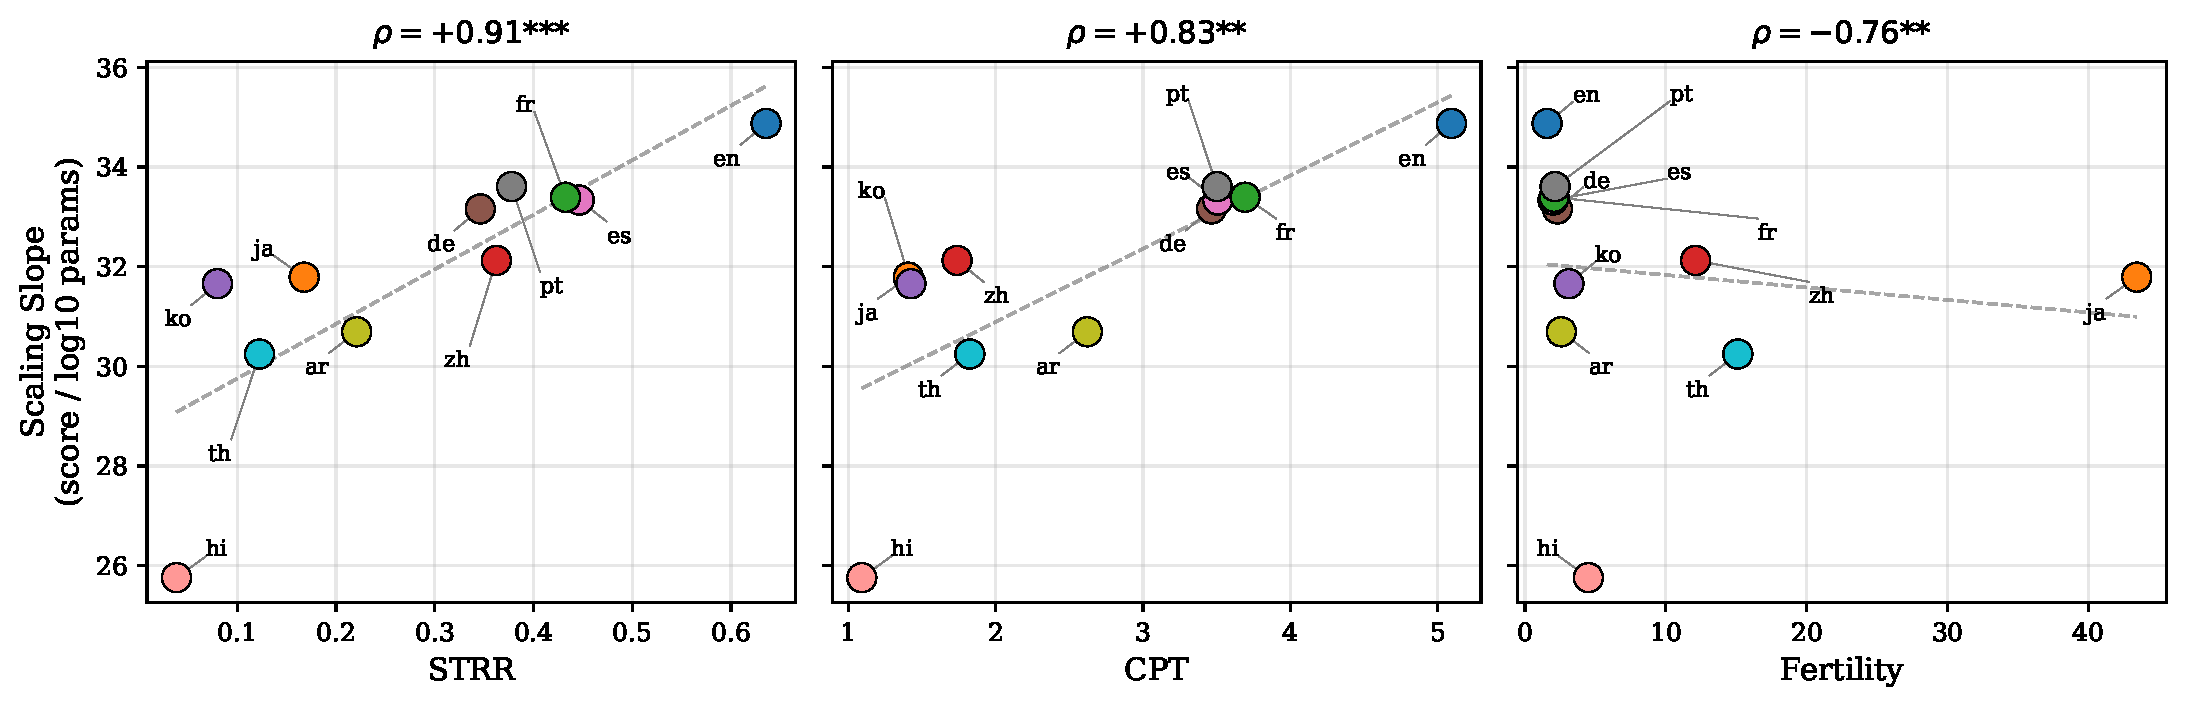
- Higher STRR correlates with steeper scaling. A controlled experiment on the Qwen2.5 family (fixed tokenizer, varying model size) shows languages with higher STRR scale more steeply (ρ = 0.91, p < 0.001).
Benchmark correlations
 |
 |
Per-language scaling slope vs. tokenizer metrics (Qwen2.5 family)
Metrics
| Metric | Description |
|---|---|
| Fertility | Tokens per whitespace-delimited word. Lower = better compression. |
| CPT | Characters per token. |
| Compression ratio | Bytes per token. |
| NSL | Normalized sequence length relative to a reference tokenizer. |
| STRR | Single-token retention rate. Fraction of words encoded as a single token. |
| Parity | Cross-lingual fairness: ratio of token counts for parallel English sentences. |
Models and Languages
22 models with Open LLM Leaderboard v2 scores, plus 2 extra tokenizers (Qwen3, DeepSeek-V3) for metric-only analysis.
15 languages across 6 scripts: English, Chinese, Japanese, Arabic, Hindi, German, Turkish, Korean, Thai, Russian, French, Spanish, Portuguese, Vietnamese, Indonesian.
Quickstart
pip install toklens
from toklens import Analyzer

analyzer = Analyzer.from_pretrained("meta-llama/Llama-3.1-8B")
report = analyzer.evaluate(langs=["en", "zh", "ja", "ar"])
report.print_table()
toklens eval meta-llama/Llama-3.1-8B --langs en zh ja ar
toklens compare meta-llama/Llama-2-7b-hf meta-llama/Llama-3.1-8B
Experiments
Reproduces the full evaluation. Run steps in order:
uv run python -m experiments.pipeline.01_collect_benchmarks
uv run python -m experiments.pipeline.02_compute_metrics
uv run python -m experiments.pipeline.03_correlation
uv run python -m experiments.pipeline.04_figures
Supplementary analyses (LME models, Qtok comparison, BPB, Qwen scaling) are in experiments/analyses/. See experiments/README.md for details.
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for toklens 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| toklens-0.1.2.tar.gz | 29.8 MB | Without provenance | Details for toklens-0.1.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| toklens-0.1.2-py3-none-any.whl | Python 3 | none | any | Details for toklens-0.1.2-py3-none-any.whl |
Total release size: 29.8 MB
Release files / toklens-0.1.2.tar.gz
| Download URL | toklens-0.1.2.tar.gz |
|---|---|
| Size | 29.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
84fe9c29fe9d28add14510235c20034fb20c0efebd85ded57e57db8e23212dba
|
|
BLAKE2b-256 checksum How to use checksums |
2ad5fac1ef1200e4ca425aeb584085b326d4f5a6868d339f6cef9818c6c60df6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.8
|
Release files / toklens-0.1.2-py3-none-any.whl
| Download URL | toklens-0.1.2-py3-none-any.whl |
|---|---|
| Size | 12.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
593af36edd754ef8494a1d992c4805e271bd98e196d793de4a3e82a72ce476e7
|
|
BLAKE2b-256 checksum How to use checksums |
48a8bdfa247dfcbf4a75b1850d188be09fbf6a1c5adf7c5cebb5d8757b8e2341
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.8
|
Security for toklens 0.1.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














