
Tokopaedi Async 🚀
High-performance, serverless-safe async Python scraper for Tokopedia.


tokopaedi-async is an asynchronous fork of Tokopaedi.
It talks to Tokopedia's internal GraphQL API through curl_cffi, which reproduces a real
iOS TLS/JA3 fingerprint, and pulls many products and reviews at once instead of one at a time.
It is built to run inside a function runtime as well as a long-lived process: importing the package has no side effects, each request owns its HTTP session, and every call has a timeout.
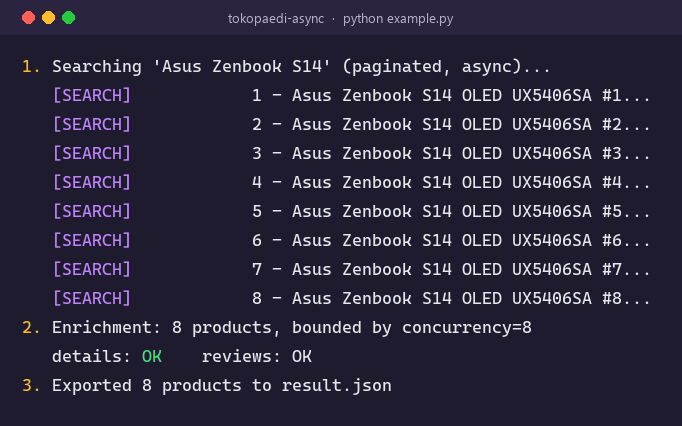
import asyncio
from tokopaedi_async import browse, SearchFilters

async def main():
    filters = SearchFilters(pmin=15_000_000, pmax=25_000_000, rt=4.5)
    results = await browse(
        "Asus Zenbook S14 32GB",
        max_result=10,
        filters=filters,
        reviews_per_product=20,
        concurrency=8,          # bounded fan-out
    )
    for product in list(results)[:3]:
        print(product.product_id, product.product_name, product.price_text)

asyncio.run(main())
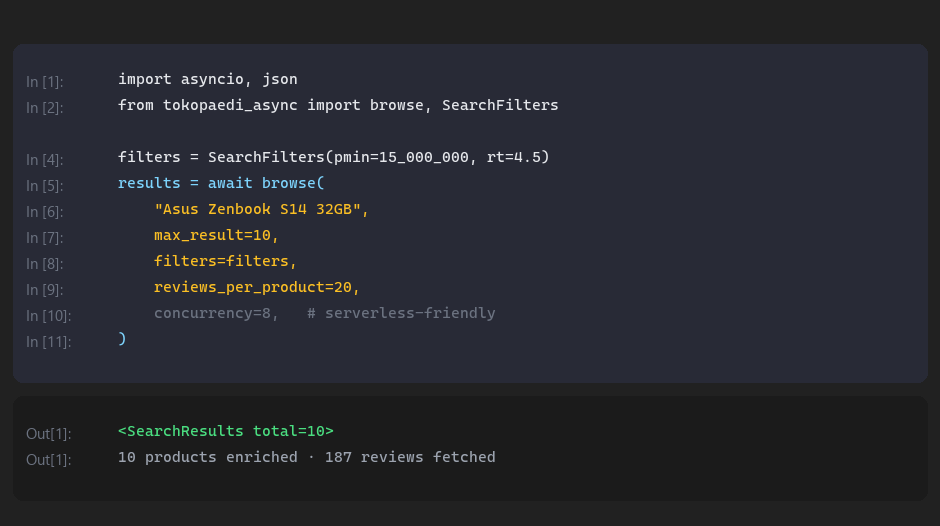
Table of contents
- Why this fork
- Installation
- Quick start
- Core concepts
- API reference
- Search filters
- Running on serverless (Vercel, Lambda, Cloud Run)
- Testing a scraper without the network
- Architecture
- Development
- Disclaimer
- Credits & license
Why this fork
The original library is synchronous: one product per call, one request at a time. Enriching 100 products meant 100 sequential round-trips.
This fork makes the network layer concurrent and puts a seam around it:
| Original | tokopaedi-async | |
|---|---|---|
| I/O model | requests, blocking |
curl_cffi.AsyncSession, non-blocking |
| Bulk enrichment | sequential loop ("one at a time") | asyncio fan-out with a semaphore |
| Pagination | recursion per page | one bounded loop |
| Failure mode | raised to the caller | logged, returned as data, batch survives |
| Testing | needs the network | offline via injected session |
The fingerprint handling (Fingerprint-Data, JA3/TLS) is unchanged — it is still what keeps
the requests looking like the real iOS app.
Installation
With uv (recommended — fastest, lockfile-aware):
uv add tokopaedi-async
With pip:
pip install tokopaedi-async
With Poetry:
poetry add tokopaedi-async
Requires Python 3.9+. The only runtime dependency is curl-cffi.
To run it once without adding it to a project:
uvx --from tokopaedi-async python -c "import tokopaedi_async; print(tokopaedi_async.__version__)"
Quick start
One call: search and enrich everything
browse() is the convenience path — it searches, then enriches each result in parallel.
import asyncio
from tokopaedi_async import browse, SearchFilters

async def main():
    results = await browse(
        "Asus Zenbook S14 32GB",
        max_result=10,
        filters=SearchFilters(pmin=15_000_000, rt=4.5, shop_tier=2),
        reviews_per_product=20,
        concurrency=8,
    )
    print(f"{len(results)} products")
    print(results.json()[0])          # plain dicts, ready for json.dump / pandas

asyncio.run(main())
Step by step
When you want to inspect the intermediate state — for example to filter cheaply on search results before paying for detail fetches — call the pieces yourself.
import asyncio
from tokopaedi_async import search, SearchFilters

async def main():
    # 1. Search. Cheap: one request per page, ~20 products per page.
    results = await search("Asus Zenbook S14 32GB", max_result=40,
                           filters=SearchFilters(rt=4.5))

    # 2. Narrow before enriching, so you don't fetch details you'll discard.
    keep = [p for p in results if p.rating and p.rating >= 4.7]
    print(f"{len(keep)} of {len(results)} kept")

    # 3. Enrich in parallel. Both calls return a list of failures, not raising.
    detail_failures = await results.enrich_details(concurrency=8)
    review_failures = await results.enrich_reviews(max_result=10, concurrency=8)
    print(f"{len(detail_failures)} detail failures, {len(review_failures)} review failures")

    # 4. Export.
    import json
    with open("result.json", "w", encoding="utf-8") as f:
        json.dump(results.json(), f, indent=2, ensure_ascii=False)

asyncio.run(main())
A single product
import asyncio
from tokopaedi_async import get_product, get_reviews

async def main():
    product = await get_product(product_id=123456789)
    # or: await get_product(url="https://www.tokopedia.com/shop/product-name")

    reviews = await get_reviews(product_id=product.product_id, max_result=50)
    print(product.product_name, product.price_text, len(reviews), "reviews")

asyncio.run(main())
Core concepts
Everything is async. await every network call: search, get_product, get_reviews,
browse, and the enrich_* methods. There is no synchronous fallback.
Paginated calls return the full page set, not the first page. search() and
get_reviews() keep requesting pages until max_result is reached or the API runs out of
results. The pagination loop is bounded (max_pages), so a cursor that never advances
cannot hang your process.
Enrichment is bounded and reports failures as data. enrich_details() and
enrich_reviews() fan out with an asyncio.Semaphore(concurrency). Each returns a list of
(item, exception) pairs for the items that failed — an empty list means everything
succeeded. Nothing is printed and nothing is swallowed, so one throttled request cannot
discard a batch of 100.
Extraction is separate from transport. Each scraper splits into a pure parser
(parse_search, parse_product, parse_reviews) and a network function. The parser is
what tests use.
Nothing happens at import time. No logging configuration, no session creation, no environment reads. This is what makes the package safe on a serverless host.
API reference
Full parameter and data-model reference: docs/API.md.
Network calls
| Function | Returns | Notes |
|---|---|---|
await search(keyword, max_result=100, filters=None, debug=False, session=None) |
SearchResults |
Paginated, deduped by product id. |
await get_product(product_id=None, url=None, debug=False, session=None) |
ProductData | None |
One PDP fetch. Returns None if the URL cannot be parsed or the request fails. |
await get_reviews(product_id=None, url=None, max_result=10, debug=False, session=None) |
List[ProductReview] |
Paginated. Resolves a URL to an id exactly once. |
await browse(keyword, max_result=20, filters=None, reviews_per_product=0, concurrency=10, session=None) |
SearchResults |
search + enrichment in one call. |
session is optional. Pass one to reuse connections in a long-lived process; omit it and
each request creates and closes its own session — the correct default on serverless.
Enrichment
failures = await results.enrich_details(concurrency=8)          # -> list[(item, exc)]
failures = await results.enrich_reviews(max_result=10, concurrency=8)
failures = await product.enrich_details()                        # single product
failures = await product.enrich_reviews(max_result=10)
Both are idempotent: a second call is a no-op once the data is attached. has_detail and
has_reviews record which enrichment has run.
Pure parsers (no network)
| Function | Input | Output |
|---|---|---|
parse_search(payload) |
decoded searchProductV5 response |
List[ProductData] |
parse_product(payload) |
decoded pdpGetLayout response |
ProductData | None |
parse_reviews(payload) |
decoded review-list response | List[ProductReview] |
These are the seams to test against. Capture a real response once, store it as a fixture, and assert on the dataclasses.
Data models
ProductData, ProductReview, TokopaediShop, ProductMedia, ProductVariant,
ProductOption — all @dataclass, all with .json() returning a plain dict.
SearchResults is the list-like container returned by search() and browse():
len(results)          # number of products
results[0]            # first product
for p in results: ... # iterate
results.json()        # list[dict]
results_a + results_b # concatenate
Search filters
Every SearchFilters field is optional; only the fields you set are sent to the API.
| Field | Type | Meaning |
|---|---|---|
pmin / pmax |
int |
Price range in IDR. |
condition |
int |
1 = new, 2 = used. |
shop_tier |
int |
2 = Mall / Official Store, 3 = Power Shop / Power Merchant. |
rt |
float |
Minimum average rating, 0.0–5.0. |
is_discount |
bool |
Discounted products only. |
bebas_ongkir_extra |
bool |
"Bebas Ongkir Extra" products only. |
is_fulfillment |
bool |
Fulfilled by Tokopedia only. |
is_plus |
bool |
Tokopedia Plus products only. |
cod |
bool |
Cash-on-delivery eligible only. |
latest_product |
int |
Product age in days: 7, 30, or 90. |
Unrecognised shop tiers resolve to None rather than being reported as "Normal", so a
missing badge does not become a wrong answer.
Running on serverless (Vercel, Lambda, Cloud Run)
A full working example lives in examples/serverless_app.py.
It is a FastAPI app that runs unchanged locally under uvicorn and on Vercel's Python
runtime.
uv add 'tokopaedi-async[serverless]'   # or: pip install 'tokopaedi-async[serverless]'
uvicorn examples.serverless_app:app --reload
curl "http://127.0.0.1:8000/search?q=zenbook&limit=5&reviews=10"
Four things make this work, and each is a deliberate property of the library:
1. No import-time side effects. A cold start is just an import. The package does not
call logging.basicConfig(), open sockets, or read configuration at import. Verify it
yourself:
import logging
before = (logging.getLogger().level, len(logging.getLogger().handlers))
import tokopaedi_async
after = (logging.getLogger().level, len(logging.getLogger().handlers))
assert before == after       # import changed nothing
2. Per-request sessions, closed deterministically. Do not cache a module-level
AsyncSession on serverless — the worker can be frozen or recycled between invocations,
and a session that outlives its event loop raises on reuse. The default (omit session=)
creates and closes one per request, on both the success and failure paths.
# Just omit session= on serverless.
results = await browse(q, max_result=20, concurrency=8)
3. Every request has a timeout. Serverless platforms kill the invocation, not the
socket; a hung read would otherwise consume the whole time budget. DEFAULT_TIMEOUT is 20
seconds. Lower it when your platform's limit is tighter.
4. Bound your work per invocation. Clamp max_result and concurrency from user
input so one caller cannot request 10 000 products and blow the function's time limit:
MAX_PRODUCTS = 40
MAX_REVIEWS = 20
CONCURRENCY = 8

limit = min(user_limit, MAX_PRODUCTS)
reviews = min(user_reviews, MAX_REVIEWS)
results = await browse(q, max_result=limit, reviews_per_product=reviews, concurrency=CONCURRENCY)
examples/serverless_app.py applies all four and returns plain JSON from results.json().
Vercel deployment — point vercel.json at the ASGI app:
{
  "builds": [{ "src": "examples/serverless_app.py", "use": "@vercel/python" }],
  "routes": [{ "src": "/(.*)", "dest": "examples/serverless_app.py" }]
}
Running on a platform with a short wall-clock limit (Vercel Hobby: 10s) means keeping
max_resultsmall or splitting the scrape across requests. The library's job is to make each request bounded and leak-free; the budget is yours to set.
Testing a scraper without the network
The point of the transport seam is that tests never hit Tokopedia. Write one fake session and drive the real pagination, dedupe, and merge logic through it.
import asyncio
import tokopaedi_async as t

class FakeResponse:
    def __init__(self, payload): self._payload = payload
    def json(self): return self._payload
    def raise_for_status(self): pass

class FakeSession:
    def __init__(self, responses): self.responses = responses; self.calls = 0
    async def post(self, url, headers=None, json=None, timeout=None):
        self.calls += 1
        return FakeResponse(self.responses[min(self.calls - 1, len(self.responses) - 1)])
    async def close(self): pass

def test_search_dedupes_across_pages():
    page = {"data": {"searchProductV5": {"header": {"additionalParams": None},
            "data": {"products": [{"id": 1, "name": "A", "url": "u", "mediaURL": {},
                                   "shop": {}, "badge": {}, "price": {}, "stock": {}}]}}}}
    results = asyncio.run(t.search("x", session=FakeSession([page])))
    assert [p.product_id for p in results] == [1]
For pure parser tests, no fake is needed at all — pass a captured payload straight to
parse_product / parse_search / parse_reviews.
The repository ships 35 such tests, all offline:
pytest              # 35 passed
pytest --cov=tokopaedi_async
Architecture
Seven small modules, one seam between "build a payload" and "send it".
src/tokopaedi_async/
├── transport.py       ← the seam: one POST, headers, fingerprint, session lifecycle, timeout
├── pagination.py      ← one bounded cursor loop, used by search and get_reviews
├── concurrency.py     ← one bounded fan-out, used by both enrich_* paths
├── search.py          ← search() + parse_search()
├── get_product.py     ← get_product() + parse_product()
├── get_reviews.py     ← get_reviews() + parse_reviews()
├── tokopaedi_types.py ← dataclasses, SearchResults, shop tier mapping
├── get_fingerprint.py ← randomized iOS device fingerprint
└── custom_logging.py  ← opt-in log levels; configures nothing on import
Each scraper is split the same way: a pure parser (fixture JSON → dataclasses) and a
network function (build payload → transport.post_graphql → parser). The pure half is
unit-testable; the network half is tested by injecting a fake session at the same seam.
If Tokopedia's response shape changes, the change is contained in one parser. If the
request shape changes, it is contained in one build_headers/payload pair.
Development
git clone https://github.com/pandamoon21/tokopaedi-async.git
cd tokopaedi-async
uv sync                    # creates .venv from uv.lock, incl. dev deps
uv run pytest
uv run python example.py   # hits the real API
Or with Poetry:
poetry install
poetry run pytest
poetry run python example.py     # hits the real API
The project uses PEP 621 metadata in pyproject.toml,
so uv sync, pip install ., and poetry build all read the same source of truth.
uv.lock is committed for reproducible dev environments.
Conventions:
- Async everywhere. All network functions are coroutines; never block the loop.
- Failures are values. Network functions log and return
None/[]/failure lists; they do not raise for a single bad request. Argument errors (ValueError) still raise. - Parsers stay pure. No I/O, no globals inside
parse_*. - No import-time side effects. Adding one breaks serverless safety — the test suite asserts the root logger is untouched after import.
Disclaimer
This is an unofficial library, not affiliated with, endorsed by, or supported by Tokopedia. It is intended for educational and research purposes. Use it responsibly and respect Tokopedia's Terms of Service.
Credits & license
- Original library by Hilmi Azizi.
- Async fork, serverless hardening, and the transport seam by pandamoon21.
- Distributed under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for tokopaedi-async 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| tokopaedi_async-0.2.2.tar.gz | 31.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| tokopaedi_async-0.2.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 62.9 kB
Release files / tokopaedi_async-0.2.2.tar.gz
| Download URL | tokopaedi_async-0.2.2.tar.gz |
|---|---|
| Size | 31.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
eb1a8e9d4a76c4d52b494b5163c6bab943a16e789121728c15aaf3f2c9ef6dbc
|
|
BLAKE2b-256 checksum How to use checksums |
11af9a280e4b959c07a66b80afa6407ba46bc960159afc0cfd1f32ba909f8cfc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.12
|
Release files / tokopaedi_async-0.2.2-py3-none-any.whl
| Download URL | tokopaedi_async-0.2.2-py3-none-any.whl |
|---|---|
| Size | 31.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
38f538abe95d9c1c11016c56339c057d3569464be64b85ee951419ed7ec4ef70
|
|
BLAKE2b-256 checksum How to use checksums |
b61cd2ed8fce09c76ec74e951add47f77a46cdf12b5ad9924b87a264b973fc2d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.12
|














