


This repository contains the torch implementation of an audio quality metric, logWMSE, originally proposed by Iver Jordal. In addition to the original metric, this implementation can also be used as a loss function for training audio separation and denoising models.
logWMSE is a custom metric and loss function for audio signals that calculates the logarithm (log) of a frequency-weighted (W) Mean Squared Error (MSE). It is designed to address several shortcomings of common audio metrics, most importantly the lack of support for digital silence targets.
Installation


pip install torch-log-wmse
Usage Example
import torch
from torch_log_wmse import LogWMSE

# Tensor shapes
audio_length = 1.0
sample_rate = 44100
audio_stems = 4 # 4 audio stems (e.g. vocals, drums, bass, other)
audio_channels = 2 # stereo
batch = 4 # batch size

# Instantiate logWMSE
# Set `return_as_loss=False` to resturn as a positive metric (Default: True)
# Set `bypass_filter=True` to bypass frequency weighting (Default: False)
log_wmse = LogWMSE(
    audio_length=audio_length,
    sample_rate=sample_rate,
    return_as_loss=True, # optional
    bypass_filter=False, # optional
)

# Generate random inputs (scale between -1 and 1)
audio_lengths_samples = int(audio_length * sample_rate)
unprocessed_audio = 2 * torch.rand(batch, audio_channels, audio_lengths_samples) - 1
processed_audio = 2 * torch.rand(batch, audio_channels, audio_stems, audio_lengths_samples) - 1
target_audio = torch.zeros(batch, audio_channels, audio_stems, audio_lengths_samples)

log_wmse = log_wmse(unprocessed_audio, processed_audio, target_audio)
print(log_wmse)  # Expected output: approx. -18.42
logWMSE accepts three torch tensors of the following shapes:
- unprocessed_audio:
[batch, audio_channels, samples] - processed_audio:
[batch, audio_channels, audio_stems, samples] - target_audio:
[batch, audio_channels, audio_stems, samples]
Each dimension being:
batch: Number of audio files in a batch (i.e. batch size).audio_channels: Number of channels (i.e. 1 for mono and 2 for stereo).audio_stems: Number of separate audio sources. For source separation, this could be multiple different instruments, vocals, etc. For denoising audio, this will be 1.samples: Number of audio samples (e.g. 1 second of audio @ 44.1kHz is 44100 samples).
Motivation
The goal of this metric is to account for several factors not present in current audio evaluation metrics, such as dealing with digital silence. Mean Squared Error (MSE) is well-defined for digital silence targets, but has its own set of drawbacks. Attempting to mitigate these issues, the following are some attributes of logWMSE:
- Supports digital silence targets not supported by other audio metrics. i.e. (SI-)SDR, SIR, SAR, ISR, VISQOL_audio, STOI, CDPAM, and VISQOL.
- Overcomes the small value range issue of MSE (i.e. between 1e-8 and 1e-3), making number formatting and sight-reading easier. It is scaled similarly to SI-SDR for consistency with current benchmark metrics (i.e. 3 is poor, 30 is very good).
- Scale-invariant, aligns with the frequency sensitivity of human hearing.
- Invariant to the tiny errors of MSE that are inaudible to humans.
- Logarithmic, reflecting the logarithmic sensitivity of human hearing.
- Tailored specifically for audio signals.
Frequency Weighting
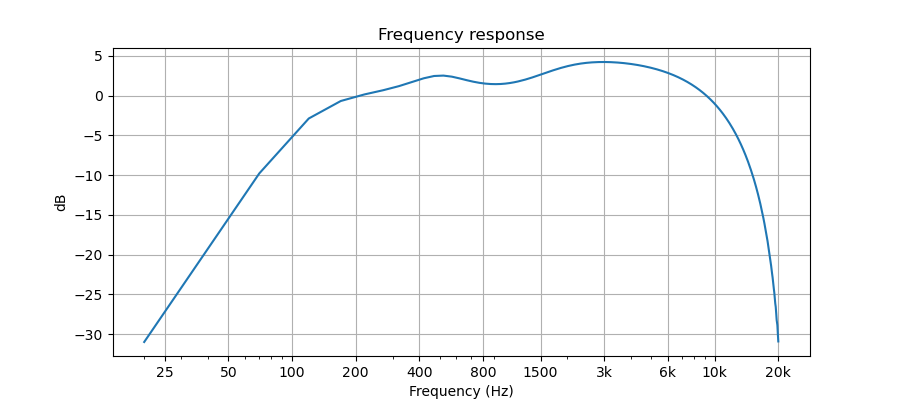
To measure the frequencies of a signal closer to that of human hearing, the following frequency weighting is applied. This helps the model effectively pay less attention to errors at frequencies that humans are not sensitive to (e.g. 50 Hz) and give more weight to those that we are acutely tuned to (e.g. 3kHz).
This metric has been constructed with high-fidelity audio in mind (sample rates ≥ 44.1kHz). It theoretically could work for lower sample rates, like 16kHz, but the metric performs an internal resampling to 44.1kHz for consistency across any input sample rates.
Inputs
Unlike many audio quality metrics, logWMSE accepts 3 audio inputs rather than 2:
- Unprocessed audio (e.g. raw, noisy audio)
- Processed audio (e.g. denoised or separated audio)
- Target audio (e.g. ground truth, clean audio)
Typically audio loss functions only use the processed audio and target audio to compare against one another. However, logWMSE requires the initial, unprocessed audio because it needs to be able to measure how well the processed audio was attenuated from the unprocessed version. This adds a factor that accounts for when the input contains silence (digital zero).
This also adds a factor of scale invariance in the sense that the processed audio needs to be scaled appropriately relative to both the unprocessed audio and ground truth. Conceptually, this means that if all 3 inputs are gained by the same arbitrary amount, the metric score will stay the same.
Limitations
- The metric isn't invariant to arbitrary scaling, polarity inversion, or offsets in the estimated audio relative to the target.
- Although it incorporates frequency filtering inspired by human auditory sensitivity, it doesn't fully model human auditory perception. For instance, it doesn't consider auditory masking.
Contributing
Contributions are welcome! Please open an issue or submit a pull request if you have any improvements or new features to suggest.
License
This project is licensed under the Apache License 2.0. See LICENSE for details.
1 maintainer

Metadata
1 maintainer
Release files for torch-log-wmse-audio-quality 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| torch_log_wmse_audio_quality-0.3.1.tar.gz | 44.0 kB | Without provenance | Details for torch_log_wmse_audio_quality-0.3.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| torch_log_wmse_audio_quality-0.3.1-py3-none-any.whl | Python 3 | none | any | Details for torch_log_wmse_audio_quality-0.3.1-py3-none-any.whl |
Total release size: 83.5 kB
Release files / torch_log_wmse_audio_quality-0.3.1.tar.gz
| Download URL | torch_log_wmse_audio_quality-0.3.1.tar.gz |
|---|---|
| Size | 44.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1589f87762c79a23cef01a4886597e0783edd81bcef09af65b5c3f57e140d20b
|
|
BLAKE2b-256 checksum How to use checksums |
2eaa47ce0ce139d5386d0cf1f779f55d6abcd018e2141474f50d6ca01a6c5086
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.18
|
Release files / torch_log_wmse_audio_quality-0.3.1-py3-none-any.whl
| Download URL | torch_log_wmse_audio_quality-0.3.1-py3-none-any.whl |
|---|---|
| Size | 39.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8155f3fdd96a52d9b5080d596b8a8bd1377fbdaedec367eeaf971a2243694dc5
|
|
BLAKE2b-256 checksum How to use checksums |
b7ef81e935ce4862ffe30b15317493d6ee13e9280ec5089e363727d296004448
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.18
|
Security for torch-log-wmse-audio-quality 0.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














