
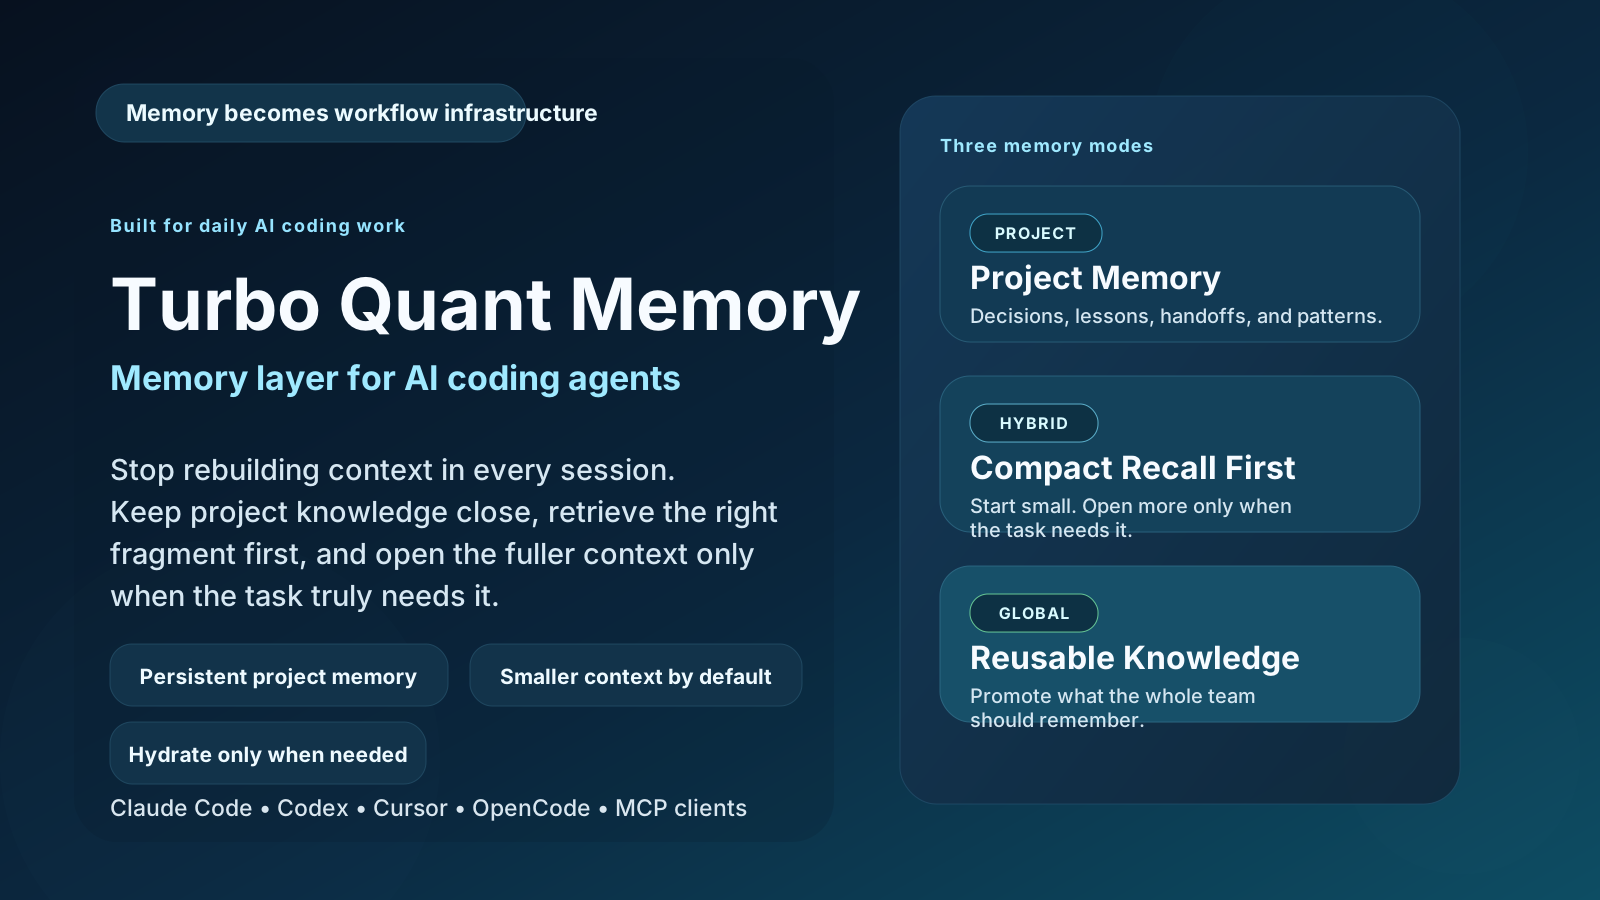
Local-first memory and knowledge graph for AI coding agents
Your agent stops re-reading files and re-deriving the same conclusions.
Your notes, code and secrets never leave your machine.




Demo
The problem
A long session accumulates hard-won detail about why the code is the way it is. Then the context compacts and it is gone. Next session the agent re-reads the same files, re-derives the same conclusions, and bills you for the same tokens again.
CLAUDE.md does not scale past a few dozen lines, and it cannot answer "what did we decide about X, and why?".
Turbo Quant Memory is an MCP server that gives the agent a persistent, searchable store it writes to while it works — decisions, lessons, patterns, session handoffs — plus a compact index of your Markdown. Retrieval returns ~220-character result cards rather than whole documents; the agent loads full content only when a card is not enough.
Why this one
| Turbo Quant Memory | mem0 / OpenMemory | MCP memory server |
|
|---|---|---|---|
| Where your data lives | your disk, always | vendor cloud or self-host | your disk |
| Your data leaves the host | never | yes, unless self-hosted | never |
| Retrieval | hybrid BM25 + dense vector, RRF-fused | dense vector | exact graph lookup |
| What a search returns | compact cards, hydrate on demand | full memories | full nodes |
| Knowledge graph | yes — with lifecycle + linting | no | yes |
| Non-English content | Cyrillic exact-match out of the box | varies | n/a |
| Measures its own savings | yes — server_info() |
no | no |
| Price | free, MIT | paid tiers | free |
No HTTP client, no telemetry, no phone-home. Verify it yourself — this returns nothing:
grep -rnE '^[[:space:]]*(import|from)[[:space:]]+(requests|httpx|aiohttp|urllib3)\b' src/
To be precise about the one exception: on first run fastembed downloads the embedding model (~0.22 GB) from Hugging Face. After that the server runs fully offline. Your notes, code and secrets are never transmitted anywhere — there is nothing in the package that could send them.
Install
Let your agent install it
Paste this into Claude Code, Codex, Gemini CLI, Cursor or Antigravity:
Install and configure the Turbo Quant Memory MCP server for this workspace from https://github.com/Lexus2016/turbo_quant_memory — follow the README, register the
tqmemoryserver, runturbo-memory-mcp skill install, run the health check, and index this project.
skill install copies an operating manual into every agent skill directory on the machine, so every future session already knows how to use the memory without being told.
Or install it yourself
uv tool install turbo-quant-memory
Upgrading from 0.27.x or earlier? The distribution was renamed in 0.28.0, so
uv tool upgrade turbo-memory-mcp no longer resolves — run
uv tool install --force turbo-quant-memory once, and uv tool upgrade turbo-quant-memory afterwards. The turbo-memory-mcp command itself is
unchanged, so client configs keep working.
Then register the server with your client:
claude mcp add --scope project tqmemory -- turbo-memory-mcp serve   # Claude Code
codex  mcp add tqmemory -- turbo-memory-mcp serve                   # Codex
gemini mcp add tqmemory turbo-memory-mcp serve                      # Gemini CLI
Cursor, OpenCode, Antigravity and other clients → CLIENT_INTEGRATIONS.md. Hermes runs MCP through a systemd gateway → docs/hermes.md.
📈 It measures its own savings — see for yourself
Turbo Quant Memory doesn't just claim to save tokens — every install keeps a running tally you can read anytime with server_info() (field usage_stats.headline). The savings are yours to verify, not ours to promise.
Live snapshot from a real developer instance (v0.28.2):
| What the memory did | Number |
|---|---|
| 🔢 Input tokens saved (cumulative) | ≈ 2,640,000 and counting |
| 🔁 Retrievals served | 2,280 searches + 280 deep hydrations |
| 📉 Average saved per retrieval | ≈ 1,200 tokens |
| 📚 Knowledge under management | 237 active notes + 763 indexed code blocks |
| 🛡️ Integrity | 0 corrupted records · 0 pending migrations |
These are one machine's cumulative numbers, not a synthetic benchmark — your own counter starts at zero and grows as your agent works. Run
server_info()on your install to see your real figure.
What it does
- Typed notes.
decision,lesson,pattern,handoff— each stored with tags, provenance and a knowledge-graph link to the file or issue it is about. - Tiered memory.
durable(decisions, patterns) andreference(indexed docs) are searched by default;episodic(session handoffs) stays out of the way until you ask for it, so yesterday's noise never buries an architectural decision. - Hybrid retrieval. A dense vector lane leads; a BM25 lane rescues exact terms — function names, file paths, IDs — fused with Reciprocal Rank Fusion. Cyrillic and other non-English terms match exactly, case- and accent-insensitive, with no configuration.
- Knowledge graph. Directed, timestamped relations between notes, files and issues. Search results carry the linked context inline, so the agent does not need a second lookup.
- Human notes outrank agent notes. Anything you explicitly asked to remember is flagged
human-explicitand ranks above the agent's own observations at equal relevance. - Encrypted secrets vault. Project-scoped, AES-256-GCM, structurally unreachable from search. → docs/secrets-vault.md
- Runs on a small machine. The default embedder is ONNX via fastembed — no PyTorch, ~0.22 GB model, comfortable on 2 GB of RAM.
- Several agents, one project — automatically. Agents working in the same git working tree see each other's sessions, announced work and recent file changes; while two or more of them share the tree, changes to text files are recorded so they can be restored. No setup.
Full technical detail → docs/features.md
Several agents in one project
If you run more than one agent in the same working tree, tqmemory connects them automatically. There is nothing to configure.
- Agents see each other.
workspace_statuslists the active sessions, what each one announced it is working on (announce_work,finish_work) and which files changed recently. A session that made no tqmemory call for 30 minutes is listed underidle_sessionsinstead: it is not an active peer and its announced areas are left out ofoverlaps. Other tqmemory responses carry a shortworkspacenote only when something new has happened, and never for a lone session.healthandserver_infoalways include a workspace diagnostics block. - Changes are recorded. While two or more sessions share a git working tree, the watcher records new versions of text files it sees change (up to 1 MiB each, skipping anything matched by
.gitignoreor.tqmemoryignore). Several quick writes in a row can be merged into one version.file_historylists the versions andrestore_filebrings one back; the restore is itself undoable. The same is available from a terminal:turbo-memory-mcp files logandturbo-memory-mcp files restore. - Limits. Versions are recorded only while two or more sessions share a git working tree. The journal never runs outside a git working tree, in your home directory or at a filesystem root. Defaults: 1 MiB per file, a 256 MiB per-project size target and 14 days of retention. Recorded versions stay recoverable for 14 days; past that, or when the project is over its size target, the oldest are removed. The newest version of each file changed in the last 24 hours is never dropped for size. These defaults are set by
TQMEMORY_JOURNAL_MAX_FILE_BYTES,TQMEMORY_JOURNAL_MAX_BYTESandTQMEMORY_JOURNAL_RETENTION_DAYS; the size limit is a target, not a hard maximum.
This is partial protection, not a guarantee that every change is saved. It does not block writes: two agents can still overwrite each other's work, and tqmemory can only show it and help you recover. Agents that never call tqmemory see nothing. It works on one computer only. To turn it off, set TQMEMORY_WORKSPACE_DISABLE=1.
Reuse one project's memory from another folder
For a temporary choice without a folder binding, call list_projects() and then select_project(project_id="<id>"). The current MCP connection uses that project's memory immediately. select_project() resets to automatic detection. Selection does not rewrite the project's original root or index local files. An explicit TQMEMORY_PROJECT_ID must not conflict with the selected ID.
list_projects() shows saved project IDs, names, display labels, original roots, and bound folders. The terminal equivalent is turbo-memory-mcp projects. To use an existing project's memory from a new folder, call bind_project(project_id="<id>", path="/absolute/new/folder"). The binding persists locally, and the current MCP connection switches to that folder immediately. server_info() confirms the resolved project. set_project_labels(project_id, labels=[...]) changes display labels; labels never determine identity. unbind_project(path="/absolute/new/folder") removes the exact binding.
Only existing project IDs can be bound. A binding does not index files in the new folder; call index_paths separately when you want that. Bindings are exact folders, so a nested repository is not silently captured. If a folder is replaced or its recorded Git origin changes, access fails until you explicitly rebind it. An explicit TQMEMORY_PROJECT_ID environment override still takes precedence.
Memory calls follow the selected folder; workspace_status, file_history, and restore_file still describe the MCP process's original working tree.
When restoring a storage snapshot on another machine, project notes, global notes, labels, and encrypted secrets move with the storage root. Local folder bindings contain the old machine's absolute paths; use select_project by ID and rebind folders on the new machine when needed. The secrets vault also requires its original passphrase or keyring key.
Automatic index maintenance
The primary storage-owning MCP process checks retrieval indexes immediately after startup and every six hours while it runs. It optimizes tables that have unindexed full-text rows or versions older than seven days. Work runs in the background under each project's in-process write lock; requests for that project may briefly receive a busy response while optimization holds the lock. Independent standalone or CLI writers are not covered by this lock; an optimization conflict is logged and retried on a later pass. Proxy clients and uncoordinated standalone fallback processes do not run maintenance. The source Markdown and canonical JSON notes are not changed. turbo-memory-mcp index-status reports table size, version age, and full-text coverage without modifying data.
LanceDB keeps recent versions for seven days, so optimization can temporarily increase disk use on an active table. Do not delete LanceDB files manually. If an older MCP process still owns the storage, restart its clients so the new process can become the owner and start maintenance.
The first full sync of a legacy table re-embeds its rows once. Later full syncs skip unchanged rows while the embedding model, backend, and backend version remain the same. Changing any of these rebuilds the vectors on the next full sync; scheduled maintenance alone does not re-embed them.
The 29 MCP tools
| Group | Tools |
|---|---|
| Write | remember_note · deprecate_note · promote_note · index_paths |
| Read | semantic_search · hydrate · recent_context · list_scopes · list_projects |
| Projects | select_project · set_project_labels · bind_project · unbind_project |
| Graph | link_entities · unlink_entities · get_related_entities |
| Hygiene | lint_knowledge_base · health · self_test · server_info |
| Vault | set_secret · get_secret · list_secrets · delete_secret |
| Workspace | announce_work · finish_work · workspace_status · file_history · restore_file |
Documentation
| MEMORY_STRATEGY.md | How to actually use the memory day to day |
| CLIENT_INTEGRATIONS.md | Per-client setup: Cursor, OpenCode, Antigravity, … |
| TECHNICAL_SPEC.md | Architecture and storage format |
| docs/features.md | Retrieval, graph, tiers, embedder, FTS language |
| docs/secrets-vault.md | Vault setup, threat model, FAQ |
| docs/hermes.md | Hermes gateway setup and troubleshooting |
| CHANGELOG.md | Release history |
License
MIT. Copy it, modify it, fork it, ship it inside a closed-source product, sell it. Attribution is the only condition.
Languages
🇺🇸 English · 🇺🇦 Українська · 🇷🇺 Русский
1 maintainer

Metadata
1 maintainer
Release files for turbo-quant-memory 0.36.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| turbo_quant_memory-0.36.0.tar.gz | 949.2 kB | With provenance | Details for turbo_quant_memory-0.36.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| turbo_quant_memory-0.36.0-py3-none-any.whl | Python 3 | none | any | Details for turbo_quant_memory-0.36.0-py3-none-any.whl |
Total release size: 1.2 MB
Release files / turbo_quant_memory-0.36.0.tar.gz
| Download URL | turbo_quant_memory-0.36.0.tar.gz |
|---|---|
| Size | 949.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
bfe9b6bce46c89363bfb9bd505d9df90fe81196ddd6dd3e7b7b76e0bcdf95aac
|
|
BLAKE2b-256 checksum How to use checksums |
c04fcfe8ea650318ad03439e0bb443b66cee39068aa1e00dbdea89171f80acdb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 9, 2026.
Transparency logRelease files / turbo_quant_memory-0.36.0-py3-none-any.whl
| Download URL | turbo_quant_memory-0.36.0-py3-none-any.whl |
|---|---|
| Size | 219.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
dc4a347fa31f254df135c18dc2aa9854f70736d57d53374dde438f2b40ad9ee4
|
|
BLAKE2b-256 checksum How to use checksums |
bb81289ba5a4cb9f014a532b58bc32af8b1399ae90b2d5ab06fcbceebf4b17a0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 9, 2026.
Transparency logSecurity for turbo-quant-memory 0.36.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for turbo_quant_memory-0.36.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 9, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














