
unalloc
Find the AI spend nobody owns. Joins OpenCost allocation data with LLM provider bills and reports what's unattributed.



Project site: timurista.github.io/unalloc, with the findings, case studies, paper (arXiv:2609.24991), blog post, GPU addendum and ledger explorer.
OpenCost tells you what your Kubernetes workloads cost. Your provider dashboard tells you what your OpenAI and Anthropic calls cost. Getting both into one view is possible today — OpenCost has an OpenAI plugin — but the answer still depends on a join nobody checks: the same dollar can arrive through both your gateway and your provider bill, and the labels that say who owns it are set per workload, not per pod template. unalloc pulls all four sources into one normalized ledger, joins them on a label dimension you choose, and reports the number your finance team keeps asking for: how much of this month's AI spend can't be attributed to any team — and how much of the rest was only rescued by a fallback key.
Avoid double counting before interpreting totals. By default, the CLI requests all four sources: OpenCost, LiteLLM, OpenAI and Anthropic. It appends their normalized
CostRows into one ledger; it does not automatically deduplicate the same economic spend across sources. Gateway charges can also appear in provider bills (or OpenCost plugin output). Choose non-overlapping sources for your setup. For traffic fully covered by LiteLLM, use--source opencost --source litellmonly if OpenCost excludes those same provider charges. Direct-provider-only traffic needs a separate coverage plan. Fixture totals below are synthetic demonstrations, not validated unique spend.
The output
$ unalloc report --fixtures --dimension team

╭──────────────────────────── unalloc ─────────────────────────────╮
│ 73.5% of $66,630.38 AI spend is unattributed                     │
│ $48,983.14 has no 'team' label                                   │
╰──────────────────────────────────────────────────────────────────╯

                        Spend by team
┏━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━┳━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━┓
┃ team            ┃        Cost ┃ Share ┃ Sources                               ┃ Rows ┃
┡━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━╇━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━┩
│ platform        │  $13,166.02 │ 19.8% │ litellm, opencost                     │    2 │
│ search          │   $4,481.22 │  6.7% │ litellm, opencost                     │    2 │
│ <unallocated>   │  $48,983.14 │ 73.5% │ anthropic, litellm, opencost, openai  │   11 │
└─────────────────┴─────────────┴───────┴───────────────────────────────────────┴──────┘
Then the actionable half: a labeling backlog sorted by dollars.
$ unalloc labels --fixtures --dimension team

      Labeling backlog — rows missing 'team', by cost
┏━━━━┳━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃  # ┃ Source   ┃ Cost object               ┃       Cost ┃ Labels it does have        ┃
┡━━━━╇━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━┩
│  1 │ opencost │ inference/vllm-llama-70b  │ $19,147.10 │ cluster, controller, ...   │
│  2 │ opencost │ __idle__                  │  $6,070.00 │ cluster                    │
│  3 │ litellm  │ claude-opus-5             │  $5,412.75 │ environment, model         │
└────┴──────────┴───────────────────────────┴────────────┴────────────────────────────┘
inference/vllm-llama-70b is the whole pitch: $19K of GPU spend carrying a costCenter label but no team, sitting next to $5K of Claude API spend on an unlabeled legacy key. Two systems, one gap, no existing tool that shows them in the same table.
Add a fallback and unalloc says how much of the "allocated" spend only got there through it, so a fallback onto something that is not an owner can't hide inside the headline:
$ unalloc report --fixtures -D team --fallback namespace
│ 37.9% of $66,630.38 AI spend is unattributed                     │
│ $25,237.54 has no 'team' label                                   │
│ $23,745.60 attributed only via fallback (namespace)              │
Install
pip install unalloc          # or: uv tool install unalloc
unalloc report --fixtures    # works immediately, no infrastructure needed
From a clone:
make dev      # editable install with test + lint tooling
make demo     # all three commands against bundled fixtures
make check    # ruff + pytest, same as CI
Or as a container, which needs no Python on the host:
docker build -t unalloc:0.2.0 .
docker run --rm unalloc:0.2.0 report --fixtures -D team

# against real systems, reachable from the container
docker run --rm --network host --env-file .env unalloc:0.2.0 report -D team
Copy .env.example to .env for the source configuration. unalloc stores
nothing: no database, no state directory, no cached credentials.
Usage
# What percentage of spend has no owner?
unalloc report --dimension team --days 30

# Accept a second-best key before declaring a row unallocated
unalloc report -D team --fallback namespace --fallback cost_center

# Fail a CI job when more than 10% of spend is unowned
unalloc report -D team --budget 10

# Which label keys does my data actually have?
unalloc labels --available

# The backlog honours the same fallbacks as the report
unalloc labels -D team --fallback namespace

# Does the ledger tie out to the invoice?
unalloc reconcile --invoice openai=4031.36 --invoice anthropic=8737.03

# Pipe it into something else
unalloc report --json | jq '.unallocated_pct, .fallback_usd'
Configure sources by environment variable:
| Variable | Purpose |
|---|---|
UNALLOC_OPENCOST_URL |
OpenCost API root, e.g. http://opencost.opencost:9003 |
UNALLOC_LITELLM_URL |
LiteLLM proxy root |
UNALLOC_LITELLM_KEY |
LiteLLM master or admin key |
OPENAI_ADMIN_KEY |
OpenAI org admin key (costs endpoint) |
ANTHROPIC_ADMIN_KEY |
Anthropic org admin key (cost report endpoint, sent as x-api-key) |
UNALLOC_OPENAI_URL, UNALLOC_ANTHROPIC_URL |
Optional overrides for the public API roots, e.g. a proxy |
Restrict the run with --source to avoid double counting: if LiteLLM covers all provider traffic and OpenCost excludes overlapping provider charges, use --source opencost --source litellm and skip the direct provider adapters. Confirm coverage and overlap for your setup. The end-to-end case study demonstrates the resulting double count with synthetic billing and invoices; it does not measure customer savings.
The case-study invoices and monthly cost pools are synthetic or illustrative. The GPU result covers one H100, one model and one two-minute run per load; waiting-request telemetry was sampled about every 0.5 seconds. Allocation-rule disagreement does not establish a uniquely correct charge or production savings.
Reproducing a result
A percentage that ends up in a finance deck will be questioned later, after the
source data has moved on. A path is not enough to answer that: a fixture or an
export can be rewritten under the same name, and a live billing API answers a
re-run with today's data. So report --json carries a provenance block, and
--keep-inputs retains the exact payloads it parsed:
unalloc report -D team --json --keep-inputs runs/2026-09/ > runs/2026-09.json
unalloc verify runs/2026-09.json --inputs runs/2026-09/
# reproduced: 73.5% unallocated of $66,630.38, result sha256:…
The provenance block records the unalloc version, the window (live runs only;
fixtures carry their own dates), a digest of the label alias table, and one
entry per requested source: its status, the SHA-256 of the payload bytes, and
the rows it produced. A source that failed or had no input is recorded as
failed or missing rather than dropped, and every command warns on stderr
when the ledger is partial, because the percentage then covers the loaded
sources only.
verify exits with a code that says which boundary moved:
| Exit | Meaning |
|---|---|
| 0 | Reproduced: same inputs, same result digest |
| 3 | Cannot reconstruct: a retained input is missing, or its bytes changed |
| 4 | Inputs match but the result differs: a rule or the tool changed in between |
| 5 | The recorded result does not conserve its own total (a dollar counted twice or dropped) |
A digest proves byte identity, not correctness. It cannot tell you a meter was accurate or a rule was fair, and it can only rebuild a result when the bytes it names were kept. Retained payloads contain your billing data; store them like the invoices they came from.
How it works
  OpenCost /allocation ─┐
  LiteLLM /spend/logs  ─┤
  OpenAI  org costs    ─┼──▶ normalize (label canonicalization + aliases)
  Anthropic cost report ┘              │
                                       ▼
                                    CostRow[]
                                       │
                      ┌────────────────┼────────────────┐
                      ▼                ▼                ▼
                  attribute        reconcile          labels
              (unallocated %)   (vs invoice)     (backlog by $)
Everything rests on one dataclass. An adapter's only job is turning a provider payload into CostRows; it never aggregates, filters or decides anything about attribution. Adding a provider is one file and one fixture.
Two design choices worth calling out:
Money is Decimal, never float. Attribution that disagrees with the invoice by a cent per row is how you lose an argument with finance.
Label canonicalization is the actual hard part. OpenCost gives you label_costCenter. LiteLLM gives you team_id or a team:platform request tag. OpenAI gives you a project ID. None of those join on a naive dict lookup, so every adapter runs its labels through normalize.py first, which strips provider prefixes (repeatedly, so label_app_kubernetes_io_name and app.kubernetes.io/name agree), converts camelCase, and applies an alias table you can extend per-org. When two raw keys land on the same canonical key, a fixed precedence decides - explicit key, then alias, then rewritten key, then path-derived key - so the result never depends on the order a provider serialized its labels in.
Case studies and paper
Six studies push real (or realistically simulated) inference workloads through unalloc's own adapters, including a run with vLLM on an NVIDIA H100. They exposed nine defects in the tool along the way, all fixed with regression tests, and they're written up as a paper: Who Pays for the KV Cache? (arXiv:2609.24991), a preprint that has not been peer reviewed. The PDF built from this repository is at paper/unalloc-case-studies.pdf. For the readable version, see the blog post and the GPU addendum on the project site.
| Study | What runs | Headline |
|---|---|---|
kv_cache |
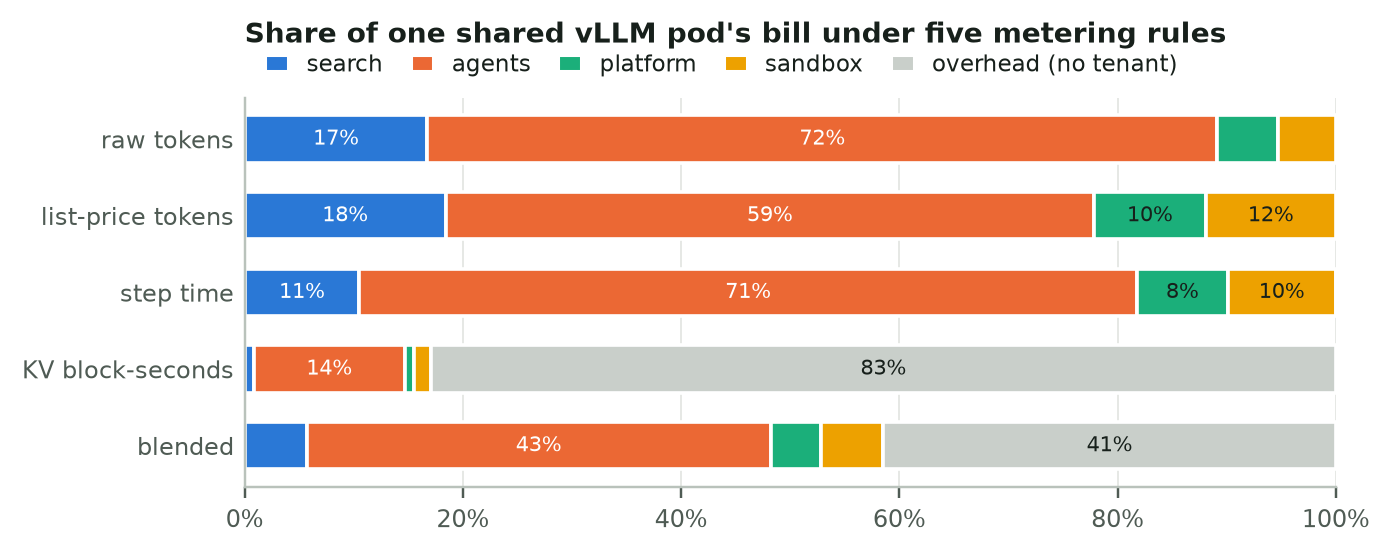
Discrete-event vLLM-style engine: paged KV blocks, prefix caching, continuous batching, preemption | Step-time metering shows ~0% idle once any request is in flight; KV-memory metering leaves a large share of the bill unowned |
torch_kv |
A from-scratch PyTorch decoder with a real KV cache serving a 4-tenant trace | Token and measured-compute allocation rules differ by 33 points for a RAG tenant ($5.7K of an illustrative monthly pool) |
distributed |
Tensor and pipeline parallel on torch.distributed (gloo), verified against a single-process reference |
Owner label on LeaderWorkerSet leaders only: 66% unallocated; falling back to name "fixes" it by sending 61% to a Helm chart name |
hybrid_e2e |
The real CLI as a subprocess against live mock OpenCost / LiteLLM / OpenAI / Anthropic APIs (Postgres-backed LiteLLM in the dev container) | Enabling every source double counts $11.8K; reading only page one of the billing APIs reports 25% of spend |
use_cases |
Labeling Pareto, per-feature unit economics, self-host break-even, CI budget gate | Three label fixes take a 67%-unallocated org under 10% |
gpu_validation |
Real vLLM 0.29 serving Qwen2.5-7B on a DigitalOcean H100, driven with the simulator's tenants (runbook, evidence) | Token and equal time-share allocation rules differ by 12–14 points for search; GPU "utilization" reads 97% at 2 req/s and 99% at 16 req/s |
make research            # build ./.venv-research: CPU torch, notebook tooling, typst
                         # (the targets below find it on their own; or pass PY=...)
make case-studies        # all five, full size (a few minutes)
make paper               # figures + PDF
make notebook            # execute case_studies/unalloc_case_studies.ipynb
make ui                  # ledger explorer on http://127.0.0.1:8765
The ledger explorer (or python -m case_studies.ui locally) shows every dataset row by row: pick the label that means "owner", add fallbacks, and watch each row resolve to a team, a fallback value, or the backlog. python -m case_studies.ui --export explorer.html writes a self-contained copy you can share.
Development environment
An isolated dev stack lives in .devcontainer/: a Python 3.11 workspace with the case-study dependencies (CPU-only PyTorch) and a small Postgres that backs the mock LiteLLM spend-log store. Open the folder in VS Code's Dev Containers, or from a terminal:
make devcontainer          # docker compose up
make devcontainer-check    # lint, tests and every case study at smoke size, inside the container
Scope, and what this is not
OpenCost 1.121.0 added inference cost tracking for vLLM and llm-d deployments: cost per million tokens, KV-cache-corrected pricing, shared infrastructure attribution. That is excellent and unalloc does not reimplement it. Those rows arrive through the same /allocation shape and land in this ledger tagged unalloc_layer=inference.
OpenCost can also bring external provider spend alongside Kubernetes cost through its plugin interface, including an OpenAI plugin announced in November 2024. So "Kubernetes cost and provider cost in one place" is not a gap unalloc invented, and it is not the claim here.
What unalloc does is narrower: read all four sources yourself — OpenCost, a LiteLLM gateway, and the OpenAI and Anthropic billing APIs directly — and answer one question about the join. Which dollars carry no owner, which were rescued only by a fallback key that may be pointing at a Helm chart rather than a team, and which arrived twice because the gateway and the provider both reported them. That is the seam it lives in, and nowhere else. It is:
- not a dashboard — it prints a number and exits (the explorer is a case-study companion, not part of the CLI)
- not an optimizer — it makes no recommendations about rightsizing or commitments
- not a collector — it queries systems you already run, and stores nothing
Roadmap
- Prometheus exporter so
unalloc_unallocated_ratiocan be alerted on - OpenCost external-cost plugin, so LLM API spend appears natively in OpenCost
- Per-feature unit economics using the
quantity/unitfields already carried onCostRow - Azure OpenAI and Bedrock adapters
-
--budgetmode: exit non-zero when unallocated share crosses a threshold, for CI - Result provenance and
unalloc verify: rebuild an earlier report from retained inputs, or say why it can't be -
--exclude label=valueon a source, so gateway traffic can be dropped from provider billing instead of whole sources - Warn when distinct raw label keys collide on one canonical key
Contributing
Adding a source is deliberately small: implement parse() on a Source subclass, add a fixture to src/unalloc/fixtures/, add a case to tests/test_sources.py. The fixtures are the contract, so a PR with a real (scrubbed) payload from a provider is valuable even without the adapter.
pip install -e ".[dev]"
ruff check . && pytest
Citing
If you use the findings, please cite the paper, a preprint on arXiv (arXiv:2609.24991, cs.DC):
@misc{urista_kvcache_2026,
  author        = {Urista, Timothy},
  title         = {Who Pays for the {KV} Cache? Attributing Shared {AI} Inference Spend Across {Kubernetes} and {LLM} Provider Bills},
  year          = {2026},
  eprint        = {2609.24991},
  archivePrefix = {arXiv},
  primaryClass  = {cs.DC},
  doi           = {10.48550/arXiv.2609.24991},
  url           = {https://arxiv.org/abs/2609.24991}
}
If you use the software itself, cite the archived release. GitHub's "Cite this repository" button produces the same entry from CITATION.cff.
- All versions: doi:10.5281/zenodo.22761012, which always resolves to the latest release — currently 0.3.0. The paper describes 0.2.3; 0.3.0 adds result provenance and
unalloc verifyand changes no attribution result - Version 0.2.1: doi:10.5281/zenodo.22761013
@software{urista_unalloc_2026,
  author  = {Urista, Timothy},
  title   = {unalloc: find the AI spend nobody owns},
  version = {0.3.0},
  year    = {2026},
  doi     = {10.5281/zenodo.22761012},
  url     = {https://github.com/timurista/unalloc}
}
License
Apache 2.0, matching OpenCost.
1 maintainer

Metadata
1 maintainer
Release files for unalloc 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| unalloc-0.3.1.tar.gz | 44.7 kB | With provenance | Details for unalloc-0.3.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| unalloc-0.3.1-py3-none-any.whl | Python 3 | none | any | Details for unalloc-0.3.1-py3-none-any.whl |
Total release size: 84.4 kB
Release files / unalloc-0.3.1.tar.gz
| Download URL | unalloc-0.3.1.tar.gz |
|---|---|
| Size | 44.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3b6e501f7364f1de610e4e03aa779bc19a138294305273a4567e09c995a92efb
|
|
BLAKE2b-256 checksum How to use checksums |
473fc91653037fd9ff8f12fa929fbd8b4177c1ad33c7d103b94019ba4beff6a4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency logRelease files / unalloc-0.3.1-py3-none-any.whl
| Download URL | unalloc-0.3.1-py3-none-any.whl |
|---|---|
| Size | 39.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ff165f4a039c9ef33cc30f1a9f09687eb46d25e6b4e6cad0ab92760720dc0424
|
|
BLAKE2b-256 checksum How to use checksums |
64a1e6f9480cf1e1caed607dc73fee1cbe1d9c29a1b7948668ec5362ad5a8243
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency logSecurity for unalloc 0.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for unalloc-0.3.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 5, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














