
UnlimitedPipe



Pipe the public internet.
Collect public web data, transform it, detect what changed, and send it anywhere, from the command line. Local-first, no account, no API key, no AI required. Think Yahoo Pipes, rebuilt as Unix commands.
See it running: 26 free feeds (AI releases, exploited vulnerabilities, cloud incidents, earthquakes, rocket launches…), each one a YAML file of about 15 lines, updated hourly on GitHub Actions. Fork them.
Install and set everything up with one command (it asks before each step):
curl -fsSL https://raw.githubusercontent.com/Fuyuki0/unlimitedpipe/main/install.sh | sh
It installs the unlimited command and runs unlimited setup, which adds what this machine can
use: the browser for JavaScript pages, a local AI model sized for its memory, the tools and skill
for Claude Code, and an offline copy of the feed catalog. Already have Python? pip install unlimitedpipe, then unlimited setup.
unlimited web https://example.com
unlimited web https://example.com | unlimited select title url | unlimited json
unlimited rss https://hnrss.org/frontpage | unlimited grep AI | unlimited diff --only added
unlimited search "cyber attack"          # search 75+ live public-record feeds at once
unlimited ask "what is the weather in Bangkok?"   # answered from the feeds, with sources
unlimited mirror && unlimited search flood --catalog offline   # works offline
What is UnlimitedPipe?
A small set of Unix-style commands that pass events to each other:
SOURCE  ->  EVENTS  ->  OPERATORS  ->  OUTPUT
web         JSONL       filter         json, jsonl, csv
rss                     select         feed (RSS / Atom / JSON Feed)
file                    diff           your terminal
...                     ...            any tool that reads JSONL
Every event is one line of JSON that records what was observed, where, when, how it was
fetched, and every step that touched it. Pipes work with jq, grep, head and friends.
The same components run from a YAML file with unlimited run.
Why?
Everyone who works with the web has written the same throwaway script: fetch a page, pull out a few values, compare with last time, send a notification. UnlimitedPipe is that script, done once and done well:
- Change detection built in.
diffremembers what it saw and emits only what was added, removed or modified, field by field. - Reads the most reliable layer first. Product data from Shopify, schema.org JSON-LD or OpenGraph before any CSS selector. Feeds before HTML.
- Provenance on every event. Source URL, observation time, fetch method, and each operator that transformed it.
- Polite by default. robots.txt (RFC 9309), one request per second per host,
ETag/If-Modified-Sincerevalidation, an honest User-Agent. - Composable. JSONL in, JSONL out. Plain JSON from other tools is accepted too.
- Extensible. A connector is one small Python class;
pip installmakes it a command.
How it compares:
- Yahoo Pipes (2007–2015) had the right idea: wire feeds and pages together, filter them,
get a feed out. It was a hosted app, and it died with its host. UnlimitedPipe is the same
idea as local commands and text files you own;
publishhosts the result for free on GitHub. - Huginn and n8n are always-on servers with a database and a web UI. UnlimitedPipe needs neither: a pipeline is a YAML file, state is a small JSON file, and a schedule is cron or GitHub Actions.
- RSS-Bridge and RSSHub turn sites into feeds with a server and one bridge per site. UnlimitedPipe reads what sites already publish (feeds, JSON APIs, product data), filters and merges it, and writes feeds as one output among several.
- changedetection.io and paid monitors are apps.
diffgives the same field-level change detection as a pipe stage you can combine with anything. curl | jqhas no memory, no politeness and no change detection. Firecrawl and similar crawlers turn pages into text for LLMs; UnlimitedPipe turns public sources into typed events with history and receipts.
Quick start
pip install unlimitedpipe # Python 3.11+
Look at a page. In a terminal you get readable output; in a pipe you get JSONL.
unlimited web https://example.com
See what a site offers and the best way to read it:
unlimited inspect https://news.ycombinator.com
Hacker News
https://news.ycombinator.com  ·  200  ·  text/html  ·  76 ms
✓ robots.txt    allowed
✗ JSON-LD       none
✗ Products      no product data
✗ OpenGraph     none
✓ Feeds         https://news.ycombinator.com/rss
✗ Sitemap       none found
✓ Readable HTML 666 words without JavaScript
Try:
  unlimited rss https://news.ycombinator.com/rss
  unlimited web https://news.ycombinator.com
  unlimited web https://news.ycombinator.com --selector 'h2'   # pick exact elements
Watch a product. The first run saves a baseline; later runs print only changes.
unlimited web https://www.allbirds.com/products/mens-strider-explore | unlimited diff
Or let UnlimitedPipe write the watch for you, then keep it running:
unlimited new https://www.allbirds.com/products/mens-strider-explore
# Wrote allbirds-com-products-mens-strider-explore.yml: price and stock changes (product data via shopify).
unlimited watch --every 1h allbirds-com-products-mens-strider-explore.yml
new picks the most reliable approach it finds: product data for store pages, the feed for
blogs and news sites, and page text otherwise, with commented hints for narrowing it down.
Sources
| Command | Emits |
|---|---|
unlimited web URL... |
A document per page (title, description, headings, text, feeds). Pages with product data become one product per variant. --selector CSS emits elements, --field NAME=CSS builds records, --emit links emits links. --browser renders pages that need JavaScript first (optional extra), --screenshot DIR keeps a picture of each page as evidence. |
unlimited rss URL... |
One entry per item of an RSS, Atom or JSON Feed. Given a page, uses the feed it advertises. |
unlimited file PATH... |
One record per JSON item, JSONL line or CSV row. - reads stdin. |
unlimited github releases|repo|tags|commits|issues OWNER/REPO... |
Public GitHub data through the official REST API. Optional GITHUB_TOKEN for higher limits. |
unlimited mastodon tag:NAME|@user|trending |
Public Mastodon posts through the open API, no key. |
unlimited telegram CHANNEL... |
Posts of public Telegram channels, from their public web preview. |
unlimited youtube videos|search ... |
Videos through the official YouTube Data API (free key: YOUTUBE_API_KEY). |
unlimited reddit r/NAME... |
Posts through Reddit's official API with your own free app (REDDIT_CLIENT_ID, REDDIT_CLIENT_SECRET). |
unlimited x search|posts ... |
Posts through X's official API with your own key (X_BEARER_TOKEN; reading needs a paid plan). |
unlimited bluesky [WORDS...] |
New public Bluesky posts, live, from Bluesky's Jetstream (endless; pip install "unlimitedpipe[live]") |
unlimited sec insider-trades |
Insider purchases and sales as they are filed with the SEC: who, their role, shares, price and total value. Needs a contact email (--contact or SEC_CONTACT), as the SEC asks. |
unlimited sec activist-stakes |
New Schedule 13D filings: which investor disclosed 5% or more of which company. |
unlimited search WORDS... |
Items from every feed of a published catalog that mention all the words, in one request (default catalog: feeds.daemonfill.dev). --list-feeds lists its feeds. |
unlimited ask QUESTION |
An answer to a question from a feed catalog, explained by a local model (Ollama) or Claude from numbered sources, which are always listed with their links. Optional: see Ask. |
unlimited inspect URL... |
An inspection: robots.txt, feeds, JSON-LD, products, sitemap, JavaScript, suggested commands. |
Sources also read URLs from stdin, so crawls compose:
unlimited web https://blog.example.com --emit links | unlimited grep 2026 | unlimited web
Insider trades read like news, straight from the filings:
$ unlimited sec insider-trades --min-value 500000
LENNAR CORP (LEN): Berkshire Hathaway Inc (10% owner) bought 1,679,700 shares at $81.19 ($136.4M)
PubMatic, Inc. (PUBM): Rajeev K. Goel (CHIEF EXECUTIVE OFFICER, director, 10% owner) sold 50,453 shares at $18.45 ($930.6K)
Public GitHub data comes through the official API, no account needed:
unlimited github releases astral-sh/uv ollama/ollama --limit 3
unlimited github repo pallets/click | unlimited select title stars forks
Operators
| Command | Does |
|---|---|
select title price=offers.0.price link=link|url |
Keep, rename, or fall back between fields |
filter 'price > 100 and availability == "InStock"' |
Keep matching events (syntax) |
filter --field country --eq Thailand |
The same without expression syntax |
map 'price=number(price)' --drop junk |
Set fields from expressions, drop fields |
grep AI LLM |
Keep events mentioning any word (whole words, any case) |
dedupe --by url |
Drop repeats within the stream |
sort --by published_at -r |
Sort (reads the whole stream) |
limit 20 |
First N events, then stop upstream |
diff |
Only what changed since the last run |
extract hashtags|cashtags|domains|words|REGEX |
Pull matches out of text into a list |
count --by tags --every 10m |
Count per value, overall or per time window |
trend |
Values rising sharply compared with earlier windows |
Fields are looked up in data first, then in the envelope (source_url, metadata.status).
Outputs
| Command | Writes |
|---|---|
jsonl [PATH] |
Full events, one per line (--data for data only) |
json [PATH] |
One JSON array of data (--full for whole events) |
csv [PATH] |
Data as CSV, nested fields as dotted columns |
feed PATH |
RSS (.xml), Atom (.atom) or JSON Feed (.json), keeping earlier items |
webhook URL |
A Discord or Slack message per event (recognized from the URL), or the event as JSON |
sqlite FILE |
One row per distinct observation, with JSON columns for SQL queries |
pretty |
Readable terminal output (the default when stdout is a terminal) |
Pipelines
The same components, in one process, from a file:
# competitor-watch.yml
name: competitor-watch

sources:
  - type: web
    url: https://competitor.example/pricing
    each: .plan
    field: [name=.plan-name, price=.price]

operators:
  - type: diff
    key: name

outputs:
  - type: feed
    path: public/competitor.xml
  - type: pretty
unlimited run competitor-watch.yml
unlimited run competitor-watch.yml --validate
unlimited watch --every 1h competitor-watch.yml     # run it every hour until Ctrl+C
Short pipelines don't need a file. Separate stages with -- and they run in one process:
unlimited run web https://example.com -- select title url -- json
unlimited watch --every 30m rss https://hnrss.org/frontpage -- grep AI -- diff --only added
watch keeps going when a run fails, reloads the pipeline file when you edit it, and adds a
little random delay so many watches don't hit a site at the same second.
Mistakes are reported with file, line and a suggestion:
error: competitor-watch.yml:8: sources[0] (web): unknown option 'feild' for web
hint: did you mean 'field'?
Publish a feed for free
publish turns a pipeline into a hosted feed: GitHub Actions runs it on a schedule, keeps the
diff state in your repository, and GitHub Pages serves the result. No server, no account
beyond GitHub.
unlimited publish feeds/*.yml --every 1h
# Wrote .github/workflows/unlimitedpipe-feeds.yml (runs every 1h, cron "54 * * * *")
# Wrote public/index.html
# ...
# Index: https://feeds.daemonfill.dev/
Live example: the feed catalog, 75+ feeds published this way from one
workflow. A feed whose source is down keeps its last good state while the others update. Each
JSON Feed carries full events, so another pipeline can read it with unlimited rss and keep
the provenance chain. Details, cron and manual setups:
docs/pipelines.md.
The Feed Catalog Protocol
What publish writes is an open format, not an UnlimitedPipe secret: a feeds.json that
lists a site's feeds and their latest items, feed files any reader understands, and a monthly
archive, all static files with a source link for every item. Any tool can write a catalog,
and every catalog can be searched, mirrored and asked the same way. The format is specified in
docs/protocol.md, with JSON Schemas in docs/schemas:
unlimited validate https://feeds.daemonfill.dev/     # check any catalog against the protocol
unlimited validate ./public --deep                   # and every feed file and archive month
Proposed next: discovery (/.well-known/feed-catalog.json), catalogs that list each other
as peers, and signed archives, so a copy can prove it is the original.
Change detection
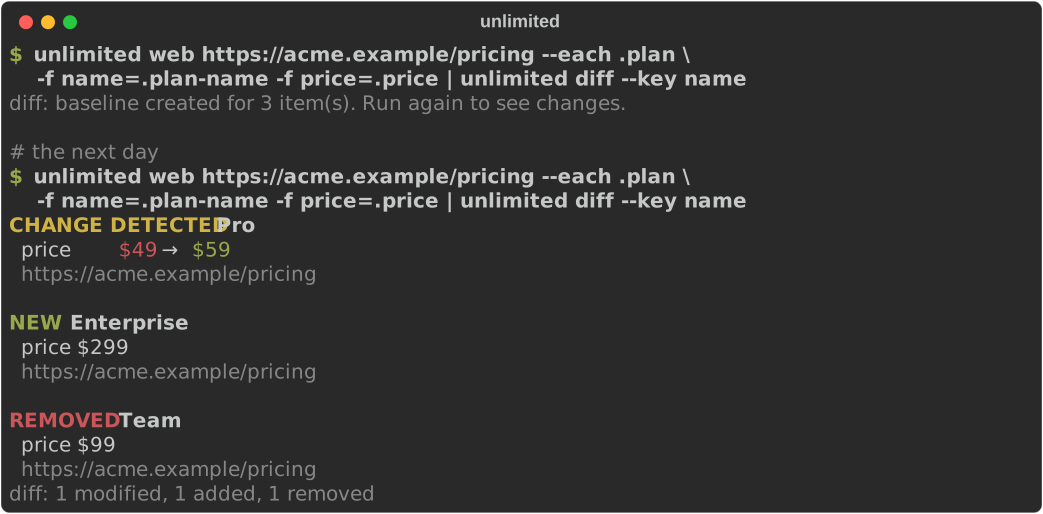
diff stores a small state file per watch and compares each item with the previous run:
- Items are matched by their key: product URL + SKU, feed item id, or
--key FIELD. - Changes come out as
changeevents with field-leveloldandnewvalues. - An item counts as removed only if its page or feed was fetched in this run, so a network failure never looks like everything disappeared.
--only addedturns any feed into a stream of new items; addwebhookto get each change as a Discord or Slack message.--ignore FIELDskips noisy fields.--resetstarts a new baseline.
{"type": "change", "key": "https://acme.example/pricing#Pro", "source_url": "https://acme.example/pricing",
 "data": {"change": "modified", "label": "Pro", "summary": "price: $49 → $59",
          "fields": [{"path": "price", "old": "$49", "new": "$59"}], "after": {"name": "Pro", "price": "$59"}}}
State lives in your platform's user state directory; set UNLIMITEDPIPE_STATE_DIR or
diff --state FILE to keep it elsewhere (for example, in a Git repository).
AI integration
UnlimitedPipe is useful without AI and ships no AI models. Agents can use it as a tool (see
the next section). Optional AI operators
(ai extract, ai summarize, ai classify) are planned behind a provider interface with
local models (Ollama) first, and every AI result will keep the provenance of the event it came
from. Until then, pipe events into any LLM command-line tool:
unlimited web https://example.com/changelog | jq -r .data.text | llm "What changed?"
Ask
ask answers a question from the feed catalog. Finding the facts is plain code, the same
matching as search; a model only explains what was found, citing numbered sources that are
always printed with their links. When nothing in the catalog matches, it says so without asking
a model.
$ unlimited ask "any big insider buys this week?"
Yes: DoubleLine Yield Opportunities Fund (DLY): Jeffrey J. Sherman (Vice President) bought
10,000 shares at $13.03 ($130.3K) [1]; CEMEX SAB DE CV (CX): Lozano Rogelio Zambrano
(director) bought 400,800 shares at $17.28 ($6.9M) [2].

Sources (answered by hf.co/unlimitedpipe/ask-0.5b-GGUF:latest)
[1] DoubleLine Yield Opportunities Fund (DLY): Jeffrey J. Sherman (Vice President) bought...
    https://www.sec.gov/Archives/edgar/data/1788399/000090445426000490/0000904454-26-000490-index.htm
[2] CEMEX SAB DE CV (CX): Lozano Rogelio Zambrano (director) bought 400,800 shares...
It uses a local model through Ollama when it is running (free, and
nothing leaves your machine), otherwise Claude when ANTHROPIC_API_KEY is set. UnlimitedPipe
itself never needs a model.
The model unlimited setup installs is
unlimitedpipe/ask-0.5b, a 0.5B model
(531 MB) trained for this one job: cite the source it uses, invent nothing, and say plainly
when the sources do not cover the question, in English and Thai. It was trained on public data
only, and graded on news it had never seen:
| Model | Answers that pass (news it never saw) |
|---|---|
| Qwen2.5 0.5B, the general model it started from | 5 of 92 (5%) |
| unlimitedpipe/ask-0.5b | 80 of 92 (87%) |
ollama pull hf.co/unlimitedpipe/ask-0.5b-GGUF # or let unlimited setup do it
It answers with its sources' own words, which is what keeps it honest; a larger general model
(ollama pull qwen2.5:3b) explains more and cites less. How it was built and graded:
research/ask.
History and offline
Every run of a published catalog also appends its new items to a monthly archive
(archive/2026-09.jsonl), so questions can reach back further than the latest items:
unlimited search sanctions --since 2026-08
unlimited ask "how did the Ebola outbreak develop?" --since 2026-07
A catalog also works without the internet. mirror downloads it, including the search index,
the archive and the index page with its search box, into your offline copy (or a folder you
name). search and ask switch to that copy by themselves when the internet is down, and say
how old it is. serve shares it with other devices on the same network (a school, a newsroom,
a disaster area):
unlimited mirror --since 2026-08                    # run it again to refresh
unlimited search flood --catalog offline            # the offline copy, on purpose
unlimited ask "what happened in Bangkok?" --catalog offline   # with a local model
unlimited serve --lan                               # phones on the same Wi-Fi get the search page
unlimited mirror ~/feeds && unlimited serve ~/feeds # or any folder
Platforms
Every platform is read through the door it offers: open APIs and feeds where they exist, and your own key where a platform requires one (YouTube, Reddit, X). Nothing tries to get around logins, paywalls or blocks. docs/platforms.md has the full table, and how to feed other tools' JSON into UnlimitedPipe's change detection.
unlimited doctor shows what works on your machine (network, browser, local AI, keys) and the
command that fixes each missing piece.
For AI agents (MCP)
unlimited mcp is a Model Context Protocol server, so Claude, Cursor and other agents can
read the public web through UnlimitedPipe and cite where every value came from:
claude mcp add unlimitedpipe -- unlimited mcp                       # Claude Code
unlimited mcp competitor-watch.yml ai-news.yml                      # your pipelines as tools
To give an agent UnlimitedPipe as a skill, tell it:
Install UnlimitedPipe: https://raw.githubusercontent.com/Fuyuki0/unlimitedpipe/main/docs/install-for-agents.md.
It installs the command, runs unlimited doctor, and learns the commands from
skills/unlimitedpipe/SKILL.md.
Built-in tools: search_feeds and list_feeds (the whole public catalog, searched in one
request: ask "did any company disclose a cyberattack to the SEC this week?"), fetch_page
(products, documents or CSS selections), read_feed, inspect_url and github. Each pipeline file becomes a tool too, so an agent can ask "what
changed on the competitor's pricing page?" and get the diff result. Results are events with
their source URL, observation time and provenance. Built-in tools refuse private and local
addresses, including through redirects, so a page an agent reads cannot steer it into your
network.
Creating a connector
A source is a small Python class. Its typed fields become CLI options, YAML keys and Python arguments at once:
from unlimitedpipe import Event, Source, arg, opt


class HackerNews(Source):
    """Search Hacker News stories."""

    name = "hackernews"
    query: str = arg("Search words")
    limit: int = opt("Maximum stories", default=30)

    async def collect(self, ctx):
        response = await ctx.http.get(
            "https://hn.algolia.com/api/v1/search_by_date",
            params={"query": self.query, "tags": "story", "hitsPerPage": self.limit},
        )
        for hit in response.json()["hits"]:
            yield Event(source="hackernews", type="story", key=hit["objectID"],
                        data={"title": hit["title"], "url": hit["url"], "points": hit["points"]})
Register it with one entry point, pip install it, and unlimited hackernews "local llm"
works, with rate limiting, retries, robots.txt, --help and YAML support included.
examples/plugin-hackernews is a complete package to copy, and
docs/connectors.md walks through creating, registering, testing,
documenting and submitting one.
Architecture
- Event (
unlimitedpipe.event/1):id,source,type,key,source_url,timestamp,observed_at,data,metadata,provenance. See docs/events.md. - Components are dataclasses: sources implement
collect, operatorsprocessorapply, outputsopen/write/close. The CLI and YAML loader are generated from their fields. - Engine: async generators chained source -> operators -> outputs. Streaming by default;
only
sortand whole-document outputs buffer. Stopping early (limit, Ctrl+C, a closed pipe) closes every stage, and outputs and diff state are always saved. - Network layer: one shared client per run with per-host throttling, retries honoring
Retry-After, RFC 9309 robots.txt withCrawl-delay, conditional requests, and a size cap. - Plugins: the
unlimitedpipe.pluginsentry point group. Commands load lazily, so a pipe stage starts in about 150 ms.
src/unlimitedpipe/
  event.py  component.py  engine.py  context.py  http.py  config.py  cli.py
  expr.py   watch.py  scaffold.py  publish.py  mcp.py
  sources/    web, rss, file, github, sec, bluesky, mastodon, telegram, youtube, reddit, x,
              search, ask, inspect
  operators/  select, filter, map, grep, dedupe, limit, sort, diff, extract, count, trend
  outputs/    jsonl, json, csv, feed, webhook, sqlite, pretty
Examples
Runnable pipelines in examples/: website to JSON, an RSS news filter published as a feed, GitHub release watching, price monitoring with Discord alerts, competitor pricing watch, multi-source research into CSV, Bluesky trends, and a complete connector package. The feed catalog has 75+ more.
Research
research/ holds experiments on UnlimitedPipe's data, with their results written
up, good or bad:
- A small model trained for
ask: a 0.5B model fine-tuned to answer from numbered sources, with citations, and to say plainly when the sources do not cover a question. - A fruit-fly brain circuit on news: the fly's mushroom body did no better than plain compression; a main network with separate modules kept old knowledge when learning new feeds, where one model forgot it.
- Public records: collectors for the dataset unlimitedpipe/public-records, public-domain US government text (the Federal Register, SEC annual reports) with provenance for every document.
Roadmap
- v0.1 Pipe: engine, CLI,
webwith product detection,rss,file,inspect, eight operators, JSON/JSONL/CSV/feed outputs, YAML pipelines, plugins. - v0.2 Feed:
watch,new,publish(free hosted feeds), thegithubconnector. - v0.3 Live:
webhook(Discord, Slack),sqlite, the trend engine (extract,count,trend), the liveblueskysource, and the MCP server for AI agents. - v0.4 Search:
searchacross a whole feed catalog,catalogindexes,list_feeds/search_feedsfor AI agents, thesecsource for insider trades, arithmetic andshort()in expressions. - v0.5 Ask:
askanswers questions from the catalog with a local model or Claude, always with sources; published index pages get a search box; feed health in the catalog. - v0.6 Browser:
web --browserrenders pages that need JavaScript in a headless browser under the same rules (robots.txt, pacing, honest User-Agent), with screenshots as evidence. - v0.7 Platforms:
mastodon,telegram,youtube,redditandxthrough their official doors,unlimited doctor, and a skill file for AI agents. - v0.8 History: a monthly archive of every catalog item,
--sinceforsearch,askand the MCP tool, local catalogs,mirrorandservefor offline use. - v0.9 Setup: a one-line installer and
unlimited setup, which sets up the browser, a local AI model, Claude Code's tools and skill, and an offline catalog. - v0.10 Open (current): the Feed Catalog Protocol with
unlimited validate, a 0.5B model trained foraskon public data (87% on news it never saw, against 5% for its base), and the public dataset unlimitedpipe/public-records. - Next: searching the archive from the web page, bot-network filtering for trends, a network of catalogs.
Responsible use
UnlimitedPipe is for public data and data you are authorized to access. It uses the front door: official APIs and feeds when they exist, polite HTML otherwise. It does not bypass logins, CAPTCHAs or blocks, and it is not for collecting data about individuals. You are responsible for complying with each site's terms and applicable law. See docs/responsible-use.md.
Contributing
Connectors, recipes and bug reports are all welcome. Start with
CONTRIBUTING.md; make test lint runs the same checks as CI.
License
1 maintainer

Metadata
1 maintainer
Release files for unlimitedpipe 0.10.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| unlimitedpipe-0.10.1.tar.gz | 278.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| unlimitedpipe-0.10.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 466.2 kB
Release files / unlimitedpipe-0.10.1.tar.gz
| Download URL | unlimitedpipe-0.10.1.tar.gz |
|---|---|
| Size | 278.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c5c73d5c6b42235285f6cecaf865983b3cc7139de5c0e2d9b709fbcc13562893
|
|
BLAKE2b-256 checksum How to use checksums |
af9089821cf2b214bd714b42a1e4eb53e43408d5c3d78f1f92ae002a00433237
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 27, 2026.
Transparency logRelease files / unlimitedpipe-0.10.1-py3-none-any.whl
| Download URL | unlimitedpipe-0.10.1-py3-none-any.whl |
|---|---|
| Size | 187.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
67e43b8d2a7c798fbd5c11437be25f9dbc34f58ef9d019919f57e52843a8956f
|
|
BLAKE2b-256 checksum How to use checksums |
d8b880bd135f6f86160d963e1e48977c63d8c78ecf711bec05aacd63b956c1df
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 27, 2026.
Transparency log













