
Introduction
This python package is a set of Salesforce.com, Veeva Network, Veeva Vault, and Veeva Nitro libraries, scripts, and functions used to help expedite the development of Veeva Tools.
Installation / Requirements
Ensure you have at least Python version 3.10 installed. To Check your installation version, type the following commands in the terminal (MacOs) / command prompt (Windows):
python --version
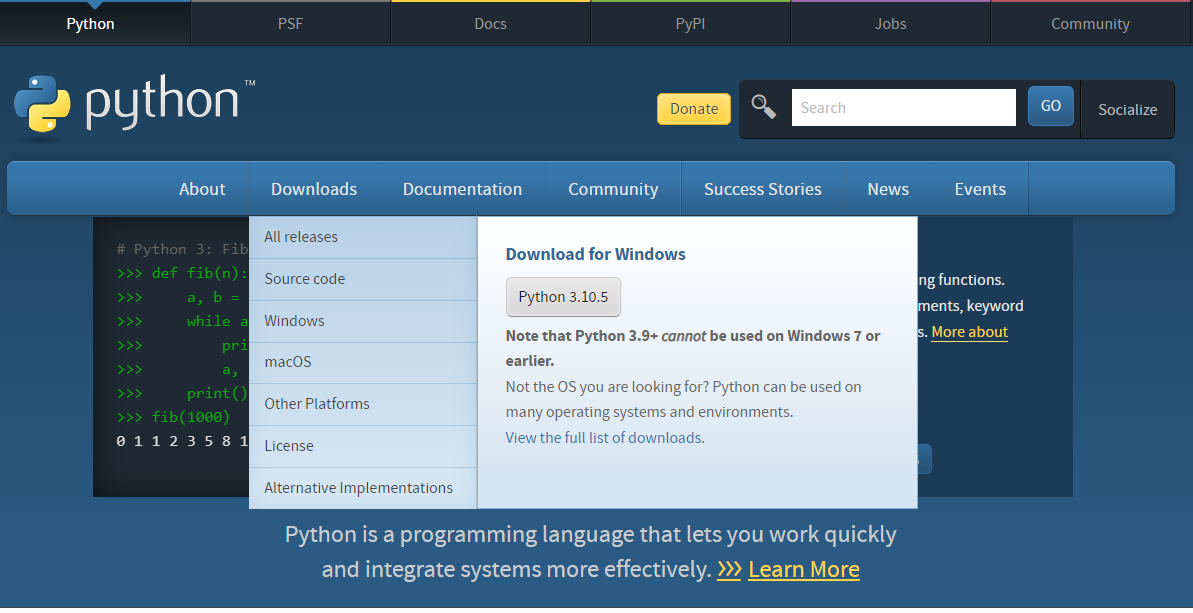
To install python, go to https://www.python.org/ then navigate to the download page of your Operating System.
You will need to have Packager Installer for Python (pip) installed. To install pip, run the following command in the terminal (MacOs) / command prompt (Windows):
curl https://bootstrap.pypa.io/get-pip.py -o get-pip.py
python3 get-pip.py
To install the Veeva Tools library:
pip install veevatools
To upgrade to the latest version of Veeva Tools library:
pip install veevatools --upgrade
Installation Options
Install only the modules you need:
# Install everything
pip install veevatools[all]

# Install individual modules
pip install veevatools[vault]        # Veeva Vault only
pip install veevatools[salesforce]   # Salesforce/CRM only
pip install veevatools[network]      # Veeva Network only
pip install veevatools[nitro]        # Veeva Nitro only

# Development dependencies
pip install veevatools[dev]
Overview
The Veeva Tools package currently contains 4 major components:
Salesforce library
Authentication:
from veevatools.salesforce import Sf
import pandas as pd

sf = Sf()

# Option 1: Direct username/password authentication
sf.authenticate(
    sfUsername='yourname@salesforce.com',
    sfPassword='password123',
    sfOrgId='00D2C0000008jIK',
    is_sandbox=False
)

# Option 2: Active Session ID authentication (Extension / SSO session)
sf.authenticate(
    session_id='00D...',
    sfOrgId='00D2C0000008jIK',
    instance_url='https://na1.salesforce.com'
)
Sidenote on Pandas DataFrames:
Pandas DataFrame (pd) is used to prepare the data for import (i.e. create, update methods) and additional export methods such as pd.to_excel() in order to save the output into an Excel file.
Additionally, Complex data manipuation (joins, merges, groupbys, filters)and data analytics (describe, statistical analysis) can all be performed using Pandas.
To learn more about Pandas DataFrames, go to the Pandas documentation <br > Or just Google tutorials on Pandas DataFrames. This YouTube playlist by Corey Schafer provides an excellent starting point into the world of Pandas!
Data methods:
The salesforce class (Sf) contains methods that can help you interact with data and metadata components:
Query
account_recordtypes = sf.query("SELECT Id, Name, SobjectType from RecordType WHERE SobjectType = 'Account'")

account_recordtypes
Return -> pd.DataFrame():
| Id | Name | SobjectType | |
|---|---|---|---|
| 0 | 012f4000001ArT3AAK | Professional_vod | Account |
| 1 | 012f4000001ArT4AAK | Institution_vod | Account |
| 2 | 012f4000001ArT5AAK | MCO_vod | Account |
| 3 | 012f4000001ArT6AAK | Organization_vod | Account |
| 4 | 012f4000001ArWzAAK | Hospital_vod | Account |
Sidenote:
You can use any Pandas (pd) methods on the return value of the query output. For exampleaccount_recordtypes.to_excel("Account RecordTypes.xlsx")
Will save the results of the DataFrame into an Excel file.
Create
## Takes a DataFrame of CRM records and creates records in CRM

account_records = pd.DataFrame([{'FirstName': 'Test', 'LastName': 'Account'}, {'FirstName': 'Test2', 'LastName': 'Account2'}])

result = sf.create('Account', account_records)

result
Return -> pd.DataFrame():
| success | created | Id | |
|---|---|---|---|
| 0 | True | True | 0010r00000tF7L1AAK |
| 1 | True | True | 0010r00000tF7L2AAK |
Update
### Takes a dataframe that contains at least the Id column
### and any other column to be updated, for example, FirstName
update_account_name = pd.DataFrame(
    [{'FirstName': 'Updated', 'Id': '0010r00000tF7L1AAK'},
     {'FirstName': 'Name', 'Id': '0010r00000tF7L2AAK'}]
    )

result = sf.update('Account', update_account_name)

result
Return -> pd.DataFrame()
| success | created | Id | |
|---|---|---|---|
| 0 | True | False | 0010r00000tF7L1AAK |
| 1 | True | False | 0010r00000tF7L2AAK |
Upsert
### Takes a dataframe that contains an external ID column
### and any other column to be updated, for example, Name
### if the external ID matches an existing record,
### the account is updated, otherwise, a new record is created

upsert_account = pd.DataFrame(
    [{'NET_External_Id__c': '242977178138969088', 'Name': 'Updated Hospital Name'},
     {'NET_External_Id__c': '555579769212255555', 'Name': 'Create New Hospital'}]
    )

result = sf.upsert(object_api='Account', external_id_field_api='NET_External_Id__c', record_dataframe=upsert_account)

result
Return -> pd.DataFrame()
| success | created | id | |
|---|---|---|---|
| 0 | True | False | 001f400000PKOrwAAH |
| 1 | True | True | 0010r00000tF7stAAC |
Delete
### Takes a dataframe that contains the Id column
### deletes records listed based on their SFID.

delete_account = pd.DataFrame([{'Id': '0010r00000tF7stAAC'}, {'Id': '001f400000PKOrwAAH'}])

result = sf.delete(object_api='Account', record_dataframe=delete_account)

result
Return -> pd.DataFrame()
| success | created | Id | |
|---|---|---|---|
| 0 | True | False | 0010r00000tF7stAAC |
| 1 | True | False | 001f400000PKOrwAAH |
Permission Sets & PermissionSetGroup Resolver
Module: veevatools.salesforce.permission_sets
A multiworker-safe, pure resolution engine for Salesforce permissions that combines base profile permissions with direct Permission Sets and PermissionSetGroups, automatically subtracting MutingPermissionSets across all three surfaces (518 system permissions, ObjectPermissions, FieldPermissions):
from veevatools.salesforce.permission_sets import (
    EffectivePermissionsResolver,
    expand_group_assignments,
    apply_muting,
)

# 1. Expand PermissionSetGroup assignments into constituent member permission sets
expanded_assignments = expand_group_assignments(
    assignments=user_psa_df,
    components=psg_components_df,
)

# 2. Compute effective permissions for a user or chunked across user batches
resolver = EffectivePermissionsResolver()
effective = resolver.for_user(
    profile_permissions=profile_perms_df,
    direct_ps_permissions=direct_ps_df,
    psg_permissions=expanded_assignments,
    muting_permissions=muting_df,
)
Metadata Methods
Metadata methods (Read, Create, Update, Rename, Delete, List) -- coming soon.
Vault library
Authentication:
from veevavault import VaultClient, DocumentService

client = VaultClient()
client.authenticate(vaultURL='https://myvault.veevavault.com', vaultUserName='user@vault.com', vaultPassword='password123')

# Services take the authenticated client as their argument
docs = DocumentService(client)
all_docs = docs.retrieval.retrieve_all_documents()
Network library
Authentication:
from veevanetwork import NetworkClient

# NetworkClient requires url, username, and password at construction
client = NetworkClient(
    url='https://mynetwork.veevanetwork.com',
    username='user',
    password='pass',
)
client.authenticate()

# Services are accessed as properties on the client
results = client.search.search(q='Smith')
objects = client.metadata.retrieve_object_types()
Nitro library
Authentication:
from veevanitro import Nitro

# Nitro wires the client and all services together
n = Nitro()
n.auth.login(server_url='https://mycompany.veevanitro.com', username='user', password='pass')

# Access services directly
tenant = n.admin.get_tenant()
users = n.admin.get_users()
1 maintainer

Metadata
1 maintainer
Release files for veevatools 1.0.20
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| veevatools-1.0.20.tar.gz | 839.3 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| veevatools-1.0.20-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.3 MB
Release files / veevatools-1.0.20.tar.gz
| Download URL | veevatools-1.0.20.tar.gz |
|---|---|
| Size | 839.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
44b8d6e23c1aed5efdcca1f092322db6e0a047b8d0e25b2a8af10710936af19c
|
|
BLAKE2b-256 checksum How to use checksums |
e9f70a8407d1861b7bafcf3fd572b4a6e3a089752545234e80ee792a41a43c99
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.13.1
|
Release files / veevatools-1.0.20-py3-none-any.whl
| Download URL | veevatools-1.0.20-py3-none-any.whl |
|---|---|
| Size | 442.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5a077ba5649532773afee3b6a3bb8aa1625c0ccabf272c810dffdb24798d155c
|
|
BLAKE2b-256 checksum How to use checksums |
b56be6b6d5487f8699facd3a280df18e9eb184bd8392c8c6a010f2d96a6eba5d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.13.1
|
Security for veevatools 1.0.20
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














