

VoiceFixer
This package provides:
- A pretrained 44.1k universal speaker-independent neural vocoder.
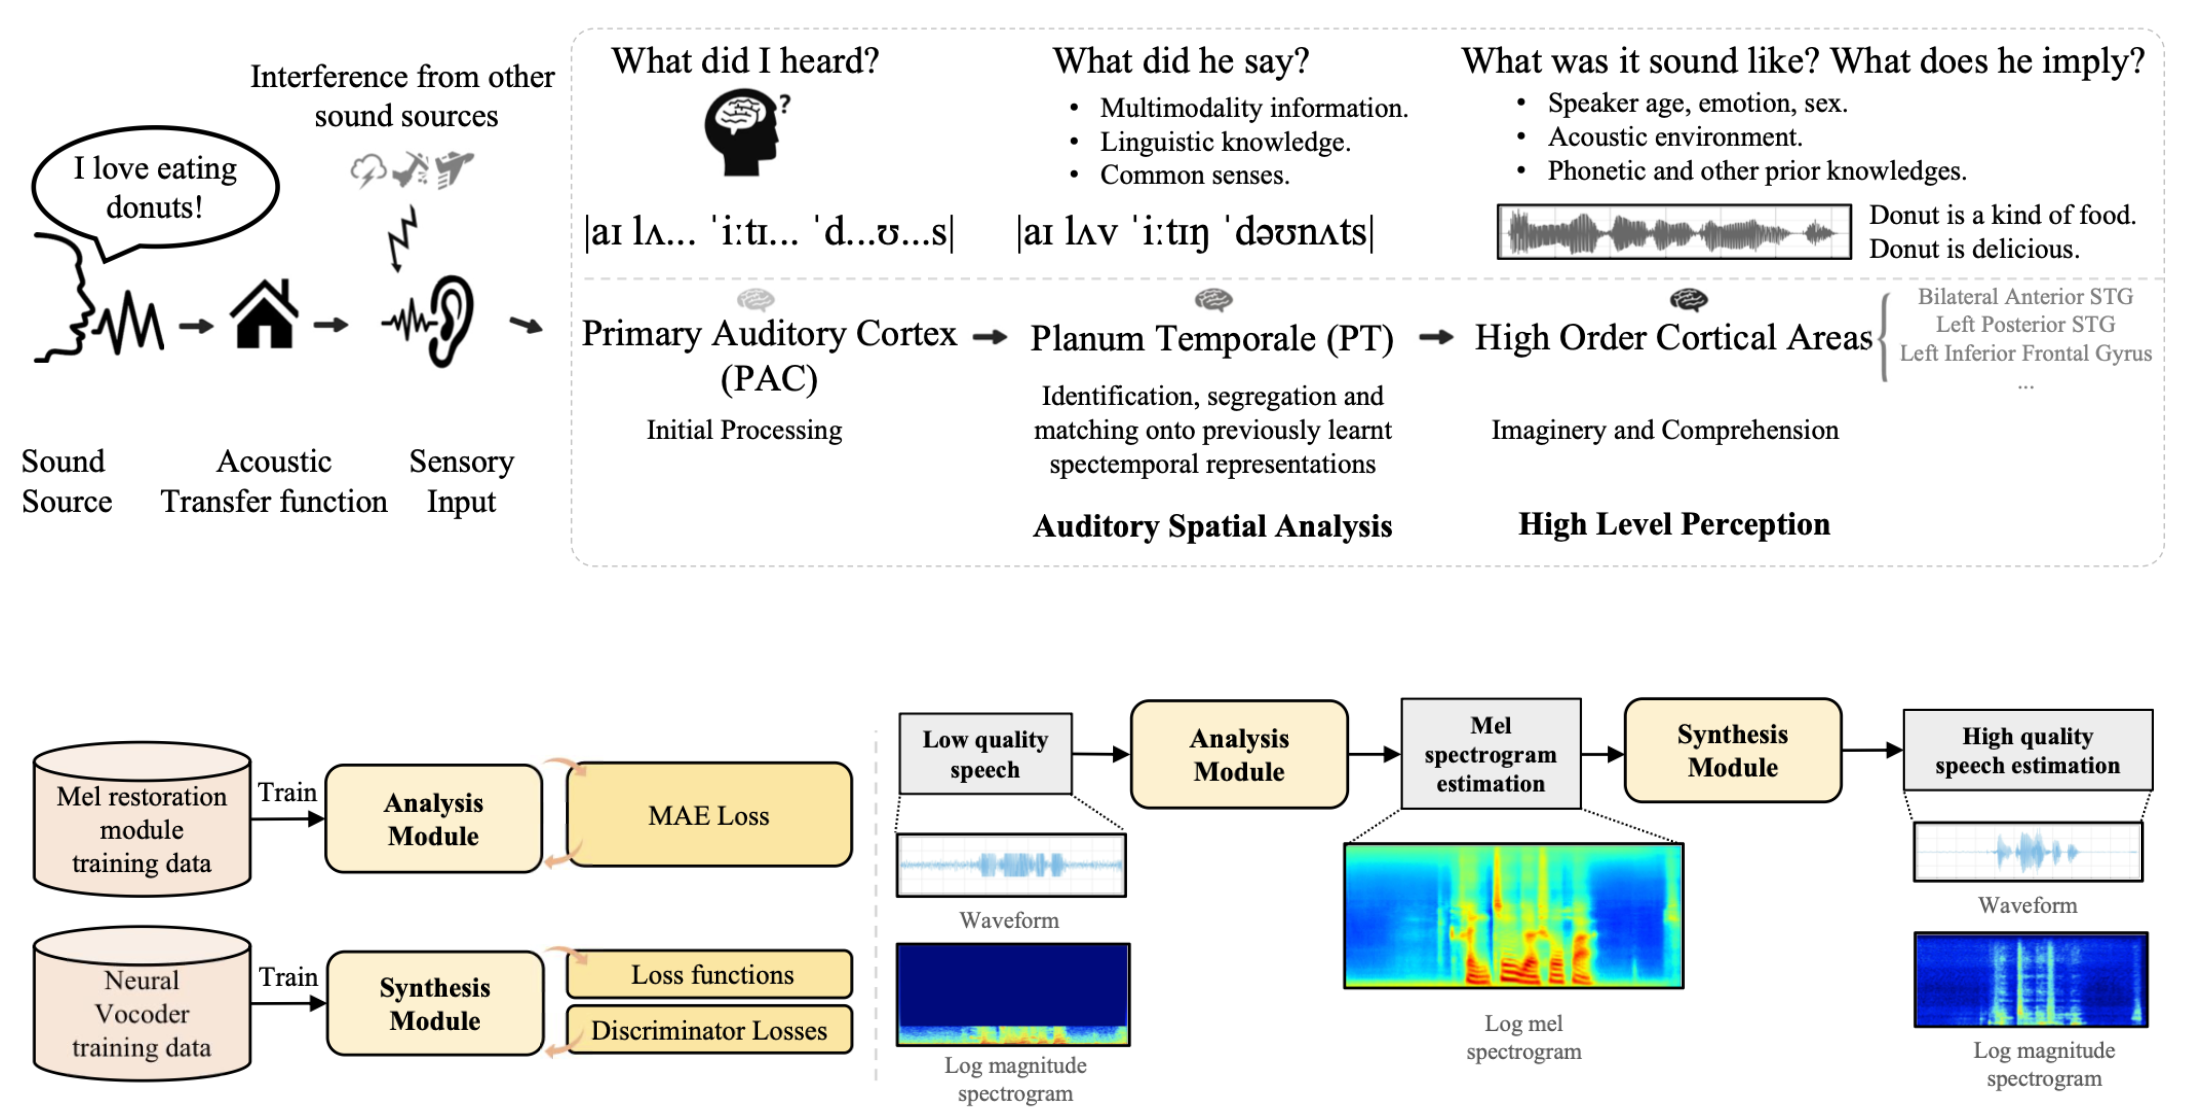
- A pretrained Voicefixer, which is build based on neural vocoder.
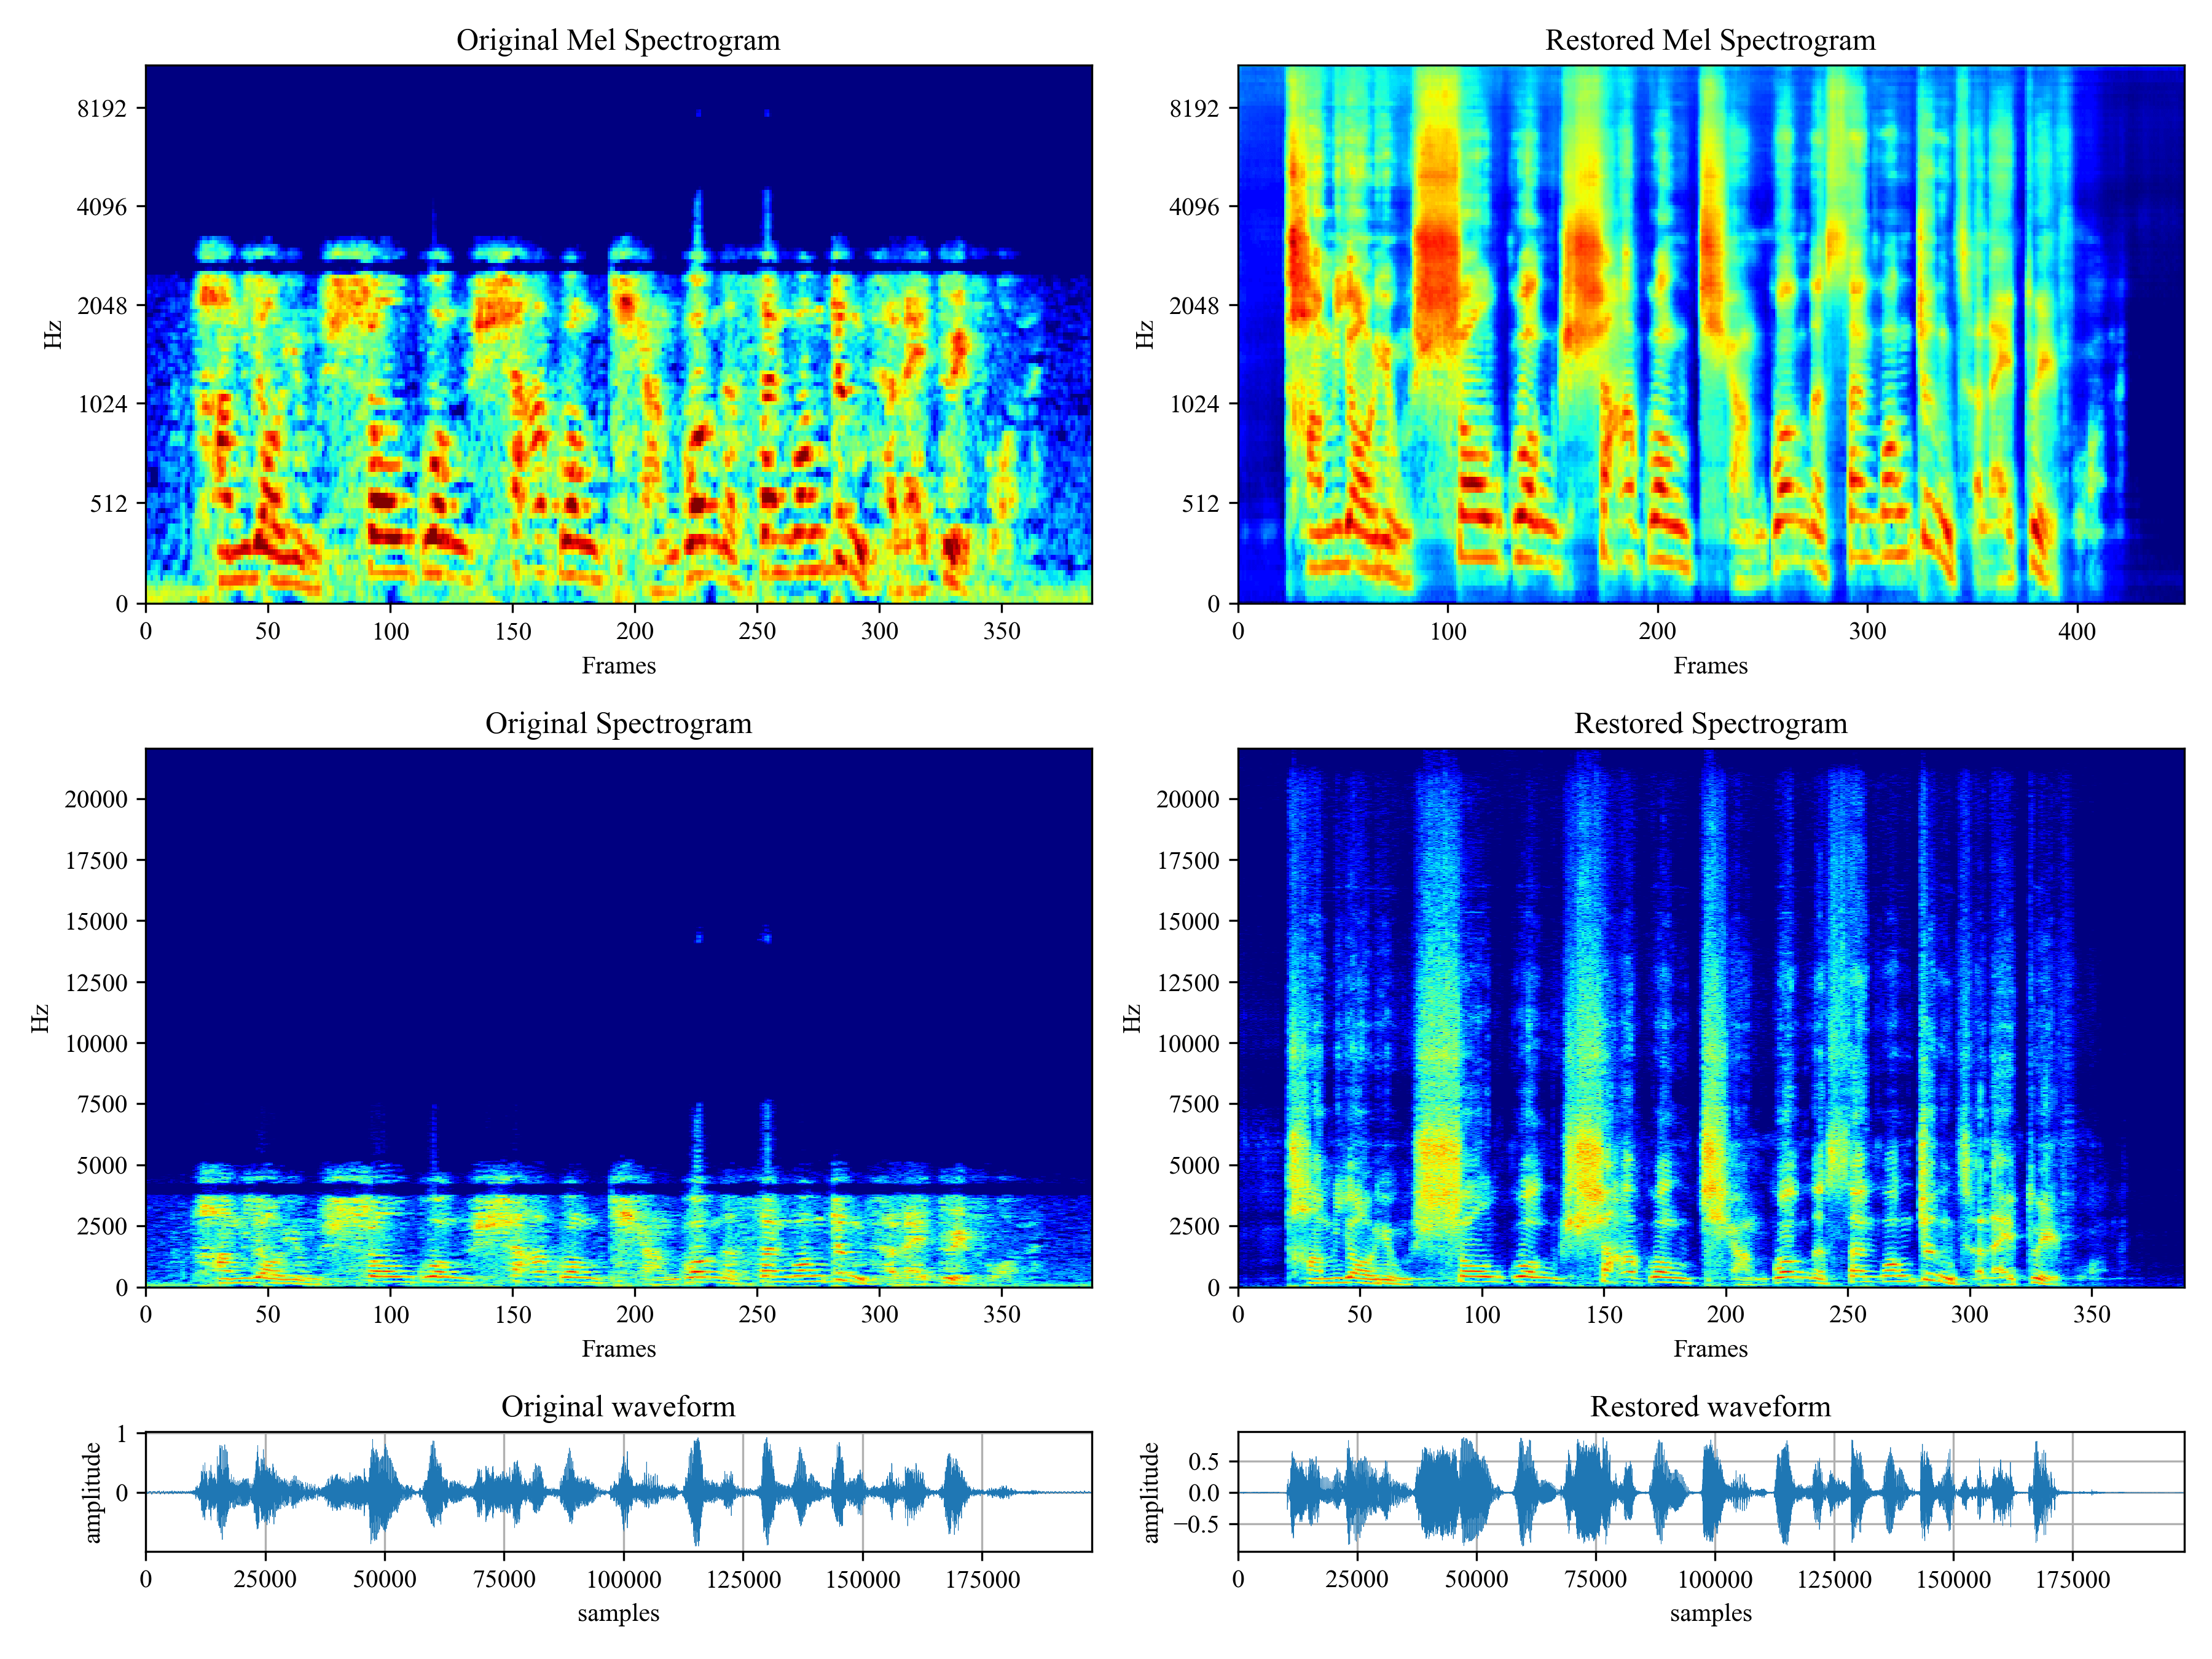
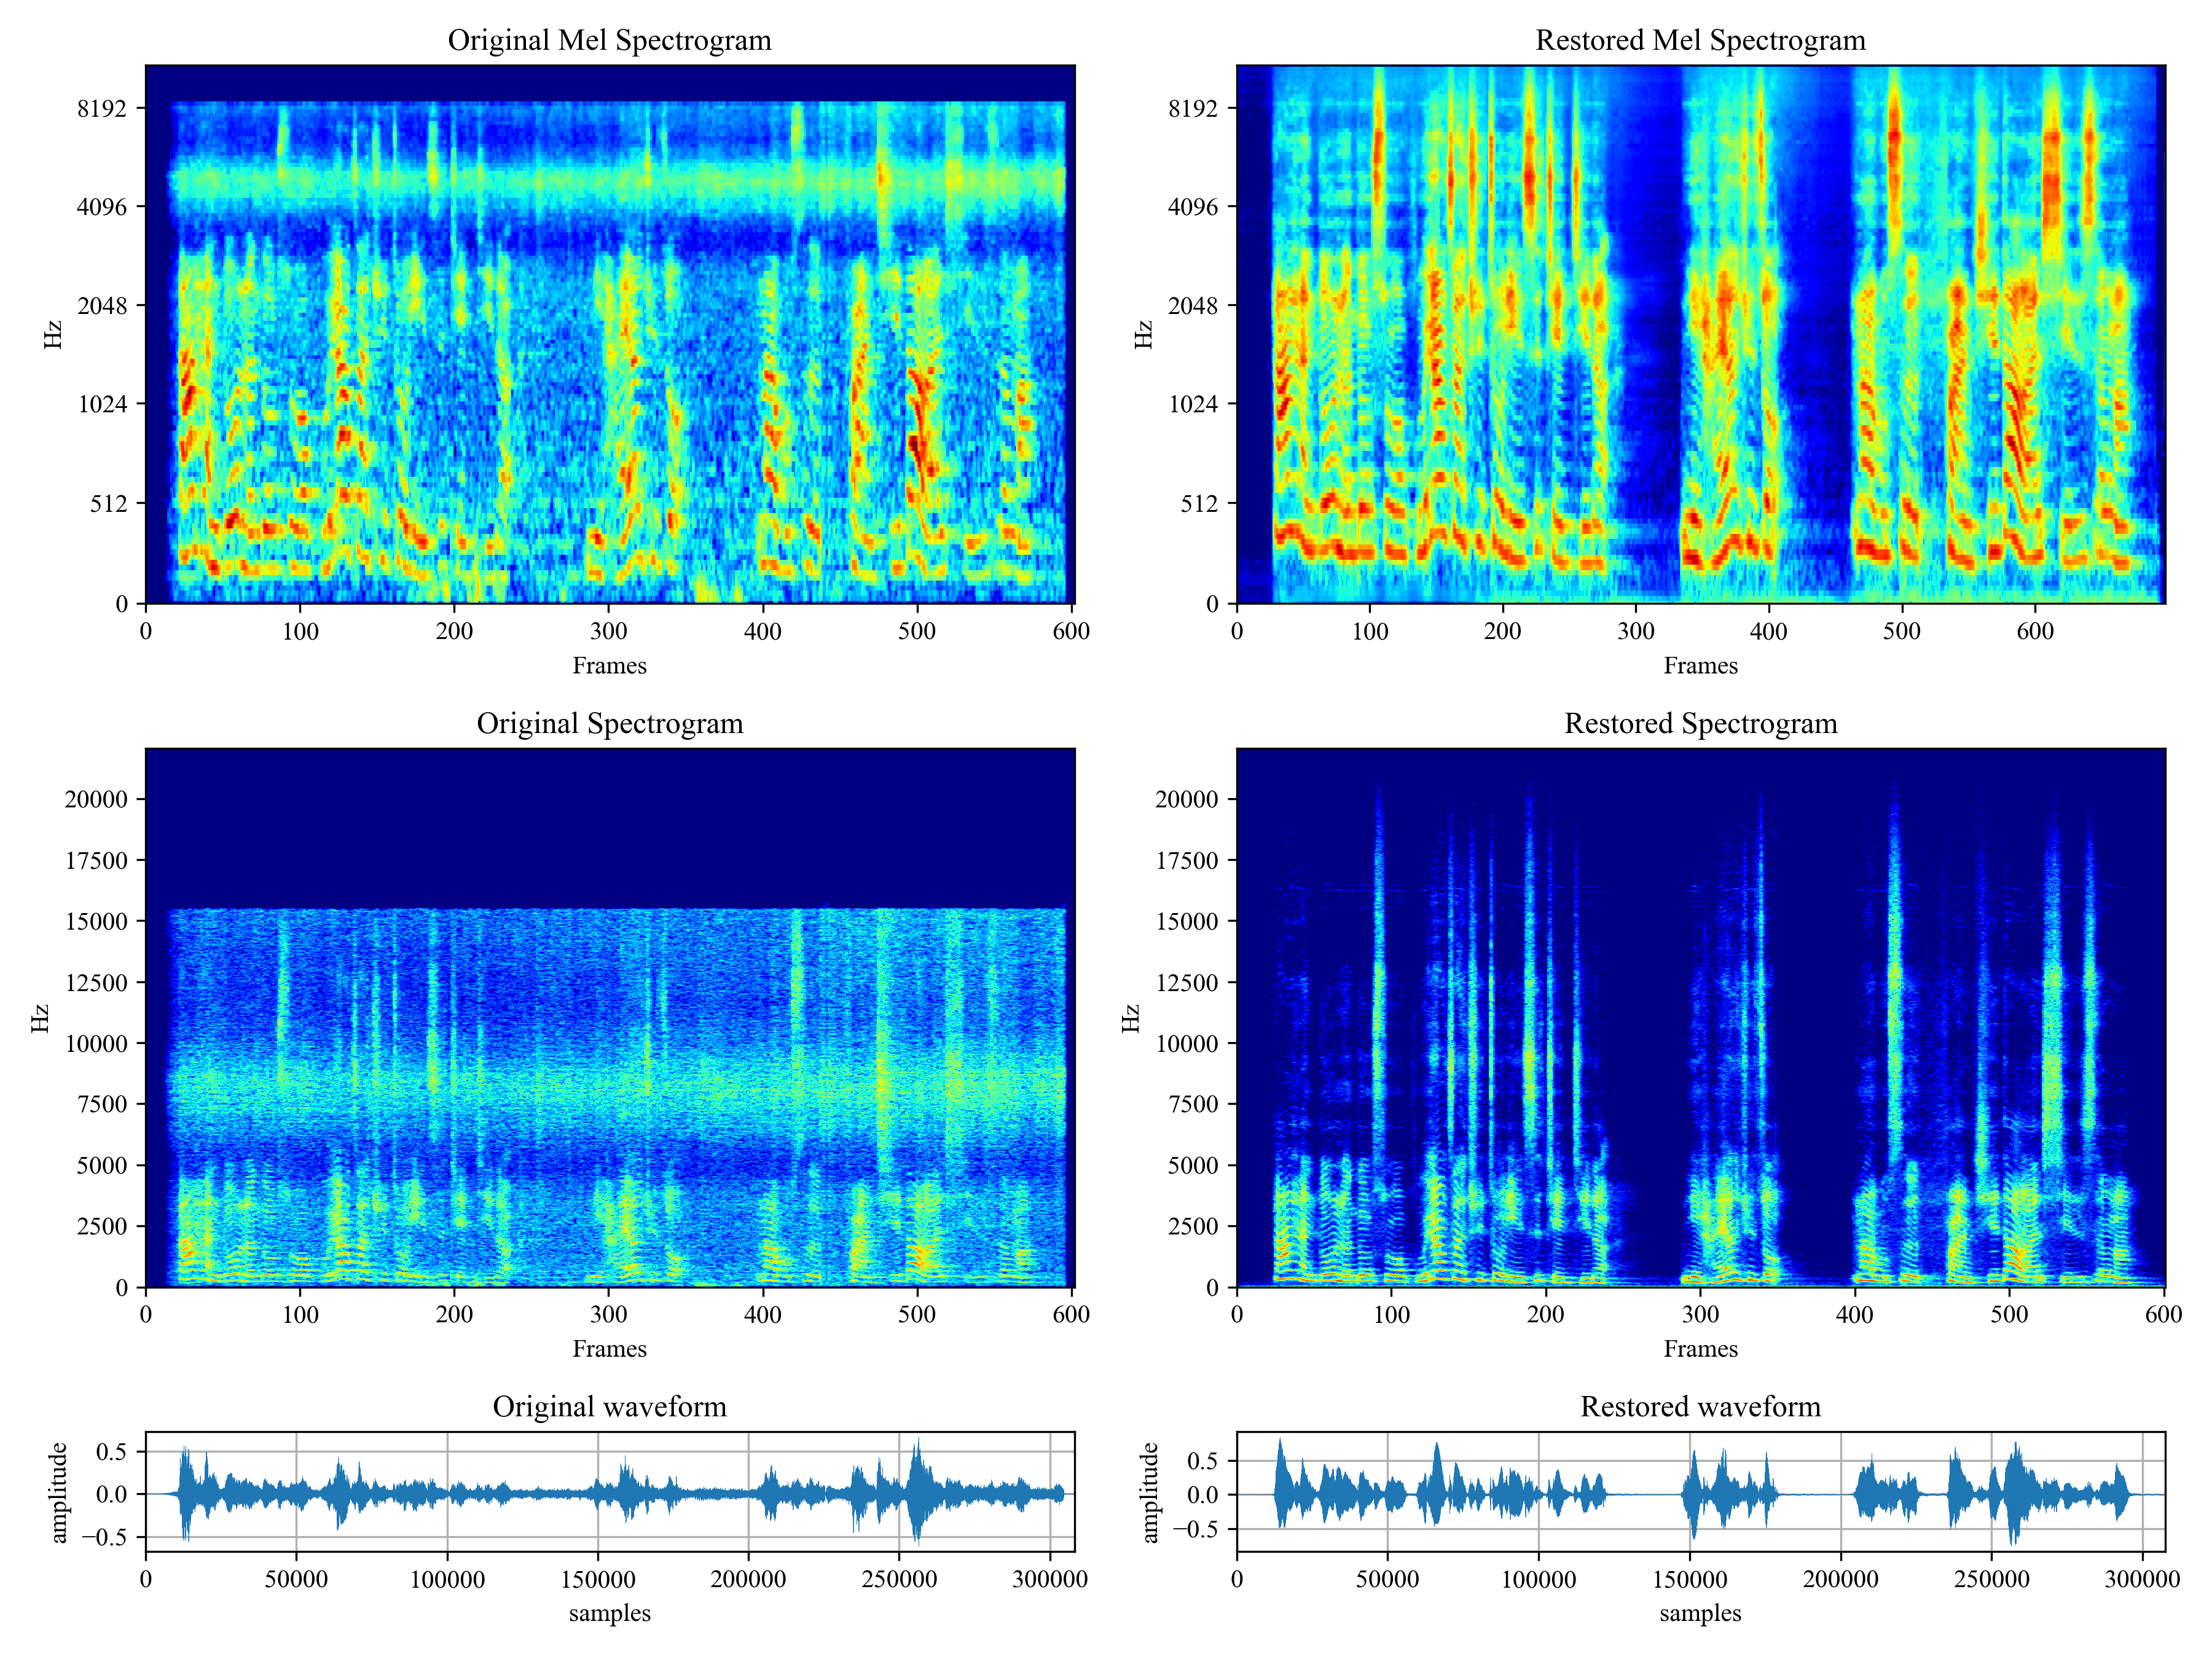
Voicefixer aims at the restoration of human speech regardless how serious its degraded. It can handle noise, reveberation, low resolution (2kHz~44.1kHz) and clipping (0.1-1.0 threshold) effect within one model.
Demo
Please visit demo page to view what voicefixer can do.
Usage
Install voicefixer first:
pip install voicefixer
Desktop App
You can test audio samples on your desktop by running website (powered by streamlit)
# Install additional web package
pip install streamlit
# Run streamlit
streamlit run test/streamlit.py
Important: When you run the above command for the first time, the web page may leave blank for several minutes for downloading models. You can checkout the terminal for downloading progresses.
Python interface
Basic example:
# Will automatically download model parameters.
from voicefixer import VoiceFixer
from voicefixer import Vocoder

# Initialize model
voicefixer = VoiceFixer()
# Speech restoration

# Mode 0: Original Model (suggested by default)
voicefixer.restore(input="", # input wav file path
                   output="", # output wav file path
                   cuda=False, # whether to use gpu acceleration
                   mode = 0) # You can try out mode 0, 1, 2 to find out the best result
# Mode 1: Add preprocessing module (remove higher frequency)
voicefixer.restore(input="", # input wav file path
                   output="", # output wav file path
                   cuda=False, # whether to use gpu acceleration
                   mode = 1) # You can try out mode 0, 1, 2 to find out the best result
# Mode 2: Train mode (might work sometimes on seriously degraded real speech)
voicefixer.restore(input="", # input wav file path
                   output="", # output wav file path
                   cuda=False, # whether to use gpu acceleration
                   mode = 2) # You can try out mode 0, 1, 2 to find out the best result

# Another similar function
# voicefixer.restore_inmem()

# Universal speaker independent vocoder
vocoder = Vocoder(sample_rate=44100) # Only 44100 sampling rate is supported.

# Convert mel spectrogram to waveform
wave = vocoder.forward(mel=mel_spec) # This forward function is used in the following oracle function.

# Test vocoder using the mel spectrogram of 'fpath', save output to file out_path
vocoder.oracle(fpath="", # input wav file path
               out_path="") # output wav file path
Others Features
- How to use your own vocoder, like pre-trained HiFi-Gan?
First you need to write a following helper function with your model. Similar to the helper function in this repo: https://github.com/haoheliu/voicefixer/blob/main/voicefixer/vocoder/base.py#L35
    def convert_mel_to_wav(mel):
        """
        :param non normalized mel spectrogram: [batchsize, 1, t-steps, n_mel]
        :return: [batchsize, 1, samples]
        """
        return wav
Then pass this function to voicefixer.restore, for example:
voicefixer.restore(input="", # input wav file path
                   output="", # output wav file path
                   cuda=False, # whether to use gpu acceleration
                   mode = 0,
                   your_vocoder_func = convert_mel_to_wav)
Note:
- For compatibility, your vocoder should working on 44.1kHz wave with mel frequency bins 128.
- The input mel spectrogram to the helper function should not be normalized by the width of each mel filter.
Materials
- Voicefixer training: https://github.com/haoheliu/voicefixer_main.git
- Demo page: https://haoheliu.github.io/demopage-voicefixer/
- If you found this repo helpful, please consider citing
 @misc{liu2021voicefixer,
     title={VoiceFixer: Toward General Speech Restoration With Neural Vocoder},
     author={Haohe Liu and Qiuqiang Kong and Qiao Tian and Yan Zhao and DeLiang Wang and Chuanzeng Huang and Yuxuan Wang},
     year={2021},
     eprint={2109.13731},
     archivePrefix={arXiv},
     primaryClass={cs.SD}
 }
1 maintainer

Metadata
1 maintainer
Release files for voicefixer 0.0.9
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| voicefixer-0.0.9.tar.gz | 38.0 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| voicefixer-0.0.9-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 81.2 kB
Release files / voicefixer-0.0.9.tar.gz
| Download URL | voicefixer-0.0.9.tar.gz |
|---|---|
| Size | 38.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3c2a1815c283ed2ee6abbe2ea5e54816091b91b12c53a9330c9cdab1b54f3ba1
|
|
BLAKE2b-256 checksum How to use checksums |
8303ef3f0d4e937ff015cfd2307f9d23bcded0df42e12aa9d473e0749ff2d28d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.2 importlib_metadata/4.8.1 pkginfo/1.7.1 requests/2.26.0 requests-toolbelt/0.9.1 tqdm/4.62.2 CPython/3.7.10
|
Release files / voicefixer-0.0.9-py3-none-any.whl
| Download URL | voicefixer-0.0.9-py3-none-any.whl |
|---|---|
| Size | 43.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1145e7985b3ff57d8f542364c18be6fc113cd6af93e0ec7e354a9b210902929d
|
|
BLAKE2b-256 checksum How to use checksums |
d0c22a22d915350fbeb0b7e493dd6649af7312be4ad088928c7ea2190eef489f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.2 importlib_metadata/4.8.1 pkginfo/1.7.1 requests/2.26.0 requests-toolbelt/0.9.1 tqdm/4.62.2 CPython/3.7.10
|
Security for voicefixer 0.0.9
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














